

Detecting Deepfake Voice Using Explainable Deep Learning Techniques
Open accessThe DOI matches its Crossref record; 21 of the 21 references it cites were found in a registry or an index.
Abstract
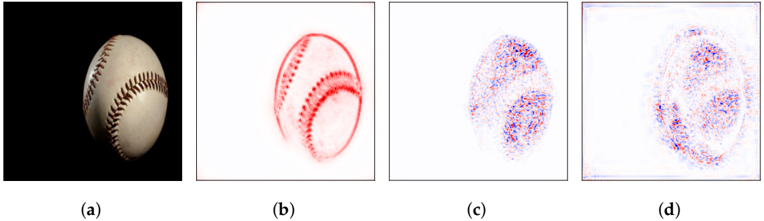
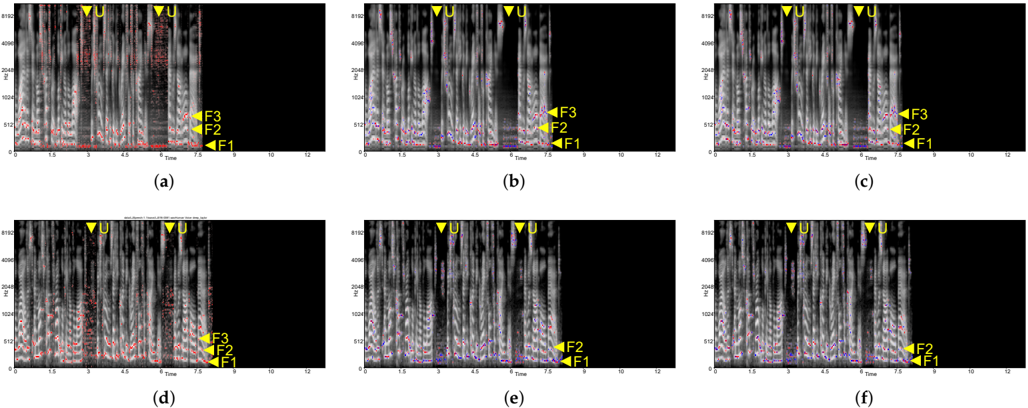
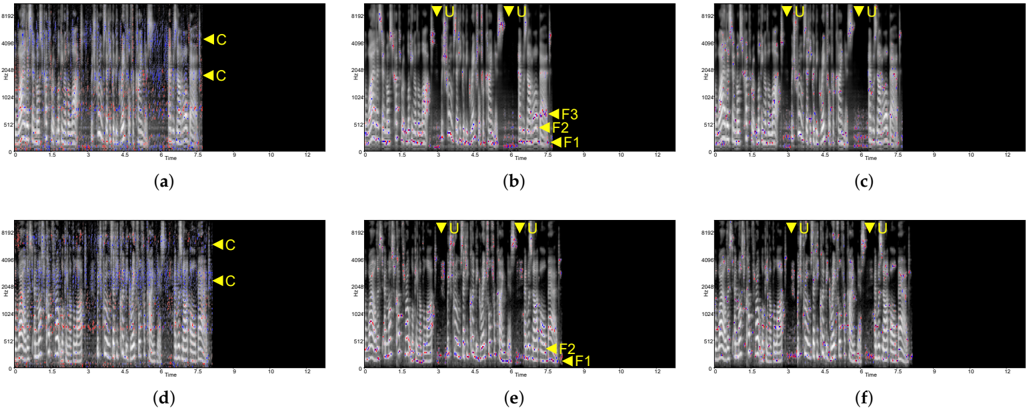
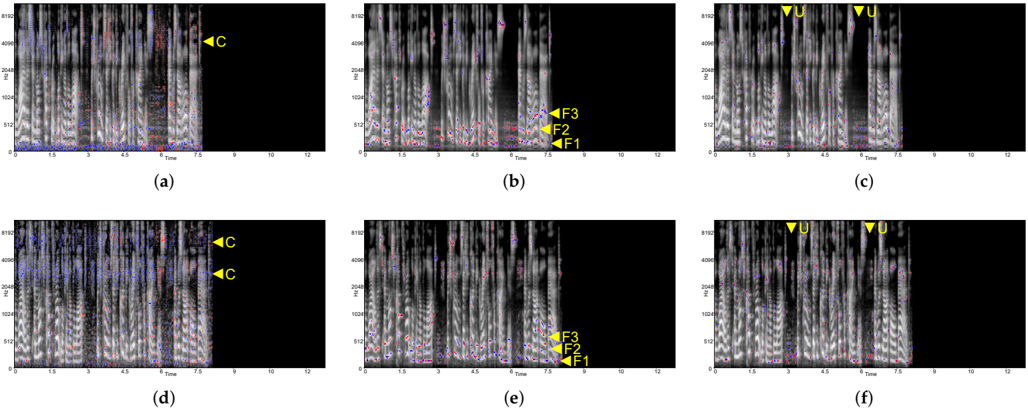
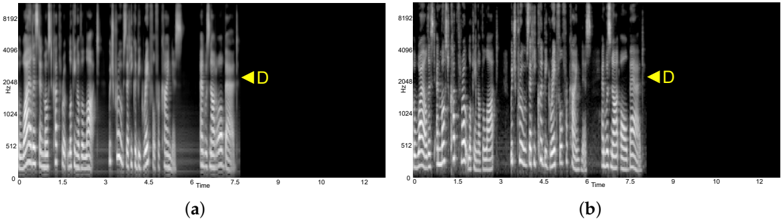
Fake media, generated by methods such as deepfakes, have become indistinguishable from real media, but their detection has not improved at the same pace. Furthermore, the absence of interpretability on deepfake detection models makes their reliability questionable. In this paper, we present a human perception level of interpretability for deepfake audio detection. Based on their characteristics, we implement several explainable artificial intelligence (XAI) methods used for image classification on an audio-related task. In addition, by examining the human cognitive process of XAI on image classification, we suggest the use of a corresponding data format for providing interpretability. Using this novel concept, a fresh interpretation using attribution scores can be provided.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Moreover, the image-based methods outperformed feature-based techniques, including those that made use of characteristics related to energy, bandwidth, frequency, and short-term transform features like MFCCs, for the identification of synthetic audio [72, 73].”
From Attention-based Multimodal learning framework for Generalized Audio-Visual Deepfake Detection (2023) · cites this paper as [73]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Lim et al. [85] used layer-wise relevance propagation (LRP) and Deep Taylor Decomposition to explain predictions in spectrogram-based detection models.”
From Deepfake Media Forensics: Status and Future Challenges (2025) · cites this paper as [85]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Axiomatic attribution for deep networks
Sundararajan, M., Taly, A., & Yan, Q. (2017) · arXiv · doi:10.48550/arxiv.1703.01365 · Cited by 4,087 · cited 2×
“With the path integral formulation, integrated gradients can satisfy the axioms and properly calculate the attribution score [13].”
MethodConformer: Convolution-augmented Transformer for Speech Recognition
Gulati, A., Qin, J., Chiu, C.-C., Parmar, N., Zhang, Y., Yu, J., Han, W., Wang, S., Zhang, Z., Wu, Y., et al. (2020) · Interspeech 2020 · doi:10.21437/interspeech.2020-3015 · Cited by 3,150
Conformer: Convolution-augmented Transformer for Speech Recognition
Gulati, A., Qin, J., Chiu, C.-C., Parmar, N., Zhang, Y., Yu, J., Han, W., Wang, S., Zhang, Z., Wu, Y., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.08100 · Cited by 3,150
Natural TTS Synthesis by Conditioning Wavenet on MEL Spectrogram Predictions
Shen, J., Pang, R., Weiss, R. J., Schuster, M., Jaitly, N., Yang, Z., Chen, Z., Zhang, Y., Wang, Y., Skerrv-Ryan, R., et al. (2018) · 2018 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2018.8461368 · Cited by 2,791
X-Vectors: Robust DNN Embeddings for Speaker Recognition
Snyder, D., Garcia-Romero, D., Sell, G., Povey, D., & Khudanpur, S. (2018) · 2018 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2018.8461375 · Cited by 2,620 · cited 1×
“Tasks, such as speaker verification, use x-vector or d-vector to make the process efficient [6,7].”
Methodwav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations
Baevski, A., Zhou, H., Mohamed, A., & Auli, M. (2020) · arXiv · doi:10.48550/arxiv.2006.11477 · Cited by 2,369 · cited 2×
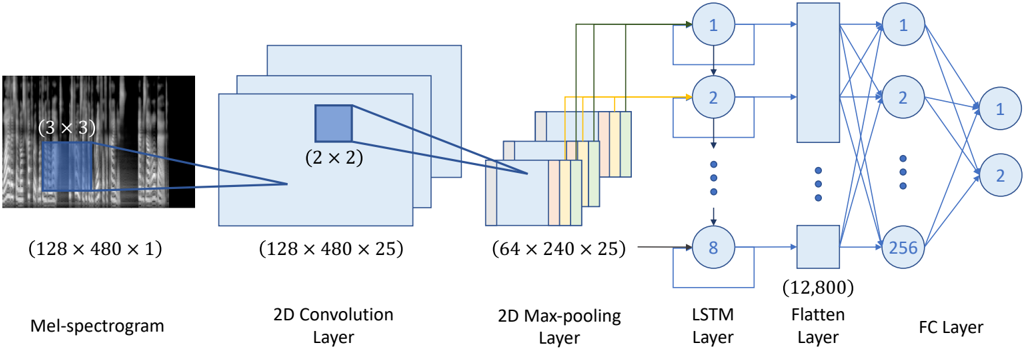
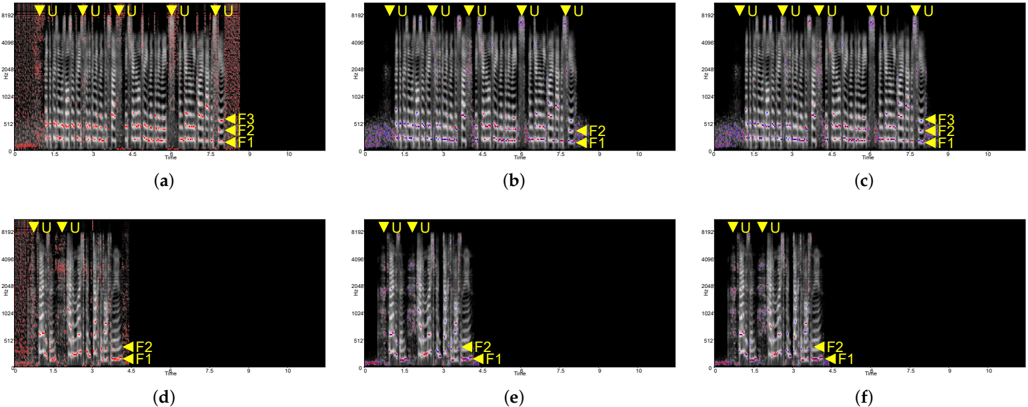
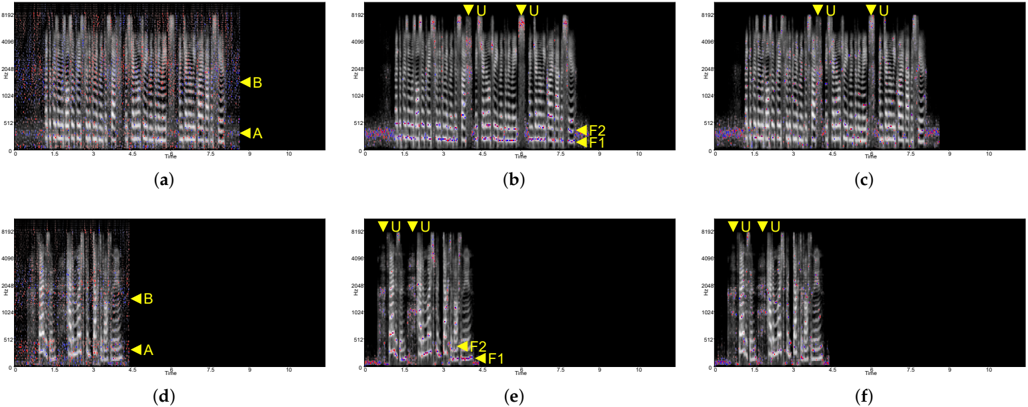
“In the case of the recomposed voice of Deep Taylor and LRP on the CNN-LSTM model, because of the lack of sensitivity on formants 1, 2, and 3, the transcript of the speech was unrecognizable.”
MethodSignal estimation from modified short-time Fourier transform
Griffin, D., & Lim, J. (1984) · IEEE Transactions on Acoustics, Speech, and Signal Processing · doi:10.1109/tassp.1984.1164317 · Cited by 2,095
Explaining nonlinear classification decisions with deep taylor decomposition
Montavon, G., Lapuschkin, S., Binder, A., Samek, W., & Müller, K.-R. (2017) · Pattern Recognition · doi:10.1016/j.patcog.2016.11.008 · Cited by 1,357
Speech-Transformer: A No-Recurrence Sequence-to-Sequence Model for Speech Recognition
Dong, L., Xu, S., & Xu, B. (2018) · 2018 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2018.8462506 · Cited by 1,100
Deep neural networks for small footprint text-dependent speaker verification
Variani, E., Lei, X., McDermott, E., Moreno, I. L., & Gonzalez-Dominguez, J. (2014) · 2014 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2014.6854363 · Cited by 1,035
ASVspoof 2019: A large-scale public database of synthesized, converted and replayed speech
Wang, X., Yamagishi, J., Todisco, M., Delgado, H., Nautsch, A., Evans, N., Sahidullah, M., Vestman, V., Kinnunen, T., Lee, K. A., et al. (2020) · Computer Speech & Language · doi:10.1016/j.csl.2020.101114 · Cited by 505
The deepfake detection challenge (dfdc) dataset
Dolhansky, B., Bitton, J., Pflaum, B., Lu, J., Howes, R., Wang, M., & Ferrer, C. C. (2020) · arXiv · doi:10.48550/arxiv.2006.07397 · Cited by 427
Speech Emotion Recognition From 3D Log-Mel Spectrograms With Deep Learning Network
Meng, H., Yan, T., Yuan, F., & Wei, H. (2019) · IEEE Access · doi:10.1109/access.2019.2938007 · Cited by 356 · cited 1×
“For a human voice, the analysis is made using a mel spectrogram, which filters the spectrogram through a mel filterbank to emphasize low-frequency spectra in which most of the energy is concentrated [15].”
MethodA practical comparison of manual and autonomous methods for acoustic monitoring
Digby, A., Towsey, M., Bell, B. D., & Teal, P. D. (2013) · Methods in Ecology and Evolution · doi:10.1111/2041-210x.12060 · Cited by 266 · cited 1×
“For human manual analysis, visualized audio data in the form of a spectrogram is traditionally used [16].”
MethodIto, K. A. (2024) · TIB Data Manager · doi:10.57702/yamk7ojd · Cited by 259
i-vector based speaker recognition on short utterances
Kanagasundaram, A., Vogt, R., Dean, D., Sridharan, S., & Mason, M. (2011) · Interspeech 2011 · doi:10.21437/interspeech.2011-58 · Cited by 234 · cited 2×
“Tasks, such as speaker verification, use x-vector or d-vector to make the process efficient [6,7].”
BackgroundJoint Audio-Visual Deepfake Detection
Zhou, Y., & Lim, S.-N. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.01453 · Cited by 217 · cited 1×
“Although there has been attempt to joint both visual and audio data to detect the deepfake, the interpretation on the model has not been tried [17].”
BackgroundSelf-citationNam, W.-J., Gur, S., Choi, J., Wolf, L., & Lee, S.-W. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i03.5632 · Cited by 98
Self-citationExplainable Deep-Fake Detection Using Visual Interpretability Methods
Malolan, B., Parekh, A., & Kazi, F. (2020) · 2020 3rd International Conference on Information and Computer Technologies (ICICT) · doi:10.1109/icict50521.2020.00051 · Cited by 70 · cited 3×
“However, contemporary research on explainable deepfake detection is not extensive and is limited to visual deepfake detection [2].”
BackgroundMethodExplaining CNN and RNN Using Selective Layer-Wise Relevance Propagation
Jung, Y.-J., Han, S.-H., & Choi, H.-J. (2021) · IEEE Access · doi:10.1109/access.2021.3051171 · Cited by 68 · cited 1×
“mentioned, the methods show limitations: high noise of heatmap output and lack of class-discriminativeness [19].”
MethodLayer-Wise Relevance Propagation for Explainable Deep Learning Based Speech Recognition
Bharadhwaj, H. (2018) · IEEE International Symposium on Signal Processing and Information Technology (ISSPIT) · doi:10.1109/isspit.2018.8642691 · Cited by 26 · cited 2×
“A study by Bharadhwaj suggested a bidirectional-GRU-based model built for the implementation of XAI methods and finding the relevance score for each input [11].”
Method
Research works printed but not linked: 2
- Bracewell, R.N., and Bracewell, R.N. (1986). The Fourier Transform and Its Applications, McGraw-Hill.
- Becker, S., Ackermann, M., Lapuschkin, S., Müller, K.R., and Samek, W. (2018). Interpreting and explaining deep neural networks for classification of audio signals. arXiv.
Cited by
A., S., & R., S. (2023) · Decision Analytics Journal · doi:10.1016/j.dajour.2023.100230 · Cited by 432
ŞAHiN, E., Arslan, N. N., & Özdemir, D. (2025) · Neural Computing and Applications · doi:10.1007/s00521-024-10437-2 · Cited by 278
What is Human-Centered about Human-Centered AI? A Map of the Research Landscape
Capel, T., & Brereton, M. (2023) · Proceedings of the 2023 CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544548.3580959 · Cited by 228
“The importance of interpretability was particularly prevalent in contexts such as child welfare screening [326], education [5, 7], medicine and healthcare [95, 196, 246], fnance [80, 186], fraud detection in digital retailing and banking [65], manufacturing [158, 236], media [170, 264], autonomous vehicles [280, 294],…”
BackgroundRecent Applications of Explainable AI (XAI): A Systematic Literature Review
Saarela, M., & Podgorelec, V. (2024) · Applied Sciences · doi:10.3390/app14198884 · Cited by 183
Understanding Human-Centred AI: a review of its defining elements and a research agenda
Schmager, S., Pappas, I. O., & Vassilakopoulou, P. (2025) · Behaviour and Information Technology · doi:10.1080/0144929x.2024.2448719 · Cited by 254
Metadata
- Authors
- Lim, S.-Y., Chae, D.-K., & Lee, S.-C.
- Affiliations
- Hanyang University (KR)
- Division of Nanotechnology, Daegu Gyeongbuk Institute of Science & Technology (DGIST), Deagu 42988, Korea
- ORCID
- Chae, Dong-Kyu
- Venue
- Applied Sciences
- Publisher
- MDPI AG
- Published
- 2022-04-13
- Volume
- 12
- Issue
- 8
- Pages
- 3926
- ISSN
- 2076-3417 (ISSN-L)
- OpenAlex
- W4223915588
- Cited by
- 82
- References
- 17
- Citations by year
- 2026: 17 · 2025: 31 · 2024: 23 · 2023: 10 · 2022: 1
- FWCI
- 5.35
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Applied Sciences (publishedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Korea government(MSIT) (No.2020-0- 378 01373)
- Korean government (MSIT) (No. NRF-2021M3E5D2A01021156)
- Ministry of Science and ICT of KOREA (21-IT-10-03)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Explainable Artificial Intelligence (XAI)
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Digital Media Forensic Detection
- Physical Sciences › Computer Science › Artificial Intelligence › Speech Recognition and Synthesis
- Keywords
- deepfake detection, explainable AI, audio forensics, interpretability, fake media, audio classification
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
