

The DOI matches its Crossref record; 22 of the 22 references it cites were found in a registry or an index.
PCT: Point cloud transformer
Open accessAbstract
The irregular domain and lack of ordering make it challenging to design deep neural networks for point cloud processing. This paper presents a novel framework named Point Cloud Transformer (PCT) for point cloud learning. PCT is based on Transformer, which achieves huge success in natural language processing and displays great potential in image processing. It is inherently permutation invariant for processing a sequence of points, making it well-suited for point cloud learning. To better capture local context within the point cloud, we enhance input embedding with the support of farthest point sampling and nearest neighbor search. Extensive experiments demonstrate that the PCT achieves the state-of-the-art performance on shape classification, part segmentation, semantic segmentation, and normal estimation tasks.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
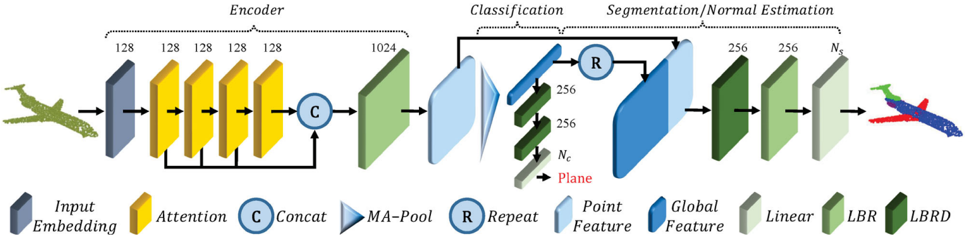
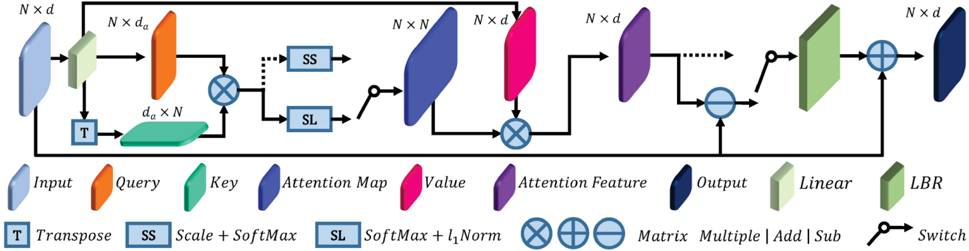
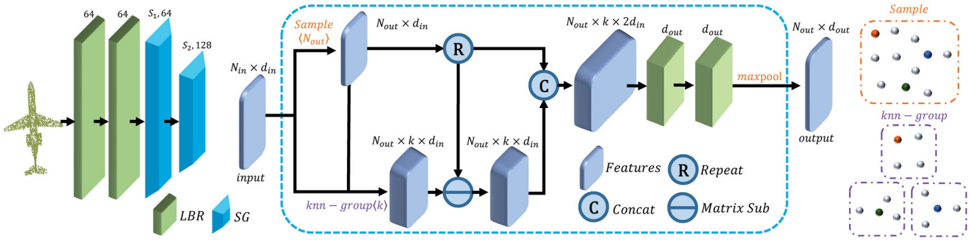
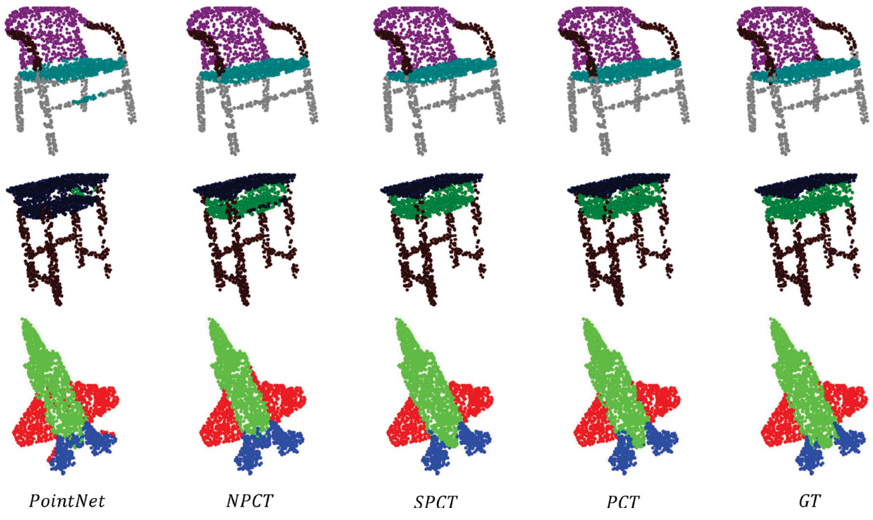
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Cross-lingual gap also should be considered for the transferability of Transformer based multimodal learning, e.g., universal cross-lingual generalization from English to non-English multimodal contexts [206], [277].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [277]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
End-to-End Object Detection with Transformers
Carion, N., Massa, F., Synnaeve, G., Usunier, N., Kirillov, A., & Zagoruyko, S. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58452-8_13 · Cited by 18,285
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,474
Squeeze-and-Excitation Networks
Hu, J., Shen, L., Albanie, S., Sun, G., & Wu, E. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2913372 · Cited by 12,157
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Dynamic Graph CNN for Learning on Point Clouds
Wang, Y., Sun, Y., Liu, Z., Sarma, S. E., Bronstein, M. M., & Solomon, J. M. (2019) · ACM Transactions on Graphics · doi:10.1145/3326362 · Cited by 7,199
Self-citationResidual Attention Network for Image Classification
Wang, F., Jiang, M., Qian, C., Yang, S., Li, C., Zhang, H., Wang, X., & Tang, X. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.683 · Cited by 4,073
Research works printed but not linked: 20
- Charles, R. Q.; Hao, S.; Mo, K. C.; Guibas, L. J. PointNet: Deep learning on point sets for 3D classification and segmentation. IN: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 77–85, 2017.
- Tchapmi, L. P.; Choy, C. B.; Armeni, I.; Gwak, J.; Savarese, S. SEGCloud: Semantic segmentation of 3D point clouds. In: Proceedings of the International Conference on 3D Vision, 537–547, 2017.
- Wu, W. X.; Qi, Z.; Fuxin, L. PointConv: Deep convolutional networks on 3D point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9613–9622, 2019.
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A. N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In: Proceedings of the 31st International Conference on Neural Information Processing, 6000–6010, 2017.
- Bruna, J.; Zaremba, W.; Szlam, A.; LeCun, Y. Spectral networks and locally connected networks on graphs. In: Proceedings of the International Conference on Learning Representations, 2014.
- Hu, S.-M.; Liang, D.; Yang, G.-Y.; Yang, G.-W.; Zhou, W.-Y. Jittor: A novel deep learning framework with meta-operators and unified graph execution. Science China Information Sciences Vol. 63, No. 12, Article No. 222103, 2020.
- Bahdanau, D.; Cho, K. H.; Bengio, Y. Neural machine translation by jointly learning to align and translate. In: Proceedings of the 3rd International Conference on Learning Representations, 2015.
- Lin, Z.; Feng, M.; dos Santos, C. N.; Yu, M.; Xiang, B.; Zhou, B.; Bengio, Y. A structured self-attentive sentence embedding. In: Proceedings of the International Conference on Learning Representations, 2017.
- Yang, Z.; Dai, Z.; Yang, Y.; Carbonell, J. G.; Salakhutdinov, R.; Le, Q. V. XLNet: Generalized autoregressive pretraining for language understanding. In: Proceedings of the 33rd Conference on Neural Information Processing Systems, 5754–5764, 2019.
- Qi, C. R.; Yi, L.; Su, H.; Guibas, L. J. PointNet++: Deep hierarchical feature learning on point sets in a metric space. In: Proceedings of the 31st Conference on Neural Information Processing Systems, 5099–5108, 2017.
- Yang, Y. Q.; Liu, S. L.; Pan, H.; Liu, Y.; Tong, X. PFCNN: Convolutional neural networks on 3D surfaces using parallel frames. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 13575–13584, 2020.
- Yan, X.; Zheng, C. D.; Li, Z.; Wang, S.; Cui, S. G. PointASNL: Robust point clouds processing using nonlocal neural networks with adaptive sampling. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 5588–5597, 2020.
- Hertz, A.; Hanocka, R.; Giryes, R.; Cohen-Or, D. PointGMM: A neural GMM network for point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 12051–12060, 2020.
- Wang, Y.; Solomon, J. Deep closest point: Learning representations for point cloud registration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 3522–3531, 2019.
- Li, J. X.; Chen, B. M.; Lee, G. H. SO-net: Self-organizing network for point cloud analysis. In: Proceeding of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9397–9406, 2018.
- Klokov, R.; Lempitsky, V. Escape from cells: Deep kdnetworks for the recognition of 3D point cloud models. In: Proceeding of the IEEE International Conference on Computer Vision, 863–872, 2017.
- Le, T.; Duan, Y. PointGrid: A deep network for 3D shape understanding. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9204–9214, 2018.
- Zhao, H.; Jiang, L.; Fu, C.; Jia, J. PointWeb: Enhancing local neighborhood features for point cloud processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 5560–5568, 2019.
- Komarichev, A.; Zhong, Z. C.; Hua, J. A-CNN: Annularly convolutional neural networks on point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 7413–7422, 2019.
- Thomas, H.; Qi, C. R.; Deschaud, J. E.; Marcotegui, B.; Goulette, F.; Guibas, L. KPConv: Flexible and deformable convolution for point clouds. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 6410–6419, 2019.
Cited by
Sorted by citations
Items 901–1,000 of 1,001
Corrupted point cloud classification based on feature compensation and cross attention mechanism
He, Y., Yang, H., Li, Z., Wu, M., Liu, J., & Zhang, Z. (2024) · Measurement · doi:10.1016/j.measurement.2024.115721 · Cited by 5
LET-UP: A Lightweight, Efficient Binarized Transformer for Point Cloud Upsampling
Zhu, Y., Zhang, Z., Liu, R., Zhang, J., Cheng, X., & Chen, S. (2024) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2024.3476569 · Cited by 6
Subdivision of Adjacent Areas for 3D Point Cloud Semantic Segmentation
Xu, H., Hu, K., Xu, Y., & Zhu, J. (2024) · Signal Image and Video Processing · doi:10.1007/s11760-024-03728-7 · Cited by 5
Multi-stage refinement network for point cloud completion based on geodesic attention
Chang, Y., & Wang, K. (2025) · Scientific Reports · doi:10.1038/s41598-025-86704-6 · Cited by 5
FACNet: Feature Alignment Fast Point Cloud Completion Network
Yu, X., Li, J., Wong, C.-C., Vong, C., & Liang, Y. (2025) · Computational Visual Media · doi:10.26599/cvm.2025.9450449 · Cited by 5
3D Part Segmentation via Geometric Aggregation of 2D Visual Features
Garosi, M., Tedoldi, R., Boscaini, D., Mancini, M., Sebe, N., & Poiesi, F. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00322 · Cited by 8
Multi-level feature fusion parallel branching networks for point cloud learning
Yan, B., Tao, Z., Lin, S., & Li, H. (2025) · Computers & Graphics · doi:10.1016/j.cag.2025.104221 · Cited by 5
Adaptive token selection for scalable point cloud transformers
Baiocchi, A., Spinelli, I., Nicolosi, A., & Scardapane, S. (2025) · Neural Networks · doi:10.1016/j.neunet.2025.107477 · Cited by 5
GeoContrast: Geometric knowledge-based contrast learning for industrial point cloud segmentation
Wang, X., Liu, Y., Wang, Y., Li, Y., & Zhang, D. (2025) · Measurement · doi:10.1016/j.measurement.2025.118204 · Cited by 5
Millionfold accelerated AI solver for 3D multi-physical simulations of ultrapermeable membranes
Liu, Y., Luo, J. L., Huang, M., Liu, H., Wang, Z., & Heng, Y. (2025) · npj Clean Water · doi:10.1038/s41545-025-00491-1 · Cited by 5
Automatic Point Cloud Patching of Intraoral Three-Dimensional Scanning Based on Deep Learning
Zheng, Q., Wang, Y., Zhou, M., Wu, Y., Chen, J., Wang, X., Gao, L., Kang, T., Chen, X., & Zhang, W. (2025) · International Dental Journal · doi:10.1016/j.identj.2025.100911 · Cited by 5
Multiscale Balanced-Attention Interactive Network for Salient Object Detection
Yang, H., Chen, R., & Deng, D. (2022) · Mathematics · doi:10.3390/math10030512 · Cited by 5
A Two-Stage Correspondence-Free Algorithm for Partially Overlapping Point Cloud Registration
Zhang, W., Zhang, Y., & Li, J. (2022) · Sensors · doi:10.3390/s22135023 · Cited by 5
CGR-Block: Correlated Feature Extractor and Geometric Feature Fusion for Point Cloud Analysis
Wang, F., Zhao, Y., Shi, G., Cui, Q., Cao, T., Jiang, X., Hou, Y., Zhuang, R., & Mei, Y. (2022) · Sensors · doi:10.3390/s22134878 · Cited by 4
Image classification based on self-distillation
Li, Y., Qing, L., He, X., Chen, H., & Liu, Q. (2022) · Applied Intelligence · doi:10.1007/s10489-022-04008-y · Cited by 5
A Novel Point Cloud Registration Method Based on ROPNet
Li, Y., Yang, F., & Zheng, W. (2023) · Sensors · doi:10.3390/s23020993 · Cited by 5
SWPT: Spherical Window-Based Point Cloud Transformer
Guo, X., Sun, Y. T., Zhao, R., Kuang, L., & Han, X. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-26319-4_24 · Cited by 5
Chen, H., & Zhao, J. (2023) · Journal of King Saud University - Computer and Information Sciences · doi:10.1016/j.jksuci.2023.03.024 · Cited by 5
Deng, Y., Yin, L., Gao, X., Zhou, H. M., Wang, Z., & Zou, G. (2023) · Multimedia Systems · doi:10.1007/s00530-023-01100-2 · Cited by 5
Point Cloud Transformer (PCT) for 3D-InISAR Automatic Target Recognition
Meucci, G., Mancuso, F., Giusti, E., Kumar, A., Ghio, S., & Martorella, M. (2023) · IEEE Radar Conference (RadarConf) · doi:10.1109/radarconf2351548.2023.10149787 · Cited by 6
Slice Transformer and Self-supervised Learning for 6DoF Localization in 3D Point Cloud Maps
Ibrahim, M., Akhtar, N., Anwar, S., Wise, M. J., & Mian, A. S. (2023) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra48891.2023.10161128 · Cited by 5
Multi-scale Geometry-aware Self-Attention for 3D Point Cloud Classification
Heng, C., Haitao, Z., Yang, J., Baochang, D., & Yuhang, J. (2023) · IEEE International Conference on Electronic Technology, Communication and Information (ICETCI) · doi:10.1109/icetci57876.2023.10176645 · Cited by 5
A dynamic learning framework integrating attention mechanism for point cloud registration
Li, C., Guan, Y., Yang, S., & Li, Y. (2023) · The Visual Computer · doi:10.1007/s00371-023-03118-z · Cited by 5
Steerable Graph Neural Network on Point Clouds via Second-Order Random Walks
Guo, X., Wang, Y., Liu, H., Xie, H., Cheng, G., & Wang, F. L. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3330338 · Cited by 5
Cheng, L., Hao, R., Cheng, Z., Li, T., Wang, T., Lu, W., Ding, Y., & Hu, H. (2023) · Remote Sensing · doi:10.3390/rs15235434 · Cited by 5
WalkFormer: 3D mesh analysis via transformer on random walk
Guo, Q., He, F., Fan, B., Song, Y., Dai, J., & Fan, L. (2023) · Neural Computing and Applications · doi:10.1007/s00521-023-09279-1 · Cited by 5
Normal Transformer: Extracting Surface Geometry From LiDAR Points Enhanced by Visual Semantics
Lin, A., Li, J., Xiang, Y., Bian, W., & Prasad, M. (2024) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2024.3363174 · Cited by 5
Learning Geometric Information via Transformer Network for Key-Points Based Motion Segmentation
Li, Q., Cheng, J., Gao, Y., & Li, J. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3382363 · Cited by 5
Multi-Space Point Geometry Compression With Progressive Relation-Aware Transformer
Shen, W., Zhang, B., Xu, H., Li, X., & Wu, J. H. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3384057 · Cited by 5
HALNet: Partial Point Cloud Registration Based on Hybrid Attention and Deep Local Features
Wang, D., Hao, H., & Zhang, J. X. (2024) · Sensors · doi:10.3390/s24092768 · Cited by 5
Graph Attentive Dual Ensemble learning for Unsupervised Domain Adaptation on point clouds
Li, Q., Yan, C., Hao, Q., Peng, X., & Liu, L. (2024) · Pattern Recognition · doi:10.1016/j.patcog.2024.110690 · Cited by 5
Point cloud downsampling based on the transformer features
Dehghanpour, A., Sharifi, Z., & Dehyadegari, M. (2024) · The Visual Computer · doi:10.1007/s00371-024-03555-4 · Cited by 5
HQ-Net: A heatmap-based query backbone for point cloud understanding
Li, J., Guo, S., Wang, L., & Han, S. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.128413 · Cited by 5
DRGNet: Dual-Relation Graph Network for point cloud analysis
Zhou, C., & Ling, Q. (2024) · Journal of Visual Communication and Image Representation · doi:10.1016/j.jvcir.2024.104353 · Cited by 5
Yang, Z., Yu, Q. J., Zhan, Y., & Liu, J. (2024) · Machine Learning Science and Technology · doi:10.1088/2632-2153/ad9fcf · Cited by 5
MD-Mamba: Feature extractor on 3D representation with multi-view depth
Li, Q., Li, Z., Tian, L., Du, Q., & Lu, G. (2024) · Image and Vision Computing · doi:10.1016/j.imavis.2024.105396 · Cited by 5
EdgeFormer: local patch-based edge detection transformer on point clouds
Xie, Y., Tu, Z., Yang, T., Zhang, Y., & Zhou, X. (2024) · Pattern Analysis and Applications · doi:10.1007/s10044-024-01386-6 · Cited by 5
Rethinking Masked Representation Learning for 3D Point Cloud Understanding
Wang, C., Zha, Y., He, J., Yang, W., & Zhang, T. (2024) · IEEE Transactions on Image Processing · doi:10.1109/tip.2024.3520008 · Cited by 8
SCAGAN: Wireless Capsule Endoscopy Lesion Image Generation Model Based on GAN
Xiao, Z., Zhang, D., Chen, X., & Li, D. (2025) · Electronics · doi:10.3390/electronics14030428 · Cited by 7
LAA: Local Awareness Attention for point cloud self-supervised representation learning
Yu, J., Wu, H., Shangguan, W., Niu, Y., & Huang, B. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.130365 · Cited by 5
Zhang, R., Jie, B., He, Y., & Wang, J. (2025) · Medical Image Analysis · doi:10.1016/j.media.2025.103653 · Cited by 5
BLNet: Bidirectional learning network for point clouds
Han, W., Wu, H. X., Wen, C., Wang, C., & Li, X. S. (2022) · Computational Visual Media · doi:10.1007/s41095-021-0260-6 · Cited by 5
Zhai, R., Zou, J., He, Y., & Meng, L. (2022) · ISPRS International Journal of Geo-Information · doi:10.3390/ijgi11030181 · Cited by 5
PAT: Point Cloud Analysis with Local Filter Embedding in Transformer
Li, X., Fan, S., Chen, Y., Liu, Y., Chen, S., Zhu, F., & Lv, Y. (2022) · IEEE International Conference on Intelligent Transportation Systems (ITSC) · doi:10.1109/itsc55140.2022.9922529 · Cited by 5
RS-TNet: point cloud transformer with relation-shape awareness for fine-grained 3D visual processing
Wang, X., Zeng, Y., Jin, Y., Cen, Y., Liu, B., & Wan, S. (2022) · Soft Computing · doi:10.1007/s00500-022-07543-5 · Cited by 5
Seleem, A., Guarda, A. F. R., Rodrigues, N. M. M., & Pereira, F. M. B. (2022) · IEEE International Symposium on Multimedia (ISM) · doi:10.1109/ism55400.2022.00016 · Cited by 5
Point MLP-Former: Combining Local and Global Receptive Fields in Point Cloud Classification
Cheng, L., An, C., Gao, Y., Gao, Y., & Ding, D. (2022) · China Automation Congress (CAC) · doi:10.1109/cac57257.2022.10055719 · Cited by 6
3D Tooth Mesh Segmentation with Simplified Mesh Cell Representation
Jana, A., Subhash, H. M., & Metaxas, D. (2023) · IEEE International Symposium on Biomedical Imaging (ISBI) · doi:10.1109/isbi53787.2023.10230650 · Cited by 5
Hybrid Cross-Feature Interaction Attention Module for Object Detection in Intelligent Mobile Scenes
Tian, D., Han, Y., Liu, Y., Li, J., Zhang, P., & Liu, M. (2023) · Remote Sensing · doi:10.3390/rs15204991 · Cited by 5
Liao, L., Wan, L., Liu, M., & Li, S. (2023) · China Automation Congress (CAC) · doi:10.1109/cac59555.2023.10450923 · Cited by 5
A Unified Framework for Human-centric Point Cloud Video Understanding
Xu, Y., Ye, K., Han, X., Ren, Y., Zhu, X., & Ma, Y. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00116 · Cited by 5
Survey on Multimodal Transformers for RobotsPreprint
Miyazawa, K., & Nagai, T. (2023) · doi:10.36227/techrxiv.21993317 · Cited by 5
Advancements in AI-Driven 3D Reality Capture: Transforming Architectural Digitisation and ModellingPreprint
Zhang, K., & Fassi, F. (2024) · Preprints.org · doi:10.20944/preprints202406.1162.v1 · Cited by 5
CAT: A Simple yet Effective Cross-Attention Transformer for One-Shot Object Detection
Lin, W.-D., Deng, Y., Gao, Y., Wang, N., Liu, L., Lei Zhang, A., & Wang, P. (2024) · Journal of Computer Science and Technology · doi:10.1007/s11390-024-1743-6 · Cited by 4
Prompt-guided and degradation prior supervised transformer for adverse weather image restoration
Liu, W., Shao, M., Meng, L., Qiao, Y., & Bao, Z. (2024) · Applied Intelligence · doi:10.1007/s10489-024-06050-4 · Cited by 4
Deep Point Cloud Edge Reconstruction via Surface Patch Segmentation
Li, Y., Wang, H., Liu, Y., Huang, J., Shun, L., Huang, C., Guo, J., Guo, J. J., & Guo, Y. (2025) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2025.3547411 · Cited by 4
Li, X., Li, F., Ding, Y., Sun, H., & Li, Z. (2025) · Computers and Electronics in Agriculture · doi:10.1016/j.compag.2025.110547 · Cited by 4
Zhang, Q., Wang, Q., Wang, N., Liu, J., & Qu, D. (2025) · Machine Vision and Applications · doi:10.1007/s00138-025-01715-7 · Cited by 4
PointMT: Efficient Point Cloud Analysis With Hybrid MLP-Transformer Architecture
Zheng, Q., Zhang, C., & Sun, J. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3581747 · Cited by 6
ToothAxis: Generalizable Tooth Axis Estimation Network From CBCT or IOS Models
Bao, N., Luo, Q., Wu, J., Cui, Z., & Zhao, Y. (2025) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2025.3590210 · Cited by 4
Zhang, Z., Dai, W., Wen, H., & Yang, B. (2025) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52734.2025.00136 · Cited by 4
Ji, T., & Zhang, D. (2025) · Sensors · doi:10.3390/s25185639 · Cited by 4
AGU-Net: advancing medical image segmentation with attention-guided U-Net architecture
Khader, S., & Ghnemat, R. (2025) · Cluster Computing · doi:10.1007/s10586-025-05781-4 · Cited by 4
A spatial-spectral multi-view contrastive learning framework for scene representation learning
Chen, J., Yu, X., Jiang, Z., Teng, Z., Wu, H., & Wu, C. (2025) · Information Fusion · doi:10.1016/j.inffus.2025.103889 · Cited by 4
Joint Semantic-Channel Coding and Modulation for Token Communications
Ying, J., Qin, Z., Feng, Y., Wang, L., & Tao, X. (2025) · IEEE Transactions on Wireless Communications · doi:10.1109/twc.2025.3636174 · Cited by 6
NPMFF-Net: A training-free unified framework for point cloud classification and segmentation
Zeng, H., Zhu, H., Yu, H., Liu, M., & An, N. (2025) · Knowledge-Based Systems · doi:10.1016/j.knosys.2025.114529 · Cited by 4
Yin, J., Zeng, P., Huang, Y., Sun, H., Zhong, J., Hao, T., & Lu, S. (2025) · Applied Energy · doi:10.1016/j.apenergy.2025.127289 · Cited by 4
Luo, Z., Zeng, T., Jiang, J., Cai, Z., Wu, W., Xie, Z., & Xu, Y. (2026) · Remote Sensing · doi:10.3390/rs18040552 · Cited by 4
AI-driven 3D point cloud analysis in plant phenotyping: A Systematic Review
Chang, J., Walsh, J., Mangina, E., Ruan, J., & Negrão, S. (2026) · Smart Agricultural Technology · doi:10.1016/j.atech.2026.101869 · Cited by 5
OG-PCL: Efficient Sparse Radar Point Cloud Processing for Human Activity Recognition
Yan, J., Wang, Y., Xu, C., & Liu, D. (2026) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp55912.2026.11462700 · Cited by 4
Conditional GAN for Point Cloud Generation
Yang, Z., Chen, Y., Zheng, X., Chang, Y., & Li, X. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-26293-7_8 · Cited by 4
3D Point Cloud Semantic Segmentation Based on Diffusion Model
Liu, C., Jiang, A., Tang, Y., Zhu, Y., & Chen, Q. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10447146 · Cited by 4
Hierarchical local global transformer for point clouds analysis
Li, D., Zheng, S., Chen, Z., Li, X., Wang, L., & Du, J. (2024) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2024.103813 · Cited by 4
Zero-Shot Detection of Buildings in Mobile LiDAR using Language Vision Model
Goo, J. M., Zeng, Z., & Boehm, J. (2024) · The international archives of the photogrammetry, remote sensing and spatial information sciences/International archives of the photogrammetry, remote sensing and spatial information sciences · doi:10.5194/isprs-archives-xlviii-2-2024-107-2024 · Cited by 4
Zhang, H., Hai, L., Wang, X., Wang, X., & Zhou, M. (2024) · Applied Soft Computing · doi:10.1016/j.asoc.2024.111839 · Cited by 4
Human identification based on sphenoid sinus in point cloud with geometric self-attention network
Li, X., Zou, R., & Chen, H. (2024) · Multimedia Tools and Applications · doi:10.1007/s11042-024-19541-w · Cited by 4
Guiding Attention in End-to-End Driving Models
Porres, D., Xiao, Y., Villalonga, G., Levy, A., & López, A. M. (2024) · IEEE Intelligent Vehicles Symposium · doi:10.1109/iv55156.2024.10588598 · Cited by 4
EGCT: enhanced graph convolutional transformer for 3D point cloud representation learning
Chen, G., Wang, W., Zhou, H., & Wang, X. (2024) · The Visual Computer · doi:10.1007/s00371-024-03600-2 · Cited by 4
Lee, D., Choi, A., & Mun, J. H. (2024) · Bioengineering · doi:10.3390/bioengineering11090941 · Cited by 4
ACLNet: A Deep Learning Model for ACL Rupture Classification Combined with Bone Morphology
Liu, C., Yu, X., Wang, D., & Jiang, T. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72086-4_6 · Cited by 4
UPose3D: Uncertainty-Aware 3D Human Pose Estimation with Cross-view and Temporal Cues
Davoodnia, V., Ghorbani, S., Carbonneau, M., Messier, A., & Etemad, A. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72640-8_2 · Cited by 8
Improving 3D Finger Traits Recognition via Generalizable Neural Rendering
Xu, H., Huang, J., Ma, Y., Li, Z., & Kang, W. (2024) · International Journal of Computer Vision · doi:10.1007/s11263-024-02248-8 · Cited by 4
Foundation Model-Powered 3D Few-Shot Class Incremental Learning via Training-Free Adaptor
Ahmadi, S., Cheraghian, A., Saberi, M., Abir, M. T., Dastmalchi, H., Hussain, F. K., & Rahman, S. (2024) · Lecture notes in computer science · doi:10.1007/978-981-96-0972-7_11 · Cited by 4
Chen, H., Zhao, S. G., Yan, Y., & Qian, F. (2024) · IEEE Signal Processing Letters · doi:10.1109/lsp.2024.3509335 · Cited by 4
Cross-Domain Incremental Feature Learning for ALS Point Cloud Semantic Segmentation With Few Samples
Dai, M., Xing, S., Xu, Q. Q., Li, P., Pan, J., & Wang, H. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3524212 · Cited by 6
Skeleton-Aware Radar-Based Gait Recognition Network With Cross-Modal Supervision
Liu, Z., Ma, C., Chen, K., & Liu, M. (2025) · IEEE Sensors Journal · doi:10.1109/jsen.2024.3523903 · Cited by 4
Self-citationLearnable Bi-directional Data Augmentation for few-shot cross-domain point cloud classification
Sun, X., Zhang, L., Xu, J., Yuan, J., & Chen, T. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.129486 · Cited by 4
Deep hierarchical learning on point clouds in feature space
Bu, L., Wang, Y., Ma, Q., Hou, Z., Wang, R., & Bu, F. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.129647 · Cited by 4
Thiruvananthapuram Aerial LiDAR Dataset (TALD): A Benchmark for Complex Urban Point Cloud
Vijaywargiya, J., & Ramiya, A. M. (2025) · IEEE Access · doi:10.1109/access.2025.3546628 · Cited by 4
Generating Transferable Adversarial Point Clouds via Autoencoders for 3D Object Classification
Xu, M., Hai, C., Zhang, C., Zou, Y., Xu, C., Zhang, Y., & Qian, F. (2025) · IET Computer Vision · doi:10.1049/cvi2.70008 · Cited by 4
Chen, Y., Wang, W., Chen, J., Deng, J., Xiang, Y., Qiao, B., Zhu, X., & Li, C. (2025) · Scientific Reports · doi:10.1038/s41598-025-92641-1 · Cited by 4
Collaborative point cloud geometry compression for both human vision and machine vision
Wang, D., Wang, J., Shi, Y., Yin, B., & Ling, N. (2025) · Multimedia Systems · doi:10.1007/s00530-025-01847-w · Cited by 4
Chen, Z., Liu, P., Gong, W., Lin, L., & Zhang, F. (2025) · Computers & Graphics · doi:10.1016/j.cag.2025.104346 · Cited by 4
Mahajan, S. N., Karthik Krishna, M., & Muthuganapathy, R. (2025) · Computers & Graphics · doi:10.1016/j.cag.2025.104357 · Cited by 4
Wang, X., Xie, L., Li, C., Wang, M., Liu, Z., Peng, X., & Wang, Z. (2025) · Multimedia Systems · doi:10.1007/s00530-025-01925-z · Cited by 4
Self-citationFeature-guided multilayer encoding–decoding network for segmentation for 3D intraoral scan data
Ma, T., Wei, X., Zhai, J., Zhang, Z., Li, Y., & Li, Y. (2025) · Scientific Reports · doi:10.1038/s41598-025-16360-3 · Cited by 4
An efficient point cloud registration method based on deep learning framework
Dongfeng, 贾. J., Liu, Y., & Lishuo, 张. Z. (2025) · GEOMATICA · doi:10.1016/j.geomat.2025.100072 · Cited by 4
Zhang, F., Mao, S., Li, Q., & Peng, X. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.130425 · Cited by 4
Transferable and undefendable point cloud attacks via medial axis transform
Tang, K., Gao, Y., Peng, W., Wang, X., Fang, M., & Zhu, P. (2026) · Computer Aided Geometric Design · doi:10.1016/j.cagd.2026.102515 · Cited by 4
Liu, Q., Jiang, N., Lu, J., Chen, M., Yi, R., & Ma, L. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3548354 · Cited by 4
Metadata
- Authors
- Guo, M.-H., Cai, J.-X., Liu, Z.-N., Mu, T.-J., Martin, R. R., & Hu, S.-M.
- Affiliations
- Tsinghua University (CN)
- Cardiff University (GB)
- Venue
- Computational Visual Media
- Publisher
- Tsinghua University Press
- Published
- 2021-06
- Volume
- 7
- Issue
- 2
- Pages
- 187-199
- ISSN
- 2096-0433 (ISSN-L)
- 2096-0662
- OpenAlex
- W3111535274
- Cited by
- 2,100
- References
- 17
- Citations by year
- 2026: 309 · 2025: 505 · 2024: 515 · 2023: 428 · 2022: 266 · 2021: 76
- FWCI
- 182.77
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Computational Visual Media (publishedVersion, cc-by)
- ORCA Online Research @Cardiff (Cardiff University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Deutsche Forschungsgemeinschaft
- National Natural Science Foundation of China (61761136018, 61521002)
- Topics
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- point cloud processing, point cloud transformer, transformer models, permutation invariance, farthest point sampling, nearest neighbor search, shape classification, part segmentation, semantic segmentation, surface normal estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
