

The DOI matches its Crossref record; 22 of the 22 references it cites were found in a registry or an index.
PCT: Point cloud transformer
Open accessAbstract
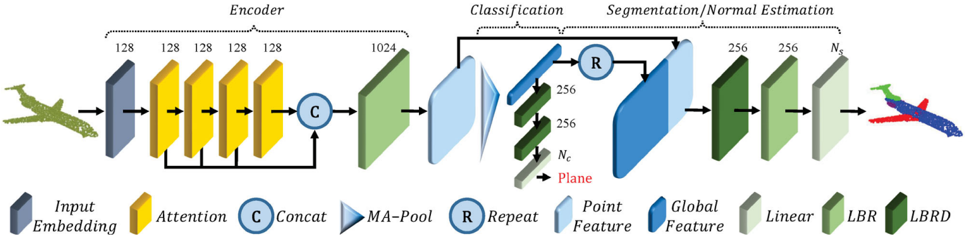
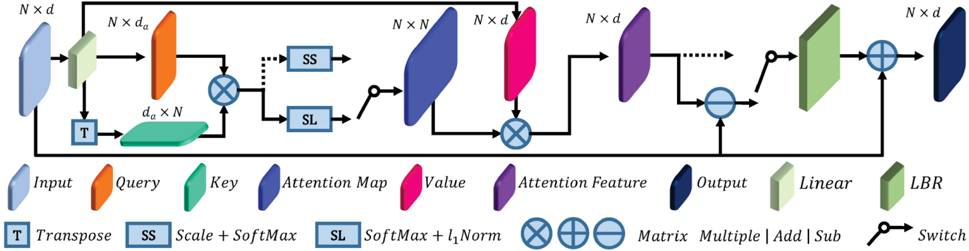
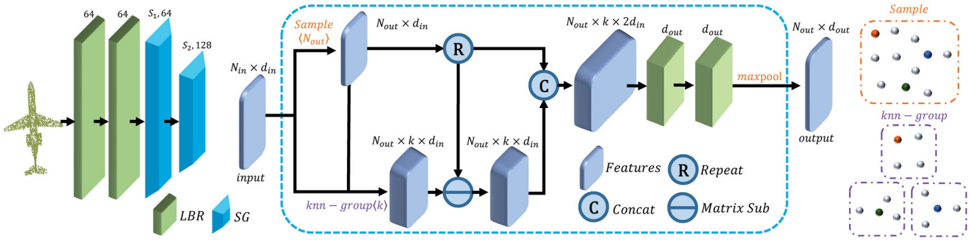
The irregular domain and lack of ordering make it challenging to design deep neural networks for point cloud processing. This paper presents a novel framework named Point Cloud Transformer (PCT) for point cloud learning. PCT is based on Transformer, which achieves huge success in natural language processing and displays great potential in image processing. It is inherently permutation invariant for processing a sequence of points, making it well-suited for point cloud learning. To better capture local context within the point cloud, we enhance input embedding with the support of farthest point sampling and nearest neighbor search. Extensive experiments demonstrate that the PCT achieves the state-of-the-art performance on shape classification, part segmentation, semantic segmentation, and normal estimation tasks.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Cross-lingual gap also should be considered for the transferability of Transformer based multimodal learning, e.g., universal cross-lingual generalization from English to non-English multimodal contexts [206], [277].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [277]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
End-to-End Object Detection with Transformers
Carion, N., Massa, F., Synnaeve, G., Usunier, N., Kirillov, A., & Zagoruyko, S. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58452-8_13 · Cited by 18,285
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,474
Squeeze-and-Excitation Networks
Hu, J., Shen, L., Albanie, S., Sun, G., & Wu, E. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2913372 · Cited by 12,157
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Dynamic Graph CNN for Learning on Point Clouds
Wang, Y., Sun, Y., Liu, Z., Sarma, S. E., Bronstein, M. M., & Solomon, J. M. (2019) · ACM Transactions on Graphics · doi:10.1145/3326362 · Cited by 7,199
Self-citationResidual Attention Network for Image Classification
Wang, F., Jiang, M., Qian, C., Yang, S., Li, C., Zhang, H., Wang, X., & Tang, X. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.683 · Cited by 4,073
Research works printed but not linked: 20
- Charles, R. Q.; Hao, S.; Mo, K. C.; Guibas, L. J. PointNet: Deep learning on point sets for 3D classification and segmentation. IN: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 77–85, 2017.
- Tchapmi, L. P.; Choy, C. B.; Armeni, I.; Gwak, J.; Savarese, S. SEGCloud: Semantic segmentation of 3D point clouds. In: Proceedings of the International Conference on 3D Vision, 537–547, 2017.
- Wu, W. X.; Qi, Z.; Fuxin, L. PointConv: Deep convolutional networks on 3D point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9613–9622, 2019.
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A. N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In: Proceedings of the 31st International Conference on Neural Information Processing, 6000–6010, 2017.
- Bruna, J.; Zaremba, W.; Szlam, A.; LeCun, Y. Spectral networks and locally connected networks on graphs. In: Proceedings of the International Conference on Learning Representations, 2014.
- Hu, S.-M.; Liang, D.; Yang, G.-Y.; Yang, G.-W.; Zhou, W.-Y. Jittor: A novel deep learning framework with meta-operators and unified graph execution. Science China Information Sciences Vol. 63, No. 12, Article No. 222103, 2020.
- Bahdanau, D.; Cho, K. H.; Bengio, Y. Neural machine translation by jointly learning to align and translate. In: Proceedings of the 3rd International Conference on Learning Representations, 2015.
- Lin, Z.; Feng, M.; dos Santos, C. N.; Yu, M.; Xiang, B.; Zhou, B.; Bengio, Y. A structured self-attentive sentence embedding. In: Proceedings of the International Conference on Learning Representations, 2017.
- Yang, Z.; Dai, Z.; Yang, Y.; Carbonell, J. G.; Salakhutdinov, R.; Le, Q. V. XLNet: Generalized autoregressive pretraining for language understanding. In: Proceedings of the 33rd Conference on Neural Information Processing Systems, 5754–5764, 2019.
- Qi, C. R.; Yi, L.; Su, H.; Guibas, L. J. PointNet++: Deep hierarchical feature learning on point sets in a metric space. In: Proceedings of the 31st Conference on Neural Information Processing Systems, 5099–5108, 2017.
- Yang, Y. Q.; Liu, S. L.; Pan, H.; Liu, Y.; Tong, X. PFCNN: Convolutional neural networks on 3D surfaces using parallel frames. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 13575–13584, 2020.
- Yan, X.; Zheng, C. D.; Li, Z.; Wang, S.; Cui, S. G. PointASNL: Robust point clouds processing using nonlocal neural networks with adaptive sampling. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 5588–5597, 2020.
- Hertz, A.; Hanocka, R.; Giryes, R.; Cohen-Or, D. PointGMM: A neural GMM network for point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 12051–12060, 2020.
- Wang, Y.; Solomon, J. Deep closest point: Learning representations for point cloud registration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 3522–3531, 2019.
- Li, J. X.; Chen, B. M.; Lee, G. H. SO-net: Self-organizing network for point cloud analysis. In: Proceeding of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9397–9406, 2018.
- Klokov, R.; Lempitsky, V. Escape from cells: Deep kdnetworks for the recognition of 3D point cloud models. In: Proceeding of the IEEE International Conference on Computer Vision, 863–872, 2017.
- Le, T.; Duan, Y. PointGrid: A deep network for 3D shape understanding. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9204–9214, 2018.
- Zhao, H.; Jiang, L.; Fu, C.; Jia, J. PointWeb: Enhancing local neighborhood features for point cloud processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 5560–5568, 2019.
- Komarichev, A.; Zhong, Z. C.; Hua, J. A-CNN: Annularly convolutional neural networks on point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 7413–7422, 2019.
- Thomas, H.; Qi, C. R.; Deschaud, J. E.; Marcotegui, B.; Goulette, F.; Guibas, L. KPConv: Flexible and deformable convolution for point clouds. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 6410–6419, 2019.
Cited by
Sorted by citations
Items 101–200 of 1,001
Zhang, Z., Ji, A., Wang, K., & Zhang, L. (2022) · Automation in Construction · doi:10.1016/j.autcon.2022.104456 · Cited by 79
Transformers in Single Object Tracking: An Experimental Survey
Kugarajeevan, J., Thanikasalam, K., Ramanan, A., & Fernando, S. (2023) · IEEE Access · doi:10.1109/access.2023.3298440 · Cited by 89
Improving Graph Representation for Point Cloud Segmentation via Attentive Filtering
Zhang, N., Pan, Z., Li, T. H., Gao, W., & Li, G. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00126 · Cited by 78
Su, Y., Liu, W., Yuan, Z., Cheng, M., Zhang, Z., Shen, X., & Wang, C. (2021) · Pattern Recognition · doi:10.1016/j.patcog.2021.108372 · Cited by 76
Parameter-Efficient Person Re-Identification in the 3D Space
Zheng, Z., Wang, X., Zheng, N., & Yang, Y. (2022) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2022.3214834 · Cited by 83
Deforming Radiance Fields with Cages
Xu, T., & Harada, T. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19827-4_10 · Cited by 74
Recent Advancements in Learning Algorithms for Point Clouds: An Updated Overview
Camuffo, E., Mari, D., & Milani, S. (2022) · Sensors · doi:10.3390/s22041357 · Cited by 73
Tian, Y., Wang, J., Wang, Y., Zhao, C., Yao, F., & Wang, X. (2022) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2022.3197815 · Cited by 72
A Review of Deep Learning-Based Visual Multi-Object Tracking Algorithms for Autonomous Driving
Guo, S., Wang, S., Yang, Z., Wang, L., Zhang, H., Guo, P., Gao, Y., & Guo, J. (2022) · Applied Sciences · doi:10.3390/app122110741 · Cited by 73
GrowSP: Unsupervised Semantic Segmentation of 3D Point Clouds
Zhang, Z., Yang, B., Wang, B., & Li, B. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01690 · Cited by 71
Automated BIM generation for large-scale indoor complex environments based on deep learning
Mahmoud, M., Chen, W., Yang, Y., & Li, Y. (2024) · Automation in Construction · doi:10.1016/j.autcon.2024.105376 · Cited by 70
Radar Transformer: An Object Classification Network Based on 4D MMW Imaging Radar
Bai, J., Zheng, L., Li, S., Tan, B., Chen, S., & Huang, L. (2021) · Sensors · doi:10.3390/s21113854 · Cited by 74
External Attention Based TransUNet and Label Expansion Strategy for Crack Detection
Fang, J., Yang, C., Shi, Y., Wang, N., & Zhao, Y. (2022) · IEEE Transactions on Intelligent Transportation Systems · doi:10.1109/tits.2022.3154407 · Cited by 69
Point Cloud Completion Via Skeleton-Detail Transformer
Zhang, W., Zhou, H., Dong, Z., Liu, J., Yan, Q., & Xiao, C. (2022) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2022.3185247 · Cited by 72
GIFS: Neural Implicit Function for General Shape Representation
Ye, J., Chen, Y., Wang, N., & Wang, X. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01249 · Cited by 73
Cross-modal knowledge transfer for 3D point clouds via graph offset prediction
Zhang, H., Yu, L., Wang, G., Tian, S., Yu, Z., Li, W., & Ning, X. (2025) · Pattern Recognition · doi:10.1016/j.patcog.2025.111351 · Cited by 71
Large-scale point cloud semantic segmentation via local perception and global descriptor vector
Zeng, Z., Xu, Y., Xie, Z., Tang, W., Wan, J., & Wu, W. (2024) · Expert Systems with Applications · doi:10.1016/j.eswa.2024.123269 · Cited by 68
Zhang, H., Wang, C., Yu, L., Tian, S., Ning, X., & Rodrigues, J. J. P. C. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3374580 · Cited by 78
FFT-Based Dynamic Token Mixer for Vision
Tatsunami, Y., & Taki, M. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i14.29457 · Cited by 73
Cross self-attention network for 3D point cloud
Wang, G., Zhai, Q., & Liu, H. (2022) · Knowledge-Based Systems · doi:10.1016/j.knosys.2022.108769 · Cited by 67
Qu, W., Li, J., Zhang, R., Liu, S., & Bao, J. (2023) · Journal of Intelligent Manufacturing · doi:10.1007/s10845-023-02081-9 · Cited by 67
CLIP goes 3D: Leveraging Prompt Tuning for Language Grounded 3D Recognition
Hegde, D., Valanarasu, J. M. J., & Patel, V. M. (2023) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw60793.2023.00217 · Cited by 87
Real-Time 3D Single Object Tracking With Transformer
Shan, J., Zhou, S., Cui, Y., & Fang, Z. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3146714 · Cited by 66
Joint Semantic-Instance Segmentation Method for Intelligent Transportation System
Li, Y., Cai, J., Zhou, Q., & Lu, H. (2022) · IEEE Transactions on Intelligent Transportation Systems · doi:10.1109/tits.2022.3190369 · Cited by 65
Self-citationDeep Magnification-Flexible Upsampling Over 3D Point Clouds
Qian, Y., Hou, J., Kwong, S., & He, Y. (2021) · IEEE Transactions on Image Processing · doi:10.1109/tip.2021.3115385 · Cited by 71
Zou, L., Huang, Z., Gu, N., & Wang, G. (2022) · IEEE Transactions on Image Processing · doi:10.1109/tip.2022.3216980 · Cited by 62
Fan, H., Chang, X.-J., Zhang, W., Cheng, Y., Sun, Y., & Kankanhalli, M. (2022) · Computer Vision and Pattern Recognition · doi:10.1109/cvpr52688.2022.00627 · Cited by 64
CSDN: Cross-Modal Shape-Transfer Dual-Refinement Network for Point Cloud Completion
Zhu, Z., Nan, L., Xie, H., Chen, H., Wang, J., Wei, M., & Qin, J. (2023) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2023.3236061 · Cited by 67
Rani, A., Ortíz-Arroyo, D., & Durdevic, P. (2024) · Information Fusion · doi:10.1016/j.inffus.2024.102575 · Cited by 67
Point cloud-based dimensional quality assessment of precast concrete components using deep learning
Shu, J., Li, W., Zhang, C., Gao, Y., Xiang, Y., & Ma, L. (2023) · Journal of Building Engineering · doi:10.1016/j.jobe.2023.106391 · Cited by 60
StructFormer: Learning Spatial Structure for Language-Guided Semantic Rearrangement of Novel Objects
Liu, W., Paxton, C., Hermans, T., & Fox, D. (2022) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra46639.2022.9811931 · Cited by 59
Deep learning aided inverse design of the buckling-guided assembly for 3D frame structures
Jin, T., Cheng, X., Xu, S., Lai, Y., & Zhang, Y. (2023) · Journal of the Mechanics and Physics of Solids · doi:10.1016/j.jmps.2023.105398 · Cited by 62
LinK: Linear Kernel for LiDAR-based 3D Perception
Lu, T., Ding, X., Liu, H., Wu, G., & Wang, L. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00113 · Cited by 59
LEARD-Net: Semantic segmentation for large-scale point cloud scene
Zeng, Z., Xu, Y., Xie, Z., Tang, W., Wan, J., & Wu, W. (2022) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2022.102953 · Cited by 58
Deep-Learning-Based Point Cloud Semantic Segmentation: A Survey
Zhang, R., Wu, Y., Jin, W., & Meng, X. (2023) · Electronics · doi:10.3390/electronics12173642 · Cited by 62
Towards Large-Scale 3D Representation Learning with Multi-Dataset Point Prompt Training
Wu, X., Tian, Z., Wen, X., Peng, B., Liu, X., Yu, K., & Zhao, H. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01849 · Cited by 72
InterFusion: Interaction-based 4D radar and LiDAR fusion for 3D object detection
Wang, L., Zhang, X., Xv, B., Zhang, J., Fu, R., Wang, X., Zhu, L., Ren, H., Lu, P., Li, J., et al. (2022) · 2022 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · doi:10.1109/iros47612.2022.9982123 · Cited by 57
Point cloud transformers applied to collider physics
Mikuni, V., & Canelli, F. (2021) · Machine Learning Science and Technology · doi:10.1088/2632-2153/ac07f6 · Cited by 57
Laplacian2Mesh: Laplacian-Based Mesh Understanding
Dong, Q., Wang, Z., Li, M., Gao, J., Chen, S., Shu, Z., Xin, S., Tu, C., & Wang, W. (2023) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2023.3259044 · Cited by 57
FA-ResNet: Feature affine residual network for large-scale point cloud segmentation
Zhan, L., Li, W., & Min, W. (2023) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2023.103259 · Cited by 57
Boosting Monocular 3D Human Pose Estimation With Part Aware Attention
Xue, Y., Chen, J., Gu, X., Ma, H., & Ma, H. (2022) · IEEE Transactions on Image Processing · doi:10.1109/tip.2022.3182269 · Cited by 56
Joint-MAE: 2D-3D Joint Masked Autoencoders for 3D Point Cloud Pre-training
Guo, Z., Zhang, R., Qiu, L., Li, X., & Heng, P. (2023) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2023/88 · Cited by 56
MPCT: Multiscale Point Cloud Transformer With a Residual Network
Wu, Y., Liu, J., Gong, M., Liu, Z., Miao, Q., & Ma, W. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3312855 · Cited by 56
Self-citation3D Person Re-Identification Based on Global Semantic Guidance and Local Feature Aggregation
Wang, C., Ning, X., Li, W., Bai, X. P., & Gao, X. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3328712 · Cited by 58
Ejiyi, C. J., Qin, Z., Nnani, A. O., Deng, F., Ejiyi, T. U., Ejiyi, M. B., Agbesi, V. K., & Bamisile, O. (2023) · Computer Methods and Programs in Biomedicine Update · doi:10.1016/j.cmpbup.2023.100133 · Cited by 61
Deep learning in industrial machinery: A critical review of bearing fault classification methods
Rehman, A. U., Jiao, W., Jiang, Y., Wei, J., Sohaib, M., Sun, J., Shiju, E., Rehman, K. U., & Chi, Y. (2025) · Applied Soft Computing · doi:10.1016/j.asoc.2025.112785 · Cited by 59
SVASeg: Sparse Voxel-Based Attention for 3D LiDAR Point Cloud Semantic Segmentation
Zhao, L. F., Xu, S., Liu, L., Ming, D., & Tao, W. (2022) · Remote Sensing · doi:10.3390/rs14184471 · Cited by 54
Recursive-NeRF: An Efficient and Dynamically Growing NeRF
Yang, G., Zhou, W., Peng, H.-Y., Liang, D., Mu, T., & Hu, S. (2022) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2022.3204608 · Cited by 53
Self-citationLiu, B., Huang, H., Su, Y. Z., Chen, S., Li, Z., Chen, E., & Tian, X. (2022) · Remote Sensing · doi:10.3390/rs14225733 · Cited by 54
FBNet: Feedback Network for Point Cloud Completion
Yan, X., Yan, H., Wang, J., Du, H., Wu, Z., Xie, D., Pu, S., & Lu, L. P. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20086-1_39 · Cited by 54
Semi-supervised learning-based point cloud network for segmentation of 3D tunnel scenes
Ji, A., Zhou, Y., Zhang, L., Tiong, R. L. K., & Xue, X. (2022) · Automation in Construction · doi:10.1016/j.autcon.2022.104668 · Cited by 52
Self-supervised learning for point cloud data: A survey
Zeng, C., Wang, W., Nguyen, A., Xiao, J., & Yue, Y. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.121354 · Cited by 60
Tree species recognition from close-range sensing: A review
Chen, J., Liang, X., Liu, Z., Gong, W., Chen, Y., Hyyppa, J. M., Kukko, A., & Wang, Y. (2024) · Remote Sensing of Environment · doi:10.1016/j.rse.2024.114337 · Cited by 52
Self-citationLiu, Y., Guo, J., Beneš, B., Deußen, O., Zhang, X., & Huang, H. F. (2021) · ACM Transactions on Graphics · doi:10.1145/3478513.3480486 · Cited by 51
GLT-T: Global-Local Transformer Voting for 3D Single Object Tracking in Point Clouds
Nie, J., He, Z., Yang, Y., Gao, M., & Zhang, J. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i2.25287 · Cited by 53
Recent Advances and Perspectives in Deep Learning Techniques for 3D Point Cloud Data Processing
Ding, Z., Sun, Y., Xu, S., Pan, Y., Peng, Y., & Mao, Z. (2023) · Robotics · doi:10.3390/robotics12040100 · Cited by 55
Wang, X., Jin, Y., Cen, Y.-G., Wang, T., Tang, B., & Li, Y.-D. (2022) · IEEE transactions on multimedia · doi:10.1109/tmm.2023.3318073 · Cited by 54
Min, C., Xiao, L., Zhao, D., Nie, Y., & Dai, B. (2023) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2023.3322409 · Cited by 85
Yan, J., Tan, F., Li, C., Jin, S., Zhang, C., Gao, P., & Xu, W. (2024) · Computers and Electronics in Agriculture · doi:10.1016/j.compag.2024.108839 · Cited by 50
Masked Autoencoders in 3D Point Cloud Representation Learning
Jiang, J., Lu, X., Zhao, L., Dazeley, R., & Wang, M. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3314973 · Cited by 61
Point cloud transformers applied to collider physics
Mikuni, V. M., & Canelli, F. (2021) · Zurich Open Repository and Archive (University of Zurich) · doi:10.5167/uzh-211130 · Cited by 53
Zhang, H., Yang, D., Wang, H., Zhao, B., Lan, X., Ding, J., & Zheng, N. (2022) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2022.3142401 · Cited by 52
Zhou, Y., Ji, A., Zhang, L., & Xue, X. (2022) · Automation in Construction · doi:10.1016/j.autcon.2022.104667 · Cited by 47
MeshMAE: Masked Autoencoders for 3D Mesh Data Analysis
Liang, Y., Zhao, S., Yu, B., Zhang, J., & He, F. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20062-5_3 · Cited by 53
Jin, A., & Zeng, X. (2023) · Journal of Marine Science and Engineering · doi:10.3390/jmse11010069 · Cited by 47
Overlap-guided Gaussian Mixture Models for Point Cloud Registration
Mei, G., Poiesi, F., Saltori, C., Zhang, J., Ricci, E., & Sebe, N. (2023) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv56688.2023.00449 · Cited by 47
GRAB-Net: Graph-Based Boundary-Aware Network for Medical Point Cloud Segmentation
Liu, Y., Li, W., Liu, J., Chen, H., & Yuan, Y. (2023) · IEEE Transactions on Medical Imaging · doi:10.1109/tmi.2023.3265000 · Cited by 47
Exploring Hierarchical Spatial Layout Cues for 3D Point Cloud Based Scene Graph Prediction
Feng, M., Hou, H., Zhang, L., Guo, Y., Yu, H., Wang, Y., & Mian, A. S. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3277736 · Cited by 49
Noichl, F., Collins, F. C., Braun, A., & Borrmann, A. (2024) · Computer-Aided Civil and Infrastructure Engineering · doi:10.1111/mice.13153 · Cited by 47
Xu, Y., Tang, W., Zeng, Z., Wu, W., Wan, J., Guo, H. W., & Xie, Z. (2023) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2023.103285 · Cited by 46
Li, J., Zhang, Z., Sun, H., Xie, S., Zou, J., Ji, C., Lu, Y., Ren, X., & Wang, L. (2023) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2023.04.011 · Cited by 45
Short-Term Residential Load Forecasting With Baseline-Refinement Profiles and Bi-Attention Mechanism
Xiao, J., Liu, P., Fang, H., Liu, X., & Wang, Y. (2023) · IEEE Transactions on Smart Grid · doi:10.1109/tsg.2023.3290598 · Cited by 46
Multiscale Vision TransformersPreprint
Fan, H., Xiong, B., Mangalam, K., Li, Y., Yan, Z., Malik, J., & Feichtenhofer, C. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2104.11227 · Cited by 46
PnP-3D: A Plug-and-Play for 3D Point Clouds
Qiu, S., Anwar, S., & Barnes, N. M. (2021) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2021.3137794 · Cited by 46
A survey of deep learning-based 3D shape generation
Xu, Q., Mu, T., & Yang, Y. (2023) · Computational Visual Media · doi:10.1007/s41095-022-0321-5 · Cited by 45
Self-citationDeep-Learning-Based 3-D Surface Reconstruction—A Survey
Farshian, A., Götz, M., Cavallaro, G., Debus, C., Nießner, M., Benediktsson, J. A., & Streit, A. (2023) · Proceedings of the IEEE · doi:10.1109/jproc.2023.3321433 · Cited by 51
AGNet: An Attention-Based Graph Network for Point Cloud Classification and Segmentation
Jing, W., Zhang, W., Li, L., Di, D., Chen, G., & Wang, J. (2022) · Remote Sensing · doi:10.3390/rs14041036 · Cited by 45
Li, M., Liu, J., Zheng, C., Huang, X., & Zhang, Z. (2021) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2021.3134839 · Cited by 48
MKConv: Multidimensional feature representation for point cloud analysis
Woo, S., Lee, D., Hwang, S., Kim, W. J., & Lee, S. (2023) · Pattern Recognition · doi:10.1016/j.patcog.2023.109800 · Cited by 44
Tu, C.-H., Mai, Z., & Chao, W. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00746 · Cited by 54
Ji, A., Zhang, L., Fan, H., Xue, X., & Dou, Y. (2023) · Automation in Construction · doi:10.1016/j.autcon.2023.105131 · Cited by 44
DGECN: A Depth-Guided Edge Convolutional Network for End-to-End 6D Pose Estimation
Cao, T., Luo, F., Fu, Y., Zhang, W., Zheng, S., & Xiao, C. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00376 · Cited by 45
Yin, F., Huang, Z., Chen, T., Luo, G., Yu, G., & Fu, B. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3239541 · Cited by 43
A strategy transfer approach for intelligent human-robot collaborative assembly
Lv, Q., Zhang, R., Liu, T., Zheng, P., Jiang, Y., Li, J., Bao, J., & Xiao, L. (2022) · Computers & Industrial Engineering · doi:10.1016/j.cie.2022.108047 · Cited by 43
DcTr: Noise-robust point cloud completion by dual-channel transformer with cross-attention
Fei, B., Yang, W., Ma, L., & Chen, W. (2022) · Pattern Recognition · doi:10.1016/j.patcog.2022.109051 · Cited by 42
Dynamic graph transformer for 3D object detection
Ren, S., Pan, X., Zhao, W., Nie, B., & Han, B. (2022) · Knowledge-Based Systems · doi:10.1016/j.knosys.2022.110085 · Cited by 42
Point Cloud Upsampling via Cascaded Refinement Network
Du, H., Yan, X., Wang, J., Xie, D., & Pu, S. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-26319-4_7 · Cited by 42
TransLO: A Window-Based Masked Point Transformer Framework for Large-Scale LiDAR Odometry
Liu, J., Wang, G., Jiang, C., Liu, Z., & Wang, H. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i2.25256 · Cited by 42
Self-citationA review of point cloud segmentation for understanding 3D indoor scenes
Sun, Y., Zhang, X., & Miao, Y. (2024) · Visual Intelligence · doi:10.1007/s44267-024-00046-x · Cited by 42
Point2CAD: Reverse Engineering CAD Models from 3D Point Clouds
Liu, Y., Obukhov, A., Wegner, J. D., & Schindler, K. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00361 · Cited by 42
Spatial-Temporal Transformer for 3D Point Cloud Sequences
Wei, Y., Liu, H., Xie, T., Ke, Q., & Guo, Y. (2022) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv51458.2022.00073 · Cited by 41
Refiner: Refining Self-attention for Vision TransformersPreprint
Zhou, D., Shi, Y., Kang, B., Yu, W., Jiang, Z., Li, Y., Jin, X., Hou, Q., & Feng, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.03714 · Cited by 64
SCTN: Sparse Convolution-Transformer Network for Scene Flow Estimation
Li, B., Zheng, C., Giancola, S., & Ghanem, B. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i2.20012 · Cited by 41
Points to Patches: Enabling the Use of Self-Attention for 3D Shape Recognition
Berg, A., Oskarsson, M., & O'Connor, M. (2022) · Proceedings - International Conference on Pattern Recognition/Proceedings/International Conference on Pattern Recognition · doi:10.1109/icpr56361.2022.9956172 · Cited by 42
SAT3D: Slot Attention Transformer for 3D Point Cloud Semantic Segmentation
Ibrahim, M. M., Akhtar, N., Anwar, S., & Mian, A. S. (2023) · IEEE Transactions on Intelligent Transportation Systems · doi:10.1109/tits.2023.3243643 · Cited by 42
Graph neural networks at the Large Hadron Collider
Dezoort, G., Battaglia, P., Biscarat, C., & Vlimant, J.-R. (2023) · Nature Reviews Physics · doi:10.1038/s42254-023-00569-0 · Cited by 47
HGNet: Learning Hierarchical Geometry from Points, Edges, and Surfaces
Yao, T., Li, Y., Pan, Y., & Mei, T. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02092 · Cited by 41
Instance-aware Dynamic Prompt Tuning for Pre-trained Point Cloud Models
Zha, Y., Wang, J., Dai, T., Chen, B., Wang, Z., & Xia, S. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01302 · Cited by 49
3DTA: No-Reference 3D Point Cloud Quality Assessment With Twin Attention
Zhu, L., Cheng, J., Wang, X., Su, H., Yang, H., Yuan, H., & Korhonen, J. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3407698 · Cited by 41
Dynamic Hand Gesture Recognition in In-Vehicle Environment Based on FMCW Radar and Transformer
Zheng, L., Bai, J., Zhu, X., Huang, L., Shan, C., Wu, Q., & Zhang, L. (2021) · Sensors · doi:10.3390/s21196368 · Cited by 44
Metadata
- Authors
- Guo, M.-H., Cai, J.-X., Liu, Z.-N., Mu, T.-J., Martin, R. R., & Hu, S.-M.
- Affiliations
- Tsinghua University (CN)
- Cardiff University (GB)
- Venue
- Computational Visual Media
- Publisher
- Tsinghua University Press
- Published
- 2021-06
- Volume
- 7
- Issue
- 2
- Pages
- 187-199
- ISSN
- 2096-0433 (ISSN-L)
- 2096-0662
- OpenAlex
- W3111535274
- Cited by
- 2,100
- References
- 17
- Citations by year
- 2026: 309 · 2025: 505 · 2024: 515 · 2023: 428 · 2022: 266 · 2021: 76
- FWCI
- 182.77
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Computational Visual Media (publishedVersion, cc-by)
- ORCA Online Research @Cardiff (Cardiff University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Deutsche Forschungsgemeinschaft
- National Natural Science Foundation of China (61761136018, 61521002)
- Topics
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- point cloud processing, point cloud transformer, transformer models, permutation invariance, farthest point sampling, nearest neighbor search, shape classification, part segmentation, semantic segmentation, surface normal estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
