

The DOI matches its Crossref record; 22 of the 22 references it cites were found in a registry or an index.
PCT: Point cloud transformer
Open accessAbstract
The irregular domain and lack of ordering make it challenging to design deep neural networks for point cloud processing. This paper presents a novel framework named Point Cloud Transformer (PCT) for point cloud learning. PCT is based on Transformer, which achieves huge success in natural language processing and displays great potential in image processing. It is inherently permutation invariant for processing a sequence of points, making it well-suited for point cloud learning. To better capture local context within the point cloud, we enhance input embedding with the support of farthest point sampling and nearest neighbor search. Extensive experiments demonstrate that the PCT achieves the state-of-the-art performance on shape classification, part segmentation, semantic segmentation, and normal estimation tasks.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
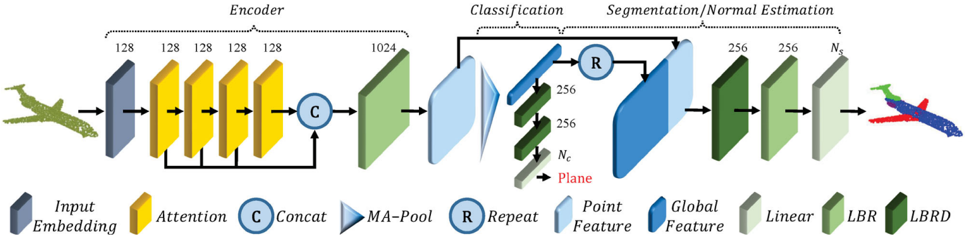
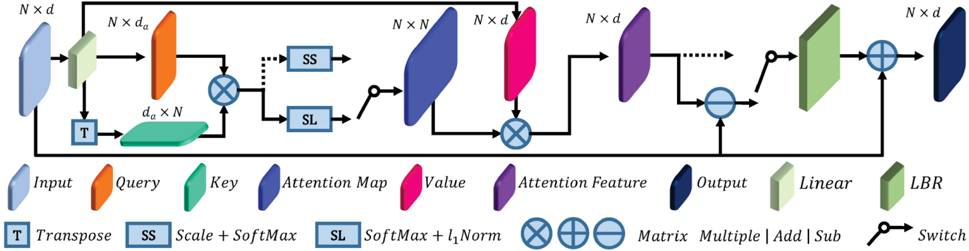
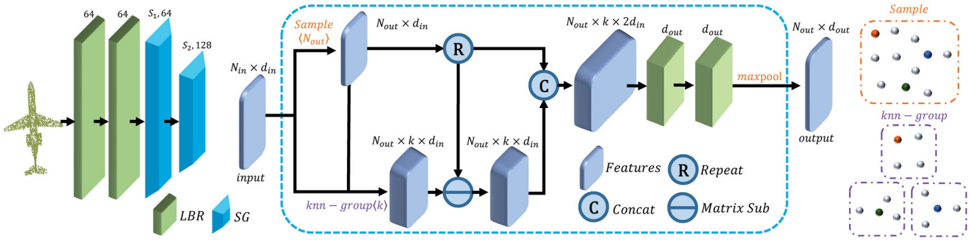
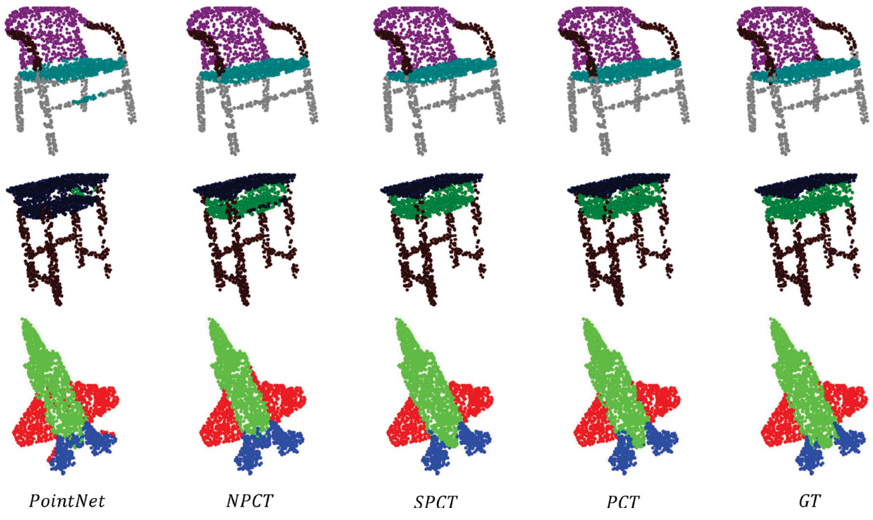
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Cross-lingual gap also should be considered for the transferability of Transformer based multimodal learning, e.g., universal cross-lingual generalization from English to non-English multimodal contexts [206], [277].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [277]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
End-to-End Object Detection with Transformers
Carion, N., Massa, F., Synnaeve, G., Usunier, N., Kirillov, A., & Zagoruyko, S. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58452-8_13 · Cited by 18,285
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,474
Squeeze-and-Excitation Networks
Hu, J., Shen, L., Albanie, S., Sun, G., & Wu, E. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2913372 · Cited by 12,157
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Dynamic Graph CNN for Learning on Point Clouds
Wang, Y., Sun, Y., Liu, Z., Sarma, S. E., Bronstein, M. M., & Solomon, J. M. (2019) · ACM Transactions on Graphics · doi:10.1145/3326362 · Cited by 7,199
Self-citationResidual Attention Network for Image Classification
Wang, F., Jiang, M., Qian, C., Yang, S., Li, C., Zhang, H., Wang, X., & Tang, X. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.683 · Cited by 4,073
Research works printed but not linked: 20
- Charles, R. Q.; Hao, S.; Mo, K. C.; Guibas, L. J. PointNet: Deep learning on point sets for 3D classification and segmentation. IN: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 77–85, 2017.
- Tchapmi, L. P.; Choy, C. B.; Armeni, I.; Gwak, J.; Savarese, S. SEGCloud: Semantic segmentation of 3D point clouds. In: Proceedings of the International Conference on 3D Vision, 537–547, 2017.
- Wu, W. X.; Qi, Z.; Fuxin, L. PointConv: Deep convolutional networks on 3D point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9613–9622, 2019.
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A. N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In: Proceedings of the 31st International Conference on Neural Information Processing, 6000–6010, 2017.
- Bruna, J.; Zaremba, W.; Szlam, A.; LeCun, Y. Spectral networks and locally connected networks on graphs. In: Proceedings of the International Conference on Learning Representations, 2014.
- Hu, S.-M.; Liang, D.; Yang, G.-Y.; Yang, G.-W.; Zhou, W.-Y. Jittor: A novel deep learning framework with meta-operators and unified graph execution. Science China Information Sciences Vol. 63, No. 12, Article No. 222103, 2020.
- Bahdanau, D.; Cho, K. H.; Bengio, Y. Neural machine translation by jointly learning to align and translate. In: Proceedings of the 3rd International Conference on Learning Representations, 2015.
- Lin, Z.; Feng, M.; dos Santos, C. N.; Yu, M.; Xiang, B.; Zhou, B.; Bengio, Y. A structured self-attentive sentence embedding. In: Proceedings of the International Conference on Learning Representations, 2017.
- Yang, Z.; Dai, Z.; Yang, Y.; Carbonell, J. G.; Salakhutdinov, R.; Le, Q. V. XLNet: Generalized autoregressive pretraining for language understanding. In: Proceedings of the 33rd Conference on Neural Information Processing Systems, 5754–5764, 2019.
- Qi, C. R.; Yi, L.; Su, H.; Guibas, L. J. PointNet++: Deep hierarchical feature learning on point sets in a metric space. In: Proceedings of the 31st Conference on Neural Information Processing Systems, 5099–5108, 2017.
- Yang, Y. Q.; Liu, S. L.; Pan, H.; Liu, Y.; Tong, X. PFCNN: Convolutional neural networks on 3D surfaces using parallel frames. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 13575–13584, 2020.
- Yan, X.; Zheng, C. D.; Li, Z.; Wang, S.; Cui, S. G. PointASNL: Robust point clouds processing using nonlocal neural networks with adaptive sampling. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 5588–5597, 2020.
- Hertz, A.; Hanocka, R.; Giryes, R.; Cohen-Or, D. PointGMM: A neural GMM network for point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 12051–12060, 2020.
- Wang, Y.; Solomon, J. Deep closest point: Learning representations for point cloud registration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 3522–3531, 2019.
- Li, J. X.; Chen, B. M.; Lee, G. H. SO-net: Self-organizing network for point cloud analysis. In: Proceeding of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9397–9406, 2018.
- Klokov, R.; Lempitsky, V. Escape from cells: Deep kdnetworks for the recognition of 3D point cloud models. In: Proceeding of the IEEE International Conference on Computer Vision, 863–872, 2017.
- Le, T.; Duan, Y. PointGrid: A deep network for 3D shape understanding. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9204–9214, 2018.
- Zhao, H.; Jiang, L.; Fu, C.; Jia, J. PointWeb: Enhancing local neighborhood features for point cloud processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 5560–5568, 2019.
- Komarichev, A.; Zhong, Z. C.; Hua, J. A-CNN: Annularly convolutional neural networks on point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 7413–7422, 2019.
- Thomas, H.; Qi, C. R.; Deschaud, J. E.; Marcotegui, B.; Goulette, F.; Guibas, L. KPConv: Flexible and deformable convolution for point clouds. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 6410–6419, 2019.
Cited by
Sorted by citations
Items 801–900 of 1,001
MANet: End‐to‐End Learning for Point Cloud Based on Robust Pointpillar and Multiattention
Gan, X., Shi, H., Yang, S., Xiao, Y., & Sun, L. (2022) · Wireless Communications and Mobile Computing · doi:10.1155/2022/6909314 · Cited by 7
Wang, L., Wang, C., Zhang, X., Lan, T., & Li, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2103.08439 · Cited by 7
Deep Magnification-Flexible Upsampling over 3D Point CloudsPreprint
Qian, Y., Hou, J., Kwong, S., & He, Y. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2011.12745 · Cited by 7
Learning-Based Sampling Method for Point Cloud Segmentation
An, Y., Wang, J., He, L., & Li, F. (2024) · IEEE Sensors Journal · doi:10.1109/jsen.2024.3410373 · Cited by 6
Unsupervised Template-assisted Point Cloud Shape Correspondence Network
Deng, J., Lu, J., & Zhang, T. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00502 · Cited by 6
Adaptive Margin Contrastive Learning for Ambiguity-aware 3D Semantic Segmentation
Chen, Y., Duan, Y., Zhang, R., & Tan, Y. (2024) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme57554.2024.10688017 · Cited by 6
Du, R., Zhang, H., Huang, Z., Zhong, H., Cao, Y., & Wang, Y. (2024) · IEEE Transactions on Industrial Informatics · doi:10.1109/tii.2024.3459014 · Cited by 6
Neural Orthodontic Staging: Predicting Teeth Movements With a Transformer
Ma, J., Lou, J., Jiang, B., Ye, H., Yu, W., Chen, X., Zhou, K., & Zheng, Y. (2024) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2024.3504866 · Cited by 7
Point‐PC: Point cloud completion guided by prior knowledge via causal inference
Gao, X., Jiao, C., Chen, R., Wang, W., & Nie, W. (2025) · CAAI Transactions on Intelligence Technology · doi:10.1049/cit2.12379 · Cited by 8
Multi-guided feature refinement for point cloud semantic segmentation with weakly supervision
Wang, Y., Zhao, Q., & Xia, Z. (2025) · Knowledge-Based Systems · doi:10.1016/j.knosys.2025.113050 · Cited by 6
Dual-path geometric relation-aware transformer for point cloud classification and segmentation
Li, X., Wang, Q., & Qiu, B. (2025) · Applied Soft Computing · doi:10.1016/j.asoc.2025.112801 · Cited by 7
Chen, J., Zhu, F., Han, Y., & Ren, D. (2025) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2025.110274 · Cited by 6
SGG-Nets: Generic Rotation-Invariant Plugin Networks for Point Cloud Analysis
Zhu, J. L., Yan, J., Huang, J., Nie, Y., Sheng, B., & Lee, T. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3543001 · Cited by 6
Exploring multi-scale and cross-type features in 3D point cloud learning with CCMNET
Zhou, W. M., Jin, W., Wang, D., Hao, X., Yu, Y., & Ma, C. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.126960 · Cited by 6
Fine-grained text and image guided point cloud completion with CLIP model
Zhou, J., Song, W., Wang, M., Tan, H., Li, N., & Liu, X. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.129768 · Cited by 13
Two-stage bridge point cloud segmentation by fusing deep learning and heuristic methods
Zhang, T., Chen, H., Li, P., & Li, H. (2025) · Measurement · doi:10.1016/j.measurement.2025.117125 · Cited by 6
Li, C. Z., Gao, T., Chen, Z., Wu, H., Deng, Y., Tam, V. W. Y., & Le, K. N. (2025) · Journal of Construction Engineering and Management · doi:10.1061/jcemd4.coeng-16210 · Cited by 6
Geodesic heatmap-based segmentation-free framework for robust tooth landmark detection
Liu, W., Zhuang, S., Fan, Y., Wei, G., & Zhou, Y. (2025) · Computers & Graphics · doi:10.1016/j.cag.2025.104332 · Cited by 6
TM-WSNet: A precise segmentation method for individual rubber trees based on UAV LiDAR point cloud
Yan, L., Zhou, G., Yan, M., & Wang, X. (2025) · Plant Phenomics · doi:10.1016/j.plaphe.2025.100093 · Cited by 6
MInet: A Novel Network Model for Point Cloud Processing by Integrating Multi-Modal Information
Wang, Y., Zuo, Y., Du, Z., Song, X., Luo, T., Hong, X., & Wu, J. (2023) · Sensors · doi:10.3390/s23146327 · Cited by 6
CAS-Net: Cascade Attention-Based Sampling Neural Network for Point Cloud Simplification
Chen, C., Yuan, H., Liu, H., Hou, J., & Hamzaoui, R. (2023) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme55011.2023.00341 · Cited by 6
PCMG:3D point cloud human motion generation based on self-attention and transformer
Ma, W., Yin, M., Li, G., Feng, Y., & Chang, K. (2023) · The Visual Computer · doi:10.1007/s00371-023-03063-x · Cited by 7
Attentional Keypoint Detection on Point Clouds for 3D Object Part Segmentation
Zhou, F., Zhang, Q., Zhu, H., Liu, S., Jiang, N., Cai, X., Qi, Q., & Hu, Y. (2023) · Applied Sciences · doi:10.3390/app132312537 · Cited by 6
Schlenz, S., Mößner, S., Ek, C. H., & Duddeck, F. M. E. (2023) · Advanced Engineering Informatics · doi:10.1016/j.aei.2023.102259 · Cited by 7
Chen, J., Liang, Y., Xie, Z., Wang, S., & Xu, Z. (2023) · Applied Sciences · doi:10.3390/app132413239 · Cited by 6
High-Performance Feature Extraction Network for Point Cloud Semantic Segmentation
Liang, Y., Lü, J., Chen, X., & Zhang, K. (2024) · IEEE Signal Processing Letters · doi:10.1109/lsp.2024.3378670 · Cited by 6
DeLiVoTr: Deep and light-weight voxel transformer for 3D object detection
Erabati, G. K., & Araújo, H. J. (2024) · Intelligent Systems with Applications · doi:10.1016/j.iswa.2024.200361 · Cited by 6
Neural Garment Dynamics via Manifold‐Aware Transformers
Li, P., Wang, T. Y., Kesdogan, T. L., Ceylan, D., & Sorkine‐Hornung, O. (2024) · Computer Graphics Forum · doi:10.1111/cgf.15028 · Cited by 6
Wu, C., Fu, H., Kaiser, J.-P., Barczak, E. T., Pfrommer, J., Lanza, G., Heizmann, M., & Beyerer, J. (2024) · Procedia CIRP · doi:10.1016/j.procir.2024.01.028 · Cited by 7
Differential Graph Convolution Network for point cloud understanding
Bai, Y., Li, G., Yang, C., Li, Y., Xiao, Q., & Li, Z. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.127940 · Cited by 6
Learning Virtual View Selection for 3D Scene Semantic Segmentation
Mu, T., Shen, M.-Y., Lai, Y., & Hu, S. (2024) · IEEE Transactions on Image Processing · doi:10.1109/tip.2024.3421952 · Cited by 6
Self-citationLuo, Z., Zeng, Z., Wan, J., Tang, W., Jin, Z., Xie, Z., & Xu, Y. (2024) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2024.104039 · Cited by 6
Multi-modal 3D Human Tracking for Robots in Complex Environment with Siamese Point-Video Transformer
Xin, S., Zhang, Z., Wang, M., Hou, X., Guo, Y., Kang, X., Liu, L., & Liu, Y. (2024) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra57147.2024.10610979 · Cited by 6
A novel Complementary Dual-aware Network for point cloud classification
Hu, R., Cao, F., & Wang, W. (2024) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2024.109224 · Cited by 6
PCAlign: a general data augmentation framework for point clouds
Zhang, C., Li, A., Zhang, D., & Lv, C. (2024) · Scientific Reports · doi:10.1038/s41598-024-72264-8 · Cited by 6
Liang, Z., & Lai, X. (2024) · Remote Sensing · doi:10.3390/rs16183386 · Cited by 9
EIDU-Net: edge-preserved inception DenseGCN U-Net for LiDAR point cloud segmentation
Xu, X., Wang, J., Zhu, Q., Zhou, P., Geng, G., Li, K., Su, L., & Cao, X. (2024) · Scientific Reports · doi:10.1038/s41598-024-74690-0 · Cited by 6
Learning Cross-Attention Point Transformer With Global Porous Sampling
Duan, Y., Sun, H., Yan, J., Lu, J., & Zhou, J. (2024) · IEEE Transactions on Image Processing · doi:10.1109/tip.2024.3486612 · Cited by 6
Chen, Y.-S., Xiao, Y., Wu, H., Chen, C., & Ding, L. (2024) · Mathematics · doi:10.3390/math12233827 · Cited by 6
APANet: Asymmetrical Parallax Attention Network for Efficient Stereo Image Deraining
Wang, C., Yan, T., Huang, W., Chen, X., Xu, K., & Chang, X. (2025) · IEEE Transactions on Computational Imaging · doi:10.1109/tci.2025.3527142 · Cited by 6
LEST: Large-Scale LiDAR Semantic Segmentation With Deployment-Friendly Transformer Architecture
Luo, C., Cheng, N., Ma, S., Li, H., Li, X., Lei, S., & Li, P. (2025) · IEEE Access · doi:10.1109/access.2025.3545957 · Cited by 6
3D point cloud semantic segmentation based on visual guidance and feature enhancement
Chen, S., Shu, Y., Qiao, L., Wu, Z., Ling, J., Wu, J., & Li, W. (2025) · Multimedia Systems · doi:10.1007/s00530-025-01777-7 · Cited by 6
PTRNet: Global Feature and Local Feature Encoding for Point Cloud Registration
Li, C., Yang, S., Shi, L., Liu, Y., & Li, Y. (2022) · Applied Sciences · doi:10.3390/app12031741 · Cited by 6
Point cloud completion by dynamic transformer with adaptive neighbourhood feature fusion
Liu, X., Xu, G., Xu, K., Wan, J., & Ma, Y. (2022) · IET Computer Vision · doi:10.1049/cvi2.12098 · Cited by 6
GICEI, I. U. P. B., Pamplona, J. V., Madrigal, C. A., Grupodot, S. A. S., Herrera-Ramírez, J. A., & GAEYCC, I. T. M. (2022) · Computer Optics · doi:10.18287/2412-6179-co-1001 · Cited by 6
Enhancing 3D-2D Representations for Convolution Occupancy Networks
Mao, Q., Li, R., Zhu, Y., Sun, J., & Zhang, Y. (2022) · Pattern Recognition · doi:10.1016/j.patcog.2022.109097 · Cited by 6
Continuous Volumetric Convolution Network With Self-Learning Kernels for Point Clouds
Zheng, R., Huang, K., Shen, H., & Ma, L. (2022) · IEEE Transactions on Consumer Electronics · doi:10.1109/tce.2022.3218107 · Cited by 6
Continuous Human Motion Recognition Based on FMCW Radar and Transformer
Jiang, L., wu, M., Che, L., Xu, X., Mu, Y., & Wu, Y. (2023) · Journal of Sensors · doi:10.1155/2023/2951812 · Cited by 6
DiffusionPointLabel: Annotated Point Cloud Generation with Diffusion Model
Li, T., Fu, Y., Han, X., Liang, H., Zhang, J., & Chang, J. M. (2022) · Computer Graphics Forum · doi:10.1111/cgf.14663 · Cited by 8
UFO-Net: A Linear Attention-Based Network for Point Cloud Classification
He, S., Guo, P., Tang, Z., Guo, D., Wan, L., & Yao, H. (2023) · Sensors · doi:10.3390/s23125512 · Cited by 6
Scene point cloud understanding and reconstruction technologies in 3D space
Gong, J., Lou, Y., Liu, F., Zhang, Z., Chen, H., Zhang, Z., Tan, X., Xie, Y., & Ma, L. (2023) · Journal of Image and Graphics · doi:10.11834/jig.230004 · Cited by 11
Long-Range Perception System for Road Boundaries and Objects Detection in Trains
Pan, W., Fan, X., Li, H., & He, K. (2023) · Remote Sensing · doi:10.3390/rs15143473 · Cited by 6
HVP-Net: A Hybrid Voxel- and Point-Wise Network for Place Recognition
Chen, L., Kong, H., Wang, H., Yang, W., Lou, J. J., Xu, F., & Ren, M. (2023) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2023.3308116 · Cited by 6
NSAW: An Efficient and Accurate Transformer for Vehicle LiDAR Object Detection
Hu, Y., Li, S., Weng, W., Xu, K., & Wang, G. (2023) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2023.3318680 · Cited by 6
SimHMR: A Simple Query-based Framework for Parameterized Human Mesh Reconstruction
Huang, Z., Shi, M., Liu, C., Xian, K., & Cao, Z. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3611814 · Cited by 6
OctPCGC-Net: Learning Octree-Structured Context Entropy Model for Point Cloud Geometry Compression
Wang, X., Wang, H., Xu, K., Wan, J., & Guo, Y. (2023) · Lecture notes in computer science · doi:10.1007/978-981-99-8432-9_28 · Cited by 6
ExpPoint-MAE: Better Interpretability and Performance for Self-Supervised Point Cloud Transformers
Romanelis, I., Fotis, V., Μουστάκας, Κ., & Munteanu, A. (2024) · IEEE Access · doi:10.1109/access.2024.3388155 · Cited by 7
Furuya, T., Chen, Z., Ohbuchi, R., & Kuang, Z. (2024) · Computer Vision and Image Understanding · doi:10.1016/j.cviu.2024.104025 · Cited by 6
SWAT: Spatial Structure Within and Among Tokens
Kahatapitiya, K., & Ryoo, M. S. (2023) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2023/106 · Cited by 10
Hierarchical Point Cloud Encoding and Decoding With Lightweight Self-Attention Based Model
Puang, E. Y., Zhang, H., Zhu, H., & Jing, W. (2022) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2022.3149569 · Cited by 6
TH-Net: A Method Of Single 3d Object Tracking Based On Transformers And Hausdorff Distance
Zhang, Z., Sang, N., & Wang, X. (2022) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp43922.2022.9746466 · Cited by 6
Furuya, T., Liu, W., Ohbuchi, R., & Kuang, Z. (2022) · The Visual Computer · doi:10.1007/s00371-022-02652-6 · Cited by 7
Research on Intelligent Robot Point Cloud Grasping in Internet of Things
Wang, Z., Li, S., Bai, Q., Song, Q., Zhang, X., & Pu, R. (2022) · Micromachines · doi:10.3390/mi13111999 · Cited by 6
Scattered Train Bolt Point Cloud Segmentation Based on Hierarchical Multi-Scale Feature Learning
Zeng, N., Li, J., Zhang, Y., Gao, X., & Luo, L. (2023) · Sensors · doi:10.3390/s23042019 · Cited by 8
Shen, X., Xu, Z., & Wang, M. (2023) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2023.3320732 · Cited by 6
Patch-Wise LiDAR Point Cloud Geometry Compression Based on Autoencoder
Huang, R., & Wang, M. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-46311-2_25 · Cited by 6
Point Cloud Pre-training by Mixing and DisentanglingPreprint
Sun, C., Zheng, Z., Wang, X., Xu, M., & Yang, Y. (2021) · arXiv (Cornell University) · Cited by 6
PointNet++ Network with Contextual Feature and Mutual Learning for Point SetsPreprint
Hu, X., & Xie, X. (2024) · Preprints.org · doi:10.20944/preprints202403.0743.v1 · Cited by 6
Edge-guided generative network with attention for point cloud completion
Li, J., Zhang, J., Zhang, X., & Chen, M. (2024) · The Visual Computer · doi:10.1007/s00371-024-03364-9 · Cited by 5
Granformer: A granular transformer net with linear complexity
Wang, K., Sun, X., & Shen, T. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.128380 · Cited by 5
Point cloud graph for LiDAR segmentation
Dou, W., & Wang, Y. (2024) · Measurement · doi:10.1016/j.measurement.2024.115851 · Cited by 5
Han, B., Wang, C., Zhang, X. M., Zhao, Z., Zhai, Z., Liu, J., Liu, N., & Chen, X. (2024) · IEEE Transactions on Aerospace and Electronic Systems · doi:10.1109/taes.2024.3479199 · Cited by 6
LGCANet:Local geometry-aware cross-attention networks for point cloud semantic segmentation
Luo, L., Lu, J., Chen, X., Zhang, K., & Zhou, J. (2025) · Measurement · doi:10.1016/j.measurement.2025.116860 · Cited by 5
Automatic Tooth Labeling After Segmentation Using Prototype-based Meta-learning
Sehar, U., Xiong, J., & Xia, Z. (2025) · Machine Intelligence Research · doi:10.1007/s11633-024-1520-6 · Cited by 5
Paying attention to the minute details: Supervised keypoint detection on dense, complex point clouds
Chen, Q., Liao, S., Kui, X., Hu, Z., & Zhou, J. (2025) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2025.110668 · Cited by 5
Mushtaq, H., Latif, S., Ilyas, M., Mohsin, S. M., & Ali, M. (2025) · IEEE Access · doi:10.1109/access.2025.3558780 · Cited by 7
CADTrans: A code tree-guided CAD generative transformer model with regularized discrete codebooks
Guo, X., Dong, X., Cao, J., & Chen, Z. (2025) · Graphical Models · doi:10.1016/j.gmod.2025.101262 · Cited by 5
Yibulayimu, S., Liu, Y., Sang, Y., Qin, J., Shi, C. J., Liang, C., Zhu, G., Wang, Y., Zhao, C., & Wu, X. (2025) · IEEE Transactions on Medical Imaging · doi:10.1109/tmi.2025.3561030 · Cited by 5
3DLST: 3D Learnable Supertoken Transformer for LiDAR point cloud scene segmentation
Lu, D., Xu, L., Zhou, J., Gao, K., & Li, J. (2025) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2025.104572 · Cited by 5
SPU+: Dimension Folding for Semantic Point Cloud Upsampling
Li, Z., Li, T. H., Liu, S., & Li, G. (2025) · IEEE Transactions on Image Processing · doi:10.1109/tip.2025.3571680 · Cited by 5
3DDGD: 3D Deepfake Generation and Detection Using 3D Face Meshes
Felouat, H., Nguyen, H. H., Yamagishi, J., & Echizen, I. (2025) · IEEE Access · doi:10.1109/access.2025.3580950 · Cited by 5
Multimodal Fusion Network for Power Tower Semantic Segmentation and Inclination Detection
Zhang, H., Liu, Y., Zhong, H., Huang, Z., Du, R., Tang, Y., Cao, Y., & Wang, Y. (2025) · IEEE Transactions on Industrial Informatics · doi:10.1109/tii.2025.3578133 · Cited by 5
Liu, X., Cai, S., Lin, H., Liu, X., Hu, X., Zhang, L. J., & Gao, Q. (2025) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2025.111460 · Cited by 5
A Collaborative Learning Framework With Coupling Graph Transformers for 3D Tooth Segmentation
Lin, Z., He, Z., Liu, C., Liang, H., Su, W., Tan, J., & Guo, J. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3599046 · Cited by 5
Zou, Y., Wang, H., Zhang, F., Ge, Y., Wang, W., & Chen, M. (2025) · Frontiers in Plant Science · doi:10.3389/fpls.2025.1621934 · Cited by 5
WHU-STree: A multi-modal benchmark dataset for street tree inventory
Ding, R., Chen, Z., Fan, W. L., Chen, L. F., Xiao, H., Zeng, Y., Dong, Z., & Yang, B. (2026) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2026.02.011 · Cited by 5
Lu, W., Chen, Y., & Huang, X. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.132019 · Cited by 5
Point-MASNet: Masked Autoencoder-Based Sampling Network for 3D Point Cloud
Wang, X., Jin, Y., Yu, H. L., Cen, Y., Wang, T., & Li, Y. (2025) · IEEE/CAA Journal of Automatica Sinica · doi:10.1109/jas.2024.125088 · Cited by 5
HyperPoint: Multimodal 3D foundation model in hyperbolic space
Sun, Y., Cheng, H., Lu, C., Li, Z., Wu, M., Lu, H., & Zhu, J. (2025) · Pattern Recognition · doi:10.1016/j.patcog.2025.112800 · Cited by 5
Chen, Y., Xia, J., Zou, X., Xiao, Z., Tang, X., Zang, Y., Chen, D., & Shen, Y. (2025) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2025.09.006 · Cited by 5
mm-ARnet: Exploring Millimeter Wave Radar Point Clouds for Human Action Recognition
Hao, Z., Xiao, J., Wang, Y., Wang, G., & Li, F. (2025) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2025.3649493 · Cited by 5
Chen, Y., Li, J., Han, T., Feng, H., Chen, J., & Wang, C. (2026) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2026.01.003 · Cited by 5
Wang, X., & Yuan, Y. (2023) · Remote Sensing · doi:10.3390/rs15153908 · Cited by 5
Dynamic Visual Prompt Tuning for Parameter Efficient Transfer Learning
Ruan, C., & Wang, H. (2023) · Lecture notes in computer science · doi:10.1007/978-981-99-8543-2_24 · Cited by 5
AFpoint: adaptively fusing local and global features for point cloud
Li, G., Liu, C., Gao, X., Xiao, H., & Ling, B. W. (2024) · Multimedia Tools and Applications · doi:10.1007/s11042-024-18658-2 · Cited by 5
Global Attention-Guided Dual-Domain Point Cloud Feature Learning for Classification and Segmentation
Li, Z., Gao, P., You, K., Yan, C., & Paul, M. (2024) · IEEE Transactions on Artificial Intelligence · doi:10.1109/tai.2024.3429050 · Cited by 5
SLS4D: Sparse Latent Space for 4D Novel View Synthesis
Feng, Q.-Y., Chen, H.-X., Xu, Q., & Mu, T. (2024) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2024.3429421 · Cited by 5
Self-citationDynamic gesture recognition method based on multi-scale feature fusion
Qiu, F., Zhou, J. Q., & Peng, D. (2024) · International Conference on Computer Vision, Image and Deep Learning (CVIDL) · doi:10.1109/cvidl62147.2024.10604197 · Cited by 5
EP-Net: Improving Point Cloud Learning Efficiency Through Feature Decoupling
Deng, H., Chen, S., Zhu, X., Jiang, B., Jing, K., & Wang, L. (2024) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2024.3451587 · Cited by 5
Revisiting 3D point cloud analysis with Markov process
Jiang, C., Ma, W., Huang, K., Wang, Q., Yang, X. D., Zhao, W., Wu, J., Wang, X., Xiao, J., & Niu, Z. (2024) · Pattern Recognition · doi:10.1016/j.patcog.2024.110997 · Cited by 5
Metadata
- Authors
- Guo, M.-H., Cai, J.-X., Liu, Z.-N., Mu, T.-J., Martin, R. R., & Hu, S.-M.
- Affiliations
- Tsinghua University (CN)
- Cardiff University (GB)
- Venue
- Computational Visual Media
- Publisher
- Tsinghua University Press
- Published
- 2021-06
- Volume
- 7
- Issue
- 2
- Pages
- 187-199
- ISSN
- 2096-0433 (ISSN-L)
- 2096-0662
- OpenAlex
- W3111535274
- Cited by
- 2,100
- References
- 17
- Citations by year
- 2026: 309 · 2025: 505 · 2024: 515 · 2023: 428 · 2022: 266 · 2021: 76
- FWCI
- 182.77
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Computational Visual Media (publishedVersion, cc-by)
- ORCA Online Research @Cardiff (Cardiff University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Deutsche Forschungsgemeinschaft
- National Natural Science Foundation of China (61761136018, 61521002)
- Topics
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- point cloud processing, point cloud transformer, transformer models, permutation invariance, farthest point sampling, nearest neighbor search, shape classification, part segmentation, semantic segmentation, surface normal estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
