

The DOI matches its Crossref record; 22 of the 22 references it cites were found in a registry or an index.
PCT: Point cloud transformer
Open accessAbstract
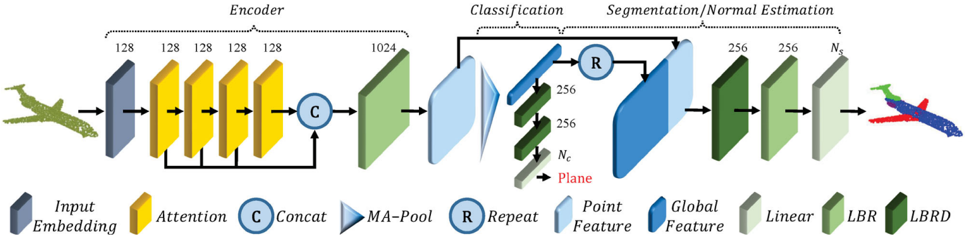
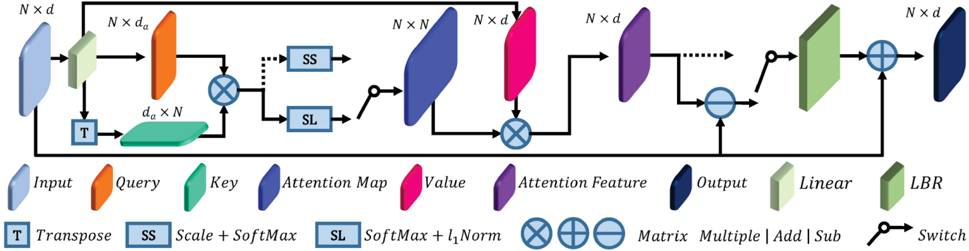
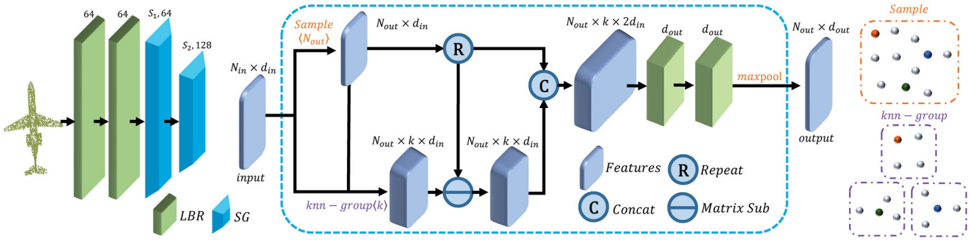
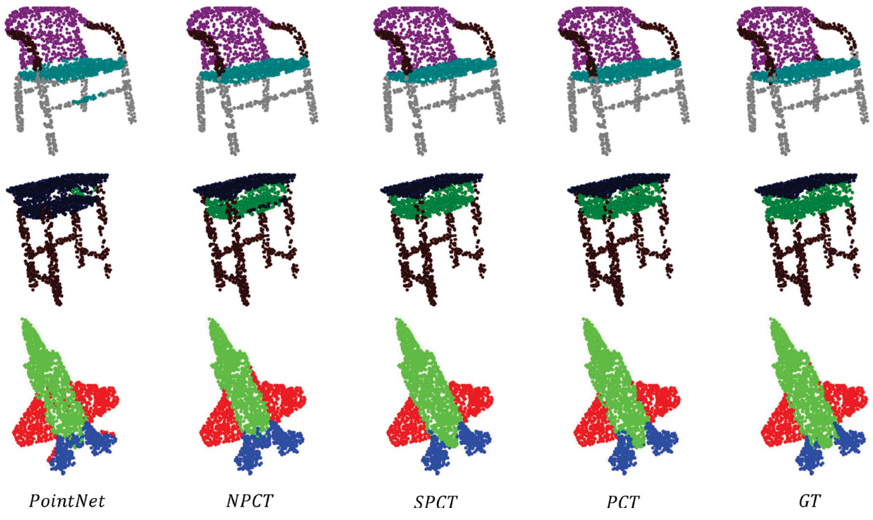
The irregular domain and lack of ordering make it challenging to design deep neural networks for point cloud processing. This paper presents a novel framework named Point Cloud Transformer (PCT) for point cloud learning. PCT is based on Transformer, which achieves huge success in natural language processing and displays great potential in image processing. It is inherently permutation invariant for processing a sequence of points, making it well-suited for point cloud learning. To better capture local context within the point cloud, we enhance input embedding with the support of farthest point sampling and nearest neighbor search. Extensive experiments demonstrate that the PCT achieves the state-of-the-art performance on shape classification, part segmentation, semantic segmentation, and normal estimation tasks.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Cross-lingual gap also should be considered for the transferability of Transformer based multimodal learning, e.g., universal cross-lingual generalization from English to non-English multimodal contexts [206], [277].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [277]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
End-to-End Object Detection with Transformers
Carion, N., Massa, F., Synnaeve, G., Usunier, N., Kirillov, A., & Zagoruyko, S. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58452-8_13 · Cited by 18,285
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,474
Squeeze-and-Excitation Networks
Hu, J., Shen, L., Albanie, S., Sun, G., & Wu, E. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2913372 · Cited by 12,157
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Dynamic Graph CNN for Learning on Point Clouds
Wang, Y., Sun, Y., Liu, Z., Sarma, S. E., Bronstein, M. M., & Solomon, J. M. (2019) · ACM Transactions on Graphics · doi:10.1145/3326362 · Cited by 7,199
Self-citationResidual Attention Network for Image Classification
Wang, F., Jiang, M., Qian, C., Yang, S., Li, C., Zhang, H., Wang, X., & Tang, X. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.683 · Cited by 4,073
Research works printed but not linked: 20
- Charles, R. Q.; Hao, S.; Mo, K. C.; Guibas, L. J. PointNet: Deep learning on point sets for 3D classification and segmentation. IN: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 77–85, 2017.
- Tchapmi, L. P.; Choy, C. B.; Armeni, I.; Gwak, J.; Savarese, S. SEGCloud: Semantic segmentation of 3D point clouds. In: Proceedings of the International Conference on 3D Vision, 537–547, 2017.
- Wu, W. X.; Qi, Z.; Fuxin, L. PointConv: Deep convolutional networks on 3D point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9613–9622, 2019.
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A. N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In: Proceedings of the 31st International Conference on Neural Information Processing, 6000–6010, 2017.
- Bruna, J.; Zaremba, W.; Szlam, A.; LeCun, Y. Spectral networks and locally connected networks on graphs. In: Proceedings of the International Conference on Learning Representations, 2014.
- Hu, S.-M.; Liang, D.; Yang, G.-Y.; Yang, G.-W.; Zhou, W.-Y. Jittor: A novel deep learning framework with meta-operators and unified graph execution. Science China Information Sciences Vol. 63, No. 12, Article No. 222103, 2020.
- Bahdanau, D.; Cho, K. H.; Bengio, Y. Neural machine translation by jointly learning to align and translate. In: Proceedings of the 3rd International Conference on Learning Representations, 2015.
- Lin, Z.; Feng, M.; dos Santos, C. N.; Yu, M.; Xiang, B.; Zhou, B.; Bengio, Y. A structured self-attentive sentence embedding. In: Proceedings of the International Conference on Learning Representations, 2017.
- Yang, Z.; Dai, Z.; Yang, Y.; Carbonell, J. G.; Salakhutdinov, R.; Le, Q. V. XLNet: Generalized autoregressive pretraining for language understanding. In: Proceedings of the 33rd Conference on Neural Information Processing Systems, 5754–5764, 2019.
- Qi, C. R.; Yi, L.; Su, H.; Guibas, L. J. PointNet++: Deep hierarchical feature learning on point sets in a metric space. In: Proceedings of the 31st Conference on Neural Information Processing Systems, 5099–5108, 2017.
- Yang, Y. Q.; Liu, S. L.; Pan, H.; Liu, Y.; Tong, X. PFCNN: Convolutional neural networks on 3D surfaces using parallel frames. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 13575–13584, 2020.
- Yan, X.; Zheng, C. D.; Li, Z.; Wang, S.; Cui, S. G. PointASNL: Robust point clouds processing using nonlocal neural networks with adaptive sampling. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 5588–5597, 2020.
- Hertz, A.; Hanocka, R.; Giryes, R.; Cohen-Or, D. PointGMM: A neural GMM network for point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 12051–12060, 2020.
- Wang, Y.; Solomon, J. Deep closest point: Learning representations for point cloud registration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 3522–3531, 2019.
- Li, J. X.; Chen, B. M.; Lee, G. H. SO-net: Self-organizing network for point cloud analysis. In: Proceeding of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9397–9406, 2018.
- Klokov, R.; Lempitsky, V. Escape from cells: Deep kdnetworks for the recognition of 3D point cloud models. In: Proceeding of the IEEE International Conference on Computer Vision, 863–872, 2017.
- Le, T.; Duan, Y. PointGrid: A deep network for 3D shape understanding. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9204–9214, 2018.
- Zhao, H.; Jiang, L.; Fu, C.; Jia, J. PointWeb: Enhancing local neighborhood features for point cloud processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 5560–5568, 2019.
- Komarichev, A.; Zhong, Z. C.; Hua, J. A-CNN: Annularly convolutional neural networks on point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 7413–7422, 2019.
- Thomas, H.; Qi, C. R.; Deschaud, J. E.; Marcotegui, B.; Goulette, F.; Guibas, L. KPConv: Flexible and deformable convolution for point clouds. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 6410–6419, 2019.
Cited by
Sorted by citations
Items 201–300 of 1,001
Learning Geometric Transformation for Point Cloud Completion
Zhang, S., Liu, X., Xie, H., Nie, L., Zhou, H., Tao, D., & Li, X. (2023) · International Journal of Computer Vision · doi:10.1007/s11263-023-01820-y · Cited by 40
TNPC: Transformer-based network for point cloud classification
Zhou, W., Zhao, Y., Xiao, Y., Min, X., & Yi, J. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.122438 · Cited by 41
Sparse Cross-Scale Attention Network for Efficient LiDAR Panoptic Segmentation
Xu, S., Wan, R., Ye, M., Zou, X., & Cao, T. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i3.20197 · Cited by 40
Zhou, Y., Ji, A., Zhang, L., & Xue, X. (2022) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2022.105554 · Cited by 41
Gaussian Radar Transformer for Semantic Segmentation in Noisy Radar Data
Zeller, M., Behley, J., Heidingsfeld, M., & Stachniss, C. (2022) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2022.3226030 · Cited by 42
3CROSSNet: Cross-Level Cross-Scale Cross-Attention Network for Point Cloud Representation
Han, X.-F., He, Z.-Y., Chen, J., & Xiao, G. (2022) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2022.3147907 · Cited by 39
MOTFR: Multiple Object Tracking Based on Feature Recoding
Kong, J., Mo, E., Jiang, M., & Liu, T. (2022) · IEEE transactions on circuits and systems for video technology (Print) · doi:10.1109/tcsvt.2022.3182709 · Cited by 37
Masked Scene Contrast: A Scalable Framework for Unsupervised 3D Representation Learning
Wu, X., Wen, X., Liu, X., & Zhao, H. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00908 · Cited by 39
HRNet: 3D object detection network for point cloud with hierarchical refinement
Lu, B., Yang, S. O., Yang, Z., Song, R., Jiang, H., & Liu, Y. (2024) · Pattern Recognition · doi:10.1016/j.patcog.2024.110254 · Cited by 39
PointDifformer: Robust Point Cloud Registration With Neural Diffusion and Transformer
She, R., Kang, Q., Wang, S., Tay, W. P., Zhao, K., Song, Y., Geng, T., Xu, Y., Navarro, D. N., & Hartmannsgruber, A. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3351286 · Cited by 46
Deep learning-based tooth segmentation methods in medical imaging: A review
Chen, X., Ma, N., Xu, T., & Xu, C. (2024) · Proceedings of the Institution of Mechanical Engineers Part H Journal of Engineering in Medicine · doi:10.1177/09544119231217603 · Cited by 39
LCDNet: Light-Weighted Cloud Detection Network for High-Resolution Remote Sensing Images
Hu, K., Zhang, D., Xia, M., Qian, M., & Chen, B. (2022) · IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing · doi:10.1109/jstars.2022.3181303 · Cited by 39
Eliminating Gradient Conflict in Reference-based Line-Art Colorization
Li, Z., Geng, Z., Kang, Z., Chen, W., & Yang, Y. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19790-1_35 · Cited by 41
A Survey of Robustness and Safety of 2D and 3D Deep Learning Models against Adversarial Attacks
Li, Y., Xie, B., Guo, S., Yang, Y., & Xiao, B. (2023) · ACM Computing Surveys · doi:10.1145/3636551 · Cited by 49
Chai, X., Shao, F., Mu, B., Chen, H., Jiang, Q., & Ho, Y. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3350180 · Cited by 38
Liu, H., Liu, R., Yang, K., Zhang, J., Peng, K., & Stiefelhagen, R. (2021) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw54120.2021.00204 · Cited by 38
Weakly supervised semantic segmentation of airborne laser scanning point clouds
Lin, Y., George Vosselman, A., & Yang, M. Y. (2022) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2022.03.001 · Cited by 38
An Adjustable Farthest Point Sampling Method for Approximately-sorted Point Cloud Data
Li, J., Zhou, J., Xiong, Y., Chen, X., & Chakrabarti, C. (2022) · SiPS ... design and implementation - IEEE Workshop on Signal Processing Systems · doi:10.1109/sips55645.2022.9919246 · Cited by 37
PointNAT: Large-Scale Point Cloud Semantic Segmentation via Neighbor Aggregation With Transformer
Zeng, Z., Qiu, H., Zhou, J. Y., Dong, Z., Xiao, J., & Li, B. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3407761 · Cited by 37
Artificial intelligence in rechargeable battery: Advancements and prospects
Xiong, Y., Zhang, D., Ruan, X., 蒋善宝, Zou, X., Yuan, W., Liu, X., Zhang, Y., Nie, Z., Wei, D., et al. (2024) · Energy storage materials · doi:10.1016/j.ensm.2024.103860 · Cited by 40
Weakly Supervised 3D Point Cloud Segmentation via Multi-Prototype Learning
Su, Y., Xu, X., & Jia, K. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3281151 · Cited by 36
Wei, T., Yuan, W., Luo, J., Zhang, W., & Lu, L. (2023) · Journal of Systems Engineering and Electronics · doi:10.23919/jsee.2023.000035 · Cited by 36
Wu, Y., Yan, Z., Cai, S., Li, G., Han, X., & Cui, S. R. (2023) · Computers & Graphics · doi:10.1016/j.cag.2023.09.006 · Cited by 36
Deep learning based computer vision under the prism of 3D point clouds: a systematic review
Tychola, K. A., Vrochidou, Ε., & Papakostas, G. A. (2024) · The Visual Computer · doi:10.1007/s00371-023-03237-7 · Cited by 42
DiffCLIP: Leveraging Stable Diffusion for Language Grounded 3D Classification
Shen, S., Zhu, Z., Fan, L., Zhang, H., & Wu, X. (2024) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv57701.2024.00356 · Cited by 39
Wireless Point Cloud Transmission
Bian, C., Shao, Y., & Gündüz, D. (2024) · IEEE International Workshop on Signal Processing Advances in Wireless Communications (SPAWC) · doi:10.1109/spawc60668.2024.10694621 · Cited by 36
GeoRec: Geometry-enhanced semantic 3D reconstruction of RGB-D indoor scenes
Huan, L., Zheng, X., & Gong, J. (2022) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2022.02.014 · Cited by 36
Transformer and Upsampling-Based Point Cloud Compression
Zhang, J., Liu, G., Ding, D., & Ma, Z. (2022) · doi:10.1145/3552457.3555731 · Cited by 36
A Hierarchical Scheme of Road Unevenness Perception With LiDAR for Autonomous Driving Comfort
Zhao, T., Guo, P., He, J., & Wei, Y. (2023) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2023.3337236 · Cited by 36
Zhu, J., Zhai, R., Ren, H. J., Xie, K., Du, A., He, X., Cui, C., Wang, Y., Ye, J., Wang, J., et al. (2024) · Scientific Data · doi:10.1038/s41597-024-04290-0 · Cited by 36
Full Transformer Framework for Robust Point Cloud Registration With Deep Information Interaction
Chen, G., Wang, M., Zhang, Q., Yuan, L., & Yue, Y. (2023) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2023.3267333 · Cited by 38
Multi-Stage Spatio-Temporal Aggregation Transformer for Video Person Re-Identification
Tang, Z., Zhang, R., Peng, Z., Chen, J., & Lin, L. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3231103 · Cited by 34
HCPVF: Hierarchical Cascaded Point-Voxel Fusion for 3D Object Detection
Fan, B., Zhang, K., & Tian, J. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3268849 · Cited by 35
Efficient Vision Transformer via Token Merger
Feng, Z., & Zhang, S. S. (2023) · IEEE Transactions on Image Processing · doi:10.1109/tip.2023.3293763 · Cited by 37
Constructing hierarchical attentive functional brain networks for early AD diagnosis
Zhang, J., Guo, Y., Zhou, L., Wang, L., Wu, W., & Shen, D. G. (2024) · Medical Image Analysis · doi:10.1016/j.media.2024.103137 · Cited by 35
S2ANet: Combining local spectral and spatial point grouping for point cloud processing
Liu, Y., Xiaorui, S. U. N., Wenbin, S. H. A. O., & Yafu, Y. U. A. N. (2024) · Virtual Reality & Intelligent Hardware · doi:10.1016/j.vrih.2023.06.005 · Cited by 35
Artificial Intelligence and Terrestrial Point Clouds for Forest Monitoring
Kulicki, M., Çabo, C., Trzcinski, T. P., Będkowski, J., & Stereńczak, K. (2024) · Current Forestry Reports · doi:10.1007/s40725-024-00234-4 · Cited by 41
Generating Inverse Feature Space for Class Imbalance in Point Cloud Semantic Segmentation
Han, J., Liu, K., Li, W., Zhang, F., & Xia, X. (2025) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2025.3553051 · Cited by 40
Spike Transformer: Monocular Depth Estimation for Spiking Camera
Zhang, J., Tang, L., Yu, Z., Lu, J., & Huang, T. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20071-7_3 · Cited by 34
Shen, B., Li, L., Hu, X., Guo, S., Huang, J., & Liang, Z. (2023) · Virtual Reality & Intelligent Hardware · doi:10.1016/j.vrih.2022.08.016 · Cited by 34
Robust Hybrid Learning for Automatic Teeth Segmentation and Labeling on 3D Dental Models
Zhuang, S., Wei, G., Cui, Z., & Zhou, Y. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3289760 · Cited by 34
A review of rigid point cloud registration based on deep learning
Chen, L., Feng, C., Ma, Y., Zhao, Y., & Wang, C. (2024) · Frontiers in Neurorobotics · doi:10.3389/fnbot.2023.1281332 · Cited by 43
Krenmayr, L., von Schwerin, R., Schaudt, D., Riedel, P., & Hafner, A. (2024) · Journal of Imaging Informatics in Medicine · doi:10.1007/s10278-024-01061-6 · Cited by 34
Graph Neural Networks in Point Clouds: A Survey
Li, D., Lu, C., Chen, Z., Guan, J., Zhao, J., & Du, J. (2024) · Remote Sensing · doi:10.3390/rs16142518 · Cited by 36
Self-Supervised Point Cloud Representation Learning via Separating Mixed Shapes
Sun, C., Zheng, Z., Wang, X., Xu, M., & Yang, Y. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3206664 · Cited by 40
Hybrid Physical Metric For 6-DoF Grasp Pose Detection
Lu, Y., Deng, B., Wang, Z., Zhi, P., Li, Y., & Wang, S. (2022) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra46639.2022.9811961 · Cited by 33
Rauch, L., & Braml, T. (2023) · Applied Sciences · doi:10.3390/app13169146 · Cited by 36
RepKPU: Point Cloud Upsampling with Kernel Point Representation and Deformation
Rong, Y., Zhou, H., Xia, K., Mei, C., Wang, J., & Lü, T. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01989 · Cited by 34
HiTPR: Hierarchical Transformer for Place Recognition in Point Cloud
Hou, Z., Yan, Y., Xu, C., & Kong, H. (2022) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra46639.2022.9811737 · Cited by 32
A Comparative Study of CNN- and Transformer-Based Visual Style Transfer
Wei, H., Deng, Y., Tang, F., Pan, X., & Dong, W. (2022) · Journal of Computer Science and Technology · doi:10.1007/s11390-022-2140-7 · Cited by 33
PointGS: Bridging and fusing geometric and semantic space for 3D point cloud analysis
Jiang, C., Huang, K., Wu, J., Wang, X., Xiao, J., & Hussain, A. (2022) · Information Fusion · doi:10.1016/j.inffus.2022.10.016 · Cited by 33
Self-Distillation for Robust LiDAR Semantic Segmentation in Autonomous Driving
Li, J., Dai, H., & Ding, Y. S. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19815-1_38 · Cited by 33
Generating Transferable 3D Adversarial Point Cloud via Random Perturbation Factorization
He, B., Liu, J., Li, Y., Liang, S., Li, J., Jia, X., & Cao, X. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i1.25154 · Cited by 33
An Overview of Vision Transformers for Image Processing: A Survey
Kameswari, C. S., Kavitha, J., Reddy, T. S., Chinthaguntla, B., Jagatheesaperumal, S. K., Gaftandzhieva, S. N., & Doneva, R. Z. (2023) · International Journal of Advanced Computer Science and Applications · doi:10.14569/ijacsa.2023.0140830 · Cited by 38
Cheng, H., Zhu, J., Lu, J., & Han, X. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.121551 · Cited by 31
A Transformer-based multi-modal fusion network for 6D pose estimation
Hong, J.-X., Zhang, H., Liu, J., Lei, Q., Yang, L., & Du, J. (2024) · Information Fusion · doi:10.1016/j.inffus.2024.102227 · Cited by 32
PointGL: A Simple Global-Local Framework for Efficient Point Cloud Analysis
Li, J., Wang, J., & Xu, T. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3358695 · Cited by 32
Wang, C., Wu, M., Lam, S.-K., Ning, X., Yu, S., Wang, R., Li, W., & Srikanthan, T. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73242-3_5 · Cited by 35
Investigating Attention Mechanism in 3D Point Cloud Object Detection
Qiu, S., Wu, Y., Anwar, S., & Li, C. (2021) · International Conference on 3D Vision (3DV) · doi:10.1109/3dv53792.2021.00050 · Cited by 34
3D point cloud descriptors: state-of-the-art
Han, X.-F., Feng, Z.-A., Sun, S., & Xiao, G. (2023) · Artificial Intelligence Review · doi:10.1007/s10462-023-10486-4 · Cited by 33
Leveraging Single-View Images for Unsupervised 3D Point Cloud Completion
Wu, L., Zhang, Q., Hou, J., & Xu, Y. D. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3340892 · Cited by 32
Point Cloud Learning with TransformerPreprint
Zhong, Q., & Han, X.-F. (2022) · Research Square · doi:10.21203/rs.3.rs-2200447/v1 · Cited by 32
CADTransformer: Panoptic Symbol Spotting Transformer for CAD Drawings
Fan, Z., Chen, T., Wang, P., & Wang, Z. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01071 · Cited by 34
Bala, R., Sharma, A., & Goel, N. (2023) · Archives of Computational Methods in Engineering · doi:10.1007/s11831-023-10002-5 · Cited by 31
Graph Transformer for 3D point clouds classification and semantic segmentation
Zhou, W. M., Wang, Q., Jin, W., Shi, X., & He, Y. (2024) · Computers & Graphics · doi:10.1016/j.cag.2024.104050 · Cited by 31
Introducing Improved Transformer to Land Cover Classification Using Multispectral LiDAR Point Clouds
Zhang, Z., Li, T., Tang, X., Lei, X., & Peng, Y. (2022) · Remote Sensing · doi:10.3390/rs14153808 · Cited by 31
Modeling Fabric-Type Actuator Using Point Clouds by Deep Learning
Peng, Y., Yamaguchi, H., Funabora, Y., & Doki, S. (2022) · IEEE Access · doi:10.1109/access.2022.3204652 · Cited by 31
Point Primitive Transformer for Long-Term 4D Point Cloud Video Understanding
Wen, H., Liu, Y., Huang, J., Duan, B., & Yi, L. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19818-2_2 · Cited by 38
Shu, J., Wang, S., Yu, S., & Zhang, J. (2023) · Computers, materials & continua/Computers, materials & continua (Print) · doi:10.32604/cmc.2023.045818 · Cited by 30
Letard, M., Lague, D., Guennec, A. L., Lefèvre, S., Feldmann, B., Leroy, P., Girardeau-Montaut, D., & Corpetti, T. (2023) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2023.11.022 · Cited by 30
MsSVT++: Mixed-Scale Sparse Voxel Transformer With Center Voting for 3D Object Detection
Li, J., Dong, S., Ding, L., & Xu, T. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3345880 · Cited by 31
Parameter-Efficient Fine-Tuning in Spectral Domain for Point Cloud Learning
Liang, D., Feng, T., Zhou, X., Zhang, Y., Zou, Z., & Bai, X. (2025) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2025.3594749 · Cited by 34
PV-RCNN++: semantical point-voxel feature interaction for 3D object detection
Wu, P., Gu, L., Yan, X., Xie, H., Wang, F. L., Cheng, G., & Wei, M. (2022) · The Visual Computer · doi:10.1007/s00371-022-02672-2 · Cited by 34
StructDiffusion: Language-Guided Creation of Physically-Valid Structures using Unseen Objects
Liu, W., Du, Y., Hermans, T., Chernova, S., & Paxton, C. (2023) · Robotics: Science and Systems · doi:10.15607/rss.2023.xix.031 · Cited by 72
Dense representative tooth landmark/axis detection network on 3D model
Wei, G., Cui, Z., Zhu, J., Yang, L., Zhou, Y., Singh, P., Gu, M., & Wang, W. (2022) · Computer Aided Geometric Design · doi:10.1016/j.cagd.2022.102077 · Cited by 29
Masked Autoencoders for 3D Point Cloud Self-supervised Learning
Pang, Y., Tay, E. H., Li, Y., & Chen, Z. (2024) · World Scientific Annual Review of Artificial Intelligence · doi:10.1142/s2811032324400010 · Cited by 29
PReFormer: A memory-efficient transformer for point cloud semantic segmentation
Akwensi, P. H., Wang, R., & Guo, B. (2024) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2024.103730 · Cited by 29
3DGTN: 3-D Dual-Attention GLocal Transformer Network for Point Cloud Classification and Segmentation
Lu, D., Gao, K., Xie, Q., Xu, L., & Li, J. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3393845 · Cited by 29
Zhang, J. F., Jiang, Z., Qiu, Q., & Liu, Z. (2024) · Pattern Recognition · doi:10.1016/j.patcog.2024.110630 · Cited by 29
Self-citationTowards Efficient Graph Convolutional Networks for Point Cloud Handling
Li, Y., Chen, H. H., Cui, Z., Timofte, R., Pollefeys, M., Chirikjian, G. S., & Gool, L. V. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00373 · Cited by 29
Lin, J., Rickert, M., Perzylo, A., & Knoll, A. (2021) · IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · doi:10.1109/iros51168.2021.9636483 · Cited by 29
PT-FlowNet: Scene Flow Estimation on Point Clouds With Point Transformer
Fu, J., Xiang, Z., Qiao, C., & Bai, T. (2023) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2023.3254431 · Cited by 29
PTC-Net: Point-Wise Transformer With Sparse Convolution Network for Place Recognition
Chen, L., Wang, H., Kong, H., Yang, W., & Ren, M. (2023) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2023.3267693 · Cited by 28
Autoregressive 3D Shape Generation via Canonical Mapping
Cheng, A., Li, X., Liu, S., Sun, M., & Yang, M. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20062-5_6 · Cited by 36
Seiler, M. V., Prager, R. P., Kerschke, P., & Trautmann, H. (2022) · Genetic and Evolutionary Computation Conference (GECCO) · doi:10.1145/3512290.3528834 · Cited by 33
Deep 3D point cloud classification and segmentation network based on GateNet
Liu, H., & Tian, S. (2023) · The Visual Computer · doi:10.1007/s00371-023-02826-w · Cited by 28
Classification of Large-Scale Mobile Laser Scanning Data in Urban Area with LightGBM
Sevgen, E., & Abdikan, S. (2023) · Remote Sensing · doi:10.3390/rs15153787 · Cited by 28
POS-BERT: Point cloud one-stage BERT pre-training
Fu, K., Gao, P., Liu, S., Qu, L., Gao, L., & Wang, M. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.122563 · Cited by 32
Exploring Point-BEV Fusion for 3D Point Cloud Object Tracking With Transformer
Luo, Z., Zhou, C., Pan, L., Zhang, G., Liu, T., Luo, Y., Zhao, H., Liu, Z., & Lu, S. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3373693 · Cited by 28
Self-citationHide in Thicket: Generating Imperceptible and Rational Adversarial Perturbations on 3D Point Clouds
Lou, T., Jia, X., Gu, J., Liu, L., Liang, S., He, B., & Cao, X. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02296 · Cited by 27
Zhao, J., Yang, Z., Chen, Q., Zhang, C., Zhao, J., Zhang, G., Dong, F., & Liu, S. (2025) · Virtual and Physical Prototyping · doi:10.1080/17452759.2024.2449171 · Cited by 27
Hypergraph BiFormer for Semantic Segmentation of High-Resolution Remote Sensing Images
Jing, W., Zhang, W., Di, D., Li, C., Emam, M., & Mian, A. S. (2025) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2025.3543556 · Cited by 29
Radar Ghost Target Detection via Multimodal Transformers
Wang, L., Giebenhain, S., Anklam, C., & Goldlüecke, B. (2021) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2021.3100176 · Cited by 27
PartGlot: Learning Shape Part Segmentation from Language Reference Games
Koo, J., Huang, I., Achlioptas, P., Guibas, L. J., & Sung, M. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01601 · Cited by 27
Unsupervised distribution-aware keypoints generation from 3D point clouds
Wu, Y., Chen, X., Huang, X., Song, K., & Zhang, D. (2024) · Neural Networks · doi:10.1016/j.neunet.2024.106158 · Cited by 27
Shape registration in the time of transformersPreprint
Trappolini, G., Cosmo, L., Moschella, L., Marin, R., Melzi, S., & Rodolà, E. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.13679 · Cited by 29
Change Detection Needs Change Information: Improving Deep 3-D Point Cloud Change Detection
de Gélis, I., Corpetti, T., & Lefèvre, S. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3359484 · Cited by 26
CRA-PCN: Point Cloud Completion with Intra- and Inter-level Cross-Resolution Transformers
Rong, Y., Zhou, H., Yuan, L., Mei, C., Wang, J., & Lu, T. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i5.28268 · Cited by 26
TransPose: 6D object pose estimation with geometry-aware Transformer
Lin, X., Wang, D., Zhou, G., Liu, C., & Chen, Q. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.127652 · Cited by 30
Deep learning for three-dimensional (3D) plant phenomics
Jin, S.-C., Li, D.-W., Yun, T., Tang, J., Wang, K., Li, S., Yang, H.-Y., Yang, S., Xu, S., Cao, L., et al. (2025) · Plant Phenomics · doi:10.1016/j.plaphe.2025.100107 · Cited by 30
Metadata
- Authors
- Guo, M.-H., Cai, J.-X., Liu, Z.-N., Mu, T.-J., Martin, R. R., & Hu, S.-M.
- Affiliations
- Tsinghua University (CN)
- Cardiff University (GB)
- Venue
- Computational Visual Media
- Publisher
- Tsinghua University Press
- Published
- 2021-06
- Volume
- 7
- Issue
- 2
- Pages
- 187-199
- ISSN
- 2096-0433 (ISSN-L)
- 2096-0662
- OpenAlex
- W3111535274
- Cited by
- 2,100
- References
- 17
- Citations by year
- 2026: 309 · 2025: 505 · 2024: 515 · 2023: 428 · 2022: 266 · 2021: 76
- FWCI
- 182.77
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Computational Visual Media (publishedVersion, cc-by)
- ORCA Online Research @Cardiff (Cardiff University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Deutsche Forschungsgemeinschaft
- National Natural Science Foundation of China (61761136018, 61521002)
- Topics
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- point cloud processing, point cloud transformer, transformer models, permutation invariance, farthest point sampling, nearest neighbor search, shape classification, part segmentation, semantic segmentation, surface normal estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
