

The DOI matches its Crossref record; 22 of the 22 references it cites were found in a registry or an index.
PCT: Point cloud transformer
Open accessAbstract
The irregular domain and lack of ordering make it challenging to design deep neural networks for point cloud processing. This paper presents a novel framework named Point Cloud Transformer (PCT) for point cloud learning. PCT is based on Transformer, which achieves huge success in natural language processing and displays great potential in image processing. It is inherently permutation invariant for processing a sequence of points, making it well-suited for point cloud learning. To better capture local context within the point cloud, we enhance input embedding with the support of farthest point sampling and nearest neighbor search. Extensive experiments demonstrate that the PCT achieves the state-of-the-art performance on shape classification, part segmentation, semantic segmentation, and normal estimation tasks.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
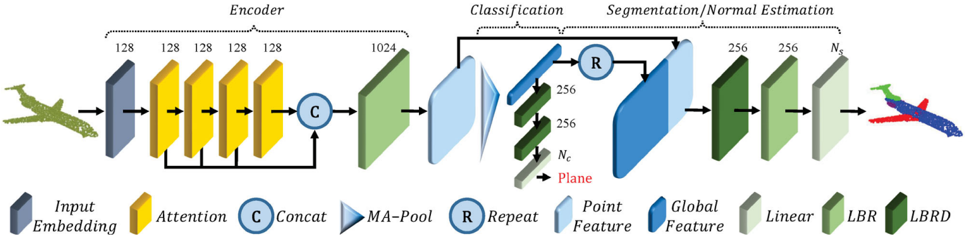
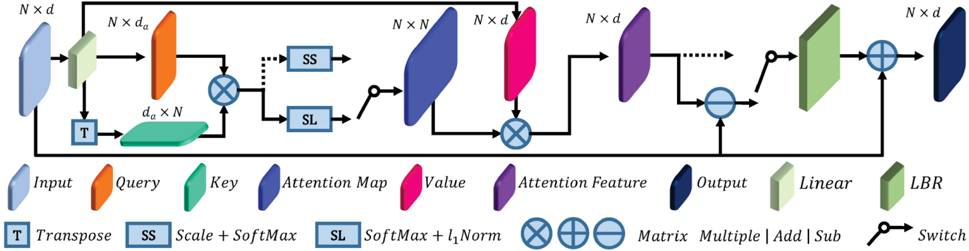
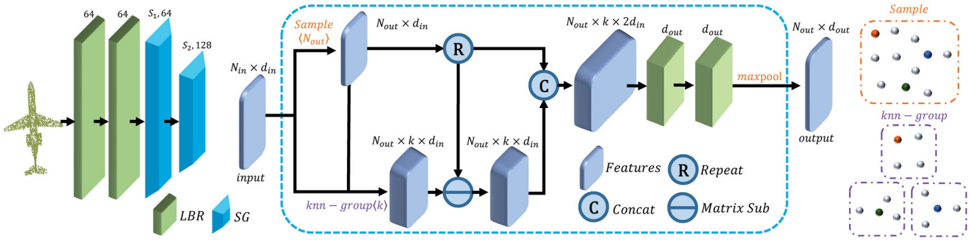
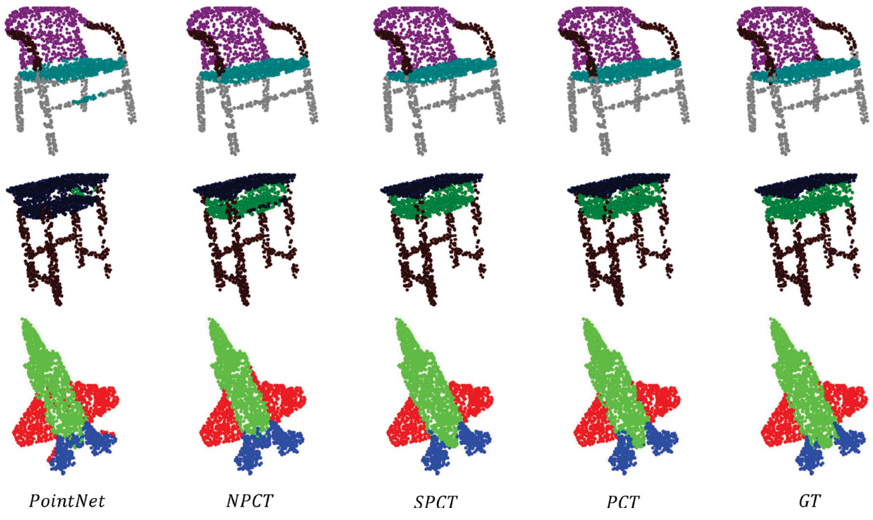
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Cross-lingual gap also should be considered for the transferability of Transformer based multimodal learning, e.g., universal cross-lingual generalization from English to non-English multimodal contexts [206], [277].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [277]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale
Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. (2020) · arXiv · doi:10.48550/arxiv.2010.11929 · Cited by 47,472
Squeeze-and-Excitation Networks
Hu, J., Shen, L., & Sun, G. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00745 · Cited by 35,667
End-to-End Object Detection with Transformers
Carion, N., Massa, F., Synnaeve, G., Usunier, N., Kirillov, A., & Zagoruyko, S. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58452-8_13 · Cited by 18,285
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,474
Squeeze-and-Excitation Networks
Hu, J., Shen, L., Albanie, S., Sun, G., & Wu, E. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2913372 · Cited by 12,157
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Dynamic Graph CNN for Learning on Point Clouds
Wang, Y., Sun, Y., Liu, Z., Sarma, S. E., Bronstein, M. M., & Solomon, J. M. (2019) · ACM Transactions on Graphics · doi:10.1145/3326362 · Cited by 7,199
Self-citationResidual Attention Network for Image Classification
Wang, F., Jiang, M., Qian, C., Yang, S., Li, C., Zhang, H., Wang, X., & Tang, X. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.683 · Cited by 4,073
Research works printed but not linked: 20
- Charles, R. Q.; Hao, S.; Mo, K. C.; Guibas, L. J. PointNet: Deep learning on point sets for 3D classification and segmentation. IN: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 77–85, 2017.
- Tchapmi, L. P.; Choy, C. B.; Armeni, I.; Gwak, J.; Savarese, S. SEGCloud: Semantic segmentation of 3D point clouds. In: Proceedings of the International Conference on 3D Vision, 537–547, 2017.
- Wu, W. X.; Qi, Z.; Fuxin, L. PointConv: Deep convolutional networks on 3D point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9613–9622, 2019.
- Vaswani, A.; Shazeer, N.; Parmar, N.; Uszkoreit, J.; Jones, L.; Gomez, A. N.; Kaiser, L.; Polosukhin, I. Attention is all you need. In: Proceedings of the 31st International Conference on Neural Information Processing, 6000–6010, 2017.
- Bruna, J.; Zaremba, W.; Szlam, A.; LeCun, Y. Spectral networks and locally connected networks on graphs. In: Proceedings of the International Conference on Learning Representations, 2014.
- Hu, S.-M.; Liang, D.; Yang, G.-Y.; Yang, G.-W.; Zhou, W.-Y. Jittor: A novel deep learning framework with meta-operators and unified graph execution. Science China Information Sciences Vol. 63, No. 12, Article No. 222103, 2020.
- Bahdanau, D.; Cho, K. H.; Bengio, Y. Neural machine translation by jointly learning to align and translate. In: Proceedings of the 3rd International Conference on Learning Representations, 2015.
- Lin, Z.; Feng, M.; dos Santos, C. N.; Yu, M.; Xiang, B.; Zhou, B.; Bengio, Y. A structured self-attentive sentence embedding. In: Proceedings of the International Conference on Learning Representations, 2017.
- Yang, Z.; Dai, Z.; Yang, Y.; Carbonell, J. G.; Salakhutdinov, R.; Le, Q. V. XLNet: Generalized autoregressive pretraining for language understanding. In: Proceedings of the 33rd Conference on Neural Information Processing Systems, 5754–5764, 2019.
- Qi, C. R.; Yi, L.; Su, H.; Guibas, L. J. PointNet++: Deep hierarchical feature learning on point sets in a metric space. In: Proceedings of the 31st Conference on Neural Information Processing Systems, 5099–5108, 2017.
- Yang, Y. Q.; Liu, S. L.; Pan, H.; Liu, Y.; Tong, X. PFCNN: Convolutional neural networks on 3D surfaces using parallel frames. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 13575–13584, 2020.
- Yan, X.; Zheng, C. D.; Li, Z.; Wang, S.; Cui, S. G. PointASNL: Robust point clouds processing using nonlocal neural networks with adaptive sampling. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 5588–5597, 2020.
- Hertz, A.; Hanocka, R.; Giryes, R.; Cohen-Or, D. PointGMM: A neural GMM network for point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 12051–12060, 2020.
- Wang, Y.; Solomon, J. Deep closest point: Learning representations for point cloud registration. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 3522–3531, 2019.
- Li, J. X.; Chen, B. M.; Lee, G. H. SO-net: Self-organizing network for point cloud analysis. In: Proceeding of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9397–9406, 2018.
- Klokov, R.; Lempitsky, V. Escape from cells: Deep kdnetworks for the recognition of 3D point cloud models. In: Proceeding of the IEEE International Conference on Computer Vision, 863–872, 2017.
- Le, T.; Duan, Y. PointGrid: A deep network for 3D shape understanding. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 9204–9214, 2018.
- Zhao, H.; Jiang, L.; Fu, C.; Jia, J. PointWeb: Enhancing local neighborhood features for point cloud processing. In: Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 5560–5568, 2019.
- Komarichev, A.; Zhong, Z. C.; Hua, J. A-CNN: Annularly convolutional neural networks on point clouds. In: Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 7413–7422, 2019.
- Thomas, H.; Qi, C. R.; Deschaud, J. E.; Marcotegui, B.; Goulette, F.; Guibas, L. KPConv: Flexible and deformable convolution for point clouds. In: Proceedings of the IEEE/CVF International Conference on Computer Vision, 6410–6419, 2019.
Cited by
Sorted by citations
Items 301–400 of 1,001
Semi-Supervised 6D Object Pose Estimation Without Using Real Annotations
Zhou, G., Wang, D., Yan, Y., Chen, H., & Chen, Q. (2021) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2021.3138129 · Cited by 26
Point attention network for point cloud semantic segmentation
Ren, D., Wu, Z., Li, J., Yu, P., Guo, J. J., Wei, M., & Guo, Y. (2022) · Science China Information Sciences · doi:10.1007/s11432-021-3387-7 · Cited by 26
3D Face Recognition: Two Decades of Progress and Prospects
Guo, Y., Wang, H., Wang, L., Lei, Y., Liu, L., & Bennamoun, M. (2023) · ACM Computing Surveys · doi:10.1145/3615863 · Cited by 26
E2PN: Efficient SE(3)-Equivariant Point Network
Zhu, M., Ghaffari, M., Clark, W. A., & Peng, H. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00124 · Cited by 26
TSegFormer: 3D Tooth Segmentation in Intraoral Scans with Geometry Guided Transformer
Xiong, H., Li, K., Tan, K., Feng, Y., Zhou, J. T., Hao, J., Ying, H., Wu, J., & Liu, Z.-Q. (2023) · International Conference on Medical Image Computing and Computer-Assisted Intervention · doi:10.1007/978-3-031-43987-2_41 · Cited by 30
Self-citationPoint Cloud Registration using Representative Overlapping PointsPreprint
Zhu, L., Liu, D.-R., Lin, C., Yan, R., G'omez-Fern'andez, F., Yang, N.-H., & Feng, Z.-Y. (2021) · arXiv.org · doi:10.48550/arxiv.2107.02583 · Cited by 34
TMVNet : Using Transformers for Multi-view Voxel-based 3D Reconstruction
Peng, K., Islam, R., Quarles, J. P., & Desai, K. (2022) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw56347.2022.00036 · Cited by 25
Lei, T., Xue, D., Ning, H., Yang, S., Lv, Z., & Nandi, A. K. (2022) · IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing · doi:10.1109/jstars.2022.3200997 · Cited by 25
GeoSegNet: point cloud semantic segmentation via geometric encoder–decoder modeling
Chen, C., Wang, Y., Chen, H., Yan, X., Ren, D., Guo, Y., Xie, H., Wang, F. L., & Wei, M. (2023) · The Visual Computer · doi:10.1007/s00371-023-02853-7 · Cited by 25
3DSGrasp: 3D Shape-Completion for Robotic Grasp
Mohammadi, S. S., Duarte, N. F., Dimou, D., Wang, Y., Taiana, M., Morerio, P., Dehban, A., Moreno, P., Bernardino, A. J. M., Bue, A. D., et al. (2023) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra48891.2023.10160350 · Cited by 25
Weakly Supervised Learning for Point Cloud Semantic Segmentation With Dual Teacher
Yao, B., Xiao, H., Zhuang, J., & Peng, C. (2023) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2023.3304116 · Cited by 25
Context-based local-global fusion network for 3D point cloud classification and segmentation
Wu, J., Sun, M., Jiang, C., Liu, J., Smith, J. S., & Zhang, Q. (2024) · Expert Systems with Applications · doi:10.1016/j.eswa.2024.124023 · Cited by 25
PVT: Point-Voxel Transformer for 3D Deep LearningPreprint
Zhang, C., Wan, H., Liu, S., Shen, X., & Wu, Z. (2021) · arXiv (Cornell University) · Cited by 24
Frozen CLIP Transformer Is an Efficient Point Cloud Encoder
Huang, X., Huang, Z., Li, S., Qu, W., He, T., Hou, Y., Zuo, Y., & Ouyang, W. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i3.28013 · Cited by 30
Deep learning network for indoor point cloud semantic segmentation with transferability
Li, L., Chen, J., Su, X., Han, H., & Fan, C. (2024) · Automation in Construction · doi:10.1016/j.autcon.2024.105806 · Cited by 24
SAPFormer: Shape-aware propagation Transformer for point clouds
Xiao, G., Ge, S. S., Zhong, Y., Xiao, Z., Song, J., & Lu, J. (2025) · Pattern Recognition · doi:10.1016/j.patcog.2025.111578 · Cited by 24
Qiao, G., Zhang, Z., Niu, B., Han, S., & Yang, E. (2025) · Frontiers in Plant Science · doi:10.3389/fpls.2025.1491170 · Cited by 24
Sun, Z., Meng, C., Huang, T., Zhang, A., & Chang, S. (2023) · PLoS ONE · doi:10.1371/journal.pone.0279248 · Cited by 25
Variational Relational Point Completion Network for Robust 3D Classification
Pan, L., Chen, X., Cai, Z., Zhang, J., Zhao, H., Yi, S., & Liu, Z. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3268305 · Cited by 24
Self-citationLi, Y., Wang, Y., & Liu, Y. (2023) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2023.3272047 · Cited by 24
Tang, Y., Li, X., Xu, J., Qiao, Y., Hu, L., Hao, Y., & Chen, M. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3282568 · Cited by 25
Fully Sparse Transformer 3-D Detector for LiDAR Point Cloud
Zhang, D., Zheng, Z., Niu, H., Wang, X., & Liu, X. (2023) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2023.3328929 · Cited by 25
Retro-FPN: Retrospective Feature Pyramid Network for Point Cloud Semantic Segmentation
Xiang, P., Wen, X., Liu, Y.-S., Zhang, H., Fang, Y., & Han, Z. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01634 · Cited by 24
Improving transferability of 3D adversarial attacks with scale and shear transformations
Zhang, J., Dong, Y., Zhu, J., Zhu, J., Kuang, M., & Yuan, X. (2024) · Information Sciences · doi:10.1016/j.ins.2024.120245 · Cited by 26
PointWavelet: Learning in Spectral Domain for 3-D Point Cloud Analysis
Wen, C. Z., Long, J., Yu, B., & Tao, D. (2024) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2024.3363244 · Cited by 24
Semantic segmentation of point clouds of ancient buildings based on weak supervision
Zhao, J., Haiquan, Y., Hua, X., Wang, X. Y., Yang, J. N., Zhao, J., & Xu, A. (2024) · Heritage Science · doi:10.1186/s40494-024-01353-8 · Cited by 23
Wang, L., Lu, D., Xu, L., Robinson, D. T., Tan, W., Xie, Q., Guan, H., Chapman, M. A., & Li, J. (2024) · Remote Sensing of Environment · doi:10.1016/j.rse.2024.114456 · Cited by 23
Lu, H., Li, B., Yang, G., Fan, G., Wang, H., Pang, Y., Wang, Z., Lian, Y., Xu, H., & Huang, H. (2025) · Remote Sensing of Environment · doi:10.1016/j.rse.2024.114591 · Cited by 26
Density-Imbalance-Eased LiDAR Point Cloud Upsampling via Feature Consistency Learning
Chen, T.-Y., Hsiao, C.-C., & Huang, C.-C. (2022) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2022.3162672 · Cited by 23
LSLPCT: An Enhanced Local Semantic Learning Transformer for 3-D Point Cloud Analysis
Song, Y., He, F., Duan, Y., Si, T., & Bai, J. (2022) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2022.3202823 · Cited by 23
Projected Generative Adversarial Network for Point Cloud Completion
Tan, L., Lin, X., Niu, D., Wang, D., Yin, M., & Zhao, X. (2022) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2022.3204771 · Cited by 23
Jalalifar, S. A., Soliman, H., Sahgal, A., & Naini, A. S. (2022) · IEEE Journal of Translational Engineering in Health and Medicine · doi:10.1109/jtehm.2022.3219625 · Cited by 23
Long-Short Range Adaptive Transformer With Dynamic Sampling for 3D Object Detection
Wang, C., Deng, J., He, J., Zhang, T., Zhang, Z., & Zhang, Y. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3272734 · Cited by 23
GAM: Gradient Attention Module of Optimization for Point Clouds Analysis
Hu, H., Wang, F., Zhang, Z., Wang, Y., Hu, L., & Zhang, Y. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i1.25162 · Cited by 23
Long and Short-Range Dependency Graph Structure Learning Framework on Point Cloud
Liang, J., Du, Z., Liang, J., Yao, K., & Cao, F. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3298711 · Cited by 23
STMT: A Spatial-Temporal Mesh Transformer for MoCap-Based Action Recognition
Zhu, X., Huang, P.-Y., Liang, J., de Melo, C. M., & Hauptmann, A. G. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00153 · Cited by 23
End-to-End Transformer for Compressed Video Quality Enhancement
Yu, L., Chang, W., Wu, S., & Gabbouj, M. (2023) · IEEE Transactions on Broadcasting · doi:10.1109/tbc.2023.3332015 · Cited by 23
Feature extraction and representation learning of 3D point cloud data
Si, H., & Wei, X. (2024) · Image and Vision Computing · doi:10.1016/j.imavis.2023.104890 · Cited by 23
3DHacker: Spectrum-based Decision Boundary Generation for Hard-label 3D Point Cloud Attack
Tao, Y., Liu, D., Zhou, P., Xie, Y., Du, W. F., & Hu, W. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01319 · Cited by 26
Ma, C., & Liu, Z. (2024) · IEEE Sensors Journal · doi:10.1109/jsen.2024.3355421 · Cited by 25
Self-citationDeep-learning-based point cloud completion methods: A review
Zhang, K., Zhang, A., Wang, X., & Li, W. (2024) · Graphical Models · doi:10.1016/j.gmod.2024.101233 · Cited by 26
Zhang, L., Wei, Z., Xiao, Z., Ji, A., & Wu, B. (2024) · Automation in Construction · doi:10.1016/j.autcon.2024.105799 · Cited by 22
Point-MPP: Point Cloud Self-Supervised Learning From Masked Position Prediction
Fan, S., Gao, W., & Li, G. (2024) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2024.3479309 · Cited by 23
Eskandari, H., Imani, M., & Moghaddam, M. P. (2024) · Energy · doi:10.1016/j.energy.2024.134168 · Cited by 26
Unsupervised deep learning for semantic segmentation of multispectral LiDAR forest point clouds
Ruoppa, L., Oinonen, O., Taher, J., Lehtomäki, M., Takhtkeshha, N., Kukko, A., Kaartinen, H., & Hyyppa, J. M. (2025) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2025.07.038 · Cited by 22
Learning Canonical View Representation for 3D Shape Recognition with Arbitrary Views
Wei, X., Gong, Y., Wang, F., Sun, X., & Sun, J. Z. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00046 · Cited by 22
A Survey on Transformers for Point Cloud Processing: An Updated Overview
Zeng, J., Wang, D., & Chen, P. (2022) · IEEE Access · doi:10.1109/access.2022.3198999 · Cited by 26
Wu, C., Bi, X., Pfrommer, J., Cebulla, A., Mangold, S., & Beyerer, J. (2023) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv56688.2023.00451 · Cited by 22
Classification of Individual Tree Species Using UAV LiDAR Based on Transformer
Sun, P., Yuan, X., & Li, D. (2023) · Forests · doi:10.3390/f14030484 · Cited by 22
FGPNet: A weakly supervised fine-grained 3D point clouds classification network
Shao, H., Bai, J., Wu, R., Jiang, J., & Liang, H. (2023) · Pattern Recognition · doi:10.1016/j.patcog.2023.109509 · Cited by 22
Sketch-Segformer: Transformer-Based Segmentation for Figurative and Creative Sketches
Zheng, Y., Xie, J., Sain, A., Song, Y.-Z., & Ma, Z. (2023) · IEEE Transactions on Image Processing · doi:10.1109/tip.2023.3302521 · Cited by 22
Zhang, Q., & Hou, J. (2023) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2023.3345353 · Cited by 23
Scenario Engineering for Autonomous Transportation: A New Stage in Open-Pit Mines
Teng, S., Li, X., Li, Y., Li, L., Xuanyuan, Z., Ai, Y., & Chen, L. (2024) · IEEE Transactions on Intelligent Vehicles · doi:10.1109/tiv.2024.3373495 · Cited by 22
Saranti, A., Pfeifer, B., Gollob, C., Stampfer, K., & Holzinger, A. (2024) · Wiley Interdisciplinary Reviews Data Mining and Knowledge Discovery · doi:10.1002/widm.1554 · Cited by 24
Zheng, Q., Wu, S., & Wei, J. (2025) · Information Processing & Management · doi:10.1016/j.ipm.2025.104155 · Cited by 22
Li, H., Hao, K., Wei, B., Tang, X., & Hu, Q. (2022) · Neurocomputing · doi:10.1016/j.neucom.2022.02.077 · Cited by 21
ARM3D: Attention-based relation module for indoor 3D object detection
Lan, Y., Duan, Y., Liu, C., Zhu, C., Xiong, Y., Huang, H. F., & Xu, K. (2022) · Computational Visual Media · doi:10.1007/s41095-021-0252-6 · Cited by 23
Prager, R. P., Seiler, M. V., Trautmann, H., & Kerschke, P. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-14714-2_1 · Cited by 22
Zhou, Z., Li, X., He, J., Bi, X., Chen, Y., Wang, G., & Zhu, P. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10096544 · Cited by 21
The Art of Defense: Letting Networks Fool the Attacker
Zhang, J., Dong, Y., Kuang, M., Liu, B., Ouyang, B., Zhu, J., Wang, H., & Meng, Y. (2023) · IEEE Transactions on Information Forensics and Security · doi:10.1109/tifs.2023.3278458 · Cited by 22
Wang, J., Zhu, H., Guo, H., Mamun, A. A., Xiang, C., & Lee, T. H. (2023) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra48891.2023.10160429 · Cited by 21
3D Spatial Multimodal Knowledge Accumulation for Scene Graph Prediction in Point Cloud
Feng, M., Hou, H., Zhang, L., Wu, Z., Guo, Y., & Mian, A. S. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00886 · Cited by 29
Inter-Modal Masked Autoencoder for Self-Supervised Learning on Point Clouds
Liu, J., Wu, Y., Gong, M., Liu, Z., Miao, Q., & Ma, W. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3317998 · Cited by 25
Self-citationRadar Instance Transformer: Reliable Moving Instance Segmentation in Sparse Radar Point Clouds
Zeller, M., Sandhu, V. S., Mersch, B., Behley, J., Heidingsfeld, M., & Stachniss, C. (2023) · IEEE Transactions on Robotics · doi:10.1109/tro.2023.3338972 · Cited by 23
Structure-Aware Cross-Modal Transformer for Depth Completion
Zhao, L., Wei, Y., Li, J., Zhou, J., & Lu, J. (2024) · IEEE Transactions on Image Processing · doi:10.1109/tip.2024.3355807 · Cited by 21
GridFormer: Point-Grid Transformer for Surface Reconstruction
Li, S., Gao, G., Liu, Y., Liu, Y.-S., & Gu, M. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i4.28100 · Cited by 21
Event Voxel Set Transformer for Spatiotemporal Representation Learning on Event Streams
Xie, B., Deng, Y., Shao, Z., Xu, Q., & Li, Y. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3448615 · Cited by 32
Point cloud semantic segmentation with adaptive spatial structure graph transformer
Han, T., Chen, Y., Ma, J., Liu, X., Zhang, W., Zhang, X., & Wang, H. (2024) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2024.104105 · Cited by 24
Ahmed, S., Abdullah, S., & Cho, S. H. (2024) · IEEE Sensors Journal · doi:10.1109/jsen.2024.3452110 · Cited by 21
S4R: Rethinking Point Cloud Sampling via Guiding Upsampling-Aware Perception
Li, Z., Liu, S., Gao, W., Li, G., & Li, G. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3586148 · Cited by 21
DMANet: Dual-branch multiscale attention network for real-time semantic segmentation
Dong, Y., Mao, C., Zheng, L., & Wu, Q. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.128991 · Cited by 20
Online Segmentation of LiDAR Sequences: Dataset and Algorithm
Loiseau, R., Aubry, M., & Landrieu, L. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19839-7_18 · Cited by 19
GeometryMotion-Transformer: An End-to-End Framework for 3D Action Recognition
Liu, J., Guo, J., & Xu, D. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3198011 · Cited by 20
3D deep-learning-enhanced void-growing approach in creating geometric digital twins of buildings
Pan, Y., Braun, A., Borrmann, A., & Brilakis, I. (2022) · Proceedings of the Institution of Civil Engineers - Smart Infrastructure and Construction · doi:10.1680/jsmic.21.00035 · Cited by 20
Few-Shot Class-Incremental Learning for 3D Point Cloud Objects
Chowdhury, T. F., Cheraghian, A., Ramasinghe, S., Ahmadi, S., Saberi, M., & Rahman, S. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20044-1_12 · Cited by 20
SemAffiNet: Semantic-Affine Transformation for Point Cloud Segmentation
Wang, Z., Rao, Y., Yu, X., Zhou, J., & Lu, J. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01152 · Cited by 20
Kernel-based feature aggregation framework in point cloud networks
Zhang, J., Zhang, Z.-X., Wang, L., Zhou, L., Zhang, X., Liu, M., & Wu, W. (2023) · Pattern Recognition · doi:10.1016/j.patcog.2023.109439 · Cited by 20
Unbinned deep learning jet substructure measurement in high Q2 ep collisions at HERA
Andreev, V., Arratia, M., Baghdasaryan, A., Baty, A., Begzsuren, K., Bolz, A. E., Boudry, V., Brandt, G., Britzger, D., Bunyatyan, A., et al. (2023) · Physics Letters B · doi:10.1016/j.physletb.2023.138101 · Cited by 20
SemanticFlow: Semantic Segmentation of Sequential LiDAR Point Clouds From Sparse Frame Annotations
Zhao, J., Huang, W., Wu, H. Y., Wen, C., Yang, B., Guo, Y., & Wang, C. (2023) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2023.3264102 · Cited by 21
Liu, H., Du, J., Zhang, Y., & Zhang, H. (2023) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2023.106227 · Cited by 20
SEFormer: Structure Embedding Transformer for 3D Object Detection
Feng, X., Du, H., Fan, H., Duan, Y., & Liu, Y. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i1.25139 · Cited by 21
ST-PCT: Spatial–Temporal Point Cloud Transformer for Sensing Activity Based on mmWave
Kang, L., Li, Z., Zhao, X., Zhao, Z., & Braun, T. I. (2023) · IEEE Internet of Things Journal · doi:10.1109/jiot.2023.3329236 · Cited by 20
Yan, S., Pan, X., & Wang, Y. (2023) · Digital Signal Processing · doi:10.1016/j.dsp.2023.104308 · Cited by 20
Enhanced multi-scale networks for semantic segmentation
Li, T., Cui, Z., Yu, H., Li, G., Li, M., & Wei, D. (2023) · Complex & Intelligent Systems · doi:10.1007/s40747-023-01279-x · Cited by 20
Wu, Z., Zhang, Y., Lan, R., Qiu, S., Ran, S., & Liu, Y. (2024) · Expert Systems with Applications · doi:10.1016/j.eswa.2024.123990 · Cited by 20
DeepPCC: Learned Lossy Point Cloud Compression
Zhang, J., Liu, G., Zhang, J., Ding, D., & Ma, Z. (2024) · IEEE Transactions on Emerging Topics in Computational Intelligence · doi:10.1109/tetci.2024.3467192 · Cited by 20
Dynamic 3D Point Cloud Sequences as 2D Videos
Zeng, Y., Hou, J., Zhang, Q., Ren, S., & Wang, W. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3421359 · Cited by 19
A survey of intracranial aneurysm detection and segmentation
Hsu, W.-C., Meuschke, M., Frangi, A. F., Preim, B., & Lawonn, K. (2025) · Medical Image Analysis · doi:10.1016/j.media.2025.103493 · Cited by 21
Weight prediction method for individual live chickens based on single-view point cloud information
Zheng, H., Ma, C., Liu, D., Huang, J., Chen, R., Fang, C., Yang, J., Berckmans, D., Norton, T., & Zhang, T. (2025) · Computers and Electronics in Agriculture · doi:10.1016/j.compag.2025.110232 · Cited by 19
SPAC: Sampling-Based Progressive Attribute Compression for Dense Point Clouds
Mao, X., Yuan, H., Guo, T., Jiang, S., Hamzaoui, R., & Kwong, S. (2025) · IEEE Transactions on Image Processing · doi:10.1109/tip.2025.3565214 · Cited by 19
Can attention enable MLPs to catch up with CNNs?
Guo, M.-H., Liu, Z.-N., Mu, T., Liang, D., Martin, R. R., & Hu, S. (2021) · Computational Visual Media · doi:10.1007/s41095-021-0240-x · Cited by 20
Self-citationTse, T. H. E., Zhang, Z., Kim, K. I., Leonardis, A., Zheng, F., & Chang, H. J. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19769-7_33 · Cited by 19
OBMO: One Bounding Box Multiple Objects for Monocular 3D Object Detection
Huang, C., He, T., Ren, H., Wang, W., Lin, B., & Cai, D. (2023) · IEEE Transactions on Image Processing · doi:10.1109/tip.2023.3333225 · Cited by 19
MSHP3D: Multi-stage cross-modal fusion based on Hybrid Perception for indoor 3D object detection
Jiang, X., Wang, D., Bi, K., Wang, S., & Zhang, M. (2024) · Information Fusion · doi:10.1016/j.inffus.2024.102591 · Cited by 19
MPVNN: Multi-resolution Point-Voxel Non-parametric Network for 3D Point Cloud Processing
Wen, K., Zhang, N., Li, G., & Gao, W. (2024) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme57554.2024.10687520 · Cited by 19
Small but mighty: Enhancing 3D point clouds semantic segmentation with U-Next framework
Zeng, Z., Hu, Q., Xie, Z., Li, B., Zhou, J., & Xu, Y. (2024) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2024.104309 · Cited by 19
VG-VAE: A Venatus Geometry Point-Cloud Variational Auto-Encoder
Anvekar, T., Tabib, R. A., Hegde, D., & Mudengudi, U. (2022) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw56347.2022.00336 · Cited by 19
Key Technologies and Trends of Active Robotic 3-D Measurement in Intelligent Manufacturing
Peng, W., Wang, W., Wang, Y., Zhang, H., Mao, J., Liu, M., Zhao, J., Tang, Y., & Huang, Z. (2024) · IEEE/ASME Transactions on Mechatronics · doi:10.1109/tmech.2024.3396222 · Cited by 19
Uni-to-Multi Modal Knowledge Distillation for Bidirectional LiDAR-Camera Semantic Segmentation
Sun, T., Zhang, Z., Tan, X., Peng, Y. L., Qu, Y., & Xie, Y. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3451658 · Cited by 18
PBWR: Parametric-Building-Wireframe Reconstruction from Aerial LiDAR Point Clouds
Huang, S., Wang, R., Guo, B., & Yang, H. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02624 · Cited by 18
Metadata
- Authors
- Guo, M.-H., Cai, J.-X., Liu, Z.-N., Mu, T.-J., Martin, R. R., & Hu, S.-M.
- Affiliations
- Tsinghua University (CN)
- Cardiff University (GB)
- Venue
- Computational Visual Media
- Publisher
- Tsinghua University Press
- Published
- 2021-06
- Volume
- 7
- Issue
- 2
- Pages
- 187-199
- ISSN
- 2096-0433 (ISSN-L)
- 2096-0662
- OpenAlex
- W3111535274
- Cited by
- 2,100
- References
- 17
- Citations by year
- 2026: 309 · 2025: 505 · 2024: 515 · 2023: 428 · 2022: 266 · 2021: 76
- FWCI
- 182.77
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Computational Visual Media (publishedVersion, cc-by)
- ORCA Online Research @Cardiff (Cardiff University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Deutsche Forschungsgemeinschaft
- National Natural Science Foundation of China (61761136018, 61521002)
- Topics
- Physical Sciences › Computer Science › Computer Graphics and Computer-Aided Design › 3D Shape Modeling and Analysis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- point cloud processing, point cloud transformer, transformer models, permutation invariance, farthest point sampling, nearest neighbor search, shape classification, part segmentation, semantic segmentation, surface normal estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
