

The DOI matches its Crossref record; 113 of the 120 references it cites were found in a registry or an index, and 7 are not checked yet.
The application of large language models in medicine: A scoping review
Open accessAbstract
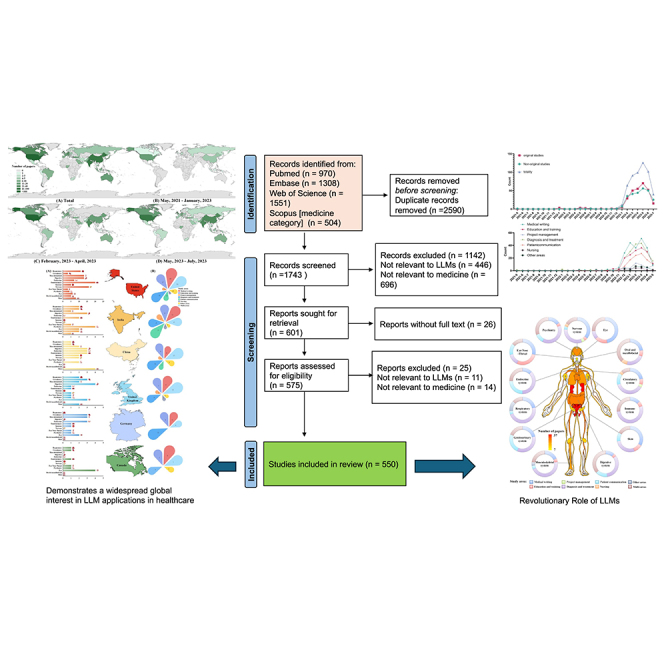
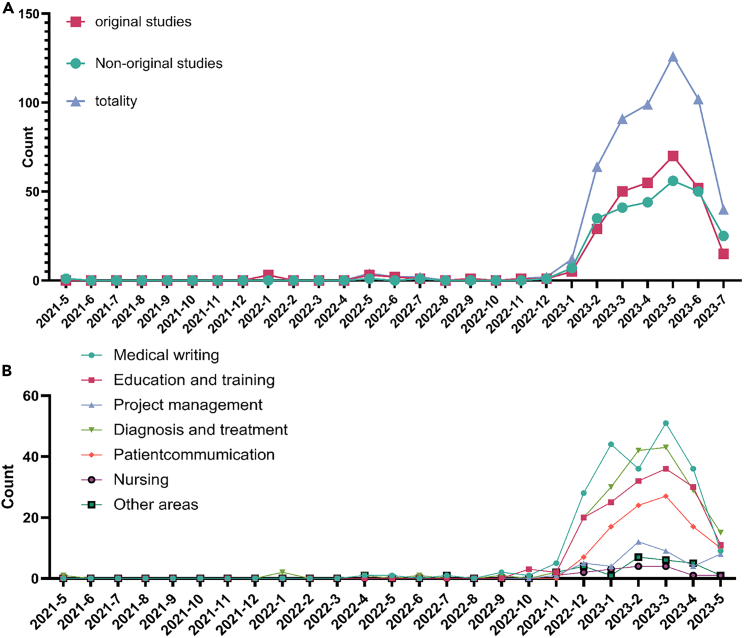
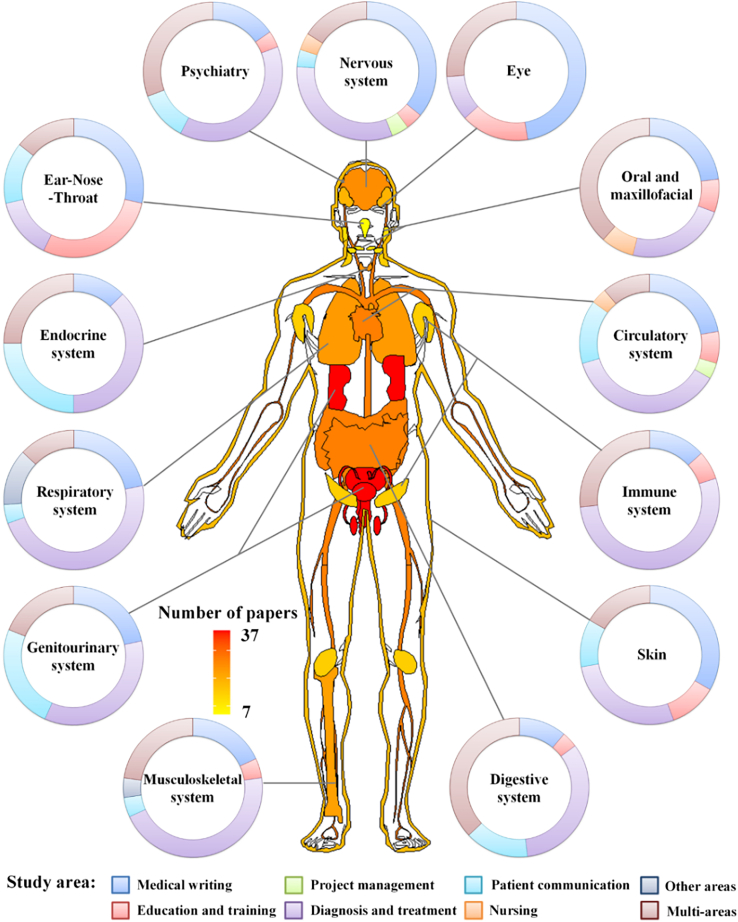
This study systematically reviewed the application of large language models (LLMs) in medicine, analyzing 550 selected studies from a vast literature search. LLMs like ChatGPT transformed healthcare by enhancing diagnostics, medical writing, education, and project management. They assisted in drafting medical documents, creating training simulations, and streamlining research processes. Despite their growing utility in assisted diagnosis and improving doctor-patient communication, challenges persisted, including limitations in contextual understanding and the risk of over-reliance. The surge in LLM-related research indicated a focus on medical writing, diagnostics, and patient communication, but highlighted the need for careful integration, considering validation, ethical concerns, and the balance with traditional medical practice. Future research directions suggested a focus on multimodal LLMs, deeper algorithmic understanding, and ensuring responsible, effective use in healthcare.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Large Language Models (LLMs) are increasingly used by healthcare professionals and patients for medical information synthesis.”
From Large Language Model Hallucinations in Spine Surgery: A Comparative Analysis of Clinician vs Patient-Level Prompts (2026) · cites this paper as [1]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Existing reviews of LLMs in healthcare have largely neglected a deeper analysis of explainability methods.”
From Explainability of decoder-only clinical large language models: A scoping review (2026) · cites this paper as [48]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Scoping studies: advancing the methodology
Levac, D., Colquhoun, H., & O'Brien, K. K. (2010) · Implementation Science · doi:10.1186/1748-5908-5-69 · Cited by 15,268
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Self-citationTraining language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Large language models in medicine
Thirunavukarasu, A. J., Ting, D. S. J., Elangovan, K., Gutierrez, L., Tan, T. F., & Ting, D. S. W. (2023) · Nature Medicine · doi:10.1038/s41591-023-02448-8 · Cited by 3,944
Revolutionizing healthcare: the role of artificial intelligence in clinical practice
Alowais, S. A., Alghamdi, S. S., Alsuhebany, N., Alqahtani, T., Alshaya, A. I., Almohareb, S. N., Aldairem, A., Alrashed, M., Bin Saleh, K., Badreldin, H. A., et al. (2023) · BMC Medical Education · doi:10.1186/s12909-023-04698-z · Cited by 3,146
Training Language Models to Follow Instructions with Human Feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2011 · Cited by 3,117
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
Self-citationA Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Wang, X., Hou, Y., Min, Y., Zhang, B., Zhang, J., Dong, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.18223 · Cited by 2,090
Self-citation
Research works printed but not linked: 2
- Thirunavukarasu, 2023, Large language models in medicine, Nat. Med., 29, 1930, 10.1038/s41591-023-02448-8 · DOI · Paper page
- Chen, 2023, Large language models in biomedical natural language processing: benchmarks, baselines, and recommendations, arXiv
Cited by
Sorted by citations
Items 101–200 of 434
The AI Annotator: Large Language Models’ Potential in Scoring Sustainability Reports
Wu, Y., Hu, P., & Wang, D. D. (2025) · Systems · doi:10.3390/systems13100899 · Cited by 11
Šimunović, I., Rezić, K., Franić, N., Boduljak, G., Batinić, M., Jukić, I. K. D., Jelovina, I., Biočić, J., Pogorelić, Z., & Markić, J. (2025) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-025-03258-3 · Cited by 9
Salehin, I., Sajib, M. T. A., Badhon, N. H., Rifat, M. S. H., Amin, N., & Moon, N. N. (2025) · Engineering Reports · doi:10.1002/eng2.70365 · Cited by 9
MedReadCtrl: Personalizing medical text generation with readability-controlled instruction learningPreprint
Tran, H., Yao, Z., Jang, W. S., Sultana, S., Chang, A., Zhang, Y., & Hong, Y. (2025) · medRxiv · doi:10.1101/2025.07.09.25331239 · Cited by 12
Papageorgiou, P. S., Christodoulou, R. C., Pitsillos, R., Petrou, V., Vamvouras, G., Kormentza, E. V., Papagelopoulos, P. J., & Georgiou, M. F. (2025) · Applied Sciences · doi:10.3390/app15169005 · Cited by 8
Guo, L., Zuo, Y., Yisha, Z., Liu, J., Gu, A., Yushan, R., Liu, G., Li, S., Liu, T., & Wang, X. (2025) · BMC Urology · doi:10.1186/s12894-025-01740-8 · Cited by 8
Self-citationDennstädt, F., Schmerder, M., Riggenbach, E., Mose, L., Bryjova, K., Bachmann, N., Mackeprang, P., Ahmadsei, M., Sinovcic, D., Windisch, P. Y., et al. (2025) · Journal of Medical Internet Research · doi:10.2196/69752 · Cited by 8
Beckmann, S. A., Link, E., & Bachl, M. (2025) · Journal of Science Communication · doi:10.22323/2.24020204 · Cited by 8
Automated MRI protocoling in neuroradiology in the era of large language models
Reiner, L. N., Chelbi, M., Fetscher, L., Stöckel, J. C., Schmidt, C. G., Guseynova, S., Mohamad, F. A., Bressem, K. K., Nawabi, J., Siebert, E., et al. (2025) · La radiologia medica · doi:10.1007/s11547-025-02040-9 · Cited by 8
Biard, M., Detcheverry, F. E., Betzner, W., Becker, S., Grewal, K. S., Azab, S., Bloniasz, P. F., Mazerolle, E. L., Phelps, J., Smith, E. E., et al. (2025) · Alzheimer s & Dementia · doi:10.1002/alz.70636 · Cited by 8
Susceptibility of Large Language Models to User-Driven Factors in Medical Queries
Lim, K. H., Kang, U., Li, X., Kim, J. S., Jung, Y., Park, S. J., & Kim, B.-H. (2025) · Journal of Healthcare Informatics Research · doi:10.1007/s41666-025-00218-4 · Cited by 8
Hamamoto, R., Koyama, T., Takahashi, S., Yasuda, T., Kobayashi, K., Akagi, Y., Kouno, N., Sudo, K., Hirata, M., Sunami, K., et al. (2026) · Journal of Hematology & Oncology · doi:10.1186/s13045-026-01781-y · Cited by 8
de Souza, F. G., Velasco, K., Cunha, S., Santos, J., Aboelkheir, M. G., Sumini, M., Thiré, R. M. D. S. M., Duarte, P. C., Andrade, A., Díaz-Martín, R. D., et al. (2025) · Journal of Drug Delivery Science and Technology · doi:10.1016/j.jddst.2025.106935 · Cited by 7
Use of ChatGPT in HIV Infection Counselling and Literacy
Ganicho, J., Carlos, M., Cristóvão, G., Cruz, C., Leal, M., Garrote, A. R., Bento, D., Seixas, D., Manata, M. J., & Maltêz, F. (2025) · Acta Médica Portuguesa · doi:10.20344/amp.22805 · Cited by 7
Artificial Intelligence-Driven Nephrology: The Role of Large Language Models in Kidney Care
Zoccali, C., Floyd, L., Cseprekál, O., Eisenga, M. F., Mirioğlu, Ş., Caravaca‐Fontán, F., & Mallamaci, F. (2025) · American Journal of Nephrology · doi:10.1159/000548208 · Cited by 9
Large Language Models: A Paradigm Shift for Dementia Diagnosis and Care
Harrison, J. R., Tang, S. L., Burston, B., Robertson, A., Liang, H., & Taylor, J. (2025) · British Journal of Hospital Medicine · doi:10.12968/hmed.2024.0666 · Cited by 7
Arias, M. I., Cadavid, L., & Velasquez, J. D. (2025) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2025.104934 · Cited by 7
Maitín, A. M., Nogales, A., Fernández-Rincón, S., Aranguren, E., Barba, E. C., Arranz, S. D., Rodríguez, A. A. M., & García-Tejedor, Á. J. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae302 · Cited by 8
Shoorgashti, R., Alimohammadi, M., Baghizadeh, S., Radmard, B., Ebrahimi, H., & Lesan, S. (2025) · Health Science Reports · doi:10.1002/hsr2.70614 · Cited by 7
Xu, Q., Wu, T., Wang, Y., Li, X., Yu, H., Cen, S., & Li, Z. (2025) · Journal of Pharmaceutical Analysis · doi:10.1016/j.jpha.2025.101406 · Cited by 7
Self-citationGeneş, M., & Deveci, B. (2024) · Diagnostics · doi:10.3390/diagnostics14232731 · Cited by 6
Machine learning and partial differential equations: benchmark, simplify, and discover
Koumoutsakos, P. (2025) · Data-Centric Engineering · doi:10.1017/dce.2025.15 · Cited by 8
Med-Aligner empowers LLM medical applications for complex medical scenarios
Meng, X., Ji, J., Yan, X., Dai, J.-T., Chen, B., Wang, G., Xu, H., Wang, J., Wang, X.-L., Liu, D., et al. (2025) · The Innovation · doi:10.1016/j.xinn.2025.101002 · Cited by 6
Self-citationLeveraging Large Language Models for Personalized Parkinson’s Disease Treatment
Zhang, R., Xie, G., Ying, J., & Hua, Z. (2025) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2025.3594014 · Cited by 6
Application of Large Language Models in Automated Interpretation of Urodynamic Parameters
Wang, Z., Xu, Z., Shi, Y., Xi, J., & Zhang, Y. (2025) · Neurourology and Urodynamics · doi:10.1002/nau.70160 · Cited by 6
Self-citationLarge language models in obesity: a systematic review
Suenghataiphorn, T., Tribuddharat, N., Danpanichkul, P., & Kulthamrongsri, N. (2025) · International Journal of Obesity · doi:10.1038/s41366-025-01992-2 · Cited by 7
Bailey, D. J., Anjum, J., Park, H., Carpenter, E., Mamlekar, C. R., & Kurland, J. (2026) · American Journal of Speech-Language Pathology · doi:10.1044/2025_ajslp-25-00262 · Cited by 6
Chen, L., He, R., Lu, P., Jin, Y., Zhou, L., Li, N., Wu, P., & Hu, B. (2026) · Journal of Medical Systems · doi:10.1007/s10916-026-02353-w · Cited by 7
Clinical Plausibility in Large Language Model Robustness Testing for Medicine: A Scoping Review
Chang, Y., Hsieh, M., Ju, P., Liu, Y., & Chang, C. (2026) · Journal of Medical Systems · doi:10.1007/s10916-026-02405-1 · Cited by 6
Jia, Q., Wen, Y., Liu, Y., Zhao, H., Yu, Q., Long, Y., Sun, D., & Yu, Y. (2026) · PLoS ONE · doi:10.1371/journal.pone.0348819 · Cited by 7
Demirbaş, K. C., Saygılı, S., Yılmaz, E. K., Gülmez, R., Ağbaş, A., Taşdemir, M. S., & Canpolat, N. (2025) · Pediatric Transplantation · doi:10.1111/petr.70068 · Cited by 6
S-Health: LLM-driven and Lightweight Blockchain-based Secure Framework for Healthcare 5.0
Kumari, A., Shah, M. H., & Sheth, P. V. (2024) · IEEE Globecom Workshops (GC Wkshps) · doi:10.1109/gcwkshp64532.2024.11100794 · Cited by 6
Kadhim, A. Z., Green, Z., Nazari, I., Baker, J., George, M. R., Heinson, A., Vadgama, B., Stammers, M., Kipps, C., Beattie, R. M., et al. (2025) · Med · doi:10.1016/j.medj.2025.100895 · Cited by 6
Álvarez-Estapé, M., Cano, I., Pino, R., Grado, C. G., Aldemira-Liz, A., Gonzálvez-Ortuño, J., do Olmo, J., Logroño, J., Martínez, M., Mascías, C., et al. (2024) · medRxiv · doi:10.1101/2024.07.23.24310847 · Cited by 6
Demir, S., & Türkeş, İ. C. (2025) · Journal of Craniofacial Surgery · doi:10.1097/scs.0000000000011608 · Cited by 5
Mudumbai, S. C., Chung, P., Chen, J., Litake, O., Regala, S., Madhok, J., Krause, M., Pearl, R. G., Boateng, A., & Gabriel, R. A. (2025) · A&A Practice · doi:10.1213/xaa.0000000000002057 · Cited by 5
Asif, S., Hadi, F., Ain, Q. U., Yan, Y., Wang, V. Y., & Xu, D. (2025) · Computer Science Review · doi:10.1016/j.cosrev.2025.100847 · Cited by 5
The rise of large language models in wearable health sensing
Farrahi, V. (2025) · Intelligent Medicine · doi:10.1016/j.imed.2025.12.003 · Cited by 5
Kumar, V., Mann, N. S., & Sharma, K. (2025) · Australian Endodontic Journal · doi:10.1111/aej.70046 · Cited by 5
Optimization of potential targets for antidepressant Chinese medicines: AI and multi-omics methods
Lei, C., Chen, Z., Ma, C., Xie, L., Wu, D., Chen, J., & Chen, J. (2026) · Chinese Medicine · doi:10.1186/s13020-025-01320-w · Cited by 5
Launes, C., Esteller-Cucala, P., Alvarez‐Estape, M., Cano, I., Pino, R., González‐Grado, C., Aldemira-Liz, A., Logroño, J., Mascías, C., do Olmo, J., et al. (2026) · Pediatric Investigation · doi:10.1002/ped4.70053 · Cited by 5
Interpretable Conversation Routing via the Latent Embeddings Approach
Maksymenko, D., & Turuta, O. (2024) · Computation · doi:10.3390/computation12120237 · Cited by 5
Ratnagandhi, A., Godavarthy, P., Gnaneswaran, M., Lim, B., & Vittalraj, R. (2025) · Anesthesia Research · doi:10.3390/anesthres2010004 · Cited by 5
Large Language Model (LLM) Support for Preliminary Consultation in Healthcare
Fernando, S. P. A. A., & Wickramaarachchi, D. (2025) · International Conference on Advanced Research in Computing (ICARC) · doi:10.1109/icarc64760.2025.10963287 · Cited by 5
Anh, N. V., & Trang, N. T. (2025) · European Journal Of Dental Education · doi:10.1111/eje.70015 · Cited by 7
Aykut, A., Akgün, B., Sezenöz, A. S., Sevik, M. O., & Şahin, Ö. (2024) · Journal of Health Sciences and Medicine · doi:10.32322/jhsm.1506378 · Cited by 4
Bessa, R. F., de Oliveira, A. C., Bessa, R. F., Sousa, D. L., Alves, R., Barbosa, A., Carneiro, A., Soares, C., & Teles, A. S. (2025) · Applied Sciences · doi:10.3390/app15137134 · Cited by 4
Lim, B., Seth, I., Cevik, J., Mu, X., Sofiadellis, F., Cuomo, R., & Rozen, W. M. (2025) · Surgeries · doi:10.3390/surgeries6030055 · Cited by 5
Natural Language Processing and Large Language Models
Wong, G. C., & Chung, K. C. (2025) · Hand Clinics · doi:10.1016/j.hcl.2025.08.004 · Cited by 4
Jo, E., Noh, T. I., & Joo, H. J. (2025) · Diagnostics · doi:10.3390/diagnostics15192474 · Cited by 4
Gupta, A., Rangarajan, K., Kumar, R., & Anshal, S. (2025) · Pediatric Radiology · doi:10.1007/s00247-025-06453-6 · Cited by 4
Nuccetelli, F., Gabellone, V., Marsano, F., Giovanetti, F., Dri, P., Valetto, M. R., & Prato, R. (2025) · European Journal of Public Health · doi:10.1093/eurpub/ckaf189 · Cited by 5
Chu, Y.-C., Chen, Y., Hsu, C., Kuo, C.-T., Cheng, Y., Lin, K., & Liao, W. (2025) · Digital Health · doi:10.1177/20552076251395449 · Cited by 4
Tan, M., Tang, S., Kan, S., Zhang, H., Wu, B., Ni, Z., Lin, C., & Ding, J. (2025) · BMJ Open · doi:10.1136/bmjopen-2025-099226 · Cited by 4
Interpretable stance detection in social media via topic-guided transformers
Muthusami, R., Saritha, K., Rao, K. S., Sugapriya, P., & Saveetha, G. (2025) · Discover Artificial Intelligence · doi:10.1007/s44163-025-00635-9 · Cited by 5
Liu, C., Lin, T.-C., & Ko, Y.-L. (2025) · iScience · doi:10.1016/j.isci.2025.114394 · Cited by 4
Ndukwe, H. C., & Otukpa, E. O. (2026) · PLoS ONE · doi:10.1371/journal.pone.0339594 · Cited by 5
Comparing large language models and search engine responses to common orthodontic questions
Ren, Y., & Sun, J. (2026) · PLoS ONE · doi:10.1371/journal.pone.0339908 · Cited by 4
Artificial intelligence-based tools for optimizing surgical research publications
Coronel, B. V., Marescaux, J., & Giménez, M. (2026) · Artificial Intelligence Surgery · doi:10.20517/ais.2025.112 · Cited by 4
Asiri, R., Ishaqui, A. A., Ahmad, S. A., Imran, M., Orayj, K. M., & Iqbal, A. (2026) · Diagnostics · doi:10.3390/diagnostics16030388 · Cited by 4
More, V., Lu, L., Ding, Z., Ding, Z., Xi, Z., Mizia, S., & Guo, N. (2026) · npj Precision Oncology · doi:10.1038/s41698-025-01265-1 · Cited by 5
Aykut, A., Karayil, A. R., Yildirim, C., Günsoy, E., Tatlı, M., & Avcı, M. (2026) · Scandinavian Journal of Trauma Resuscitation and Emergency Medicine · doi:10.1186/s13049-026-01577-6 · Cited by 4
Exploring the utility of ChatGPT as a learning tool in osteopathic medical education
Martin, P., Pate, N., & Benmerzouga, I. (2026) · International journal of osteopathic medicine · doi:10.1016/j.ijosm.2026.100816 · Cited by 4
Prabhakaran, S., Bell, S. W., Lee, J. C., & Kong, J. C. H. (2026) · European Journal of Surgical Oncology · doi:10.1016/j.ejso.2026.111741 · Cited by 4
Kong, S., Kim, Y., Jeong, I., Park, S., Shon, S., Park, J.-H., Kim, B., Jhon, M., Kim, J., Kim, J.-W., et al. (2026) · Scientific Reports · doi:10.1038/s41598-026-47312-0 · Cited by 4
Large Language Models in Colorectal Cancer Care and Clinical Decision Support: Systematic Review
Tian, J., Lou, Q., Wang, X., xuhangying, Mei, H., & Yu, Y. (2026) · Journal of Medical Internet Research · doi:10.2196/89862 · Cited by 5
Self-citationYang, A. J., Woo, J. J., & Ramkumar, P. N. (2025) · Arthroscopy · doi:10.1016/j.arthro.2025.06.020 · Cited by 4
Performance of multimodal large language models in the Japanese surgical specialist examination
Miyamoto, Y., Nakaura, T., Nakamura, H., Hirai, T., & Iwatsuki, M. (2025) · BMC Medical Education · doi:10.1186/s12909-025-07938-6 · Cited by 3
Carrillo-Larco, R. M., Lovón-Melgarejo, J., Castillo‐Cara, M., & Bravo-Rocca, G. (2026) · Medical Science Educator · doi:10.1007/s40670-026-02692-w · Cited by 3
Jarchow, H., Bobrowski, C., Falk, S. S. I., Hermann, A., Kulaga, A. Y., Põder, J.-C., Unfried, M., Usanov, N., Zendeh, B., Kennedy, B. K., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01996-2 · Cited by 4
Recent Advances and Future Directions of Artificial Intelligence in Glaucoma Management
Tang, W., Hang, Y., Zhang, J., & Dang, Y. (2025) · The Open Ophthalmology Journal · doi:10.2174/0118743641430437251130165439 · Cited by 3
RxSafeBench: Identifying Medication Safety Issues of Large Language Models in Simulated Consultation
Zhao, J., Xu, L., Tan, M., Zhang, L., Argha, A., Alinejad-Rokny, H., & Yang, M. (2025) · IEEE International Conference on Bioinformatics and Biomedicine (BIBM) · doi:10.1109/bibm66473.2025.11356353 · Cited by 3
Khanehzar, E., Shams, F., Jafari, A., & Poustforoosh, A. (2026) · In Silico Pharmacology · doi:10.1007/s40203-026-00582-y · Cited by 3
Choi, M., Park, J., Lee, M., Beom, J., Jung, S. Y., & Lee, K. (2026) · Journal of Clinical Medicine · doi:10.3390/jcm15062457 · Cited by 3
Wass, L. M., Wu, Z., Vizoso, J., Wu, J. T. K., & Lin, L. K. (2026) · Journal of Medical Internet Research · doi:10.2196/80346 · Cited by 4
The digital therapist? LLMs and the future of clinical dialogue
Shi, E. R., Pei, R., & Barceló-Coblijn, L. (2026) · Language and Health · doi:10.1016/j.laheal.2026.100086 · Cited by 3
AI for science: Progress, challenges, and perspectives
Xu, Y., Shao, Z., Liu, X., Li, Y., An, Z., Fu, C., Huang, C., Zhang, L., Gao, F., Li, J., et al. (2026) · The Innovation · doi:10.1016/j.xinn.2026.101530 · Cited by 6
Self-citationTransforming Multimodal Models into Action Models for Radiotherapy
Ferrante, M., Carosi, A., D’Angelillo, R. M., & Toschi, N. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-82007-6_5 · Cited by 3
Andrew, A., & Zhao, S. (2025) · Indian Journal of Surgery · doi:10.1007/s12262-025-04296-x · Cited by 3
Artificial intelligence and dichotomania
McShane, B. B., Gal, D., & Duhachek, A. (2025) · Judgment and Decision Making · doi:10.1017/jdm.2025.7 · Cited by 5
Human vs. AI: Assessing the Quality of Weight Loss Dietary Information Published on the Web
Fappa, E., Micheli, M., Panaretos, D., Skordis, M., Tsirpanli, P., & Panoutsopoulos, G. I. (2025) · Information · doi:10.3390/info16070526 · Cited by 3
Nosta, J. (2024) · American Journal of Hematology · doi:10.1002/ajh.27480 · Cited by 3
Large language models in medicine: current ethical challenges
Kostrov, S. А., & Potapov, M. (2025) · Медицинская этика · doi:10.24075/medet.2025.008 · Cited by 2
Shah, P., Boughanem, D. J., Templeton, J. M., Wiranowska, M., & Hanna, K. (2025) · Cureus · doi:10.7759/cureus.90103 · Cited by 2
Large language models in scientific publications: challenges and opportunities
Vardas, P. E. (2025) · European Heart Journal · doi:10.1093/eurheartj/ehaf669 · Cited by 2
Qing, L., Xue, W. X., Meng, L., Zhu, Y., & Li, J. (2025) · Frontiers in Education · doi:10.3389/feduc.2025.1640684 · Cited by 2
Amirrajab, S., Vehof, V., Bietenbeck, M., & Yılmaz, A. (2026) · Scientific Reports · doi:10.1038/s41598-026-75150-7 · Cited by 2
Exploring Artificial Intelligence's Potential to Enhance Conventional Anticancer Drug Development
Bobolea, S., Hinoveanu, M. I., Dimitriu, A., Brașoveanu, M., Iliescu, C., Dinu‐Pîrvu, C., Ghica, M. V., Anuța, V., Popa, L., & Prisada, R. M. (2025) · Drug Development Research · doi:10.1002/ddr.70182 · Cited by 2
Wei, M.-Y., Li, Y., Liu, S.-Y., & Li, G. (2025) · Frontiers in Cell and Developmental Biology · doi:10.3389/fcell.2025.1704762 · Cited by 2
Clinician’s Guide to Artificial Intelligence
Schroeder, A. W., Tran, Z. K., Sexton, K. W., & Salzberg, A. D. (2025) · Medical Clinics of North America · doi:10.1016/j.mcna.2025.07.010 · Cited by 2
Avsar, D. B., & Ertan, A. A. (2025) · BMC Oral Health · doi:10.1186/s12903-025-07415-y · Cited by 2
Evaluation of the accuracy of large language models in answering bone cancer-related questions
Pan, Q., Huang, L., Liu, N., Lin, F., & Ye, S. (2025) · Frontiers in Public Health · doi:10.3389/fpubh.2025.1719047 · Cited by 2
Jiang, W., Wang, D., Zeng, Y., Huang, J., Xu, C., & Liu, C. (2025) · Journal of Medical Internet Research · doi:10.2196/80770 · Cited by 2
Cutting-edge AI technologies in skin cancer applications
Diao, Y., Chen, X., Huang, Z., Tan, Q., Yang, M., Yu, H., Xu, Y., & Hu, X. (2026) · Cancer Letters · doi:10.1016/j.canlet.2026.218256 · Cited by 2
Olukanni, E. O., Akanmu, A. A., & Jebelli, H. (2026) · ASCE OPEN Multidisciplinary Journal of Civil Engineering · doi:10.1061/aomjah.aoeng-0102 · Cited by 2
Li, X., Hu, X., Xu, H., Sun, Z., Yu, P., & Ju, H. (2026) · PLoS ONE · doi:10.1371/journal.pone.0338328 · Cited by 2
Liu, B., Shang, Q., Li, J., Yao, S., Ouyang, M., Wang, Y., Luo, S., & Ouyang, Q. (2026) · Cancer Innovation · doi:10.1002/cai2.70047 · Cited by 2
Self-citationTool-wielding language model-based agent offers conversational exploration of clinical tabular data
Yang, A. J., Woo, J. J., Zhang, R., Mach, A., Ramkumar, P., & Ma, Y. (2026) · npj Artificial Intelligence · doi:10.1038/s44387-025-00070-2 · Cited by 3
Hoyt, R. E., & Bajwa, M. (2026) · Applied Clinical Informatics · doi:10.1055/a-2807-4256 · Cited by 2
Poser, P. L., Klimas, R., Luerweg, J., Reuter, E., Hanefeld, C., Gold, R., Salmen, A., & Motte, J. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2026.1658575 · Cited by 2
Metadata
- Authors
- Meng, X., Yan, X., Zhang, K., Liu, D., Cui, X., Yang, Y., Zhang, M., Cao, C., Wang, J., Wang, X., Gao, J., Wang, Y.-G.-S., Ji, J.-M., Qiu, Z., Li, M., Qian, C., Guo, T., Ma, S., Wang, Z., Guo, Z., Lei, Y., Shao, C., Wang, W., Fan, H., & Tang, Y.-D.
- Affiliations
- Peking University (CN)
- Tianjin University (CN)
- Chinese Academy of Medical Sciences & Peking Union Medical College (CN)
- Hebei Medical University (CN)
- Peking University Third Hospital (CN)
- Beihang University (CN)
- Corresponding author
- Fan, Haojun
- Tang, Yi-Da
- ORCID
- Venue
- iScience
- Publisher
- Elsevier BV
- Published
- 2024-05
- Volume
- 27
- Issue
- 5
- Pages
- 109713
- ISSN
- 2589-0042 (ISSN-L)
- PMC
- PMC11091685
- OpenAlex
- W4395052272
- Cited by
- 414
- References
- 114
- Citations by year
- 2026: 188 · 2025: 188 · 2024: 38
- FWCI
- 9.44
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- iScience (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- Funders
- National Key Research and Development Program of China Stem Cell and Translational Research (2020YFC2004705)
- National Natural Science Foundation of China (81825003, 82270376, 91957123)
- China Scholarship Council (CSCF2021A04)
- CAMS Innovation Fund for Medical Sciences
- Chinese Academy of Meteorological Sciences (2021-I2M-5-003, T-B-119)
- National Key Research and Development Program of China
- Beijing Municipal Science and Technology Commission, Adminitrative Commission of Zhongguancun Science Park
- Beijing Nova Program (Z201100006820002)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- large language models, ChatGPT, medical applications of AI, medical diagnostics, medical writing, medical education, training simulation, physician-patient communication, overreliance on AI, multimodal large language models, ethics of AI in healthcare
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
