

The DOI matches its Crossref record; 113 of the 120 references it cites were found in a registry or an index, and 7 are not checked yet.
The application of large language models in medicine: A scoping review
Open accessAbstract
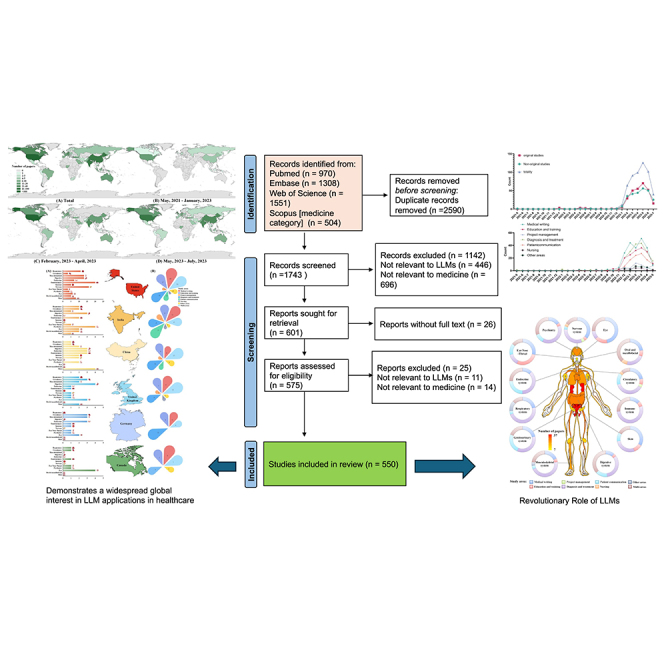
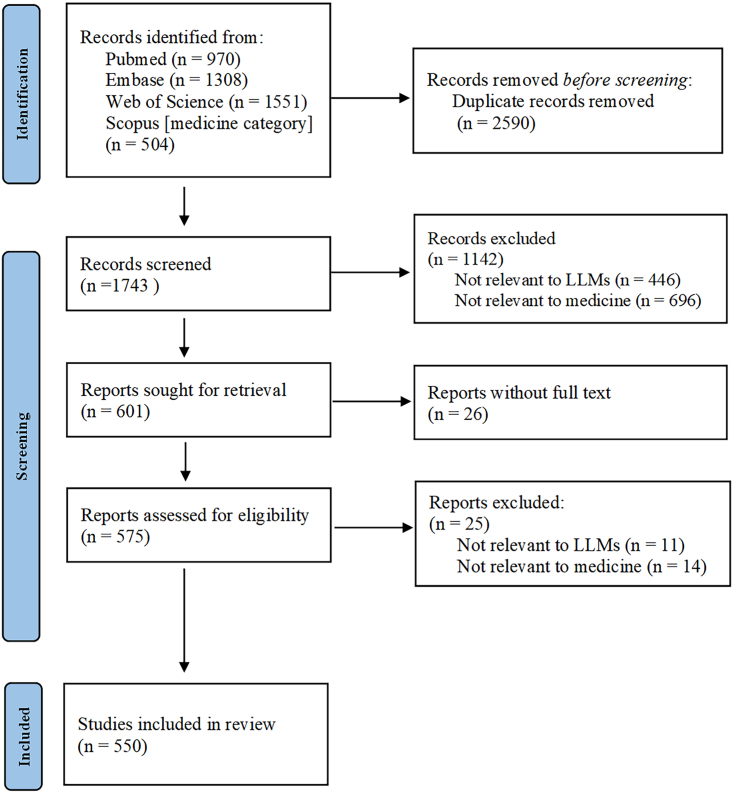
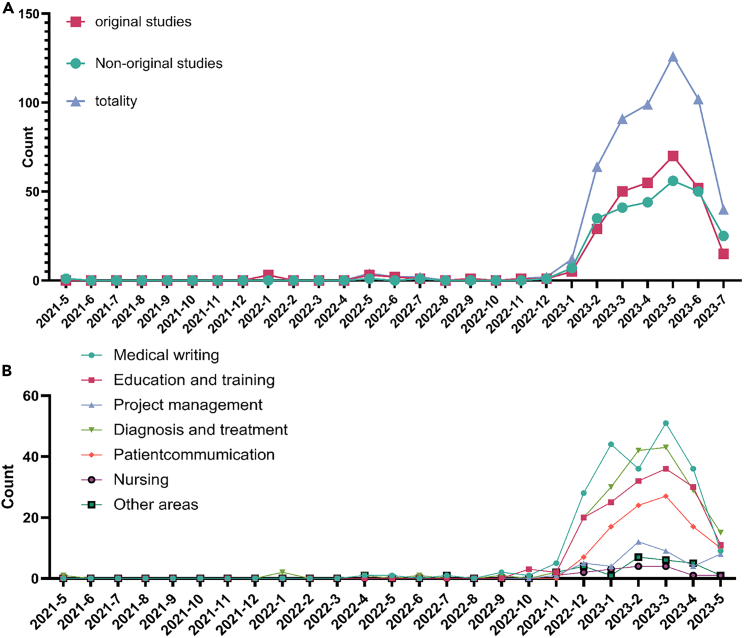
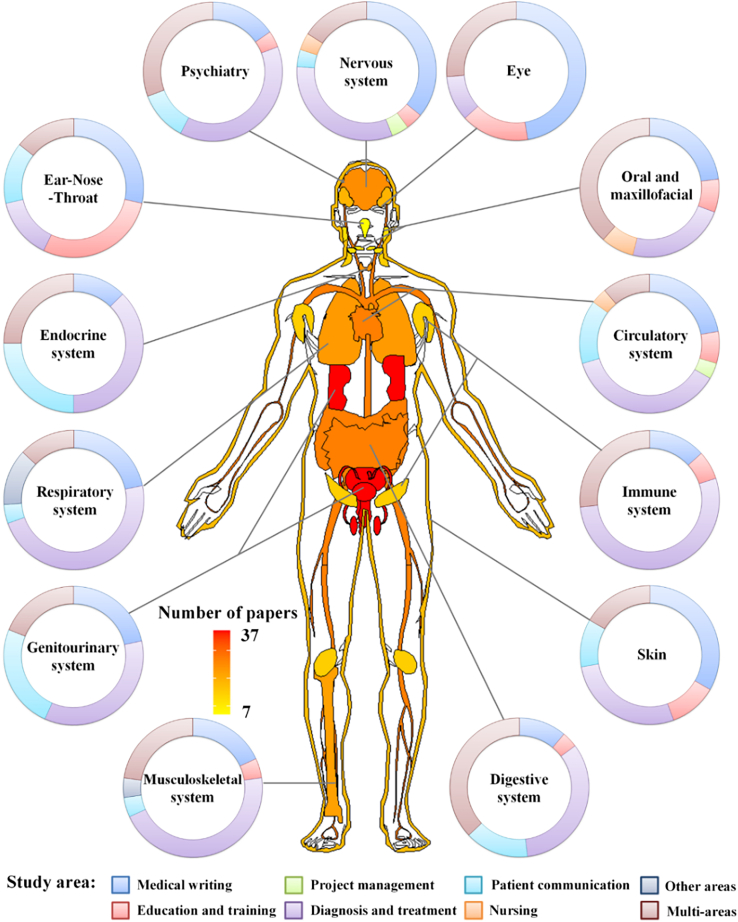
This study systematically reviewed the application of large language models (LLMs) in medicine, analyzing 550 selected studies from a vast literature search. LLMs like ChatGPT transformed healthcare by enhancing diagnostics, medical writing, education, and project management. They assisted in drafting medical documents, creating training simulations, and streamlining research processes. Despite their growing utility in assisted diagnosis and improving doctor-patient communication, challenges persisted, including limitations in contextual understanding and the risk of over-reliance. The surge in LLM-related research indicated a focus on medical writing, diagnostics, and patient communication, but highlighted the need for careful integration, considering validation, ethical concerns, and the balance with traditional medical practice. Future research directions suggested a focus on multimodal LLMs, deeper algorithmic understanding, and ensuring responsible, effective use in healthcare.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
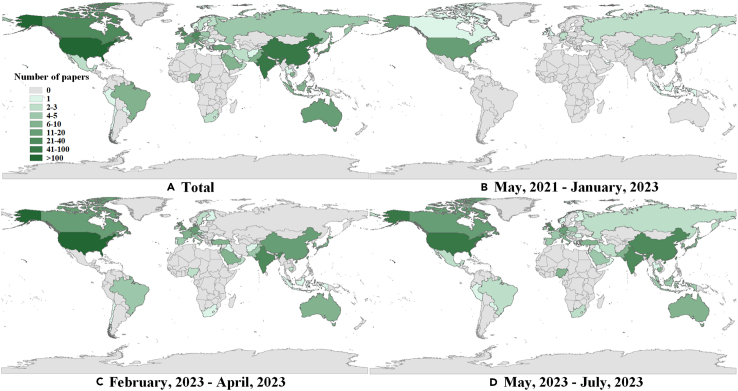
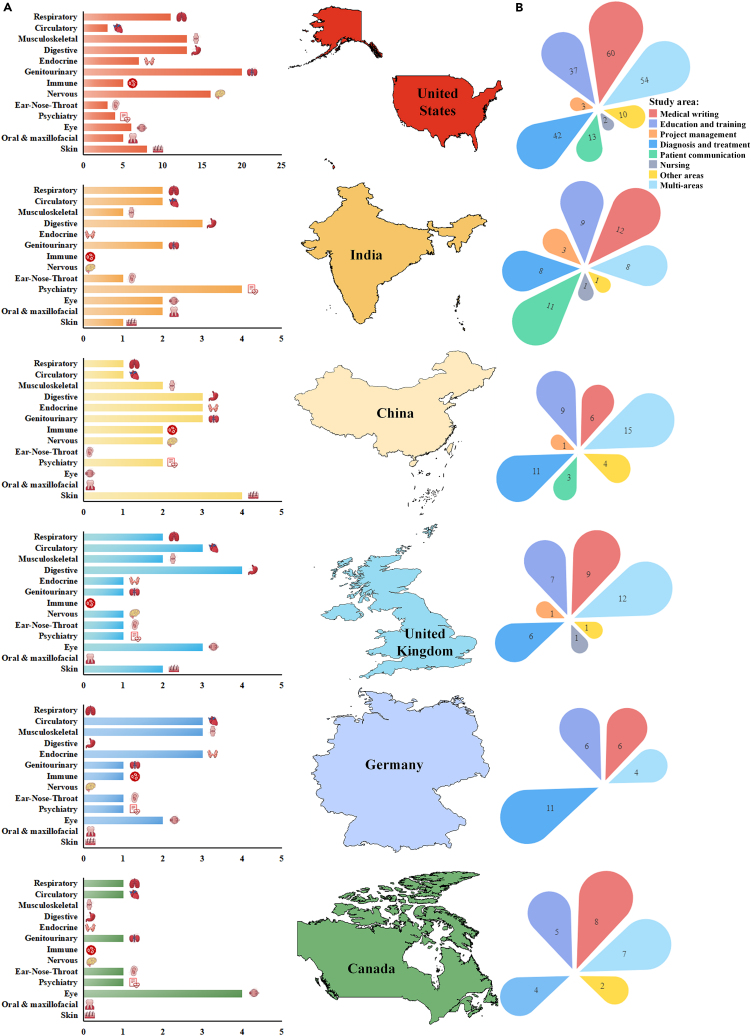
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Large Language Models (LLMs) are increasingly used by healthcare professionals and patients for medical information synthesis.”
From Large Language Model Hallucinations in Spine Surgery: A Comparative Analysis of Clinician vs Patient-Level Prompts (2026) · cites this paper as [1]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Existing reviews of LLMs in healthcare have largely neglected a deeper analysis of explainability methods.”
From Explainability of decoder-only clinical large language models: A scoping review (2026) · cites this paper as [48]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Scoping studies: advancing the methodology
Levac, D., Colquhoun, H., & O'Brien, K. K. (2010) · Implementation Science · doi:10.1186/1748-5908-5-69 · Cited by 15,268
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Self-citationTraining language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Large language models in medicine
Thirunavukarasu, A. J., Ting, D. S. J., Elangovan, K., Gutierrez, L., Tan, T. F., & Ting, D. S. W. (2023) · Nature Medicine · doi:10.1038/s41591-023-02448-8 · Cited by 3,944
Revolutionizing healthcare: the role of artificial intelligence in clinical practice
Alowais, S. A., Alghamdi, S. S., Alsuhebany, N., Alqahtani, T., Alshaya, A. I., Almohareb, S. N., Aldairem, A., Alrashed, M., Bin Saleh, K., Badreldin, H. A., et al. (2023) · BMC Medical Education · doi:10.1186/s12909-023-04698-z · Cited by 3,146
Training Language Models to Follow Instructions with Human Feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2011 · Cited by 3,117
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
Self-citationA Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Wang, X., Hou, Y., Min, Y., Zhang, B., Zhang, J., Dong, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.18223 · Cited by 2,090
Self-citation
Research works printed but not linked: 2
- Thirunavukarasu, 2023, Large language models in medicine, Nat. Med., 29, 1930, 10.1038/s41591-023-02448-8 · DOI · Paper page
- Chen, 2023, Large language models in biomedical natural language processing: benchmarks, baselines, and recommendations, arXiv
Cited by
Sorted by citations
Items 201–300 of 434
Li, Z., Wan, Y., Xu, L., Su, W., Wang, P., & Zhou, X. (2026) · IEEE Transactions on Computational Social Systems · doi:10.1109/tcss.2026.3665229 · Cited by 2
Akkuş, İ., & Deniz, G. (2026) · Journal of Imaging Informatics in Medicine · doi:10.1007/s10278-026-01920-4 · Cited by 2
Sidhu, R., Selvamogan, A., & Boddy, A. (2026) · Annals of The Royal College of Surgeons of England · doi:10.1308/rcsann.2026.0021 · Cited by 2
Warkiani, M. E., Safari, B., Moattar, M. H., & Hosseinzadeh, M. (2026) · Applied Soft Computing · doi:10.1016/j.asoc.2026.115051 · Cited by 2
HybridGNN: a graph neural network approach for human miRNA–disease association prediction
Ahmad, B., Musaddiq, M. H., Temesgen, S. A., Kissanga, G.-M. B., Fida, H., Lin, H., & Qi, Y. (2026) · Bioinformatics · doi:10.1093/bioinformatics/btag171 · Cited by 2
Current and Future View on Artificial Intelligence in Cardiothoracic Surgery
Engelhardt, S., Kostiuchik, G., Bezák, B., Chacko, J., Daeter, E. J., Fallouh, H. B., Grieshaber, P., Hussein, N., Meyer, A., Quattroni, P., et al. (2026) · European Journal of Cardio-Thoracic Surgery · doi:10.1093/ejcts/ezag112 · Cited by 2
Fatawi, I., Bilad, M. R., & Asy’ari, M. (2026) · IAES International Journal of Artificial Intelligence · doi:10.11591/ijai.v15.i2.pp1071-1086 · Cited by 2
Viculin, I., Vrdoljak, J., Tomić, K., Canjko, I., Čerina, D., Ćurin, M., Bošković, L., Družijanić, Z., Vuković, B., Dunkić, N., et al. (2026) · Journal of Medical Internet Research · doi:10.2196/91733 · Cited by 2
Lee, G., Kim, S., Byun, Y., Lee, J., & Choi, H. (2026) · International Journal of Precision Engineering and Manufacturing-Green Technology · doi:10.1007/s40684-026-00890-w · Cited by 2
Zhang, Q., Yu, Q., Wang, G., Zeng, Z., Liu, S., Rao, X., Cheng, C., Wang, X., Shi, L., Wang, Y. L., et al. (2026) · Journal of Cancer Education · doi:10.1007/s13187-026-02918-w · Cited by 2
Self-citationChen, L., Liu, W., & Zhou, Y. (2026) · Frontiers in Public Health · doi:10.3389/fpubh.2026.1824962 · Cited by 2
Bilgiç, B., Turan, S., Avcıl, S., & Pekcanlar, A. A. (2026) · BMC Psychiatry · doi:10.1186/s12888-026-08280-x · Cited by 2
Corso, F., Peppoloni, V., Mazzeo, L., Leone, G., Passos, L., Miskovic, V., Armanini, J., Ferrarin, A., Wiest, I. C., Wolf, F., et al. (2026) · Communications Medicine · doi:10.1038/s43856-026-01790-5 · Cited by 2
Zhao, Y., Miao, Y., Guo, R., Luo, Y., Wang, H., & Wu, Y. X. (2026) · Journal of Medical Internet Research · doi:10.2196/90046 · Cited by 2
Multi-agent Assessment Generation System for SBIRT Training in Nursing
Godbole, M. S., Garg, A., Seo, J. H., Thai, L., Kroll, N. P., Weston, C., Bruce, C., & Wells-Beede, E. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-93508-4_2 · Cited by 2
Highlighting Case Studies in LLM Literature Review of Interdisciplinary System Science
McGinness, L. P., Baumgartner, P., Onyango, E., & Lema, Z. (2024) · Lecture notes in computer science · doi:10.1007/978-981-96-0348-0_3 · Cited by 3
Abrantes, J. (2025) · Cureus · doi:10.7759/cureus.84165 · Cited by 2
Evaluating the Performance of Large Language Models on Multispecialty FRCS Section 1 Questions
Ahmed, H. S. (2025) · Journal of Surgical Research · doi:10.1016/j.jss.2025.06.026 · Cited by 2
Ishadya, A. P. D., Withanaarachchi, A. S., & Jayalal, S. (2025) · International Conference on Advances in Technology and Computing (ICATC) · doi:10.1109/icatc68823.2025.11407841 · Cited by 2
Musleh, A. M., Alwisi, N., Serhan, H. A. A., Toubasi, A. A., Malkawi, L. W., & AlRyalat, S. A. (2025) · medRxiv · doi:10.1101/2025.10.27.25338904 · Cited by 2
McLaughlin, N. D., Srinivas, A. N., Lowe, Z. F., Botterbush, K. S., Patel, M. S., & Avila, M. J. (2026) · Neurosurgery Practice · doi:10.1227/neuprac.0000000000000244 · Cited by 1
Integration of Large Language Models as an Adjunct Tool in Healthcare
Mondal, H. (2024) · Turkish Archives of Otorhinolaryngology · doi:10.4274/tao.2024-10-11 · Cited by 1
Reasoning Engine with Pre-Trained LLMs: An Operation GPT
Pany, P. (2025) · International Journal for Research in Applied Science and Engineering Technology · doi:10.22214/ijraset.2025.68761 · Cited by 1
Best practice for supply chain in LLM-assisted medical applications
Zhao, S., & Wang, J. (2025) · ACM SIGSOFT International Symposium on Software Testing and Analysis (ISSTA) · doi:10.1145/3713081.3731748 · Cited by 1
Self-citationHuman versus artificial social cognition and metacognition: the normative difference
Tison, R., & Zawidzki, T. W. (2025) · AI and Ethics · doi:10.1007/s43681-025-00774-w · Cited by 1
Singireddi, S., Pandey, S., Pardasani, R., Kiran, R., V, & Awasthi, N. (2025) · IEEE International Conference on Healthcare Informatics (ICHI) · doi:10.1109/ichi64645.2025.00036 · Cited by 1
Survey of AI-Driven Advancements in Diagnosis and Clinical Decisions for Healthcare
Abid, A., Tayari, K., & Cheikhrouhou, O. (2025) · Studies in computational intelligence · doi:10.1007/978-3-031-90573-5_1 · Cited by 1
Understanding use of Large Language Models in Healthcare: An HCI Scoping Review
Bandara, P. S., Halloluwa, T., & Vyas, D. (2024) · Australian Conference on Human-Computer Interaction (OzCHI) · doi:10.1145/3726986.3727023 · Cited by 1
AI-enabled resilience modeling for brain health
Wister, A., Pinigina, E., Liang, J., & Linkov, I. (2025) · Frontiers in Molecular Medicine · doi:10.3389/fmmed.2025.1671337 · Cited by 1
Guardians of Privacy: Leveraging LLMs in Assistive Robotic Systems for Healthcare
Zoughalian, K., Aitsam, M., Marchang, J., & Nuovo, A. G. D. (2025) · IEEE Conference on Communications and Network Security · doi:10.1109/cns66487.2025.11195035 · Cited by 1
Macharia, P. M., Hartley, A., Ding, J., Kan, S., Currie, S., Wamalwa, P., Ngugi, L., Nyongesa, T., Mukhwana, R., Mbwayo, A., et al. (2025) · Open Research Africa · doi:10.12688/openresafrica.16217.1 · Cited by 1
Blinded evaluation of GPT-4 and physician responses to patient inquiries across multiple specialties
Sallabi, A., Hrvoj, H., & Štajduhar, A. (2025) · Digital Health · doi:10.1177/20552076251390001 · Cited by 2
Mastroleo, F., Borras-Osorio, M., Patel, S. P., Peterson, S. M., Wilson, R., Namazi, M. J., Zhou, M., Shiraishi, S., Foong, A., Routman, D. M., et al. (2025) · Technical Innovations & Patient Support in Radiation Oncology · doi:10.1016/j.tipsro.2025.100372 · Cited by 1
Jang, S., Jeong, C., Kim, J., & Kahng, H. (2025) · Electronics · doi:10.3390/electronics14244919 · Cited by 1
Turizm Sektöründe Yenilikçi Veri Analizi: Yapay Zekâ ve Sektörel Uygulamaları
Boz, B. (2025) · Özgür Yayınları eBooks · doi:10.58830/ozgur.pub1026.c4110 · Cited by 1
Veri Çağında Teknostres ile Tükenmişlik Arasındaki Kuramsal İlişki
Akgül, V. (2025) · Özgür Yayınları eBooks · doi:10.58830/ozgur.pub1026.c4108 · Cited by 1
Taşyürek, M., Adıgüzel, Ö., Cangül, S., & Ortaç, H. (2025) · Journal of Medical and Dental Investigations · doi:10.5577/jomdi.e250161 · Cited by 1
Çiçek, V., Zhao, L., Tur, Y., Öz, A., Kılıç, Ş., Durak, G., Şaylık, F., Hayıroğlu, M. İ., Çınar, T., & Bağcı, U. (2026) · Medical Sciences · doi:10.3390/medsci14010033 · Cited by 1
Language models in pharmacovigilance: Applications, promises and limits
Salvo, F., Crupi, L., & Cholle, C. (2026) · Therapies · doi:10.1016/j.therap.2025.12.003 · Cited by 1
Wang, E. J., Oğuztüzün, Ç., Xu, R., & Gao, Z. (2026) · Journal of Alzheimer s Disease · doi:10.1177/13872877261415635 · Cited by 1
Wang, Y., Wang, Q., Xun, Y., Zhou, Q., Zhang, H., Liu, H., Qin, Y., Wu, M. Y., Wang, Z., Li, H., et al. (2026) · Journal of Evidence-Based Medicine · doi:10.1111/jebm.70114 · Cited by 1
Self-citationAssessing the Role of Large Language Models in Veterinary Dentistry Client Communication
Baykal, B., & Okur, S. (2026) · Journal of Veterinary Dentistry · doi:10.1177/08987564261424454 · Cited by 1
Retrieval-Augmented LLMs with Indonesian Clinical Trials Guidelines: A Comparative Study
Raputri, E., Teguh, A. J., Hidayah, S. N., Anom, A. K., Setiawan, F., & Qomariyah, N. N. (2025) · International Seminar on Research of Information Technology and Intelligent Systems (ISRITI) · doi:10.1109/isriti68345.2025.11393253 · Cited by 1
Chu, B., Modi, N. D., Menz, B. D., Cornelisse, E., Bacchi, S., Bulamu, N. B., Ullah, S., McKinnon, R. A., Gradoń, K., Rowland, A., et al. (2026) · Public Health Reports · doi:10.1177/00333549261418596 · Cited by 1
Kormilitzin, A., Joyce, D. W., Tsiachristas, A., Borschmann, R., Kapur, N., & Geulayov, G. (2026) · JMIR Mental Health · doi:10.2196/87586 · Cited by 1
From Verification Burden to Trusted Collaboration: Design Goals for LLM-Assisted Literature Reviews
Nogueira, B., Geyer, W., Anderson, A. W., Li, T. J.-J., Kim, D., Moniz, N., & Chawla, N. V. (2026) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3742414.3794723 · Cited by 1
Gupta, A. K., Adams, L. C., & Rangarajan, K. (2026) · Journal of Imaging Informatics in Medicine · doi:10.1007/s10278-026-01904-4 · Cited by 1
Large language models in portuguese for healthcare: a systematic review
Shimaoka, A. M., Junior, A. C. D. S., Duarte, J. M., Costa, T. B. D. S., Pisa, I. T., Lopes, L. R., & Bandiera‐Paiva, P. (2026) · Research on Biomedical Engineering · doi:10.1007/s42600-026-00465-3 · Cited by 2
Forero, D. A. (2026) · Current Genomics · doi:10.2174/0113892029403403260112075225 · Cited by 1
Arora, A., Parmar, U. P. S., Anjali, Mathur, P., Kishore, K., Singh, U., Pandav, S. S., & Gupta, V. (2026) · Indian Journal of Ophthalmology · doi:10.4103/ijo.ijo_808_25 · Cited by 1
Lee, J., Shin, J., & Cho, B. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02567-9 · Cited by 1
Castano-Villegas, N., Villa, M. C., Barrientos, K. M., Llano, I., Velásquez, L., & Zea, J. (2026) · Mayo Clinic Proceedings Digital Health · doi:10.1016/j.mcpdig.2026.100356 · Cited by 1
Prajapati, D. H. (2026) · Medical Journal Armed Forces India · doi:10.1016/j.mjafi.2026.02.011 · Cited by 1
Guo, Y., Meng, X., Yu, E., Zhang, W., Yang, Y., Ma, H., Shao, C., Wang, W., Wang, R., Wang, H., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02644-z · Cited by 3
Self-citationLightweight large language models for early sepsis prediction via a semantic abstraction rule engine
Yang, Y., Yi, B., & Chen, Y. (2026) · Scientific Reports · doi:10.1038/s41598-026-49672-z · Cited by 1
Self-citationWang, R., Li, Y., Feng, X., & Feng, X. (2026) · International Journal of Clinical Pharmacy · doi:10.1007/s11096-026-02138-8 · Cited by 1
Wu, X., Li, J., Liu, S., Li, Y., Wang, Q., Luo, C., Shi, L., Zheng, Y., Meng, L., Fan, M., et al. (2026) · Calcified Tissue International · doi:10.1007/s00223-026-01546-2 · Cited by 1
Xie, Y. U. Q. I. A. O., Ou, Z., Huang, Y., Huang, H., Ran, X., Dai, H., Huang, B., & Shu, L. (2026) · BMC Medical Education · doi:10.1186/s12909-026-09518-8 · Cited by 1
Large Language Model Driven Clinical Knowledge Graph Enhancing Medical Decision Accuracy
Gokula, A. (2026) · International Conference on Signal, Systems, and Computing for Next-Gen Automation (ICSSCNA) · doi:10.1109/icsscna68616.2026.11546824 · Cited by 1
AI in respiratory care: findings from the GOLD report
Al-waqeerah, A., Bashah, A., Ghaleb, E., He, H., & Gao, L. (2026) · Journal of Translational Medicine · doi:10.1186/s12967-026-08454-x · Cited by 1
Huang, H., Yen, D. W., Li, M. Y., Jutras, G., Deng, L. X., McCulloch, C. E., Pletcher, M. J., Lai, J. C., Hameed, B., & Ge, J. (2026) · Hepatology Communications · doi:10.1097/hc9.0000000000000983 · Cited by 1
Self-citationSato, K., Niimi, Y., Ihara, R., Suzuki, K., Iwata, A., & Iwatsubo, T. (2026) · Journal of Alzheimer s Disease · doi:10.1177/13872877261464182 · Cited by 1
On-premises open-source large language models for privacy-preserving multimodal depression screening
Kwon, S., Kim, Y., Jhon, M., Park, J.-H., Lim, B., Jeon, E., Kim, J.-M., Kim, J.-W., & Lee, H. (2026) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2026.106577 · Cited by 1
Lee, K. (2026) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2026.106594 · Cited by 1
Buosi, S., Krewer, F., Harris, L., Deswani, H., Creagh, H., Ganesan, M., Mellotte, G., Eustace, P. J., Judge, C. S., & Curry, E. (2026) · Intelligence-Based Medicine · doi:10.1016/j.ibmed.2026.100428 · Cited by 1
Toward Autonomous Clinics: Human–Robot Collaboration in Clinical Care
Wu, X., Zhang, J., Xu, M., Chu, H. K., Chen, X., Zhong, P., Liu, B., He, M., & Shi, D. (2026) · MedComm · doi:10.1002/mco2.70885 · Cited by 1
Ryzhenko, V. P., Бурлака, Б. С., Belenichev, I., Burlaka, K., Aliyeva, O., Bukhtiyarova, N., Halabitska, I., Petakh, P., & Kamyshnyi, O. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2026.1898857 · Cited by 1
NoseSense: Benchmarking LLMs for Test Smell Detection
Macedo, M., de Fraga, L., Ribeiro, L., Virgínio, T., Ribeiro, M., & Machado, I. (2026) · Simpósio Brasileiro de Testes de Software Sistemático e Automatizado (SAST) · doi:10.5753/sast.2026.31302 · Cited by 1
Chen, D., Blayne, A., Ning, T., Chattha, I., Afshar, M., Ong, J. C. L., Hong, J. C., Liu, N., Celi, L. A., Moons, K. G. M., et al. (2026) · BMJ · doi:10.1136/bmj-2026-100855 · Cited by 1
Sugiarti, S., & Abdurrahman, D. (2024) · Journal of Elementary Education · doi:10.61580/jeesica.v1i1.27 · Cited by 1
Health Diagnostic Assistant using LLMs
Malphedwar, L., Monika, A., Mangesh, D., Tanmay, D., & Raman, G. (2024) · International Journal of Advanced Research in Science Communication and Technology · doi:10.48175/ijarsct-22330 · Cited by 1
Utilizing Large Language Models to Predict ICD-10 Diagnosis Codes from Patient Medical Records
Pathak, R., Vald, G., Sermet, Y., & Demir, İ. (2024) · IEEE MIT Undergraduate Research Technology Conference (URTC) · doi:10.1109/urtc65039.2024.10937521 · Cited by 1
Adugna, A., Abebaw, D., Abebaw, A., & Jemal, M. (2025) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2025.1521886 · Cited by 1
Using Analytics to Reduce Perioperative Clinical Variance
Giarrizzo‐Wilson, S., & Stimson, N. (2025) · AORN Journal · doi:10.1002/aorn.70001 · Cited by 1
AI Streamlines Prostate Pathology Data Extraction
Basourakos, S. P., & Shoag, J. E. (2025) · NEJM AI · doi:10.1056/aie2500388 · Cited by 1
Large Language Models in Stroke Management: A Review of the LiteraturePreprint
Soffer, S., Mudrik, A., Efros, O., Omar, M., Nadkarni, G. N., & Klang, E. (2025) · medRxiv · doi:10.1101/2025.06.28.25330477 · Cited by 1
Kadhim, A., Green, Z., Boags, A. T., George, M., Heinson, A., Stammers, M., Kipps, C., Beattie, R. M., Robinson, P. N., Ashton, J., et al. (2025) · medRxiv · doi:10.64898/2025.12.20.25342726 · Cited by 1
Shimelash, N., Rutunda, S., Menon, V., Emmanuel-Fabula, M., Uwimbabazi, A., Rugege, C., Nshimiyimana, C., Rwema, I. S., Kandekwe, M., Berhe, D. F., et al. (2026) · medRxiv · doi:10.64898/2026.02.16.26346409 · Cited by 1
Bhattacharya, K., Bhattacharya, S., Sharma, D., & Cotton, M. (2026) · Tropical Doctor · doi:10.1177/00494755261437565 · Cited by 1
Explainability of decoder-only clinical large language models: A scoping review
Mishra, N., Abu-Hanna, A., & Calixto, I. (2026) · Artificial Intelligence in Medicine · doi:10.1016/j.artmed.2026.103501
Tang, Y. (2024) · Research Square · doi:10.21203/rs.3.rs-4785726/v1
Self-citationNavigating the Future of Healthcare
Musunuri, R. L., & Bhatt, A. (2024) · Advances in healthcare information systems and administration book series · doi:10.4018/979-8-3693-8552-4.ch003
Recent Advances in AI: Exploring the Impact of GPT-4 and Beyond
Sriram, A. P. (2025) · International Journal of Scientific Research in Computer Science Engineering and Information Technology · doi:10.32628/cseit25111240
Hsu, C.-Y., Cheng, Y. L., Chang, C., Quita, R. M., Chen, R., & Wang, W. (2026) · Next research. · doi:10.1016/j.nexres.2026.101720
Self-citationFoundation Models for Course Equivalency Evaluation
Kim, M., Puder, A., Hayward, C., & Yang, H. (2024) · IEEE ... International Conference on Data Mining workshops · doi:10.1109/icdmw65004.2024.00045
Procedural Guideline Execution Training Improves LLM Performance in Rule-Based Clinical TasksPreprint
Boonmee, P. (2025) · doi:10.31224/4544
Domain specific models outperform large vision language models on cytomorphology tasksPreprint
Kukuljan, I., Dasdelen, M. F., Schäfer, J., Buck, M. C., Götze, K. S. S., & Marr, C. (2025) · medRxiv · doi:10.1101/2025.05.05.25326989
Enhancing Diagnostic Accuracy in Bangla: LLM Approaches to Gender Based Medical Specialty Prediction
Hemel, R. I., Asef, M., & Tamiti, T. I. (2024) · International Conference on Computer and Information Technology (ICCIT) · doi:10.1109/iccit64611.2024.11022612
Benrubi, L., Sato, T., Westgard, L. K., Zollo‐Venecek, K., Socrates, B., Sweigart, B., Ridgway, J. P., Suzuki, J., Morales, Y., Goodman‐Meza, D., et al. (2025) · Open Forum Infectious Diseases · doi:10.1093/ofid/ofaf370
Dong, F., Zhang, H., Ren, Y., Li, W., Li, Y., Cui, G., & Liu, P. (2025) · International Journal of Gynecology & Obstetrics · doi:10.1002/ijgo.70437
SCHIAPPACASSA, J. S. V., & COSTA, G. S. M. D. (2025) · doi:10.17771/pucrio.acad.72097
Mukisa, R., & Matovu, R. (2025) · Lecture notes in networks and systems · doi:10.1007/978-3-031-92611-2_3
Glenn, E. R., Mao, E., O’Connell, E. M., Rowshan, A. P., Beeram, I. R., & LaPorte, D. M. (2025) · Journal of Orthopaedic Reports · doi:10.1016/j.jorep.2025.100770
Generative AI tools in reflective essays: Moderating moral injuries and epistemic injustices
Mapukata, N. O. (2025) · South African Family Practice · doi:10.4102/safp.v67i1.6123
曾健文,朱徐乐,曹世华,周诗颖,张鑫瑜,贾宇阳 (2025) · 环球医学研究 · doi:10.62836/medicine.v2i2.687
A Virtual Patients Ensemble Approach for Predicting Surgical ComplicationsPreprint
Neuman, Y., Cohen, Y., & Neuman, Y. (2025) · medRxiv · doi:10.1101/2025.09.21.25336262
Large language models and their current use in perioperative medicine: a scoping review protocol
Hondjeu, A. R. M., Zhao, Z. Y., Newton, L., Ajenkar, A., Termos, B., Shorr, R., Ladha, K. S., Wijeysundera, D. N., & McIsaac, D. I. (2025) · JBI Evidence Synthesis · doi:10.11124/jbies-25-00003
Performance of a Large Language Model in BI-RADS Classification of Ultrasound Based Breast LesionsPreprint
Pillai, K., & Nausheen, F. (2025) · medRxiv · doi:10.1101/2025.09.28.25336860
Metadata
- Authors
- Meng, X., Yan, X., Zhang, K., Liu, D., Cui, X., Yang, Y., Zhang, M., Cao, C., Wang, J., Wang, X., Gao, J., Wang, Y.-G.-S., Ji, J.-M., Qiu, Z., Li, M., Qian, C., Guo, T., Ma, S., Wang, Z., Guo, Z., Lei, Y., Shao, C., Wang, W., Fan, H., & Tang, Y.-D.
- Affiliations
- Peking University (CN)
- Tianjin University (CN)
- Chinese Academy of Medical Sciences & Peking Union Medical College (CN)
- Hebei Medical University (CN)
- Peking University Third Hospital (CN)
- Beihang University (CN)
- Corresponding author
- Fan, Haojun
- Tang, Yi-Da
- ORCID
- Venue
- iScience
- Publisher
- Elsevier BV
- Published
- 2024-05
- Volume
- 27
- Issue
- 5
- Pages
- 109713
- ISSN
- 2589-0042 (ISSN-L)
- PMC
- PMC11091685
- OpenAlex
- W4395052272
- Cited by
- 414
- References
- 114
- Citations by year
- 2026: 188 · 2025: 188 · 2024: 38
- FWCI
- 9.44
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- iScience (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- Funders
- National Key Research and Development Program of China Stem Cell and Translational Research (2020YFC2004705)
- National Natural Science Foundation of China (81825003, 82270376, 91957123)
- China Scholarship Council (CSCF2021A04)
- CAMS Innovation Fund for Medical Sciences
- Chinese Academy of Meteorological Sciences (2021-I2M-5-003, T-B-119)
- National Key Research and Development Program of China
- Beijing Municipal Science and Technology Commission, Adminitrative Commission of Zhongguancun Science Park
- Beijing Nova Program (Z201100006820002)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- large language models, ChatGPT, medical applications of AI, medical diagnostics, medical writing, medical education, training simulation, physician-patient communication, overreliance on AI, multimodal large language models, ethics of AI in healthcare
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
