

The DOI matches its Crossref record; 113 of the 120 references it cites were found in a registry or an index, and 7 are not checked yet.
The application of large language models in medicine: A scoping review
Open accessAbstract
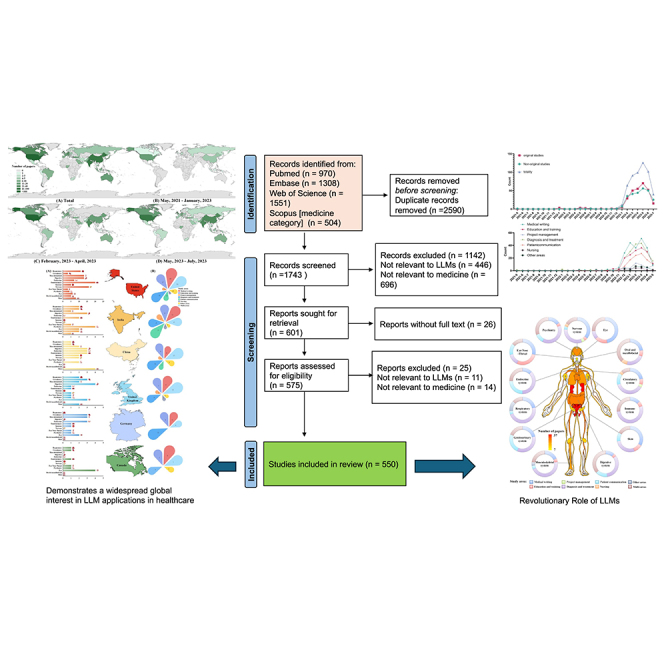
This study systematically reviewed the application of large language models (LLMs) in medicine, analyzing 550 selected studies from a vast literature search. LLMs like ChatGPT transformed healthcare by enhancing diagnostics, medical writing, education, and project management. They assisted in drafting medical documents, creating training simulations, and streamlining research processes. Despite their growing utility in assisted diagnosis and improving doctor-patient communication, challenges persisted, including limitations in contextual understanding and the risk of over-reliance. The surge in LLM-related research indicated a focus on medical writing, diagnostics, and patient communication, but highlighted the need for careful integration, considering validation, ethical concerns, and the balance with traditional medical practice. Future research directions suggested a focus on multimodal LLMs, deeper algorithmic understanding, and ensuring responsible, effective use in healthcare.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Large Language Models (LLMs) are increasingly used by healthcare professionals and patients for medical information synthesis.”
From Large Language Model Hallucinations in Spine Surgery: A Comparative Analysis of Clinician vs Patient-Level Prompts (2026) · cites this paper as [1]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Existing reviews of LLMs in healthcare have largely neglected a deeper analysis of explainability methods.”
From Explainability of decoder-only clinical large language models: A scoping review (2026) · cites this paper as [48]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Scoping studies: advancing the methodology
Levac, D., Colquhoun, H., & O'Brien, K. K. (2010) · Implementation Science · doi:10.1186/1748-5908-5-69 · Cited by 15,268
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Self-citationTraining language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Large language models in medicine
Thirunavukarasu, A. J., Ting, D. S. J., Elangovan, K., Gutierrez, L., Tan, T. F., & Ting, D. S. W. (2023) · Nature Medicine · doi:10.1038/s41591-023-02448-8 · Cited by 3,944
Revolutionizing healthcare: the role of artificial intelligence in clinical practice
Alowais, S. A., Alghamdi, S. S., Alsuhebany, N., Alqahtani, T., Alshaya, A. I., Almohareb, S. N., Aldairem, A., Alrashed, M., Bin Saleh, K., Badreldin, H. A., et al. (2023) · BMC Medical Education · doi:10.1186/s12909-023-04698-z · Cited by 3,146
Training Language Models to Follow Instructions with Human Feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2011 · Cited by 3,117
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
Self-citationA Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Wang, X., Hou, Y., Min, Y., Zhang, B., Zhang, J., Dong, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.18223 · Cited by 2,090
Self-citationEmergent Abilities of Large Language Models
Wei, J., Tay, Y., Bommasani, R., Raffel, C., Zoph, B., Borgeaud, S., Yogatama, D., Bosma, M., Zhou, D., Metzler, D., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.07682 · Cited by 1,264
A Comprehensive Overview of Large Language Models
Naveed, H., Khan, A. U., Qiu, S., Saqib, M., Anwar, S., Usman, M., Akhtar, N., Barnes, N., & Mian, A. (2023) · arXiv · doi:10.48550/arxiv.2307.06435 · Cited by 1,259
A Comprehensive Overview of Large Language Models
Naveed, H., Khan, A. U., Qiu, S., Saqib, M., Anwar, S., Usman, M., Akhtar, N., Barnes, N., & Mian, A. (2025) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3744746 · Cited by 1,257
Dave, T., Athaluri, S. A., & Singh, S. (2023) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2023.1169595 · Cited by 1,204
BioGPT: generative pre-trained transformer for biomedical text generation and mining
Luo, R., Sun, L., Xia, Y., Qin, T., Zhang, S., Poon, H., & Liu, T.-Y. (2022) · Briefings in Bioinformatics · doi:10.1093/bib/bbac409 · Cited by 1,150
Cascella, M., Montomoli, J., Bellini, V., & Bignami, E. (2023) · Journal of Medical Systems · doi:10.1007/s10916-023-01925-4 · Cited by 1,120
A large language model for electronic health records
Yang, X., Chen, A., PourNejatian, N., Shin, H. C., Smith, K. E., Parisien, C., Compas, C., Martin, C., Costa, A. B., Flores, M. G., et al. (2022) · npj Digital Medicine · doi:10.1038/s41746-022-00742-2 · Cited by 847
Structured information extraction from scientific text with large language models
Dagdelen, J., Dunn, A., Lee, S., Walker, N., Rosen, A. S., Ceder, G., Persson, K. A., & Jain, A. (2024) · Nature Communications · doi:10.1038/s41467-024-45563-x · Cited by 771
ChatGPT and the rise of large language models: the new AI-driven infodemic threat in public health
De Angelis, L., Baglivo, F., Arzilli, G., Privitera, G. P., Ferragina, P., Tozzi, A. E., & Rizzo, C. (2023) · Frontiers in Public Health · doi:10.3389/fpubh.2023.1166120 · Cited by 708
Harnessing the power of llms in practice: a survey on chatGPT and beyond
Yang, J., Jin, H., Tang, R., Han, X., Feng, Q., Jiang, H., Zhong, S., Yin, B., & Hu, X. (2024) · ACM Transactions on Knowledge Discovery from Data · doi:10.1145/3649506 · Cited by 644
Harnessing the Power of LLMs in Practice: A Survey on ChatGPT and Beyond
Yang, J., Jin, H., Tang, R., Han, X., Feng, Q., Jiang, H., Yin, B., & Hu, X. (2023) · arXiv · doi:10.48550/arxiv.2304.13712 · Cited by 644
Multimodal Neural Language Models
Kiros, R., Salakhutdinov, R., & Zemel, R. (2014) · Cited by 593
PaLM-E: An Embodied Multimodal Language Model
Driess, D., Xia, F., Sajjadi, M. S. M., Lynch, C., Chowdhery, A., Ichter, B., Wahid, A., Tompson, J., Vuong, Q., Yu, T., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.03378 · Cited by 591
Emergency department triage prediction of clinical outcomes using machine learning models
Raita, Y., Goto, T., Faridi, M. K., Brown, D., Camargo, C. A., & Hasegawa, K. (2019) · Critical Care · doi:10.1186/s13054-019-2351-7 · Cited by 556
Large language models in healthcare and medical domain: A reviewPreprint
Nazi, Z. A., & Peng, W. (2023) · Informatics · doi:10.48550/arxiv.2401.06775 · Cited by 551
Artificial intelligence in clinical and genomic diagnostics
Dias, R., & Torkamani, A. (2019) · Genome Medicine · doi:10.1186/s13073-019-0689-8 · Cited by 499
Harrer, S. (2023) · eBioMedicine · doi:10.1016/j.ebiom.2023.104512 · Cited by 480
Health system-scale language models are all-purpose prediction engines
Jiang, L. Y., Liu, X. C., Nejatian, N. P., Nasir-Moin, M., Wang, D., Abidin, A., Eaton, K., Riina, H. A., Laufer, I., Punjabi, P., et al. (2023) · Nature · doi:10.1038/s41586-023-06160-y · Cited by 460
Accuracy of a Generative Artificial Intelligence Model in a Complex Diagnostic Challenge
Kanjee, Z., Crowe, B., & Rodman, A. (2023) · JAMA · doi:10.1001/jama.2023.8288 · Cited by 449
Creation and Adoption of Large Language Models in Medicine
Shah, N. H., Entwistle, D., & Pfeffer, M. A. (2023) · JAMA · doi:10.1001/jama.2023.14217 · Cited by 435
ToolQA: A Dataset for LLM Question Answering with External ToolsPreprint
Zhuang, Y.-C., Yu, Y., Wang, K., et al. (2023) · Neural Information Processing Systems · doi:10.48550/arxiv.2306.13304 · Cited by 421
Large language models propagate race-based medicine
Omiye, J. A., Lester, J. C., Spichak, S., Rotemberg, V., & Daneshjou, R. (2023) · npj Digital Medicine · doi:10.1038/s41746-023-00939-z · Cited by 417
Large language models in healthcare and medical domain: A review
Nazi, Z. A., & Peng, W. (2024) · Informatics · doi:10.3390/informatics11030057 · Cited by 415
Generative AI in Medicine and Healthcare: Promises, Opportunities and Challenges
Zhang, P., & Kamel Boulos, M. N. (2023) · Future Internet · doi:10.3390/fi15090286 · Cited by 411 · cited 1×
“67 The expansive knowledge base of LLMs enables coverage across diverse medical fields, from orthodontics to cardiac surgery, potentially narrowing the communication divide between doctors and patients.”
A study of generative large language model for medical research and healthcare
Peng, C., Yang, X., Chen, A., Smith, K. E., PourNejatian, N., Costa, A. B., Martin, C., Flores, M. G., Zhang, Y., Magoc, T., et al. (2023) · npj Digital Medicine · doi:10.1038/s41746-023-00958-w · Cited by 408
Daneshjou, R., Smith, M. P., Sun, M. D., Rotemberg, V., & Zou, J. (2021) · JAMA Dermatology · doi:10.1001/jamadermatol.2021.3129 · Cited by 403
Using ChatGPT to write patient clinic letters
Ali, S. R., Dobbs, T. D., Hutchings, H. A., & Whitaker, I. S. (2023) · The Lancet Digital Health · doi:10.1016/s2589-7500(23)00048-1 · Cited by 375
Social Media– and Internet-Based Disease Surveillance for Public Health
Aiello, A. E., Renson, A., & Zivich, P. N. (2020) · Annual Review of Public Health · doi:10.1146/annurev-publhealth-040119-094402 · Cited by 363
Leveraging large language models for decision support in personalized oncology
Benary, M., Wang, X. D., Schmidt, M., Soll, D., Hilfenhaus, G., Nassir, M., Sigler, C., Knödler, M., Keller, U., Beule, D., et al. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.43689 · Cited by 306
Self-citationEight Things to Know about Large Language Models
Bowman, S. R. (2024) · Critical AI · doi:10.1215/2834703x-11556011 · Cited by 305
Sezgın, E. (2023) · Digital Health · doi:10.1177/20552076231186520 · Cited by 298
Bernstein, I. A., Zhang, Y., Govil, D., Majid, I., Chang, R. T., Sun, Y., Shue, A., Chou, J. C., Schehlein, E. M., Christopher, K. L., et al. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.30320 · Cited by 260
Korngiebel, D. M., & Mooney, S. D. (2021) · npj Digital Medicine · doi:10.1038/s41746-021-00464-x · Cited by 259
Qureshı, R., Shaughnessy, D. P., Gill, K., Robinson, K. A., Li, T., & Agai, E. (2023) · Systematic Reviews · doi:10.1186/s13643-023-02243-z · Cited by 230
Chen, Q., Hu, Y., Peng, X., Xie, Q., Jin, Q., Gilson, A., Singer, M. B., Ai, X., Lai, P.-T., Wang, Z., et al. (2025) · Nature Communications · doi:10.1038/s41467-025-56989-2 · Cited by 219
Self-citationWill ChatGPT transform healthcare?
(2023) · Nature Medicine · doi:10.1038/s41591-023-02289-5 · Cited by 214
Large language model AI chatbots require approval as medical devices
Gilbert, S., Harvey, H., Melvin, T., Vollebregt, E., & Wicks, P. (2023) · Nature Medicine · doi:10.1038/s41591-023-02412-6 · Cited by 207
Decker, H., Trang, K., Ramirez, J., Colley, A., Pierce, L., Coleman, M., Bongiovanni, T., Melton, G. B., & Wick, E. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.36997 · Cited by 178
The Challenges for Regulating Medical Use of ChatGPT and Other Large Language Models
Minssen, T., Vayena, E., & Cohen, I. G. (2023) · JAMA · doi:10.1001/jama.2023.9651 · Cited by 171
ToolQA: A Dataset for LLM Question Answering with External Tools
Zhuang, Y., Yu, Y., Wang, K., Sun, H., & Zhang, C. (2023) · neural information processing systems · doi:10.52202/075280-2180 · Cited by 160
Using ChatGPT in Medical Research: Current Status and Future Directions
Ruksakulpiwat, S., Kumar, A., & Ajibade, A. (2023) · Journal of Multidisciplinary Healthcare · doi:10.2147/jmdh.s413470 · Cited by 156
The promise of large language models in health care
Arora, A., & Arora, A. (2023) · The Lancet · doi:10.1016/s0140-6736(23)00216-7 · Cited by 153
Leveraging Large Language Models for Multiple Choice Question AnsweringPreprint
Robinson, J. A., Rytting, C. M., & Wingate, D. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2210.12353 · Cited by 141
Eight Things to Know about Large Language Models
Bowman, S. R. (2023) · arXiv · doi:10.48550/arxiv.2304.00612 · Cited by 137 · cited 2×
“40,41 Additionally, LLMs can simplify complex medical statistics for better comprehension.”
Flexible electronics for cardiovascular healthcare monitoring
Zhang, T., Liu, N., Xu, J., Liu, Z., Zhou, Y., Yang, Y., Li, S., Huang, Y., & Jiang, S. (2023) · The Innovation · doi:10.1016/j.xinn.2023.100485 · Cited by 129
Self-citationArtificial intelligence in health‐care: implications for the job design of healthcare professionals
Tursunbayeva, A., & Renkema, M. (2022) · Asia Pacific Journal of Human Resources · doi:10.1111/1744-7941.12325 · Cited by 128
Ins and outs of AlphaFold2 transmembrane protein structure predictions
Hegedűs, T., Geisler, M., Lukács, G. L., & Farkas, B. (2022) · Cellular and Molecular Life Sciences · doi:10.1007/s00018-021-04112-1 · Cited by 127
ChatGPT has entered the classroom: how LLMs could transform education
Extance, A. (2023) · Nature · doi:10.1038/d41586-023-03507-3 · Cited by 127
Li, S. W. L., Kemp, M. W., Logan, S. J. S., Dimri, P. S., Singh, N., Mattar, C. N. Z., Dashraath, P., Ramlal, H., Mahyuddin, A. P., Kanayan, S., et al. (2023) · American Journal of Obstetrics and Gynecology · doi:10.1016/j.ajog.2023.04.020 · Cited by 124
González-Sendino, R., Serrano, E., & Bajo, J. (2024) · Future Generation Computer Systems · doi:10.1016/j.future.2024.02.023 · Cited by 119
Evaluating Artificial Intelligence Responses to Public Health Questions
Ayers, J. W., Zhu, Z., Poliak, A., Leas, E. C., Dredze, M. H., Hogarth, M. A., & Smith, D. M. (2023) · JAMA Network Open · doi:10.1001/jamanetworkopen.2023.17517 · Cited by 115
Use of ChatGPT: What does it mean for biology and environmental science?
Agathokleous, E., Saitanis, C. J., Fang, C., & Yu, Z. (2023) · The Science of The Total Environment · doi:10.1016/j.scitotenv.2023.164154 · Cited by 113
ChatGPT, Bard, and large language models for biomedical research: opportunities and pitfalls
Thapa, S., & Adhikari, S. (2023) · Annals of Biomedical Engineering · doi:10.1007/s10439-023-03284-0 · Cited by 111
Ali, T., Kostakos, P., & Sheikhi, S. (2026) · Telecom · doi:10.3390/telecom7030073 · Cited by 104
Li, R., Kumar, A., & Chen, J. H. (2023) · JAMA Internal Medicine · doi:10.1001/jamainternmed.2023.1835 · Cited by 104
Artificial Intelligence Discusses the Role of Artificial Intelligence in Translational Medicine
Mann, D. L. (2023) · JACC: Basic to Translational Science · doi:10.1016/j.jacbts.2023.01.001 · Cited by 93
MLCopilot: Unleashing the Power of Large Language Models in Solving Machine Learning TasksPreprint
Zhang, L., Zhang, Y., Ren, K., Li, D., & Yang, Y.-Q. (2023) · Conference of the European Chapter of the Association for Computational Linguistics · doi:10.48550/arxiv.2304.14979 · Cited by 93
Self-citationLLM Censorship: A Machine Learning Challenge or a Computer Security Problem?Preprint
Glukhov, D., Shumailov, I., Gal, Y., Papernot, N., & Papyan, V. (2023) · arXiv.org · doi:10.48550/arxiv.2307.10719 · Cited by 89
What Should Data Science Education Do With Large Language Models?
Tu, X., Zou, J., Su, W., & Zhang, L. (2024) · Harvard Data Science Review · doi:10.1162/99608f92.bff007ab · Cited by 82
Large Language Models Answer Medical Questions Accurately, but Can’t Match Clinicians’ Knowledge
Harris, E. (2023) · JAMA · doi:10.1001/jama.2023.14311 · Cited by 70
ChatGPT—A promising generative AI tool and its implications for cancer care
Uprety, D., Zhu, D., & West, H. (. (2023) · Cancer · doi:10.1002/cncr.34827 · Cited by 68
Structured information extraction from complex scientific text with fine-tuned large language models
Dunn, A., Dagdelen, J., Walker, N., Lee, S., Rosen, A. S., Ceder, G., Persson, K., & Jain, A. (2022) · arXiv · doi:10.48550/arxiv.2212.05238 · Cited by 67
Is ChatGPT an Evidence-based Doctor?
Zhou, Z., Wang, X., Li, X., & Liao, L. (2023) · European Urology · doi:10.1016/j.eururo.2023.03.037 · Cited by 66
Self-citationAssessing the Strengths and Weaknesses of Large Language Models
Lappin, S. (2023) · Journal of Logic Language and Information · doi:10.1007/s10849-023-09409-x · Cited by 66
Harnessing large language models (LLMs) for candidate gene prioritization and selection
Toufiq, M., Rinchai, D., Bettacchioli, É., Kabeer, B. S. A., Khan, T., Subba, B., White, O., Yurieva, M., George, J., Jourde‐Chiche, N., et al. (2023) · Journal of Translational Medicine · doi:10.1186/s12967-023-04576-8 · Cited by 65
Empowering Education with LLMs - The Next-Gen Interface and Content Generation
Moore, S., Tong, R. M., Singh, A., Liu, Z., Hu, X., Lu, Y., Liang, J., Cao, C., Khosravi, H., Denny, P. C., et al. (2023) · Communications in computer and information science · doi:10.1007/978-3-031-36336-8_4 · Cited by 64
Self-citationLarge language models will not replace healthcare professionals: curbing popular fears and hype.
Thirunavukarasu, A. J. (2023) · Journal of the Royal Society of Medicine · doi:10.1177/01410768231173123 · Cited by 63
Assessing the Accuracy and Clinical Utility of ChatGPT in Laboratory Medicine
Muñoz‐Zuluaga, C., Zhao, Z., Wang, F., Greenblatt, M. B., & Yang, H. S. (2023) · Clinical Chemistry · doi:10.1093/clinchem/hvad058 · Cited by 61
Large Language Models Understand and Can be Enhanced by Emotional Stimuli
Li, C., Wang, J., Zhang, Y., Zhu, K., Hou, W., Lian, J., Luo, F., Yang, Q., & Xie, X. (2023) · arXiv · doi:10.48550/arxiv.2307.11760 · Cited by 59
Self-citationMYCRUNCHGPT: A LLM ASSISTED FRAMEWORK FOR SCIENTIFIC MACHINE LEARNING
Kumar, V., Gleyzer, L., Kahana, A., Shukla, K., & Karniadakis, G. E. (2023) · Journal of Machine Learning for Modeling and Computing · doi:10.1615/jmachlearnmodelcomput.2023049518 · Cited by 52
Lower, K., Seth, I., Lim, B., & Seth, N. (2023) · Indian Journal of Orthopaedics · doi:10.1007/s43465-023-00967-7 · Cited by 50
How to approach machine learning-based prediction of drug/compound–target interactions
Ataş, H., & Doğan, T. (2023) · Journal of Cheminformatics · doi:10.1186/s13321-023-00689-w · Cited by 48
Ali, T., & Kostakos, P. (2023) · arXiv · doi:10.48550/arxiv.2309.16021 · Cited by 47
Cheng, K., Wu, C., Gu, S., Lu, Y., Wu, H., & Li, C. (2023) · International Journal of Surgery · doi:10.1097/js9.0000000000000521 · Cited by 46
Evaluating GPT-4-based ChatGPT's clinical potential on the NEJM quiz
Ueda, D., Walston, S. L., Matsumoto, T., Deguchi, R., Tatekawa, H., & Miki, Y. (2024) · BMC Digital Health · doi:10.1186/s44247-023-00058-5 · Cited by 46
Han, C., Kim, D. W., Kim, S., You, S. C., Park, J. Y., Bae, S., & Yoon, D. (2024) · iScience · doi:10.1016/j.isci.2024.109022 · Cited by 46
Large Language Models (LLMs) and Empathy – A Systematic ReviewPreprint
Sorin, V., Brin, D., Barash, Y., Konen, E., Charney, A. W., Nadkarni, G. N., & Klang, E. (2023) · medRxiv · doi:10.1101/2023.08.07.23293769 · Cited by 45
A descriptive study based on the comparison of ChatGPT and evidence-based neurosurgeons
Liu, J., Zheng, J., Cai, X., Wu, D., & Yin, C. (2023) · iScience · doi:10.1016/j.isci.2023.107590 · Cited by 44
Caution with AI-generated content in biomedicine
Zhavoronkov, A. (2023) · Nature Medicine · doi:10.1038/d41591-023-00014-w · Cited by 39
Social media: A new tool for outbreak surveillance
Wilson, A. E., Lehmann, C. U., Saleh, S. N., Hanna, J. J., & Medford, R. J. (2021) · Antimicrobial Stewardship & Healthcare Epidemiology · doi:10.1017/ash.2021.225 · Cited by 39
ChatGPT: when the artificial intelligence meets standardized patients in clinical training
Liu, X., Wu, C., Lai, R., Lin, H., Xu, Y., Lin, Y., & Zhang, W. (2023) · Journal of Translational Medicine · doi:10.1186/s12967-023-04314-0 · Cited by 37
ChatGPT is not the solution to physicians’ documentation burden
Preiksaitis, C. M., Sinsky, C. A., & Rose, C. C. (2023) · Nature Medicine · doi:10.1038/s41591-023-02341-4 · Cited by 36
Telemedicine: a Bridge Over Knowledge Gaps in Healthcare
Eisenstein, E., Kopacek, C., Cavalcante, S. S., Neves, A. C., Fraga, G. P., & Messina, L. A. (2020) · Current Pediatrics Reports · doi:10.1007/s40124-020-00221-w · Cited by 35
Large language models (LLM) and ChatGPT: a medical student perspective
Perera Molligoda Arachchige, A. S. (2023) · European Journal of Nuclear Medicine and Molecular Imaging · doi:10.1007/s00259-023-06227-y · Cited by 35
Interventions to optimize medication use in nursing homes: a narrative review
Spinewine, A., Evrard, P., & Hughes, C. M. (2021) · European Geriatric Medicine · doi:10.1007/s41999-021-00477-5 · Cited by 34
Komorowski, M., Lopez, M. D. P. A., & Chang, A. C. (2023) · Intensive Care Medicine · doi:10.1007/s00134-023-07096-7 · Cited by 30
Galido, P. V., Butala, S., Chakerian, M., & Agustines, D. (2023) · Cureus · doi:10.7759/cureus.38166 · Cited by 29
ChatGPT and large language models in gastroenterology
Sharma, P., & Parasa, S. (2023) · Nature Reviews Gastroenterology & Hepatology · doi:10.1038/s41575-023-00799-8 · Cited by 27
MLCopilot: Unleashing the Power of Large Language Models in Solving Machine Learning Tasks
Zhang, L., Zhang, Y., Ren, K., Li, D., & Yang, Y. (2024) · Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2024.eacl-long.179 · Cited by 27
Self-citationSoftware Testing with Large Language Models: Survey, Landscape, and VisionPreprint
Wang, J., Huang, Y., Chen, C., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2307.07221 · Cited by 26
Self-citationGPT-4: the future of artificial intelligence in medical school assessments
Haruna‐Cooper, L., & Rashid, A. (2023) · Journal of the Royal Society of Medicine · doi:10.1177/01410768231181251 · Cited by 24
ChatGPT/GPT-4: enabling a new era of surgical oncology
Cheng, K., Wu, H., & Li, C. (2023) · International Journal of Surgery · doi:10.1097/js9.0000000000000451 · Cited by 19
Pearls and pitfalls of ChatGPT in medical oncology
Blum, J., Menta, A. K., Zhao, X., Yang, V., Gouda, M. A., & Subbiah, V. (2023) · Trends in cancer · doi:10.1016/j.trecan.2023.06.007 · Cited by 19
Azizi, Z., Alipour, P., Gomez, S. E., Broadwin, C., Islam, S., Sarraju, A., Rogers, A. J., Sandhu, A. T., & Rodríguez, F. (2023) · Circulation Arrhythmia and Electrophysiology · doi:10.1161/circep.123.012015 · Cited by 18
How can we transform travel medicine by leveraging on AI-powered search engines?
Kwok, K. O., Wei, W. I., Tsoi, M. T. F., Tang, A., Chan, M. W. H., Ip, M., Li, K., & Wong, S. Y. S. (2023) · Journal of Travel Medicine · doi:10.1093/jtm/taad058 · Cited by 16
Building Emotional Support Chatbots in the Era of LLMsPreprint
Zheng, Z., Liao, L., Deng, Y., & Nie, L. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2308.11584 · Cited by 15
Artificial Intelligence—From Starting Pilots to Scalable Privilege
Butte, A. J. (2023) · JAMA Oncology · doi:10.1001/jamaoncol.2023.2867 · Cited by 15
Opportunities for artificial intelligence in healthcare and in vitro fertilization
Miloski, B. (2023) · Fertility and Sterility · doi:10.1016/j.fertnstert.2023.05.006 · Cited by 13
Plan, Generate and Match: Scientific Workflow Recommendation with Large Language Models
Gu, Y., Cao, J., Guo, Y., Qian, S., & Guan, W. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-48421-6_7 · Cited by 11
Nakaura, T., & Naganawa, S. (2023) · Japanese Journal of Radiology · doi:10.1007/s11604-023-01408-z · Cited by 8
Evolving Methods to Assess Chatbot Performance in Health Sciences Research
Ward, E., & Gross, C. P. (2023) · JAMA Internal Medicine · doi:10.1001/jamainternmed.2023.2567 · Cited by 8
Application and technology of an open source AI large language model in the medical field
Zhang, T., & Feng, T. (2023) · Radiology Science · doi:10.15212/radsci-2023-0007 · Cited by 8
In the era of prominent AI, what role will physicians be expected to play?
Kaneda, Y. (2023) · QJM · doi:10.1093/qjmed/hcad099 · Cited by 8
Chatbots, Artificial Intelligence, and the Future of Scientific Reporting
Volpe, N. J., & Mirza, R. G. (2023) · JAMA Ophthalmology · doi:10.1001/jamaophthalmol.2023.3344 · Cited by 6
Hu, Z.-Y., Han, F., Li, Y., Jiang, Y., & Cai, G. (2023) · The Innovation · doi:10.1016/j.xinn.2023.100494 · Cited by 6
Yeo, Y. H., Samaan, J. S., & Ng, W. H. (2023) · Clinical and Molecular Hepatology · doi:10.3350/cmh.2023.0183 · Cited by 5
WHO declares end of mpox global health emergency: first glance from a perspective of ChatGPT/GPT-4
Lu, Y., Qi, S., Cheng, K., & Wu, H. (2023) · International Journal of Surgery · doi:10.1097/js9.0000000000000543 · Cited by 4
da Silva, J. A. T. (2023) · Diabetes & Metabolic Syndrome Clinical Research & Reviews · doi:10.1016/j.dsx.2023.102779 · Cited by 3
LARGE LANGUAGE MODELS (LLMS) AND CHATGPT FOR BIOMEDICINE
Arighi, C. N., Brenner, S. E., & Lu, Z. (2023) · Pacific Symposium on Biocomputing (PSB) · doi:10.1142/9789811286421_0048 · Cited by 3
Chen, Q., Hu, Y., Peng, X., Xie, Q., Jin, Q., Gilson, A., Singer, M. B., Ai, X., Lai, P.-T., Wang, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2305.16326
Self-citation
Research works printed but not linked: 2
- Thirunavukarasu, 2023, Large language models in medicine, Nat. Med., 29, 1930, 10.1038/s41591-023-02448-8 · DOI · Paper page
- Chen, 2023, Large language models in biomedical natural language processing: benchmarks, baselines, and recommendations, arXiv
Cited by
Sorted by citations
Large language models in patient education: a scoping review of applications in medicine
Aydin, S., Karabacak, M., Vlachos, V., & Margetis, K. (2024) · Frontiers in Medicine · doi:10.3389/fmed.2024.1477898 · Cited by 318
Large Language Models in Healthcare and Medical Applications: A Review
Maity, S., & Saikia, M. J. (2025) · Bioengineering · doi:10.3390/bioengineering12060631 · Cited by 249
Large language models for disease diagnosis: a scoping review
Zhou, S., Xu, Z., Zhang, M., Xu, C., Guo, Y., Zhan, Z., Fang, Y., Ding, S., Wang, J., Xu, K., et al. (2025) · npj Artificial Intelligence · doi:10.1038/s44387-025-00011-z · Cited by 188
Self-citationRevolutionizing Health Care: The Transformative Impact of Large Language Models in Medicine
Zhang, K., Meng, X., Yan, X., Ji, J., Liu, J., Xu, H., Zhang, H., Liu, D., Wang, J., Wang, X., et al. (2024) · Journal of Medical Internet Research · doi:10.2196/59069 · Cited by 148
Self-citationArtsi, Y., Sorin, V., Glicksberg, B. S., Korfiatis, P. D., Nadkarni, G. N., & Klang, E. (2025) · Frontiers in Digital Health · doi:10.3389/fdgth.2025.1659134 · Cited by 113
Metadata
- Authors
- Meng, X., Yan, X., Zhang, K., Liu, D., Cui, X., Yang, Y., Zhang, M., Cao, C., Wang, J., Wang, X., Gao, J., Wang, Y.-G.-S., Ji, J.-M., Qiu, Z., Li, M., Qian, C., Guo, T., Ma, S., Wang, Z., Guo, Z., Lei, Y., Shao, C., Wang, W., Fan, H., & Tang, Y.-D.
- Affiliations
- Peking University (CN)
- Tianjin University (CN)
- Chinese Academy of Medical Sciences & Peking Union Medical College (CN)
- Hebei Medical University (CN)
- Peking University Third Hospital (CN)
- Beihang University (CN)
- Corresponding author
- Fan, Haojun
- Tang, Yi-Da
- ORCID
- Venue
- iScience
- Publisher
- Elsevier BV
- Published
- 2024-05
- Volume
- 27
- Issue
- 5
- Pages
- 109713
- ISSN
- 2589-0042 (ISSN-L)
- PMC
- PMC11091685
- OpenAlex
- W4395052272
- Cited by
- 414
- References
- 114
- Citations by year
- 2026: 188 · 2025: 188 · 2024: 38
- FWCI
- 9.44
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- iScience (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- Funders
- National Key Research and Development Program of China Stem Cell and Translational Research (2020YFC2004705)
- National Natural Science Foundation of China (81825003, 82270376, 91957123)
- China Scholarship Council (CSCF2021A04)
- CAMS Innovation Fund for Medical Sciences
- Chinese Academy of Meteorological Sciences (2021-I2M-5-003, T-B-119)
- National Key Research and Development Program of China
- Beijing Municipal Science and Technology Commission, Adminitrative Commission of Zhongguancun Science Park
- Beijing Nova Program (Z201100006820002)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- large language models, ChatGPT, medical applications of AI, medical diagnostics, medical writing, medical education, training simulation, physician-patient communication, overreliance on AI, multimodal large language models, ethics of AI in healthcare
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
