

The DOI matches its Crossref record; 113 of the 120 references it cites were found in a registry or an index, and 7 are not checked yet.
The application of large language models in medicine: A scoping review
Open accessAbstract
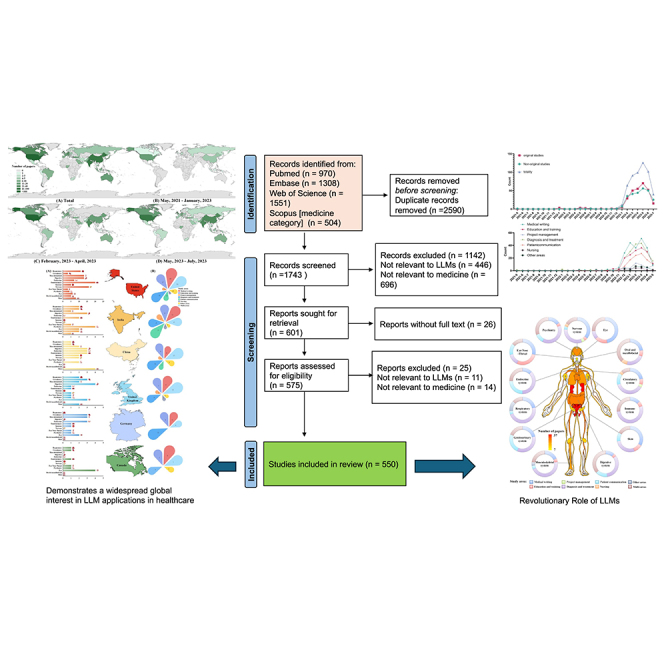
This study systematically reviewed the application of large language models (LLMs) in medicine, analyzing 550 selected studies from a vast literature search. LLMs like ChatGPT transformed healthcare by enhancing diagnostics, medical writing, education, and project management. They assisted in drafting medical documents, creating training simulations, and streamlining research processes. Despite their growing utility in assisted diagnosis and improving doctor-patient communication, challenges persisted, including limitations in contextual understanding and the risk of over-reliance. The surge in LLM-related research indicated a focus on medical writing, diagnostics, and patient communication, but highlighted the need for careful integration, considering validation, ethical concerns, and the balance with traditional medical practice. Future research directions suggested a focus on multimodal LLMs, deeper algorithmic understanding, and ensuring responsible, effective use in healthcare.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Large Language Models (LLMs) are increasingly used by healthcare professionals and patients for medical information synthesis.”
From Large Language Model Hallucinations in Spine Surgery: A Comparative Analysis of Clinician vs Patient-Level Prompts (2026) · cites this paper as [1]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Existing reviews of LLMs in healthcare have largely neglected a deeper analysis of explainability methods.”
From Explainability of decoder-only clinical large language models: A scoping review (2026) · cites this paper as [48]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Scoping studies: advancing the methodology
Levac, D., Colquhoun, H., & O'Brien, K. K. (2010) · Implementation Science · doi:10.1186/1748-5908-5-69 · Cited by 15,268
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Self-citationTraining language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Large language models in medicine
Thirunavukarasu, A. J., Ting, D. S. J., Elangovan, K., Gutierrez, L., Tan, T. F., & Ting, D. S. W. (2023) · Nature Medicine · doi:10.1038/s41591-023-02448-8 · Cited by 3,944
Revolutionizing healthcare: the role of artificial intelligence in clinical practice
Alowais, S. A., Alghamdi, S. S., Alsuhebany, N., Alqahtani, T., Alshaya, A. I., Almohareb, S. N., Aldairem, A., Alrashed, M., Bin Saleh, K., Badreldin, H. A., et al. (2023) · BMC Medical Education · doi:10.1186/s12909-023-04698-z · Cited by 3,146
Training Language Models to Follow Instructions with Human Feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2011 · Cited by 3,117
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
Self-citationA Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Wang, X., Hou, Y., Min, Y., Zhang, B., Zhang, J., Dong, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.18223 · Cited by 2,090
Self-citation
Research works printed but not linked: 2
- Thirunavukarasu, 2023, Large language models in medicine, Nat. Med., 29, 1930, 10.1038/s41591-023-02448-8 · DOI · Paper page
- Chen, 2023, Large language models in biomedical natural language processing: benchmarks, baselines, and recommendations, arXiv
Cited by
Sorted by citations
Items 401–434 of 434
Assessing the clinical applicability of large language models for microwave ablation guidance
Mathy, R. M., Schmitz, F., Kauczor, H., Jang, H., & Sedaghat, S. (2026) · European Journal of Radiology Open · doi:10.1016/j.ejro.2026.100804
Wang, J., Yang, J., & Guo, R. (2026) · Journal of Medical Internet Research · doi:10.2196/89963
Self-citationA KG-LLM Pipeline for Automated Regulatory Alignment in CPS-IoT Systems
Muriga, V., Yang, J., Li, J., & Kumar, S. (2026) · IEEE International Workshop on Foundation Models for Cyber-Physical Systems & Internet of Things (FMSys) · doi:10.1109/fmsys72110.2026.00018
Wegmann, S., Rosenkranz, T. A., Egenolf, P., Oikonomidis, S., Weber, M., & Lenz, M. (2026) · European Spine Journal · doi:10.1007/s00586-026-10280-0
Mudumba, R., Modi, A. B., & Mayo, K. (2026) · Journal of Managed Care & Specialty Pharmacy · doi:10.18553/jmcp.2026.32.9.1090
Hierarchical LLM-Assisted Clinical Coding in ICD-10-CM: A Hybrid Prompting and Embedding Approach
Costa, N., Martins, C. L., & Freitas, A. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-27541-7_15
Sannathimmappa, M. B. (2026) · Bulletin of the National Research Centre/Bulletin of the National Research Center · doi:10.1186/s42269-026-01482-z
Generative large language models in medicine: a scoping review of recent methodological advances
LI, F., Li, J., Cao, W., Li, H., Li, Y., Sun, Z., Chen, D., Duan, T., Li, P., Tizhoosh, H., et al. (2026) · npj Health Systems · doi:10.1038/s44401-026-00137-5
Ma, Y., Liu, S., Song, J., Song, X., Yang, X., Zhao, Q., Xiao, M., & Wang, J. (2026) · Journal of Nursing Management · doi:10.1155/jonm/9524014
Self-citationKobayashi, Y., Jiang, S. S., Huang, J., Kim, T., Roeder, K., Chen, L., Kobayashi, N. S., Fine, D. H., & Shimizu, E. (2026) · Dentistry Journal · doi:10.3390/dj14090575
Knowledge-guided multi-agent framework for intelligent acupuncture diagnosis and reasoning
Zhang, W., Cui, J., Zhao, M., Zhang, M., & Li, P. (2026) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2026.116139
Self-citationPredicting phase 3 clinical trial outcomes with an evidence-driven large language model
Zhang, W., Meng, X., Jia, X., Yu, E., Lan, J., Wang, T., Chen, G., Guo, Y., Liu, Y., Chu, X., et al. (2026) · The Innovation · doi:10.1016/j.xinn.2026.101574
Self-citationLarge language models as integrative intelligence for multimodal cardiovascular decision support
Mitrovic, P. (2026) · Journal of Clinical and Translational Research · doi:10.36922/jctr026290071
Peterson, G. M., Oermann, M. H., Owens, J. K., Templeton, G. F., Bailey, H. E., & Carter‐Templeton, H. (2026) · Research Square · doi:10.21203/rs.3.rs-10346244/v1
Effectiveness of ChatGPT and DeepSeek in Urology Medical Education: Randomized Controlled Trial
Yang, W., Xu, T., Wei, J., Zheng, W., Yan, W., Wang, J., Chu, G., & Niu, H. (2026) · Journal of Medical Internet Research · doi:10.2196/89315
Self-citationChen, Y., Zhang, S., Liu, X., Li, L., Si, M., & Xu, C. (2026) · Behavioral Sciences · doi:10.3390/bs16101715
Pan, J., Zhou, H., Chen, Y., & Chu, S. (2026) · Biomedical Signal Processing and Control · doi:10.1016/j.bspc.2026.111462
Beyond technical skills: redefining managerial competencies for AI-driven organizations
Mauro, A. D., Mura, R., Leo, A. D., & Peruffo, E. (2026) · Management Decision · doi:10.1108/md-11-2025-3503
Li, J., Shihang, N., & Jiang, C. (2026) · Scientometrics · doi:10.1007/s11192-026-05838-0
Symptom checkers: Gaps in their evidence base and suggestions for accuracy evaluation
Donner‐Banzhoff, N., Schaefer, H., Schlicker, N., Becker, A., Haasenritter, J., & van der Wardt, V. (2026) · Digital Health · doi:10.1177/20552076261487359
Hu, G., Lai, Q., Liu, S., Xie, B., Wu, Z., Zhuang, Q., Tang, H., & Xu, J. (2026) · Frontiers in Public Health · doi:10.3389/fpubh.2026.1961597
Stępień, M., Strauchman, M., Siodłak, A., Marcin, S., & Błaszczyk, B. (2026) · Annales Academiae Medicae Silesiensis · doi:10.18794/aams/240194
A Contextual AI Agent Decision Support System for e-Government Cybersecurity Self-Assessment
Darmayanti, N. D. S., Samsudiat, Yuniantoro, R. M. T., Nugroho, C., Hakim, S. A., Saputra, A., & Siagian, A. H. A. M. (2026) · International Conference on Computer, Control, Informatics and its Applications · doi:10.1109/ic3ina72033.2026.11714650
Brumer, M., Vandersteen, L., Duquet, N., Strauven, G., Sadeleer, E. D., Meyer, G. R. Y. D., & Loof, H. D. (2026) · Exploratory Research in Clinical and Social Pharmacy · doi:10.1016/j.rcsop.2026.100752
Utility of OpenEvidence and ChatGPT in Selecting Neuroimaging Based on Appropriateness Criteria
Kumarapuram, S., Satti, M., Xu, S., Kavia, J., Bhaskar, A., Azmi, A., Goldszal, A. F., Soliman, A., Sundararajan, S., Gupta, G., et al. (2026) · Academic Radiology · doi:10.1016/j.acra.2026.09.049
Application of large language models in early screening of Alzheimer’s disease: a scoping review
Tian, J., Huang, W., Wen, Y., & Liang, Y. (2026) · Frontiers in Aging Neuroscience · doi:10.3389/fnagi.2026.1906641
Jones, B. Z., Olsen, J. R., Miller, S. M., Herrera, E., Okelberry, D. R., Sitto, M. M., Brandenburg, T., Hoopes, P. C., & Moshirfar, M. (2026) · Cureus · doi:10.7759/cureus.117869
Moghadam, S. T., & Jabin, M. S. R. (2026) · Research Square · doi:10.21203/rs.3.rs-11197970/v1
Muluk, N. B. (2026) · Personalized Medicine · doi:10.1080/17410541.2026.2753744
Jagade, V. T., Bijali, S. S., Dawle, D. R., Bhosale, A. K., & Vanmali, P. (2026) · Iconic Research and Engineering Journals · doi:10.64388/irev10i4-1724206
Artificial intelligence: Physicians and patients’ communication
Meo, S. A. (2026) · Elsevier eBooks · doi:10.1016/b978-0-443-45973-3.00016-6
Lee, J., Shin, J., & Cho, B. (2026) · Journal of Korean Medical Science · doi:10.3346/jkms.2026.41.e339
Sharma, B. (2026) · International Journal of Advanced Research in Science Communication and Technology · doi:10.48175/ijarsct-40491
Metadata
- Authors
- Meng, X., Yan, X., Zhang, K., Liu, D., Cui, X., Yang, Y., Zhang, M., Cao, C., Wang, J., Wang, X., Gao, J., Wang, Y.-G.-S., Ji, J.-M., Qiu, Z., Li, M., Qian, C., Guo, T., Ma, S., Wang, Z., Guo, Z., Lei, Y., Shao, C., Wang, W., Fan, H., & Tang, Y.-D.
- Affiliations
- Peking University (CN)
- Tianjin University (CN)
- Chinese Academy of Medical Sciences & Peking Union Medical College (CN)
- Hebei Medical University (CN)
- Peking University Third Hospital (CN)
- Beihang University (CN)
- Corresponding author
- Fan, Haojun
- Tang, Yi-Da
- ORCID
- Venue
- iScience
- Publisher
- Elsevier BV
- Published
- 2024-05
- Volume
- 27
- Issue
- 5
- Pages
- 109713
- ISSN
- 2589-0042 (ISSN-L)
- PMC
- PMC11091685
- OpenAlex
- W4395052272
- Cited by
- 414
- References
- 114
- Citations by year
- 2026: 188 · 2025: 188 · 2024: 38
- FWCI
- 9.44
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- iScience (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- Funders
- National Key Research and Development Program of China Stem Cell and Translational Research (2020YFC2004705)
- National Natural Science Foundation of China (81825003, 82270376, 91957123)
- China Scholarship Council (CSCF2021A04)
- CAMS Innovation Fund for Medical Sciences
- Chinese Academy of Meteorological Sciences (2021-I2M-5-003, T-B-119)
- National Key Research and Development Program of China
- Beijing Municipal Science and Technology Commission, Adminitrative Commission of Zhongguancun Science Park
- Beijing Nova Program (Z201100006820002)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- large language models, ChatGPT, medical applications of AI, medical diagnostics, medical writing, medical education, training simulation, physician-patient communication, overreliance on AI, multimodal large language models, ethics of AI in healthcare
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
