

The DOI matches its Crossref record; 49 of the 54 references it cites were found in a registry or an index; none of the 25 sources its claims cite is checked for support yet.
Foundation model for cancer imaging biomarkers
Open accessAbstract
Foundation models in deep learning are characterized by a single large-scale model trained on vast amounts of data serving as the foundation for various downstream tasks. Foundation models are generally trained using self-supervised learning and excel in reducing the demand for training samples in downstream applications. This is especially important in medicine, where large labelled datasets are often scarce. Here, we developed a foundation model for cancer imaging biomarker discovery by training a convolutional encoder through self-supervised learning using a comprehensive dataset of 11,467 radiographic lesions. The foundation model was evaluated in distinct and clinically relevant applications of cancer imaging-based biomarkers. We found that it facilitated better and more efficient learning of imaging biomarkers and yielded task-specific models that significantly outperformed conventional supervised and other state-of-the-art pretrained implementations on downstream tasks, especially when training dataset sizes were very limited. Furthermore, the foundation model was more stable to input variations and showed strong associations with underlying biology. Our results demonstrate the tremendous potential of foundation models in discovering new imaging biomarkers that may extend to other clinical use cases and can accelerate the widespread translation of imaging biomarkers into clinical settings.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
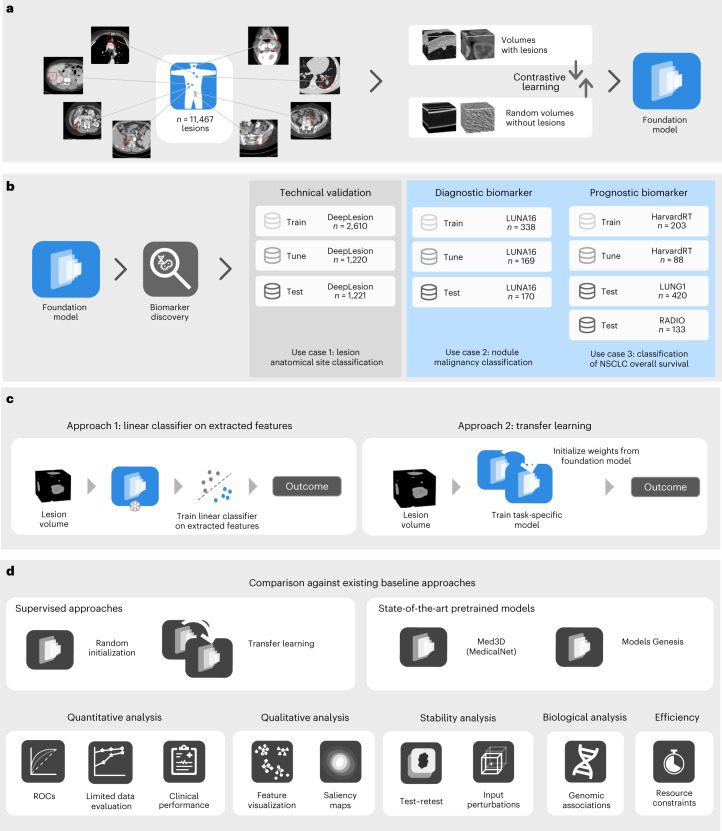
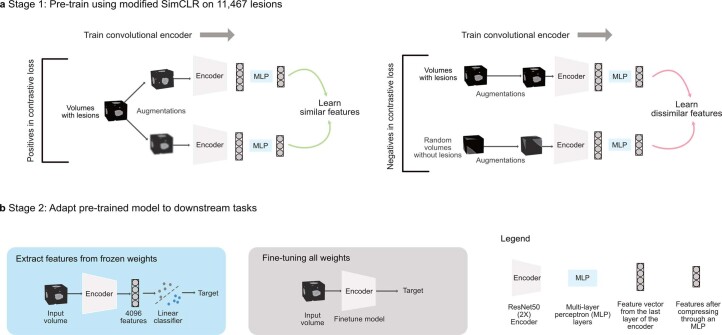
A 3D ResNet50 foundation model was pretrained with a modified SimCLR objective on 11,467 CT lesions from 2,312 patients and evaluated on anatomical site classification, lung nodule malignancy, and NSCLC prognosis. It improved downstream imaging-biomarker performance, especially with limited training data, and showed stability and biological associations.
Key findings
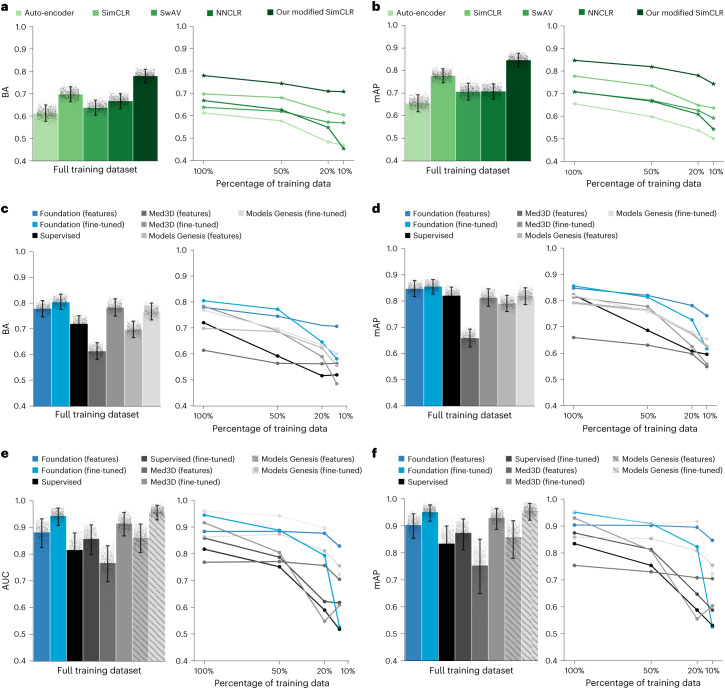
- Modified SimCLR pretraining outperformed auto-encoder, SimCLR, SwAV, and NNCLR on lesion anatomical site classification, achieving balanced accuracy 0.779 (95% CI 0.750–0.810) and mAP 0.847 (95% CI 0.750–0.810); SimCLR was second best with balanced accuracy 0.696 (95% CI 0.663–0.728) and mAP 0.779 (95% CI 0.749–0.811).
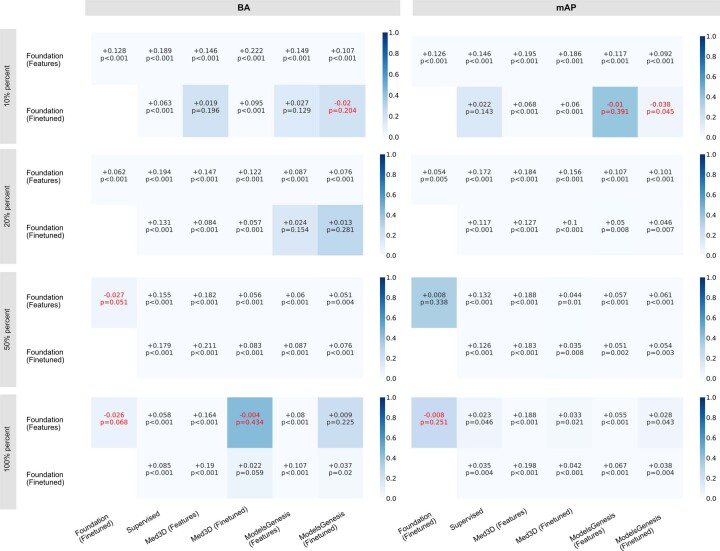
- For lesion anatomical site classification (use case 1), Foundation (fine-tuned) reached mAP 0.857 (95% CI 0.828–0.886) and balanced accuracy 0.804 (95% CI 0.775–0.835), significantly outperforming baselines on mAP and most baselines on balanced accuracy; Foundation (features) was especially robust under reduced training data.
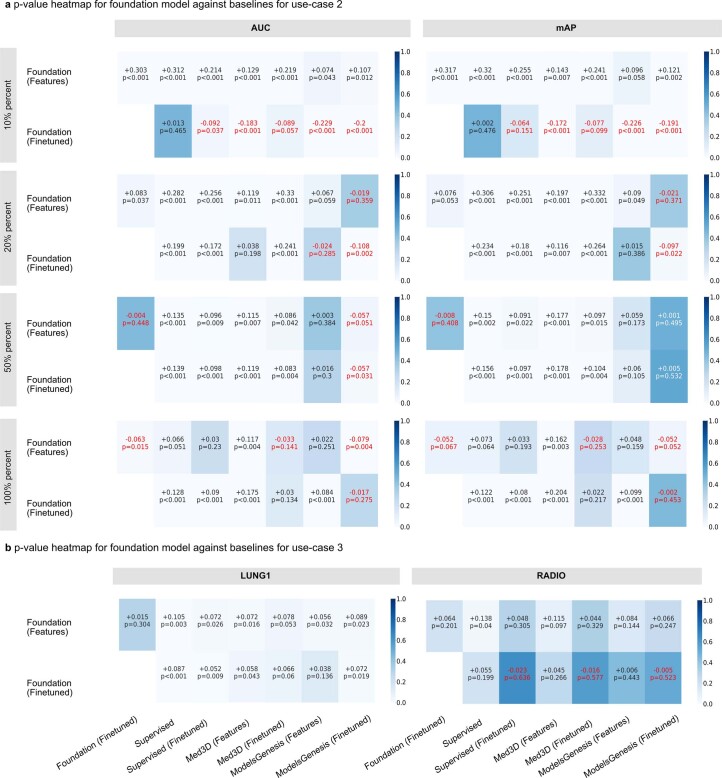
- For lung nodule malignancy (use case 2), Foundation (fine-tuned) achieved AUC 0.944 (95% CI 0.907–0.972) and mAP 0.953 (95% CI 0.915–0.979); Foundation (features) dominated baselines at 50%, 20%, and 10% training data (n = 254, 101, and 51).
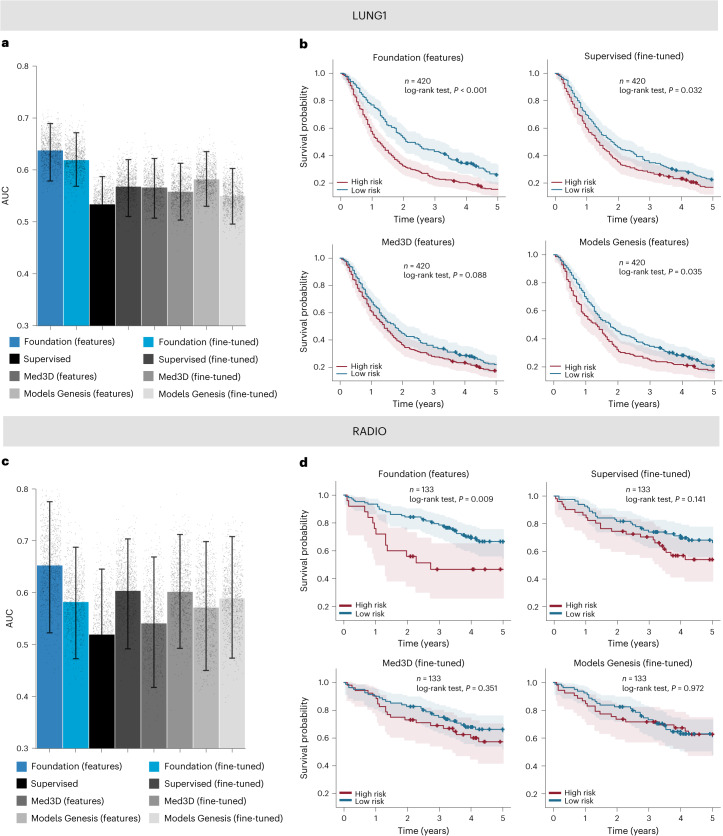
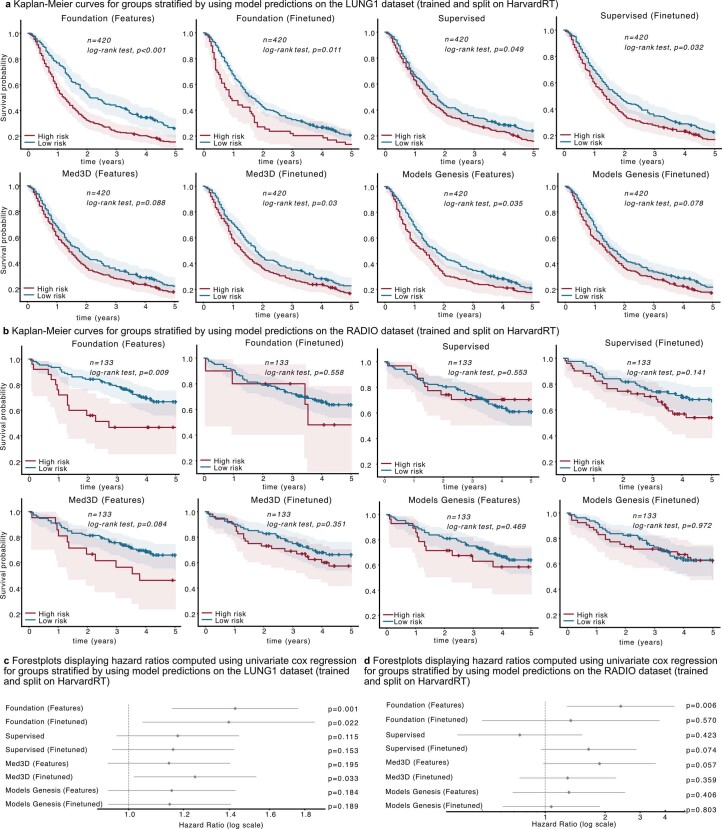
- For NSCLC prognostication (use case 3), Foundation (features) achieved AUC 0.638 (95% CI 0.584–0.692) on LUNG1 and AUC 0.653 (95% CI 0.532–0.771) on RADIO; it was the only model with significant Kaplan–Meier stratification on RADIO (P = 0.009), had test–retest ICC 0.984 versus 0.966 for Supervised (fine-tuned), and showed significantly higher absolute gene-expression correlations (P = 0.008) with immune-associated pathway enrichment.
Methods
- Design: self-supervised contrastive pretraining of a 3D ResNet50 encoder using a modified SimCLR framework on 11,467 unlabelled CT lesions from 5,513 scans across 2,312 patients; downstream tasks used either frozen features with a logistic regression classifier or full fine-tuning.
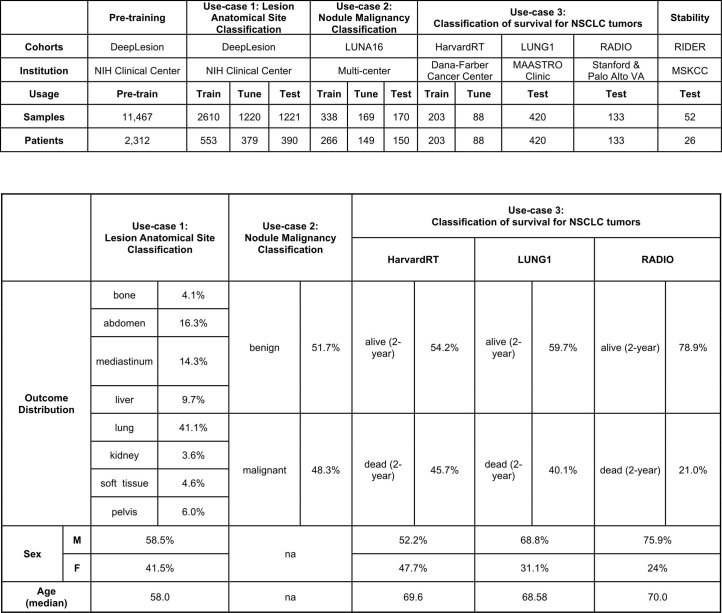
- Data: five datasets—DeepLesion, LUNA16, HarvardRT, LUNG1, and RADIO—covering three use cases: anatomical site classification (3,830 train/tune lesions; 1,221 test), nodule malignancy (338 train, 169 tune, 170 test nodules), and NSCLC 2-year overall survival (HarvardRT n = 291 train/tune; LUNG1 n = 420 and RADIO n = 133 test).
- Analysis: balanced accuracy and mAP for anatomical site, AUC-ROC for malignancy and prognosis, permutation tests with 1,000 permutations, bootstrap 95% CIs with 1,000 resamples, Kaplan–Meier/log-rank tests, stability analyses (ICC, MSE, perturbation trials), saliency maps, and gene-expression correlation plus gene-set enrichment analysis.
Limitations
- Stated by the paper: the study is retrospective; reliability across diverse demographic groups, distribution shifts, and biomarker tasks remains to be evaluated; larger pretraining data and integration of clinical covariates may be needed; deep-learning models remain “black box,” and saliency attribution methods have technical limitations; the biological association analysis is preliminary.
- Evident from the text: Models Genesis was excluded from use case 2 because it was pretrained on the same LUNA16 split, making comparison unfair due to overfitting; RADIO had a small sample size, so most model differences were not significant; reduced-training-data experiments were not performed for use case 3 because that use case already has inherently small sample sizes.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
50 Own result · 16 Not checked yet · 16 Own interpretation · 6 No basis given · 4 Own method
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
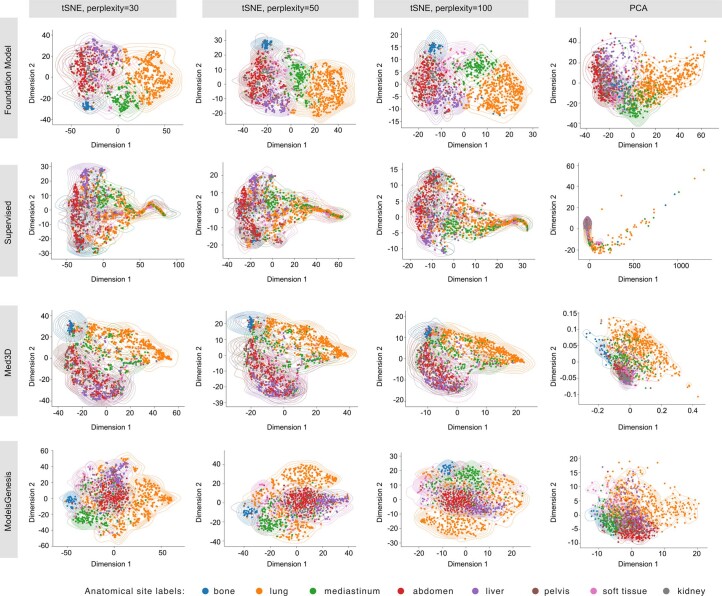
“We observed that features from the pretrained foundation model provided consistently interpretable and well-separated clusters across different settings.”
§ Foundation model for cancer imaging biomarkers > Results > Lesion anatomical site classification (use case 1)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Notably, none of the deep-learning fine-tuned baselines significantly improve over linear classification.”
§ Foundation model for cancer imaging biomarkers > Results > Nodule malignancy prediction (use case 2)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Moreover, when considering only mAP, the simple linear classification significantly (P < 0.05) outperformed all other implementations.”
§ Foundation model for cancer imaging biomarkers > Results > Lesion anatomical site classification (use case 1)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
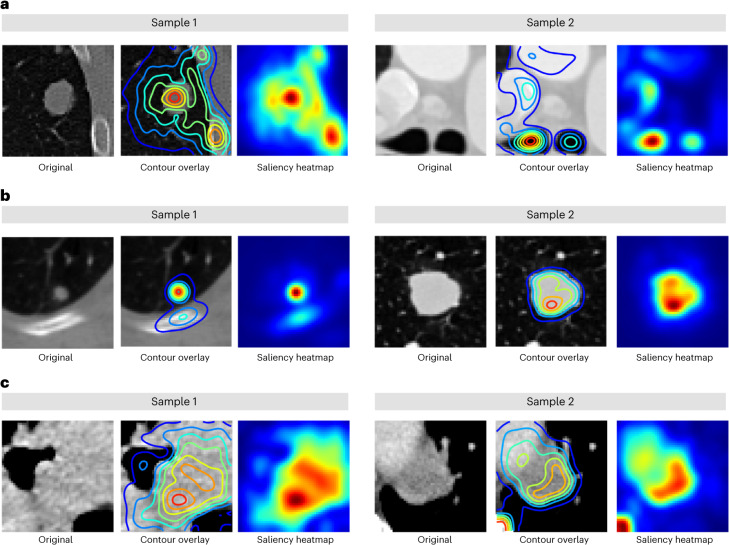
“Specifically, in use case 1 (Fig. 5a), the focus was mainly on areas surrounding the lesions, such as the parenchyma and bone regions in the lung and the trachea in mediastinal lesions.”
§ Foundation model for cancer imaging biomarkers > Results > Saliency maps for fine-tuned foundation models
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Similar to the LUNG1 cohort, deep-learning implementations did not demonstrate superior performance (Fig. 3c).”
§ Foundation model for cancer imaging biomarkers > Results > NSCLC prognostication (use case 3)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
- Rests on an assumption: Image-biomarker studies for predicting endpoints such as overall survival on small cohorts largely rely on statistical feature extraction (engineered radiomics) and classical machine learning-based modelling.
- Rests on an assumption: These statistical feature extraction approaches require precise 3D segmentations, increasing the annotation burden of these studies.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The auto-encoder approach, previously popular for pretraining, performed the worst compared to state-of-the-art contrastive SSL approaches.”
§ Foundation model for cancer imaging biomarkers > Results > Pretraining strategy selection
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: Following pretraining, foundation models can be applied to task-specific problems, improving generalization, especially in tasks with small datasets.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Regarding interpretability, we observed that models focused on varying regions of the tumour and surrounding tissue relevant to the associated use case.”
§ Foundation model for cancer imaging biomarkers > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our analysis revealed that for each use case, the focus was primarily around tissues within or in proximity to the tumour”
§ Foundation model for cancer imaging biomarkers > Results > Saliency maps for fine-tuned foundation models
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Features extracted from the foundation model, Foundation (features), when linearly classified, showed significantly improved performance in balanced accuracy and mAP over features extracted from Med3D (ref. 17) and Models Genesis18 baseline methods.”
§ Foundation model for cancer imaging biomarkers > Results > Lesion anatomical site classification (use case 1)
What the sources say
- Not checked yetcites [17] Chen, S., Ma, K. & Zheng, Y. Med3D: transfer learning for 3D medical image analysis. Preprint at https://arxiv.org/abs/1904.00625 (2019).
- Not checked yetcites [18] Zhou, Z. et al. Models Genesis: generic autodidactic models for 3D medical image analysis. Med. Image Comput. Comput. Assist. Interv. 11767, 384–393 (2019).
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, features and predictions from the foundation model features were found to be highly stable against inter-reader and test–retest variations.”
§ Foundation model for cancer imaging biomarkers > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- It may state two separate claims as one. 25
- Probably not a substantial claim. 18
- The quote only partly states this claim. 2
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
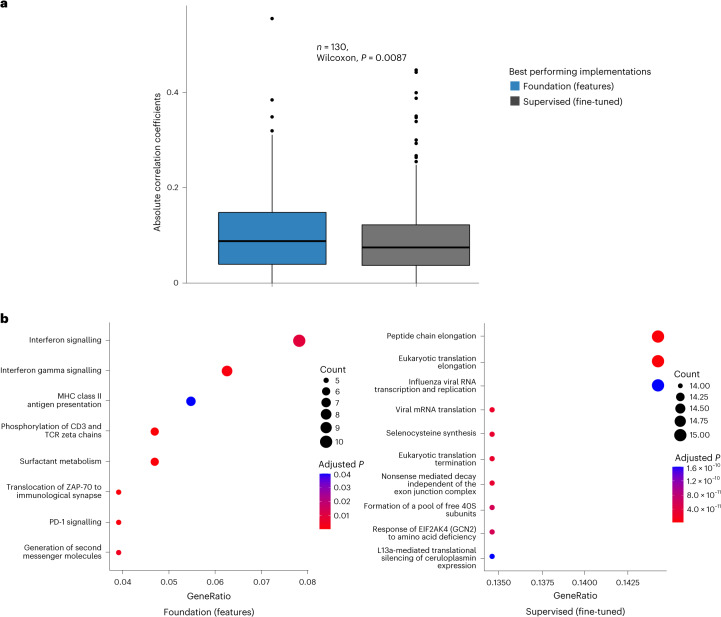
“Conversely, while the supervised model did show enrichment of individual pathways, no identifiable pattern was observed (Fig. 6b).”
§ Foundation model for cancer imaging biomarkers > Results > Underlying biological basis of the foundation model
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Use case 3 (Fig. 5c) primarily attributed areas surrounding the centre of mass of the tumour, with some contribution from high-density bone regions.”
§ Foundation model for cancer imaging biomarkers > Results > Saliency maps for fine-tuned foundation models
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The implementation Med3D (fine-tuned), with AUC = 0.917 (95% CI 0.871–0.957) and mAP = 0.9307 (95% CI 0.888–0.964), performs slightly worse than our model, but this is not significant (P = 0.134).”
§ Foundation model for cancer imaging biomarkers > Results > Nodule malignancy prediction (use case 2)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Using these features provided the best performance on small cohorts in predicting prognosis and also demonstrated significant stratification of patients by their associated risk for each of the LUNG1 and RADIO cohorts (P < 0.01).”
§ Foundation model for cancer imaging biomarkers > Discussion
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
- Rests on an assumption: Image-biomarker studies for predicting endpoints such as overall survival on small cohorts largely rely on statistical feature extraction (engineered radiomics) and classical machine learning-based modelling.
- Rests on an assumption: These statistical feature extraction approaches require precise 3D segmentations, increasing the annotation burden of these studies.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“With a balanced accuracy of 0.804 (95% CI 0.775–0.835), a significant (P < 0.01) improvement in balanced accuracy was also observed in comparison to all baselines except Med3D (fine-tuned), where the improvement was borderline (P = 0.059).”
§ Foundation model for cancer imaging biomarkers > Results > Lesion anatomical site classification (use case 1)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“achieving a balanced accuracy of 0.779 (95% confidence interval (CI) 0.750–0.810) and mAP = 0.847 (95% CI 0.750–0.810).”
§ Foundation model for cancer imaging biomarkers > Results > Pretraining strategy selection
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Following pretraining, foundation models can be applied to task-specific problems, improving generalization, especially in tasks with small datasets.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“All comparisons were significant (P < 0.05) except for Med3D (fine-tuned), where borderline significance was observed (P = 0.053).”
§ Foundation model for cancer imaging biomarkers > Results > NSCLC prognostication (use case 3)
plainn = 420 ·- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
- Rests on an assumption: Image-biomarker studies for predicting endpoints such as overall survival on small cohorts largely rely on statistical feature extraction (engineered radiomics) and classical machine learning-based modelling.
- Rests on an assumption: These statistical feature extraction approaches require precise 3D segmentations, increasing the annotation burden of these studies.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Due to the small sample size, none of the models showed significant differences from the rest (P > 0.05) except for the Foundation (features) improving over the Supervised model, which had near-random performance (AUC = 0.520).”
§ Foundation model for cancer imaging biomarkers > Results > NSCLC prognostication (use case 3)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
- Rests on an assumption: Image-biomarker studies for predicting endpoints such as overall survival on small cohorts largely rely on statistical feature extraction (engineered radiomics) and classical machine learning-based modelling.
- Rests on an assumption: These statistical feature extraction approaches require precise 3D segmentations, increasing the annotation burden of these studies.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The approach of fine-tuning the foundation model, Foundation (fine-tuned), with an area under the curve (AUC) = 0.944 (95% CI 0.907–0.972) and mAP = 0.953 (95% CI 0.915–0.979) resulted in significant (P < 0.01) superiority over most of the baseline implementations (Fig. 2e,f).”
§ Foundation model for cancer imaging biomarkers > Results > Nodule malignancy prediction (use case 2)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
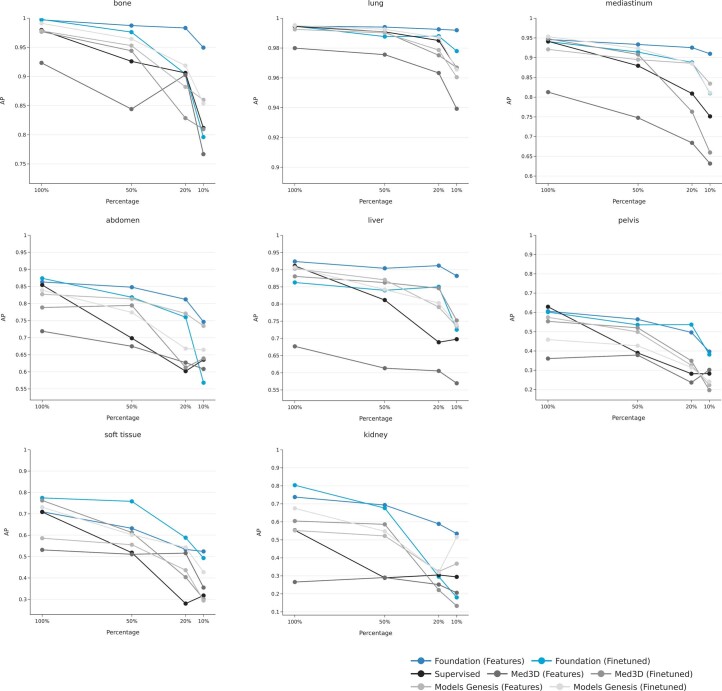
“More importantly, it remained robust as evidenced by the smallest decline in balanced accuracy and mAP of 9 and 12%, respectively, when reducing training data from 100 to 10%.”
§ Foundation model for cancer imaging biomarkers > Results > Pretraining strategy selection
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Following pretraining, foundation models can be applied to task-specific problems, improving generalization, especially in tasks with small datasets.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Foundation (fine-tuned) showed a larger drop in performance and failed to improve significantly over baseline implementations as training data were decreased (losing significance from 20% onward).”
§ Foundation model for cancer imaging biomarkers > Results > Lesion anatomical site classification (use case 1)
plaindirectn = 1,010- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
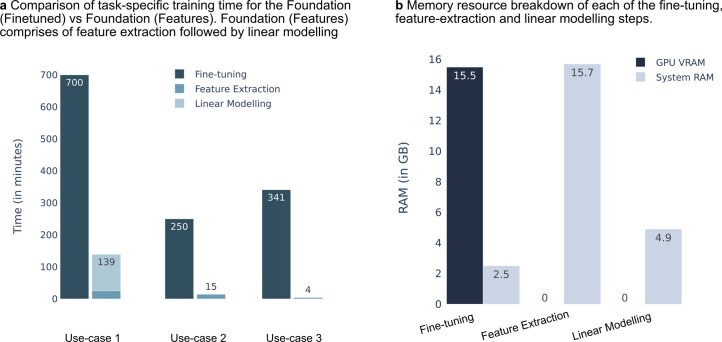
“Feature-based implementations were also computationally efficient when considering both time and memory.”
§ Foundation model for cancer imaging biomarkers > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the RADIO cohort, Foundation (features) shows the best performance with an AUC of 0.653 (95% CI 0.532–0.771).”
§ Foundation model for cancer imaging biomarkers > Results > NSCLC prognostication (use case 3)
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
- Rests on an assumption: Image-biomarker studies for predicting endpoints such as overall survival on small cohorts largely rely on statistical feature extraction (engineered radiomics) and classical machine learning-based modelling.
- Rests on an assumption: These statistical feature extraction approaches require precise 3D segmentations, increasing the annotation burden of these studies.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that absolute correlation coefficients between gene expression profiles and model predictions were significantly higher (P = 0.008) for the foundation model, indicating a stronger association with underlying tumour biology (Fig. 6a).”
§ Foundation model for cancer imaging biomarkers > Results > Underlying biological basis of the foundation model
hedgedcorrelationaln = 130 ·- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Modelling using features extracted from the foundation model was the most robust across these use cases when subjected to drops in training data, offering stable performance even when data sizes were considerably reduced, for example, using only 51 samples in use case 2.”
§ Foundation model for cancer imaging biomarkers > Discussion
plaincorrelationaln = 51- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“When limited data (50, 20 and 10%) was used for downstream task training, our method demonstrated consistently improved performance.”
§ Foundation model for cancer imaging biomarkers > Results > Pretraining strategy selection
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
- Rests on an assumption: Following pretraining, foundation models can be applied to task-specific problems, improving generalization, especially in tasks with small datasets.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As expected, the second best-performing approach was SimCLR (balanced accuracy 0.696 (95% CI 0.663–0.728); mAP = 0.779 (95% CI 0.749–0.811)).”
§ Foundation model for cancer imaging biomarkers > Results > Pretraining strategy selection
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Following pretraining, foundation models can be applied to task-specific problems, improving generalization, especially in tasks with small datasets.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
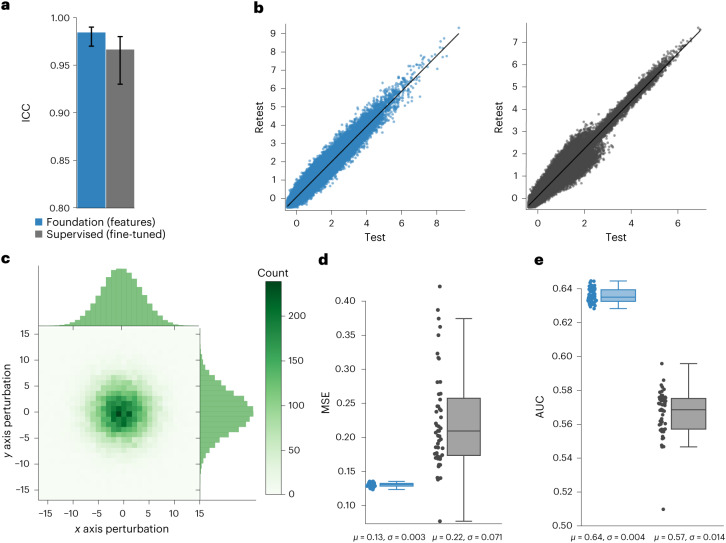
“We found that predictions from the overall best-performing models on LUNG1 and RADIO: Foundation (features) and Supervised (fine-tuned) had high stability with intraclass correlation coefficient (ICC) values of 0.984 and 0.966, respectively.”
§ Foundation model for cancer imaging biomarkers > Results > Stability of the foundation model
plainn = 26- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Foundation (fine-tuned) shows superior performance over all baselines at 50% but shows large drops in performance from a 20% reduction onward.”
§ Foundation model for cancer imaging biomarkers > Results > Nodule malignancy prediction (use case 2)
plaincorrelationaln = 254- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Furthermore, it surpasses current deep-learning techniques in various tasks while fitting conveniently into existing radiomic research methods.”
§ Foundation model for cancer imaging biomarkers > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, the original value of 0.1 proposed by the original paper was the most effective.”
§ Foundation model for cancer imaging biomarkers > Methods > Task-agnostic pretraining of the foundation model
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The baseline Models Genesis implementation was excluded in this analysis as this model was pretrained on the same dataset and, therefore, does not indicate a fair comparison.”
§ Foundation model for cancer imaging biomarkers > Results > Nodule malignancy prediction (use case 2)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By contrast, our approach is generalizable to multiple use cases, and for nodule malignancy, we obtain high performance using significantly lesser training data, only 338 nodules (due to our more stringent exclusion criteria).”
§ Foundation model for cancer imaging biomarkers > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
- Rests on an assumption: The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
In the paper
“which is consistent with research demonstrating the tumour microenvironment’s influence on cancer development22 and prognosis.”
§ Foundation model for cancer imaging biomarkers > Results > Saliency maps for fine-tuned foundation models
What the sources say
- Not checked yetcites [22] Hinshaw, D. C. & Shevde, L. A. The tumor microenvironment innately modulates cancer progression. Cancer Res. 79, 4557–4566 (2019). source
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“as expressing saliency maps over 4,096-dimensional outputs remains challenging in practice.”
§ Foundation model for cancer imaging biomarkers > Methods > Feature visualization and saliency maps
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This approach allows for significantly higher throughput than manual segmentation, which can be more tedious.”
§ Foundation model for cancer imaging biomarkers > Methods > Data preprocessing
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In conclusion, our foundation model offers a powerful and reliable framework for discovering cancer imaging biomarkers, especially in small datasets.”
§ Foundation model for cancer imaging biomarkers > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
In the paper
“Existing literature12 has suggested several strategies, such as image reconstruction, to pretrain networks to learn these representations.”
§ Foundation model for cancer imaging biomarkers > Main
What the sources say
- Not checked yetcites [12] Balestriero, R. et al. A cookbook of self-supervised learning. Preprint at https://arxiv.org/abs/2304.12210 (2023).
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“This point largely depends on the nature and sizes of training data in the downstream task.”
§ Foundation model for cancer imaging biomarkers > Discussion
What the sources say
- Not checked yetcites Cole et al.38 Cole, E., Yang, X., Wilber, K., Aodha, O. M. & Belongie, S. When does contrastive visual representation learning work? In Proc. 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 14755–14764 (IEEE, 2022). source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Deep-learning methods, in comparison, are robust to differences in acquisition and segmentation variability and provide improved performance10.”
§ Foundation model for cancer imaging biomarkers > Discussion
What the sources say
- Not checked yetcites [10] Hosny, A. et al. Deep learning for lung cancer prognostication: a retrospective multi-cohort radiomics study. PLoS Med. 15, e1002711 (2018). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“as it is typical to have inherently small sample sizes in such use cases when compared to task complexity due to study-specific inclusion criteria.”
§ Foundation model for cancer imaging biomarkers > Methods > Task-specific training of the foundation model
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Third, a significant challenge with deep-learning models, including ours, is their ‘black box’ nature, which limits interpretability and explainability.”
§ Foundation model for cancer imaging biomarkers > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In our study, we pretrained on 11,467 lesion volumes and randomly sampled volumes, from 5,513 unique CT scans, leveraging not only one of the largest lesion-specific datasets but also one of the largest pretraining 3D CT datasets.”
§ Foundation model for cancer imaging biomarkers > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“While many studies investigating imaging-based biomarkers incorporate supervised deep-learning algorithms into their models9–11, they are typically applied in scenarios where large datasets are available for training and testing.”
§ Foundation model for cancer imaging biomarkers > Main
What the sources say
- Not checked yetcites [9] Mahajan, A. et al. Deep learning-based predictive imaging biomarker model for EGFR mutation status in non-small cell lung cancer from CT imaging. J. Clin. Orthod. 38, 3106 (2020).
- Not checked yetcites [10] Hosny, A. et al. Deep learning for lung cancer prognostication: a retrospective multi-cohort radiomics study. PLoS Med. 15, e1002711 (2018). source
- Not checked yetcites [11] Braghetto, A., Marturano, F., Paiusco, M., Baiesi, M. & Bettinelli, A. Radiomics and deep learning methods for the prediction of 2-year overall survival in LUNG1 dataset. Sci. Rep. 12, 14132 (2022). source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“They show a saturation point associated with pretraining dataset size and diminishing returns beyond this point.”
§ Foundation model for cancer imaging biomarkers > Discussion
What the sources say
- Not checked yetcites Cole et al.38 Cole, E., Yang, X., Wilber, K., Aodha, O. M. & Belongie, S. When does contrastive visual representation learning work? In Proc. 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) 14755–14764 (IEEE, 2022). source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“In our comparative analysis, we maintained uniformity in batch sizes and dataset parameters across all methods, while optimizer and loss-specific settings were aligned with each method’s original configuration.”
§ Foundation model for cancer imaging biomarkers > Methods > Task-agnostic pretraining of the foundation model
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Furthermore, our initial biological association analysis, aimed at explaining the model’s decisions, is preliminary and requires more rigorous investigation for a concrete understanding.”
§ Foundation model for cancer imaging biomarkers > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“due to the high proportion of negatives relative to positives, which results in consistently low false-positive rates and might overestimate the AUC.”
§ Foundation model for cancer imaging biomarkers > Methods > Performance analysis
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Several studies23–25 have demonstrated the efficacy of SSL in medicine where only limited data might be available for training deep-learning networks.”
§ Foundation model for cancer imaging biomarkers > Discussion
What the sources say
- Not checked yetcites [23] Azizi, S. et al. Big self-supervised models advance medical image classification. In 2021 IEEE/CVF International Conference on Computer Vision (ICCV) 3458–3468 (IEEE, 2021). source
- Not checked yetcites [24] Krishnan, R., Rajpurkar, P. & Topol, E. J. Self-supervised learning in medicine and healthcare. Nat. Biomed. Eng. 6, 1346–1352 (2022). source
- Not checked yetcites [25] Ghesu, F. C. et al. Contrastive self-supervised learning from 100 million medical images with optional supervision. J. Med. Imaging 9, 064503 (2022). source
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“We used scans from 26 patients from the RIDER dataset19, routinely used for test–retest robustness analysis in tumour imaging19–21.”
§ Foundation model for cancer imaging biomarkers > Results > Stability of the foundation model
What the sources say
- Not checked yetcites [19] Zhao, B. et al. Evaluating variability in tumor measurements from same-day repeat CT scans of patients with non-small cell lung cancer. Radiology 252, 263–272 (2009). source
- Not checked yetcites [20] Aerts, H. J. W. L. et al. Decoding tumour phenotype by noninvasive imaging using a quantitative radiomics approach. Nat. Commun. 5, 4006 (2014). source
- Not checked yetcites [21] Hosny, A. et al. Clinical validation of deep learning algorithms for radiotherapy targeting of non-small-cell lung cancer: an observational study. Lancet Digit. Health 4, e657–e666 (2022). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Therefore, experiments involving further data reduction in this case do not provide any valuable insights.”
§ Foundation model for cancer imaging biomarkers > Methods > Task-specific training of the foundation model
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
The paper relies on this without support.
Access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.
“However, access to large amounts of annotated data for specialized applications is often challenging and demands expertise, time and labour.”
The paper relies on this without support.
There is still limited evidence investigating whether SSL can help train foundation models that learn general, robust and transferrable representations that can act as imaging biomarkers, especially prognostic, for tasks of clinical relevance.
“There is still limited evidence investigating whether SSL can help train foundation models that learn general, robust and transferrable representations that can act as imaging biomarkers, especially prognostic, for tasks of clinical relevance.”
The paper relies on this without support.
The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.
“The quantity and quality of annotated data are strongly linked to the robustness of deep-learning models.”
The paper relies on this without support.
In scenarios with limited annotated data, many investigators fall back on traditional handcrafted or engineered approaches that limit the scope of discovery.
“In such scenarios, many investigators fall back on traditional handcrafted or engineered approaches based on defined mathematical and statistical algorithms that analyse attributes such as the shape and texture of objects in images, which limit the scope of discovery.”
The paper relies on this without support.
Following pretraining, foundation models can be applied to task-specific problems, improving generalization, especially in tasks with small datasets.
“Following pretraining, foundation models can be applied to task-specific problems, improving generalization, especially in tasks with small datasets.”
The paper relies on this without support.
Image-biomarker studies for predicting endpoints such as overall survival on small cohorts largely rely on statistical feature extraction (engineered radiomics) and classical machine learning-based modelling.
“Image-biomarker studies for predicting endpoints, such as overall survival on small cohorts, largely rely on statistical feature extraction (engineered radiomics) and classical machine learning-based modelling.”
The paper relies on this without support.
These statistical feature extraction approaches require precise 3D segmentations, increasing the annotation burden of these studies.
“These require precise 3D segmentations for feature extraction, increasing the annotation burden of these studies.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Built on rich knowledge representations, these models have shown impressive performance across medical fields such as ophthalmology20, radiology21 and pathology22–25.”
From A Multimodal Vision Foundation Model for Clinical Dermatology (2025) · cites this paper as [21]
In the citing paper
“In oncology, transformer-based methods support clinical text processing, whole-slide and radiologic image interpretation (vision transformers), and genomic sequence modeling [24,25,26,27].”
From Artificial Intelligence in Clinical Oncology: From Productivity Enhancement to Creative Discovery (2025) · cites this paper as [24]
In the citing paper
“Specialty-specific foundation models20,21,23 typically focus on single imaging modalities”
From A Multimodal Vision Foundation Model for Clinical Dermatology (2025) · cites this paper as [21]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Foundation model for cancer imaging biomarkers > Results > Stability of the foundation model
“Each AUC and MSE measure in the box plots (d,e) have been computed on a dataset with n = 422 samples”
§ Foundation model for cancer imaging biomarkers > Methods > Study population
“For our study, we selected CT scans of 420 patients (right-censored for 2-year survival) with annotated primary gross tumour volumes and used these as an independent test set for prognostication networks.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Foundation model for cancer imaging biomarkers > Results > Pretraining strategy selection
“mAP = 0.847”
§ Foundation model for cancer imaging biomarkers > Results > Pretraining strategy selection
“95% CI 0.750–0.810”
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Learning Transferable Visual Models From Natural Language Supervision
Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., et al. (2021) · arXiv · doi:10.48550/arxiv.2103.00020 · Cited by 15,293
Larian Studios Dev Team (2024) · doi:10.1145/3292500.3330701 · Cited by 8,618
Decoding tumour phenotype by noninvasive imaging using a quantitative radiomics approach
Aerts, H. J. W. L., Velazquez, E. R., Leijenaar, R. T. H., Parmar, C., Grossmann, P., Carvalho, S., Bussink, J., Monshouwer, R., Haibe-Kains, B., Rietveld, D., et al. (2014) · Nature Communications · doi:10.1038/ncomms5006 · Cited by 5,132
Self-citationTraining language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
The Tumor Microenvironment Innately Modulates Cancer Progression
Hinshaw, D. C., & Shevde, L. A. (2019) · Cancer Research · doi:10.1158/0008-5472.can-18-3962 · Cited by 3,270
On the Opportunities and Risks of Foundation Models
Bommasani, R., Hudson, D. A., Adeli, E., Altman, R., Arora, S., von Arx, S., Bernstein, M. S., Bohg, J., Bosselut, A., Brunskill, E., et al. (2021) · arXiv · doi:10.48550/arxiv.2108.07258 · Cited by 2,676
Unsupervised Learning of Visual Features by Contrasting Cluster Assignments
Caron, M., Misra, I., Mairal, J., Goyal, P., Bojanowski, P., & Joulin, A. (2020) · arXiv · doi:10.48550/arxiv.2006.09882 · Cited by 2,499
Foundation models for generalist medical artificial intelligence
Moor, M., Banerjee, O., Abad, Z. S. H., Krumholz, H. M., Leskovec, J., Topol, E. J., & Rajpurkar, P. (2023) · Nature · doi:10.1038/s41586-023-05881-4 · Cited by 2,028
SmoothGrad: removing noise by adding noise
Smilkov, D., Thorat, N., Kim, B., Viégas, F., & Wattenberg, M. (2017) · arXiv · doi:10.48550/arxiv.1706.03825 · Cited by 1,467
Setio, A. A. A., Traverso, A., de Bel, T., Berens, M. S. N., van den Bogaard, C., Cerello, P., Chen, H., Dou, Q., Fantacci, M. E., Geurts, B. H. J., et al. (2017) · Medical Image Analysis · doi:10.1016/j.media.2017.06.015 · Cited by 1,456
DINOv2: Learning Robust Visual Features without Supervision
Oquab, M., Darcet, T., Moutakanni, T., Vo, H., Szafraniec, M., Khalidov, V., Fernandez, P., Haziza, D., Massa, F., El-Nouby, A., et al. (2023) · arXiv · doi:10.48550/arxiv.2304.07193 · Cited by 1,078
A foundation model for generalizable disease detection from retinal images
Zhou, Y., Chia, M. A., Wagner, S. K., Ayhan, M. S., Williamson, D. J., Struyven, R. R., Liu, T., Xu, M., Lozano, M. G., Woodward-Court, P., et al. (2023) · Nature · doi:10.1038/s41586-023-06555-x · Cited by 1,014
Diffusion models in medical imaging: A comprehensive survey
Kazerouni, A., Aghdam, E. K., Heidari, M., Azad, R., Fayyaz, M., Hacihaliloglu, I., & Merhof, D. (2023) · Medical Image Analysis · doi:10.1016/j.media.2023.102846 · Cited by 1,006
Understanding the Behaviour of Contrastive Loss
Wang, F., & Liu, H. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00252 · Cited by 730
Big Self-Supervised Models Advance Medical Image Classification
Azizi, S., Mustafa, B., Ryan, F., Beaver, Z., Freyberg, J., Deaton, J., Loh, A., Karthikesalingam, A., Kornblith, S., Chen, T., et al. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00346 · Cited by 685
Med3D: Transfer Learning for 3D Medical Image AnalysisPreprint
Chen, S., Ma, K., & Zheng, Y. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1904.00625 · Cited by 656
Multi-crop Convolutional Neural Networks for lung nodule malignancy suspiciousness classification
Shen, W., Zhou, M., Yang, F., Yu, D., Dong, D., Yang, C., Zang, Y., & Tian, J. (2016) · Pattern Recognition · doi:10.1016/j.patcog.2016.05.029 · Cited by 655
Multi-scale Convolutional Neural Networks for Lung Nodule Classification
Shen, W., Zhou, M., Yang, F., Yang, C., & Tian, J. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-19992-4_46 · Cited by 649
Self-supervised learning in medicine and healthcare
Krishnan, R., Rajpurkar, P., & Topol, E. J. (2022) · Nature Biomedical Engineering · doi:10.1038/s41551-022-00914-1 · Cited by 605
Deep learning for lung cancer prognostication: A retrospective multi-cohort radiomics study
Hosny, A., Parmar, C., Coroller, T. P., Grossmann, P., Zeleznik, R., Kumar, A., Bussink, J., Gillies, R. J., Mak, R. H., & Aerts, H. J. W. L. (2018) · PLOS Medicine · doi:10.1371/journal.pmed.1002711 · Cited by 579
Self-citationYan, K., Wang, X., Lu, L., & Summers, R. M. (2018) · Journal of medical imaging · doi:10.1117/1.jmi.5.3.036501 · Cited by 573
MONAI: An open-source framework for deep learning in healthcarePreprint
Cardoso, M. J., Li, W., Brown, R., Ma, N., Kerfoot, E., Wang, Y., Murrey, B., Myronenko, A., Zhao, C. H., Yang, D., et al. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2211.02701 · Cited by 485
Huang, S.-C., Pareek, A., Jensen, M., Lungren, M. P., Yeung, S., & Chaudhari, A. S. (2023) · npj Digital Medicine · doi:10.1038/s41746-023-00811-0 · Cited by 479 · cited 2×
“The expanding literature on SSL in medical imaging 13 focuses primarily on two-dimensional (2D) images (X-ray, whole slide images, dermatology images, fundus images and so on) for diagnostic applications.”
Tiu, E., Talius, E., Patel, P., Langlotz, C. P., Ng, A. Y., & Rajpurkar, P. (2022) · Nature Biomedical Engineering · doi:10.1038/s41551-022-00936-9 · Cited by 442
With a Little Help from My Friends: Nearest-Neighbor Contrastive Learning of Visual Representations
Dwibedi, D., Aytar, Y., Tompson, J., Sermanet, P., & Zisserman, A. (2021) · arXiv · doi:10.48550/arxiv.2104.14548 · Cited by 405
With a Little Help from My Friends: Nearest-Neighbor Contrastive Learning of Visual Representations
Dwibedi, D., Aytar, Y., Tompson, J., Sermanet, P., & Zisserman, A. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00945 · Cited by 404
Models Genesis: Generic Autodidactic Models for 3D Medical Image Analysis
Zhou, Z., Sodha, V., Siddiquee, M. M. R., Feng, R., Tajbakhsh, N., Gotway, M. B., & Liang, J. (2019) · Lecture notes in computer science · doi:10.1007/978-3-030-32251-9_42 · Cited by 342
Assessing the trustworthiness of saliency maps for localizing abnormalities in medical imaging
Arun, N., Gaw, N., Singh, P., Chang, K., Aggarwal, M., Chen, B., Hoebel, K., Gupta, S., Patel, J., Gidwani, M., et al. (2021) · Radiology: Artificial Intelligence · doi:10.1148/ryai.2021200267 · Cited by 342
Zhao, B., James, L. P., Moskowitz, C. S., Guo, P., Ginsberg, M. S., Lefkowitz, R. A., Qin, Y., Riely, G. J., Kris, M. G., & Schwartz, L. H. (2009) · Radiology · doi:10.1148/radiol.2522081593 · Cited by 337
Robust and data-efficient generalization of self-supervised machine learning for diagnostic imaging
Azizi, S., Culp, L., Freyberg, J., Mustafa, B., Baur, S., Kornblith, S., Chen, T., Tomasev, N., Mitrović, J., Strachan, P., et al. (2023) · Nature Biomedical Engineering · doi:10.1038/s41551-023-01049-7 · Cited by 250
A Cookbook of Self-Supervised Learning
Balestriero, R., Ibrahim, M., Sobal, V., Morcos, A., Shekhar, S., Goldstein, T., Bordes, F., Bardes, A., Mialon, G., Tian, Y., et al. (2023) · arXiv · doi:10.48550/arxiv.2304.12210 · Cited by 182 · cited 1×
“Existing literature 12 has suggested several strategies, such as image reconstruction, to pretrain networks to learn these representations.”
Foundational Models in Medical Imaging: A Comprehensive Survey and Future VisionPreprint
Azad, B., Azad, R., Eskandari, S., Bozorgpour, A., Kazerouni, A., Rekik, I., & Merhof, D. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.18689 · Cited by 158
Radiomics feature reproducibility under inter-rater variability in segmentations of CT images
Haarburger, C., Müller-Franzes, G., Weninger, L., Kuhl, C., Truhn, D., & Merhof, D. (2020) · Scientific Reports · doi:10.1038/s41598-020-69534-6 · Cited by 139
Aerts, H. J. W. L., Wee, L., Rios Velazquez, E., et al. (2019) · Research Publications (Maastricht University) · doi:10.7937/k9/tcia.2015.pf0m9rei · Cited by 125
Self-citationContrastive self-supervised learning from 100 million medical images with optional supervision
Ghesu, F. C., Georgescu, B., Mansoor, A., Yoo, Y., Neumann, D., Patel, P. K., Vishwanath, R. S., Balter, J. M., Cao, Y., Grbić, S., et al. (2022) · Journal of medical imaging · doi:10.1117/1.jmi.9.6.064503 · Cited by 111
When Does Contrastive Visual Representation Learning Work?
Cole, E., Yang, X., Wilber, K., Aodha, O. M., & Belongie, S. (2022) · 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52688.2022.01434 · Cited by 105
Mukherjee, P., Zhou, M., Lee, E. H., Schicht, A., Balagurunathan, Y., Napel, S. A., Gillies, R. J., Wong, S. S., Thieme, A. H., Leung, A. N. C., et al. (2020) · Nature Machine Intelligence · doi:10.1038/s42256-020-0173-6 · Cited by 100
Fedorov, A., Longabaugh, W. J. R., Pot, D., Clunie, D., Pieper, S., Aerts, H. J. W. L., Homeyer, A., Lewis, R., Akbarzadeh, A., Bontempi, D., et al. (2021) · Cancer Research · doi:10.1158/0008-5472.can-21-0950 · Cited by 77
Self-citationHosny, A., Bitterman, D. S., Guthier, C. V., Qian, J. M., Roberts, H. J., Perni, S., Saraf, A., Peng, L. C., Pashtan, I. M., Ye, Z., et al. (2022) · The Lancet Digital Health · doi:10.1016/s2589-7500(22)00129-7 · Cited by 74
Self-citationImage-Based Survival Prediction for Lung Cancer Patients Using CNNS
Haarburger, C., Weitz, P., Rippel, O., & Merhof, D. (2019) · IEEE International Symposium on Biomedical Imaging (ISBI) · doi:10.1109/isbi.2019.8759499 · Cited by 61
Models Genesis: Generic Autodidactic Models for 3D Medical Image AnalysisPreprint
Zhou, Z., Sodha, V., Siddiquee, M. M. R., et al. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1908.06912 · Cited by 44
Mahajan, A., Kania, V., Agarwal, U., Ashtekar, R. M., Shukla, S., Patil, V., Noronha, V., Joshi, A., Menon, N. S., Kumar, R., et al. (2024) · Cancers · doi:10.3390/cancers16061130 · Cited by 39
Radiomics and deep learning methods for the prediction of 2-year overall survival in LUNG1 dataset
Braghetto, A., Marturano, F., Paiusco, M., Baiesi, M., & Bettinelli, A. (2022) · Scientific Reports · doi:10.1038/s41598-022-18085-z · Cited by 34
Uemura, T., Näppi, J. J., Hironaka, T., Kim, H., & Yoshida, H. (2020) · Medical Imaging 2020: Computer-Aided Diagnosis · doi:10.1117/12.2549103 · Cited by 31 · cited 1×
“While the SimCLR authors used a 2D ResNet50 architecture, we opted for its 3D counterpart, which has proven effective in handling 3D medical imaging data 46 .”
Foundation Models in Healthcare: Opportunities, Risks & Strategies Forward
Thieme, A., Nori, A., Ghassemi, M., Bommasani, R., Andersen, T. O., & Luger, E. (2023) · Extended Abstracts of the 2023 CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544549.3583177 · Cited by 25
Minimising multi-centre radiomics variability through image normalisation: a pilot study
Campello, V. M., Martín-Isla, C., Izquierdo, C., Guala, A., Palomares, J. F. R., Viladés, D., Descalzo, M. L., Karakas, M., Çavuş, E., Raisi-Estabragh, Z., et al. (2022) · Scientific Reports · doi:10.1038/s41598-022-16375-0 · Cited by 24
NSCLC Radiogenomics: Initial Stanford Study of 26 Cases
Napel, S., & Plevritis, S. K. (2014) · The Cancer Imaging Archive · doi:10.7937/k9/tcia.2014.x7ony6b1 · Cited by 13
Mahajan, A., Kania, V., Patil, V., et al. (2020) · Journal of Clinical Oncology · doi:10.1200/jco.2020.38.15_suppl.3106 · Cited by 8
Research works printed but not linked: 8
- Devlin, J., Chang, M.-W., Lee, K. & Toutanova, K. BERT: Pre-training of deep bidirectional transformers for language understanding. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics (eds Burstein, J. et al.) 4171–4186 (ACL, 2019).
- Chen, T., Kornblith, S., Norouzi, M. & Hinton, G. A simple framework for contrastive learning of visual representations. In Proc. 37th International Conference on Machine Learning (eds III, H.D. & Singh, A.) 1597–1607 (PMLR, 2020).
- Kumar, D. et al. in Image Analysis and Recognition (eds Karray, F. et al.) 54–62 (Springer, 2017).
- Taleb, A. et al. 3D self-supervised methods for medical imaging. Adv. Neural Inf. Process. Syst. 33, 18158–18172 (2020).
- Adebayo, J. et al. Sanity checks for saliency maps. In Advances in Neural Information Processing Systems 9505–9515 (Curran Associates, 2018).
- Sohn, K. Improved deep metric learning with multi-class N-pair loss objective. In Advances in Neural Information Processing Systems (eds Lee, D. et al.) 1857–1865 (Curran Associates, 2016).
- van der Maaten, L. & Hinton, G. Visualizing data using t-SNE. J. Mach. Learn. Res. 9, 2579–2605 (2008).
- Springenberg, J. T., Dosovitskiy, A., Brox, T. & Riedmiller, M. A. Striving for simplicity: the all convolutional net. In 3rd International Conference on Learning Representations Workshop (ICLR, 2015).
Cited by
Sorted by citations
Artificial intelligence in drug development
Zhang, K., Yang, X., Wang, Y., Yu, Y., Huang, N., Li, G. L., Li, X., Wu, J. C., & Yang, S. (2025) · Nature Medicine · doi:10.1038/s41591-024-03434-4 · Cited by 585
“Robust validation and responsible data curation will facilitate biomarker identification and application, supporting future drug development and disease treatment.”
Medical digital twins: enabling precision medicine and medical artificial intelligence
Sadée, C., Testa, S., Barba, T., Hartmann, K., Schuessler, M., Thieme, A. H., Church, G. M., Okoye, I. J., Hernandez‐Boussard, T., Hood, L., et al. (2025) · The Lancet Digital Health · doi:10.1016/j.landig.2025.02.004 · Cited by 167
“19,40 These abstract feature vectors are then concatenated in a data fusion approach and passed to the patient-in-silico.”
Acquired resistance in cancer: towards targeted therapeutic strategies
Soragni, A., Knudsen, E. S., O’Connor, T. N., Tognon, C. E., Tyner, J. W., Gini, B., Kim, D., Bivona, T. G., Zang, X., Witkiewicz, A. K., et al. (2025) · Nature reviews. Cancer · doi:10.1038/s41568-025-00824-9 · Cited by 151
“AI foundation models that link imaging and pathology provide new perspectives on spatial and temporal resistance trajectories to enhance cancer therapy and resistance monitoring 289 .”
Generative artificial intelligence in medicine
Teo, Z. L., Thirunavukarasu, A. J., Elangovan, K., Cheng, H., Moova, P., Soetikno, B., Nielsen, C., Pollreisz, A., Ting, D. S. J., Morris, R. J. T., et al. (2025) · Nature Medicine · doi:10.1038/s41591-025-03983-2 · Cited by 119
A Multimodal Vision Foundation Model for Clinical Dermatology
Yan, S., Yu, Z., Primiero, C., Vico-Alonso, C., Wang, Z., Yang, L., Tschandl, P., Hu, M., Ju, L., Tan, G., et al. (2025) · Nature Medicine · doi:10.1038/s41591-025-03747-y · Cited by 117
“Specialty-specific foundation models 20,21,23 typically focus on single imaging modalities, while general biomedical models, despite their broad scope, struggle with domain-specific data scarcity and integrating heterogeneous modalities for comprehensive clinical analysis.”
Metadata
- Authors
- Pai, S., Bontempi, D., Hadzic, I., Prudente, V., Sokač, M., Chaunzwa, T. L., Bernatz, S., Hosny, A., Mak, R. H., Birkbak, N. J., & Aerts, H. J. W. L.
- Affiliations
- Brigham and Women's Hospital (US)
- Aarhus University (DK)
- Harvard University (US)
- Corresponding author
- Aerts, Hugo J. W. L.
- ORCID
- Venue
- Nature Machine Intelligence
- Published
- 2024-03-15
- Volume
- 6
- Issue
- 3
- Pages
- 354-367
- ISSN
- 2522-5839 (ISSN-L)
- PMC
- PMC10957482
- OpenAlex
- W4392850630
- Semantic Scholar
- b0dc5a23b2f834660c53c436bd1c3dd9fa01d354
- Cited by
- 199
- References
- 54
- Citations by year
- 2026: 81 · 2025: 98 · 2024: 19
- FWCI
- 50.44
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- Nature Machine Intelligence (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Research Publications (Maastricht University) (publishedVersion, cc-by)
- Funders
- European Commission
- Deutsche Forschungsgemeinschaft (502050303)
- National Institutes of Health (R35CA22052)
- National Cancer Institute (U01CA190234, U24CA194354, U54CA274516, U01CA209414)
- H2020 European Research Council (866504)
- Topics
- Health Sciences › Medicine › Radiology, Nuclear Medicine and Imaging › Radiomics and Machine Learning in Medical Imaging
- Physical Sciences › Computer Science › Artificial Intelligence › AI in cancer detection
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- foundation models, cancer imaging biomarkers, self-supervised learning, convolutional encoder, radiographic lesions, limited labeled data, transfer learning, biomarker discovery, radiology
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-07, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-07 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
