

The DOI matches its Crossref record; 101 of the 104 references it cites were found in a registry or an index; none of the 27 sources its claims cite is checked for support yet.
The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation
Open accessAbstract
Background: To evaluate binary classifications and their confusion matrices, scientific researchers can employ several statistical rates, accordingly to the goal of the experiment they are investigating. Despite being a crucial issue in machine learning, no widespread consensus has been reached on a unified elective chosen measure yet. Accuracy and F 1 score computed on confusion matrices have been (and still are) among the most popular adopted metrics in binary classification tasks. However, these statistical measures can dangerously show overoptimistic inflated results, especially on imbalanced datasets. Results: The Matthews correlation coefficient (MCC), instead, is a more reliable statistical rate which produces a high score only if the prediction obtained good results in all of the four confusion matrix categories (true positives, false negatives, true negatives, and false positives), proportionally both to the size of positive elements and the size of negative elements in the dataset. Conclusions: In this article, we show how MCC produces a more informative and truthful score in evaluating binary classifications than accuracy and F 1 score, by first explaining the mathematical properties, and then the asset of MCC in six synthetic use cases and in a real genomics scenario. We believe that the Matthews correlation coefficient should be preferred to accuracy and F 1 score in evaluating binary classification tasks by all scientific communities.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
The paper argues that the Matthews correlation coefficient (MCC) is a more reliable metric than accuracy and F1 score for evaluating binary classifications, especially on imbalanced datasets, because MCC requires good performance on both positive and negative classes. It supports this through mathematical analysis, six synthetic use cases, and a real colon cancer gene expression experiment.
Key findings
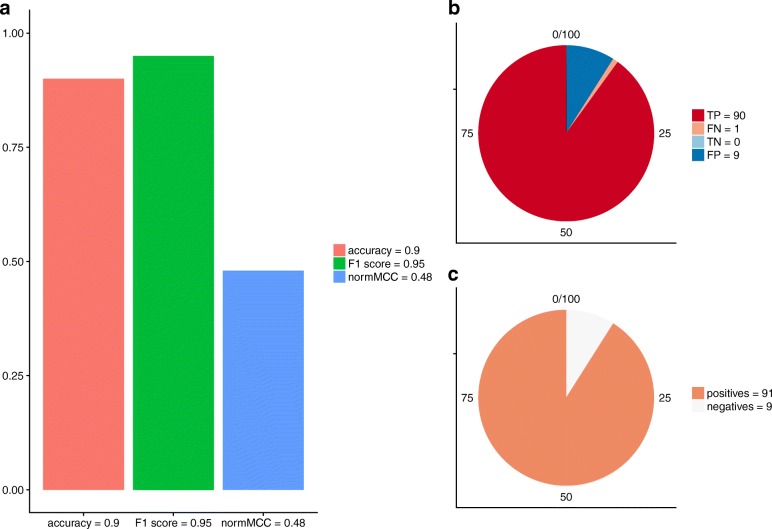
- In six synthetic use cases, MCC was the only metric that correctly indicated the prediction problem in all six. For Use case A1 (91 positives, 9 negatives; TP=90, FN=1, TN=0, FP=9), accuracy=0.90 and F1=0.95, but MCC=−0.03. For Use case C2 (11 positives, 89 negatives; TP=2, FN=9, TN=88, FP=1), accuracy=0.90, F1=0.29, and MCC=+0.31.
- Correlation analysis over all possible confusion matrices showed MCC and accuracy were strongly correlated, while F1 correlated less than 0.8 with the other two measures. For N=1000, PCC(MCC,F1)=0.775982, PCC(MCC,accuracy)=0.921030, and PCC(accuracy,F1)=0.778652.
- In the colon cancer gene expression dataset (2,000 gene probesets, 62 patients: 22 healthy controls and 40 colon cancer; 35.48% negatives, 64.52% positives), rankings differed by metric. MCC ranked gradient boosting top (MCC=+0.55, TP rate=0.85, TN rate=0.69), while F1 and accuracy ranked k-NN top (F1=0.87, accuracy=0.80, TP rate=0.92, TN rate=0.52). Radial SVM had F1=0.75 and accuracy=0.67 but TN rate=0.40 and MCC=+0.29.
- MCC produces a high score only if the classifier correctly predicts the majority of positive and negative instances; F1 is independent of true negatives and is not symmetric for class swapping, while accuracy can be overoptimistic on imbalanced datasets.
Methods
- The paper defines accuracy, MCC, and F1 score mathematically, explores their relationships using Pearson correlation coefficient over all possible confusion matrices for N≥10 up to 1000, and plots all 21,084,251 possible confusion matrices for a 500-sample dataset on the MCC/F1 plane.
- Six synthetic use cases vary class balance and imbalance with specified confusion matrices to compare metric behavior.
- The real genomics experiment uses colon cancer gene expression data from Alon et al. via the plsgenomics R package, applying gradient boosting, decision tree, k-nearest neighbors, linear SVM, and radial SVM. Training/test splits were 80/20 or 60/20/20 with validation for hyperparameter grid search; experiments were repeated ten times and averaged for MCC, F1, accuracy, TP rate, and TN rate.
Limitations
- The paper states that additional comparisons with other rates such as Cohen’s Kappa, Cramér’s V, and K measure would have provided further information, but the authors focused on accuracy and F1 because they are more commonly used in biomedical machine learning studies.
- The paper notes that MCC can be undefined when a whole row or column of the confusion matrix is zero, and handles these cases via an approximation using an arbitrarily small value ε; it also cites situations where MCC can display large fluctuations due to imbalanced outcomes.
- Evident from the text: the real-world validation uses a single colon cancer gene expression dataset, the six use cases are synthetic, and Table 5 excludes standard deviations to keep the table simple.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
29 Own interpretation · 28 Own result · 15 Not checked yet · 13 No basis given
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“A potential problem with MCC lies in the fact that MCC is undefined when a whole row or column of M is zero, as it happens in the previously cited case of the trivial majority classifier.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Notation and mathematical foundations
plainn = 4- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Second, F1 score is independent from the number of samples correctly classified as negative.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“she/he would notice good results (F1 score = 0.75 and accuracy = 0.67)”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the Use case A1 (negatively imbalanced dataset), the machine learning classifier was unable to correctly predict negative data instances, and it therefore produced confusion matrices featuring few true negatives (TN).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“First, the top classifier changes when we consider the ranking based on MCC, F1 score, or accuracy.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“MCC = +0.31 in the [–1, +1] interval”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In the Use case B1 (balanced dataset), the machine learning method was unable to correctly predict negative data instances, and therefore produced a confusion matrix featuring few true negatives (TN).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Finally, in the last Use case C2 (positively imbalanced dataset), the prediction technique failed in predicting negative elements, and therefore its confusion matrix showed a low percentage of true negatives.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“F1 score = 0.29 in the [0, 1] interval”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“the radial SVM has performed poorly on the true negatives (TN rate = 0.40), by correctly predicting less than half patients.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 15
- The quote only partly states this claim. 5
- It may state two separate claims as one. 36
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Here, accuracy showed a high value: 0.90 in the [0, 1] interval.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In this case, all three statistical rates showed a low score which emphasized the deficiency in the prediction process (accuracy = 0.24, F1 score = 0.12, and MCC = −0.24).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“It ranges in the interval [−1,+1], with extreme values –1 and +1 reached in case of perfect misclassification and perfect classification, respectively, while MCC=0 is the expected value for the coin tossing classifier.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Notation and mathematical foundations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“F1 ranges in [0,1], where the minimum is reached for TP=0, that is, when all the positive samples are misclassified, and the maximum for FN=FP=0, that is for perfect classification.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Notation and mathematical foundations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Like for the Use case A2, accuracy, F1 and MCC show average or low result scores (accuracy = 0.56, F1 score = 0.31, and MCC = +0.17), correctly informing you about the non-optimal performance of the prediction method (Additional file 3a).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“If M has only one non-zero entry, this means that all samples in the dataset belong to one class, and they are either all correctly (for TP≠0 or TN≠0) or incorrectly (for FP≠0 or FN≠0) classified. In this situations, MCC=1 for the former case and MCC=−1 for the latter case.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Notation and mathematical foundations
plaindirectSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“If the dataset is highly unbalanced, ni≈1, and thus the accuracy measure gives an unreliable estimation of the goodness of the classifier.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Notation and mathematical foundations
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Checking only F1, one would read a good value (0.66 in the [0, 1] interval), and would be overall satisfied about the prediction (Additional file 2a).”
- Also stated in: § Use cases · hedged
“The Matthews correlation coefficient, instead, by showing a score close to random guessing (+0.07 in the [–1, +1] interval) would be able to inform that the machine learning method has been on the wrong track. Also, it is worth noticing that accuracy would provide with an informative result in this case (0.52 in the [0, 1] interval).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one. The quote only partly states this claim.
- Also stated in: § Use cases · hedged
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, accuracy and of F1 showed high values in this case: accuracy = 0.90 and F1 score = 0.95, both close to the best possible value 1.00 in the [0, 1] interval (Fig. 2a).”
- Also stated in: § Use cases · hedged
“Instead, if one decided to take advantage of the Matthews correlation coefficient in the Use case A1, he/she would notice the resulting MCC = –0.03 (Fig. 2a).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plainSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one. The quote only partly states this claim.
- Also stated in: § Use cases · hedged
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Similar to the Use case A2 and B2, all three statistical scores generated low results that reflect the mediocre quality of the prediction: F1 score = 0.17 and accuracy = 0.10 in the [0, 1] interval, and MCC = −0.19 in the [–1, +1] interval (Additional file 4a).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plainSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“On the other hand, for a given value MCC=μ, the F1 score can range in [0,μ+1] if μ≤0 and in [μ,1] if μ>0, so that the width of the range is 1−|μ|, that is, it depends on the MCC value μ.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The two measures are reasonably concordant, but the scatterplot cloud is wide, implying that for each value of F1 score there is a corresponding range of values of MCC and vice versa, although with different width.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Overall, accuracy, F1, and MCC show reliable concordant scores for predictions that correctly classify both positives and negatives (having therefore many TP and TN), and for predictions that incorrectly classify both positives and negatives (having therefore few TP and TN); however, these measures show discordant behaviors when the prediction performs well just with one of the two binary classes.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“First, F1 varies for class swapping, while MCC is invariant if the positive class is renamed negative and vice versa.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Interestingly, the correlation grows with N, but the increments are limited.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“With these positions MCC is now defined for all confusion matrices M. As a consequences, MCC=0 for the trivial majority classifier, and 0 is also the expected value for the coin tossing classifier.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Notation and mathematical foundations
plainn = 4- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“MCC and accuracy resulted strongly correlated, while the Pearson coefficient is less than 0.8 for the correlation of F1 with the other two measures (Table 3).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In fact, for any value F1=ϕ, the MCC varies approximately between [ϕ−1,ϕ], so that the width of the variability range is 1, independent from the value of ϕ.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“The micro/macro averaged F1 is invariant for class swapping and its behaviour is more similar to MCC.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Here, accuracy showed a high value: 0.90 in the [0, 1] interval.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“linear SVM is ranked forth in the MCC ranking and in the accuracy ranking, but ranked second in the F1 score ranking.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“k-NN, that is the top performing method both in the F1 score ranking and in the accuracy ranking, instead, obtained an excellent score for recall (TP rate = 0.92) but just sufficient on the specificity (TN rate = 0.52).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“However, ROC AUC presents several flaws [92], and it is sensitive to class imbalance [93].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [92] Lobo JM, Jiménez-Valverde A, Real R. AUC: a misleading measure of the performance of predictive distribution models. Glob Ecol Biogeogr. 2008; 17(2):145–51. source
- Not checked yetcites [93] Hanczar B, Hua J, Sima C, Weinstein J, Bittner M, Dougherty ER. Small-sample precision of ROC-related estimates. Bioinformatics. 2010; 26(6):822–30. source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Once again, this score would hide the truth: the classification algorithm has performed poorly on the negative subset.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one. The quote only partly states this claim.
None of the sources cited for this claim have been checked yet.
In the paper
“The effectiveness of MCC has been shown in other scientific fields as well [43, 44].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [43] Liu Y, Cheng J, Yan C, Wu X, Chen F. Research on the Matthews correlation coefficients metrics of personalized recommendation algorithm evaluation. Int J Hybrid Informa Technol. 2015; 8(1):163–72. source
- Not checked yetcites [44] Naulaerts S, Dang CC, Ballester PJ. Precision and recall oncology: combining multiple gene mutations for improved identification of drug-sensitive tumours. Oncotarget. 2017; 8(57):97025. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Even if less common than the ROC curve, several scientists consider the PR curve more informative than the ROC curve, especially on imbalanced biological and medical datasets [48, 97, 98].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [48] Saito T, Rehmsmeier M. The precision-recall plot is more informative than the ROC plot when evaluating binary classifiers on imbalanced datasets. PLoS ONE. 2015; 10(3):0118432. source
- Not checked yetcites [97] Chicco D. Ten quick tips for machine learning in computational biology. BioData Min. 2017; 10(35):1–17.
- Not checked yetcites [98] Ozenne B, Subtil F, Maucort-Boulch D. The precision–recall curve overcame the optimism of the receiver operating characteristic curve in rare diseases. J Clin Epidemiol. 2015; 68(8):855–9. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“MCC was re-proposed by Baldi and colleagues [39] in 2000 as a standard performance metric for machine learning with a natural extension to the multiclass case [40].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [39] Baldi P, Brunak S, Chauvin Y, Andersen CA, Nielsen H. Assessing the accuracy of prediction algorithms for classification: an overview. Bioinformatics. 2000; 16(5):412–24. source
- Not checked yetcites [40] Gorodkin J. Comparing two K-category assignments by a K-category correlation coefficient. Comput Biol Chem. 2004; 28(5–6):367–74. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“For example, when Whalen and colleagues released TargetFinder, a tool to predict enhancer-promoters interactions in genomics, they showed its results measured only by F1 score [13], making it impossible to detect the actual true positive rate and true negative rate of their tests [69].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [13] Whalen S, Truty RM, Pollard KS. Enhancer–promoter interactions are encoded by complex genomic signatures on looping chromatin. Nat Genet. 2016; 48(5):488. source
- Not checked yetcites [69] Xi W, Beer MA. Local epigenomic state cannot discriminate interacting and non-interacting enhancer–promoter pairs with high accuracy. PLoS Comput Biol. 2018; 14(12):1006625. source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“Although being widely acknowledged as a reliable metric, there are situations - albeit extreme - where either MCC cannot be defined or it displays large fluctuations [45], due to imbalanced outcomes in the classification.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [45] Brown JB. Classifiers and their metrics quantified. Mol Inform. 2018; 37:1700127. source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“An effective solution overcoming the class imbalance issue comes from the Matthews correlation coefficient (MCC), a special case of the ϕ phi coefficient [36].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [36] Guilford JP. Psychometric Methods. New York City: McGraw-Hill; 1954.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“for instance, the Food and Drug Administration (FDA) agency of the USA employed the MCC as the main evaluation measure in the MicroArray II / Sequencing Quality Control (MAQC/SEQC) projects [41, 42].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [41] The MicroArray Quality Control (MAQC) Consortium. The MAQC-II Project: a comprehensive study of common practices for the development and validation of microarray-based predictive models. Nat Biotechnol. 2010; 28(8):827–38. source
- Not checked yetcites [42] The SEQC/MAQC-III Consortium. A comprehensive assessment of RNA-seq accuracy, reproducibility and information content by the Sequence Quality Control consortium. Nat Biotechnol. 2014; 32:903–14. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“However, this procedure is biased [65], and it is still far from being accepted as a standard practice by the community.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [65] Van Asch V. Macro-and micro-averaged evaluation measures. Technical report. 2013:1–27.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In this case, the algorithm showed its ability to predict the positive data instances (90 sick patients out of 91 were correctly predicted), but it also displayed its lack of talent in identifying healthy controls (only 1 healthy individual out of 9 was correctly recognized) (Fig. 2b). Therefore, the overall performance should be judged poor.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plaindirectSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Similar to the Use case A1 and B1, the method was able to correctly identify multiple negative data instances (88 healthy patients out of 89), but unable to correctly predict most of sick patients (only 2 true positives out of 11 possible elements).”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plainn = 88- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Originally developed by Matthews in 1975 for comparison of chemical structures [38]”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [38] Matthews BW. Comparison of the predicted and observed secondary structure of T4 phage lysozyme. Biochim Biophys Acta (BBA) Protein Struct. 1975; 405(2):442–51. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Despite its popularity, in the learning context there are a number of issues causing the kappa measure to produce unreliable results (for instance, its high sensitivity to the distribution of the marginal totals [73–75])”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Background
What the sources say
- Not checked yetcites [73] Flight L, Julious SA. The disagreeable behaviour of the kappa statistic. Pharm Stat. 2015; 14:74–8. source
- Not checked yetcites [74] Powers DMW. The problem with Kappa. In: Proceedings of EACL 2012 – the 13th Conference of the European Chapter of the Association for Computational Linguistics. Avignon: ACL: 2012. p. 345–55.
- Not checked yetcites [75] Delgado R, Tibau X-A. Why Cohen’s Kappa should be avoided as performance measure in classification. PloS ONE. 2019; 14(9):0222916.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In fact, when a prediction displays many true positives but few true negatives (or many true negatives but few true positives) we will show that F1 and accuracy can provide misleading information, while MCC always generates results that reflect the overall prediction issues.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These results show that, while accuracy and F1 score often generate high scores that do not inform the user about ongoing prediction issues, the MCC is a robust, useful, reliable, truthful statistical measure able to correctly reflect the deficiency of any prediction in any dataset.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
boosteddirectn = 6- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one. The quote only partly states this claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Here accuracy again generated overoptimistic, misleading, and inflated high results”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plaindirectSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The F1 score ranking and the accuracy ranking, in conclusion, are hiding this important flaw of the top classifier: k-NN was unable top correctly predict a high percentage of patients.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“There, accuracy and F1 generated overoptimistic and inflated results”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Accuracy and F1 score, although popular, can generate misleading results on imbalanced datasets, because they fail to consider the ratio between positive and negative elements.”
- Also stated in: § Conclusions · plain
“F1 and accuracy, instead, generate reliable results only when applied to balanced datasets, and produce misleading results when applied to imbalanced cases.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Conclusions
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Conclusions · plain
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“With its low value (MCC = +0.29), the MCC informs the readers about the poor general outcome of the radial SVM, while the accuracy and F1 score show misleading values.”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“The dataset contains 2,000 gene probsets for 62 patients, of which 22 are healthy controls and 40 have colon cancer (35.48% negatives and 64.52% positives) [106].”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
What the sources say
- Not checked yetcites [106] Alon U, Barkai N, Notterman DA, Gish K, Ybarra S, Mack D, Levine AJ. Data pertaining to the article ‘Broad patterns of gene expression revealed by clustering of tumor and normal colon tissues probed by oligonucleotide arrays’. 2000. http://genomics-pubs.princeton.edu/oncology/affydata/index.html. Accessed 10 Dec 2019.
plainn = 62- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper relies on this without support.
Accuracy and F1 score are the most common metrics used for binary classification in machine learning.
“We decided to focus on accuracy and F1 score because they are the most common metrics used for binary classification in machine learning.”
The paper relies on this without support.
The synthetic use cases are realistic representations of binary classification scenarios.
“here we describe some synthetic, realistic scenarios where MCC results are more informative and truthful than the other two measures analyzed.”
The paper relies on this without support.
Accuracy and F1 score are more commonly used in machine learning studies related to biomedical applications than other rates.
“because accuracy and F1 score are more commonly used in machine learning studies related to biomedical applications.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“MCC is a more reliable metric, whereby a high score is assigned only if the prediction was correct for the four base categories (TP, FP, TN and FP), taking into account the size of P and N [85].”
From A Survey of Underwater Acoustic Data Classification Methods Using Deep Learning for Shoreline Surveillance (2022) · cites this paper as [85]
In the citing paper
“since it has been shown to present a balanced score when dealing with imbalanced data [11, 6] as is our case with fewer manipulated images.”
From BioFors: A Large Biomedical Image Forensics Dataset (2021) · cites this paper as [11]
In the citing paper
“(3) the absolute value of F1 changes by simply switching the outcome labels (ie, when 1 becomes 0 and 0 becomes 1).”
From Evaluation of performance measures in predictive artificial intelligence models to support medical decisions: overview and guidance (2025) · cites this paper as [77]
In the citing paper
“(2) F1 has no intuitive interpretation”
From Evaluation of performance measures in predictive artificial intelligence models to support medical decisions: overview and guidance (2025) · cites this paper as [77]
In the citing paper
“(1) F1 ignores true negatives”
From Evaluation of performance measures in predictive artificial intelligence models to support medical decisions: overview and guidance (2025) · cites this paper as [77]
In the citing paper
“F1 and MCC were introduced to address the challenges caused by class imbalance, where classification accuracy can be inflated by classifying all patients as low risk when the event is rare.”
From Evaluation of performance measures in predictive artificial intelligence models to support medical decisions: overview and guidance (2025) · cites this paper as [77]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“Here, accuracy again generated an overoptimistic inflated score”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“all three statistical scores generated low results that reflect the mediocre quality of the prediction: F1 score = 0.17 and accuracy = 0.10 in the [0, 1] interval”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“the prediction technique failed in predicting negative elements, and therefore its confusion matrix showed a low percentage of true negatives”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“the method was able to correctly identify multiple negative data instances (88 healthy patients out of 89), but unable to correctly predict most of sick patients (only 2 true positives out of 11 possible elements)”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“Even if accuracy showed an excessively high result score”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“all three statistical rates showed a low score which emphasized the deficiency in the prediction process (accuracy = 0.24, F1 score = 0.12, and MCC = −0.24)”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
“the best classifier resulted being k-NN (F1 score = 0.87 and accuracy = 0.81)”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Genomics scenario: colon cancer gene expression
“k-nearest neighbors | +0.48 | 0.87 | 0.80 | 0.92 | 0.52”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“only 1 healthy individual out of 9 was correctly recognized”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“TP=90, FN=1, TN=0, FP=9”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“Finally, in the last Use case C2 (positively imbalanced dataset)”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“Use case C2 Negatively imbalanced dataset | 11 | 89 | 2 | 9 | 88 | 1”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“For the Use case A1 (negatively imbalanced dataset)”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“made of 9 healthy individuals (negatives =9%) and 91 sick patients (positives =91%)”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“Also in the Use case C1 (positively imbalanced dataset)”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“90 healthy controls (negatives =90%) and 10 sick patients (positives =10%)”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“only 5 sick patients out of 70”
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“TP = 5, FN = 70, TN = 19, FP = 6”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Results and discussion > Use cases
“the resulting MCC = –0.03”
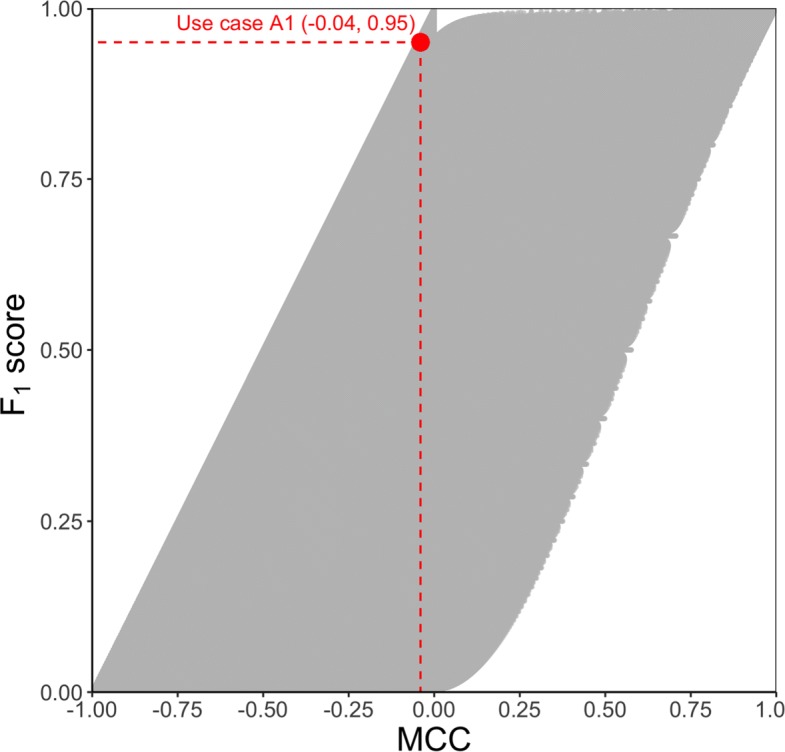
§ The advantages of the Matthews correlation coefficient (MCC) over F1 score and accuracy in binary classification evaluation > Methods > Relationship between measures
“In red, the (−0.04, 0.95) point corresponding to use case A1”
Citations
Cites
Breiman, L. (2001) · Machine Learning · doi:10.1023/a:1010933404324 · Cited by 133,538
LeCun, Y., Bengio, Y., & Hinton, G. (2015) · Nature · doi:10.1038/nature14539 · Cited by 84,126
The Measurement of Observer Agreement for Categorical Data
Landis, J. R., & Koch, G. G. (1977) · Biometrics · doi:10.2307/2529310 · Cited by 81,148
XGBoost: A Scalable Tree Boosting System
Chen, T., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939785 · Cited by 54,569
A Coefficient of Agreement for Nominal Scales
Cohen, J. (1960) · Educational and Psychological Measurement · doi:10.1177/001316446002000104 · Cited by 42,398
An introduction to ROC analysis
Fawcett, T. (2006) · Pattern Recognition Letters · doi:10.1016/j.patrec.2005.10.010 · Cited by 21,879
The meaning and use of the area under a receiver operating characteristic (ROC) curve.
Hanley, J. A., & McNeil, B. J. (1982) · Radiology · doi:10.1148/radiology.143.1.7063747 · Cited by 21,856
Interrater reliability: The kappa statistic
McHugh, M. L. (2012) · Biochemia Medica · doi:10.11613/bm.2012.031 · Cited by 19,877
Measures of the Amount of Ecologic Association Between Species
Dice, L. R. (1945) · Ecology · doi:10.2307/1932409 · Cited by 12,187
Statistical Comparisons of Classifiers over Multiple Data Sets
Demšar, J. (2006) · doi:10.5555/1248547.1248548 · Cited by 12,051
Research works printed but not linked: 7
- Akosa JS. Predictive accuracy: a misleading performance measure for highly imbalanced data. In: Proceedings of the SAS Global Forum 2017 Conference. Cary, North Carolina: SAS Institute Inc.: 2017. p. 942–2017.
- Guilford JP. Psychometric Methods. New York City: McGraw-Hill; 1954.
- van Rijsbergen CJ, Joost C. Information Retrieval. New York City: Butterworths; 1979.
- Sasaki Y. The truth of the F-measure. Teach Tutor Mater. 2007; 1(5):1–5.
- Dubey A, Tarar S. Evaluation of approximate rank-order clustering using Matthews correlation coefficient. Int J Eng Adv Technol. 2018; 8(2):106–13.
- Suresh Babu N. Various performance measures in binary classification – An overview of ROC study. Int J Innov Sci Eng Technol. 2015; 2(9):596–605.
- Ferri C, Hernández-Orallo J, Flach PA. A coherent interpretation of AUC as a measure of aggregated classification performance. In: Proceedings of ICML 2011 – the 28th International Conference on Machine Learning. Norristown: Omnipress: 2011. p. 657–64.
Cited by
Sorted by citations
Items 801–900 of 1,016
Public Health Discussions on Social Media: Evaluating Automated Sentiment Analysis Methods
Gandy, L. M., Ivanitskaya, L. V., Bacon, L., & Bizri-Baryak, R. (2024) · JMIR Formative Research · doi:10.2196/57395 · Cited by 26
“Finally, MCC was calculated by measuring the sensitivity, specificity, precision, and negative predictive value to evaluate the model performance [36].”
InfluentialUmaa Mahesswari, G., & Uma Maheswari, P. (2024) · Heliyon · doi:10.1016/j.heliyon.2024.e39205 · Cited by 29
“The performance metrics in Equations (5) – (9) serve as a representation of these In addition, the Matthew ’ s correlation coefficient (MCC) was employed in the assessment of classifier performance [52].”
MethodLin, C., Wu, J., Li, C., Chen, P.-Y., Pai, N., & Kuo, Y. (2020) · IEEE photonics journal · doi:10.1109/jphot.2020.3013193 · Cited by 26
“The K-fold cross- validation is used to verify the performance of the proposed multilayer machine vision classifier with recall (%), precision (%), accuracy (%), and F1 score [31].”
MethodIdentification of early liver toxicity gene biomarkers using comparative supervised machine learning
Smith, B. P., Auvil, L. S., Welge, M. E., Bushell, C., Bhargava, R., Elango, N., Johnson, K. J., & Madak‐Erdogan, Z. (2020) · Scientific Reports · doi:10.1038/s41598-020-76129-8 · Cited by 32
Tschaikowsky, M., Selig, M., Brander, S., et al. (2020) · Osteoarthritis and Cartilage · doi:10.1016/j.joca.2020.10.003 · Cited by 26
Optimal feature configuration for dynamic malware detection
García, D. E., & DeCastro‐García, N. (2021) · Computers & Security · doi:10.1016/j.cose.2021.102250 · Cited by 32
Naseer, S., Ali, R. F., Muneer, A., & Fati, S. M. (2021) · Symmetry · doi:10.3390/sym13040560 · Cited by 26
Mamandipoor, B., Frutos–Vivar, F., Peñuelas, Ó., Rezar, R., Raymondos, K., Muriel, A., Du, B., Thille, A. W., Ríos, F., Gonzalez, M. A., et al. (2021) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-021-01506-w · Cited by 28
“We use Mathews correlation coefficient (MCC) [17] to compare quality of binary classifications between the different algorithms [18].”
MethodKara, A. C., & Hardalaç, F. (2021) · Machine Learning and Knowledge Extraction · doi:10.3390/make3040050 · Cited by 28
“An MCC is an effective method when the number of dataset elements is disproportionate—that is, the number of instances in one class is much greater than the number of instances in other classes [54].”
MethodA new detection model of microaneurysms based on improved FC-DenseNet
Wang, Z., Li, X., Yao, M., et al. (2022) · Scientific Reports · doi:10.1038/s41598-021-04750-2 · Cited by 26
Sekajugo, J., Kagoro‐Rugunda, G., Mutyebere, R., Kabaseke, C., Namara, E., Dewitte, O., Kervyn, M., & Jacobs, L. (2022) · Environmental Research Letters · doi:10.1088/1748-9326/ac5bb5 · Cited by 26
“Sensitivity (also called true positive rate or recall rate) is used to refer to the proportion of existing positives that are correctly identified or detected as positives (Powers 2008, Tharwat 2018, Chicco and Jurman 2020).”
BackgroundMethodDMCS : Density Modularity based Community Search
Kim, J., Luo, S., Cong, G., & Yu, W. (2022) · ACM SIGMOD International Conference on Management of Data (SIGMOD) · doi:10.1145/3514221.3526137 · Cited by 28
“Note that for the binary classification tasks (the community search can be considered as binary classification task), Fscore measure returns overoptimistic inflated results [14] since it cannot capture the ratio between positive and negative elements.”
BackgroundTama, B. A., Vania, M., Kim, I., & Lim, S. (2022) · IEEE Access · doi:10.1109/access.2022.3160179 · Cited by 28
“5 × ( FP + FN ) (6) Furthermore, Kappa and MCC [40] are considered to measure performance.”
BackgroundDeep learning-based classification of DSA image sequences of patients with acute ischemic stroke
Mittmann, B. J., Braun, M., Runck, F., Schmitz, B., Tran, T. N., Yamlahi, A., Maier‐Hein, L., & Franz, A. M. (2022) · International Journal of Computer Assisted Radiology and Surgery · doi:10.1007/s11548-022-02654-8 · Cited by 27
“Unlike the accuracy or F1-score, the Matthews correlation coefficient (MCC) [5] does not tend to overestimate the classification performance especially for an unbalanced binary class distribution, as it was the case for our DSA data set (72% positives | 28% negatives).”
Decoding Task-Based fMRI Data with Graph Neural Networks, Considering Individual Differences
Saeidi, M., Karwowski, W., Farahani, F. V., Fiok, K., Hancock, P. A., Sawyer, B. D., Christov‐Moore, L., & Douglas, P. K. (2022) · Brain Sciences · doi:10.3390/brainsci12081094 · Cited by 32
“F1 macro and MCC have been widely considered as metrics to evaluate imbalanced datasets in which all classes are weighted equally [79,80].”
BackgroundRasmussen, I., Kvalsvik, S., Andersen, P., Aune, T. N., & Hagen, D. (2022) · Applied Sciences · doi:10.3390/app12178534 · Cited by 36
Rauf, Z., Sohail, A., Khan, S. H., Khan, A., Gwak, J., & Maqbool, M. (2022) · Microscopy · doi:10.1093/jmicro/dfac051 · Cited by 30
Guo, Y., Xia, H., Zhao, X., et al. (2022) · IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing · doi:10.1109/jstars.2022.3215589 · Cited by 26
“Theearliestidentifiabledatesofthe wintercropsaredefinedastheMatthewscorrelationcoefficient (MCC),givenasfollows,whichisconsideredmorestablethan theKappacoefficientandF1score,reachingalocalmaximum [52]: 3”
Ruiz, Á. Y., Cavagnaro, M., & Crocco, L. (2023) · Sensors · doi:10.3390/s23020643 · Cited by 26
“The double contribution of the TP to the DSC worsens the estimation further [34].”
BackgroundIn Silico Screening and Optimization of Cell-Penetrating Peptides Using Deep Learning Methods
Park, H., Park, J., Kim, M. S., et al. (2023) · Biomolecules · doi:10.3390/biom13030522 · Cited by 26
Demirhan, D. B., Yılmaz, H., Erol, H., Kayılı, H. M., & Salih, B. (2023) · The Analyst · doi:10.1039/d2an02057b · Cited by 27
TC-Net: A Modest & Lightweight Emotion Recognition System Using Temporal Convolution Network
Ishaq, M., Khan, M., & Kwon, S. (2023) · Computer Systems Science and Engineering · doi:10.32604/csse.2023.037373 · Cited by 26
Vock, I. W., & Simon, M. D. (2023) · RNA · doi:10.1261/rna.079451.122 · Cited by 26
“The MCC is more informative than other popular binary classification metrics (e.g., F1 score and model accuracy) as it accounts for the relative abundances of all four categories of classifications (i.e., false positives, false negatives, true positives, and true negatives) (Chicco and Jurman 2020).”
BackgroundAhmad, I., Wan, Z., & Ahmad, A. (2023) · Internet of Things · doi:10.1016/j.iot.2023.100825 · Cited by 26
Azhdari, S. M. H., Mahmoodzadeh, A., Khishe, M., et al. (2023) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2023.106415 · Cited by 26
Dehghan, A., Rayatinejad, A., Khezri, R., Aune, D., & Rezaei, F. (2023) · BMC Medical Research Methodology · doi:10.1186/s12874-023-01961-1 · Cited by 28
“While MCC = 0 means the classifier performance is no better than random classification [28].”
BackgroundAhluwalia, M., Abdalla, M., Sanayei, J., Seyyed-Kalantari, L., Hussain, M., Ali, A., & Fine, B. (2023) · Radiology: Artificial Intelligence · doi:10.1148/ryai.220270 · Cited by 26
Predicting the formation of NADES using a transformer-based model
Ayres, L. B., Gómez, F. J. V., Silva, M. F., Linton, J. R., & García, C. D. (2024) · Scientific Reports · doi:10.1038/s41598-022-27106-w · Cited by 27
“A detailed explanation of the advantages of using MCC over traditional metrics for machine learning such as F1-score and accuracy can be found elsewhere 70 .”
MethodHuman gesture recognition under degraded environments using 3D-integral imaging and deep learning
Krishnan, G. S., Joshi, R. C., O’Connor, T., Pla, F., & Javidi, B. (2020) · Optics Express · doi:10.1364/oe.396339 · Cited by 27
Choubineh, A., Wood, D. A., & Choubineh, Z. (2020) · International Journal of Critical Infrastructure Protection · doi:10.1016/j.ijcip.2020.100357 · Cited by 26
Benjamin, A. J., Young, A. J., Holcomb, J. B., Fox, E. E., Wade, C. E., Meador, C., & Cannon, J. W. (2023) · Annals of Surgery Open · doi:10.1097/as9.0000000000000314 · Cited by 26
“23 The calibration of the final model was assessed by plotting the predicted probabilities derived from the model versus the actual probabilities.”
Banik, A., & Singh, J. P. (2023) · IEEE Access · doi:10.1109/access.2023.3323845 · Cited by 25
“…tool that measures the difference between the predicted values and actual values and can be calculated as shown in equation (7) - MCC value can range from + 1 to − 1, where + 1 implies perfect prediction, and − 1 indicates predicted values are completely different from the actual values [33].”
BackgroundRam, B. G., Zhang, Y., da Costa, C. A., et al. (2023) · Computers and Electronics in Agriculture · doi:10.1016/j.compag.2023.108444 · Cited by 25
“MCC has been studied to be a more robust evaluation metric for binary classifiers (Chicco and Jurman, 2020).”
BackgroundReal-time pollen identification using holographic imaging and fluorescence measurements
Erb, S., Graf, E., Zeder, Y., Lionetti, S., Berne, A., Clot, B., Lieberherr, G.-D., Tummon, F., Wullschleger, P., & Crouzy, B. (2024) · Atmospheric measurement techniques · doi:10.5194/amt-17-441-2024 · Cited by 28
Underwater fish detection and counting using image segmentation
Zhang, L., Qiu, Y., Fan, J., Li, S., Hu, Q., Xing, B., & Xu, J. (2024) · Aquaculture International · doi:10.1007/s10499-024-01402-w · Cited by 25
“To evaluate the performance of the proposed BoTS-YOLOv5s-seg model, formula (1)–(5) illustrate the commonly used indices, including precision, recall (Powers 2020), F1-score (Chicco and Jurman 2020), accuracy precision (AP) (Revaud et al. 2019), and mean average precision (mAP).”
Wang, T., Xu, L., Lan, T., et al. (2024) · Spectrochimica Acta Part A Molecular and Biomolecular Spectroscopy · doi:10.1016/j.saa.2024.123976 · Cited by 25
Alhussaini, A. J., Steele, J. D., Jawli, A., & Nabi, G. (2024) · Cancers · doi:10.3390/cancers16081454 · Cited by 26
“The AUC-ROC curve is a popular evaluation metric used when a single threshold of the confusion matrix is unavailable [56].”
MethodŞenkaya, M., Silahtar, A., Erkan, E. F., & Karaaslan, H. (2024) · Engineering Geology · doi:10.1016/j.enggeo.2024.107605 · Cited by 26
Ahmad, M. N., Shao, Z., Xiao, X., Fu, P., Javed, A., & Ara, I. (2024) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2024.104013 · Cited by 32
Twelve practical recommendations for developing and applying clinical predictive models
Feng, G., Xu, H., Wan, S., Wang, H., Chen, X., Magari, R. T., Han, Y. K., Wei, Y., & Gu, H. (2024) · The Innovation Medicine · doi:10.59717/j.xinn-med.2024.100105 · Cited by 27
VisEvol: Visual Analytics to Support Hyperparameter Search through Evolutionary Optimization
Chatzimparmpas, A., Martins, R. M., Kucher, K., & Kerren, A. (2021) · Computer Graphics Forum · doi:10.1111/cgf.14300 · Cited by 25
“Alternatives, such as Matthews correlation coefficient (MCC), might be more informative for imbalanced classification data [CJ20], but even advanced metrics are not the holy grail, and additional challenges can be found in the literature [LJVR08,Pow11].”
BackgroundRecSNO: Prediction of Protein S-Nitrosylation Sites Using a Recurrent Neural Network
Siraj, A., Chantsalnyam, T., Tayara, H., & Chong, K. T. (2021) · IEEE Access · doi:10.1109/access.2021.3049142 · Cited by 24
Im, H., Hwang, S.-H., Kim, B., & Choi, S.-H. (2021) · Proceedings of the National Academy of Sciences of the United States of America · doi:10.1073/pnas.2018877118 · Cited by 16
“Because our input dataset consisting of 2,292 clinical isolates and 354 environmental isolates was imbalanced, the MCC and AUROC scoring methods were further used to produce a more informative and truthful score (55, 56).”
MethodCasanova-Alvarez, O., Helguera, A. M., Cabrera‐Pérez, M. Á., Molina, R., & Molina, C. G. (2021) · Journal of Chemical Information and Modeling · doi:10.1021/acs.jcim.0c01439 · Cited by 25
Murugesan, K., Sharaf, R., Montesion, M., Moore, J. A., Pao, J. J., Pavlick, D. C., Frampton, G. M., Upadhyay, V. A., Alexander, B. M., Miller, V. A., et al. (2021) · JCO Precision Oncology · doi:10.1200/po.20.00397 · Cited by 27
Zhang, H., Dong, Z., Sun, M., Gu, H., & Wang, Z. (2021) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2021.106358 · Cited by 25
The Global Water Body Layer from TanDEM-X Interferometric SAR Data
Bueso–Bello, J., Martone, M., González, C., Sica, F., Valdo, P., Posovszky, P., Pulella, A., & Rizzoli, P. (2021) · Remote Sensing · doi:10.3390/rs13245069 · Cited by 29
“The MCC is often used to assess the quality of binary classification, since it is generally regarded as a balanced measure of accuracy, even in the presence of classes with very different population sizes [57,58].”
BackgroundMethodRevisiting the Impact of Dependency Network Metrics on Software Defect Prediction
Gong, L., Rajbahadur, G. K., Hassan, A. E., & Jiang, S. (2021) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2021.3131950 · Cited by 25
“…evaluate the effectiveness of Defect-classification models, we use the following performance measures such as: Area Under the Reciever-operator Characteristic Curve (AUC), Matthews correlation coefficient (MCC), Precision, Recall and Brier score similar to several prior studies [13, 23, 72, 90, 105].”
MethodMachine Learning for Outcome Prediction in First-Line Surgery of Prolactinomas
Huber, M., Luedi, M. M., Schubert, G. A., Musahl, C., Tortora, A., Frey, J., Beck, J., Mariani, L., Christ, E., & Andereggen, L. (2022) · Frontiers in Endocrinology · doi:10.3389/fendo.2022.810219 · Cited by 25
“One of the advantages of the MCC is that it is based on the full confusion matrix (i.e. true and false both positives and negatives) (48); another is that it performs well on imbalanced data sets (49).”
BackgroundFoo, K. Y., Newman, K., Fang, Q., Gong, P., Ismail, H. M., Lakhiani, D. D., Zilkens, R., Dessauvagie, B. F., Latham, B. I., Saunders, C. M., et al. (2022) · Biomedical Optics Express · doi:10.1364/boe.455110 · Cited by 25
Tanabe, T. S., & Dahl, C. (2022) · Molecular Ecology Resources · doi:10.1111/1755-0998.13642 · Cited by 26
“For assessment, balanced accuracy (Brodersen et al., 2010), F1-score (Forman & Scholz, 2010), and Matthew- correlation-coefficient (MCC) (Chicco & Jurman, 2020) were calculated.”
BackgroundInfluentialBenedetti, D., Olcese, U., Bruno, S., Barsotti, M., Maestri, M., Bonanni, E., Siciliano, G., & Faraguna, U. (2022) · Nature and Science of Sleep · doi:10.2147/nss.s352335 · Cited by 23
“MCC ranges from −1 (perfect misclassification) to 1 (perfect classification).(45) Confusion matrices were produced through scikit-learn(44) library, while all the other parameters were calculated through a custom script based on NumPy library.”
MethodPeng, X., Wang, X., Guo, Y., Ge, Z., Li, F., Gao, X., & Song, J. (2022) · Briefings in Bioinformatics · doi:10.1093/bib/bbac215 · Cited by 24
Singh, S. K., & Chaturvedi, A. (2022) · Multimedia Tools and Applications · doi:10.1007/s11042-022-14117-y · Cited by 27
Jacob, S. G., Sulaiman, M. M. B. A., & Bennet, B. (2023) · Computational Intelligence and Neuroscience · doi:10.1155/2023/6330002 · Cited by 26
Varied Image Data Augmentation Methods for Building Ensemble
Bravin, R., Nanni, L., Loreggia, A., Brahnam, S., & Paci, M. (2023) · IEEE Access · doi:10.1109/access.2023.3239816 · Cited by 27
“In the literature [10], MCC is proved to be a more reliable statistical indicator than accuracy even for binary classification datasets.”
BackgroundCannon, S. J., Williams, M., Gunning, A. C., & Wright, C. F. (2023) · BMC Medical Genomics · doi:10.1186/s12920-023-01454-6 · Cited by 26
“Standard performance metrics (sensitivity, specificity, positive and negative predictive values) and the Matthews Correlation Coefficient (MCC) [32] were calculated for all tools.”
MethodInfluentialKopál, J., Kumar, K., Saltoun, K., Modenato, C., Moreau, C. A., Martin‐Brevet, S., Huguet, G., Jean‐Louis, M., Martin, C.-O., Saci, Z., et al. (2023) · Nature Human Behaviour · doi:10.1038/s41562-023-01541-9 · Cited by 27
Fake news detection in Urdu language using machine learning
Farooq, M. S., Naseem, A., Rustam, F., et al. (2023) · PeerJ Computer Science · doi:10.7717/peerj-cs.1353 · Cited by 25
Predicting systemic risk in financial systems using Deep Graph Learning
Balmaseda, V., Vaca, M. C., & Santiago, G. D. C. (2023) · Intelligent Systems with Applications · doi:10.1016/j.iswa.2023.200240 · Cited by 26
Murmu, A., & Kumar, P. (2023) · Medical & Biological Engineering & Computing · doi:10.1007/s11517-023-02824-z · Cited by 26
“(21) is F1-Score [52].”
Hulme, A., Stanton, N. A., Walker, G. H., Waterson, P. E., & Salmon, P. M. (2023) · Ergonomics · doi:10.1080/00140139.2023.2240048 · Cited by 25
“…< 20% indicating the acceptable levels of agreement between analyses for HR and FAR, respectively: Whilst HR and FAR are useful for evaluating the accuracy of a single prediction, such rates remain limited as they only account for two of four categories in SDT (Chicco 2017; Chicco and Jurman 2020).”
BackgroundLöhle, M., Timpka, J., Bremer, A., Khodakarami, H., Gandor, F., Horne, M. K., Ebersbach, G., Odin, P., & Storch, A. (2023) · npj Digital Medicine · doi:10.1038/s41746-023-00937-1 · Cited by 25
ForestTrav: 3D LiDAR-Only Forest Traversability Estimation for Autonomous Ground Vehicles
Ruetz, F., Lawrance, N., Hernández, E., et al. (2024) · IEEE Access · doi:10.1109/access.2024.3373004 · Cited by 25
“We evaluate the performance of the proposed method using the Matthews correlation coefficient (MCC) [38].”
BackgroundMethodRevolutionizing Diabetes Diagnosis: Machine Learning Techniques Unleashed
Shaukat, Z., Zafar, W., Ahmad, W., et al. (2023) · Healthcare · doi:10.3390/healthcare11212864 · Cited by 24
“We mentioned some important errors in our research paper, which are shown in the form of tables and graphs The true positive rate (TPR) and the true negative rate (TNR) are performance metrics used in machine learning, especially in the context of binary clas-si fi cation problems [35].”
MethodRibeiro, P., Sá, J., Paiva, D., & Rodrigues, P. M. (2024) · Bioengineering · doi:10.3390/bioengineering11010058 · Cited by 30
“The F 1-Score is the harmonic average between the Recall and the Precision [63], and the equation is defined as The Kappa normalises the Accuracy by the possibility of agreement by chance [64] and is defined as The MCC is useful for uneven data [65].”
Yang, Y.-Y., Ho, M.-Y., Tai, C.-H., Wu, R., Kuo, M., & Tseng, Y. J. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01022-x · Cited by 26
Andersen, K. H., Johra, H., Schaffer, M., Marszal-Pomianowska, A., Knudsen, H. N., Heiselberg, P., & O’Brien, W. (2024) · Building and Environment · doi:10.1016/j.buildenv.2024.111319 · Cited by 26
LIVABLE: Exploring Long-Tailed Classification of Software Vulnerability Types
Wen, X.-C., Gao, C., Luo, F., Wang, H., Li, G., & Liao, Q. (2024) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2024.3382361 · Cited by 28
“Specifically, we compare the performance of LIVABLE with Devign and Reveal in precision, recall, macro F1 score, weighted F1 score and Matthews Correlation Coefficient (MCC) metrics [52], as summarized in Table VII.”
MethodPelletier, S., Leclercq, M., Roux‐Dalvai, F., de Geus, M. B., Leslie, S. N., Wang, W., Lam, T. T., Nairn, A. C., Arnold, S. E., Carlyle, B. C., et al. (2024) · Nature Communications · doi:10.1038/s41467-024-48177-5 · Cited by 24
POxload: Machine Learning Estimates Drug Loadings of Polymeric Micelles
Kehrein, J., Bunker, A., & Luxenhofer, R. (2024) · Molecular Pharmaceutics · doi:10.1021/acs.molpharmaceut.4c00086 · Cited by 27
Zhang, H.-W., Wang, Y., Hu, B., Song, B., Wen, Z.-J., Su, L., Chen, X.-M., Wang, X., Zhou, P., Zhong, X.-M., et al. (2024) · Scientific Reports · doi:10.1038/s41598-024-80210-x · Cited by 24
Anila, M., & Daramola, O. (2024) · Artificial Intelligence Review · doi:10.1007/s10462-024-11003-x · Cited by 38
Pediatric brain tumor classification using deep learning on MR images with age fusion
Tampu, I. E., Bianchessi, T., Blystad, I., Lundberg, P., Nyman, P., Eklund, A., & Haj‐Hosseini, N. (2024) · Neuro-Oncology Advances · doi:10.1093/noajnl/vdae205 · Cited by 28
“Models’ performance was evaluated volume-wise in terms of Matthew’s correlation coefficient (MCC) [–1, 1] 26 since it is a more stable metric in case of class imbalance.”
Improved RT-DETR and its application to fruit ripeness detection
Wu, M., Qiu, Y., Wang, W., et al. (2025) · Frontiers in Plant Science · doi:10.3389/fpls.2025.1423682 · Cited by 24
Multiple Threshold‐Selection Methods Are Needed to Binarise Species Distribution Model Predictions
Hellegers, M., van Hinsberg, A., Lenoir, J., Dengler, J., Huijbregts, M. A. J., & Schipper, A. M. (2025) · Diversity and Distributions · doi:10.1111/ddi.70019 · Cited by 33
“…proportion of falsely predicted presences relative to all predicted presences) and the overprediction of the absences (false omission rate, i.e., the proportion of falsely predicted absences relative to all predicted absences) (Chicco and Jurman 2020; Chicco et al. 2021; Matthews 1975; Yule 1912).”
An analytical approach to credit risk assessment using machine learning models
Machado, M., Chen, D., & Osterrieder, J. R. (2025) · Decision Analytics Journal · doi:10.1016/j.dajour.2025.100605 · Cited by 51
Wafa, A. A., Eldefrawi, M. M., & Farhan, M. S. (2025) · Journal Of Big Data · doi:10.1186/s40537-025-01264-w · Cited by 24
A review of approaches investigated for right ventricular segmentation using short‐axis cardiac MRI
Ammari, A., Mahmoudi, R., Hmida, B., Saouli, R., & Bedoui, M. H. (2021) · IET Image Processing · doi:10.1049/ipr2.12165 · Cited by 25
“Moreover, an effective solution to overcome the problem of class imbalance comes from the Matthews Correlation Coefficient (MCC), which is calculated according to Equation (8) [22].”
MethodDefective Product Classification System for Smart Factory Based on Deep Learning
Nguyen, H. T., Yu, G.-H., Shin, N.-R., Kwon, G.-J., Kwak, W.-Y., & Kim, J. Y. (2021) · Electronics · doi:10.3390/electronics10070826 · Cited by 25
“That is the Matthews correlation coefficient (MCC) [39].”
BackgroundThe rapid decline of an Endangered temperate soft coral species
Larkin, M. F., Davis, T. R., Harasti, D., et al. (2021) · Estuarine Coastal and Shelf Science · doi:10.1016/j.ecss.2021.107364 · Cited by 24
Sykes, A. L., Silva, G. S., Holtkamp, D., Mauch, B. W., Osemeke, O., Linhares, D. C. L., & Machado, G. (2021) · Transboundary and Emerging Diseases · doi:10.1111/tbed.14369 · Cited by 26
Wang, H., Zhao, H. S., Yan, Z., Zhao, J., & Han, J. (2021) · Biomolecules · doi:10.3390/biom11060872 · Cited by 24
“However, MCC and AUPR are usually sensitive to the imbalance of datasets [42,44].”
BackgroundMethodGIS derived synthetic rating curves and HAND model to support on-the-fly flood mapping
Scriven, B. W. G., McGrath, H., & Stefanakis, E. (2021) · Natural Hazards · doi:10.1007/s11069-021-04892-6 · Cited by 24
Deep Learning Model to Detect Diabetes Mellitus Based on DNA Sequence
El-Attar, N. E., Moustafa, B. M., & Awad, W. A. (2021) · Intelligent Automation & Soft Computing · doi:10.32604/iasc.2022.019970 · Cited by 24
Vu, N. T., Phúc, T. H., Oanh, K. T. P., Sáng, N. V., Trang, T. T., & Nguyen, N. H. (2021) · G3 Genes Genomes Genetics · doi:10.1093/g3journal/jkab361 · Cited by 27
Pérez-Cova, M., Tauler, R., & Jaumot, J. (2022) · Separations · doi:10.3390/separations9030079 · Cited by 24
Lin, X.-J., Hong, D.-W., Zhang, D., et al. (2022) · Diagnostics · doi:10.3390/diagnostics12051047 · Cited by 24
“, the number of caries samples and non-caries samples differed extremely in quantity) [47].”
BackgroundVerma, D., Jansen, D., Bach, K., Poel, M., Mork, P. J., & Nijeweme-d’Hollosy, W. O. (2022) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-022-01973-9 · Cited by 26
“MCC has a value in the range [− 1, 1] and produces a high score only when the predictions obtain good results in all of the four confusion matrix categories, which is useful for imbalanced classes [51].”
BackgroundBayğın, M., Barua, P. D., Chakraborty, S., Tuncer, I., Doğan, Ş., Palmer, E. E., Tuncer, T., Kamath, A. P., Ciaccio, E. J., & Acharya, U. R. (2023) · Physiological Measurement · doi:10.1088/1361-6579/acb03c · Cited by 24
“Mathematical equations that were employed for performance evaluation of the developedmodel are given in equations (11)–(16), as also utilized by others (Warrens 2008, Chicco and Jurman 2020).”
MethodIdentifying Eukaryotes and Factors Influencing Their Biogeography in Drinking Water Metagenomes
Gabrielli, M., Dai, Z., Delafont, V., Timmers, P. H. A., van der Wielen, P. W. J. J., Antonelli, M., & Pinto, A. J. (2023) · Environmental Science & Technology · doi:10.1021/acs.est.2c09010 · Cited by 23
Islam, M. S., Crawford, T. W., & Shao, Y. (2023) · Frontiers in Environmental Science · doi:10.3389/fenvs.2023.1144686 · Cited by 24
“The F1 score metric is a more balanced metric than recall and precision (Chicco and Jurman, 2020).”
BackgroundPartial Discharge Detection by Edge Computing
Klein, L., Zmij, P., & Krömer, P. (2023) · IEEE Access · doi:10.1109/access.2023.3268763 · Cited by 24
“Prediction accuracy was evaluated by the Matthews correlation coefficient (MCC) [57] because the data set is highly unbalanced.”
MethodCIS-WQMS: Connected intelligence smart water quality monitoring scheme
Ajakwe, S. O., Ajakwe, I. U., Jun, T., et al. (2023) · Internet of Things · doi:10.1016/j.iot.2023.100800 · Cited by 24
Li, T., Liu, Z., Thakkar, S., Roberts, R. A., & Tong, W. (2023) · Regulatory Toxicology and Pharmacology · doi:10.1016/j.yrtph.2023.105486 · Cited by 25
PhyMER: Physiological Dataset for Multimodal Emotion Recognition With Personality as a Context
Pant, S., Yang, H.-J., Lim, E., Kim, S.-H., & Yoo, S. B. (2023) · IEEE Access · doi:10.1109/access.2023.3320053 · Cited by 29
“As F1-score does not consider the true negatives, MCC can better represent the classification accuracy [57].”
Predicting 90-Day Prognosis in Ischemic Stroke Patients Post Thrombolysis Using Machine Learning
Abujaber, A. A., Albalkhi, I., Imam, Y. Z. B., Nashwan, A. J., Yaseen, S., Akhtar, N., & Alkhawaldeh, I. M. (2023) · Journal of Personalized Medicine · doi:10.3390/jpm13111555 · Cited by 25
DR-BERT: A protein language model to annotate disordered regions
Nambiar, A., Forsyth, J. M., Liu, S., & Maslov, S. (2024) · Structure · doi:10.1016/j.str.2024.04.010 · Cited by 30
Aouraghe, I., Alae, A., Khaissidi, G., et al. (2020) · Journal of Neuroscience Methods · doi:10.1016/j.jneumeth.2020.108727 · Cited by 24
Combrisson, E., Allegra, M., Basanisi, R., Ince, R. A. A., Giordano, B. L., Bastin, J., & Brovelli, A. (2022) · NeuroImage · doi:10.1016/j.neuroimage.2022.119347 · Cited by 31
Metadata
- Authors
- Chicco, D., & Jurman, G.
- Affiliations
- Krembil Research Institute (CA)
- Fondazione Bruno Kessler (IT)
- Corresponding author
- Chicco, Davide
- Venue
- BMC Genomics
- Published
- 2020-01-02
- Volume
- 21
- Issue
- 1
- Pages
- 6-6
- ISSN
- 1471-2164 (ISSN-L)
- PMC
- PMC6941312
- OpenAlex
- W2999309192
- Semantic Scholar
- 44858b662822d291a5e1e9e3501ad19a9f1572c2
- Cited by
- 6,143
- References
- 104
- Citations by year
- 2026: 1118 · 2025: 1152 · 2024: 1060 · 2023: 1032 · 2022: 883 · 2021: 682 · 2020: 211
- FWCI
- 276.55
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- BMC Genomics (publishedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- BOA (University of Milano-Bicocca) (submittedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- Iris (University of Trento) (submittedVersion)
- Funders
- University of Toronto
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Imbalanced Data Classification Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning and Data Classification
- Physical Sciences › Mathematics › Statistics and Probability › Statistical Methods in Epidemiology
- Keywords
- Matthews correlation coefficient, F1 score, accuracy, confusion matrix, class imbalance, classification metrics
- MeSH terms
- Machine Learning, Correlation of Data, Algorithms, Data Interpretation, Statistical, Computational Biology
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
