

Efficient Contextualized Representation: Language Model Pruning for Sequence Labeling
Open accessThe DOI matches its Crossref record; 43 of the 43 references it cites were found in a registry or an index.
Abstract
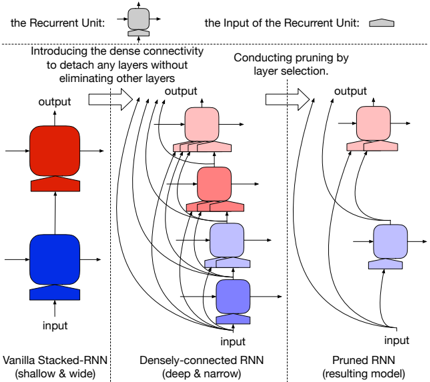
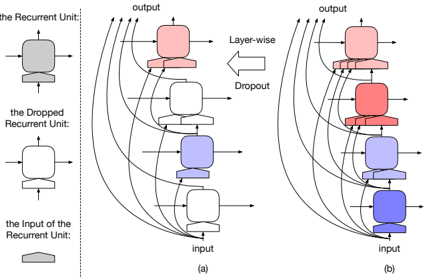
Many efforts have been made to facilitate natural language processing tasks with pre-trained language models (LMs), and brought significant improvements to various applications.To fully leverage the nearly unlimited corpora and capture linguistic information of multifarious levels, large-size LMs are required; but for a specific task, only parts of these information are useful.Such large-sized LMs, even in the inference stage, may cause heavy computation workloads, making them too time-consuming for large-scale applications.Here we propose to compress bulky LMs while preserving useful information with regard to a specific task.As different layers of the model keep different information, we develop a layer selection method for model pruning using sparsityinducing regularization.By introducing the dense connectivity, we can detach any layer without affecting others, and stretch shallow and wide LMs to be deep and narrow.In model training, LMs are learned with layerwise dropouts for better robustness.Experiments on two benchmark datasets demonstrate the effectiveness of our method.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Prompt-based methods have shown great power in few-shot setting [199, 200, 70, 72], zero-shot setting [129, 201], and even fully-supervised setting [74, 75].”
From Pre-trained models for natural language processing: A survey (2020) · cites this paper as [201]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
Densely Connected Convolutional Networks
Huang, G., Liu, Z., Van Der Maaten, L., & Weinberger, K. Q. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.243 · Cited by 48,566
Distilling the Knowledge in a Neural Network
Hinton, G., Vinyals, O., & Dean, J. (2015) · arXiv · doi:10.48550/arxiv.1503.02531 · Cited by 14,204
(2010) · Cited by 14,134
Deep Contextualized Word Representations
Peters, M., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., & Zettlemoyer, L. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1202 · Cited by 11,983
Identity mappings in deep residual networks
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46493-0_38 · Cited by 10,741
Neural Architectures for Named Entity Recognition
Lample, G., Ballesteros, M., Subramanian, S., Kawakami, K., & Dyer, C. (2016) · Proceedings of the 2016 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/n16-1030 · Cited by 4,401 · cited 3×
“Many attempts have been made to conduct end-to-end learning and build reliable models without handcrafted features (Chiu and Nichols, 2016; Lample et al., 2016; Ma and Hovy, 2016).”
BackgroundMethodFitNets: Hints for Thin Deep Nets
Romero, A., Ballas, N., Kahou, S. E., Chassang, A., Gatta, C., & Bengio, Y. (2014) · arXiv · doi:10.48550/arxiv.1412.6550 · Cited by 2,859
Introduction to the CoNLL-2003 Shared Task: Language-Independent Named Entity Recognition
Tjong Kim Sang, E. F., & De Meulder, F. (2003) · Proceedings of the seventh conference on Natural language learning at HLT-NAACL 2003 - · doi:10.3115/1119176.1119195 · Cited by 2,788
End-to-end Sequence Labeling via Bi-directional LSTM-CNNs-CRF
Ma, X., & Hovy, E. (2016) · Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p16-1101 · Cited by 2,567 · cited 1×
“Many attempts have been made to conduct end-to-end learning and build reliable models without handcrafted features (Chiu and Nichols, 2016; Lample et al., 2016; Ma and Hovy, 2016).”
BackgroundCourbariaux, M., Hubara, I., Soudry, D., El-Yaniv, R., & Bengio, Y. (2016) · arXiv · doi:10.48550/arxiv.1602.02830 · Cited by 2,106
Named Entity Recognition with Bidirectional LSTM-CNNs
Chiu, J. P. C., & Nichols, E. (2016) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00104 · Cited by 1,909
Introduction to the CoNLL-2002 Shared Task: Language-Independent Named Entity Recognition
Sang, E. T. K. (2002) · arXiv (Cornell University) · doi:10.48550/arxiv.cs/0209010 · Cited by 1,560
Design challenges and misconceptions in named entity recognition
Ratinov, L., & Roth, D. (2009) · Proceedings of the Thirteenth Conference on Computational Natural Language Learning - CoNLL '09 · doi:10.3115/1596374.1596399 · Cited by 1,448
Kiros, R., Zhu, Y., Salakhutdinov, R., Zemel, R. S., Torralba, A., Urtasun, R., & Fidler, S. (2015) · arXiv · doi:10.48550/arxiv.1506.06726 · Cited by 1,293 · cited 1×
“Actually, contextualized representations have strong connections with the skip-thought vectors (Kiros et al., 2015).”
BackgroundOne Billion Word Benchmark for Measuring Progress in Statistical Language Modeling
Chelba, C., Mikolov, T., Schuster, M., Ge, Q., Brants, T., Koehn, P., & Robinson, T. (2013) · arXiv · doi:10.48550/arxiv.1312.3005 · Cited by 1,051
Semi-supervised Sequence Learning
Dai, A. M., & Le, Q. V. (2015) · arXiv · doi:10.48550/arxiv.1511.01432 · Cited by 994
Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer
Shazeer, N., Mirhoseini, A., Maziarz, K., Davis, A., Le, Q., Hinton, G., & Dean, J. (2017) · arXiv · doi:10.48550/arxiv.1701.06538 · Cited by 933 · cited 2×
“Specifically, with extensive corpora, language models can be well trained to generate high-quality sentences from scratch (Józefowicz et al., 2016; Grave et al., 2017; Li et al., 2018; Shazeer et al., 2017).”
BackgroundExploring the Limits of Language Modeling
Józefowicz, R., Vinyals, O., Schuster, M., Shazeer, N., & Wu, Y. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1602.02410 · Cited by 823
To prune, or not to prune: exploring the efficacy of pruning for model compression
Zhu, M., & Gupta, S. (2017) · arXiv · doi:10.48550/arxiv.1710.01878 · Cited by 805
Introduction to the CoNLL-2000 shared task: chunking
Tjong Kim Sang, E. F., & Buchholz, S. (2000) · Proceedings of the 2nd workshop on Learning language in logic and the 4th conference on Computational natural language learning - · doi:10.3115/1117601.1117631 · Cited by 705
Semi-supervised sequence tagging with bidirectional language models
Peters, M., Ammar, W., Bhagavatula, C., & Power, R. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1161 · Cited by 655
One billion word benchmark for measuring progress in statistical language modeling
Chelba, C., Mikolov, T., Schuster, M., Ge, Q., Brants, T., Koehn, P., & Robinson, T. (2014) · Interspeech 2014 · doi:10.21437/interspeech.2014-564 · Cited by 627
Torres H., J. P. (2025) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.17754506 · Cited by 580
Learning Structured Sparsity in Deep Neural Networks
Wen, W. X., Wu, C., Wang, Y., Chen, Y., & Li, H. H. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1608.03665 · Cited by 402
Empower Sequence Labeling with Task-Aware Neural Language Model
Liu, L., Shang, J., Ren, X., Xu, F., Gui, H., Peng, J., & Han, J. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.12006 · Cited by 333
Self-citationLearning to Generate Reviews and Discovering Sentiment
Radford, A., Jozefowicz, R., & Sutskever, I. (2017) · arXiv · doi:10.48550/arxiv.1704.01444 · Cited by 330 · cited 2×
“Specifically, we recognize the cell states of LSTMs are more like to be the sentence embedding (Radford et al., 2017), since they are only passed to the next time stamps.”
BackgroundAn Ontology for CoNLL-RDF: Formal Data Structures for TSV Formats in Language Technology
Chiarcos, C., Ionov, M., Glaser, L., & Fäth, C. (2000) · arXiv (Cornell University) · doi:10.4230/oasics.ldk.2021.20 · Cited by 322
Tying Word Vectors and Word Classifiers: A Loss Framework for Language Modeling
Inan, H., Khosravi, K., & Socher, R. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1611.01462 · Cited by 288
Semi-supervised Multitask Learning for Sequence Labeling
Rei, M. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1194 · Cited by 257
Efficient softmax approximation for GPUs
Grave, É., Joulin, A., Cissé, M., & Jeǵou, H. (2017) · International Conference on Machine Learning · Cited by 219
CharNER: Character-Level Named Entity Recognition
Kuru, O., Can, O. A., & Yüret, D. (2016) · International Conference on Computational Linguistics · Cited by 164
Empower Sequence Labeling with Task-Aware Neural Language ModelPreprint
Liu, L., Shang, J., Xu, F. F., et al. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1709.04109 · Cited by 150
Self-citationAn algorithm for nonlinear optimization problems with binary variables
Murray, W., & Ng, K. M. (2008) · Computational Optimization and Applications · doi:10.1007/s10589-008-9218-1 · Cited by 141
Efficient softmax approximation for GPUs
Grave, É., Joulin, A., Cissé, M., Grangier, D., & Jeǵou, H. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1609.04309 · Cited by 132
Zilly, J., Srivastava, R., Koutník, J., & Schmidhuber, J. (2016) · arXiv (Cornell University) · doi:10.3929/ethz-b-000233981 · Cited by 74
Analysis of Dropout Learning Regarded as Ensemble Learning
Hara, K., Saitoh, D., & Shouno, H. (2016) · Lecture notes in computer science · doi:10.1007/978-3-319-44781-0_9 · Cited by 66
Ternary Neural Networks with Fine-Grained Quantization
Mellempudi, N., Kundu, A., Mudigere, D., Das, D., Kaul, B., & Dubey, P. K. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1705.01462 · Cited by 55
On the State of the Art of Evaluation in Neural Language Models
Melis, G., Dyer, C., & Blunsom, P. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1707.05589 · Cited by 42
Slim Embedding Layers for Recurrent Neural Language Models
Li, Z., Kulhanek, R., Wang, S., Zhao, Y., & Wu, S. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.12000 · Cited by 25
Slim Embedding Layers for Recurrent Neural Language ModelsPreprint
Li, Z., Kulhanek, R., Wang, S., et al. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1711.09873 · Cited by 18
Improving Language Modeling using Densely Connected Recurrent Neural Networks
Godin, F., Dambre, J., & Neve, W. D. (2017) · Workshop on Representation Learning for NLP (RepL4NLP) · doi:10.18653/v1/w17-2622 · Cited by 8
Quantized Neural Networks: Training Neural Networks with Low Precision Weights and Activations
Hubara, I., Courbariaux, M., Soudry, D., El-Yaniv, R., & Bengio, Y. (2016) · arXiv · doi:10.48550/arxiv.1609.07061
Research works printed but not linked: 4
- Xavier Glorot and Yoshua Bengio. 2010. Understand- ing the difficulty of training deep feedforward neu- ral networks. In Proceedings of the Thirteenth In- ternational Conference on Artificial Intelligence and Statistics.
- Song Han, Jeff Pool, John Tran, and William Dally. 2015. Learning both weights and connections for efficient neural network. In Advances in neural in- formation processing systems, pages 1135-1143.
- Gao Huang, Zhuang Liu, Laurens Van Der Maaten, and Kilian Q Weinberger. 2017. Densely connected con- volutional networks. In CVPR.
- Walter Murray and Kien-Ming Ng. 2010. An algo- rithm for nonlinear optimization problems with bi- nary variables. Computational Optimization and Applications, 47(2):257-288.
Cited by
A Survey on Deep Learning for Named Entity Recognition
Li, J., Sun, A., Han, J., & Li, C. (2022) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2020.2981314 · Cited by 1,567
Self-citationPre-trained models for natural language processing: A survey
Qiu, X., Sun, T., Xu, Y., Shao, Y., Dai, N., & Huang, X. (2020) · Science China Technological Sciences · doi:10.1007/s11431-020-1647-3 · Cited by 1,591
“[107] used layer-wise pruning and dense connection to speed up ELMo’s inference on NER.”
MethodOn the Variance of the Adaptive Learning Rate and Beyond
Liu, L., Jiang, H., He, P., Chen, W., Liu, X., Gao, J., & Han, J. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1908.03265 · Cited by 595
Self-citationMoverScore: Text Generation Evaluating with Contextualized Embeddings and Earth Mover Distance
Zhao, W., Peyrard, M., Liu, F., Gao, Y., Meyer, C. M., & Eger, S. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1053 · Cited by 490
“…of multi-layer attentive neural architectures (Devlin et al., 2018; Peters et al., 2018), consolidating layer-wise information remains an open problem as different layers capture information at disparate scales and task-specific layer selection methods may be limited (Liu et al., 2018, 2019).”
BackgroundDissecting Contextual Word Embeddings: Architecture and Representation
Peters, M., Neumann, M., Zettlemoyer, L., & Yih, W.-T. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1179 · Cited by 434
Metadata
- Authors
- Liu, L., Ren, X., Shang, J., Gu, X., Peng, J., & Han, J.
- Affiliations
- University of Illinois Urbana-Champaign (US)
- University of Southern California (US)
- Venue
- Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing
- Published
- 2018
- Pages
- 1215-1225
- OpenAlex
- W2963972328
- Cited by
- 45
- References
- 43
- Citations by year
- 2026: 1 · 2025: 2 · 2024: 1 · 2023: 5 · 2022: 8 · 2021: 3 · 2020: 13 · 2019: 11 · 2018: 1
- FWCI
- 2.86
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Army Research Laboratory (Cooperative Agreement Number W911NF-09-2-0053 (the, W911NF, W911NF-09-2-0053)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- sequence labeling, layer selection, sparsity-promoting regularization, dense connections, model compression, pre-trained language models, inference efficiency
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
