

The DOI matches its DataCite record; 34 of the 34 references it cites were found in a registry or an index.
Towards Accurate Differential Diagnosis with Large Language Models
Open accessAbstract
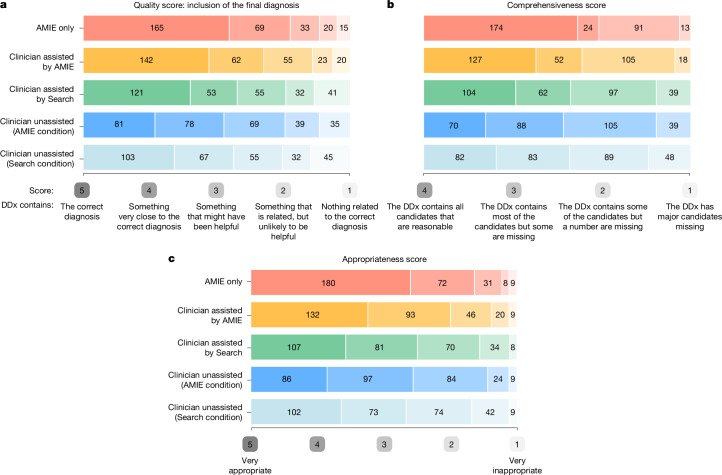
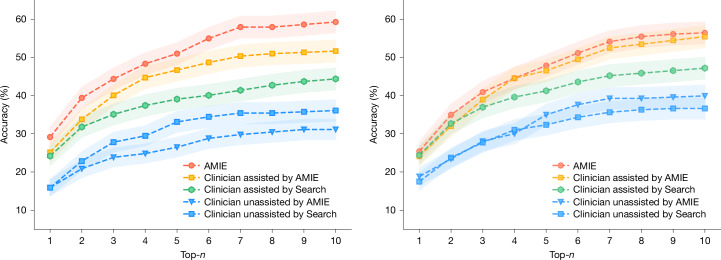
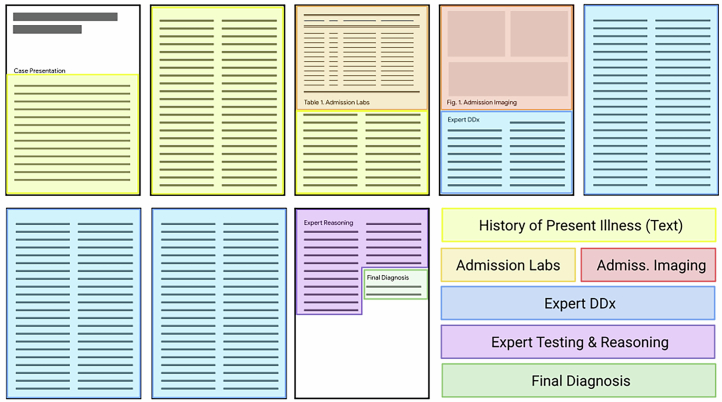
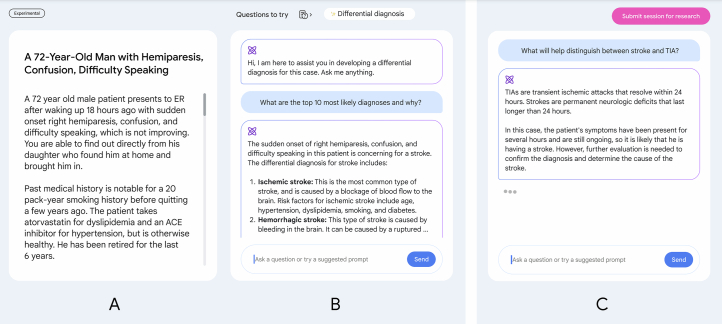
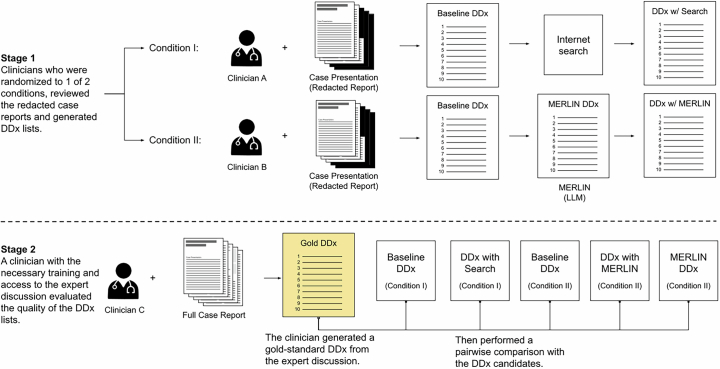
An accurate differential diagnosis (DDx) is a cornerstone of medical care, often reached through an iterative process of interpretation that combines clinical history, physical examination, investigations and procedures. Interactive interfaces powered by Large Language Models (LLMs) present new opportunities to both assist and automate aspects of this process. In this study, we introduce an LLM optimized for diagnostic reasoning, and evaluate its ability to generate a DDx alone or as an aid to clinicians. 20 clinicians evaluated 302 challenging, real-world medical cases sourced from the New England Journal of Medicine (NEJM) case reports. Each case report was read by two clinicians, who were randomized to one of two assistive conditions: either assistance from search engines and standard medical resources, or LLM assistance in addition to these tools. All clinicians provided a baseline, unassisted DDx prior to using the respective assistive tools. Our LLM for DDx exhibited standalone performance that exceeded that of unassisted clinicians (top-10 accuracy 59.1% vs 33.6%, [p = 0.04]). Comparing the two assisted study arms, the DDx quality score was higher for clinicians assisted by our LLM (top-10 accuracy 51.7%) compared to clinicians without its assistance (36.1%) (McNemar's Test: 45.7, p < 0.01) and clinicians with search (44.4%) (4.75, p = 0.03). Further, clinicians assisted by our LLM arrived at more comprehensive differential lists than those without its assistance. Our study suggests that our LLM for DDx has potential to improve clinicians' diagnostic reasoning and accuracy in challenging cases, meriting further real-world evaluation for its ability to empower physicians and widen patients' access to specialist-level expertise.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“An unexpected secondary result was that the LLM alone performed significantly better than both groups of humans, similar to a recent study with different LLM technology.31”
From Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial (2024) · cites this paper as [31]
Experimental — accuracy not yet measuredThe check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Our study included 6 cases that could feasibly be completed within a single study session while remaining comparable to standard practices in national licensing and objective structured clinical examinations to use a small, but broad sample of clinical cases.6,46,47,48,49”
From Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial (2024) · cites this paper as [46]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Measurement of Observer Agreement for Categorical Data
Landis, J. R., & Koch, G. G. (1977) · Biometrics · doi:10.2307/2529310 · Cited by 81,148
MIMIC-III, a freely accessible critical care database
Johnson, A. E. W., Pollard, T. J., Shen, L., Lehman, L.-W. H., Feng, M., Ghassemi, M., Moody, B., Szolovits, P., Anthony Celi, L., & Mark, R. G. (2016) · Scientific Data · doi:10.1038/sdata.2016.35 · Cited by 8,141
Dissecting racial bias in an algorithm used to manage the health of populations
Obermeyer, Z., Powers, B., Vogeli, C., & Mullainathan, S. (2019) · Science · doi:10.1126/science.aax2342 · Cited by 7,137
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Self-citationLlama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604
Reasoning Foundations of Medical Diagnosis
Ledley, R. S., & Lusted, L. B. (1959) · Science · doi:10.1126/science.130.3366.9 · Cited by 998
LLaVA-Med: Training a Large Language-and-Vision Assistant for Biomedicine in One Day
Li, C., Wong, C., Zhang, S., Usuyama, N., Liu, H., Yang, J., Naumann, T., Poon, H., & Gao, J. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-1240 · Cited by 986
Seyyed-Kalantari, L., Zhang, H., McDermott, M. B. A., Chen, I. Y., & Ghassemi, M. (2021) · Nature Medicine · doi:10.1038/s41591-021-01595-0 · Cited by 928
A deep learning system for differential diagnosis of skin diseases
Liu, Y., Jain, A., Eng, C., Way, D. H., Lee, K., Bui, P., Kanada, K., de Oliveira Marinho, G., Gallegos, J., Gabriele, S., et al. (2020) · Nature Medicine · doi:10.1038/s41591-020-0842-3 · Cited by 853
Self-citationAnil, R., Dai, A. M., Firat, O., Johnson, M., Lepikhin, D., Passos, A., Shakeri, S., Taropa, E., Bailey, P., Chen, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2305.10403 · Cited by 834
Self-citation
Research works printed but not linked: 5
- [6]6. OpenAI. GPT-4 Technical Report 2023. arXiv: 2303.08774 [cs.CL] . · arXiv
- [13]13. Buckley, T., Diao, J. A., Rodman, A. & Manrai, A. K. Accuracy of a Vision-Language Model on Challenging Medical Cases 2023. arXiv: 2311.05591 [cs.CV] . · arXiv
- [17]17. Hong, J., Levine, S. & Dragan, A. Zero-Shot Goal-Directed Dialogue via RL on Imagined Conversations. arXiv preprint arXiv:2311.05584 (2023). · arXiv
- [21]21. Miller, R. A., Pople Jr, H. E. & Myers, J. D. in Computer-assisted medical decision making 139-158 (Springer, 1985).
- [30]30. Umapathi, L. K., Pal, A. & Sankarasubbu, M. Med-halt: Medical domain hallucination test for large language models. arXiv preprint arXiv:2307.15343 (2023). · arXiv
Cited by
Sorted by citations
Items 201–300 of 315
Hunton, R. W., Potter, D., & Schuer, K. M. (2025) · The Journal of Physician Assistant Education · doi:10.1097/jpa.0000000000000690 · Cited by 1
Hunton, R. W., & Potter, D. J. (2025) · doi:10.2196/preprints.80150
Context is King: From Prompt Engineering to Context Engineering in Healthcare AIPreprint
Shankar, R. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5365971
Zero-Shot Evaluation of Kimi K2 on Pediatric Clinical CasesPreprint
Mondillo, G., Masino, M., Colosimo, S., Perrotta, A., Frattolillo, V., & Abbate, F. G. (2025) · medRxiv · doi:10.1101/2025.07.29.25332368
Штучний інтелект у цифровій трансформації бізнесу та маркетингу
Havryliuk, O., & Ponomarenko, I. (2025) · Проблеми сучасних трансформацій Серія економіка та управління · doi:10.54929/2786-5738-2025-20-04-03 · Cited by 3
Foundations of Clinical Informatics for Generalists
Patel, S. Y., Mezoff, E. A., & Rust, L. (2025) · Medical Clinics of North America · doi:10.1016/j.mcna.2025.06.003
Self-citationUnderstanding Human Detection of Algorithmic Bias Through Drift-Diffusion ModelingPreprint
Overbye-Thompson, H. E., Hamilton, K. A., & Fisher, J. C. (2025) · Research Square · doi:10.21203/rs.3.rs-7359286/v1
aiDIVA – Diagnostics of Rare Genetic Diseases Using Large Language ModelsPreprint
Boceck, D., Laugwitz, L., Sturm, M., Bezdan, D., Gschwind, A., Haack, T. B., & Ossowski, S. (2025) · medRxiv · doi:10.1101/2025.09.04.25335099
Yano, Y., Kakizaki, H., Nagasu, H., Kishi, S., Koshida, T., Nihei, Y., Hirano, A., Nangaku, M., Mori, H., Naito, T., et al. (2025) · medRxiv · doi:10.1101/2025.09.04.25334460
Emerging Role of AI in Cardiovascular Medicine
Kodera, S., & Takeda, N. (2025) · Journal of Coronary Artery Disease · doi:10.7793/jcad.31.007
Contemplating the Potential of My Own Obsolescence
El‐Samad, H. (2025) · GEN Biotechnology · doi:10.1177/27681572251363643
Meißner, T., Konrad, K., Kerth, J.-L., Reinhart, L., Henn, A. T., Bell, L., Bischops, A., & Hagemeister, M. (2025) · Springer eBooks · doi:10.1007/978-3-658-48573-3_15
Transforming LLMs into Domain Experts: A Case Study of Train Trajectory Evaluation
Yu, Y., Sun, P., Zhao, H., Wang, Q., & Liu, C. (2025) · IEEE International Conference on Intelligent Rail Transportation (ICIRT) · doi:10.1109/icirt66379.2025.11216746
Zusatzweiterbildung „Digitale Medizin“, ergibt das Sinn?
Fuchtmann, J., & Wilhelm, D. (2025) · Zentralblatt für Chirurgie - Zeitschrift für Allgemeine Viszeral- Thorax- und Gefäßchirurgie · doi:10.1055/a-2690-4214
Biased decisions of Large Language Models (LLM): Computer control agents and the decoy effect
Bösch, K. (2026) · Journal of Behavioral and Experimental Economics · doi:10.1016/j.socec.2026.102641
Comparing the Neuropsychology Knowledge Base of Publicly Available Large Language Models
Kronenberger, O. R., Hutnyan, M., Kaser, A. N., Bullinger, L., Lacritz, L. H., & Cullum, C. M. (2025) · Archives of Clinical Neuropsychology · doi:10.1093/arclin/acaf112
Yan, B.-C., Zhang, R., Fan, Y., Li, Y., Chen, L., Song, X., Tang, Y., Tu, Y., Cao, Z., Shen, L., et al. (2025) · Research Square · doi:10.21203/rs.3.rs-7998391/v1
Transforming Healthcare: Sustainable and Inclusive Outcomes through AI and Deep Learning
Gokhale, P., & Pande, M. (2025) · International Conference on Sustainable Technologies for Humanity and Smart World (HSWTech) · doi:10.1109/hswtech64936.2025.11277427
Shao, M., & Zhang, H. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-02146-4 · Cited by 2
Yang, X., Zhu, J., Pan, W., Wang, Y., Yan, K., & Fang, Z. (2026) · doi:10.2196/preprints.91222
Ahmed, M., & Abbas, G. (2025) · IEEE International Conference on Smart Communities: Improving Quality of Life using AI, Robotics and IoT (HONET) · doi:10.1109/honet67928.2025.11318509
RiemannInfer: improving transformer inference through Riemannian geometry
Mao, R., Zhang, Z., Yang, M., Xie, H., Wei, S., & Hu, C. (2026) · Scientific Reports · doi:10.1038/s41598-026-37328-x
Practical Frameworks for Integrating Artificial Intelligence in Forensic Psychology
Rilen, S. (2026) · Journal of Forensic Psychology Research and Practice · doi:10.1080/24732850.2026.2630383 · Cited by 1
Figueroa, C. A., Garikipati, K., Yang, H., & Capecelatro, J. (2026) · Annual Review of Biomedical Engineering · doi:10.1146/annurev-bioeng-081325-031501
Next Generation Herzchirurgie: Prompt Engineering
Safarov, R., Wippermann, J., & Wacker, M. (2026) · Zeitschrift für Herz- Thorax- und Gefäßchirurgie · doi:10.1007/s00398-026-00763-z
Yang, J., Yang, S., Shao, Z., Chen, T., Shen, H., Zhou, P., Xia, B., Lei, X., Wang, L., Xue, D., et al. (2026) · Burns & Trauma · doi:10.1093/burnst/tkag026
Taraf, N. H., Camalan, B. V., Doluoğlu, S., Arslan, E., Ural, A., Demiroğlu, G., Elhan, A. E., & Özlügedik, S. (2026) · European Journal of Rhinology and Allergy · doi:10.65396/ejra.1846059
From Regression to Reasoning: Predicting M&A Announcement Returns With Large Language Models
Schreiter, M., Struve, A., & Uhle, M. (2026) · European Financial Management · doi:10.1111/eufm.70059 · Cited by 2
Lu, X., Wang, X., Liu, D., Zhang, Z., Zhang, Y., Zhang, T., Lü, D., Kuang, S., Lai, C., Piao, F., et al. (2026) · PLOS Digital Health · doi:10.1371/journal.pdig.0001317
Li, Y., Yan, B.-C., Zhang, R., Song, X. Z., Chen, L., & Cao, Z. (2026) · doi:10.2196/preprints.96304
Okada, N., Nakanishi, H., Sakamoto, Y., Hirayama, S., Liu, C., Mitarai, S., Mitarai, S., Yamamoto, G., & Okamoto, K. (2026) · JMIR Medical Informatics · doi:10.2196/preprints.96996
Yang, X., Li, J., Xiang, Y., Ju, M., Liang, K., He, Y., Zhao, Q., & Huang, H. (2026) · doi:10.2196/preprints.99511
Assessment of frontier Large Language Models in sleep medicine
Patel, A., Contractor, H., Heninger, H., Vallamchetla, S. K., Li, P., Tao, C., & Cheung, J. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1769386 · Cited by 1
Preparing Citizens for Emergency Calls with a Hybrid FSM-LLM Dialogue Agent
Klein, S. P., & Kiam, J. J. (2026) · ACM International Conference on Intelligent Virtual Agents (IVA) · doi:10.1145/3806774.3827975
Feistkorn, E., Böhning, D. A., Reuser, M., Davis, E., Begemann, K., & Greiner, M. (2026) · Clinical Toxicology · doi:10.1080/15563650.2026.2647647
Case Studies of Explainable LLMs in Diagnosis, Treatment Planning, and Patient Interaction
Tabatabaei, A., Gorji, M., & Rahimi, A. (2026) · Springer eBooks · doi:10.1007/978-3-032-15088-2_8
Murphy, K. B., Schilder, B. M., & Skene, N. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1794934 · Cited by 4
Akazua, L., Zhou, J. J., Chen, F., Shafiabady, N., George, T., Holzinger, A., & Müller, H. (2026) · Machine Learning and Knowledge Extraction · doi:10.3390/make8060144 · Cited by 1
The Potential Expertise Paradox in AI-Assisted Radiology
McMillan, A. B. (2026) · Radiology · doi:10.1148/radiol.261178
Demystifying Artificial Intelligence
Collins, J. E., Harari, R. E., & Duryea, J. (2026) · Rheumatic Disease Clinics of North America · doi:10.1016/j.rdc.2026.04.001
Yano, Y., Kakizaki, H., Nagasu, H., Kishi, S., Koshida, T., Nihei, Y., Hirano, A., Nangaku, M., Mori, H., (43611), T. N., et al. (2026) · JMIR Formative Research · doi:10.2196/89726
MetaGD-CAN: A Hybrid Generative–Discriminative Method for Cancer Detection in EHR Data
Chang, Y., Tsai, W.-C., Ting, L. P.-Y., & Chuang, K.-T. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-1465-5_22
Et-Tousy, J., Malek, C., & Zyane, A. (2026) · International Conference on Innovative Research in Applied Science, Engineering and Technology (IRASET) · doi:10.1109/iraset68627.2026.11538732
Zhu, J., Pan, W., Wang, Y., Yan, K., Fang, Z., & Yang, X. (2026) · Journal of Medical Internet Research · doi:10.2196/91222
Caring in the Age of AI: A Framework for the Pediatric Trainee
Lima, G. P., & Morton, S. U. (2026) · PEDIATRICS · doi:10.1542/peds.2025-075138
Proulx, J., Daines, B., Barton, M. B., Leonard, M. E., Garcia, J. A., Young, B., Snell, Q. O., West, T. W., Watson, S. R., Alqaseer, M., et al. (2026) · medRxiv · doi:10.64898/2026.06.05.26354271
Clinical artificial intelligence applications of vision-language foundation models
Thirunavukarasu, A. J., Li, S. Y., Qin, P., Nie, D., Sanghera, R., Lim, E., Yu, J., & Zhang, L. (2026) · PLOS Digital Health · doi:10.1371/journal.pdig.0001453
Cusácovich, I., Martin, M. P., & Castro, R. G. (2026) · JMIR Formative Research · doi:10.2196/104579
Large reasoning models as thinking machines for medicine
Zhou, H.-Y., Rodman, A. M., Liu, P., Rajpurkar, P., Hu, Y., Wong, T. Y., & Topol, E. J. (2026) · Nature Biomedical Engineering · doi:10.1038/s41551-026-01701-y
Academia and industry in the age of artificial intelligence: a narrative review
Bernstam, E. V., Johnson, T. R., & Alahdab, F. (2026) · BMJ Digital Health & AI · doi:10.1136/bmjdh-2026-000047
Saha, D., Lin, Y., & Ghose, D. (2026) · ACM Transactions on Computing for Healthcare · doi:10.1145/3828166
The 5R's of large language model‐assisted diagnosis: A practical framework for hospitalists
Barish, P. N., Auerbach, A. D., & Ranji, S. R. (2026) · Journal of Hospital Medicine · doi:10.1002/jhm.70390
AI-powered Dynamic Hybrid Teaming
Fouse, A. S., Ganberg, G., Bruni, S., Volkova, S., Orvis, K. L., & Klinefelter, Z. P. (2026) · Emerald Group Publishing Limited eBooks · doi:10.1108/s1534-085620260000021015
Epistemologically Guided LLM Reasoning for Differential Diagnosis
Rancati, S., Bergomi, L., Parimbelli, E., Nicora, G., & Bellazzi, R. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-30710-1_14
Developing an approach to differential diagnosis of eye diseases based on knowledge formalization
Dolinina, O. N., Kochkareva, E. I., Arutyunyan, D. A., Kamenskikh, T. G., & Викторовна, В. Е. (2026) · Saratov Medical Journal · doi:10.15275/sarmj.2026.0104
Diagnostic performance of artificial intelligence in the syncope unit
van Zanten, S., Boel, T. T., de Jong, J. S. Y., Koomen, E. M., Bais, B., Dara, A., Giele, F., Geertsma, C., Sutton, R., Scheffer, M. G., et al. (2026) · Exploration of Cardiology · doi:10.37349/ec.2026.1012114
Rojansky, R. B., Keyes, T., & Oak, J. S. (2026) · Cytometry Part B Clinical Cytometry · doi:10.1002/cyto.b.70051 · Cited by 2
İlgün, M., Eren, E., Kibar, B., Okur, S., Aktaş, M. S., EROĞLU, M. S., Arslan, T., Baykal, B., Petek, B., Gürel, A., et al. (2026) · The Veterinary Journal · doi:10.1016/j.tvjl.2026.106776
Hautz, S. C., Epprecht, T. P., Marcin, T., Jankovska, K., Krummrey, G., & Hautz, W. E. (2026) · Diagnosis · doi:10.1515/dx-2026-0025
Benchmarking the Evolution of Large Language Models Toward Safe and Collaborative Clinical Reasoning
Asawaponwiput, W., Sri-iesaranusorn, P., Angkurawaranon, C., & Surangsrirat, D. (2026) · International Conference on Human Centric Artificial Intelligence (ICHCAI) · doi:10.1109/ichcai70183.2026.11607497
Can AI assist in reducing diagnostic error? A narrative review
Scott, I. A. (2026) · Diagnosis · doi:10.1515/dx-2026-0021
Large language models enable consensus-level interpretation in metagenomic diagnosticsPreprint
Steinig, E. J., Krysiak, M., Deo, K., Duncan, A., Prestedge, J., Barr, J. J., Moselen, J. M., Khan, S. F., Fernando, J. A., Savic, I., et al. (2026) · medRxiv · doi:10.64898/2026.07.29.26358751 · Cited by 1
AI in Clinical Practice: Examining the Role of LLMs in Medical Decision-Making
BenGhida, R., Benghida, S., BenGhida, S., & Benghida, D. (2026) · Signals and communication technology · doi:10.1007/978-3-032-18834-2_3
Rajpoot, A. K., Virdee, B., & Khanna, A. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-23317-2_12
Clinical Reasoning and Diagnostic Agents
Dinç, R., & Ardıç, N. (2026) · Springer eBooks · doi:10.1007/978-3-032-26723-8_11
From Algorithm to Bedside: A Clinician's Framework for AI in Practice
Abdelqader, A., Alkhateeb, M., Al-Marrawi, A., Baianonie, H., & Alahdab, F. (2026) · Avicenna Journal of Medicine · doi:10.1055/s-0046-1827198
Preliminary Benchmarking for Semantic Clinical Artificial Intelligence (SCAI)
Stephens, R., & Elkin, P. L. (2026) · IEEE International Conference on Healthcare Informatics (ICHI) · doi:10.1109/ichi69079.2026.00147
MEMRL: Aligning Medical Reasoning through Maximum Entropy Implicit Process Supervision
Zhu, X., & He, S. (2026) · IEEE International Conference on Electronics, Energy Systems and Power Engineering (EESPE) · doi:10.1109/eespe68405.2026.11649286
Artificial intelligence agents and agentic artificial intelligence applied to precision medicine
Costa, F. F. (2026) · Drug Discovery Today · doi:10.1016/j.drudis.2026.104781
Corral-Gudino, L., Ramos-Casals, M., Marcos, M., & Rios-Blanco, J. J. (2026) · Medicina Clínica (English Edition) · doi:10.1016/j.medcli.2026.107567
Hu, H., Ran, L. I., Yin, Y., Liu, Y., & Wang, X. (2026) · Frontiers in Industrial Engineering · doi:10.3389/fieng.2026.1854270
Self-citationA domain-enhanced multi-agent framework for trustworthy literature screening in water research
Wang, R., Lin, X., Zhong, B., Li, J., Huang, R., Huang, Y., Cai, Y., Jantarakasem, C., Xiang, Y., Plakas, K. V., et al. (2026) · Water Research · doi:10.1016/j.watres.2026.126813
Kim, J.-W., Yoon, H., Jung, D., Oh, W., Choi, D., Yoon, S.-H., Kim, D.-J., Lee, S.-Y., Kim, B.-N., & Yang, C.-M. (2026) · IEEE Access · doi:10.1109/access.2026.3727881
Hack, S., Kahn, C., García‐Lliberós, A., Rodriguez‐Prado, C., Biadsee, A., Fieux, M., Liu, M., Glikson, E., Takashima, M., Ahmed, O. G., et al. (2026) · World Journal of Otorhinolaryngology - Head and Neck Surgery · doi:10.1002/wjo2.70164
Zhao, J., Ju, M., Dong, M., Zhang, Y., Tang, K., Liu, X., Yang, K., Luo, H., Zhang, C., & Liu, G. (2026) · Journal of Cleaner Production · doi:10.1016/j.jclepro.2026.149322
Boceck, D., Laugwitz, L., Sturm, M., Bezdan, D., Gschwind, A., Haack, T. B., & Ossowski, S. (2026) · npj Genomic Medicine · doi:10.1038/s41525-026-00611-x · Cited by 3
Kremer, P., Schlicker, N., Hasnaj, R., Bamberger, J., Witte, T., Haase, I., Mayr, A., Schmidt, C., Østerås, N., Baraliakos, X., et al. (2026) · medRxiv · doi:10.64898/2026.08.29.26361715
Artificial Intelligence and Sleep
Schneider, L. D., Hernandez, J., & Heneghan, C. (2026) · Neurologic Clinics · doi:10.1016/j.ncl.2026.07.015
Turky, M., & Dummer, P. M. H. (2026) · International Dental Journal · doi:10.1016/j.identj.2026.109807
Transforming large language models into medical specialists via knowledge injection
Kim, K., Song, J., Kim, D. Y., Nam, Y., Park, S., Shin, K., Jo, W., & Kim, N. (2026) · Cell Reports Medicine · doi:10.1016/j.xcrm.2026.103020
Chen, X., She, Z., Yang, S., Chu, M., & Zhou, Y. (2026) · Journal of Global Health · doi:10.7189/jogh.16.03029
Engineering Agentic Systems: Toward Verification-First AIware Engineering
Lu, Q., Hassan, A. E., Lo, D., & Zimmermann, T. (2026) · IEEE Software · doi:10.1109/ms.2026.3697911
Language, power, and access: large language models and equity in medicine
Lashin, H. (2026) · British Journal of Anaesthesia · doi:10.1016/j.bja.2026.08.008
Dorr, D. A., Weiskopf, N. G., Sabile, J. M. G., Young, E., Mathis, D., Weller, S. L., Alex, J., Doerr, K., & Bedrick, S. (2026) · JAMIA Open · doi:10.1093/jamiaopen/ooag175
KafkaGPT: On algorithmic bureaucracy and keeping law’s promise
Allen, J. G. (2026) · Cambridge Forum on AI Law and Governance · doi:10.1017/cfl.2026.10047
MDT-guided language-model reasoning for spinal infection diagnosisPreprint
Chen, J., Zhang, R., Xu, C., Li, H., 胡维维, Cai, L., Ma, S., Meng, Y., Li, X., Chen, Y., et al. (2026) · Research Square · doi:10.21203/rs.3.rs-10692703/v1
The Long road to AI–physician partnership starts with learners: a map for AI in medical education
Patel, N., Kumar, A. D., Chi, J., Keet, K., Kugler, J., Hom, J., & Hosamani, P. (2026) · BMJ Digital Health & AI · doi:10.1136/bmjdh-2026-000056 · Cited by 1
Sorka, M., Gorenshtein, A., Abramovitch, H., Soontrapa, P., Shelly, S., & Aran, D. (2026) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocag143
Feng, J., Jiao, Y., Xie, H., Wang, J., Li, Y., Xie, L., Peng, W., & Sun, X. (2026) · medRxiv · doi:10.64898/2026.09.24.26363897
Hayakawa, C., Tsuchiya, K., Dodo, Y., Kudo, Y., & Okano, I. (2026) · Research Square · doi:10.21203/rs.3.rs-11044030/v1
The Importance of Personal Medicine in an Era of Efficiency
Mpody, C. (2026) · PEDIATRICS · doi:10.1542/peds.2026-078191
Bold, C., Faizan, R., Hua, C.-H., Kang, S. M., Lee, S., & Kim, S. T. (2026) · International Conference on Advanced Network Technologies and Applications (APAN) · doi:10.1109/apan70967.2026.11709588
Prokop, G., Biesalski, A., Krause, M., Rebmann, P. S., Piel, J. H. A., & Schmidt‐Graf, F. (2026) · BMC Medical Education · doi:10.1186/s12909-026-10515-0
BAYDİLİ, I., Taşçı, B., Taşçı, G., Doğan, Ş., & Tuncer, T. (2026) · Bioengineering · doi:10.3390/bioengineering13101175 · Cited by 1
Singh, A. J., Singh, A., Kumar, S., Dhelim, S., & Singh, C. (2026) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2026.106760
Barone, M., Selvaggi, F., Pasquale, V., Nusrath, S., Vashist, Y. K., & Marano, L. (2026) · Journal of Clinical Medicine · doi:10.3390/jcm15207802
Differential Diagnosis Provider using Clinical Case Histories and Discharge Summaries
Shirsat, A., & Haribhakta, Y. V. (2026) · International Conference on Computer, Mechatronics, Robotics & Artificial Intelligence (ICCMRAI) · doi:10.1109/iccmrai67732.2026.11723876
Goel, R., Raza, S., Russell, W. A., Seheult, J. N., Pham, T. D., D’Alessandro, A., Dubey, R., Montemayor, C., Daniel, D. B., Numark, C., et al. (2026) · Transfusion · doi:10.1111/trf.70418
Wu, D., Yang, K.-C., Zhang, L., Zhang, L., Wang, S., Ji, Q., Liu, J., Zhang, P., Zheng, L., Jiang, A., et al. (2026) · doi:10.2196/preprints.114435
Metadata
- Authors
- McDuff, D., Schaekermann, M., Tu, T., Palepu, A., Wang, A., Garrison, J., Singhal, K., Sharma, Y., Azizi, S., Kulkarni, K., Hou, L., Cheng, Y., Liu, Y., Mahdavi, S. S., Prakash, S., Pathak, A., Semturs, C., Patel, S., Webster, D. R., Dominowska, E., Gottweis, J., Barral, J., Chou, K., Corrado, G. S., Matias, Y., Sunshine, J., Karthikesalingam, A., & Natarajan, V.
- Affiliations
- Google (United States) (US)
- Google (Switzerland) (CH)
- Google (United Kingdom) (GB)
- Corresponding author
- McDuff, Daniel
- Schaekermann, Mike
- Karthikesalingam, Alan
- Natarajan, Vivek
- ORCID
- McDuff, Daniel
- Schaekermann, Mike
- Tu, Tao
- Palepu, Anil
- Wang, Amy
- Singhal, Karan
- Azizi, Shekoofeh
- Cheng, Yong
- Liu, Yun
- Mahdavi, S Sara
- Prakash, Sushant
- Pathak, Anupam
- Semturs, Christopher
- Patel, Shwetak
- Webster, Dale R
- Dominowska, Ewa
- Gottweis, Juraj
- Barral, Joelle
- Chou, Katherine
- Corrado, Greg S
- Matias, Yossi
- Karthikesalingam, Alan
- Natarajan, Vivek
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2023
- Volume
- 642
- Issue
- 8067
- Pages
- 451-457
- ISSN
- 0028-0836 (ISSN-L)
- arXiv
- 2312.00164
- PMC
- PMC12158753
- OpenAlex
- W4409283616
- Cited by
- 311
- References
- 34
- Citations by year
- 2026: 172 · 2025: 108 · 2024: 31
- FWCI
- 67.40
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, other-oa)
- arXiv (Cornell University)
- Funders
- Massachusetts Medical Society
- DeepMind
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- differential diagnosis, large language models, diagnostic reasoning, clinical decision support, clinician performance, AI-assisted diagnosis, medical knowledge retrieval
- MeSH terms
- Case Reports as Topic, Large Language Models, Artificial Intelligence, Diagnosis, Differential, Humans, Language
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
