

The DOI matches its Crossref record; 48 of the 48 references it cites were found in a registry or an index; 19 of the 36 sources its claims cite were checked for support.
Experimental evidence of effective human–AI collaboration in medical decision-making
Open accessPublished version of a preprint
Abstract
Artificial Intelligence ( ai ) systems are precious support for decision-making, with many applications also in the medical domain. The interaction between md s and ai enjoys a renewed interest following the increased possibilities of deep learning devices. However, we still have limited evidence-based knowledge of the context, design, and psychological mechanisms that craft an optimal human– ai collaboration. In this multicentric study, 21 endoscopists reviewed 504 videos of lesions prospectively acquired from real colonoscopies. They were asked to provide an optical diagnosis with and without the assistance of an ai support system. Endoscopists were influenced by ai ( $$\textsc {or}=3.05$$ O R = 3.05 ), but not erratically: they followed the ai advice more when it was correct ( $$\textsc {or}=3.48$$ O R = 3.48 ) than incorrect ( $$\textsc {or}=1.85$$ O R = 1.85 ). Endoscopists achieved this outcome through a weighted integration of their and the ai opinions, considering the case-by-case estimations of the two reliabilities. This Bayesian-like rational behavior allowed the human– ai hybrid team to outperform both agents taken alone. We discuss the features of the human– ai interaction that determined this favorable outcome.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
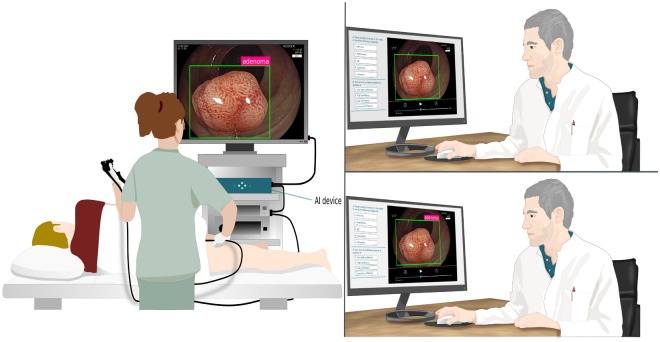
In a multicentric within-subject experiment, 21 endoscopists diagnosed 504 colonoscopy lesion videos with and without AI support. They were influenced by AI but selectively followed correct more than incorrect advice, producing better hybrid human–AI accuracy than either alone.
Key findings
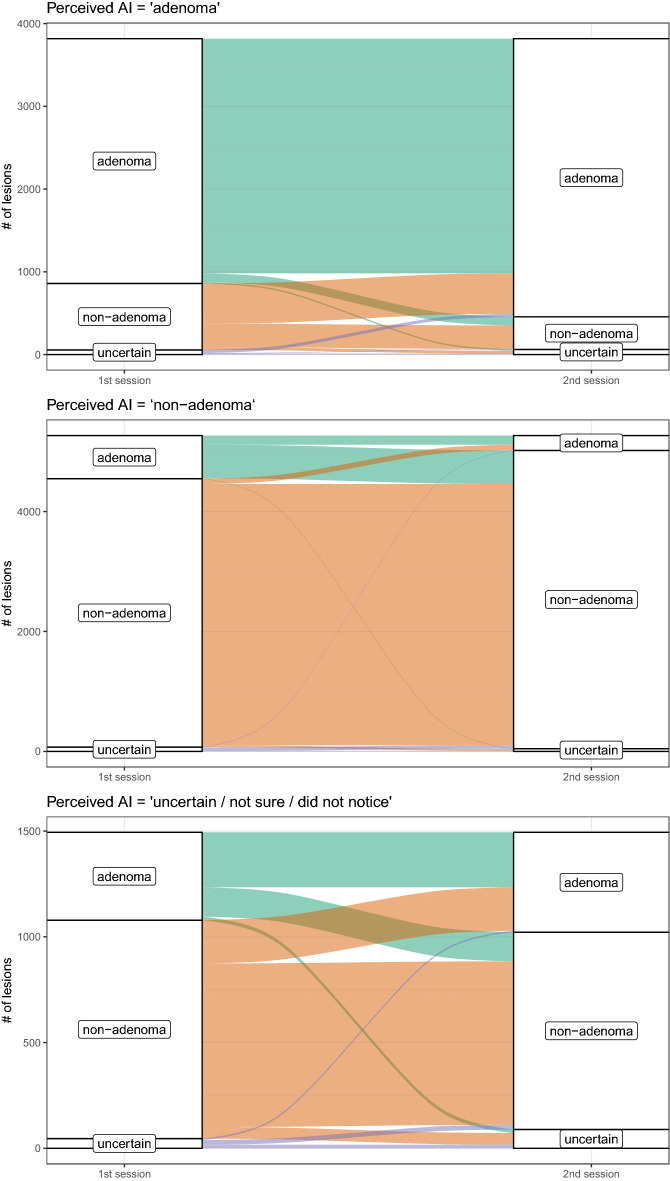
- AI influenced endoscopists’ decisions (OR = 3.05 [2.76, 3.39]); on average, for every three lesions where endoscopists disagreed with AI in Session 1, only one disagreement remained in Session 2.
- AI improved diagnostic accuracy (OR = 1.39 [1.28, 1.51]); every five lesions correctly evaluated without AI became seven correctly evaluated with AI. Effectiveness was OR = 3.48 [3.07, 3.98], while safety was OR = 0.54 [0.48, 0.62], indicating some negative impact when AI was wrong but a stronger tendency to accept correct AI advice.
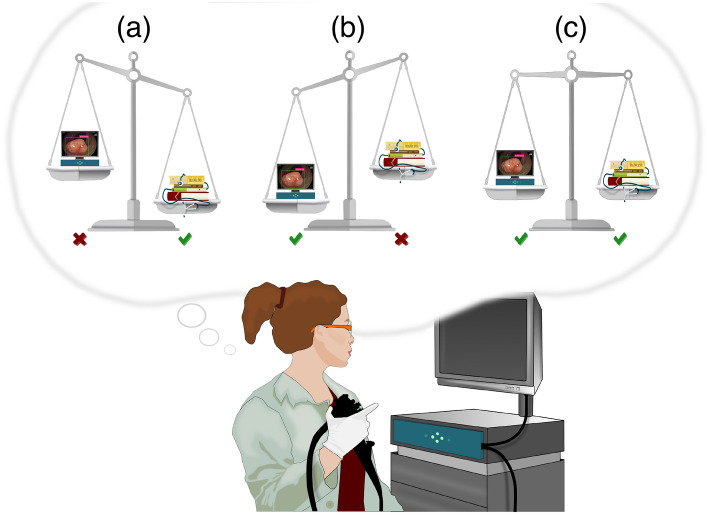
- Endoscopists discriminated good from bad AI advice: they followed AI more when it was correct than when it was incorrect, and their own confidence and perceived AI confidence predicted accuracy and modulated opinion switching.
- Expertise modulated effects: non-experts benefited more in accuracy (OR = 1.61 [1.44, 1.79]) than experts (OR = 1.15 [1.01, 1.30]); both groups showed influence, effectiveness, and safety, though experts had lower safety (0.45 [0.37, 0.54]) than non-experts (0.63 [0.54, 0.75]).
Methods
- Mixed design: within-subjects factor was treatment (no AI vs. AI); between-subjects factor was expertise (experts vs. non-experts). Twenty-one endoscopists participated: 10 experts and 11 non-experts from Austria, Israel, Japan, Portugal, and Spain.
- Participants reviewed 504 videos of real colonoscopies, each presenting one lesion, in two sessions separated by at least two weeks per batch. Session 1 had no AI advice; Session 2 used GI Genius v3.0 in cade+cadx modality to dynamically offer an optical diagnosis. Histopathological diagnosis was ground truth.
- Main analysis used logistic regression models with lesion- and endoscopist-specific random effects via lme4, estimating four odds-ratio endpoints: influence of AI, diagnostic accuracy, effectiveness, and safety. The study was preregistered.
Limitations
- The paper does not include a dedicated limitations section. Evident from the text: the sample was 21 endoscopists using one AI device in one clinical domain (colonoscopy optical diagnosis), limiting generalizability.
- AI accuracy depended on interpretation of its dynamic output: human-interpreted standard accuracy was 84.9% but 72.9% when “uncertain” or “not sure/not notice” outputs were counted as errors; automated interpretation gave 84.5% excluding “uncertain” and 79.3% including it.
- The AI device was non-transparent about its reasons, and the authors note that absence of algorithmic transparency did not disrupt performance; this leaves the mechanisms by which endoscopists inferred AI reliability only indirectly examined.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
31 Own result · 10 Own interpretation · 8 Own method · 8 No basis given · 3 Supported · 3 Partly supported · 3 Not checked yet · 2 Supported so far · 1 Couldn’t confirm · 1 No full text of the sources · accuracy not yet measured
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Notwithstanding a clear agenda on the issues that we should explore further, we still have limited evidence-based knowledge of the context, design, and psychological mechanisms that would craft an optimal human–ai team15–17.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Introduction
What the sources say
- Not checked — no full text of the sourcecites [15] Cabitza, F., Campagner, A. & Simone, C. The need to move away from agential-AI: Empirical investigations, useful concepts and open issues. Int. J. Hum. Comput. Stud. 155, 1–11 (2021). source
- Partly supportedcites [16] Okamura, K. & Yamada, S. Adaptive trust calibration for human–AI collaboration. PLoS One 15 (2020). sourceExperimental — accuracy not yet measured
The Discussion’s “Limitations and future research” section calls for further experiments on different tasks, effective cue designs, and dispositional and situational trust. That supports a narrower claim that aspects of human–AI trust calibration need more evidence; it does not establish a general lack of evidence-based knowledge about all the context, design, and psychological mechanisms needed for an optimal human–AI team. No page number is available in our copy. (LLM, conf=0.82)
- Partly supportedcites [17] Gu, H., Huang, J., Hung, L. & Chen, X. A. Lessons learned from designing an AI-enabled diagnosis tool for pathologists. In Proceedings of the ACM on Human–Computer Interaction, Vol. 5, 1–25 (2021). sourceExperimental — accuracy not yet measured
The Introduction says little work has addressed how physicians can use imperfect AI in diagnosis, and §2.1 identifies a lack of research on how medical human–AI collaboration can provide new knowledge to AI. Those passages support a narrower research gap, but not the claim of limited evidence-based knowledge about context, design, and psychological mechanisms for optimal human–AI teams generally. Page numbers are unavailable in our copy. (LLM, conf=0.84)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“The endoscopists were able to build a correct mental model of the ai’s error boundaries43.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
What the sources say
- Could not verifycites [43] Hoffman, R. R., Mueller, S. T., Klein, G. & Litman, J. Metrics for explainable AI: Challenges and prospects. arXiv preprint arXiv:1812.04608 (2018). sourceExperimental — accuracy not yet measured
Section 3 (p. 9) defines a mental model as a user’s understanding of an AI system, and Section 1.1 (p. 3) hypothesizes that explanations can help users develop good mental models. Neither reports whether endoscopists learned the AI’s error boundaries; searches for endoscopists, error boundaries, and clinical endoscopy found no such finding in our copy. (LLM, conf=0.76)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Could not verify
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“The successful extraction of two critical task parameters was likely at the core of this ability: endoscopists could intuitively but reliably predict for each lesion both their accuracy (not obvious37,38) and the accuracy of the ai (not obvious39).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
What the sources say
- Not checked — no full text of the sourcecites [37] Naguib, M. et al. Anesthesiologists’ overconfidence in their perceived knowledge of neuromuscular monitoring and its relevance to all aspects of medical practice: An international survey. Anesth. Analg. 128, 1118–1126. https://doi.org/10.1213/ANE.0000000000003714 (2019). source
- Not checked — no full text of the sourcecites [38] Meyer, A. N. D., Payne, V. L., Meeks, D. W., Rao, R. & Singh, H. Physicians’ diagnostic accuracy, confidence, and resource requests: A vignette study. JAMA Intern. Med. 173, 1952–1958. https://doi.org/10.1001/jamainternmed.2013.10081 (2013). source
- Supportedcites [39] Benda, N. C., Novak, L. L., Reale, C. & Ancker, J. S. Trust in AI: Why we should be designing for APPROPRIATE reliance. J. Am. Med. Inform. Assoc. 29, 207–212. https://doi.org/10.1093/jamia/ocab238 (2022). source
The citation is attached to the parenthetical that predicting the AI’s accuracy is ‘not obvious,’ not to the endoscopists’ observed ability. In the Introduction (page unavailable), the source explains that overall performance statistics only indirectly inform whether to trust an AI recommendation for a specific patient and that health professionals struggle to interpret other accuracy measures. (LLM, conf=0.88)
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Every source the paper cites for this claim was checked and supports it.
In the paper
“Knowing when to trust or distrust the ai allows the human expert to apply its knowledge appropriately, improving decision outcomes in cases where the ai is likely to perform poorly4,40.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
What the sources say
- Supportedcites [4] Zhang, Y., Liao, Q. V. & Bellamy, R. K. Effect of confidence and explanation on accuracy and trust calibration in AI-assisted decision making. In Proceedings of the 2020 Conference on Fairness, Accountability, and Transparency, 295–305 (2020). source
The Abstract states the attributed point almost verbatim: knowing when to trust or distrust the AI lets experts apply their knowledge when the model is likely to perform poorly. The Introduction likewise describes this as a key to successful AI-assisted decisions. The paper distinguishes this general rationale from its own experimental result, which did not show improved decision accuracy (Section 3.2). (LLM, conf=0.94)
- Supportedcites [40] Bansal, G. et al. Updates in human–AI teams: Understanding and addressing the performance/compatibility tradeoff. In Proceedings of the AAAI Conference on Artificial Intelligence, Vol. 33, 2429–2437 (2019). source
The Introduction (p. 1) says team success hinges on the human knowing when to follow an AI recommendation and when to override it, particularly where the AI is likely to err. “Trust as a Human's Mental Model of the AI” (p. 2) says an accurate understanding of AI reliability improves collaboration and team performance. (LLM, conf=0.92)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that endoscopists’ confidence in an optical diagnosis is strongly predictive of its accuracy in both sessions: the higher the confidence, the higher the accuracy (Table 3).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Endoscopists were influenced by the ai opinion ().”
- Also stated in: § Statistical analyses · plain
“| 1. Influence of the ai | | 3.05 [2.76, 3.39] |”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Statistical analyses · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“On average, for every three lesions over which endoscopists disagreed with ai in S1, only one remained in S2.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It is consistent across endoscopists (77% of average agreement among all the possible pairs of endoscopists, 94% when “uncertain” are excluded).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The other way around in case of low endoscopist confidence or high ai confidence.”
- Also stated in: § Discussion · plain
“these prediction estimates affected endoscopists’ decisions so that they switched their diagnosis towards the ai opinion more when their confidence was low and ai perceived confidence was high.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“when endoscopist confidence (as estimated in S1) is high, or ai confidence is low, the endoscopists tend to stick with their decision, i.e., they do not change their mind in case of disagreement with ai (Table 4).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 17
- It may state two separate claims as one. 16
- The quote only partly states this claim. 2
Every source the paper cites for this claim was checked and supports it.
In the paper
“Such complementarity advises a collaboration between human and artificial minds, fostering a “hybrid intelligence” that could deliver outcomes superior to those reached by each mind alone2,3.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Introduction
What the sources say
- Supportedcites [2] Dellermann, D. et al. The future of human–AI collaboration: A taxonomy of design knowledge for hybrid intelligence systems. arXiv:2105.03354 (2021). source
Section 2.3 (Hybrid Intelligence) defines hybrid intelligence as combining the complementary strengths of humans and AI to achieve results superior to what either could achieve alone. This directly supports the cited sentence’s proposed collaboration; it does not present superior outcomes as an established result in medicine. (LLM, conf=0.93)
- Supportedcites [3] Akata, Z. et al. A research agenda for hybrid intelligence: Augmenting human intellect with collaborative, adaptive, responsible, and explainable artificial intelligence. Computer 53, 18–28 (2020). source
The “What Is Hybrid Intelligence?” section defines hybrid intelligence as combining human and machine intelligence to achieve goals unreachable by either alone. The “State of the art” section also describes exploiting complementary human and machine skills through collaboration. The supplied passages do not give page numbers. (LLM, conf=0.93)
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Previous studies on cadx systems for colonoscopy focused on assessing the performances of ai against the accuracy of physicians19,20,27–30, or against the criteria established by gastroenterology societies for implementing the technology in a clinical setting31–34.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Introduction
What the sources say
- Not checked — no full text of the sourcecites [19] Kudo, S.-E. et al. Artificial intelligence and colonoscopy: Current status and future perspectives. Dig. Endosc. 31, 363–371 (2019). source
- Partly supportedcites [20] Larsen, S. L. V. & Mori, Y. Artificial intelligence in colonoscopy: A review on the current status. DEN Open 2 (2022). sourceExperimental — accuracy not yet measured
The ‘Computer-aided polyp diagnosis’ section (page unavailable) reports a comparison of CADx accuracy with observers’ diagnoses and describes a study assessing whether CADx met the NPV ≥ 90% threshold for a diagnose-and-leave strategy. It does not identify that threshold as a criterion established by a gastroenterology society or describe it as a general criterion for clinical implementation. (LLM, conf=0.84)
- Not checked — no full text of the sourcecites [27] Mori, Y. et al. Real-time use of artificial intelligence in identification of diminutive polyps during colonoscopy: A prospective study. Ann. Intern. Med. 169, 357–366 (2018). source
- Partly supportedcites [28] Byrne, M. F. et al. Real-time differentiation of adenomatous and hyperplastic diminutive colorectal polyps during analysis of unaltered videos of standard colonoscopy using a deep learning model. Gut 68, 94–100 (2019). sourceExperimental — accuracy not yet measured
Split into 2 atoms — 1 confirmed, 1 partially supported, 0 disputed, 0 misattributed, 0 unverifiable. Expand the claim to see per-atom verdicts.
- Supportedcites [29] Xu, Y. et al. Comparison of diagnostic performance between convolutional neural networks and human endoscopists for diagnosis of colorectal polyp: A systematic review and meta-analysis. PLoS One 16, e0246892. https://doi.org/10.1371/journal.pone.0246892 (2021). source
The Introduction says the study compares CNN diagnostic performance with that of human endoscopists, and the Results report performance measures for both. This supports the physician-comparison part of the citing sentence, where this citation is placed. The society-criteria part has a separate citation group and is not attributed to this source. (LLM, conf=0.94)
- Partly supportedcites [30] Kudo, S.-E. et al. Artificial intelligence and computer-aided diagnosis for colonoscopy: where do we stand now? Transl. Gastroenterol. Hepatol. 6 (2021). sourceExperimental — accuracy not yet measured
Split into 2 atoms — 0 confirmed, 1 partially supported, 0 disputed, 0 misattributed, 1 unverifiable. Expand the claim to see per-atom verdicts.
- Partly supportedcites [31] ASGE Technology Committee et al. ASGE Technology Committee systematic review and meta-analysis assessing the ASGE PIVI thresholds for adopting real-time endoscopic assessment of the histology of diminutive colorectal polyps. Gastrointest. Endosc. 81 (2015). sourceExperimental — accuracy not yet measured
The Discussion states that ASGE PIVI established performance thresholds for adopting real-time optical assessment of diminutive colorectal polyps, and this review assesses imaging technologies against those thresholds. It does not establish that previous AI-based CADx studies evaluated their performance against those criteria; the technologies analyzed here are endoscopic imaging methods such as NBI, i-SCAN, and FICE. (LLM, conf=0.86)
- Not checked — no full text of the sourcecites [32] Berzin, T. M. et al. Position statement on priorities for artificial intelligence in GI endoscopy: A report by the ASGE Task Force. Gastrointest. Endosc. 92, 951–959. https://doi.org/10.1016/j.gie.2020.06.035 (2020). source
- Not checked — no full text of the sourcecites [33] Barua, I. et al. Real-time artificial intelligence-based optical diagnosis of neoplastic polyps during colonoscopy. NEJM Evid. 1 (2022). source
- Not checked — no full text of the sourcecites [34] Hassan, C., Balsamo, G., Lorenzetti, R., Zullo, A. & Antonelli, G. Artificial intelligence allows leaving-in-situ colorectal polyps. Clin. Gastroenterol. Hepatol.https://doi.org/10.1016/j.cgh.2022.04.045 (2022). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
Every source the paper cites for this claim was checked and supports it.
In the paper
“what is envisaged is teaming humans together with artificial intelligence to exploit the advantages of hybrid intelligence2,3.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
What the sources say
- Supportedcites [2] Dellermann, D. et al. The future of human–AI collaboration: A taxonomy of design knowledge for hybrid intelligence systems. arXiv:2105.03354 (2021). source
Section 2.3 (Hybrid Intelligence) explicitly envisions systems that combine human and artificial intelligence, using their complementary strengths to achieve better results together than either could alone. This supports the cited paraphrase about teaming humans with AI to gain the advantages of hybrid intelligence. (LLM, conf=0.94)
- Supportedcites [3] Akata, Z. et al. A research agenda for hybrid intelligence: Augmenting human intellect with collaborative, adaptive, responsible, and explainable artificial intelligence. Computer 53, 18–28 (2020). source
In the opening section, the paper envisions mixed teams in which humans and machines cooperate to achieve shared goals. The 'What Is Hybrid Intelligence?' section says this combination can achieve goals unreachable by either alone. Page numbers are not provided in our copy. (LLM, conf=0.94)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“over-reliance or under-reliance on ai, regard a general attitude towards support systems, which is wrong when decoupled from considerations on the relative informativeness of the ai39,41,42.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
What the sources say
- Supportedcites [39] Benda, N. C., Novak, L. L., Reale, C. & Ancker, J. S. Trust in AI: Why we should be designing for APPROPRIATE reliance. J. Am. Med. Inform. Assoc. 29, 207–212. https://doi.org/10.1093/jamia/ocab238 (2022). source
In the Introduction’s model of appropriate reliance, the paper says reliance should match the AI’s capabilities. Its table on trust calibration adds that trust should be higher for better-performing systems and lower for poorer-performing ones, supporting the claim that reliance should not be judged apart from the AI’s informativeness. (LLM, conf=0.90)
- Partly supportedcites [41] Medow, M. A., Arkes, H. R. & Shaffer, V. A. Are residents’ decisions influenced more by a decision aid or a specialist’s opinion? A randomized controlled trial. J. Gen. Intern. Med. 25, 316–320. https://doi.org/10.1007/s11606-010-1251-y (2010). sourceExperimental — accuracy not yet measured
The Discussion says disregarding advice solely on the basis of confidence may be ill-advised, and cautions that the management decision studied had no indisputably correct answer. This supports caution about judging reliance in isolation, but the paper does not establish the broader claim that both over- and under-reliance on AI are wrong unless assessed against the AI’s relative informativeness. (LLM, conf=0.78)
- Partly supportedcites [42] Rubin, D. L. Artificial intelligence in imaging: The radiologist’s role. J. Am. Coll. Radiol. 16, 1309–1317. https://doi.org/10.1016/j.jacr.2019.05.036 (2019). sourceExperimental — accuracy not yet measured
In “Maintaining radiologist expertise” (page not provided), Rubin warns that blindly accepting AI output can lead radiologists astray, particularly when an algorithm performs poorly on unusual cases. “Evaluation of AI tools” also urges testing performance on local data. The paper does not address under-reliance or frame the issue as a general attitude that must be judged against AI’s informativeness relative to the user’s. (LLM, conf=0.85)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Supported
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“algorithmic transparency has been sometimes advocated as pivotal for promoting an effective interaction with ai6,9,36”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
What the sources say
- Not checked — no full text of the sourcecites [6] Gretton, C. Trust and transparency in machine learning-based clinical decision support. In Human and Machine Learning 279–292 (Springer, 2018). source
- Supportedcites [9] Ghassemi, M., Oakden-Rayner, L. & Beam, A. L. The false hope of current approaches to explainable artificial intelligence in health care. Lancet Digit. Health 3, e745–e750 (2021). source
The Introduction (page unavailable) reports a growing chorus calling for explainable AI in health care and recommendations that AI be explainable to clinical users. This supports the claim that transparency has been advocated to help people work with AI; the paper does not itself endorse current explanations as effective. (LLM, conf=0.86)
- Not matchedcites [36] WHO. Ethics and Governance of Artificial Intelligence for Health: WHO Guidance (World Health Organization, 2021).
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“| 3. Effectiveness | | 3.48 [3.07, 3.98] |”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Statistical analyses
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“| 4. Safety | | 0.54 [0.48, 0.62] |”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Statistical analyses
plaindirect- Asserted: unclear — It is unclear whether the authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The benefits on accuracy were stronger for non-experts (also given their lower baseline), making their performance with ai assistance similar to that of experts without assistance.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“experts were less able than non-experts to discriminate between good and bad ai advice: both efficacy and safety are higher in non-experts than in experts (Table 5).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We showed that endoscopists consider and are substantially influenced by ai opinion.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Similar results were obtained in a related analysis on confidence scores (see Appendix B.3).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“no differences were present in the relative trust towards ai in the two groups: both groups had a slightly higher average confidence towards ai as compared to themselves (see Fig. B.11 in Appendix).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“endoscopists can separate the good from the bad ai advice, accepting selectively more the former than the latter, as shown by a higher efficacy than safety index.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“in S2 non-experts increased both their specificity and sensitivity, whereas experts increased only their sensitivity (see Appendix B.5).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > Additional analyses: explaining endoscopist behavior
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“when an automated algorithm interprets the output, the ai accuracy is 84.5% when the label “uncertain” is excluded, while it is 79.3% when “uncertain” is considered an error.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results > ai performance
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In the present case study, the use of ai proved effective and safe.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Artificial Intelligence systems are increasingly recognized as a precious tool for improving medical-decision making1.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Introduction
What the sources say
- Not checked — no full text of the sourcecites [1] Topol, E. J. High-performance medicine: The convergence of human and artificial intelligence. Nat. Med. 25, 44–56 (2019). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Our predictions were pre-registered before the data gathering, together with the study plan, the statistical models, and the analyses (preregistration is available at https://osf.io/y9at5).”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The study was approved by the local Institutional Review Board (Comitato Etico Lazio 1, prot. 611/CE Lazio1) and conducted following the Declaration of Helsinki.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Study design and participants
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In qualitative Bayesian terms, the ai output is a further piece of information that should be integrated to revise the endoscopist’s diagnosis, not differently as it would happen by considering an “informed opinion” volunteered by a human colleague with a slightly different expertise profile.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“For evaluating human and AI performance, we considered the histopathological diagnosis of each lesion as ground truth.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Procedure and data collection
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“All participants provided written informed consent.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Study design and participants
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Incoming visual information is compared to previously stored knowledge about a finite set of possible diagnoses in a Bayesian-like procedure that revises the endoscopist’s confidence toward those diagnoses.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Introduction
What the sources say
- Not matchedcites [25] Griffiths, T. L., Kemp, C. & Tenenbaum, J. B. Bayesian models of cognition. In The Cambridge Handbook of Computational Psychology (Cambridge University Press, 2008).
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not checked — no full text of the sourcecites [26] Anderson, J. R. The adaptive nature of human categorization. Psychol. Rev. 98, 409 (1991). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Not matched
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“All methods were carried out, and results were reported following STROBE guidelines and regulations.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Study design and participants
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“At least two weeks passed from the conclusion of the evaluation of one batch in S1 and the evaluation of the same batch in S2 to avoid memory effects.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Procedure and data collection
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The above four sets of odds ratios are obtained as the result of logistic regression models that account for lesion- and endoscopist- specific random effects.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Statistical analyses
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In other words, endoscopists could not fully escape from the negative consequences of a wrong ai advice (i.e., is less than 1), but this was more than compensated by their stronger tendency to accept a correct ai advice.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In this way, belief revision turned out to be a sound practice in Bayesian terms, resulting in overall increased accuracy of the human–ai hybrid team.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: A Bayesian decision-maker that weighs each opinion over its estimated reliability is an appropriate normative model for how endoscopists should integrate their own opinion with the ai's.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“When these enabling conditions are met, hybrid decision-making is an effective and appropriate diagnostic approach.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our results could generalize to different medical settings.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“in many scenarios ai cannot (or should not) substitute the human professional1,36.”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Discussion
What the sources say
- Not checked — no full text of the sourcecites [1] Topol, E. J. High-performance medicine: The convergence of human and artificial intelligence. Nat. Med. 25, 44–56 (2019). source
- Not matchedcites [36] WHO. Ethics and Governance of Artificial Intelligence for Health: WHO Guidance (World Health Organization, 2021).
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. It may state two separate claims as one.
The paper relies on this without support.
No previous experimental study addressed the inner dynamics of AI-supported MDs' beliefs revision.
“To our knowledge, no previous experimental study addressed the inner dynamics of ai-supported mds’ beliefs revision.”
The paper relies on this without support.
The critical parameters collected (MDs' opinion, confidence, interpretation of AI output, and perceived reliability of each AI advice) were ignored in previous studies on AI medical devices.
“These parameters were ignored in previous studies on ai medical devices.”
The paper relies on this without support.
A Bayesian decision-maker that weighs each opinion over its estimated reliability is an appropriate normative model for how endoscopists should integrate their own opinion with the ai's.
“An intuitive Bayesian decision-maker would weigh each opinion over its estimated reliability.”
The paper relies on this without support.
Endoscopists' optical diagnosis is a psychological categorization process in which confidence is revised in a Bayesian-like manner.
“Endoscopists’ optical diagnosis is a psychological categorization process.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Previous generations of non-LLM AI systems can improve human management decisions in some situations, especially when a human user treats an AI suggestion as a second opinion.14”
From Large Language Model Influence on Management Reasoning: A Randomized Controlled Trial (2024) · cites this paper as [14]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“The effect on experts was smaller, but it still held significance thanks to the study's high power.”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Crucially, all endoscopists were more likely to accept AI advice when it was correct than when it was wrong.”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Furthermore, the performance of available CADx systems is comparable, if not inferior, to that of experienced endoscopists [66 , 94-96] .”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Such intuitive assessment predicted AI accuracy on the specific lesion, thus allowing endoscopists to accept only good advice [66] .”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
Experimental — accuracy not yet measured
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Endoscopists generated an intuitive assessment of AI opinion's quality on a lesion-by-lesion basis, likely based on subtle features of the AI output like its temporal stability.”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“This limited impact may stem from the absence of standardized workflows, the complexity of deep learning algorithms, and nuanced interactions between artificial intelligence (AI) and human operators.17”
From Structured Integration of an Artificial Intelligence-Based System for the Optical Diagnosis of Colorectal Polyps (2026) · cites this paper as [17]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“First, it may prevent the formation of reliable case-by-case expectations of AI accuracy [65 , 66] .”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
The cited source says what the claim attributes to it.
In the citing paper
“This remarkable ability to discern the quality of AI opinion significantly improved the integrated human-AI decision accuracy, especially among non-experts.”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
The cited source says what the claim attributes to it.
In the citing paper
“The study revealed that the AI output substantially influenced both groups of endoscopists.”
From Enhancing human-AI collaboration: The case of colonoscopy (2024) · cites this paper as [66]
The cited source says what the claim attributes to it.
In the citing paper
“Previously, it was shown that CADx affected nonexperts more than experts.27”
From Appropriate trust in artificial intelligence for the optical diagnosis of colorectal polyps: the role of human/artificial intelligence interaction (2024) · cites this paper as [27]
The cited source says what the claim attributes to it.
In the citing paper
“Reverberi et al 27 showed that CADx advice was followed more often when the CADx prediction was correct compared to when the CADx prediction was incorrect.27”
From Appropriate trust in artificial intelligence for the optical diagnosis of colorectal polyps: the role of human/artificial intelligence interaction (2024) · cites this paper as [27]
The cited source says what the claim attributes to it.
In the citing paper
“These results are in concordance with previous results and emphasize that endoscopists take the CADx prediction into consideration (even when they might not change their eventual diagnosis).27”
From Appropriate trust in artificial intelligence for the optical diagnosis of colorectal polyps: the role of human/artificial intelligence interaction (2024) · cites this paper as [27]
In the citing paper
“The integration of human and AI judgment led to superior performance compared to either alone, highlighting effective human-AI collaboration dynamics in medical decision-making (109).”
From The impact of generative artificial intelligence on socioeconomic inequalities and policy making (2024) · cites this paper as [109]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Procedure and data collection
“using 3 forced-choice response options: “Adenoma”, “Non-Adenoma”, and “Uncertain””
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Procedure and data collection
“| Perceived ai diagnosis | The endoscopists’ interpretation of the ai dynamic output in S2. It takes the following values: “Adenoma”, “Non-Adenoma”, “Uncertain”, and “I am not sure/I did not notice the output of the ai” |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Procedure and data collection
“| Accuracy of the perceived ai diagnosis | A binary variable indicating whether each lesion is correctly diagnosed by the ai. We considered the ai diagnosis perceived by the endoscopist. “Uncertain” and “not sure/not notice” were excluded from the computation |”
§ Experimental evidence of effective human–AI collaboration in medical decision-making > Methods > Procedure and data collection
“| Accuracy of the perceived ai diagnosis | A binary variable indicating whether each lesion is correctly diagnosed by the ai. We considered the ai diagnosis judged by the endoscopist. Classifications of the ai output as “Uncertain” and “not sure/not notice” were conservatively considered errors |”
Citations
Cites
Fitting Linear Mixed-Effects Models Using lme4
Bates, D., Mächler, M., Bolker, B., & Walker, S. (2015) · Journal of Statistical Software · doi:10.18637/jss.v067.i01 · Cited by 86,835
Proceedings of IEEE Conference on Computer Vision and Pattern Recognition
(1993) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.1993.341010 · Cited by 14,475
High-performance medicine: the convergence of human and artificial intelligence
Topol, E. J. (2019) · Nature Medicine · doi:10.1038/s41591-018-0300-7 · Cited by 10,450
Deep neural networks are easily fooled: High confidence predictions for unrecognizable images
Nguyen, A., Yosinski, J., & Clune, J. (2015) · 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2015.7298640 · Cited by 3,258
Algorithm aversion: People erroneously avoid algorithms after seeing them err.
Dietvorst, B. J., Simmons, J. P., & Massey, C. (2015) · Journal of Experimental Psychology: General · doi:10.1037/xge0000033 · Cited by 3,232
The false hope of current approaches to explainable artificial intelligence in health care
Ghassemi, M., Oakden-Rayner, L., & Beam, A. L. (2021) · The Lancet Digital Health · doi:10.1016/s2589-7500(21)00208-9 · Cited by 1,724
Dietvorst, B. J., Simmons, J. P., & Massey, C. (2018) · Management Science · doi:10.1287/mnsc.2016.2643 · Cited by 1,230
Nagendran, M., Chen, Y., Lovejoy, C. A., Gordon, A. C., Komorowski, M., Harvey, H., Topol, E. J., Ioannidis, J. P. A., Collins, G. S., & Maruthappu, M. (2020) · BMJ · doi:10.1136/bmj.m689 · Cited by 1,152
The adaptive nature of human categorization.
Anderson, J. R. (1991) · Psychological Review · doi:10.1037/0033-295x.98.3.409 · Cited by 1,069
Zhang, Y., Liao, Q. V., & Bellamy, R. K. E. (2020) · Proceedings of the 2020 Conference on Fairness, Accountability, and Transparency · doi:10.1145/3351095.3372852 · Cited by 895
Research works printed but not linked: 1
- Griffiths, T. L., Kemp, C. & Tenenbaum, J. B. Bayesian models of cognition. In The Cambridge Handbook of Computational Psychology (Cambridge University Press, 2008).
Cited by
Sorted by citations
Items 201–241 of 241
Addressing Challenges of Science Assessment with Artificial Intelligence
Liu, L., Haudek, K. C., Zhaı, X., Nehm, R. H., & Neumann, K. (2026) · Springer eBooks · doi:10.1007/978-3-032-16871-9_9
Bercovich, E., & Ackerman, R. (2026) · Radiology · doi:10.1148/radiol.252834
Xu, T., Liu, Z., Li, L., Valdres, R., & Walker, M. A. (2026) · American Journal of Hospice and Palliative Medicine® · doi:10.1177/10499091261456197
Human-AI Collaboration in Leadership and Decision Making
Kumar, P., & Kumar, S. (2026) · Advances in computational intelligence and robotics book series · doi:10.4018/979-8-3373-6650-0.ch004 · Cited by 1
Gewald, H., & Faußer, S. (2026) · Journal of Information Technology · doi:10.1177/02683962261462966
Human-AI dyads in radiology: insights from human factors research
Liew, C. J. Y., & Sridharan, S. (2026) · Discover Artificial Intelligence · doi:10.1007/s44163-026-01568-7
Saoud, L. S., & Qureshi, O. A. (2026) · Communications in computer and information science · doi:10.1007/978-3-032-28819-6_31
Introduction to the Special Issue on Human and Machine Intelligence
Goldstone, R. L. (2026) · Current Directions in Psychological Science · doi:10.1177/09637214261450881
Benchmarking large language models against practicing clinicians on psychopathological assessment
Lenz, E., Naamanka, J., Trabert, W., Bottlender, R., Malchow, B., Meyer‐Lindenberg, A., Gradinger, T., & Schwarz, E. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02852-7
Ahn, Y., & Ha, T. (2026) · Human Factors and Ergonomics in Manufacturing & Service Industries · doi:10.1002/hfm.70054
Network Orchestration Framework Design Using AI-Driven Automation and Cybersecurity
Annahdi, T., Alsumayt, A., & Alshammari, M. (2026) · Future Internet · doi:10.3390/fi18080394
Do people rely on ChatGPT more than their peers to detect deepfake news?
Fu, Y., & Hanaki, N. (2026) · Journal of Economic Interaction and Coordination · doi:10.1007/s11403-026-00490-6 · Cited by 1
Angioni, D., & Bello, F. D. (2026) · AboutOpen · doi:10.33393/ao.2026.3940 · Cited by 1
Intelligent Automation Improved Efficiency in Pharmacovigilance Safety Signal Assessment
Warner, J., Souza‐Teodoro, L. H., Jardim, A. P., & Albera, C. (2026) · Clinical Pharmacology & Therapeutics · doi:10.1002/cpt.70409
Chen, L., Huang, B., & Ahmad, S. N. B. (2026) · Journal of Retailing and Consumer Services · doi:10.1016/j.jretconser.2026.105004
Rosbach, E., Ammeling, J., Bertram, C., Riener, A., & Aubreville, M. (2026) · Veterinary Pathology · doi:10.1177/03009858261472493
Fox, B. T., Balaji, A. K., Seger, P. J., Glazer, R. S., Nordin, A. B., Himidan, S. A., Yang, G., Fabiano, T., Tung, K. H.-Y., Schwaitzberg, S. D., et al. (2026) · Journal of Pediatric Surgery · doi:10.1016/j.jpedsurg.2026.163385
The Digital Pharmacist Proxy and the Clinical Acts That Must Remain Human
Petrova, E., Georgiev, I., Stoyanov, N., & Kolev, P. (2026) · Archives of Pharmacy Practice · doi:10.51847/pn0idcypwh
Hu, H., Ran, L. I., Yin, Y., Liu, Y., & Wang, X. (2026) · Frontiers in Industrial Engineering · doi:10.3389/fieng.2026.1854270
Impacts of AI decision support on conversational strategies of emergency call-takersPreprint
Shrestha, A., Shao, R., Byrne, K. A., & Fan, C. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.7358581
Mızrak, F., & Karakaya, T. (2026) · Data · doi:10.3390/data11090215
Cheng, R., Sun, R., & Tang, W. (2026) · Systems · doi:10.3390/systems14091081
Kerstan, S., Grote, G., & Schmutz, J. B. (2026) · Human Factors The Journal of the Human Factors and Ergonomics Society · doi:10.1177/00187208261477411
Noessel, C. (2026) · AI Magazine · doi:10.1002/aaai.70096
Effects of proactivity, autonomy, and transparency on user perception in human-AI agent interactions
Liu, N., & Zuo, Y. (2026) · International Journal of Industrial Ergonomics · doi:10.1016/j.ergon.2026.104058
Dzieran, R., Dağli, C. H., & Marley, R. J. (2026) · Procedia Computer Science · doi:10.1016/j.procs.2026.08.182
Deng, C., Yu, Q., Wang, Y., & Kong, F. (2026) · Journal of service management · doi:10.1108/josm-08-2025-0421
Performance of large language models in ambiguous treatment scenarios of early breast cancer
Oseledchyk, A., Weber, W. P., & Kasenda, B. (2026) · The Breast · doi:10.1016/j.breast.2026.104932
Ensemble of deep architectures for SWARM AI-based decision-making
Pedraza, A., Montealegre-Macias, P., Mateos-Aparicio-Ruiz, I., Déniz, Ó., & Bueno, G. (2026) · Information Sciences · doi:10.1016/j.ins.2026.124200
Rethinking Objectivity in Clinical AI: A Qualitative Study of Concussion Evaluators
Zaidi, A. M., Saw, J. J.-W., Fu, L., Arneson, K., Kim, I., Cross, A., & Karahalios, K. G. (2026) · Proceedings of the ACM on Human-Computer Interaction · doi:10.1145/3816992
Deen, M., King, K., Awan, M., Inam, E., & Yan, R. (2026) · INNOVAPATH · doi:10.63501/be3qrc22
Ohmoto, Y., Terada, K., Iwanaga, R., & Kumazaki, H. (2026) · JMIR Formative Research · doi:10.2196/98367
Electronic Health Record Workflows in Acute Care Surgery: Ethnographic Study
Lee, A., Narayanan, D., Staudenmayer, K., Nassar, A. K., & Hameed, S. M. (2026) · JMIR Medical Informatics · doi:10.2196/89846
Artificial intelligence in biomedical visualization and education: a narrative review
Wang, X., Song, L., Liu, B., Chen, J., & Zhao, H. (2026) · Frontiers in Public Health · doi:10.3389/fpubh.2026.1956708
Luo, W., & Lu, G. (2026) · Frontiers in Public Health · doi:10.3389/fpubh.2026.1971194
Machain, J. D. J. R., Lizárraga, D. M., García, V. M. M., Romero, Y. D., Ramírez, M. I. T., & Lizarraga, P. A. V. (2026) · SAP Engineering and Industry · doi:10.62486/ei202670
Assistance curve analysis: evaluating the clinical value of AI-assisted decision makingPreprint
Alqumbaey, M., & Nasher, Y. M. (2026) · Research Square · doi:10.21203/rs.3.rs-10899895/v1
Gallazzi, M., & Spoladore, D. (2026) · IFIP advances in information and communication technology · doi:10.1007/978-3-032-41230-0_36
EchoWeave: Designing an AI-Driven Conversational Agent System for Product Design Research Interviews
Chen, X., Zhang, L., Xu, L., Bao, L., García, C., & Sareh, P. (2026) · International Journal of Human-Computer Interaction · doi:10.1080/10447318.2026.2744496
Cyberlogic-enabled Thinking Space: a closed-loop human-cyber cognitive architecture in CPST
Chen, R., Zhou, L., Ding, J., & Ning, H. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2026.1899109
Wang, X., Lo, C., Lo, W.-H., Wang, M., & Huang, G. (2026) · Proceedings of the Human Factors and Ergonomics Society Annual Meeting · doi:10.1177/10711813261485995
Metadata
- Authors
- Reverberi, C., Rigon, T., Solari, A., Hassan, C., Cherubini, P., GI Genius CADx Study Group, Antonelli, G., Awadie, H., Bernhofer, S., Carballal, S., Dinis-Ribeiro, M., Fernández-Clotett, A., Esparrach, G. F., Gralnek, I., Higasa, Y., Hirabayashi, T., Hirai, T., Iwatate, M., Kawano, M., Mader, M., Maieron, A., Mattes, S., Nakai, T., Ordas, I., Ortigão, R., Zúñiga, O. O., Pellisé, M., Pinto, C., Riedl, F., Sánchez, A., Steiner, E., Tanaka, Y., & Cherubini, A.
- Affiliations
- University of Milano-Bicocca (IT)
- Humanitas University (IT)
- University of Pavia (IT)
- Emek Medical Center (IL)
- Universitätsklinikum St. Pölten (AT)
- IPO Porto (PT)
- Hyogo Prefectural Cancer Center (JP)
- Sugita Genpaku Memorial Obama Municipal Hospital (JP)
- Japanese Red Cross Kobe Hospital (JP)
- Kobe University Hospital (JP)
- Corresponding author
- Reverberi, Carlo
- Cherubini, Andrea
- ORCID
- Reverberi, Carlo
- Rigon, Tommaso
- Solari, Aldo
- Hassan, Cesare
- Cherubini, Paolo
- Antonelli, Giulio
- Awadie, Halim
- Bernhofer, Sebastian
- Carballal, Sabela
- Dinis-Ribeiro, Mário
- Gralnek, Ian
- Hirai, Tatsuki
- Iwatate, Mineo
- Kawano, Miki
- Mader, Markus
- Maieron, Andreas
- Ortigão, Raquel
- Riedl, Florian
- Sánchez, Ariadna
- Steiner, Emanuel
- Tanaka, Yukari
- Cherubini, Andrea
- Venue
- Scientific Reports
- Published
- 2022-09-02
- Volume
- 12
- Issue
- 1
- Pages
- 14952-14952
- ISSN
- 2045-2322 (ISSN-L)
- PMC
- PMC9440124
- OpenAlex
- W4294243134
- Semantic Scholar
- 1bfc69cd9a06be740ea6a0f421e0852a90856220
- Cited by
- 281
- References
- 46
- Citations by year
- 2026: 103 · 2025: 99 · 2024: 47 · 2023: 30 · 2022: 1
- FWCI
- 12.59
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- Scientific Reports (publishedVersion, cc-by)
- Research Square (submittedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- BOA (University of Milano-Bicocca) (submittedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- ARCA (Università Ca' Foscari Venezia) (submittedVersion, cc-by-nc-nd)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Social Sciences › Human Factors and Ergonomics › Human-Automation Interaction and Safety
- Health Sciences › Medicine › Family Practice › Clinical Reasoning and Diagnostic Skills
- Keywords
- human-AI collaboration, clinical decision-making, colonoscopy, endoscopists, AI-assisted diagnosis, lesion classification, trust in AI, Bayesian integration, reliability estimation, deep learning
- MeSH terms
- Clinical Decision-Making, Artificial Intelligence, Bayes Theorem, Humans
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
