

The DOI matches its Crossref record; 93 of the 93 references it cites were found in a registry or an index.
WavCaps: A ChatGPT-Assisted Weakly-Labelled Audio Captioning Dataset for Audio-Language Multimodal Research
Open accessAbstract
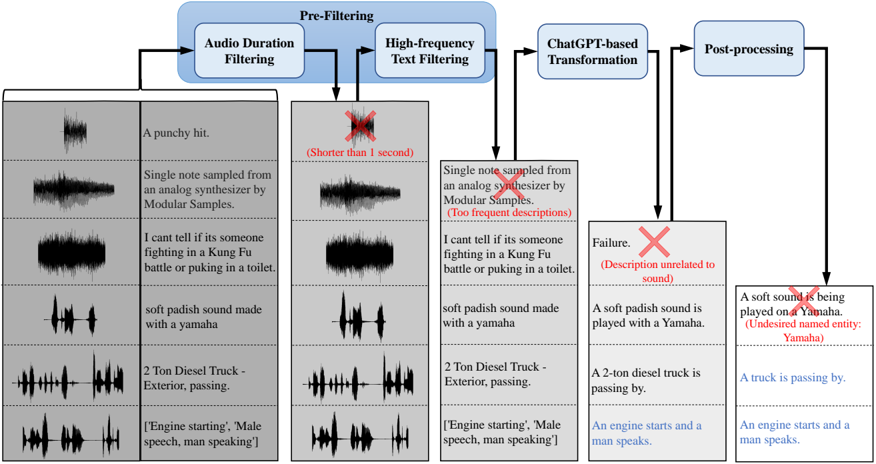
The advancement of audio-language (AL) multimodal learning tasks has been significant in recent years, yet the limited size of existing audio-language datasets poses challenges for researchers due to the costly and time-consuming collection process. To address this data scarcity issue, we introduceWavCaps, the first large-scale weakly-labelled audio captioning dataset, comprising approximately 400 k audio clips with paired captions. We sourced audio clips and their raw descriptions from web sources and a sound event detection dataset. However, the online-harvested raw descriptions are highly noisy and unsuitable for direct use in tasks such as automated audio captioning. To overcome this issue, we propose a three-stage processing pipeline for filtering noisy data and generating high-quality captions, where ChatGPT, a large language model, is leveraged to filter and transform raw descriptions automatically. We conduct a comprehensive analysis of the characteristics of WavCaps dataset and evaluate it on multiple downstream audio-language multimodal learning tasks. The systems trained on WavCaps outperform previous state-of-the-art (SOTA) models by a significant margin. Our aspiration is for the WavCaps dataset we have proposed to facilitate research in audio-language multimodal learning and demonstrate the potential of utilizing large language models (LLMs) to enhance academic research.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“There have been similar and successful use cases of LLMs for general audio understanding [18] and music generation [19].”
From LP-MusicCaps: LLM-Based Pseudo Music Captioning (2023) · cites this paper as [18]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Finally, Mel et al.. [18] introduce WavCaps, a 400k audio captioning dataset using ChatGPT [23].”
From LP-MusicCaps: LLM-Based Pseudo Music Captioning (2023) · cites this paper as [18]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
LeCun, Y., Bengio, Y., & Hinton, G. (2015) · Nature · doi:10.1038/nature14539 · Cited by 84,126
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Learning representations by back-propagating errors
Rumelhart, D. E., Hinton, G. E., & Williams, R. J. (1986) · Nature · doi:10.1038/323533a0 · Cited by 31,892
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
High-Resolution Image Synthesis with Latent Diffusion Models
Rombach, R., Blattmann, A., Lorenz, D., Esser, P., & Ommer, B. (2022) · 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52688.2022.01042 · Cited by 20,302
Learning Transferable Visual Models From Natural Language Supervision
Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., et al. (2021) · arXiv · doi:10.48550/arxiv.2103.00020 · Cited by 15,293
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929
(2004) · Cited by 9,718
Lewis, M., Liu, Y., Goyal, N., Ghazvininejad, M., Mohamed, A., Levy, O., Stoyanov, V., & Zettlemoyer, L. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.703 · Cited by 8,821
Denoising Diffusion Probabilistic Models
Ho, J., Jain, A., & Abbeel, P. (2020) · arXiv · doi:10.48550/arxiv.2006.11239 · Cited by 8,712
CIDEr: Consensus-based image description evaluation
Vedantam, R., Zitnick, C. L., & Parikh, D. (2015) · 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2015.7299087 · Cited by 4,845
VQA: Visual Question Answering
Antol, S., Agrawal, A., Lu, J., Mitchell, M., Batra, D., Zitnick, C. L., & Parikh, D. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.279 · Cited by 4,487
(2005) · Cited by 4,152
Kincaid, J. P., Fishburne, Jr., Robert P., R., Richard L., C., & Brad, S. (1975) · doi:10.21236/ada006655 · Cited by 3,497
Audio Set: An ontology and human-labeled dataset for audio events
Gemmeke, J. F., Ellis, D. P. W., Freedman, D., Jansen, A., Lawrence, W., Moore, R. C., Plakal, M., & Ritter, M. (2017) · 2017 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2017.7952261 · Cited by 3,134
Hierarchical Text-Conditional Image Generation with CLIP Latents
Ramesh, A., Dhariwal, P., Nichol, A., Chu, C., & Chen, M. (2022) · arXiv · doi:10.48550/arxiv.2204.06125 · Cited by 2,511 · cited 1×
“While AL research is relatively young, vision-language (VL) multimodal learning [20], the counterpart of AL multimodal learning, has been studied for decades and has contributed to the success of many vision-language applications, such as cross-modal search [21], [22], image and video captioning [23], [24], text-to-im…”
BackgroundYoung, P., Lai, A., Hodosh, M., & Hockenmaier, J. (2014) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00166 · Cited by 2,439
SPICE: Semantic Propositional Image Caption Evaluation
Anderson, P., Fernando, B., Johnson, M., & Gould, S. (2016) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-46454-1_24 · Cited by 1,986
Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision
Jia, C., Yang, Y., Xia, Y., Chen, Y.-T., Parekh, Z., Pham, H., Le, Q. V., Sung, Y., Li, Z., & Duerig, T. (2021) · arXiv · doi:10.48550/arxiv.2102.05918 · Cited by 1,977
A brief introduction to weakly supervised learning
Zhou, Z.-H. (2018) · National Science Review · doi:10.1093/nsr/nwx106 · Cited by 1,899
Conceptual Captions: A Cleaned, Hypernymed, Image Alt-text Dataset For Automatic Image Captioning
Sharma, P., Ding, N., Goodman, S., & Soricut, R. (2018) · Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p18-1238 · Cited by 1,879
Oscar: Object-Semantics Aligned Pre-training for Vision-Language Tasks
Li, X., Yin, X. P., Li, C., Zhang, P., Hu, X., Zhang, L., Wang, L., Hu, H., Li, D., Wei, F., et al. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-58577-8_8 · Cited by 1,791
Li, J., Li, D., Xiong, C., & Hoi, S. (2022) · arXiv · doi:10.48550/arxiv.2201.12086 · Cited by 1,741
Microsoft COCO Captions: Data Collection and Evaluation Server
Chen, X., Fang, H., Lin, T.-Y., Vedantam, R., Gupta, S., Dollar, P., & Zitnick, C. L. (2015) · arXiv · doi:10.48550/arxiv.1504.00325 · Cited by 1,614
Piczak, K. J. (2015) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/2733373.2806390 · Cited by 1,572
A Dataset and Taxonomy for Urban Sound Research
Salamon, J., Jacoby, C., & Bello, J. P. (2014) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/2647868.2655045 · Cited by 1,355
PANNs: Large-Scale Pretrained Audio Neural Networks for Audio Pattern Recognition
Kong, Q., Cao, Y., Iqbal, T., Wang, Y., Wang, W., & Plumbley, M. D. (2020) · IEEE/ACM Transactions on Audio, Speech, and Language Processing · doi:10.1109/taslp.2020.3030497 · Cited by 1,235
Self-citationAST: Audio Spectrogram Transformer
Gong, Y., Chung, Y.-A., & Glass, J. (2021) · Interspeech 2021 · doi:10.21437/interspeech.2021-698 · Cited by 1,159
Align before Fuse: Vision and Language Representation Learning with Momentum Distillation
Li, J., Selvaraju, R. R., Gotmare, A. D., Joty, S., Xiong, C., & Hoi, S. (2021) · arXiv · doi:10.48550/arxiv.2107.07651 · Cited by 1,078
Deep reinforcement learning from human preferences
Christiano, P., Leike, J., Brown, T. B., Martic, M., Legg, S., & Amodei, D. (2017) · arXiv · doi:10.48550/arxiv.1706.03741 · Cited by 1,058
Deep Modular Co-Attention Networks for Visual Question Answering
Zhou, Y., Yu, J., Cui, Y., Tao, D., & Tian, Q. C. (2019) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2019.00644 · Cited by 1,033
Unified Vision-Language Pre-Training for Image Captioning and VQA
Zhou, L., Palangi, H., Zhang, L., Hu, H., Corso, J., & Gao, J. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i07.7005 · Cited by 864
High-Resolution Image Synthesis with Latent Diffusion Models
Rombach, R., Blattmann, A., Lorenz, D., Esser, P., & Ommer, B. (2021) · arXiv · doi:10.48550/arxiv.2112.10752 · Cited by 737
Conceptual 12M: Pushing Web-Scale Image-Text Pre-Training To Recognize Long-Tail Visual Concepts
Changpinyo, S., Sharma, P. K., Ding, N., & Soricut, R. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00356 · Cited by 701
AudioLDM: Text-to-Audio Generation with Latent Diffusion ModelsPreprint
Liu, H., Chen, Z., Yuan, Y. G., Mei, X., Liu, X., Mandic, D. P., Wang, W., & Plumbley, M. D. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2301.12503 · Cited by 608
Self-citationFSD50K: An Open Dataset of Human-Labeled Sound Events
Fonseca, E., Favory, X., Pons, J., Font, F., & Serra, X. (2021) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2021.3133208 · Cited by 572
Vggsound: A Large-Scale Audio-Visual Dataset
Chen, H., Xie, W., Vedaldi, A., & Zisserman, A. (2020) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp40776.2020.9053174 · Cited by 507
Wu, Y., Chen, K., Zhang, T., Hui, Y., Berg-Kirkpatrick, T., & Dubnov, S. (2023) · ICASSP 2023 - 2023 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp49357.2023.10095969 · Cited by 459 · cited 7×
“Unlike traditional large language models such as T5 [54] used in LAION-Audio-630K [53], ChatGPT has been shown to excel at generating human-like responses to natural language prompts, and has garnered widespread attention for its powerful understanding, reasoning, and dialogue abilities.”
BackgroundMethodResultInfluentialCLAP Learning Audio Concepts from Natural Language Supervision
Elizalde, B., Deshmukh, S., Ismail, M. A., & Wang, H. (2023) · ICASSP 2023 - 2023 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp49357.2023.10095889 · Cited by 449
Improved Image Captioning via Policy Gradient optimization of SPIDEr
Liu, S., Zhu, Z., Ye, N., Guadarrama, S., & Murphy, K. (2017) · 2017 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.100 · Cited by 430
Acoustic Scene Classification: Classifying environments from the sounds they produce
Barchiesi, D., Giannoulis, D. A., Stowell, D., & Plumbley, M. D. (2015) · IEEE Signal Processing Magazine · doi:10.1109/msp.2014.2326181 · Cited by 423
Self-citationnocaps: novel object captioning at scale
Agrawal, H., Desai, K., Wang, Y., Chen, X., Jain, R., Johnson, M., Batra, D., Parikh, D., Lee, S., & Anderson, P. (2019) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00904 · Cited by 419
AudioLDM 2: Learning Holistic Audio Generation With Self-Supervised Pretraining
Liu, H., Yuan, Y., Liu, X., Mei, X., Kong, Q., Tian, Q., Wang, Y.-P., Wang, W., Wang, Y., & Plumbley, M. D. (2024) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2024.3399607 · Cited by 352
Self-citationAudioclip: Extending Clip to Image, Text and Audio
Guzhov, A., Raue, F., Hees, J., & Dengel, A. (2022) · ICASSP 2022 - 2022 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp43922.2022.9747631 · Cited by 330
Font, F., Roma, G., & Serra, X. (2013) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/2502081.2502245 · Cited by 321
Sound Event Detection: A tutorial
Mesaros, A., Heittola, T., Virtanen, T. I., & Plumbley, M. D. (2021) · IEEE Signal Processing Magazine · doi:10.1109/msp.2021.3090678 · Cited by 299
Self-citationHTS-AT: A Hierarchical Token-Semantic Audio Transformer for Sound Classification and Detection
Chen, K., Du, X., Zhu, B., Ma, Z., Berg-Kirkpatrick, T., & Dubnov, S. (2022) · ICASSP 2022 - 2022 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp43922.2022.9746312 · Cited by 294
Clotho: an Audio Captioning Dataset
Drossos, K., Lipping, S., & Virtanen, T. (2020) · ICASSP 2020 - 2020 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp40776.2020.9052990 · Cited by 285
Diffsound: Discrete Diffusion Model for Text-to-Sound Generation
Yang, D., Yu, J., Wang, H., Wang, W., Weng, C., Zou, Y., & Yu, D. (2023) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2023.3268730 · Cited by 284
Self-citationImageBERT: Cross-modal Pre-training with Large-scale Weak-supervised Image-Text DataPreprint
Qi, D., Su, L., Song, J. L., Cui, E., Bharti, T., & Sacheti, A. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2001.07966 · Cited by 255
Text-to-Audio Generation using Instruction Guided Latent Diffusion Model
Ghosal, D., Majumder, N., Mehrish, A., & Poria, S. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3612348 · Cited by 242
Wav2CLIP: Learning Robust Audio Representations from Clip
Wu, H.-H., Seetharaman, P., Kumar, K., & Bello, J. P. (2022) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp43922.2022.9747669 · Cited by 223
MusicLM: Generating Music From Text
Agostinelli, A., Denk, T. I., Borsos, Z., Engel, J., Verzetti, M., Caillon, A., Huang, Q., Jansen, A., Roberts, A., Tagliasacchi, M., et al. (2023) · arXiv · doi:10.48550/arxiv.2301.11325 · Cited by 183
Towards Safe Weakly Supervised Learning
Li, Y.-F., Guo, L.-Z., & Zhou, Z.-H. (2019) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2019.2922396 · Cited by 165
BEATs: Audio Pre-Training with Acoustic Tokenizers
Chen, S., Wu, Y., Wang, C., Liu, S., Tompkins, D., Chen, Z., & Wei, F. (2022) · arXiv · doi:10.48550/arxiv.2212.09058 · Cited by 131
AudioGen: Textually Guided Audio GenerationPreprint
Kreuk, F., Synnaeve, G., Polyak, A., Singer, U., Défossez, A., Copet, J., Parikh, D., Taigman, Y., & Adi, Y. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2209.15352 · Cited by 121
Multimodal research in vision and language: A review of current and emerging trends
Uppal, S., Bhagat, S., Hazarika, D., Majumder, N., Poria, S., Zimmermann, R., & Zadeh, A. (2021) · Information Fusion · doi:10.1016/j.inffus.2021.07.009 · Cited by 118
The Benefit of Temporally-Strong Labels in Audio Event Classification
Hershey, S., Ellis, D. P. W., Fonseca, E., Jansen, A., Liu, C., Moore, R. C., & Plakal, M. (2021) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp39728.2021.9414579 · Cited by 97
Separate What You Describe: Language-Queried Audio Source Separation
Liu, X., Liu, H., Kong, Q., Mei, X., Zhao, J., Huang, Q., Plumbley, M. D., & Wang, W. (2022) · Interspeech (USB) · doi:10.21437/interspeech.2022-10894 · Cited by 92
Self-citationWeakly Labelled AudioSet Tagging With Attention Neural Networks
Kong, Q., Yu, C., Xu, Y., Iqbal, T., Wang, W., & Plumbley, M. D. (2019) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2019.2930913 · Cited by 88
Self-citationAudio Retrieval With Natural Language Queries: A Benchmark Study
Koepke, A. S., Oncescu, A.-M., Henriques, J. F., Akata, Z., & Albanie, S. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3149712 · Cited by 87
Learning Audio-Video Modalities from Image Captions
Nagrani, A., Seo, P. H., Seybold, B., Hauth, A., Manén, S., Sun, C., & Schmid, C. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19781-9_24 · Cited by 82
Unsupervised Feature Learning Based on Deep Models for Environmental Audio Tagging
Xu, Y., Huang, Q., Wang, W., Foster, P., Sigtia, S., Jackson, P. J. B., & Plumbley, M. D. (2017) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2017.2690563 · Cited by 81
Self-citationChatBridge: Bridging Modalities with Large Language Model as a Language CatalystPreprint
Zhao, Z., Guo, L., Yue, T., Chen, S., Shao, S., Zhu, X., Yuan, Z., & Liu, J. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.16103 · Cited by 80
SALMONN: Towards Generic Hearing Abilities for Large Language Models
Tang, C., Yu, W., Sun, G., Chen, X., Tan, T., Li, W., Lu, L., Ma, Z., & Zhang, C. (2023) · arXiv · doi:10.48550/arxiv.2310.13289 · Cited by 67
On Metric Learning for Audio-Text Cross-Modal Retrieval
Mei, X., Liu, X., Sun, J., Plumbley, M. D., & Wang, W. (2022) · Interspeech (USB) · doi:10.21437/interspeech.2022-11115 · Cited by 63
Self-citationTemporal Reasoning via Audio Question Answering
Fayek, H. M., & Johnson, J. (2020) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2020.3010650 · Cited by 57
Automated audio captioning: an overview of recent progress and new challenges
Mei, X., Liu, X., Plumbley, M. D., & Wang, W. (2022) · EURASIP Journal on Audio Speech and Music Processing · doi:10.1186/s13636-022-00259-2 · Cited by 54
Self-citationAudio Caption: Listen and Tell
Wu, M., Dinkel, H., & Yu, K. (2019) · ICASSP 2019 - 2019 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2019.8682377 · Cited by 52
A Transformer-Based Audio Captioning Model with Keyword Estimation
Koizumi, Y., Masumura, R., Nishida, K., Yasuda, M., & Saito, S. (2020) · Interspeech (USB) · doi:10.21437/interspeech.2020-2087 · Cited by 45
Audio Captioning TransformerPreprint
Mei, X., Liu, X., Huang, Q., Plumbley, M. D., & Wang, W. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2107.09817 · Cited by 44
Self-citationGong, Y., Luo, H., Liu, A. H., Karlinsky, L., & Glass, J. (2023) · arXiv · doi:10.48550/arxiv.2305.10790 · Cited by 43
Auto-ACD: A Large-scale Dataset for Audio-Language Representation Learning
Sun, L., Xu, X., Wu, M., & Xie, W. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3681472 · Cited by 42
Prefix Tuning for Automated Audio Captioning
Kim, M., Kim, S.-B., & Oh, T.-H. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10096877 · Cited by 39
Clotho-AQA: A Crowdsourced Dataset for Audio Question Answering
Lipping, S., Sudarsanam, P., Drossos, K., & Virtanen, T. I. (2022) · European Signal Processing Conference (EUSIPCO) · doi:10.23919/eusipco55093.2022.9909680 · Cited by 34
UniAudio: An Audio Foundation Model Toward Universal Audio GenerationPreprint
Yang, D., Tian, J., Tan, X., Huang, R., Liu, S., Chang, X., Shi, J., Zhao, S., Bian, J., Zhao, Z., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.00704 · Cited by 33
Ye, Z., Wang, H., Yang, D., & Zou, Y.-X. (2021) · Workshop on Detection and Classification of Acoustic Scenes and Events · doi:10.48550/arxiv.2110.06100 · Cited by 31
Self-citationGazneli, A., Zimerman, G., Ridnik, T., Sharir, G., & Noy, A. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2204.11479 · Cited by 30
Audio Retrieval with WavText5K and CLAP Training
Deshmukh, S., Elizalde, B., & Wang, H. (2023) · Interspeech (USB) · doi:10.21437/interspeech.2023-1136 · Cited by 29
Crowdsourcing a Dataset of Audio Captions
Lipping, S., Drossos, K., & Virtanen, T. I. (2019) · Detection and Classification of Acoustic Scenes and Events Workshop (DCASE) · doi:10.33682/sezz-vd31 · Cited by 23
Leveraging Pre-trained BERT for Audio Captioning
Liu, X., Mei, X., Huang, Q., Sun, J., Zhao, J., Liu, H., Plumbley, M. D., Kılıç, V., & Wang, W. (2022) · European Signal Processing Conference (EUSIPCO) · doi:10.23919/eusipco55093.2022.9909761 · Cited by 22
Self-citationVisually-Aware Audio Captioning With Adaptive Audio-Visual Attention
Liu, X., Huang, Q., Mei, X., Liu, H., Kong, Q., Sun, J., Li, S., Ko, T., Zhang, Y., Tang, L. H. Y., et al. (2023) · Interspeech (USB) · doi:10.21437/interspeech.2023-914 · Cited by 22
Self-citationImproving Text-Audio Retrieval by Text-Aware Attention Pooling and Prior Matrix Revised Loss
Xin, Y., Yang, D., & Zou, Y. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10096972 · Cited by 22
Self-citationAutomated audio captioning by fine-tuning bart with audioset tags
Gontier, F., Serizel, R., & Cerisara, C. (2021) · HAL · Cited by 21
BLAT: Bootstrapping Language-Audio Pre-training based on AudioSet Tag-guided Synthetic Data
Xu, X., Zhang, Z., Zhou, Z., Zhang, P., Xie, Z., Wu, M., & Zhu, K. Q. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3613820 · Cited by 16
Acoustic Prompt Tuning: Empowering Large Language Models With Audition Capabilities
Liang, J., Liu, X., Wang, W., Plumbley, M. D., Phan, H., & Benetos, E. (2025) · IEEE Transactions on Audio Speech and Language Processing · doi:10.1109/taslpro.2025.3533375 · Cited by 16
Self-citationLP-MusicCaps: LLM-Based Pseudo Music Captioning
Doh, S., Choi, K., Lee, J., & Nam, J. (2023) · arXiv · doi:10.48550/arxiv.2307.16372 · Cited by 16
Xie, H., Räsänen, O. J., Drossos, K., & Virtanen, T. I. (2022) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp43922.2022.9747336 · Cited by 13
Interactive Audio-text Representation for Automated Audio Captioning with Contrastive LearningPreprint
Chen, C., Hou, N., Hu, Y., Zou, H., Qi, X., & Chng, E. S. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2203.15526 · Cited by 8
FeatureCut: An Adaptive Data Augmentation for Automated Audio Captioning
Ye, Z., Wang, Y., Wang, H., Yang, D., & Zou, Y. (2022) · Asia-Pacific Signal and Information Processing Association Annual Summit and Conference (APSIPA ASC) · doi:10.23919/apsipaasc55919.2022.9980325 · Cited by 7
Self-citation
Research works printed but not linked: 4
- Kim, 2019, AudioCaps: Generating captions for audios in the wild, 119
- Martin, 2021, Diversity and bias in audio captioning datasets, 90
- 10.5555/3524938.3525087 · DOI
- Han, 2021, Automated audio captioning with weakly supervised pre-training and word selection methods, 6
Cited by
Sorted by citations
A Comprehensive Overview of Large Language Models
Naveed, H., Khan, A. U., Qiu, S., Saqib, M., Anwar, S., Usman, M., Akhtar, N., Barnes, N., & Mian, A. (2025) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3744746 · Cited by 1,257
A survey on multimodal large language models
Yin, S., Fu, C., Zhao, S., Li, K., Sun, X., Xu, T., & Chen, E. (2024) · National Science Review · doi:10.1093/nsr/nwae403 · Cited by 893
A Survey of GPT-3 Family Large Language Models Including ChatGPT and GPT-4
Kalyan, K. S. (2024) · Natural Language Processing Journal · doi:10.1016/j.nlp.2023.100048 · Cited by 335
InternVideo2: Scaling Foundation Models for Multimodal Video Understanding
Wang, Y., Li, K., Li, X., Yu, J., He, Y., Chen, G., Pei, B., Zheng, R., Wang, Z., Shi, Y., et al. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73013-9_23 · Cited by 427
AudioLDM 2: Learning Holistic Audio Generation With Self-Supervised Pretraining
Liu, H., Yuan, Y., Liu, X., Mei, X., Kong, Q., Tian, Q., Wang, Y.-P., Wang, W., Wang, Y., & Plumbley, M. D. (2024) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2024.3399607 · Cited by 352
Self-citation
Metadata
- Authors
- Mei, X., Meng, C., Liu, H., Kong, Q., Ko, T., Zhao, C., Plumbley, M. D., Zou, Y., & Wang, W.
- Affiliations
- University of Surrey (GB)
- Johns Hopkins University (US)
- Chinese University of Hong Kong (HK)
- ByteDance (China) (CN)
- Peking University (CN)
- ORCID
- Venue
- IEEE/ACM Transactions on Audio, Speech, and Language Processing
- Published
- 2024
- Volume
- 32
- Pages
- 3339-3354
- ISSN
- 2329-9290 (ISSN-L)
- 2329-9304
- OpenAlex
- W4400033239
- Cited by
- 150
- References
- 92
- Citations by year
- 2026: 38 · 2025: 61 · 2024: 47
- FWCI
- 20.44
- Type
- journal article
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- IEEE/ACM Transactions on Audio Speech and Language Processing (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by-nc-nd)
- arXiv (Cornell University)
- Funders
- Engineering and Physical Sciences Research Council (EP/T019751/1)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Signal Processing › Music and Audio Processing
- Physical Sciences › Computer Science › Artificial Intelligence › Speech Recognition and Synthesis
- Keywords
- audio captioning, ChatGPT, large language models, data filtering, sound event detection, data scarcity
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
