

The DOI matches its Crossref record; 83 of the 88 references it cites were found in a registry or an index; 2 of the 74 sources its claims cite were checked for support.
Reporting and Methods in Clinical Prediction Research: A Systematic Review
Open accessAbstract
BACKGROUND: We investigated the reporting and methods of prediction studies, focusing on aims, designs, participant selection, outcomes, predictors, statistical power, statistical methods, and predictive performance measures. METHODS AND FINDINGS: We used a full hand search to identify all prediction studies published in 2008 in six high impact general medical journals. We developed a comprehensive item list to systematically score conduct and reporting of the studies, based on recent recommendations for prediction research. Two reviewers independently scored the studies. We retrieved 71 papers for full text review: 51 were predictor finding studies, 14 were prediction model development studies, three addressed an external validation of a previously developed model, and three reported on a model's impact on participant outcome. Study design was unclear in 15% of studies, and a prospective cohort was used in most studies (60%). Descriptions of the participants and definitions of predictor and outcome were generally good. Despite many recommendations against doing so, continuous predictors were often dichotomized (32% of studies). The number of events per predictor as a measure of statistical power could not be determined in 67% of the studies; of the remainder, 53% had fewer than the commonly recommended value of ten events per predictor. Methods for a priori selection of candidate predictors were described in most studies (68%). A substantial number of studies relied on a p-value cut-off of p<0.05 to select predictors in the multivariable analyses (29%). Predictive model performance measures, i.e., calibration and discrimination, were reported in 12% and 27% of studies, respectively. CONCLUSIONS: The majority of prediction studies in high impact journals do not follow current methodological recommendations, limiting their reliability and applicability.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This systematic review of 71 multivariable clinical prediction studies published in six high-impact general medical journals in 2008 found that most were predictor-finding studies and that key methodological and reporting recommendations were frequently not followed. Reporting was generally adequate for aims, participant selection, and predictor/outcome definitions, but poor for blinding, continuous predictors, power, missing data, multivariable result presentation, and model performance/validation.
Key findings
- Of 1,204 hand-searched articles, 71 met inclusion criteria: 51 were predictor-finding studies, 14 were model development studies (11 without and 3 with external validation), 3 were external validation studies, and 3 were impact studies; these 71 papers studied 135 models or sets of predictors.
- Statistical power was often inadequately reported: based on predictors in the final model, >10 events per variable occurred in 84 of 124 models, but candidate predictors were not described in the vast majority of studies; among studies clearly describing candidate predictors, effective sample size was <10 events per variable in 50% (n = 21) of presented models.
- Missing data occurrence or handling was not described or unclear in 38% of all studies; complete case analysis was used in 65% (45/71), while multiple imputation was used in 7% (5/71) per Table 7 (the text states 8% of all studies).
- Model performance and validation were limited: C-statistic/AUC-ROC was reported in 12% of predictor-finding and 80% of development/external-validation studies combined; calibration plots in 6% (4/66) and Hosmer-Lemeshow statistic in 9% (6/66); internal validation was performed in 33% (5/14) of model development studies, and external validation in only four studies.
Methods
- Systematic review by hand search of the six highest-impact general medicine journals for 2008: *The New England Journal of Medicine*, *The Lancet*, *JAMA*, *Annals of Internal Medicine*, *BMJ*, and *PLoS Medicine*; original research with an abstract was eligible, and two reviewers independently assessed eligibility and extracted data, with median inter-reviewer agreement of 92% (IQR 75%–100%).
- Included multivariable diagnostic and prognostic prediction studies predicting an outcome by two or more independent variables; excluded single predictor/test/marker studies, causality-only studies, and studies not contributing to patient care. An item list was developed from existing reporting statements/checklists (CONSORT, REMARK, STARD, STROBE, QUADAS) and prediction methodology recommendations.
- Studies were classified into five types: predictor finding, model development without external validation, model development with external validation, external validation without or with model updating, and model impact; results were grouped by study type, medical specialty, and whether prediction was a primary or secondary aim.
Limitations
- Stated: the review examined six high-impact journals, likely representing higher-quality studies; reporting may have improved since 2008, though the authors considered this unlikely because no major reporting guidelines for this research type had been produced recently; the work assessed reporting and statistical methods, not necessarily the appropriateness of design and conduct; conduct may be better than reported because journals limit paper length; poor reporting prevents readers from gauging relevance and reliability.
- Stated: statistical power or effective sample size could not be assessed for many studies because of inadequate reporting of the number of candidate predictors; selective reporting of outcomes and predictors could not generally be assessed because study registration is not mandated for prediction research.
- Evident from the text: the review is restricted to 2008 publications in six general medical journals, so findings may not generalize to other years, journals, or specialty journals; classification relied on full-text interpretation because authors generally did not explicitly state their aim, especially to distinguish predictor-finding from model-development studies.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
71 Own result · 26 Not checked yet · 12 No basis given · 5 Own interpretation · 4 Own method · 1 Partly supported · accuracy not yet measured
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Commonly missing values are related to observed participant or disease characteristics.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
What the sources say
- Not checked yetcites [10] EW Steyerberg, 2009, Clinical prediction models: a practical approach to development, validation, and updating source
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Supportedcites [23] AR Donders, 2006, Review: a gentle introduction to imputation of missing values., J Clin Epidemiol source
Section 2, “Types of missing data,” says the probability of missingness commonly depends on observed patient characteristics. It gives disease status as an example of such an observed characteristic, directly supporting the claim. (LLM, conf=0.94)
- Not checked yetcites [24] S Greenland, 1995, A critical look at methods for handling missing covariates in epidemiologic regression analyses., Am J Epidemiol source
- Partly supportedcites [57] A Burton, 2004, Missing covariate data within cancer prognostic studies: a review of current reporting and proposed guidelines., Br J Cancer sourceExperimental — accuracy not yet measured
The Results section ('Exploration of the missing data mechanism'; page not provided) reports differences between patients with complete and missing data in seven articles, including comparisons of patient or clinical characteristics. But only 10 of the 100 reviewed articles examined such differences, so the paper does not establish that missingness is commonly related to observed participant or disease characteristics across studies. (LLM, conf=0.85)
- Not checked yetcites [58] MH Gorelick, 2006, Bias arising from missing data in predictive models., J Clin Epidemiol source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Study recruitment dates were reported in 88% of the studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Participant Recruitment, Follow-Up, and Setting
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“11/68 studies had all cause mortality as the outcome, where such bias would not be a factor.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Given this, effective sample size was sufficient in the majority of the external validation studies (9/13 models).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Outcomes were well defined in 62/68 studies (Table 3).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A number of studies predicted a combined endpoint (14/71).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In the studies that clearly described the number of candidate predictors, the effective sample size was <10 events per variable in 50% (n = 21) of the presented models.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
plainn = 21- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Prediction of more than one outcome was very common in predictor finding studies, apparently because of their exploratory aim (Table S1).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“There were few multivariable diagnostic studies (n = 5).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Study Aims
plainn = 5- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Description of the cohort characteristics was clear in 68/69 of the relevant prediction studies (not applicable for two non-nested case-control studies).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Participant Recruitment, Follow-Up, and Setting
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- It may state two separate claims as one. 37
- Probably not a substantial claim. 13
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A randomized trial was used by two of the three impact studies; the third used an observational before-after (prospective) cohort design, comparing participant outcomes before and after the introduction of a prediction model.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Design of Participant Sampling
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Of the prediction modelling studies (n = 20), the vast majority were model development studies, without (n = 11) or with (n = 3) external validation.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Study Aims
plainn = 20- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Predictor interaction (non-additivity) was tested in 25 of the 51 predictor finding studies and in 11 of the 14 model development studies (total n = 36).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Candidate Predictors
plainn = 36- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Pure external validation (n = 3) and impact studies (n = 3) were rare.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Study Aims
plainn = 3- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Whether (all) consecutive participants were included or how many participants refused to participate was rarely reported and so could not be evaluated.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Participant Recruitment, Follow-Up, and Setting
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In outcome reporting, we expected differences between studies with prediction as a primary versus a secondary aim, but this was not observed.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
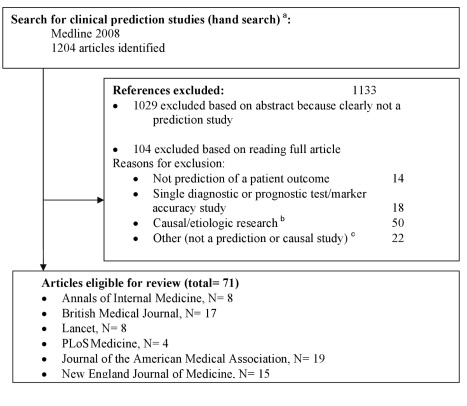
“We identified 1,204 articles by hand searching, of which 71 met the inclusion criteria (Figure 1 and Text S2).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Authors in general did not explicitly state their aim, so we used full text interpretations to classify studies as predictor finding or model development studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Data Extraction and Reviewer Agreement
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Discrimination was assessed with the C-statistic or area under the receiver operating characteristic (ROC) curve in 12% of the predictor finding and, as expected, 80% of the model development and external validation studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Model Performance and Internal and External Validity
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The majority, 65% of the predictor finding and 79% of the model development studies, reported the predictor coefficients or effect estimates of the model after predictor selection (the final model).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Presentation of Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By comparison, multiple imputation, the most rigorous strategy for dealing with missing values, was used in only 8% of all studies.”
- Also stated in: § Discussion · hedged
“Recommended methods, such as multiple imputation, were applied and reported in very few studies, although this may be due to the fact that consensus in recommending these methods was arrived at only recently.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · hedged
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In descriptions of participant selection, it often remained unclear whether participants were included in an unbiased way, notably with respect to refusals and whether all consecutive eligible participants were included.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“and external validation in only four studies.”
- Also stated in: § Discussion · plain
“Similarly, only a very few model development studies reported an external validation of the model in the same paper.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Model Performance and Internal and External Validity
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“External validation and model impact studies were rare (n = 6).”
- Also stated in: § Discussion · plain
“Only a very small minority of the papers involved the most useful approaches in predicting participant clinical outcomes, namely, external validations or impact assessments of a previously developed prediction model.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plainn = 6- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Study design, participant selection, definitions of outcomes and predictors, and predictor selection were generally well reported.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“18% of all studies investigated the added value of specific predictors, and 42% included predictors regardless of statistical significance.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Analysis of participants with complete data (i.e., complete case analysis) was performed in the vast majority of studies.”
- Also stated in: § Discussion · plain
“Complete case analysis was by far the most commonly used approach to handle missing values, despite many methodological recommendations to do otherwise [10],[12],[13],[23],[24],[57],[58].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The most commonly reported criterion for predictor selection in multivariable models was a p-value of <0.05, used in 18% of all studies (and in 26% of the studies that indeed applied predictor selection in multivariable analyses).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our investigation found that among the 71 prediction studies identified, the vast majority were predictor finding studies (n = 51), followed by model development studies (n = 14).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plainn = 51- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that 14 studies developed new prediction models (of which three included an external validation).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plainn = 14- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Three studies externally validated models, and three investigated the impact of an existing prediction model.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Studies reported using backward selection in 17% of the primary-aim and 18% of the secondary-aim studies, whereas forward selection was reported in 6% and 0%, respectively.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In studies with prediction as the primary aim, the majority (71%) selected their candidate predictors based on existing literature, whereas this was less often the case (29%) in studies with prediction as a secondary aim.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Internal validation was performed in 33% (n = 5) of the 14 model development studies”
- Also stated in: § Discussion · plain
“but use of these techniques was rare.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Model Performance and Internal and External Validity
plainn = 5- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Pre-selection of candidate predictors for inclusion in the multivariable analyses based on univariable predictor–outcome associations was used in 13% of the primary-aim and in 24% of the secondary-aim prediction studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that selection of candidate predictors was described for 36 (75%) of the studies where prediction was the primary aim and for eight (47%) of the studies where prediction was a secondary aim (Table 6).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, sample size considerations, applied statistical methods, and procedures for dealing with missing data were poorly reported despite being highlighted in several reporting guidelines.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The statistical methods reported in the published prediction studies reflect the methods actually used in those studies.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Most studies reported the occurrence of missing data but did not report sufficient detail.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“C-statistics or area under the ROC curves were the most frequently reported discrimination statistics, whereas measures of calibration (such as calibration slope) and overall measures of fit were rarely reported.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, encouraging findings included the frequent use of prospective studies, and adequate description of participant selection, predictor and outcome definitions, and the process for (pre)selection of candidate predictors.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Two authors (W. B., N. P. A. Z.) independently extracted the data. In case of doubt, items were discussed with a third and fourth reviewer (K. G. M. M., Y. V.).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Methods > Data Extraction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“However, many methodological reports have shown that selection based on (significant) univariable predictor–outcome associations is not recommended, as this method increases the chance of biased results in terms of spurious predictors and overfitted and unstable models [12],[13],[43],[56].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
What the sources say
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Not checked yetcites [43] EW Steyerberg, 2001, Internal validation of predictive models: efficiency of some procedures for logistic regression analysis., J Clin Epidemiol source
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“To externally validate a prediction model, a minimum effective sample size of 100 participants with and 100 without the event has been recommended [55].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
What the sources say
- Not checked yetcites [55] Y Vergouwe, 2005, Substantial effective sample sizes were required for external validation studies of predictive logistic regression models., J Clin Epidemiol source
plainn = 100- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
None of the sources cited for this claim have been checked yet.
In the paper
“A frequently mentioned rule of thumb is “10 events needed per candidate predictor” [12],[25],[26],[30],[54].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
What the sources say
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [25] P Peduzzi, 1996, A simulation study of the number of events per variable in logistic regression analysis., J Clin Epidemiol source
- Not checked yetcites [26] P Peduzzi, 1995, Importance of events per independent variable in proportional hazards regression analysis. II. Accuracy and precision of regression estimates., J Clin Epidemiol source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“a practice that is not recommended because less accurate predictions are likely to result, as with dichotomizing predictor variables [50].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
What the sources say
- Not checked yetcites [50] P Royston, 2006, Dichotomizing continuous predictors in multiple regression: a bad idea., Stat Med source
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
None of the sources cited for this claim have been checked yet.
In the paper
“Adequate reporting of predictor selection methods used is important, because the number of candidate predictors and how they were selected at various stages of the study can both influence the specific predictors included in the final multivariable model, and thus affect the interpretation of the results 12,13,43,56.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
What the sources say
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Not checked yetcites [43] EW Steyerberg, 2001, Internal validation of predictive models: efficiency of some procedures for logistic regression analysis., J Clin Epidemiol source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The two reviewers agreed on a median of 92% (interquartile range 75%–100%) of the items extracted.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Data Extraction and Reviewer Agreement
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The full text of all thus selected studies was obtained, and two authors (W. B. and N. P. A. Z.) independently assessed eligibility; in case of doubt a third independent reader was involved (K. G. M. M. or Y. V.).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Methods > Literature Search
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The inter-reviewer agreement on the data extraction was assessed by calculating the percentage of overall agreement between the two reviewers.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Methods > Data Extraction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Imputation, notably multiple imputation, of missing values is often advocated to preserve power and obtain less biased results, on the assumption that the reason for the missing data is not entirely due to non-observed information (i.e., data are not “missing not at random”).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- The authors state this as an assumption: The reason for missing data is not entirely due to non-observed information (data are not missing not at random) when multiple imputation is used.
None of the sources cited for this claim have been checked yet.
In the paper
“Various reports have indicated that in prediction modelling research there is an unfortunate practice of developing new models instead of externally validating or updating existing models [8]–[10],[15],[29],[36],[48].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [8]–[10]
- Not checked yetcites [15] A Laupacis, 1997, Clinical prediction rules. a review and suggested modifications of methodological standards., JAMA source
- Not checked yetcites [29] JH Wasson, 1985, Clinical prediction rules. Applications and methodological standards., N Engl J Med source
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Exclusion of participants with missing values will therefore not only lead to loss of statistical power, but often also to biased results 10,12,13,23,24,57,58.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
What the sources say
- Not checked yetcites [10] EW Steyerberg, 2009, Clinical prediction models: a practical approach to development, validation, and updating source
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Not checked yetcites [23] AR Donders, 2006, Review: a gentle introduction to imputation of missing values., J Clin Epidemiol source
- Not checked yetcites [24] S Greenland, 1995, A critical look at methods for handling missing covariates in epidemiologic regression analyses., Am J Epidemiol source
- Not checked yetcites [57] A Burton, 2004, Missing covariate data within cancer prognostic studies: a review of current reporting and proposed guidelines., Br J Cancer source
- Not checked yetcites [58] MH Gorelick, 2006, Bias arising from missing data in predictive models., J Clin Epidemiol source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“These items have been identified as important in several well-known guidelines for reporting of clinical research [4],[38]–[41].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [4] LM McShane, 2005, Reporting recommendations for tumor marker prognostic studies (REMARK)., J Natl Cancer Inst source
- Not checked yetcites [38]–[41]
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Poor reporting of sample size rationale has also been observed by others [3],[21],[68].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [3] DG Altman, 1998, Methodological challenges in the evaluation of prognostic factors in breast cancer., Breast Cancer Res Treat source
- Not checked yetcites [21] S Mallett, 2010, Reporting methods in studies developing prognostic models in cancer: a review., BMC Med source
- Not checked yetcites [68] LM Bachmann, 2006, Sample sizes of studies on diagnostic accuracy: literature survey., BMJ source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To conclude, we identified poor reporting and poor methods in many published prediction studies, which limits the reliability and applicability of the published findings.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The 71 prediction studies published in six high-impact general medical journals in 2008 are representative of current clinical prediction research.
- Rests on an assumption: The statistical methods reported in the published prediction studies reflect the methods actually used in those studies.
None of the sources cited for this claim have been checked yet.
In the paper
“This apparent model performance, however, is generally too optimistic, as the model has been tailored to the dataset at hand.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [10] EW Steyerberg, 2009, Clinical prediction models: a practical approach to development, validation, and updating source
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [70] JC Van Houwelingen, 1990, Predictive value of statistical models., Stat Med source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“The REMARK guidelines for prognostic tumour marker studies recommend using a REMARK profile table instead of a flow diagram [69].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [69] S Mallett, 2010, Reporting of prognostic studies of tumour markers: a review of published articles in relation to REMARK guidelines., Br J Cancer source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper relies on this without support.
Study registration is not mandated for prediction research.
“study registration is not mandated for prediction research”
The authors state this as an assumption.
The reason for missing data is not entirely due to non-observed information (data are not missing not at random) when multiple imputation is used.
“on the assumption that the reason for the missing data is not entirely due to non-observed information (i.e., data are not “missing not at random”).”
The paper relies on this without support.
The 71 prediction studies published in six high-impact general medical journals in 2008 are representative of current clinical prediction research.
“We assessed the reporting and methods in all clinical prediction studies published in six high-impact general medical journals in 2008.”
“We have described the state of current prediction research, and highlighted aspects that clearly need improvement.”
The paper relies on this without support.
The statistical methods reported in the published prediction studies reflect the methods actually used in those studies.
“We note that our work assessed researchers' reporting and statistical methods in modelling, and not necessarily the appropriateness of the design and conduct of the studies.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“However, the overwhelming evidence shows that the quality of reporting of prediction model studies is poor.”
From Transparent Reporting of a Multivariable Prediction Model for Individual Prognosis or Diagnosis (TRIPOD): The TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Bouwmeester and colleagues [23] evaluated 71 reports, published in 2008 in 6 high-impact general medical journals, and likewise observed an overwhelmingly poor level of reporting.”
From Transparent reporting of a multivariable prediction model for individual prognosis or diagnosis (TRIPOD): the TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Many reviews have showed that the quality of reporting in published articles describing the development or validation of multivariable prediction models in medicine is poor [23–27,29].”
From Transparent reporting of a multivariable prediction model for individual prognosis or diagnosis (TRIPOD): the TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Unfortunately, extraction of calibration measures is often hampered by poor assessment and reporting.11,16”
From A framework for meta-analysis of prediction model studies with binary and time-to-event outcomes (2019) · cites this paper as [16]
In the citing paper
“In a meta-analysis without access to individual participant data (IPD), we are reliant on extracting these performance measures from study publications. However, they are often poorly reported.”
From A framework for meta-analysis of prediction model studies with binary and time-to-event outcomes (2019) · cites this paper as [16]
In the citing paper
“For instance, validation studies rarely present information on the calibration intercept and slope, or different studies report estimates for different risk strata or time horizons.”
From A framework for meta-analysis of prediction model studies with binary and time-to-event outcomes (2019) · cites this paper as [16]
In the citing paper
“Bouwmeester and colleagues23 evaluated 71 reports, published in 2008 in 6 high-impact general medical journals, and likewise observed an overwhelmingly poor level of reporting.”
From Transparent Reporting of a Multivariable Prediction Model for Individual Prognosis or Diagnosis (TRIPOD): The TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Many reviews have showed that the quality of reporting in published articles describing the development or validation of multivariable prediction models in medicine is poor.23–27,29”
From Transparent Reporting of a Multivariable Prediction Model for Individual Prognosis or Diagnosis (TRIPOD): The TRIPOD Statement (2015) · cites this paper as [23]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Similar predictors combinedd | 17 (8) | 6 (1) | 11 (7) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
Reported 7 · recomputed 9
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Not reported or unclear | 35 (18) | 53 (9) | 0 (0) | 0 (0) | 38 (27) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
Reported 35 · recomputed 37.5
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Time to event | 48 (30) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
Reported 48 · recomputed 44.117647
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
“48 predictor finding studies, 17 model development studies, or 65 total”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Presentation of Results
“| Type of Result Presented | Predictor Finding Studies (n = 51) | Development Studies (n = 14) | Total (n = 65)a |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Change in C-statistic | 10; 14 (5) | 0; 0 (0) | 9; 13 (6) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
Reported 6 · recomputed 5
Citations
Cites
von Elm, E., Altman, D. G., Egger, M., Pocock, S. J., Gøtzsche, P. C., Vandenbroucke, J. P., & Initiative, F. T. S. (2007) · PLoS Medicine · doi:10.1371/journal.pmed.0040296 · Cited by 23,020
Self-citationvon Elm, E., Altman, D. G., Egger, M., Pocock, S. J., Gøtzsche, P. C., & Vandenbroucke, J. P. (2007) · The Lancet · doi:10.1016/s0140-6736(07)61602-x · Cited by 21,320
Self-citationA simulation study of the number of events per variable in logistic regression analysis
Peduzzi, P., Concato, J., Kemper, E., Holford, T. R., & Feinstein, A. R. (1996) · Journal of Clinical Epidemiology · doi:10.1016/s0895-4356(96)00236-3 · Cited by 9,655
Regression Modeling Strategies
Harrell, F. E. (2001) · Springer series in statistics · doi:10.1007/978-1-4757-3462-1 · Cited by 9,270
Moher, D., Hopewell, S., Schulz, K. F., Montori, V., Gotzsche, P. C., Devereaux, P. J., Elbourne, D., Egger, M., & Altman, D. G. (2010) · BMJ · doi:10.1136/bmj.c869 · Cited by 8,883
Self-citationVandenbroucke, J. P., von Elm, E., Altman, D. G., Gøtzsche, P. C., Mulrow, C. D., Pocock, S. J., Poole, C., Schlesselman, J. J., Egger, M., & Initiative, F. T. S. (2007) · PLoS Medicine · doi:10.1371/journal.pmed.0040297 · Cited by 8,613 · cited 1×
“, from a multivariable analysis) [4,38,63].”
Self-citationRelaxing the Rule of Ten Events per Variable in Logistic and Cox Regression
Vittinghoff, E., & McCulloch, C. E. (2007) · American Journal of Epidemiology · doi:10.1093/aje/kwk052 · Cited by 4,359
Whiting, P., Rutjes, A. W., Reitsma, J. B., Bossuyt, P. M., & Kleijnen, J. (2003) · BMC Medical Research Methodology · doi:10.1186/1471-2288-3-25 · Cited by 3,592
Vandenbroucke, J. P., Elm, E. V., Altman, D. G., Gøtzsche, P. C., Mulrow, C. D., Pocock, S. J., Poole, C., Schlesselman, J. J., Egger, M., & initiative, F. T. S. (2007) · Annals of Internal Medicine · doi:10.7326/0003-4819-147-8-200710160-00010-w1 · Cited by 3,543
Self-citationClinical Prediction Models: A Practical Approach to Development, Validation, and Updating
Steyerberg, E. W. (2019) · Statistics for Biology and Health · doi:10.1007/978-3-030-16399-0 · Cited by 3,281
Self-citation
Cited by
Sorted by citations
Items 201–300 of 579
Ramis, M., Chang, A., & Nissen, L. M. (2017) · Worldviews on Evidence-Based Nursing · doi:10.1111/wvn.12268 · Cited by 33
“Each of the included studies had a sufficient sample size to meet statistical power as determined by the common rationale of “10 items per variable” (Bouwmeester et al., 2012).”
BackgroundNECPAL tool prognostication in advanced chronic illness: a rapid review and expert consensus
Gómez‐Batiste, X., Turrillas, P., Tebé, C., Calsina-Berna, A., & Amblàs-Novellas, J. (2020) · BMJ Supportive & Palliative Care · doi:10.1136/bmjspcare-2019-002126 · Cited by 38
Amacher, S. A., Blatter, R., Briel, M., Appenzeller‐Herzog, C., Bohren, C., Becker, C., Beck, K., Groß, S., Tisljar, K., Sutter, R., et al. (2022) · Critical Care · doi:10.1186/s13054-022-04263-y · Cited by 36
Lo, B. W. Y., Fukuda, H., Nishimura, Y., et al. (2015) · Surgical Neurology International · doi:10.4103/2152-7806.162676 · Cited by 32
“For this systematic review, we sampled the quality checklist using Delphi methods for prescriptive clinical prediction rules (QUADCPR),[9] and criteria proposed by Bouwmeester et al. 2012[5] for methodologic quality assessment of clinical prediction research.”
BackgroundMethodInfluentialOgero, M. O., Sarguta, R. J., Malla, L., Aluvaala, J., Agweyu, A., English, M., Onyango, N. O., & Akech, S. (2020) · BMJ Open · doi:10.1136/bmjopen-2019-035045 · Cited by 32
Wan, S., Liu, X., Hua, W., Xi, M. Y., Zhou, Y., & Wan, Y. (2021) · Bioengineered · doi:10.1080/21655979.2021.1915725 · Cited by 32
Polce, E. M., Kunze, K. N., Dooley, M. S., Piuzzi, N. S., Boettner, F., & Sculco, P. K. (2022) · Journal of Bone and Joint Surgery · doi:10.2106/jbjs.21.00717 · Cited by 34
Mateen, B. A., Bussas, M., Doogan, C., Waller, D., Saverino, A., Király, F. J., & Playford, E. D. (2018) · Clinical Rehabilitation · doi:10.1177/0269215518771127 · Cited by 34
Con: Most clinical risk scores are useless
Dekker, F. W., Ramspek, C. L., & van Diepen, M. (2017) · Nephrology Dialysis Transplantation · doi:10.1093/ndt/gfx073 · Cited by 34
“Indeed, a systematic review of prediction studies in six high-impact general medical journals found that the majority of articles did not adhere to methodological recommendations and were lacking in reported details [16].”
BackgroundCollins, S. D., Peek, N. B., Riley, R. D., & Martin, G. P. (2020) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2020.12.011 · Cited by 32
“Indeed, several systematic reviews have observed that prediction model studiesdboth development and validationefrequently provide no rationale for the sample size used, or discuss the potential for overfitting [3,40,41].”
Backgroundvan Giessen, A., Peters, J., Wilcher, B., Hyde, C., Moons, C. G. M., de Wit, G. A., & Koffijberg, H. (2017) · Value in Health · doi:10.1016/j.jval.2017.01.001 · Cited by 33
“Several reviews have shown that across different disease areas and different journals the level of reporting on PM studies is generally poor [1,44].”
BackgroundArtificial intelligence for precision medicine in autoimmune liver disease
Gerussi, A., Scaravaglio, M., Cristoferi, L., Verda, D., Milani, C., Bernardi, E. D., Ippolito, D., Asselta, R., Invernizzi, P., Kather, J. N., et al. (2022) · Frontiers in Immunology · doi:10.3389/fimmu.2022.966329 · Cited by 37
Manuel, D. G., Tuna, M., Perez, R., Tanuseputro, P., Hennessy, D. A., Bennett, C. L., Rosella, L. C., Sanmartin, C., van Walraven, C., & Tu, J. V. (2015) · PLoS ONE · doi:10.1371/journal.pone.0143342 · Cited by 34
“[32] Further details of the methods are provided in S2 Table.”
MethodInfluentialWilson, C. M., Soupir, A. C., Thapa, R., et al. (2022) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1009900 · Cited by 30
“An alternate to setting the pre-defined threshold is use of the “optimal cut-point”, which is selected to maximize the test statistic of interest [29,30].”
MethodDiagnostic Clinical Prediction Rules for Specific Subtypes of Low Back Pain: A Systematic Review
Haskins, R., Osmotherly, P. G., & Rivett, D. A. (2015) · Journal of Orthopaedic and Sports Physical Therapy · doi:10.2519/jospt.2015.5723 · Cited by 29
D'Souza, R. D., Silversides, C. K., TOMLINSON, G. A., & Siu, S. C. (2020) · Canadian Journal of Cardiology · doi:10.1016/j.cjca.2020.02.079 · Cited by 32
Acute kidney injury risk prediction score for critically-ill surgical patients
Trongtrakul, K., Patumanond, J., Kongsayreepong, S., Morakul, S., Pipanmekaporn, T., Akaraborworn, O., & Poopipatpab, S. (2020) · BMC Anesthesiology · doi:10.1186/s12871-020-01046-2 · Cited by 29
A Critical Appraisal of Risk Models for Predicting Sexually Transmitted Infections
Falasinnu, T., Gustafson, P., Salway, T. J., et al. (2014) · Sexually Transmitted Diseases · doi:10.1097/olq.0000000000000120 · Cited by 29
“Second, calibration measures are essential in model validation studies to ascertain whether the predicted probabilities equal observed probability of the outcome in consideration.(26) For example, consider a scenario where an individual presenting for testing in an online setting or triaging at a clinic may be interes…”
BackgroundInfluentialHabets, P. C., Thomas, R. M., Milaneschi, Y., Jansen, R., Pool, R., Peyrot, W. J., Penninx, B. W. J. H., Meijer, O. C., van Wingen, G. A., & Vinkers, C. H. (2023) · Biological Psychiatry · doi:10.1016/j.biopsych.2023.05.024 · Cited by 32
“, prevented double dipping) (23,52,53); used balanced train and test sets (54); used separate repeated 10-fold cross-validation procedures in the train sample independent of the final test set (23,24); used a sample size for prediction analysis of several hundred (23); and tested final model performance on an outheld…”
de Castro, T. P., Waissmann, W., Simões, T. C., de Mello, R. C. R., & de Carvalho, D. P. (2016) · Clinical Endocrinology · doi:10.1111/cen.13032 · Cited by 28
CORR Synthesis: When Should We Be Skeptical of Clinical Prediction Models?
Karhade, A. V., & Schwab, J. H. (2020) · Clinical Orthopaedics and Related Research · doi:10.1097/corr.0000000000001367 · Cited by 29
“Unfortunately, only a few studies have reported model calibration [4, 9, 44].”
BackgroundMaloca, P. M., Müller, P. L., Lee, A., Tufail, A., Balaskas, K., Niklaus, S., Kaiser, P., Suter, S. K., Zarranz‐Ventura, J., Egan, C. A., et al. (2021) · Communications Biology · doi:10.1038/s42003-021-01697-y · Cited by 28
Aldin, A., Umlauff, L., Estcourt, L. J., Collins, P. G. S., Moons, K. G. M., Engert, A., Kobe, C., von Tresckow, B., Haque, M., Foroutan, F., et al. (2019) · Cochrane Database of Systematic Reviews · doi:10.1002/14651858.cd012643.pub2 · Cited by 28
Self-citationRauh, S. P., Rutters, F., van der Heijden, A. A. W. A., Luimes, T., Alssema, M., Heymans, M. W., Magliano, D. J., Shaw, J. E., Beulens, J. W. J., & Dekker, J. M. (2017) · Journal of General Internal Medicine · doi:10.1007/s11606-017-4231-7 · Cited by 27
van de Laar, R., IntHout, J., Gorp, T. V., et al. (2013) · British Journal of Cancer · doi:10.1038/bjc.2013.717 · Cited by 27
“…Biology, Maastricht University, P Debyelaan 25, 6229 HA Maastricht, The Netherlands; 4Department for Health Evidence, Radboud University Medical Centre, Geert Grooteplein 10, 6500 HB Nijmegen, The Netherlands and 5Department of Obstetrics and Gynecology, Meander Medical Centre, Utrechtseweg 160,”
BackgroundCalibration of clinical prediction rules does not just assess bias
Vach, W. (2013) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2013.06.003 · Cited by 26
Ratna, M. B., Bhattacharya, S., & McLernon, D. J. (2023) · Human Reproduction · doi:10.1093/humrep/dead165 · Cited by 23
“The HFEA has yet to publish data on UK LBRs for 2019–2022 so it is difficult to estimate how much calibration drift has affected our updated model.”
MethodInfluentialMateen, B., Bussas, M., Doogan, C., Waller, D., Saverino, A., Király, F., & Playford, E. D. (2018) · UCL Discovery (University College London) · Cited by 25
Silva, F. G., Costa, L. O. P., Hancock, M. J., Palomo, G. A., Costa, L. C., & da Silva, T. M. (2022) · Journal of physiotherapy · doi:10.1016/j.jphys.2022.03.009 · Cited by 27
Machine Learning in Colorectal Cancer Risk Prediction from Routinely Collected Data: A Review
Burnett, B., Zhou, S., Brophy, S. T., Davies, P., Ellis, P., Kennedy, J., Bandyopadhyay, A., Parker, M., & Lyons, R. A. (2023) · Diagnostics · doi:10.3390/diagnostics13020301 · Cited by 32
“[50] achieved good results using only age and gender, providing good evidence that applying this to other databank datasets, such as those in SAIL (Secure Anonymised Information Linkage), is a worthwhile initial step to take [56].”
BackgroundRamaekers, M., Viviers, C. G. A., Janssen, B. V., Hellström, T. A. E., Ewals, L. J. S., van der Wulp, K., Nederend, J., Jacobs, I., Pluyter, J. R., Mavroeidis, D., et al. (2023) · Journal of Clinical Medicine · doi:10.3390/jcm12134209 · Cited by 26
“Metrics such as accuracy, sensitivity, specificity, and area under the receiver’s operating characteristics should be described [102,106].”
BackgroundHashemi, S. M., Fischer, K., Moons, K. G. M., & van den Berg, H. M. (2014) · Haemophilia · doi:10.1111/hae.12566 · Cited by 26
Self-citationStineman, M. G., Kwong, P. L., Bates, B. E., Kurichi, J. E., Ripley, D. C., & Xie, D. (2013) · American Journal of Physical Medicine & Rehabilitation · doi:10.1097/phm.0b013e3182a92bfb · Cited by 26
“This included two concepts: model discrimination and model fit or calibration.(36)”
MethodTwelve practical recommendations for developing and applying clinical predictive models
Feng, G., Xu, H., Wan, S., Wang, H., Chen, X., Magari, R. T., Han, Y. K., Wei, Y., & Gu, H. (2024) · The Innovation Medicine · doi:10.59717/j.xinn-med.2024.100105 · Cited by 27
Eilertsen, S. E. H., & Eilertsen, T. (2023) · BMC Psychology · doi:10.1186/s40359-023-01238-8 · Cited by 27
“Unfortunately, many studies do not even meet current methodological recommendations, making interpretations of findings even harder [51].”
BackgroundThe application of unsupervised deep learning in predictive models using electronic health records
Wang, L., Tong, L., Davis, D. A., Arnold, T., & Esposito, T. (2020) · BMC Medical Research Methodology · doi:10.1186/s12874-020-00923-1 · Cited by 28
Cox, E. G. M., Wiersema, R., Eck, R. J., Kaufmann, T., Granholm, A., Vaara, S. T., Møller, M. H., van Bussel, B. C. T., Snieder, H., Pleijhuis, R. G., et al. (2022) · Critical Care Medicine · doi:10.1097/ccm.0000000000005712 · Cited by 27
“The poor reporting of models is not unique to the ICU setting, as shown in several reviews (6, 8, 9, 46).”
Violence risk assessment in psychiatric patients in China: A systematic review
Zhou, J., Witt, K., Xiang, Y., Zhu, X.-M., Wang, X., & Fazel, S. (2015) · Australian & New Zealand Journal of Psychiatry · doi:10.1177/0004867415585580 · Cited by 24
“Greater adherence to existing guidelines for the reporting of clinical risk prediction research may also help to improve the reliability and applicability of work in this area (Bouwmeester et al., 2012).”
BackgroundRisk predictive modelling for diabetes and cardiovascular disease
Kengne, A. P., Masconi, K. L., Mbanya, V. N., Lekoubou, A., Echouffo-Tcheugui, J. B., & Matsha, T. E. (2013) · Critical Reviews in Clinical Laboratory Sciences · doi:10.3109/10408363.2013.853025 · Cited by 24
Prognostic value of microRNAs in lung cancer: A systematic review and meta‑analysis
Xiao, W., Zhong, Y., Wu, L., et al. (2018) · Molecular and Clinical Oncology · doi:10.3892/mco.2018.1763 · Cited by 24
“The biased risks of all the included studies were according to the basis for assessing the internal validity of the prognostic study and the recommendations on the biomarker research report (15-17).”
Prognostic models for chronic kidney disease: a systematic review and external validation
van Rijn, M. H. C., van de Luijtgaarden, M. W. M., van Zuilen, A. D., Blankestijn, P. J., Wetzels, J. F. M., Debray, T. P. A., & van den Brand, J. A. J. G. (2020) · Nephrology Dialysis Transplantation · doi:10.1093/ndt/gfaa155 · Cited by 26
Nuñez, J.-J., Nguyen, T. T., Zhou, Y., Cao, B., Ng, R. T., Chen, J., Frey, B. N., Milev, R. V., Müller, D. J., Rotzinger, S., et al. (2021) · PLoS ONE · doi:10.1371/journal.pone.0253023 · Cited by 26
Carters-White, L., Chambers, S., Skivington, K., & Hilton, S. (2021) · Food Policy · doi:10.1016/j.foodpol.2021.102139 · Cited by 25
Internet marketing directed at children on food and restaurant websites in two policy environments
Kent, M. P., Dubois, L., Kent, E. A., & Wanless, A. (2013) · Obesity · doi:10.1002/oby.20124 · Cited by 24
Chandna, A., Tan, R., Carter, M. J., Bruel, A. V. D., Verbakel, J. Y. J., Koshiaris, C., Salim, N., Lubell, Y., Turner, P., & Keitel, K. (2021) · BMJ Global Health · doi:10.1136/bmjgh-2020-003451 · Cited by 20
“Full details on risk of bias and applicability assessments are provided in online supplemental appendix S6.”
Grigore, B., Lewis, R. A., Peters, J., Robinson, S., & Hyde, C. (2020) · BMC Cancer · doi:10.1186/s12885-020-07572-z · Cited by 23
Aluvaala, J., Collins, P. G. S., Maina, M., Berkley, J. A., & English, M. (2017) · Systematic Reviews · doi:10.1186/s13643-017-0649-6 · Cited by 23
The Novel 10-Item Asthma Prediction Tool: External Validation in the German MAS Birth Cohort
Grabenhenrich, L., Reich, A., Fischer, F. H., Zepp, F., Förster, J., Schuster, A., Bauer, C., Bergmann, R. L., Bergmann, K. E., Wahn, U., et al. (2014) · PLoS ONE · doi:10.1371/journal.pone.0115852 · Cited by 22
“validated the new asthma prediction tool in the cohort used for development itself [13, 20], which now requires replication in other populations [21] as the most rigorous assessment of a model’s validity [22].”
MethodQuality of reporting of studies evaluating time to diagnosis: a systematic review in paediatrics
Launay, E., Morfouace, M., Deneux‐Tharaux, C., Guen, C. G., Ravaud, P., & Chalumeau, M. (2013) · Archives of Disease in Childhood · doi:10.1136/archdischild-2013-304778 · Cited by 25
Shanahan, D. R., Sousa, I. L. D., & Marshall, D. M. (2017) · Research Integrity and Peer Review · doi:10.1186/s41073-017-0044-9 · Cited by 25
“Inadequate reporting is also a huge problem in study types other than randomised trials, including systematic reviews [23], diagnostic studies [24], animal studies [25], observational studies [26], clinical predication studies [27], qualitative studies [28] and surveys [29, 30], contributing to an estimated $85billion…”
Fundamentals of Clinical Prediction Modeling for the Neurosurgeon
Mijderwijk, H.-J., Steyerberg, E. W., Steiger, H., Fischer, I., & Kamp, M. A. (2019) · Neurosurgery · doi:10.1093/neuros/nyz282 · Cited by 23
Self-citationvan Loon, F. H. J., Korsten, H. H. M., Daele, A. T. M. D.-V., et al. (2021) · PLoS ONE · doi:10.1371/journal.pone.0252166 · Cited by 21
“Though, an AUC greater than 80% is stated as strongly acceptable regarding its discriminability [12, 17].”
BackgroundPredictors of Invasive Herpes Simplex Virus Infection in Young Infants
Cruz, A. T., Nigrovic, L. E., Xie, J., Mahajan, P., Thomson, J. E., Okada, P. J., Uspal, N. G., Mistry, R. D., Garro, A. C., Schnadower, D., et al. (2021) · PEDIATRICS · doi:10.1542/peds.2021-050052 · Cited by 21
Smith, H., Sweeting, M. J., Morris, T. P., & Crowther, M. J. (2022) · Diagnostic and Prognostic Research · doi:10.1186/s41512-022-00124-y · Cited by 26
Makarchev, N., Xiao, C., Yao, B., Zhang, Y., Tao, X., & Le, D. A. (2022) · Environmental Science & Policy · doi:10.1016/j.envsci.2022.07.015 · Cited by 21
Otokiti, A. U., Ozoude, M. M., Williams, K. S., Sadiq-Onilenla, R. A., Ojo, S. A., Warsame, L., Walsh, S., & Edomwande, M. (2022) · JMIR Research Protocols · doi:10.2196/37685 · Cited by 26
“Adhering to these guidelines may ensure study reproducibility and could improve future real-life applications [62,63,68].”
BrAIST-Calc: Prediction of Individualized Benefit From Bracing for Adolescent Idiopathic Scoliosis
Dolan, L. A., Weinstein, S. L., Dobbs, M. B., Flynn, J. M. “., Green, D. W., Halsey, M. F., Hresko, M. T., Krengel, W. F., Mehlman, C. T., Milbrandt, T. A., et al. (2023) · Spine · doi:10.1097/brs.0000000000004879 · Cited by 23
Guglielminotti, J. R., Dechartres, A., Mentré, F., Montravers, P., Longrois, D., & Laouenan, C. (2014) · Anesthesia & Analgesia · doi:10.1213/ane.0000000000000517 · Cited by 21
Depression following critical illness: Analysis of incidence and risk factors
Battle, C. E., James, K., & Temblett, P. (2014) · Journal of the Intensive Care Society · doi:10.1177/1751143714559904 · Cited by 24
“There was less than 1% missing data, therefore we used a simple imputation of the mean method to avoid exclusion of patients from the final analysis.(13) Statistical analyses were performed using SPSS Version 20 (Chicago, Illinois, USA).”
MethodPrediction of unsuccessful endometrial ablation: a retrospective study
Stevens, K. Y. R., Meulenbroeks, D., Houterman, S., et al. (2019) · Gynecological Surgery · doi:10.1186/s10397-019-1060-1 · Cited by 20
Berger, A., Cesbron-Métivier, É., Bertrais, S., et al. (2021) · Clinics and Research in Hepatology and Gastroenterology · doi:10.1016/j.clinre.2021.101693 · Cited by 20
Lorton, C. M., Higgins, L. S., O’Donoghue, N., Donohoe, C. L., O'Connell, J. E. A., Mockler, D., Reynolds, J. V., Walsh, D., & Lysaght, J. (2021) · Annals of Surgical Oncology · doi:10.1245/s10434-021-10988-x · Cited by 20
“All included studies were retrospective, which can be associated with poorer quality of data in prognostic factor studies.(33) Future studies should examine these scores prospectively.”
BackgroundMethods for Stratification and Validation Cohorts: A Scoping Review
Torres, T., Niubo, A. S., Monistrol-Mula, A., Gerardi, C., Banzi, R., Garcia, P., Demotes‐Mainard, J., Haro, J. M., & the PERMIT Group (2022) · Journal of Personalized Medicine · doi:10.3390/jpm12050688 · Cited by 22
“One review suggested that internal validation often gives exaggerated estimates of biomarker performance, probably due to feature selection bias, population selection bias or optimization biases [22,65].”
BackgroundHuang, X. B., Cao, T., Chen, L., Li, J., Tan, Z., Xu, B. P., Xu, R., Song, Y., Zhou, Z., Wang, Z., et al. (2022) · Frontiers in Cardiovascular Medicine · doi:10.3389/fcvm.2022.901240 · Cited by 26
Decruyenaere, A., Decruyenaere, P., Peeters, P. C., & Vermassen, F. E. G. (2015) · Annals of Transplantation · doi:10.12659/aot.894034 · Cited by 20
Collins, P. G. S., Reitsma, J. B., Altman, D. G., & Moons, K. G. M. (2015) · Diabetic Medicine · doi:10.1111/dme.12654 · Cited by 20
“Many reviews have showed that the quality of reporting in published articles describing the development or validation of multivariable prediction models in medicine is poor (23–27 , 29 ).”
InfluentialSelf-citationByrne, C. J., Toarta, C., Backus, B. E., & Holt, T. (2018) · Systematic Reviews · doi:10.1186/s13643-018-0816-4 · Cited by 22
Personalized Pancreatic Cancer Management
Bradley, A., Meer, R. V. D., & McKay, C. J. (2019) · Pancreas · doi:10.1097/mpa.0000000000001312 · Cited by 20
Burke, L., Hinkson, A., Haghnejad, V., Jones, R. L., Parker, R., & Rowe, I. A. C. (2024) · JHEP Reports · doi:10.1016/j.jhepr.2024.101227 · Cited by 20
“25,43,44 Yang et al. reviewed reporting of HBV HCC risk models based on the TRIPOD statement with many similar fi ndings to our current review.”
Bradley, A., Meer, R. V. D., & McKay, C. J. (2019) · BMJ Open · doi:10.1136/bmjopen-2018-027192 · Cited by 19
“This can only be achieved if future research focuses on improving the methodological quality of model development, regardless of whether they employ traditional or machine learning methods.(52)”
BackgroundKlunder, J. H., Panneman, S. L., Wallace, E., de Vries, R., Joling, K. J., Maarsingh, O. R., & van Hout, H. P. J. (2022) · PLoS ONE · doi:10.1371/journal.pone.0275116 · Cited by 22
Developing a model of factors that influence meeting the needs of family with a relative in ICU
Kynoch, K., Chang, A., Coyer, F. M., & McArdle, A. (2018) · International Journal of Nursing Practice · doi:10.1111/ijn.12693 · Cited by 18
Fazel, S., Wolf, A., Vazquez-Montes, M., & Fanshawe, T. R. (2019) · Scientific Reports · doi:10.1038/s41598-018-37539-x · Cited by 18
Chandna, A., Osborn, J., Bassat, Q., et al. (2021) · BMJ Global Health · doi:10.1136/bmjgh-2021-006057 · Cited by 19
Riley, S. M., Zhang, Q., Tse, W.-Y., Connor, A., & Wei, Y. (2022) · Transplant International · doi:10.3389/ti.2022.10397 · Cited by 20
Boulesteix, A., Janitza, S., Hornung, R., Probst, P., Marchi, H., & Hapfelmeier, A. (2018) · Biometrical Journal · doi:10.1002/bimj.201700243 · Cited by 18
Lancaster, T. S., Schill, M. R., Greenberg, J. W., Ruaengsri, C., Schuessler, R. B., Lawton, J. S., Maniar, H. S., Pasque, M. K., Moon, M. R., Damiano, R. J., et al. (2017) · The Annals of Thoracic Surgery · doi:10.1016/j.athoracsur.2017.11.045 · Cited by 17
“Preferably performed by investigators independent from the original development team [14, 15], external validation helps to address potential methodologic limitations that might reduce the generalizability of a clinical model.”
BackgroundLebenbaum, M., Espin‐Garcia, O., Li, Y., & Rosella, L. C. (2018) · PLoS ONE · doi:10.1371/journal.pone.0191169 · Cited by 18
Roheger, M., Folkerts, A., Krohm, F., Skoetz, N., & Kalbe, E. (2020) · Diagnostic and Prognostic Research · doi:10.1186/s41512-020-0071-8 · Cited by 20
Chandna, A., Aderie, E. M., Ahmad, R. A., Arguni, E., Ashley, E. A., Cope, T., Dat, V. Q., Day, N., Dondorp, A. M., Illanes, V., et al. (2021) · BMJ Open · doi:10.1136/bmjopen-2020-045826 · Cited by 15
“38 This study was designed following the latest guidance 39 : the sample size calculation and recruitment strategy (sampling frame) are based on recent methodological advances, 40 41 and selection of candidate predictors was informed by expert consensus, feasibility and systematic review of the…”
MethodBan, J.-W., Emparanza, J. I., Urreta, I., & Burls, A. (2016) · PLOS ONE · doi:10.1371/journal.pone.0145779 · Cited by 18
“Despite the available methodological standards, overall methodological qualities of clinical prediction rule research described in previous reports have been far from optimal [1, 2, 14 – 17].”
A computational approach to compare regression modelling strategies in prediction research
Pajouheshnia, R., Pestman, W. R., Teerenstra, S., & Groenwold, R. H. H. (2016) · BMC Medical Research Methodology · doi:10.1186/s12874-016-0209-0 · Cited by 21
“Furthermore, we currently only provide a framework for linear and logistic regression problems, and while this is most useful for diagnostic settings, a natural extension would be to enable the comparison of survival models, such as Cox proportional hazards models, as these are the most commonly used methods in progno…”
MethodSauerbrei, W., Bland, M., Evans, S. J. W., Riley, R. D., Royston, P. J., Schumacher, M. C., & Collins, P. G. S. (2020) · Biometrical Journal · doi:10.1002/bimj.202000053 · Cited by 17
“He was involved in numerous systematic reviews evaluating the methodological conduct and reporting of prognostic models (Altman, 2009; Bouwmeester et al., 2012; Collins et al., 2014; Mallett et al., 2010).”
BackgroundAshburner, J. M., Wang, X., Li, X., Khurshid, S. S., Ko, D., Lipsanopoulos, A. T., Lee, P. R., Carmichael, T., Turner, A. C., Jackson, C. R., et al. (2021) · Journal of the American Heart Association · doi:10.1161/jaha.121.022363 · Cited by 18
Haller, M. C., Aschauer, C., Wallisch, C., Leffondré, K., van Smeden, M., Oberbauer, R. W., & Heinze, G. (2022) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2022.01.025 · Cited by 19
Milders, J., Ramspek, C. L., Janse, R. J., Bos, W. J. W., Rotmans, J. I., Dekker, F. W., & van Diepen, M. (2023) · Journal of the American Society of Nephrology · doi:10.1681/asn.0000000000000285 · Cited by 20
“41,42 First, many studies included a relatively small sample of patients.”
BackgroundAbdul-Samad, K., Ma, S., Austin, D. E., Chong, A. S., Wang, C. X., Wang, X., Austin, P. C., Ross, H. J., Wang, B., & Lee, D. S. (2024) · American Heart Journal · doi:10.1016/j.ahj.2024.07.017 · Cited by 20
Sobhani, N., D’Angelo, A., Pittacolo, M., Mondani, G., & Generali, D. (2024) · Cancers · doi:10.3390/cancers16173089 · Cited by 19
“In response, new methods have been deemed necessary to resolve the issue of incomplete reporting of models in prediction model studies [43,44].”
MethodKrepper, D., Cesari, M., Hubel, N. J., Zelger, P., & Sztankay, M. J. (2024) · Journal of Patient-Reported Outcomes · doi:10.1186/s41687-024-00808-7 · Cited by 22
Hughes, T., Sergeant, J., Parkes, M., & Callaghan, M. (2017) · BMJ Open Sport & Exercise Medicine · doi:10.1136/bmjsem-2017-000263 · Cited by 18
Ramis, M., Chang, A., & Nissen, L. M. (2019) · Worldviews on Evidence-Based Nursing · doi:10.1111/wvn.12384 · Cited by 17
Hafermann, L., Becher, H., Herrmann, C., Klein, N., Heinze, G., & Rauch, G. (2021) · BMC Medical Research Methodology · doi:10.1186/s12874-021-01373-z · Cited by 20
“As several systematic reviews showed [13, 14], in many studies the method of univariable selection was used meaning that predictors were identified by evaluating unadjusted associations of candidate variables with the outcome.”
MethodNiehaus, I. M., Kansy, N., Stock, S., Dötsch, J., & Müller, D. (2022) · BMJ Open · doi:10.1136/bmjopen-2021-055956 · Cited by 19
Belt, O., Stamatakos, K., Ayers, A. J., et al. (2014) · Addiction · doi:10.1111/add.12727 · Cited by 17
Halliday, D. (2013) · Philosophy Compass · doi:10.1111/phc3.12092 · Cited by 17
Mortality prediction models for community-dwelling older adults: A systematic review
Exmann, C. J., Kooijmans, E. C. M., Joling, K. J., Burchell, G. L., Hoogendijk, E. O., & van Hout, H. P. J. (2024) · Ageing Research Reviews · doi:10.1016/j.arr.2024.102525 · Cited by 17
“In line with previous reviews about prediction models (Bouwmeester et al., 2012; Navarro et al., 2023), we conclude that better reporting is needed to improve transparency of studies on mortality prediction, as we observed that the AUC was often the only reported performance measure.”
ResultSafari, S., Yousefifard, M., Baikpour, M., et al. (2016) · Journal of Clinical Orthopaedics and Trauma · doi:10.1016/j.jcot.2016.02.005 · Cited by 16
Helmrich, I. R., Mikolić, A., Kent, D. M., Lingsma, H. F., Wynants, L., Steyerberg, E. W., & Klaveren, D. V. (2022) · Diagnostic and Prognostic Research · doi:10.1186/s41512-022-00122-0 · Cited by 18
“Prior systematic reviews found that calibration, the agreement between observed and predicted outcomes, is described less often than discrimination [5, 26, 35].”
BackgroundSelf-citationLi, Z., & Ding, X. (2018) · Clinical Cardiology · doi:10.1002/clc.23021 · Cited by 16
“Thus, we could not assess statistical power or effective sample size for the included studies.(9) Fourth, our study focused on the STS score and Euro SCORE, two commonly used models for perioperative risk assessments.”
BackgroundMethodResultInfluentialBattle, C. E., Hutchings, H. A., Bouamra, O., & Evans, P. A. (2014) · PLoS ONE · doi:10.1371/journal.pone.0091284 · Cited by 17
“[16] Stata Release 13 was used for all data analysis.”
Method
Metadata
- Authors
- Bouwmeester, W., Zuithoff, N. P. A., Mallett, S., Geerlings, M. I., Vergouwe, Y., Steyerberg, E. W., Altman, D. G., & Moons, K. G. M.
- Affiliations
- University Medical Center Utrecht (NL)
- University of Oxford (GB)
- Erasmus MC (NL)
- Corresponding author
- Moons, Karel G. M.
- ORCID
- Venue
- PLoS Medicine
- Publisher
- Public Library of Science (PLoS)
- Published
- 2012-05-22
- Volume
- 9
- Issue
- 5
- Pages
- e1001221
- ISSN
- 1549-1277 (ISSN-L)
- 1549-1676
- PMC
- PMC3358324
- OpenAlex
- W1998392635
- Semantic Scholar
- 2d86e73e56aa4394fe4ac9a6ed742d850abc73ce
- Cited by
- 600
- References
- 88
- Citations by year
- 2026: 24 · 2025: 39 · 2024: 36 · 2023: 47 · 2022: 65 · 2021: 50 · 2020: 65 · 2019: 36 · 2018: 40 · 2017: 43 · 2016: 40 · 2015: 46 · 2014: 38 · 2013: 24 · 2012: 7
- FWCI
- 5.61
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- PLoS Medicine (publishedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- EUR Research Repository (Erasmus University Rotterdam) (publishedVersion, other-oa)
- EUR Research Repository (Erasmus University Rotterdam) (submittedVersion, other-oa)
- RePub (Erasmus University Rotterdam) (submittedVersion, other-oa)
- RePEc: Research Papers in Economics (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Figshare (submittedVersion, cc-by)
- University of Birmingham Research Portal (University of Birmingham) (submittedVersion, other-oa)
- Topics
- Physical Sciences › Mathematics › Statistics and Probability › Statistical Methods in Epidemiology
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Health Sciences › Nursing › Research and Theory › Methodologies in Health Research and Practice
- Keywords
- prediction model development, reporting quality, methodological quality, predictor selection, calibration, discrimination (statistics), external validation, prospective cohort, general medical journals
- MeSH terms
- Forecasting, Humans, Periodicals as Topic, Prospective Studies, Research Design, Biomedical Research, Research Report
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
