

The DOI matches its Crossref record; 83 of the 88 references it cites were found in a registry or an index; 2 of the 74 sources its claims cite were checked for support.
Reporting and Methods in Clinical Prediction Research: A Systematic Review
Open accessAbstract
BACKGROUND: We investigated the reporting and methods of prediction studies, focusing on aims, designs, participant selection, outcomes, predictors, statistical power, statistical methods, and predictive performance measures. METHODS AND FINDINGS: We used a full hand search to identify all prediction studies published in 2008 in six high impact general medical journals. We developed a comprehensive item list to systematically score conduct and reporting of the studies, based on recent recommendations for prediction research. Two reviewers independently scored the studies. We retrieved 71 papers for full text review: 51 were predictor finding studies, 14 were prediction model development studies, three addressed an external validation of a previously developed model, and three reported on a model's impact on participant outcome. Study design was unclear in 15% of studies, and a prospective cohort was used in most studies (60%). Descriptions of the participants and definitions of predictor and outcome were generally good. Despite many recommendations against doing so, continuous predictors were often dichotomized (32% of studies). The number of events per predictor as a measure of statistical power could not be determined in 67% of the studies; of the remainder, 53% had fewer than the commonly recommended value of ten events per predictor. Methods for a priori selection of candidate predictors were described in most studies (68%). A substantial number of studies relied on a p-value cut-off of p<0.05 to select predictors in the multivariable analyses (29%). Predictive model performance measures, i.e., calibration and discrimination, were reported in 12% and 27% of studies, respectively. CONCLUSIONS: The majority of prediction studies in high impact journals do not follow current methodological recommendations, limiting their reliability and applicability.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This systematic review of 71 multivariable clinical prediction studies published in six high-impact general medical journals in 2008 found that most were predictor-finding studies and that key methodological and reporting recommendations were frequently not followed. Reporting was generally adequate for aims, participant selection, and predictor/outcome definitions, but poor for blinding, continuous predictors, power, missing data, multivariable result presentation, and model performance/validation.
Key findings
- Of 1,204 hand-searched articles, 71 met inclusion criteria: 51 were predictor-finding studies, 14 were model development studies (11 without and 3 with external validation), 3 were external validation studies, and 3 were impact studies; these 71 papers studied 135 models or sets of predictors.
- Statistical power was often inadequately reported: based on predictors in the final model, >10 events per variable occurred in 84 of 124 models, but candidate predictors were not described in the vast majority of studies; among studies clearly describing candidate predictors, effective sample size was <10 events per variable in 50% (n = 21) of presented models.
- Missing data occurrence or handling was not described or unclear in 38% of all studies; complete case analysis was used in 65% (45/71), while multiple imputation was used in 7% (5/71) per Table 7 (the text states 8% of all studies).
- Model performance and validation were limited: C-statistic/AUC-ROC was reported in 12% of predictor-finding and 80% of development/external-validation studies combined; calibration plots in 6% (4/66) and Hosmer-Lemeshow statistic in 9% (6/66); internal validation was performed in 33% (5/14) of model development studies, and external validation in only four studies.
Methods
- Systematic review by hand search of the six highest-impact general medicine journals for 2008: *The New England Journal of Medicine*, *The Lancet*, *JAMA*, *Annals of Internal Medicine*, *BMJ*, and *PLoS Medicine*; original research with an abstract was eligible, and two reviewers independently assessed eligibility and extracted data, with median inter-reviewer agreement of 92% (IQR 75%–100%).
- Included multivariable diagnostic and prognostic prediction studies predicting an outcome by two or more independent variables; excluded single predictor/test/marker studies, causality-only studies, and studies not contributing to patient care. An item list was developed from existing reporting statements/checklists (CONSORT, REMARK, STARD, STROBE, QUADAS) and prediction methodology recommendations.
- Studies were classified into five types: predictor finding, model development without external validation, model development with external validation, external validation without or with model updating, and model impact; results were grouped by study type, medical specialty, and whether prediction was a primary or secondary aim.
Limitations
- Stated: the review examined six high-impact journals, likely representing higher-quality studies; reporting may have improved since 2008, though the authors considered this unlikely because no major reporting guidelines for this research type had been produced recently; the work assessed reporting and statistical methods, not necessarily the appropriateness of design and conduct; conduct may be better than reported because journals limit paper length; poor reporting prevents readers from gauging relevance and reliability.
- Stated: statistical power or effective sample size could not be assessed for many studies because of inadequate reporting of the number of candidate predictors; selective reporting of outcomes and predictors could not generally be assessed because study registration is not mandated for prediction research.
- Evident from the text: the review is restricted to 2008 publications in six general medical journals, so findings may not generalize to other years, journals, or specialty journals; classification relied on full-text interpretation because authors generally did not explicitly state their aim, especially to distinguish predictor-finding from model-development studies.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
71 Own result · 26 Not checked yet · 12 No basis given · 5 Own interpretation · 4 Own method · 1 Partly supported · accuracy not yet measured
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Commonly missing values are related to observed participant or disease characteristics.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
What the sources say
- Not checked yetcites [10] EW Steyerberg, 2009, Clinical prediction models: a practical approach to development, validation, and updating source
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Supportedcites [23] AR Donders, 2006, Review: a gentle introduction to imputation of missing values., J Clin Epidemiol source
Section 2, “Types of missing data,” says the probability of missingness commonly depends on observed patient characteristics. It gives disease status as an example of such an observed characteristic, directly supporting the claim. (LLM, conf=0.94)
- Not checked yetcites [24] S Greenland, 1995, A critical look at methods for handling missing covariates in epidemiologic regression analyses., Am J Epidemiol source
- Partly supportedcites [57] A Burton, 2004, Missing covariate data within cancer prognostic studies: a review of current reporting and proposed guidelines., Br J Cancer sourceExperimental — accuracy not yet measured
The Results section ('Exploration of the missing data mechanism'; page not provided) reports differences between patients with complete and missing data in seven articles, including comparisons of patient or clinical characteristics. But only 10 of the 100 reviewed articles examined such differences, so the paper does not establish that missingness is commonly related to observed participant or disease characteristics across studies. (LLM, conf=0.85)
- Not checked yetcites [58] MH Gorelick, 2006, Bias arising from missing data in predictive models., J Clin Epidemiol source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Study recruitment dates were reported in 88% of the studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Participant Recruitment, Follow-Up, and Setting
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“11/68 studies had all cause mortality as the outcome, where such bias would not be a factor.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Given this, effective sample size was sufficient in the majority of the external validation studies (9/13 models).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Outcomes were well defined in 62/68 studies (Table 3).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A number of studies predicted a combined endpoint (14/71).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In the studies that clearly described the number of candidate predictors, the effective sample size was <10 events per variable in 50% (n = 21) of the presented models.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
plainn = 21- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Prediction of more than one outcome was very common in predictor finding studies, apparently because of their exploratory aim (Table S1).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“There were few multivariable diagnostic studies (n = 5).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Study Aims
plainn = 5- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Description of the cohort characteristics was clear in 68/69 of the relevant prediction studies (not applicable for two non-nested case-control studies).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Participant Recruitment, Follow-Up, and Setting
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- It may state two separate claims as one. 37
- Probably not a substantial claim. 13
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A randomized trial was used by two of the three impact studies; the third used an observational before-after (prospective) cohort design, comparing participant outcomes before and after the introduction of a prediction model.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Design of Participant Sampling
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Of the prediction modelling studies (n = 20), the vast majority were model development studies, without (n = 11) or with (n = 3) external validation.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Study Aims
plainn = 20- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Predictor interaction (non-additivity) was tested in 25 of the 51 predictor finding studies and in 11 of the 14 model development studies (total n = 36).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Candidate Predictors
plainn = 36- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Pure external validation (n = 3) and impact studies (n = 3) were rare.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Study Aims
plainn = 3- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Whether (all) consecutive participants were included or how many participants refused to participate was rarely reported and so could not be evaluated.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Participant Recruitment, Follow-Up, and Setting
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In outcome reporting, we expected differences between studies with prediction as a primary versus a secondary aim, but this was not observed.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
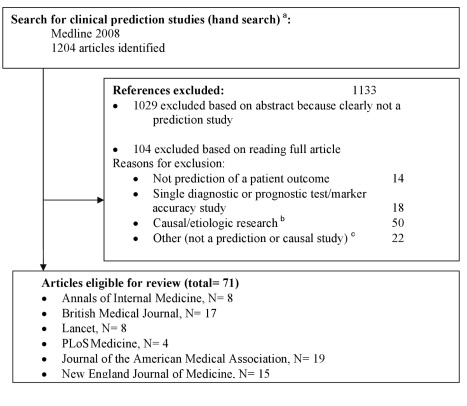
“We identified 1,204 articles by hand searching, of which 71 met the inclusion criteria (Figure 1 and Text S2).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Authors in general did not explicitly state their aim, so we used full text interpretations to classify studies as predictor finding or model development studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Data Extraction and Reviewer Agreement
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Discrimination was assessed with the C-statistic or area under the receiver operating characteristic (ROC) curve in 12% of the predictor finding and, as expected, 80% of the model development and external validation studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Model Performance and Internal and External Validity
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The majority, 65% of the predictor finding and 79% of the model development studies, reported the predictor coefficients or effect estimates of the model after predictor selection (the final model).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Presentation of Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By comparison, multiple imputation, the most rigorous strategy for dealing with missing values, was used in only 8% of all studies.”
- Also stated in: § Discussion · hedged
“Recommended methods, such as multiple imputation, were applied and reported in very few studies, although this may be due to the fact that consensus in recommending these methods was arrived at only recently.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · hedged
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In descriptions of participant selection, it often remained unclear whether participants were included in an unbiased way, notably with respect to refusals and whether all consecutive eligible participants were included.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“and external validation in only four studies.”
- Also stated in: § Discussion · plain
“Similarly, only a very few model development studies reported an external validation of the model in the same paper.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Model Performance and Internal and External Validity
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“External validation and model impact studies were rare (n = 6).”
- Also stated in: § Discussion · plain
“Only a very small minority of the papers involved the most useful approaches in predicting participant clinical outcomes, namely, external validations or impact assessments of a previously developed prediction model.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plainn = 6- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Study design, participant selection, definitions of outcomes and predictors, and predictor selection were generally well reported.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“18% of all studies investigated the added value of specific predictors, and 42% included predictors regardless of statistical significance.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Analysis of participants with complete data (i.e., complete case analysis) was performed in the vast majority of studies.”
- Also stated in: § Discussion · plain
“Complete case analysis was by far the most commonly used approach to handle missing values, despite many methodological recommendations to do otherwise [10],[12],[13],[23],[24],[57],[58].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The most commonly reported criterion for predictor selection in multivariable models was a p-value of <0.05, used in 18% of all studies (and in 26% of the studies that indeed applied predictor selection in multivariable analyses).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our investigation found that among the 71 prediction studies identified, the vast majority were predictor finding studies (n = 51), followed by model development studies (n = 14).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plainn = 51- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that 14 studies developed new prediction models (of which three included an external validation).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plainn = 14- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Three studies externally validated models, and three investigated the impact of an existing prediction model.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Studies reported using backward selection in 17% of the primary-aim and 18% of the secondary-aim studies, whereas forward selection was reported in 6% and 0%, respectively.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In studies with prediction as the primary aim, the majority (71%) selected their candidate predictors based on existing literature, whereas this was less often the case (29%) in studies with prediction as a secondary aim.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Internal validation was performed in 33% (n = 5) of the 14 model development studies”
- Also stated in: § Discussion · plain
“but use of these techniques was rare.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Model Performance and Internal and External Validity
plainn = 5- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Discussion · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Pre-selection of candidate predictors for inclusion in the multivariable analyses based on univariable predictor–outcome associations was used in 13% of the primary-aim and in 24% of the secondary-aim prediction studies.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that selection of candidate predictors was described for 36 (75%) of the studies where prediction was the primary aim and for eight (47%) of the studies where prediction was a secondary aim (Table 6).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, sample size considerations, applied statistical methods, and procedures for dealing with missing data were poorly reported despite being highlighted in several reporting guidelines.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The statistical methods reported in the published prediction studies reflect the methods actually used in those studies.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Most studies reported the occurrence of missing data but did not report sufficient detail.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“C-statistics or area under the ROC curves were the most frequently reported discrimination statistics, whereas measures of calibration (such as calibration slope) and overall measures of fit were rarely reported.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, encouraging findings included the frequent use of prospective studies, and adequate description of participant selection, predictor and outcome definitions, and the process for (pre)selection of candidate predictors.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Two authors (W. B., N. P. A. Z.) independently extracted the data. In case of doubt, items were discussed with a third and fourth reviewer (K. G. M. M., Y. V.).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Methods > Data Extraction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“However, many methodological reports have shown that selection based on (significant) univariable predictor–outcome associations is not recommended, as this method increases the chance of biased results in terms of spurious predictors and overfitted and unstable models [12],[13],[43],[56].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
What the sources say
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Not checked yetcites [43] EW Steyerberg, 2001, Internal validation of predictive models: efficiency of some procedures for logistic regression analysis., J Clin Epidemiol source
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“To externally validate a prediction model, a minimum effective sample size of 100 participants with and 100 without the event has been recommended [55].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
What the sources say
- Not checked yetcites [55] Y Vergouwe, 2005, Substantial effective sample sizes were required for external validation studies of predictive logistic regression models., J Clin Epidemiol source
plainn = 100- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
None of the sources cited for this claim have been checked yet.
In the paper
“A frequently mentioned rule of thumb is “10 events needed per candidate predictor” [12],[25],[26],[30],[54].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Statistical Power
What the sources say
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [25] P Peduzzi, 1996, A simulation study of the number of events per variable in logistic regression analysis., J Clin Epidemiol source
- Not checked yetcites [26] P Peduzzi, 1995, Importance of events per independent variable in proportional hazards regression analysis. II. Accuracy and precision of regression estimates., J Clin Epidemiol source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“a practice that is not recommended because less accurate predictions are likely to result, as with dichotomizing predictor variables [50].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
What the sources say
- Not checked yetcites [50] P Royston, 2006, Dichotomizing continuous predictors in multiple regression: a bad idea., Stat Med source
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
None of the sources cited for this claim have been checked yet.
In the paper
“Adequate reporting of predictor selection methods used is important, because the number of candidate predictors and how they were selected at various stages of the study can both influence the specific predictors included in the final multivariable model, and thus affect the interpretation of the results 12,13,43,56.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
What the sources say
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Not checked yetcites [43] EW Steyerberg, 2001, Internal validation of predictive models: efficiency of some procedures for logistic regression analysis., J Clin Epidemiol source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The two reviewers agreed on a median of 92% (interquartile range 75%–100%) of the items extracted.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Data Extraction and Reviewer Agreement
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The full text of all thus selected studies was obtained, and two authors (W. B. and N. P. A. Z.) independently assessed eligibility; in case of doubt a third independent reader was involved (K. G. M. M. or Y. V.).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Methods > Literature Search
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The inter-reviewer agreement on the data extraction was assessed by calculating the percentage of overall agreement between the two reviewers.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Methods > Data Extraction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Imputation, notably multiple imputation, of missing values is often advocated to preserve power and obtain less biased results, on the assumption that the reason for the missing data is not entirely due to non-observed information (i.e., data are not “missing not at random”).”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- The authors state this as an assumption: The reason for missing data is not entirely due to non-observed information (data are not missing not at random) when multiple imputation is used.
None of the sources cited for this claim have been checked yet.
In the paper
“Various reports have indicated that in prediction modelling research there is an unfortunate practice of developing new models instead of externally validating or updating existing models [8]–[10],[15],[29],[36],[48].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [8]–[10]
- Not checked yetcites [15] A Laupacis, 1997, Clinical prediction rules. a review and suggested modifications of methodological standards., JAMA source
- Not checked yetcites [29] JH Wasson, 1985, Clinical prediction rules. Applications and methodological standards., N Engl J Med source
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Exclusion of participants with missing values will therefore not only lead to loss of statistical power, but often also to biased results 10,12,13,23,24,57,58.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
What the sources say
- Not checked yetcites [10] EW Steyerberg, 2009, Clinical prediction models: a practical approach to development, validation, and updating source
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [13] FE Harrell Jr, 1996, Multivariable prognostic models: issues in developing models, evaluating assumptions and adequacy, and measuring and reducing errors., Stat Med source
- Not checked yetcites [23] AR Donders, 2006, Review: a gentle introduction to imputation of missing values., J Clin Epidemiol source
- Not checked yetcites [24] S Greenland, 1995, A critical look at methods for handling missing covariates in epidemiologic regression analyses., Am J Epidemiol source
- Not checked yetcites [57] A Burton, 2004, Missing covariate data within cancer prognostic studies: a review of current reporting and proposed guidelines., Br J Cancer source
- Not checked yetcites [58] MH Gorelick, 2006, Bias arising from missing data in predictive models., J Clin Epidemiol source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“These items have been identified as important in several well-known guidelines for reporting of clinical research [4],[38]–[41].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [4] LM McShane, 2005, Reporting recommendations for tumor marker prognostic studies (REMARK)., J Natl Cancer Inst source
- Not checked yetcites [38]–[41]
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Poor reporting of sample size rationale has also been observed by others [3],[21],[68].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [3] DG Altman, 1998, Methodological challenges in the evaluation of prognostic factors in breast cancer., Breast Cancer Res Treat source
- Not checked yetcites [21] S Mallett, 2010, Reporting methods in studies developing prognostic models in cancer: a review., BMC Med source
- Not checked yetcites [68] LM Bachmann, 2006, Sample sizes of studies on diagnostic accuracy: literature survey., BMJ source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To conclude, we identified poor reporting and poor methods in many published prediction studies, which limits the reliability and applicability of the published findings.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The 71 prediction studies published in six high-impact general medical journals in 2008 are representative of current clinical prediction research.
- Rests on an assumption: The statistical methods reported in the published prediction studies reflect the methods actually used in those studies.
None of the sources cited for this claim have been checked yet.
In the paper
“This apparent model performance, however, is generally too optimistic, as the model has been tailored to the dataset at hand.”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [10] EW Steyerberg, 2009, Clinical prediction models: a practical approach to development, validation, and updating source
- Not checked yetcites [12] FE Harrell, 2001, Regression modeling strategies with applications to linear models, logistic regression and survival analysis
- Not checked yetcites [70] JC Van Houwelingen, 1990, Predictive value of statistical models., Stat Med source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“The REMARK guidelines for prognostic tumour marker studies recommend using a REMARK profile table instead of a flow diagram [69].”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Discussion
What the sources say
- Not checked yetcites [69] S Mallett, 2010, Reporting of prognostic studies of tumour markers: a review of published articles in relation to REMARK guidelines., Br J Cancer source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper relies on this without support.
Study registration is not mandated for prediction research.
“study registration is not mandated for prediction research”
The authors state this as an assumption.
The reason for missing data is not entirely due to non-observed information (data are not missing not at random) when multiple imputation is used.
“on the assumption that the reason for the missing data is not entirely due to non-observed information (i.e., data are not “missing not at random”).”
The paper relies on this without support.
The 71 prediction studies published in six high-impact general medical journals in 2008 are representative of current clinical prediction research.
“We assessed the reporting and methods in all clinical prediction studies published in six high-impact general medical journals in 2008.”
“We have described the state of current prediction research, and highlighted aspects that clearly need improvement.”
The paper relies on this without support.
The statistical methods reported in the published prediction studies reflect the methods actually used in those studies.
“We note that our work assessed researchers' reporting and statistical methods in modelling, and not necessarily the appropriateness of the design and conduct of the studies.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“However, the overwhelming evidence shows that the quality of reporting of prediction model studies is poor.”
From Transparent Reporting of a Multivariable Prediction Model for Individual Prognosis or Diagnosis (TRIPOD): The TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Bouwmeester and colleagues [23] evaluated 71 reports, published in 2008 in 6 high-impact general medical journals, and likewise observed an overwhelmingly poor level of reporting.”
From Transparent reporting of a multivariable prediction model for individual prognosis or diagnosis (TRIPOD): the TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Many reviews have showed that the quality of reporting in published articles describing the development or validation of multivariable prediction models in medicine is poor [23–27,29].”
From Transparent reporting of a multivariable prediction model for individual prognosis or diagnosis (TRIPOD): the TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Unfortunately, extraction of calibration measures is often hampered by poor assessment and reporting.11,16”
From A framework for meta-analysis of prediction model studies with binary and time-to-event outcomes (2019) · cites this paper as [16]
In the citing paper
“In a meta-analysis without access to individual participant data (IPD), we are reliant on extracting these performance measures from study publications. However, they are often poorly reported.”
From A framework for meta-analysis of prediction model studies with binary and time-to-event outcomes (2019) · cites this paper as [16]
In the citing paper
“For instance, validation studies rarely present information on the calibration intercept and slope, or different studies report estimates for different risk strata or time horizons.”
From A framework for meta-analysis of prediction model studies with binary and time-to-event outcomes (2019) · cites this paper as [16]
In the citing paper
“Bouwmeester and colleagues23 evaluated 71 reports, published in 2008 in 6 high-impact general medical journals, and likewise observed an overwhelmingly poor level of reporting.”
From Transparent Reporting of a Multivariable Prediction Model for Individual Prognosis or Diagnosis (TRIPOD): The TRIPOD Statement (2015) · cites this paper as [23]
In the citing paper
“Many reviews have showed that the quality of reporting in published articles describing the development or validation of multivariable prediction models in medicine is poor.23–27,29”
From Transparent Reporting of a Multivariable Prediction Model for Individual Prognosis or Diagnosis (TRIPOD): The TRIPOD Statement (2015) · cites this paper as [23]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Similar predictors combinedd | 17 (8) | 6 (1) | 11 (7) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
Reported 7 · recomputed 9
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Not reported or unclear | 35 (18) | 53 (9) | 0 (0) | 0 (0) | 38 (27) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Missing Values
Reported 35 · recomputed 37.5
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Time to event | 48 (30) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Outcome
Reported 48 · recomputed 44.117647
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
“48 predictor finding studies, 17 model development studies, or 65 total”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Presentation of Results
“| Type of Result Presented | Predictor Finding Studies (n = 51) | Development Studies (n = 14) | Total (n = 65)a |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“| Change in C-statistic | 10; 14 (5) | 0; 0 (0) | 9; 13 (6) |”
§ Reporting and Methods in Clinical Prediction Research: A Systematic Review > Results > Selection of Candidate and Final Predictors
Reported 6 · recomputed 5
Citations
Cites
von Elm, E., Altman, D. G., Egger, M., Pocock, S. J., Gøtzsche, P. C., Vandenbroucke, J. P., & Initiative, F. T. S. (2007) · PLoS Medicine · doi:10.1371/journal.pmed.0040296 · Cited by 23,020
Self-citationvon Elm, E., Altman, D. G., Egger, M., Pocock, S. J., Gøtzsche, P. C., & Vandenbroucke, J. P. (2007) · The Lancet · doi:10.1016/s0140-6736(07)61602-x · Cited by 21,320
Self-citationA simulation study of the number of events per variable in logistic regression analysis
Peduzzi, P., Concato, J., Kemper, E., Holford, T. R., & Feinstein, A. R. (1996) · Journal of Clinical Epidemiology · doi:10.1016/s0895-4356(96)00236-3 · Cited by 9,655
Regression Modeling Strategies
Harrell, F. E. (2001) · Springer series in statistics · doi:10.1007/978-1-4757-3462-1 · Cited by 9,270
Moher, D., Hopewell, S., Schulz, K. F., Montori, V., Gotzsche, P. C., Devereaux, P. J., Elbourne, D., Egger, M., & Altman, D. G. (2010) · BMJ · doi:10.1136/bmj.c869 · Cited by 8,883
Self-citationVandenbroucke, J. P., von Elm, E., Altman, D. G., Gøtzsche, P. C., Mulrow, C. D., Pocock, S. J., Poole, C., Schlesselman, J. J., Egger, M., & Initiative, F. T. S. (2007) · PLoS Medicine · doi:10.1371/journal.pmed.0040297 · Cited by 8,613 · cited 1×
“, from a multivariable analysis) [4,38,63].”
Self-citationRelaxing the Rule of Ten Events per Variable in Logistic and Cox Regression
Vittinghoff, E., & McCulloch, C. E. (2007) · American Journal of Epidemiology · doi:10.1093/aje/kwk052 · Cited by 4,359
Whiting, P., Rutjes, A. W., Reitsma, J. B., Bossuyt, P. M., & Kleijnen, J. (2003) · BMC Medical Research Methodology · doi:10.1186/1471-2288-3-25 · Cited by 3,592
Vandenbroucke, J. P., Elm, E. V., Altman, D. G., Gøtzsche, P. C., Mulrow, C. D., Pocock, S. J., Poole, C., Schlesselman, J. J., Egger, M., & initiative, F. T. S. (2007) · Annals of Internal Medicine · doi:10.7326/0003-4819-147-8-200710160-00010-w1 · Cited by 3,543
Self-citationClinical Prediction Models: A Practical Approach to Development, Validation, and Updating
Steyerberg, E. W. (2019) · Statistics for Biology and Health · doi:10.1007/978-3-030-16399-0 · Cited by 3,281
Self-citation
Cited by
Sorted by citations
Items 501–579 of 579
Moons, K. G. M., Altman, D. G., Reitsma, J. B., loannidis, J. P. A., Macaskill, P., Steyerberg, E. W., Vickers, A. J., Ransohoff, D. F., & Collins, P. G. S. (2023) · Вопросы современной педиатрии · doi:10.15690/vsp.v22i2.2557 · Cited by 1
Self-citationHooft, A. M., Umuhoza, C., Trawin, J., Mfuranziza, C., Uwiragiye, E., Zhang, C., Nguyen, V., Kornblith, A. E., Kenya‐Mugisha, N., Ansermino, J. M., et al. (2025) · PLOS Global Public Health · doi:10.1371/journal.pgph.0004606 · Cited by 1
Ginjupalli, R., Cole, K., Manji, K. P., Kisenge, R. R., Rogers, H., Westbrook, A. L., Bassat, Q., Varo, R., Madrid, L., Mandomando, I., et al. (2025) · PLOS Global Public Health · doi:10.1371/journal.pgph.0004788 · Cited by 1
Bligard, K. H., Papastefanou, I., & Odibo, A. O. (2025) · Ultrasound in Obstetrics and Gynecology · doi:10.1002/uog.29284 · Cited by 1
“Testing the predictive value of the FMF competing-risks model in independent populations is of paramount importance to determine its generalizability 22,23 .”
Validation of the Calgary Spine Severity Score
St-Pierre, G. H., JACK, A. S., Thomas, K. C., et al. (2015) · The Spine Journal · doi:10.1016/j.spinee.2015.06.005 · Cited by 1
“Although methodology is steadily improving [6], significant challenges remain in”
MethodMethods for Prediction Research in Mild Traumatic Brain Injury
Cnossen, M. C., Steyerberg, E. W., & Lingsma, H. F. (2016) · Journal of Neurotrauma · doi:10.1089/neu.2015.4359 · Cited by 1
Self-citationVernooij, L. M., Damen, J. A., van Klei, W. A., Moons, K. G. M., & Peelen, L. M. (2018) · Cochrane Database of Systematic Reviews · doi:10.1002/14651858.cd013139 · Cited by 1
“However, several systematic reviews focusing on the methodological conduct and reporting of prognostic models found that these performance measures are frequently not reported (Bouwmeester 2012).”
BackgroundMethodSelf-citationHou, Z., Peng, D., Yang, J., Zhang, S., & Wang, J. (2022) · Journal of Thoracic Disease · doi:10.21037/jtd-21-1830 · Cited by 1
“Discrimination and calibration are cardinal characteristics in assessing model performance; however, they are underreported in the published medical literature (50).”
BackgroundKhalifa, M., Magrabi, F., & Gallego, B. (2020) · doi:10.21203/rs.3.rs-15929/v1 · Cited by 1
Bautista, F. J., Rubio‐San‐Simón, A., Verdú‐Amorós, J., Neven, A., & de Rojas, T. (2020) · European Journal of Cancer · doi:10.1016/j.ejca.2020.08.027 · Cited by 1
“Methodological errors that are made in the development of prediction models [9] can ultimately lead to wrong decisions when applied into clinical practice.”
BackgroundImai, S., Ihara, K., Takahashi, N., et al. (2026) · Journal of the Neurological Sciences · doi:10.1016/j.jns.2026.125802 · Cited by 1
Desarrollo y aplicación de modelos pronósticos en patología lumbar
Royuela, A. (2014) · Biblos-e Archivo (Universidad Autónoma de Madrid)
Meta-analysis of clinical prediction models
Debray, T. P. A. (2013) · Utrecht University Repository (Utrecht University) · doi:10.7490/f1000research.445.1
Senior, J. M., Arévalo, E. F., Sánchez, J. M. S., et al. (2015) · Acta Médica Colombiana · doi:10.36104/amc.2015.530
Use of generalised additive models to categorise continuous variables in clinical
Aróstegui, I., & Quintana, J. M. (2013)
The TRIPOD Statement: how to present the results of diagnostic and prognostic studies
Колос, И. П., Аничков, Д. А., & Boytsov, S. A. (2015) · Rational Pharmacotherapy in Cardiology · doi:10.20996/1819-6446-2015-11-6-558-560
Kwong, K. (2016) · uO Research (University of Ottawa) · doi:10.20381/ruor-5825
Brenner, A. T. (2013) · ResearchWorks at the University of Washington (University of Washington)
Maskerine, C. (2017) · uO Research (University of Ottawa) · doi:10.20381/ruor-20165
Characteristics and risk factors of postoperative acute kidney injury in ICU patients
Shao, L.-J.-Z., Xue, F., Guo, R., et al. (2018) · International Urology and Nephrology · doi:10.1007/s11255-018-1981-z
Haskins, R., Cook, C. E., Osmotherly, P. G., & Rivett, D. A. (2019) · Elsevier eBooks · doi:10.1016/b978-0-7020-5976-6.00010-3
The Problem of Incomplete Validation in Reporting Prediction Models
Sachs, M. C. (2019) · The American Journal of Gastroenterology · doi:10.14309/ajg.0000000000000188
Scientific Utopia: II. Restructuring incentives and practices to promote truth over publishabilityPreprint
Nosek, B. A., Spies, J. R., & Motyl, M. S. (2016) · doi:10.31219/osf.io/k4bgq_v1
Risk Assessment Prior and During Pregnancy
Siu, S. C., & Silversides, C. K. (2019) · doi:10.1002/9781119409861.ch4
Jiang, D., & Shen, Y. (2019) · Expert Review of Molecular Diagnostics · doi:10.1080/14737159.2019.1692656
Incidence and prognosis of post-traumatic headache in adults
Cancelliere, C. (2017) · TSpace (University of Toronto)
Sardesai, S., Arumugam, A., Durairaj, S., Guddattu, V., Solomon, J. M., Gorthi, S. P., & Senthil Kumaran, D. (2020) · Physical Therapy Reviews · doi:10.1080/10833196.2020.1761163
Maximizing research value: adequate reporting and effective (de-)implementation strategies
Heus, P. (2020) · Utrecht University Repository (Utrecht University) · doi:10.33540/8
Pang, C. L. (2020) · PEARL (University of Plymouth) · doi:10.24382/878
Prognostic Prediction Models for Patients with Low Back Pain: Systematic Review ProtocolPreprint
Silva, F. G., Costa, L. O. P., Hancock, M. J., Palomo, G. A., Costa, L. D. C. M., & da Silva, T. M. (2020) · doi:10.21203/rs.3.rs-88541/v1
Zhang, X., Zhou, K., Zhang, J., Chen, Y., Dai, H., Wan, S., Guan, Z., Hu, M., Kang, J., Liu, Y., et al. (2021) · Research Square · doi:10.21203/rs.3.rs-948336/v1
(2021) · Journal of Medical Imaging and Radiation Oncology · doi:10.1111/1754-9485.13302
Hemming, K., & Taljaard, M. (2021) · Diagnostic and Prognostic Research · doi:10.1186/s41512-021-00109-3
“One approach is to formulate a directive decision rule based on cut-points for the predicted probabilities — for example, low or high risk [2, 6, 8].”
BackgroundRiley, R. D., Tierney, J. F., & Stewart, L. A. (2021) · Wiley eBooks · doi:10.1002/9781119333784.refs5
Khalifa, M., Magrabi, F., & Gallego, B. (2020) · doi:10.21203/rs.3.rs-15929/v2
Ramis, M. (2017) · Queensland University of Technology · doi:10.5204/thesis.eprints.109614 · Cited by 1
Estimation of Newborn Risk for Child or Adolescent Obesity
Morandi, A., Meyre, D., Lobbens, S., KLEINMAN, K. P., Kaakinen, M., Rifas‐Shiman, S. L., Vatin, V., Gaget, S., Pouta, A. M., Hartikainen, A., et al. (2013) · Apple Academic Press eBooks · doi:10.1201/b16340-5
Interpreting and Implementing Evidence for Quality Research
Cahan, E. M., & Shea, K. G. (2022) · Springer eBooks · doi:10.1007/978-3-031-07105-8_13
Habets, P. C., Thomas, R. M., Milaneschi, Y., Jansen, R., Pool, R., Peyrot, W. J., Penninx, B. W. J. H., Meijer, O. C., van Wingen, G. A., & Vinkers, C. H. (2023) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2023.01.10.523383
“724) was based on 10-fold cross-validation results, not on outheld test set results, possibly leading to overoptimistic performance metrics (23,24).”
MethodCalonge‐Pascual, S. (2023) · European journal of human movement · doi:10.21134/eurjhm.2022.49.11
Otokiti, A. U., Shih, H.-J., Ozoude, M. M., Siguachi, I., Warsame, L., Williams, K. S., & Akinloye, S. J. (2023) · doi:10.2196/preprints.55618
¿Una bola de cristal en la consulta? Interpretación de una regla de predicción clínica
Muelas, A. L., CASTELLANOS, H. M. C., & Arias, M. M. (2024) · Actualización en Medicina de Familia · doi:10.55783/amf.s200201
Wilson, J. P., Chowdhury, F., Hassan, S., Harriss, E. P., Alves, F. P., Musa, A. M., Dahal, P., Stepniewska, K., & Guerin, P. J. (2024) · medRxiv · doi:10.1101/2024.03.20.24304622
Yasuda, M. E., Renedo, D. B., Recalde, R. J., Zaninovich, R., Abbati, S. G., Cervio, A., Giovannini, S. J. M., Villalonga, J. F., Ulloque-Caamaño, L., Reddy, K. K. V., et al. (2024) · World Neurosurgery · doi:10.1016/j.wneu.2024.01.175
Lusa, L., Kappenberg, F., Collins, P. G. S., Schmid, M., Sauerbrei, W., & Rahnenführer, J. (2024) · medRxiv · doi:10.1101/2024.08.09.24311759
“Contibuting to the poor uptake is likely the poor adherence to methodological recommendations in the development of the models [1,3,4], which was also the main finding of the review of prediction models published in high-impact journals in 2008 [5].”
BackgroundResultRocha-Gomes, J. R., & Fortuna, I. (2025) · Smart innovation, systems and technologies · doi:10.1007/978-981-97-7498-2_10
de Groot, L. M., Twisk, J. W. R., Kok, A. A. L., et al. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5218477
Benders, P. M. B., Schouten, J. A., Vena, A., Buil, J. B., Bronkhorst, E., & Bassetti, M. (2025) · BMC Infectious Diseases · doi:10.1186/s12879-025-10644-9 · Cited by 1
Jacobs, B. K. M., Maseko, T., Lynen, L., et al. (2025) · BMC Medical Research Methodology · doi:10.1186/s12874-025-02591-5
“In the past, most methods were regression based [9], while machine learning approaches are relatively new.”
Arora, V. K., Aggarwal, N., & Rajpal, S. (2025) · Indian Journal of Tuberculosis · doi:10.1016/j.ijtb.2025.09.001
Slim, K., Veziant, J., Nsiri, A., et al. (2025) · Journal of Visceral Surgery · doi:10.1016/j.jviscsurg.2025.11.009
Utilité des scores prédictifs de morbi-mortalité per- ou postopératoire en chirurgie viscérale
Slim, K., Véziant, J., Nsiri, A., et al. (2025) · Journal de Chirurgie Viscérale · doi:10.1016/j.jchirv.2025.11.004
Predicting recurrent preeclampsia : empirical and methodological studies
van Kuijk, S. M. J. (2013) · doi:10.26481/dis.20131217sk
Application of artificial intelligence in management of myasthenia gravis
Prajapati, J. B., Prajapati, B., Jadeja, P., & Patel, R. (2025) · Elsevier eBooks · doi:10.1016/b978-0-443-36647-5.00005-4
Pommerich, U. M., Stubbs, P. W., & Nielsen, J. Z. (2025) · Acta Neurologica Belgica · doi:10.1007/s13760-025-02973-y
Li, L., Lan, X., Zeng, W., Xu, Y., & Chen, Q. (2026) · BMC Infectious Diseases · doi:10.1186/s12879-026-12687-y
“Research indicates that model development based on existing cases may introduce selection bias and recall bias into the temporal relationship between predictors and outcomes, whereas prospective cohort studies allow for more accurate and reliable measurement of both predictors and outcomes [42].”
Wilson, J. P., Chowdhury, F. U. H., Hassan, S., Harriss, E., Alves, F. P., Musa, A. M., Dahal, P., Stepniewska, K., & Guerin, P. J. (2026) · BMJ Public Health · doi:10.1136/bmjph-2024-001196
“6”
Chu, C., Wang, Y., Ma, L., Jin, L., & Pan, Y. (2026) · Alzheimer s & Dementia Diagnosis Assessment & Disease Monitoring · doi:10.1002/dad2.70336
Sun, Y., Qin, Y., Chen, W., Zhao, W., & Sun, H. (2026) · Crystals · doi:10.3390/cryst16050288
Ribeiro, T., Bondzi‐Simpson, A., Chan, W. C., Mahar, A., Jerath, A., Coburn, N. G., & Hallet, J. I. (2026) · Journal of the American College of Surgeons · doi:10.1097/xcs.0000000000002011
Bassi, A., Almalki, A., Alshehri, E., Alenezi, F. B., Bokhari, R. Y., Alhawsawi, H. T., Alaqil, N. A., Aljumaiah, D. F., Mulayhi, F. A., Demadi, S. S., et al. (2026) · Journal of Nature and Science of Medicine · doi:10.4103/jnsm.jnsm_320_25
Terry, D., Büttner, F., & Iverson, G. L. (2020) · OSF Preprints (OSF Preprints)
Fuller, G. W., Baird, J., Miller, J., Pilbery, R., Herbert, E., Keating, S., Callaghan, T., Pollard, D. J., Pandor, A., Essat, M., et al. (2025) · Health Technology Assessment · doi:10.3310/alpe8857
Seifu, B. L., Belsti, Y., Yimer, N. B., Goldstein, R. F., Enticott, J., & Teede, H. J. (2026) · Acta Obstetricia Et Gynecologica Scandinavica · doi:10.1111/aogs.70300
“Although the TRIPOD + AI guidelines strongly recommend reporting calibration performance in prediction modeling studies, 24 our findings, consistent with previous reviews 15,70,84,85 to assess RoB and applicability.”
Cao, M.-Y., Chen, Y.-F., Liao, Y.-X., et al. (2026) · World Journal of Gastrointestinal Oncology · doi:10.4251/wjgo.v18.i7.118867
Risk prediction models for malnutrition in patients with cancer: a systematic review
Jiang, K., Pan, J., & Zhang, Y. (2026) · Frontiers in Nutrition · doi:10.3389/fnut.2026.1900944
“Risk prediction models, also known as clinical prediction models, combine multiple predictors factors to estimate the presence of specific conditions or the risk of a future event (11).”
Evaluating discrimination of prediction models for recurrent clinical events
Spain, T. J., Hunt, A., Sudell, M., Hutton, J. L., Putter, H., Watson, V., Blakey, J., Marson, A. G., & Bonnett, L. J. (2026) · Diagnostic and Prognostic Research · doi:10.1186/s41512-026-00238-7
Amirvala, R., Hadaegh, F., Khalili, D., Rahmani, F., & Asgari, S. (2026) · Diabetes Research and Clinical Practice · doi:10.1016/j.diabres.2026.113576
Reproducibility in biomedical research
Zhong, J., D’Angelo, D., Lyu, C., Xu, I., Enns, P. K., Wang, F., & Kaushal, R. (2026) · Nature Medicine · doi:10.1038/s41591-026-04667-1
Selecting the optimal study design!
Albabtain, M. A., AlRasheed, M. M., Arafat, A. A., Breitinger, H., Breitinger, U., Elsisi, G. H., Gaber, A., Gumaa, M., Hozien, M., Abdelghany, R. M., et al. (2026) · Elsevier eBooks · doi:10.1016/b978-0-443-45595-7.00015-7
Metadata
- Authors
- Bouwmeester, W., Zuithoff, N. P. A., Mallett, S., Geerlings, M. I., Vergouwe, Y., Steyerberg, E. W., Altman, D. G., & Moons, K. G. M.
- Affiliations
- University Medical Center Utrecht (NL)
- University of Oxford (GB)
- Erasmus MC (NL)
- Corresponding author
- Moons, Karel G. M.
- ORCID
- Venue
- PLoS Medicine
- Publisher
- Public Library of Science (PLoS)
- Published
- 2012-05-22
- Volume
- 9
- Issue
- 5
- Pages
- e1001221
- ISSN
- 1549-1277 (ISSN-L)
- 1549-1676
- PMC
- PMC3358324
- OpenAlex
- W1998392635
- Semantic Scholar
- 2d86e73e56aa4394fe4ac9a6ed742d850abc73ce
- Cited by
- 600
- References
- 88
- Citations by year
- 2026: 24 · 2025: 39 · 2024: 36 · 2023: 47 · 2022: 65 · 2021: 50 · 2020: 65 · 2019: 36 · 2018: 40 · 2017: 43 · 2016: 40 · 2015: 46 · 2014: 38 · 2013: 24 · 2012: 7
- FWCI
- 5.61
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- PLoS Medicine (publishedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- EUR Research Repository (Erasmus University Rotterdam) (publishedVersion, other-oa)
- EUR Research Repository (Erasmus University Rotterdam) (submittedVersion, other-oa)
- RePub (Erasmus University Rotterdam) (submittedVersion, other-oa)
- RePEc: Research Papers in Economics (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Figshare (submittedVersion, cc-by)
- University of Birmingham Research Portal (University of Birmingham) (submittedVersion, other-oa)
- Topics
- Physical Sciences › Mathematics › Statistics and Probability › Statistical Methods in Epidemiology
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Health Sciences › Nursing › Research and Theory › Methodologies in Health Research and Practice
- Keywords
- prediction model development, reporting quality, methodological quality, predictor selection, calibration, discrimination (statistics), external validation, prospective cohort, general medical journals
- MeSH terms
- Forecasting, Humans, Periodicals as Topic, Prospective Studies, Research Design, Biomedical Research, Research Report
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
