

A Robust Approach to Multimodal Deepfake Detection
Open accessThe DOI matches its Crossref record; 52 of the 54 references it cites were found in a registry or an index; 10 of the 23 sources its claims cite were checked for support.
Abstract
The widespread use of deep learning techniques for creating realistic synthetic media, commonly known as deepfakes, poses a significant threat to individuals, organizations, and society. As the malicious use of these data could lead to unpleasant situations, it is becoming crucial to distinguish between authentic and fake media. Nonetheless, though deepfake generation systems can create convincing images and audio, they may struggle to maintain consistency across different data modalities, such as producing a realistic video sequence where both visual frames and speech are fake and consistent one with the other. Moreover, these systems may not accurately reproduce semantic and timely accurate aspects. All these elements can be exploited to perform a robust detection of fake content. In this paper, we propose a novel approach for detecting deepfake video sequences by leveraging data multimodality. Our method extracts audio-visual features from the input video over time and analyzes them using time-aware neural networks. We exploit both the video and audio modalities to leverage the inconsistencies between and within them, enhancing the final detection performance. The peculiarity of the proposed method is that we never train on multimodal deepfake data, but on disjoint monomodal datasets which contain visual-only or audio-only deepfakes. This frees us from leveraging multimodal datasets during training, which is desirable given their lack in the literature. Moreover, at test time, it allows to evaluate the robustness of our proposed detector on unseen multimodal deepfakes. We test different fusion techniques between data modalities and investigate which one leads to more robust predictions by the developed detectors. Our results indicate that a multimodal approach is more effective than a monomodal one, even if trained on disjoint monomodal datasets.
Overview
CoChat Summary
TL;DR
The paper proposes a multimodal deepfake video detector that fuses visual and audio features using time-aware neural networks, trained only on disjoint monomodal deepfake datasets. It reports that Early Fusion is the most robust fusion strategy and that multimodal detection outperforms monomodal baselines on unseen multimodal datasets.
Key findings
- Preliminary monomodal detectors achieved AUC 0.91 and BA0.5 0.83 for visual-only, and AUC 0.96 and BA0.5 0.90 for audio-only.
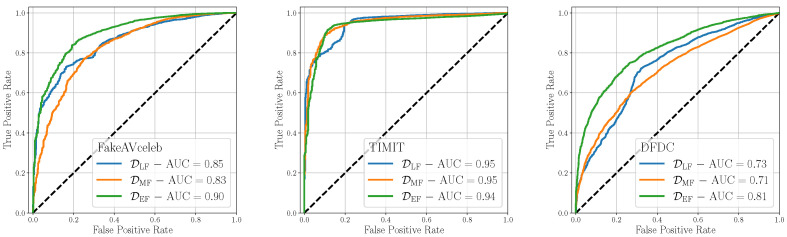
- Early Fusion was the most effective fusion strategy on average, achieving AUCs ≥ 0.90 for two of three datasets and being best on the remaining dataset; it exceeded other fusion strategies by 7% and 10% on FakeAVceleb and DFDC, respectively, while being competitive on TIMIT.
- The multimodal approach consistently outperformed the monomodal detectors, supporting the benefit of multimodal analysis.
- In mixed-class experiments, the Early Fusion detector achieved best average results when trained with the All Class strategy: average AUC = 0.80 vs. average AUC = 0.76 for Same Class. A fixed threshold t = 0.5 did not considerably change BA values, though FakeAVceleb showed a 5% accuracy improvement when using the best threshold for DEF; Early Fusion on FakeAVceleb was unbalanced toward “Real” (TPR0.5 = 0.954 vs. TNR0.5 = 0.580).
Methods
- Two-stage pipeline: visual features extracted with an EfficientNetB4 ensemble modified per prior work, and audio features extracted as TDNN x-vectors via SpeechBrain; extraction at 10 Hz, with 100 ms non-overlapped audio windows, time window TW = 3.0 s, N = 30 time instants, MV = 1072 visual features, MA = 512 audio features. The detector uses a Transformer-based classifier with a single hidden layer, 8 attention heads, 0.1 dropout, and GELU, evaluated with Late, Mid, and Early Fusion strategies.
- Training data: FaceForensics++ (5000 videos, QP 23 and QP 40 merged) for visual-only training, and ASVspoof 2019 Logical Access (>120,000 audio tracks at 16 kHz) for audio-only training. Testing was cross-dataset on FakeAVCeleb (~20,000 deepfake videos from 500 real VoxCeleb2 videos), DFDC (12,547 samples from folders 45–49), and TIMIT (VidTIMIT + DeepfakeTIMIT + TIMIT-TTS DTW subset with almost 20,000 synthetic speech tracks).
- Training and analysis: 150 epochs with early stopping patience 15, weighted cross-entropy loss, Adam optimization, learning rate e-3, weight decay e-4, and learning-rate reduction on plateau by factor 0.1; class balancing by oversampling the less represented class. Evaluation used ROC curves, AUC, and Balanced Accuracy at threshold t = 0.5 and at the best threshold.
Limitations
- The paper states that multimodal deepfake datasets are lacking, and that training on monomodal datasets means the detectors cannot leverage all intra-modality relationships within the content. It also states the system cannot detect synthetic content that appears realistic in individual modalities but lacks audio-video synchronization, even if simpler detectors trained explicitly for this could spot such inconsistencies.
- The paper notes that training on monomodal datasets could impact performance on multimodal ones, and that poor AUC on DFDC is likely due to distinct characteristics between training and test data.
- Evident from the text: evaluation is limited to three multimodal test corpora (FakeAVCeleb, DFDC, TIMIT) without multimodal training data; fixed threshold t = 0.5 yields unbalanced TPR/TNR on FakeAVCeleb, though best-threshold selection improves accuracy by 5% for DEF. The recursive Late Fusion approach was not considered further due to limited novelty and computational overhead.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures




Verification
Claims the paper makes
6 Valid · 0 Not valid · 6 Not checked · 29 Own results and interpretations
Every source the paper cites for this claim was checked and supports it.
In the paper
“Moreover, the results of [38] show that an ensemble of audio and visual baselines outperforms monomodal counterparts.”
§ A Robust Approach to Multimodal Deepfake Detection > 2. Deepfake Detection > 2.3. Audio-Visual Deepfake Detection
What the sources say
- Supportedcites [38] Khalid, H., Kim, M., Tariq, S., and Woo, S.S. (2021, January 24). Evaluation of an audio-video multimodal deepfake dataset using unimodal and multimodal detectors. Proceedings of the 1st Workshop on Synthetic Multimedia-Audiovisual Deepfake Generation and Detection, Virtual Event. source
The Abstract (p. 1) says that audio- or video-only unimodal methods do not perform well compared with ensemble-based methods. Section 4.2.2 (p. 5) identifies those ensembles as combinations of one audio and one video classifier, matching the claim. (LLM, conf=0.91)
states a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“In the recent years, few multimodal datasets have been proposed, containing both counterfeited video and audio tracks.”
- Also stated in: § 2.3. Audio-Visual Deepfake Detection · plain
“These are DFDC [42], FakeAVCeleb [43], and DeepfakeTIMIT [44] with TIMIT-TTS [6].”
§ A Robust Approach to Multimodal Deepfake Detection > 2. Deepfake Detection > 2.3. Audio-Visual Deepfake Detection
What the sources say
- Partly supportedcites [42] Dolhansky, B., Bitton, J., Pflaum, B., Lu, J., Howes, R., Wang, M., and Ferrer, C.C. (2020). The deepfake detection challenge (DFDC) dataset. arXiv. sourceExperimental — accuracy not yet measured
The Introduction (p. 1) and Dataset Construction (p. 2) identify DFDC as a dataset of videos with manipulated faces, supporting its identification as a counterfeited-video dataset. They describe face swaps but do not establish that the audio tracks are also counterfeited. This source also does not establish the claim about FakeAVCeleb or DeepFakeTIMIT with TIMIT-TTS. (LLM, conf=0.84)
- Partly supportedcites [43] Khalid, H., Tariq, S., Kim, M., and Woo, S.S. (2021, January 6–14). FakeAVCeleb: A Novel Audio-Video Multimodal Deepfake Dataset. Proceedings of the Conference on Neural Information Processing Systems Datasets and Benchmarks Track (Round 2), Virtual. sourceExperimental — accuracy not yet measured
The Introduction (p. 2) identifies DFDC as a dataset containing deepfake video and synthesized audio, and describes FakeAVCeleb as containing both. That supports the citing sentence’s general point that such datasets were few. But Background and Motivation (p. 3) says Deepfake TIMIT’s audio was real, not fake; our copy does not identify a TIMIT-TTS variant, so the claim’s three-dataset list is not fully supported. (LLM, conf=0.86)
- Partly supportedcites [44] Korshunov, P., and Marcel, S. (2018). Deepfakes: A new threat to face recognition? Assessment and detection. arXiv. sourceExperimental — accuracy not yet measured
Our copy supports scarcity only at a different level: the Introduction (p. 1) presents 'a first publicly available database of videos where faces are swapped' and Related Work (p. 2) states 'no public Deepfake video database where GAN-based approach was applied is available' — i.e., few/none Deepfake VIDEO databases, not multimodal ones with counterfeited audio. The part the source does not support is the audio modality: the Introduction (p. 1) explicitly says 'For the audio, we kept the original audio track of each video, i.e., no manipulation was done to the audio channel', so its own DeepfakeTIMIT dataset is not a counterfeited-video-and-audio dataset, and the paper nowhere discusses the scarcity of such multimodal datasets (DFDC and FakeAVCeleb are not mentioned). (LLM, conf=0.68)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 2.3. Audio-Visual Deepfake Detection · plain
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“To overcome these limitations, multimodal approaches have been recently proposed, able to combine information from various domains to enhance the accuracy of the detection process [7,8].”
§ A Robust Approach to Multimodal Deepfake Detection > 1. Introduction
What the sources say
- Supportedcites [7] Agarwal, S., Hu, L., Ng, E., Darrell, T., Li, H., and Rohrbach, A. (2023, January 2–7). Watch those words: Video falsification detection using word-conditioned facial motion. Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), Waikoloa, HI, USA. source
The Related Work section (p. 3) says multimodal techniques use both audio and visual signals to detect deepfakes. The Discussion (p. 8) describes the paper’s own multimodal approach, combining spoken words with facial gestures, and reports that it outperformed other methods in most tested cases. (LLM, conf=0.90)
- Not checked — no full text of the sourcecites [8] Mittal, T., Bhattacharya, U., Chandra, R., Bera, A., and Manocha, D. (2020, January 12–16). Emotions don’t lie: An audio-visual deepfake detection method using affective cues. Proceedings of the 28th ACM International Conference on Multimedia, Seattle, WA, USA. source
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“These results are consistent with those of many cutting-edge detectors reported in the literature [20,34], indicating that the proposed monomodal classifiers are suitable for subsequent multimodal experiments.”
§ A Robust Approach to Multimodal Deepfake Detection > 5. Results > 5.2. Monomodal Results
What the sources say
- Supportedcites [20] Bonettini, N., Cannas, E.D., Mandelli, S., Bondi, L., Bestagini, P., and Tubaro, S. (2021, January 10–15). Video face manipulation detection through ensemble of CNNs. Proceedings of the International Conference on Pattern Recognition (ICPR), Virtual Event. source
The citation supports the comparison with published face-manipulation detectors, not the citing authors’ inference about their later multimodal experiments. The Introduction (p. 2) reports that the proposed CNN ensemble outperformed an FF++ baseline on two datasets, and the Results (p. 6) compare detector performance using AUC and LogLoss. (LLM, conf=0.86)
- Not checked — no full text of the sourcecites [34] Attorresi, L., Salvi, D., Borrelli, C., Bestagini, P., and Tubaro, S. (2022, January 21–25). Combining Automatic Speaker Verification and Prosody Analysis for Synthetic Speech Detection. Proceedings of the International Conference on Pattern Recognition, Montréal, QC, Canada. source
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The DEF model achieves the best average results when trained following the All Class strategy (average AUC = 0.80 vs. average AUC = 0.76 of the Same Class).”
§ A Robust Approach to Multimodal Deepfake Detection > 5. Results > 5.3. Multimodal Results
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
18 more claims
Create a free account to see all 41 claims and to verify the 2 references still open.
- It may state two separate claims as one. 15
- The quote only partly states this claim. 1
- Probably not a substantial claim. 2
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A Robust Approach to Multimodal Deepfake Detection > 5. Results > 5.3. Multimodal Results
“Early Fusion results on FakeAVceleb are strongly unbalanced towards the “Real” class (i.e., TPR0.5=0.954 vs. TNR0.5=0.580).”
§ A Robust Approach to Multimodal Deepfake Detection > 5. Results > 5.1. Evaluation Metrics
“If the likelihood exceeds the threshold, the sequence is classified as “Fake”, otherwise it is classified as “Real”.”
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks
Tan, M., & Le, Q. V. (2019) · arXiv · doi:10.48550/arxiv.1905.11946 · Cited by 17,072 · cited 1×
“Regarding the visual modality, we exploit the EfficientNetB4 [45] network modified following the implementation proposed in [20], which investigates the ensembling of differently trained CNNs making use of attention layers and siamese training.”
FaceForensics++: Learning to Detect Manipulated Facial Images
Rossler, A., Cozzolino, D., Verdoliva, L., Riess, C., Thies, J., & Niessner, M. (2019) · 2019 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00009 · Cited by 3,314
X-Vectors: Robust DNN Embeddings for Speaker Recognition
Snyder, D., Garcia-Romero, D., Sell, G., Povey, D., & Khudanpur, S. (2018) · 2018 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2018.8461375 · Cited by 2,620
VoxCeleb2: Deep Speaker Recognition
Chung, J. S., Nagrani, A., & Zisserman, A. (2018) · Interspeech 2018 · doi:10.21437/interspeech.2018-1929 · Cited by 2,256
VoxCeleb: A Large-Scale Speaker Identification Dataset
Nagrani, A., Chung, J. S., & Zisserman, A. (2017) · Interspeech 2017 · doi:10.21437/interspeech.2017-950 · Cited by 2,210 · cited 2×
“In particular, FV was trained on FaceForensics++, while FA was trained on Voxceleb [57] and Voxceleb2 [50] datasets, considering audio data sampled at 16 kHz.”
MesoNet: a Compact Facial Video Forgery Detection Network
Afchar, D., Nozick, V., Yamagishi, J., & Echizen, I. (2018) · 2018 IEEE International Workshop on Information Forensics and Security (WIFS) · doi:10.1109/wifs.2018.8630761 · Cited by 1,872
Deepfake Video Detection Using Recurrent Neural Networks
Guera, D., & Delp, E. J. (2018) · 2018 15th IEEE International Conference on Advanced Video and Signal Based Surveillance (AVSS) · doi:10.1109/avss.2018.8639163 · Cited by 1,285
DARPA TIMIT: acoustic-phonetic continuous speech corpus CD-ROM, NIST speech disc 1-1.1
Garofolo, J. S., Lamel, L. F., Fisher, W. M., Fiscus, J. G., Pallett, D. S., & Dahlgren, N. L. (1993) · doi:10.6028/nist.ir.4930 · Cited by 1,267
Exposing Deep Fakes Using Inconsistent Head Poses
Yang, X., Li, Y., & Lyu, S. (2019) · ICASSP 2019 - 2019 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2019.8683164 · Cited by 1,196
In Ictu Oculi: Exposing AI Created Fake Videos by Detecting Eye Blinking
Li, Y., Chang, M.-C., & Lyu, S. (2018) · 2018 IEEE International Workshop on Information Forensics and Security (WIFS) · doi:10.1109/wifs.2018.8630787 · Cited by 1,089
Multi-attentional Deepfake Detection
Zhao, H., Wei, T., Zhou, W., Zhang, W., Chen, D., & Yu, N. (2021) · 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr46437.2021.00222 · Cited by 1,019 · cited 1×
“The authors of [20] consider an ensemble of CNNs to detect video face manipulations, while those of [21] introduce the multi-head attention and fine-grained classification to detect deepfake videos, showing that the approach is robust to low-quality videos.”
Self-citationMedia Forensics and DeepFakes: An Overview
Verdoliva, L. (2020) · IEEE Journal of Selected Topics in Signal Processing · doi:10.1109/jstsp.2020.3002101 · Cited by 979
A Lip Sync Expert Is All You Need for Speech to Lip Generation In the Wild
Prajwal, K. R., Mukhopadhyay, R., Namboodiri, V. P., & Jawahar, C. V. (2020) · Proceedings of the 28th ACM International Conference on Multimedia · doi:10.1145/3394171.3413532 · Cited by 897 · cited 1×
“In particular, F V was trained on FaceForensics++, while F A was trained on Voxceleb [57] and Voxceleb2 [50] datasets, considering audio data sampled at 16 kHz.”
Exploiting Visual Artifacts to Expose Deepfakes and Face Manipulations
Matern, F., Riess, C., & Stamminger, M. (2019) · 2019 IEEE Winter Applications of Computer Vision Workshops (WACVW) · doi:10.1109/wacvw.2019.00020 · Cited by 824
FSGAN: Subject Agnostic Face Swapping and Reenactment
Nirkin, Y., Keller, Y., & Hassner, T. (2019) · 2019 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00728 · Cited by 706
ASVspoof 2019: Future Horizons in Spoofed and Fake Audio Detection
Todisco, M., Wang, X., Vestman, V., Sahidullah, M., Delgado, H., Nautsch, A., Yamagishi, J., Evans, N., Kinnunen, T., & Lee, K. A. (2019) · arXiv · doi:10.48550/arxiv.1904.05441 · Cited by 688
ASVspoof 2019: Future Horizons in Spoofed and Fake Audio Detection
Todisco, M., Wang, X., Vestman, V., Sahidullah, M., Delgado, H., Nautsch, A., Yamagishi, J., Evans, N., Kinnunen, T. H., & Lee, K. A. (2019) · Interspeech 2019 · doi:10.21437/interspeech.2019-2249 · Cited by 687
Spatial-Phase Shallow Learning: Rethinking Face Forgery Detection in Frequency Domain
Liu, H., Li, X., Zhou, W., Chen, Y., He, Y., Xue, H., Zhang, W., & Yu, N. (2021) · 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr46437.2021.00083 · Cited by 600
Self-citationMasood, M., Nawaz, M., Malik, K. M., Javed, A., Irtaza, A., & Malik, H. (2023) · Applied Intelligence · doi:10.1007/s10489-022-03766-z · Cited by 543
Transfer learning from speaker verification to multispeaker text-to-speech synthesis
Jia, Y., Zhang, Y., Weiss, R. J., Wang, Q., Shen, J., Ren, F., Chen, Z., Nguyen, P., Pang, R., Moreno, I. L., et al. (2018) · arXiv · doi:10.48550/arxiv.1806.04558 · Cited by 519 · cited 1×
“Deepfake video frames have been generated with Faceswap [51] and FSGAN [52], while the deepfake audios have been synthesized using Real-Time Voice Cloning (RTVC) [53].”
Fast Face-Swap Using Convolutional Neural Networks
Korshunova, I., Shi, W., Dambre, J., & Theis, L. (2017) · 2017 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.397 · Cited by 501
FakeCatcher: Detection of Synthetic Portrait Videos using Biological Signals
Ciftci, U. A., Demir, I., & Yin, L. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2020.3009287 · Cited by 499
DeepFakes: a New Threat to Face Recognition? Assessment and Detection
Korshunov, P., & Marcel, S. (2018) · arXiv · doi:10.48550/arxiv.1812.08685 · Cited by 497
Deepfake Video Detection through Optical Flow Based CNN
Amerini, I., Galteri, L., Caldelli, R., & Del Bimbo, A. (2019) · 2019 IEEE/CVF International Conference on Computer Vision Workshop (ICCVW) · doi:10.1109/iccvw.2019.00152 · Cited by 424 · cited 1×
“Early forgery detection methods primarily depend on handcrafted features such as facial landmarks [12–14], optical flow [15] and various digital image processing techniques designed to enhance the visibility of artifacts [16].”
The Deepfake Detection Challenge (DFDC) Preview Dataset
Dolhansky, B., Howes, R., Pflaum, B., Baram, N., & Ferrer, C. C. (2019) · arXiv · doi:10.48550/arxiv.1910.08854 · Cited by 413
End-to-End anti-spoofing with RawNet2
Tak, H., Patino, J., Todisco, M., Nautsch, A., Evans, N., & Larcher, A. (2021) · ICASSP 2021 - 2021 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp39728.2021.9414234 · Cited by 402 · cited 1×
“Alternatively, the authors of [28] propose an end-to-end network training for extracting deep features from speech, while those of [29] use Mel-Frequency Cepstral Coefficient (MFCC) features and an Support Vector Machines (SVM) classifier.”
A comparison of features for synthetic speech detection
Sahidullah, M., Kinnunen, T., & Hanilçi, C. (2015) · Interspeech 2015 · doi:10.21437/interspeech.2015-472 · Cited by 382 · cited 1×
“For instance, [32] exploits classic audio features inherited from the Music Information Retrieval (MIR) community to perform speech deepfake detection.”
Emotions Don't Lie: An Audio-Visual Deepfake Detection Method using Affective Cues
Mittal, T., Bhattacharya, U., Chandra, R., Bera, A., & Manocha, D. (2020) · Proceedings of the 28th ACM International Conference on Multimedia · doi:10.1145/3394171.3413570 · Cited by 319 · cited 1×
“To overcome these limitations, multimodal approaches have been recently proposed, able to combine information from various domains to enhance the accuracy of the detection process [7,8].”
Deepfake Audio Detection via MFCC features using Machine Learning
Hamza, A., Javed, A. R. R., Iqbal, F., Kryvinska, N., Almadhor, A. S., Jalil, Z., & Borghol, R. (2022) · IEEE Access · doi:10.1109/access.2022.3231480 · Cited by 264 · cited 1×
“In [40], the authors establish a mapping between audio and video frames by analyzing the changes in the lip opening degree.”
Detecting Deep-Fake Videos from Phoneme-Viseme Mismatches
Agarwal, S., Farid, H., Fried, O., & Agrawala, M. (2020) · 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw50498.2020.00338 · Cited by 234
Joint Audio-Visual Deepfake Detection
Zhou, Y., & Lim, S.-N. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.01453 · Cited by 217 · cited 1×
“[41] exploits the inconsistency of lip shape between the audio and video signals.”
A Survey of Speaker Recognition: Fundamental Theories, Recognition Methods and Opportunities
Kabir, M. M., Mridha, M. F., Shin, J., Jahan, I., & Ohi, A. Q. (2021) · IEEE Access · doi:10.1109/access.2021.3084299 · Cited by 128
Detect and locate: Exposing face manipulation by semantic-and noise-level telltales
Kong, C., Chen, B., Li, H., Wang, S., Rocha, A., & Kwong, S. (2022) · IEEE Transactions on Information Forensics and Security · doi:10.1109/tifs.2022.3169921 · Cited by 120 · cited 1×
“In this section we introduce the reader to the deepfake detection task, providing a literature overview for the visual-only, audio-only and audio-visual deepfake detection scenarios.”
FakeAVCeleb: A Novel Audio-Video Multimodal Deepfake Dataset
Khalid, H., Tariq, S., Kim, M., & Woo, S. S. (2021) · arXiv · doi:10.48550/arxiv.2108.05080 · Cited by 116
Evaluation of an Audio-Video Multimodal Deepfake Dataset using Unimodal and Multimodal Detectors
Khalid, H., Kim, M., Tariq, S., & Woo, S. S. (2021) · Proceedings of the 1st Workshop on Synthetic Multimedia - Audiovisual Deepfake Generation and Detection · doi:10.1145/3476099.3484315 · Cited by 110
Channel pattern noise based playback attack detection algorithm for speaker recognition
Wang, Z.-F., Wei, G., & He, Q.-H. (2011) · 2011 International Conference on Machine Learning and Cybernetics · doi:10.1109/icmlc.2011.6016982 · Cited by 101 · cited 1×
“An example of an artifacts-based approach is presented in [25], where channel pattern noise analysis is used to secure Automatic Speaker Verification (ASV) systems against physical attacks.”
Speaker Inconsistency Detection in Tampered Video
Korshunov, P., & Marcel, S. (2018) · 2018 26th European Signal Processing Conference (EUSIPCO) · doi:10.23919/eusipco.2018.8553270 · Cited by 97
Synthetic speech detection through short-term and long-term prediction traces
Borrelli, C., Bestagini, P., Antonacci, F., Sarti, A., & Tubaro, S. (2021) · EURASIP Journal on Information Security · doi:10.1186/s13635-021-00116-3 · Cited by 80 · cited 1×
“Moreover, the results of [38] show that an ensemble of audio and visual baselines outperforms monomodal counterparts.”
Self-citationDo Deepfakes Feel Emotions? A Semantic Approach to Detecting Deepfakes Via Emotional Inconsistencies
Hosler, B., Salvi, D., Murray, A., Antonacci, F., Bestagini, P., Tubaro, S., & Stamm, M. C. (2021) · 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw53098.2021.00112 · Cited by 78 · cited 1×
“[37] leverages the incongruity between emotional cues portrayed by audio and visual modalities, while Ref.”
Self-citationDeepfake Speech Detection Through Emotion Recognition: A Semantic Approach
Conti, E., Salvi, D., Borrelli, C., Hosler, B., Bestagini, P., Antonacci, F., Sarti, A., Stamm, M. C., & Tubaro, S. (2022) · ICASSP 2022 - 2022 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp43922.2022.9747186 · Cited by 69 · cited 2×
“Similarly, the authors of [33] leverage the lack of emotional content in synthetic voices generated via Text-to-Speech (TTS) techniques to recognize them, while [34] combines ASV and prosody features.”
Self-citationTIMIT-TTS: A Text-to-Speech Dataset for Multimodal Synthetic Media Detection
Salvi, D., Hosler, B., Bestagini, P., Stamm, M. C., & Tubaro, S. (2023) · IEEE Access · doi:10.1109/access.2023.3276480 · Cited by 65
Self-citationOpen Challenges in Synthetic Speech Detection
Cuccovillo, L., Papastergiopoulos, C., Vafeiadis, A., Yaroshchuk, A., Aichroth, P., Votis, K., & Tzovaras, D. (2022) · 2022 IEEE International Workshop on Information Forensics and Security (WIFS) · doi:10.1109/wifs55849.2022.9975433 · Cited by 33 · cited 1×
“To do so, the scientific community has proposed numerous speech deepfake detectors that employ different detection approaches and strategies [24].”
Combining Automatic Speaker Verification and Prosody Analysis for Synthetic Speech Detection
Attorresi, L., Salvi, D., Borrelli, C., Bestagini, P., & Tubaro, S. (2023) · Lecture Notes in Computer Science · doi:10.1007/978-3-031-37742-6_21 · Cited by 30
Self-citationMultimodal Approach for DeepFake Detection
Lomnitz, M., Hampel-Arias, Z., Sandesara, V., & Hu, S. (2020) · 2020 IEEE Applied Imagery Pattern Recognition Workshop (AIPR) · doi:10.1109/aipr50011.2020.9425192 · Cited by 30
Watch Those Words: Video Falsification Detection Using Word-Conditioned Facial Motion
Agarwal, S., Hu, L., Ng, E., Darrell, T., Li, H., & Rohrbach, A. (2023) · 2023 IEEE/CVF Winter Conference on Applications of Computer Vision (WACV) · doi:10.1109/wacv56688.2023.00469 · Cited by 28
Securing Voice-Driven Interfaces Against Fake (Cloned) Audio Attacks
Malik, H. (2019) · 2019 IEEE Conference on Multimedia Information Processing and Retrieval (MIPR) · doi:10.1109/mipr.2019.00104 · Cited by 27
Video Face Manipulation Detection Through Ensemble of CNNs
Bonettini, N., Cannas, E. D., Mandelli, S., Bondi, L., Bestagini, P., & Tubaro, S. (2021) · 2020 25th International Conference on Pattern Recognition (ICPR) · doi:10.1109/icpr48806.2021.9412711 · Cited by 27
Self-citationVisual-Semantic Transformer for Face Forgery Detection
Xu, Y., Jia, G., Huang, H., Duan, J., & He, R. (2021) · 2021 IEEE International Joint Conference on Biometrics (IJCB) · doi:10.1109/ijcb52358.2021.9484407 · Cited by 24
Tampered Speaker Inconsistency Detection with Phonetically Aware Audio-visual Features
Korshunov, P., Halstead, M., Castán, D., Graciarena, M., McLaren, M., Burns, B., Lawson, A., & Marcel, S. (2019) · Infoscience (Ecole Polytechnique Fédérale de Lausanne) · Cited by 23
Reliability Estimation for Synthetic Speech Detection
Salvi, D., Bestagini, P., & Tubaro, S. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10095524 · Cited by 19
Self-citationSynthetic Speech Detection through Audio Folding
Salvi, D., Bestagini, P., & Tubaro, S. (2023) · ACM International Workshop on Multimedia AI against Disinformation (MAD) · doi:10.1145/3592572.3592844 · Cited by 12
Self-citation
Research works printed but not linked: 2
- Koopman, M., Rodriguez, A.M., and Geradts, Z. (2018, January 29–31). Detection of deepfake video manipulation. Proceedings of the 20th Irish Machine Vision and Image Processing Conference (IMVIP), Belfast, UK.
- Ravanelli, M., Parcollet, T., Plantinga, P., Rouhe, A., Cornell, S., Lugosch, L., Subakan, C., Dawalatabad, N., Heba, A., and Zhong, J. (2021). SpeechBrain: A General-Purpose Speech Toolkit. arXiv.
Cited by
Abbas, F., & Taeihagh, A. (2024) · Expert Systems with Applications · doi:10.1016/j.eswa.2024.124260 · Cited by 184
Deepfake Media Forensics: Status and Future Challenges
Amerini, I., Barni, M., Battiato, S., Bestagini, P., Boato, G., Bruni, V., Caldelli, R., De Natale, F., De Nicola, R., Guarnera, L., et al. (2025) · Journal of Imaging · doi:10.3390/jimaging11030073 · Cited by 113
Self-citationA novel approach for detecting deep fake videos using graph neural network
El-Gayar, M. M., Abouhawwash, M., Askar, S., & Sweidan, S. (2024) · Journal Of Big Data · doi:10.1186/s40537-024-00884-y · Cited by 82
Deepfake video detection methods, approaches, and challenges
Alrashoud, M. (2025) · Alexandria Engineering Journal · doi:10.1016/j.aej.2025.04.007 · Cited by 49
Audio–Visual Synchronization and Lip Movement Analysis for Real-Time Deepfake Detection
Javed, M., Zhang, Z., Dahri, F. H., Laghari, A. A., Krajčík, M., & Almadhor, A. S. (2025) · International Journal of Computational Intelligence Systems · doi:10.1007/s44196-025-00911-7 · Cited by 62
Metadata
- Authors
- Salvi, D., Liu, H., Mandelli, S., Bestagini, P., Zhou, W., Zhang, W., & Tubaro, S.
- Affiliations
- Politecnico di Milano (IT)
- University of Science and Technology of China (CN)
- Corresponding author
- Salvi, Davide
- Bestagini, Paolo
- Venue
- Journal of Imaging
- Publisher
- MDPI AG
- Published
- 2023-06-19
- Volume
- 9
- Issue
- 6
- Pages
- 122
- ISSN
- 2313-433X (ISSN-L)
- PMC
- PMC10299653
- OpenAlex
- W4381140704
- Cited by
- 96
- References
- 54
- Citations by year
- 2026: 34 · 2025: 35 · 2024: 24 · 2023: 3
- FWCI
- 8.68
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Journal of Imaging (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Virtual Community of Pathological Anatomy (University of Castilla La Mancha) (submittedVersion, other-oa)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Defense Advanced Research Projects Agency (FA8750-20-2-1004, PE00000001)
- European Union (FA8750-20-2-1004, PE00000001)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Digital Media Forensic Detection
- Social Sciences › Sociology and Political Science › Misinformation and Its Impacts
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Generative Adversarial Networks and Image Synthesis
- Keywords
- deepfake detection, multimodal fusion, audio-visual consistency, synthetic media, fusion techniques
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-09-29, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-09-29 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol and qwen3.8-omni-flash).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
