

The DOI matches its Crossref record; 113 of the 113 references it cites were found in a registry or an index; none of the 100 sources its claims cite is checked for support yet.
Perils and opportunities in using large language models in psychological research
Open accessAbstract
The emergence of large language models (LLMs) has sparked considerable interest in their potential application in psychological research, mainly as a model of the human psyche or as a general text-analysis tool. However, the trend of using LLMs without sufficient attention to their limitations and risks, which we rhetorically refer to as “GPTology”, can be detrimental given the easy access to models such as ChatGPT. Beyond existing general guidelines, we investigate the current limitations, ethical implications, and potential of LLMs specifically for psychological research, and show their concrete impact in various empirical studies. Our results highlight the importance of recognizing global psychological diversity, cautioning against treating LLMs (especially in zero-shot settings) as universal solutions for text analysis, and developing transparent, open methods to address LLMs’ opaque nature for reliable, reproducible, and robust inference from AI-generated data. Acknowledging LLMs’ utility for task automation, such as text annotation, or to expand our understanding of human psychology, we argue for diversifying human samples and expanding psychology’s methodological toolbox to promote an inclusive, generalizable science, countering homogenization, and over-reliance on LLMs.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
The paper warns against “GPTology”—the hurried, unjustified use of large language models as replacements for human participants or as universal text-analysis tools in psychology. It combines review with empirical demonstrations showing LLM biases, reduced response variance, weak zero-shot annotation, and reproducibility problems, while arguing LLMs can still aid research if validated, fine-tuned, and used cautiously.
Key findings
- GPT-3.5’s responses to the Moral Foundations Questionnaire-2 across 1,000 queries had 43–121 times smaller variance than human data across six moral domains (all *P*s < 0.001), and its moral-value network differed substantially from a diverse human sample (*N* = 3,902 from 19 populations).
- Across self-report measures from over 43 countries, ChatGPT showed significantly less variance and demographic differences; for example, it was more agreeable than politically liberal (*d* = −0.230), conservative (*d* = −0.403), and moderate (*d* = −0.285) individuals, and endorsed less right-wing authoritarianism than male (*d* = 0.44), White (*d* = 0.35), and younger 18–24 (*d* = 0.49) participants.
- For moral-language annotation of 2,983 social media posts, fine-tuned BERT achieved F1 = 0.48 and fine-tuned ChatGPT-3.5 achieved F1 = 0.53, outperforming zero-shot ChatGPT (F1 = 0.22), LIWC (F1 = 0.27), and few-shot ChatGPT (F1 = 0.32); zero-shot ChatGPT was over 10 times more likely to predict a text as moral compared with human raters (Δodds = +1,240%, *P* < 0.001).
- Minor prompt changes significantly altered outputs: adding a study introduction to the Big Five Inventory reduced Openness (*d* = −0.30), Extraversion (*d* = −0.54), and Agreeableness (*d* = −0.14); a modified moral prompt changed care (−56%), equality (−62%), loyalty (−33%), authority (+71%), and purity (+164%) annotations.
Methods
- The paper combines a critical review with original empirical analyses. It administered the MFQ-2 to GPT-3.5 1,000 times and compared responses with a culturally diverse human sample from 19 populations, then extended comparisons to self-report measures from over 43 countries, including Big Five Inventory (*N* = 3,924), Need for Closure (*N* = 315), Need for Cognition (*N* = 900), Right-wing authoritarianism (*N* = 1,020), Empathizing–Systemizing (*N* = 3,141), and Rational–Experiential Inventory (*N* = 1,456).
- For text analysis, ChatGPT annotated 2,983 social media posts for moral language in zero-shot, few-shot, and fine-tuned settings; results were compared with fine-tuned BERT, LIWC, human raters, and Contextualized Construct Representation (CCR). The authors also tested prompt modifications and an open-source LLaMA-based pipeline.
- Main analyses included variance comparisons, effect sizes (*d*), F1 scores, odds changes, inter-correlations and partial-correlation networks, and Dunnett’s tests.
Limitations
- Stated: the authors note that LLMs are rapidly evolving and that the concerns raised “could already be mitigated in the near future”; they also caution that open-source models do not fully solve the black-box problem, prompting may be insufficient to close demographic bias gaps, fine-tuning is resource-intensive, and few-shot learning depends on example quality and stability.
- Stated: closed-source models lack freely available past versions, and even added parameters such as “seed” do not guarantee reproducibility; “system_fingerprint” increases transparency but not reproducibility itself.
- Evident from the text: the empirical demonstrations focus on GPT-3.5/ChatGPT and selected psychological measures and annotation tasks, so the specific numerical findings may not generalize to all LLMs, model versions, or research domains.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
57 Not checked yet · 44 Own result · 25 Own interpretation · 12 No basis given · 1 Own method
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“GPT-3.5’s variance was 43–121 times smaller than human data in different moral domains, even when using parameter settings for maximum variability in generated responses.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Differences of this kind and strength were observed across all surveys and demographic groups.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
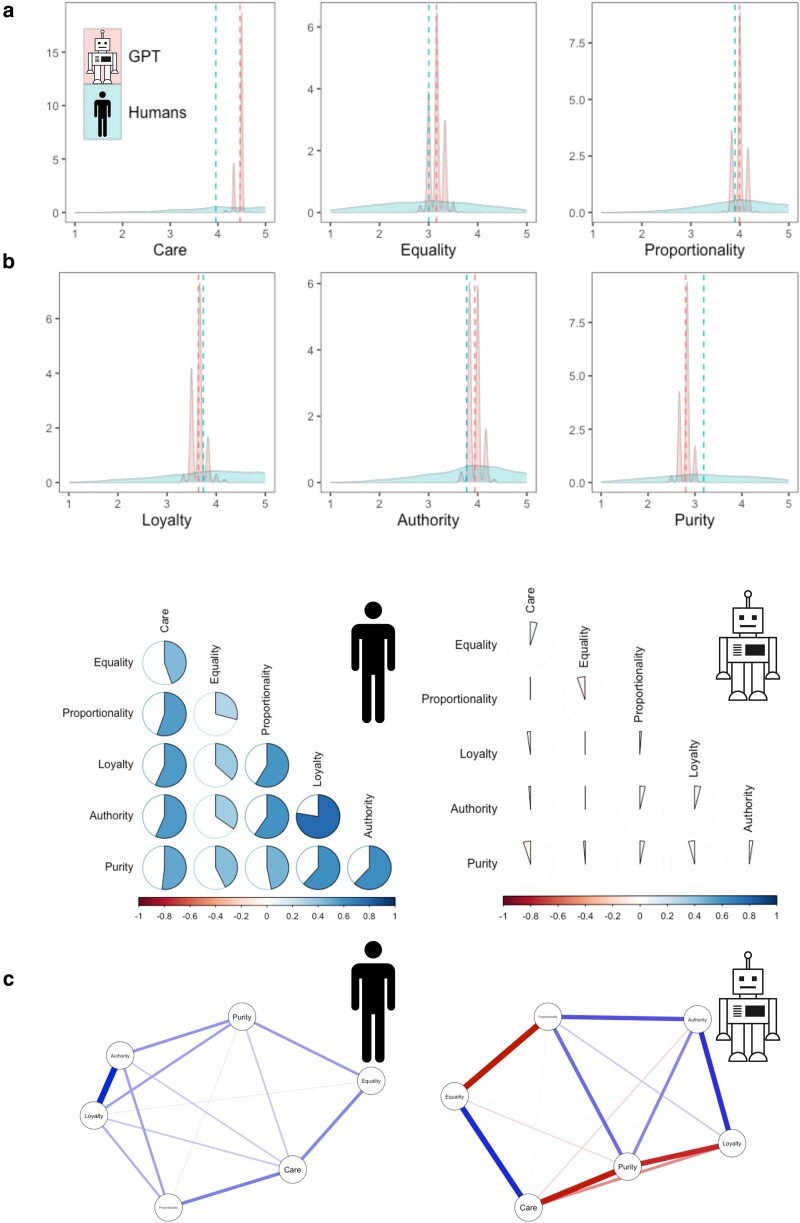
“As shown in Fig. 1(b) and (c), the networks of moral values are substantially different, indicating that GPT struggles to produce previously established nomological networks.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
hedgedn = 3,902- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
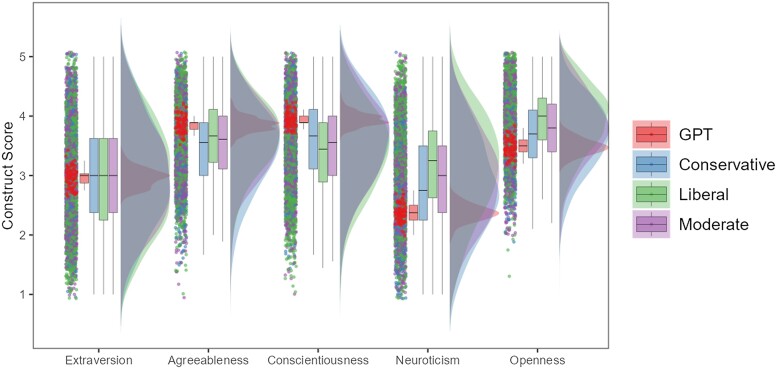
“For example, when responding to personality surveys, ChatGPT was significantly more agreeable than politically liberal individuals (d=−0.230, P<0.001, 95% CI [−0.369, −0.091]), conservatives (d=−0.403, P<0.001, 95% CI [−0.550, −0.257]), and moderates (d=−0.285, P<0.001, 95% CI [−0.424, −0.145]) as shown in Fig. 2.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
plaincorrelationaln = 3,924 ·- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As can be seen in Fig. 1(a), GPT produces substantially smaller variance in six moral domains (i.e. care, equality, proportionality, loyalty, authority, and purity) compared with actual human populations (all Ps<0.001).”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Additionally, the performance of both zero-shot and few-shot ChatGPT was extremely poor on several foundations, often reaching F1 scores of nearly zero.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Particularly, we find that fine-tuning ChatGPT leads to significant improvement in identifying the Loyalty foundation (about 25% increase in F1 score) and Care foundation (about 10% increase in F1 score).”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“In fact, our fine-tuned BERT model demonstrated superior performance over both GPT-4 and GPT-4-Turbo across all foundations except the Loyalty foundation, and fine-tuned GPT-3.5 outperformed GPT-4 and GPT-4-Turbo (zero-shot) on all foundations.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites Rathje et al. (75) Rathje, 2023
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Notably, ChatGPT (zero-shot) showed significantly more false positives, being over 10 times more likely Δodds=+1,240%,P<0.001 to predict a text as moral compared to human raters (see Table S2).”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We find that fine-tuned BERT vastly outperformed ChatGPT applied in a zero-shot setting, achieving an F1 score of 0.48 vs. ChatGPT’s 0.22.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- It may state two separate claims as one. 38
- Probably not a substantial claim. 17
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
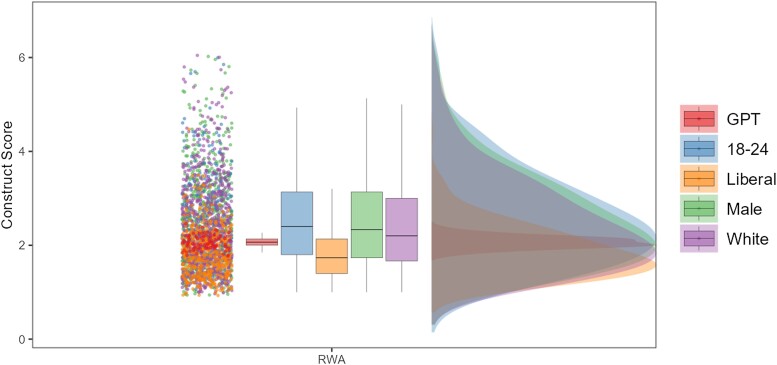
“Across these psychological constructs, we consistently found that ChatGPT responses generally showed significantly less variance across all measures (see Table S20 for an overview of variance differences across all surveys) and differed significantly between various demographics.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
plaincorrelationaln = 3,924 ·- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Further comparisons (Tables S7 and S8 in Rathje et al. (75)) on another moral foundations dataset, on which the BERT model was not fine-tuned (MFTC; (81)), showed that BERT, despite being applied cross-context, outperformed GPT-4 on the Authority and Purity foundations, and GPT-4-Turbo also on the Loyalty foundation.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites Rathje et al. (75) Rathje, 2023
- Not checked yetcites [81] Hoover, 2020, Moral foundations twitter corpus: a collection of 35k tweets annotated for moral sentiment, Soc Psychol Personal Sci source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Notably, even the LIWC-based approach outperformed ChatGPT (zero-shot) with an F1 score of 0.27 and was significantly less likely and less extreme in deviating from trained human annotators, despite being a magnitudes smaller, less complex, and cheaper model.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Interestingly, even our zero-shot application of GPT-3.5 outperformed the reported GPT-4 results on three foundations (Care, Proportionality, Authority), indicating inconsistent advancements between newer and older models.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites Rathje et al. (75) Rathje, 2023
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Our fine-tuned models also performed substantially better on average, with fine-tuned BERT achieving an average F1 score of 0.48 and fine-tuned ChatGPT-3.5 an average score of 0.53, compared with reported F1 scores of 0.34 for GPT-4 and 0.29 for GPT-4-Turbo.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites Rathje et al. (75) Rathje, 2023
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“GPT-4 performed slightly better than BERT on the Loyalty foundation and significantly better only on the Care foundation.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites Rathje et al. (75) Rathje, 2023
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, ChatGPT was more extreme in over- or under-predicting a moral sentiment, while BERT did in all but one case not significantly deviate from trained human annotators.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, note that in our experiments, ChatGPT was still more extreme in over- or under-predicting individual moral sentiments compared with BERT, which replicated the distribution of moral foundations most similar to human annotators.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As anticipated, both few-shot learning and fine-tuning increased the performance of ChatGPT in our experiments.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Similarly, our additional analyses, showing increased performance for ChatGPT when predicting at the item level instead of the construct level, highlight that LLMs can benefit from integrating theory-driven approaches.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Despite the model’s significantly smaller size (7 billion vs. 175 billion parameters) and while being self-hosted on consumer-grade hardware, it achieved a comparable performance in a text annotation task discussed above (F1 of 0.23 vs. 0.22) and a similar response pattern when answering self-report psychological measures.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“was significantly less likely to annotate the care foundation (−56%, P<0.001), the equality foundation (−62%, P<0.001), the loyalty foundation (−33%, P=0.009), and significantly more likely to annotate the authority foundation (+71%, P<0.001), and purity foundation (+164%, P=0.020).”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“For example, ChatGPT has shown gender biases favoring male perspectives and narratives (35, 36), cultural biases toward American perspectives (37) or majority populations in general (38), and political biases favoring liberal, environmental, and left-libertarian viewpoints (11, 39, 40).”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
What the sources say
- Not checked yetcites [37] Cao, 2023
- Not checked yetcites [38] Chen, 2022
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Models like GPT have been trained chiefly on WEIRD (Western, Educated, Industrialized, Rich, Democratic; (32)) people’s textual data primarily in English, perpetuating the English-centricity of psychology (33), hindering efforts to take linguistic diversity seriously.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
What the sources say
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Furthermore, the difference in convenience between zero-shot applications of LLMs and fine-tuning of models may not be as stark as commonly perceived.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
- Rests on an assumption: Fine-tuned small(er) language models for various tasks are now increasingly publicly available.
- Rests on an assumption: There are more and more high-quality and specialized datasets available to researchers for fine-tuning language models themselves.
None of the sources cited for this claim have been checked yet.
In the paper
“See also the discussion of environmental costs of LLMs in the Supplementary Materials, as training and deploying LLMs is energy intensive and therefore connected to significant carbon emissions (92, 93).”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites [92] Bender, 2021
- Not checked yetcites [93] Strubell, 2019
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“We suggest a slightly different narrative, given that the fine-tuned model still outperformed GPT-4-Turbo on three out of four foundations (and two out of four for GPT-4) and performed better on average than both.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites Rathje et al. (75) Rathje, 2023
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“However, the output variance when repeating the same prompt using a temperature of 1 then simply reflects the output probability over the response options and therefore how sure the model is about its response, which itself is affected by the correct answer bias observed by Park et al. (17) and others.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
What the sources say
- Not checked yetcites [17] Park, 2024, Diminished diversity-of-thought in a standard large language model, Behav Res source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Kocoń et al. (76) found that LLMs may struggle with complex, subjective tasks such as emotion recognition, and Huang et al. (18) found that LLMs can reinforce lay perspectives when detecting implicit hate speech and may thus mislead nonexperts with their explanations in cases where they make incorrect decisions.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites [18] Huang, 2023
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“However, this perspective of LLMs, as a convenient and comprehensive tool in psychological text analysis, is challenged by recent critiques emphasizing their limitations, such as inconsistencies in text annotations, difficulties in explaining complex constructs such as implicit hate speech, and a potential lack of depth in specialized or sensitive areas (18, 76, 77).”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites [18] Huang, 2023
- Not checked yetcites [76] Kocoń, 2023, ChatGPT: Jack of all trades, master of none, Inf Fusion source
- Not checked yetcites [77] Reiss, 2023
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Furthermore, Reiss (77) demonstrated that LLMs may produce inconsistent outputs when subjected to minor prompt variations and can fall short of scientific thresholds for reliability, sometimes even when pooling outputs from multiple repetitions and prompts.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites [77] Reiss, 2023
boostedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Human morality has also been argued to be a particularly difficult concept to grasp for language models, making it an interesting test case for comparing powerful LLMs against less complex smaller language models (90), as well as testing the efficacy of different LLM application strategies.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
What the sources say
- Not checked yetcites [90] Russell, 2019
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“For instance, Webb et al. (26) examined the analogical reasoning abilities of ChatGPT and found that it had developed an emergent capacity for zero-shot reasoning, allowing it to solve a wide range of analogy problems without explicit training.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
What the sources say
- Not checked yetcites [26] Webb, 2023, Emergent analogical reasoning in large language models, Nat Hum Behav source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These findings show that, first, LLMs’ supposed cross-context and flexibility advantages may not always hold, and second, that using LLMs conveniently “out-of-the-box” can sometimes drastically fail while highlighting that fine-tuning can mitigate the very same issues.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“This is because moral values are often only implicitly signaled in language, and online posts often contain little contextual information due to length constraints.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The MFQ-2 is a new measure published in 2023, and its items are unlikely to exist verbatim in the corpora on which GPT was trained; hence, it does not have the problem of extensively appearing in the training corpora.”
§ Perils and opportunities in using large language models in psychological research > LLMs should not replace human participants
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It should be noted here that while fine-tuning ChatGPT or applying a few-shot paradigm can yield better results, such processes are significantly more resource-intensive and expensive compared with LIWC or even BERT.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“This is because moral values are often only implicitly signaled in language, and online posts often contain little contextual information due to length constraints.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We caution against mistakenly treating the use of open-source rather than closed-source LLMs as sufficient to solve the black-box problem: a problem that remains largely unsolved, even for open-source LLMs.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Compared with closed-source LLMs, open-source LLMs may thus come with a replicability benefit and increased control over the model when it comes to computational–psychological research.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“One of the main advantages of computational models is that they allow us to “look under the hood” and thus make inferences about psychological processes that may be difficult to test otherwise.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Across our experiments, we found that LLMs can achieve high performances but stress that this cannot always be achieved using the model’s zero-shot capabilities and instead requires exploring techniques, such as few-shot prompting or outright fine-tuning of the LLM”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Particularly in cases where data for fine-tuning is scarce, such as with new constructs or understudied populations, LLMs’ zero-shot capabilities may still offer acceptable performances and allow researchers to investigate urgent research questions.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Such lack of transparency is antithetical to the scientific principles of openness and replicability that should be central to computational–psychological research (106).”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
What the sources say
- Not checked yetcites [106] Hofman, 2021, Integrating explanation and prediction in computational social science, Nature source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Additionally, ChatGPT and other closed-source models require (if possible at all) fine-tuning on a corporate platform, which introduces constraints compared with models like BERT which provide full control about the fine-tuning process and can be trained offline without additional costs”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Overall, our results show that LLMs can be a superior tool but they also show that achieving this level of performance might not always be trivial and convenient.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For example, fine-tuning can be costly, might not always work, and negates many of the conveniences of using LLMs in a zero-shot setting by requiring a dataset for training and expertise with training models.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, the “seed” does not guarantee reproducibility, and while the “system_fingerprint” increases transparency, allowing researchers to identify potential reasons for failure to replicate, it does not increase reproducibility itself.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Additionally, openness is a spectrum requiring researchers to closely monitor to what extent LLMs fulfill relevant openness criteria for their projects.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
What the sources say
- Not checked yetcites [110] Liesenfeld, 2023
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
None of the sources cited for this claim have been checked yet.
In the paper
“This means that even when updates address and mitigate detected biases, they also introduce the potential for “process reproducibility failure” (98) in the generated data and impede reproducibility, critical for scientific rigor (15, 100, 101).”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
What the sources say
- Not checked yetcites [98] Nosek, 2022, Replicability, robustness, and reproducibility in psychological science, Annu Rev Psychol source
- Not checked yetcites [15] Bail, 2024, Can generative AI improve social science?, Proc Natl Acad Sci U S A source
- Not checked yetcites [100] Spirling, 2023, Why open-source generative AI models are an ethical way forward for science, Nature source
- Not checked yetcites [101] Zhai, 2023, Chatgpt for next generation science learning, XRDS: Crossroads ACM Mag Stud source
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Taken together, past work and our present findings consistently demonstrate that for many use cases, smaller (fine-tuned) models can be more powerful and less biased than the current large (generative) language models, particularly in zero-shot and few-shot settings.”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The overconfidence with which researchers may trust open-source LLMs’ findings as replicable and transparent can systematically cause such researchers to over-rely on these findings, even in out-of-distribution settings where the findings may not generalize.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
In the paper
“Wang et al. (34) argued that due to their training processes, LLMs inherently struggle with accurately representing identity groups, often leading to distorted, simplified, and stereotypical portrayals of these groups.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
What the sources say
- Not checked yetcites Wang et al. (34) Wang, 2024
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
In the paper
“Our research emphasizes the importance of considering context and specific prompts when using ChatGPT to emulate diverse human behaviors (125).”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
What the sources say
- Not checked yetcites [125] Rao, 2023
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, OpenAI offers embedding models, such as “text-embedding-ada-3,” that can be used in a similar manner to BERT for downstream tasks.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“GPTology—which we define as the hurried and unjustified application of LLMs either as “replacements” for human participants, or as an off-the-shelf “one-size-fits-all” method in psychological text analysis—can lead to a proliferation of low-quality research, especially if the convenience of using LLMs such as ChatGPT leads researchers to rely too heavily on them.”
§ Perils and opportunities in using large language models in psychological research > Conclusion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Continuous algorithmic changes necessitate ongoing validation of prompting strategies, a task made challenging by the complex and opaque nature of LLMs (72, 123, 126).”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
What the sources say
- Not checked yetcites [72] Liu, 2023, Pre-train, prompt, and predict: a systematic survey of prompting methods in natural language processing, ACM Comput Surv source
- Not checked yetcites [123] Mishra, 2023
- Not checked yetcites [126] Jiang, 2022
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“While LLMs, especially fine-tuned ones, can achieve impressive performances on many tasks, the presence of a WEIRD bias, along with the opaque and often irreproducible nature of these models, particularly the proprietary ones, makes them a double-edged sword for psychological research.”
§ Perils and opportunities in using large language models in psychological research > Conclusion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It is further crucial to recognize that many advantages attributed to LLMs are also present in other models.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The newest generation of LLMs offered as an online service (e.g. ChatGPT, Gemini, Claude) provide many researchers with an accessible yet powerful tool—representing a pivotal advancement.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For instance, models such as BERT or open-source LLMs can be accessed via APIs, providing a convenient and low-cost option for researchers who cannot self-host these technologies.”
§ Perils and opportunities in using large language models in psychological research > Reproducibility matters
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
The paper relies on this without support.
LLMs are trained on vast amounts of data that can contain many of the items and tasks used in psychological experiments, leading the model to rely on its memory instead of making inferences.
“Furthermore, LLMs are trained on vast amounts of data, which can contain many of the items and tasks used in psychological experiments, thus leading the model to rely on its memory instead of making inferences, exacerbating the problem above.”
The paper relies on this without support.
LLMs largely operate as black-boxes.
“However, unlike traditional agent-based models, which define the environment, agents, interactions, and their consequences to allow for inferences based on these parameters, LLMs largely operate as black-boxes.”
The paper relies on this without support.
Fine-tuned small(er) language models for various tasks are now increasingly publicly available.
“Fine-tuned small(er) language models for various tasks are now increasingly publicly available.”
The paper relies on this without support.
There are more and more high-quality and specialized datasets available to researchers for fine-tuning language models themselves.
“Similarly, there are more and more high-quality and specialized datasets available to researchers for fine-tuning language models themselves.”
The paper relies on this without support.
Human annotations provide a valid ground truth for moral language classification.
“We compared the annotations of all models against the “ground truth” of human raters.”
The paper relies on this without support.
ChatGPT's behavior is representative of large language models generally.
“Building on this perspective, we extend these recent studies by investigating ChatGPT’s ability to annotate moral language across three distinct settings: zero-shot, few-shot, and fine-tuned.”
The paper relies on this without support.
The human annotator demographics and psychometrics provided for the test data are accurate and valid for assessing annotation bias.
“We did so by using human annotator demographics and psychometrics provided for our test data (see Supplementary Materials for a detailed description of the experimental procedures).”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Additionally, GPT itself can be fine-tuned to further increase its performance. For instance, one paper found that fine-tuned GPT outperformed even fine-tuned BERT at detecting moral foundations (73).”
From GPT is an effective tool for multilingual psychological text analysis (2024) · cites this paper as [73]
In the citing paper
“the output of human annotators, like GPT, is also not reproducible and usually has far lower test–retest reliability (73).”
From GPT is an effective tool for multilingual psychological text analysis (2024) · cites this paper as [73]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
“it is biased toward annotators who have a lower preference for equality (Δodds=−97%, P<0.001)”
§ Perils and opportunities in using large language models in psychological research > LLMs are not a panacea for text analysis
“Agreement with proportionality and equality endorsing annotators aligns with past findings that ChatGPT is (left-)libertarian-leaning (11, 39, 40).”
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173 · cited 1×
“For instance, in most reported cases in Rathje et al. (75), small fine-tuned language models, including older models such as base-BERT (Bidirectional Encoder Representations from Transformers; (65)), outperform even the newest generation of ChatGPT (GPT-4) on a variety of text annotation tasks.”
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372 · cited 3×
“…to adjusting the entire Recently, there has been a surge of studies using LLMs zero-shot capabilities, that is their capability to perform tasks without any prior training on that specific task (8, 71 – 73), for psychological text analysis, presumably due to their ease of use and accessibility.”
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515 · cited 1×
“Additionally, these smaller language models have since then further undergone significant improvement, such as Sentence-BERT (85), RoBERTa (86), and their subsequent iterations, highlighting additional potential perform - ance advantages.”
LoRA: Low-Rank Adaptation of Large Language Models
Hu, E. J., Shen, Y., Wallis, P., Allen-Zhu, Z., Li, Y., Wang, S., Wang, L., & Chen, W. (2021) · arXiv · doi:10.48550/arxiv.2106.09685 · Cited by 13,453
The weirdest people in the world?
Henrich, J., Heine, S. J., & Norenzayan, A. (2010) · Behavioral and Brain Sciences · doi:10.1017/s0140525x0999152x · Cited by 12,641
Elman, J. L. (1990) · Cognitive Science · doi:10.1207/s15516709cog1402_1 · Cited by 11,212 · cited 1×
“Building upon these developments and motivated by theories in working memory and cognitive processes, Elman (5) introduced recurrent neural networks, enabling researchers to model sequential data in language models.”
Prototypical Networks for Few-shot LearningPreprint
Snell, J., Swersky, K., & Zemel, R. S. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1703.05175 · Cited by 6,245 · cited 1×
“There are various alternative ways to utilize LLMs, such as by fine-tuning the LLM on the respective task, or via few-shot prompting which includes few examples of solving a task in a prompt so that the LLM can generalize to the given examples (8, 72, 87).”
Cacioppo, J. T., & Petty, R. E. (1982) · Journal of Personality and Social Psychology · doi:10.1037/0022-3514.42.1.116 · Cited by 5,359
LLaMA: Open and Efficient Foundation Language Models
Touvron, H., Lavril, T., Izacard, G., Martinet, X., Lachaux, M.-A., Lacroix, T., Rozière, B., Goyal, N., Hambro, E., Azhar, F., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.13971 · Cited by 4,602 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Liu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2023) · ACM Computing Surveys · doi:10.1145/3560815 · Cited by 4,361
Liu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2021) · arXiv · doi:10.48550/arxiv.2107.13586 · Cited by 4,352
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q., & Zhou, D. (2022) · arXiv · doi:10.48550/arxiv.2201.11903 · Cited by 4,263
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Energy and Policy Considerations for Deep Learning in NLP
Strubell, E., Ganesh, A., & McCallum, A. (2019) · arXiv · doi:10.48550/arxiv.1906.02243 · Cited by 3,735 · cited 1×
“See also the discussion of environmental costs of LLMs in the Supplementary Materials, as training and deploying LLMs is energy intensive and therefore connected to significant carbon emissions (92, 93).”
Lazer, D., Pentland, A., Adamic, L., Aral, S., Barabási, A.-L., Brewer, D., Christakis, N., Contractor, N., Fowler, J., Gutmann, M., et al. (2009) · Science · doi:10.1126/science.1167742 · Cited by 3,365
Self-reports: How the questions shape the answers.
Schwarz, N. (1999) · American Psychologist · doi:10.1037/0003-066x.54.2.93 · Cited by 2,846 · cited 2×
“The changes to the prompts were derived from past work that showed how minor changes to the self-report design, such as adding contextual information or changing the response scale, can elicit different response patterns (124).”
Individual differences in need for cognitive closure.
Webster, D. M., & Kruglanski, A. W. (1994) · Journal of Personality and Social Psychology · doi:10.1037/0022-3514.67.6.1049 · Cited by 2,494
Linguistic Inquiry and Word Count (LIWC)
Chung, C. K., & Pennebaker, J. W. (2012) · IGI Global eBooks · doi:10.4018/978-1-60960-741-8.ch012 · Cited by 2,215
Large Language Models are Zero-Shot Reasoners
Kojima, T., Gu, S. S., Reid, M., Matsuo, Y., & Iwasawa, Y. (2022) · arXiv · doi:10.48550/arxiv.2205.11916 · Cited by 2,013
Large language models are zero-shot reasoners
Kojima, T., Gu, S. (., Reid, M., Matsuo, Y., & Iwasawa, Y. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1613 · Cited by 2,013
The Ethics of AI Ethics: An Evaluation of Guidelines
Hagendorff, T. (2020) · Minds and Machines · doi:10.1007/s11023-020-09517-8 · Cited by 1,911
The Ethics of AI Ethics -- An Evaluation of Guidelines
Hagendorff, T. (2019) · arXiv · doi:10.48550/arxiv.1903.03425 · Cited by 1,907
ChatGPT: five priorities for research
van Dis, E. A. M., Bollen, J., Zuidema, W., van Rooij, R., & Bockting, C. L. (2023) · Nature · doi:10.1038/d41586-023-00288-7 · Cited by 1,842
Zero-Shot Learning—A Comprehensive Evaluation of the Good, the Bad and the Ugly
Xian, Y., Lampert, C. H., Schiele, B., & Akata, Z. (2019) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2857768 · Cited by 1,678
Ease of retrieval as information: another look at the availability heuristic
Schwarz, N., Bless, H., Strack, F., Klumpp, G., Rittenauer-Schatka, H., & Simons, A. (1991) · Journal of Personality and Social Psychology · doi:10.1037/0022-3514.61.2.195 · Cited by 1,412 · cited 1×
“While these challenges do not negate the applicability of LLMs in psychological research, they do highlight the need for robust, standardized methods akin to those used in traditional human research (124, 127).”
Pacini, R., & Epstein, S. J. (1999) · Journal of Personality and Social Psychology · doi:10.1037/0022-3514.76.6.972 · Cited by 1,258
Distributed memory and the representation of general and specific information.
McClelland, J. L., & Rumelhart, D. (1985) · Journal of experimental psychology. General · doi:10.1037/0096-3445.114.2.159 · Cited by 1,160 · cited 1×
“For example, inspired by the psychology of feedback and learning mechanisms, McClelland and Rumelhart (3) explored connectionist models demonstrating the potential of neural networks, and Rumelhart et al. (4) introduced key algorithms like backpropagation.”
Distributed memory and the representation of general and specific information.
McClelland, J. L., & Rumelhart, D. E. (1985) · Journal of Experimental Psychology General · doi:10.1037//0096-3445.114.2.159 · Cited by 1,129
Baron-Cohen, S., Richler, J., Bisarya, D., Gurunathan, N., & Wheelwright, S. (2003) · Philosophical Transactions of the Royal Society of London. Series B: Biological Sciences · doi:10.1098/rstb.2002.1206 · Cited by 870
(2019) · Cited by 771
Replicability, Robustness, and Reproducibility in Psychological Science
Nosek, B. A., Hardwicke, T. E., Moshontz, H., Allard, A., Corker, K. S., Dreber, A., Fidler, F., Hilgard, J., Kline Struhl, M., Nuijten, M. B., et al. (2022) · Annual Review of Psychology · doi:10.1146/annurev-psych-020821-114157 · Cited by 770
ChatGPT: Jack of all trades, master of none
Kocoń, J., Cichecki, I., Kaszyca, O., Kochanek, M., Szydło, D., Baran, J., Bielaniewicz, J., Gruza, M., Janz, A., Kanclerz, K., et al. (2023) · Information Fusion · doi:10.1016/j.inffus.2023.101861 · Cited by 758
Muthukrishna, M., & Henrich, J. (2019) · Nature Human Behaviour · doi:10.1038/s41562-018-0522-1 · Cited by 745 · cited 1×
“…outperform top-down methods in zero or few-shot settings, this would be another reason for psychologists (and other social scientists) to consider using top-down models rather than LLMs (at least the existing ones), because in social sciences, theory and interpretability are of prime concern (95).”
Corporate Social Responsibility: Three Key Approaches
Windsor, D. (2006) · Journal of Management Studies · doi:10.1111/j.1467-6486.2006.00584.x · Cited by 713 · cited 1×
“As such, researchers should consider to what extent each model and the organization behind it conflicts with scientific and ethical principles of research (111 – 113).”
Artificial intelligence and illusions of understanding in scientific research
Messeri, L., & Crockett, M. J. (2024) · Nature · doi:10.1038/s41586-024-07146-0 · Cited by 707
Fantastically Ordered Prompts and Where to Find Them: Overcoming Few-Shot Prompt Order Sensitivity
Lu, Y., Bartolo, M., Moore, A., Riedel, S., & Stenetorp, P. (2021) · arXiv · doi:10.48550/arxiv.2104.08786 · Cited by 615
The neglected 95% revisited: Is American psychology becoming less American?
Thalmayer, A. G., Toscanelli, C., & Arnett, J. J. (2021) · American Psychologist · doi:10.1037/amp0000622 · Cited by 521 · cited 1×
“(45)).”
Dale, R. (2020) · Natural Language Engineering · doi:10.1017/s1351324920000601 · Cited by 509
Bozkurt, A., Xiao, J., Lambert, S., Pazurek, A., Crompton, H., Koseoglu, S., Farrow, R., Bond, M., Nerantzi, C., Honeychurch, S., et al. (2023) · Dublin City University Open Access Institutional Repository (Dublin City University) · doi:10.5281/zenodo.7636567 · Cited by 454
Fine-Tuning Language Models from Human Preferences
Ziegler, D. M., Stiennon, N., Wu, J., Brown, T. B., Radford, A., Amodei, D., Christiano, P., & Irving, G. (2019) · arXiv · doi:10.48550/arxiv.1909.08593 · Cited by 413 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Can AI language models replace human participants?
Dillion, D., Tandon, N., Gu, Y., & Gray, K. (2023) · Trends in Cognitive Sciences · doi:10.1016/j.tics.2023.04.008 · Cited by 405
Morality beyond the WEIRD: How the nomological network of morality varies across cultures.
Atari, M., Haidt, J., Graham, J., Koleva, S. P., Stevens, S. T., & Dehghani, M. (2023) · Journal of Personality and Social Psychology · doi:10.1037/pspp0000470 · Cited by 405
Self-citationAI as Agency Without Intelligence: on ChatGPT, Large Language Models, and Other Generative Models
Floridi, L. (2023) · Philosophy & Technology · doi:10.1007/s13347-023-00621-y · Cited by 404
Emergent analogical reasoning in large language models
Webb, T., Holyoak, K. J., & Lu, H. (2023) · Nature Human Behaviour · doi:10.1038/s41562-023-01659-w · Cited by 404
Bennett, C., Miller, M., & Wolford, G. (2009) · NeuroImage · doi:10.1016/s1053-8119(09)71202-9 · Cited by 400
Implications of the Credibility Revolution for Productivity, Creativity, and Progress
Vazire, S. (2018) · Perspectives on Psychological Science · doi:10.1177/1745691617751884 · Cited by 398 · cited 1×
“To prevent issues like nonsensical, but statistically significant correlations, it is essential to approach LLMs with caution, keeping in mind similar challenges the field has faced in recent decades (e.g. the credibility revolution; (23)).”
Over-reliance on English hinders cognitive science
Blasi, D. E., Henrich, J., Adamou, E., Kemmerer, D., & Majid, A. (2022) · Trends in Cognitive Sciences · doi:10.1016/j.tics.2022.09.015 · Cited by 396
Talking about Large Language Models
Shanahan, M. (2024) · Communications of the ACM · doi:10.1145/3624724 · Cited by 381
Construction of a short version of the Right-Wing Authoritarianism (RWA) scale
Zakrisson, I. (2005) · Personality and Individual Differences · doi:10.1016/j.paid.2005.02.026 · Cited by 380
AI and the transformation of social science research
Grossmann, I., Feinberg, M., Parker, D. C., Christakis, N. A., Tetlock, P. E., & Cunningham, W. A. (2023) · Science · doi:10.1126/science.adi1778 · Cited by 377
Integrating explanation and prediction in computational social science
Hofman, J. M., Watts, D. J., Athey, S., Garip, F., Griffiths, T. L., Kleinberg, J., Margetts, H., Mullainathan, S., Salganik, M. J., Vazire, S., et al. (2021) · Nature · doi:10.1038/s41586-021-03659-0 · Cited by 371 · cited 1×
“Such lack of transparency is antithetical to the scientific principles of openness and replicability that should be central to computational – psychological research (106).”
Assessing Cross-Cultural Alignment between ChatGPT and Human Societies: An Empirical StudyPreprint
Cao, Y., Zhou, L., Lee, S., et al. (2023) · C3NLP · doi:10.48550/arxiv.2303.17466 · Cited by 370 · cited 1×
“For example, ChatGPT has shown gender biases favoring male perspectives and narratives (35, 36), cultural biases toward American perspectives (37) or majority populations in general (38), and political biases favoring liberal, environmental, and left-libertarian viewpoints (11, 39, 40).”
Using large language models in psychology
Demszky, D., Yang, D., Yeager, D. S., Bryan, C. J., Clapper, M., Chandhok, S., Eichstaedt, J. C., Hecht, C., Jamieson, J., Johnson, M., et al. (2023) · Nature Reviews Psychology · doi:10.1038/s44159-023-00241-5 · Cited by 369
Can Generative AI improve social science?
Bail, C. A. (2024) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2314021121 · Cited by 369
Bozkurt, A., Xiao, J., Lambert, S., Pazurek, A., Crompton, H., Koseoglu, S., Farrow, R., Bond, M., Nerantzi, C., Honeychurch, S., et al. (2023) · Zenodo · doi:10.5281/zenodo.7636568 · Cited by 350
Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
Reimers, N., & Gurevych, I. (2019) · arXiv · doi:10.48550/arxiv.1908.10084 · Cited by 343 · cited 2×
“Additionally, these smaller language models have since then further undergone significant improvement, such as Sentence-BERT (85), RoBERTa (86), and their subsequent iterations, highlighting additional potential perform - ance advantages.”
Small-scale societies exhibit fundamental variation in the role of intentions in moral judgment
Barrett, H. C., Bolyanatz, A., Crittenden, A. N., Fessler, D. M. T., Fitzpatrick, S., Gurven, M., Henrich, J., Kanovský, M., Kushnick, G., Pisor, A. C., et al. (2016) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1522070113 · Cited by 338 · cited 1×
“First, research using LLMs to simulate human participants needs to pay more attention to the substantial cross-cultural variation in cognitive processes — including moral judgments — around the globe (see Refs (30, 31)) and develop robust ways to mimic them using synthetic agents.”
Bang, Y., Cahyawijaya, S., Lee, N., Dai, W., Su, D., Wilie, B., Lovenia, H., Ji, Z., Yu, T., Chung, W., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.04023 · Cited by 337 · cited 2×
“Many studies of state-of-the-art LLMs have concluded that their outputs are highly “human-like” (24 – 26).”
More human than human: measuring ChatGPT political bias
Motoki, F., Pinho Neto, V., & Rodrigues, V. (2024) · Public Choice · doi:10.1007/s11127-023-01097-2 · Cited by 329
Beyond WEIRD: A review of the last decade and a look ahead to the global laboratory of the future
Apicella, C. L., Norenzayan, A., & Henrich, J. (2020) · Evolution and Human Behavior · doi:10.1016/j.evolhumbehav.2020.07.015 · Cited by 302
Study and Analysis of Chat GPT and its Impact on Different Fields of Study
Kalla, D., Smith, N., Kuraku, S., & Samaah, F. (2023) · International Journal of Innovative Science and Research Technology (IJISRT) · doi:10.5281/zenodo.7767674 · Cited by 293
Prompting GPT-3 To Be ReliablePreprint
Si, C., Gan, Z., Yang, Z., Wang, S., Wang, J., Boyd-Graber, J. L., & Wang, L. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2210.09150 · Cited by 251 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Voodoo Correlations Are Everywhere—Not Only in Neuroscience
Fiedler, K. (2011) · Perspectives on Psychological Science · doi:10.1177/1745691611400237 · Cited by 248 · cited 1×
“…illustrated in an fMRI of post-mortem Atlantic Salmon (20), where the fish displayed apparent significant brain activity during the experiment despite being deceased, and a study on the high likelihood of finding spurious correlations in fMRI research due to statistical misapplications (21).”
Handbook of Personality Theory and Research
Crockett, H. J., Borgatta, E. F., & Lambert, W. W. (1971) · Social Forces · doi:10.2307/3005768 · Cited by 248
Huang, F., Kwak, H., & An, J. (2023) · arXiv · doi:10.48550/arxiv.2302.07736 · Cited by 231 · cited 4×
“Kocon ́ et al. (76) found that LLMs may struggle with complex, subjective tasks such as emotion recognition, and Huang et al. (18) found that LLMs can reinforce lay perspectives when detecting implicit hate speech and may thus mislead nonexperts with their explanations in cases where they make incorrect decisions.”
InfluentialWang, A., Morgenstern, J., & Dickerson, J. P. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.01908 · Cited by 212
Can ChatGPT Reproduce Human-Generated Labels? A Study of Social Computing TasksPreprint
Zhu, Y.-M., Zhang, P., Haq, E.-U., Hui, P., & Tyson, G. (2023) · arXiv.org · doi:10.48550/arxiv.2304.10145 · Cited by 183 · cited 2×
“For example, Markowitz (74), Rathje et al. (75) and Zhu et al. (19), reported high performance of ChatGPT as an automated text analysis tool, such as for sentiment analysis, offensive language, thinking style, or emotion detection.”
Chatgpt for next generation science learning
Zhai, X. (2023) · XRDS Crossroads The ACM Magazine for Students · doi:10.1145/3589649 · Cited by 178
Toxicity in ChatGPT: Analyzing Persona-assigned Language Models
Deshpande, A., Murahari, V., Rajpurohit, T., Kalyan, A., & Narasimhan, K. (2023) · arXiv · doi:10.48550/arxiv.2304.05335 · Cited by 178 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
The Self-Perception and Political Biases of ChatGPT
Rutinowski, J., Franke, S., Endendyk, J., Dormuth, I., & Pauly, M. (2023) · arXiv · doi:10.48550/arxiv.2304.07333 · Cited by 178
Moral foundations twitter corpus: a collection of 35k tweets annotated for moral sentiment
Hoover, J., Portillo-Wightman, G., Yeh, L., Havaldar, S., Davani, A. M., Lin, Y., Kennedy, B., Atari, M., Kamel, Z., Mendlen, M., et al. (2020) · Social Psychological and Personality Science · doi:10.1177/1948550619876629 · Cited by 177 · cited 1×
“Further comparisons (Tables S7 and S8in Rathje et al. (75)) on another moral foundations dataset, on which the BERT model was not fine-tuned (MFTC; (81)), showed that BERT, despite being applied cross-context, outperformed GPT-4 on the Authority and Purity foundations, and GPT-4-Turbo also on the…”
Self-citationAtari, M., Xue, M. J., Park, P. S., Blasi, D. E., & Henrich, J. (2023) · doi:10.31234/osf.io/5b26t · Cited by 151
Self-citationGPT is an effective tool for multilingual psychological text analysisPreprint
Rathje, S., Mirea, D.-M., Sucholutsky, I., Marjieh, R., Robertson, C., & Bavel, J. J. V. (2023) · doi:10.31234/osf.io/sekf5 · Cited by 129
Whose Opinions Do Language Models Reflect?
Santurkar, S., Durmus, E., Ladhak, F., Lee, C., Liang, P., & Hashimoto, T. (2023) · arXiv · doi:10.48550/arxiv.2303.17548 · Cited by 114
Can ChatGPT Assess Human Personalities? A General Evaluation FrameworkPreprint
Rao, H., Leung, C., & Miao, C. (2023) · Conference on Empirical Methods in Natural Language Processing · doi:10.48550/arxiv.2303.01248 · Cited by 111
Deep Reinforcement Learning from Policy-Dependent Human FeedbackPreprint
Arumugam, D., Lee, J. K., Saskin, S., & Littman, M. L. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1902.04257 · Cited by 107 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Why open-source generative AI models are an ethical way forward for science
Spirling, A. (2023) · Nature · doi:10.1038/d41586-023-01295-4 · Cited by 104
Turning large language models into cognitive modelsPreprint
Binz, M., & Schulz, E. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2306.03917 · Cited by 104 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Evaluating the logical reasoning ability of chatgpt and GPT-4
Liu, H., Ning, R., Teng, Z., Liu, J., Zhou, Q., & Zhang, Y. (2023) · arXiv · doi:10.48550/arxiv.2304.03439 · Cited by 100 · cited 1×
“…using LLMs to study human behavior need to move beyond methods that simulate single responses — such as merely predicting group averages or simulating an individual’s response across various tasks (e.g. (24, 25, 27)) — and instead develop robust methods to emulate the complexity of human samples.”
Interactive Natural Language ProcessingPreprint
Wang, Z., Zhang, G., Yang, K., Shi, N., Zhou, W., Hao, S., Xiong, G., Li, Y., Sim, M. Y., Chen, X., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.13246 · Cited by 90
Diminished diversity-of-thought in a standard large language model
Park, P. S., Schoenegger, P., & Zhu, C. (2024) · Behavior Research Methods · doi:10.3758/s13428-023-02307-x · Cited by 83
Self-citationOn Second Thought, Let’s Not Think Step by Step! Bias and Toxicity in Zero-Shot Reasoning
Shaikh, O., Zhang, H., Held, W., Bernstein, M., & Yang, D. (2022) · arXiv · doi:10.48550/arxiv.2212.08061 · Cited by 76
Probing the psychology of AI models
Shiffrin, R., & Mitchell, M. (2023) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2300963120 · Cited by 70
Mishra, A., Soni, U., Arunkumar, A., Huang, J., Kwon, B. C., & Bryan, C. (2023) · arXiv.org · doi:10.48550/arxiv.2304.01964 · Cited by 49
Towards Measuring the Representation of Subjective Global Opinions in Language Models
Durmus, E., Nguyen, K., Liao, T. I., Schiefer, N., Askell, A., Bakhtin, A., Chen, C., Hatfield-Dodds, Z., Hernandez, D., Joseph, N., et al. (2023) · arXiv · doi:10.48550/arxiv.2306.16388 · Cited by 48
Automated Annotation with Generative AI Requires Validation
Pangakis, N., Wolken, S., & Fasching, N. (2023) · arXiv · doi:10.48550/arxiv.2306.00176 · Cited by 47 · cited 1×
“…(110) discussing of LLM openness in detail as well as their openness ratings of current LLMs https://opening-up-chatgpt.github.io, including their specific openness criteria and evaluation strategies https://github.com/ opening-up-chatgpt/opening-up-chatgpt.github.io/tree/main/ projects#criteria.”
Predicting Personality from Social Media Text
Golbeck, J. (2016) · AIS Transactions on Replication Research · doi:10.17705/1atrr.00009 · Cited by 46
Rahman, A. U., & Halim, Z. (2022) · Multimedia Tools and Applications · doi:10.1007/s11042-022-13114-5 · Cited by 44
Should large language models replace human participants?Preprint
Crockett, M. J., & Messeri, L. (2023) · doi:10.31234/osf.io/4zdx9 · Cited by 43
MetaAgents: Large Language Model Based Agents for Decision-Making on Teaming
Li, Y., Sun, L., & Zhang, Y. (2023) · arXiv · doi:10.48550/arxiv.2310.06500 · Cited by 38
Hartmann, J., Schwenzow, J., & Witte, M. (2023) · arXiv · doi:10.48550/arxiv.2301.01768 · Cited by 37 · cited 2×
“For example, ChatGPT has shown gender biases favoring male perspectives and narratives (35, 36), cultural biases toward American perspectives (37) or majority populations in general (38), and political biases favoring liberal, environmental, and left-libertarian viewpoints (11, 39, 40).”
Testing the Reliability of ChatGPT for Text Annotation and Classification: A Cautionary Remark
Reiss, M. V. (2023) · arXiv · doi:10.48550/arxiv.2304.11085 · Cited by 34 · cited 2×
“…in psychological text analysis, is challenged by recent critiques emphasizing their limitations, such as inconsistencies in text annotations, difficulties in explaining complex constructs such as implicit hate speech, and a potential lack of depth in specialized or sensitive areas ( 18, 76, 77).”
Morality classification in natural language text
Pavan, M. C., dos Santos, V. G., Lan, A. G. J., Martins, J. T., dos Santos, W. R., Deutsch, C., da Costa, P. B., Hsieh, F. C., & Paraboni, I. (2023) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2020.3034050 · Cited by 30
PersonaLLM: Investigating the Ability of Large Language Models to Express Personality TraitsPreprint
Jiang, H., Zhang, X., Cao, X., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.02547 · Cited by 30
ChatGPT Is More Likely to Be Perceived as Male Than Female
Wong, J., & Kim, J. (2023) · arXiv.org · doi:10.48550/arxiv.2305.12564 · Cited by 24 · cited 1×
“For example, ChatGPT has shown gender biases favoring male perspectives and narratives (35, 36), cultural biases toward American perspectives (37) or majority populations in general (38), and political biases favoring liberal, environmental, and left-libertarian viewpoints (11, 39, 40).”
Atari, M., Omrani, A., & Dehghani, M. (2023) · PsyArXiv (OSF Preprints) · doi:10.31234/osf.io/m93pd · Cited by 24
Self-citationMarkowitz, D. M. (2024) · Behavior Research Methods · doi:10.3758/s13428-024-02344-0 · Cited by 19
Who's Harry Potter? Approximate Unlearning in LLMs
Eldan, R., & Russinovich, M. (2023) · arXiv · doi:10.48550/arxiv.2310.02238 · Cited by 19 · cited 2×
“To get unbiased evaluations of human-like LLM behavior, researchers need to make sure that their tasks are not part of the model’s training data (48) or adjust the models not to affect the outcome of their experiments, such as by “unlearning” data from an LLM (49).”
Large language models as models of human cognitionPreprint
Frank, M. C. (2023) · doi:10.31234/osf.io/wxt69 · Cited by 17
Pournaras, E. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.15299 · Cited by 15 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Kjell, O., Kjell, K., & Schwartz, H. A. (2023) · doi:10.31234/osf.io/yfd8g · Cited by 15
Ghosh, S., & Caliskan, A. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.10510 · Cited by 13
Opportunities and challenges of ChatGPT for design knowledge managementPreprint
Hu, X., Tian, Y., Nagato, K., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2304.02796 · Cited by 13 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Ji, Y., & Gao, S. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.giscience.2023.43 · Cited by 10
Chen, K., Shao, A., Burapacheep, J., et al. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2209.13627 · Cited by 9
Large language models can replicate cross-cultural differences in personalityPreprint
Niszczota, P., Janczak, M., & Misiak, M. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.10679 · Cited by 6 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Gan, C., & Mori, T. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.08714 · Cited by 5
Aligning Language Models to User OpinionsPreprint
Hwang, E., Majumder, B. P., & Tandon, N. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2305.14929 · Cited by 1 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
BLOOM: A 176B-Parameter Open-Access Multilingual Language Model
Workshop, B., :, Scao, T. L., Fan, A., Akiki, C., Pavlick, E., Ilić, S., Hesslow, D., Castagné, R., Luccioni, A. S., et al. (2022) · arXiv · doi:10.48550/arxiv.2211.05100 · cited 1×
“A commitment to rigor and replicability should guide the integration of AI into psychological research, not convenience.”
Research works printed but not linked: 2
- Rumelhart, 1987, Parallel distributed processing: explorations in the microstructure of cognition: foundations, 45
- Radford, 2019, Language models are unsupervised multitask learners, OpenAI Blog, 1, 9
Cited by
Sorted by citations
Cultural bias and cultural alignment of large language models
Tao, Y., Viberg, O., Baker, R. S., & Kizilcec, R. F. (2024) · PNAS Nexus · doi:10.1093/pnasnexus/pgae346 · Cited by 383
GPT is an effective tool for multilingual psychological text analysis
Rathje, S., Mirea, D.-M., Sucholutsky, I., Marjieh, R., Robertson, C. E., & Van Bavel, J. J. (2024) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2308950121 · Cited by 297
“For instance, one paper found that fine - tuned GPT outperformed even fine - tuned BERT at detecting moral foundations (73).”
BackgroundUsing natural language processing to analyse text data in behavioural science
Feuerriegel, S., Maarouf, A., Bär, D., Geissler, D., Schweisthal, J., Pröllochs, N., Robertson, C. E., Rathje, S., Hartmann, J., Mohammad, S. M., et al. (2025) · Nature Reviews Psychology · doi:10.1038/s44159-024-00392-z · Cited by 140
“LLMs have several advantages for behavioural science 91,92 .”
InfluentialExploring the frontiers of LLMs in psychological applications: a comprehensive review
Ke, L., Tong, S., Cheng, P., & Peng, K. (2025) · Artificial Intelligence Review · doi:10.1007/s10462-025-11297-5 · Cited by 117
An, J., Huang, D., Lin, C., & Tai, M. (2025) · PNAS Nexus · doi:10.1093/pnasnexus/pgaf089 · Cited by 58
“For instance, Abdurahman et al. (72), Atari et al. (73), and Zewail et al. (74)suggest that both skewed training data and debiasing procedures can lead LLMs to favor Western, Educated, Industrialized, Rich, and Democratic social values.”
Metadata
- Authors
- Abdurahman, S., Atari, M., Karimi-Malekabadi, F., Xue, M. J., Trager, J., Park, P. S., Golazizian, P., Omrani, A., & Dehghani, M.
- Affiliations
- University of Southern California (US)
- Harvard University (US)
- Massachusetts Institute of Technology (US)
- Corresponding author
- Atari, Mohammad
- ORCID
- Venue
- PNAS Nexus
- Publisher
- Oxford University Press (OUP)
- Published
- 2024-06-28
- Volume
- 3
- Issue
- 7
- Pages
- pgae245-pgae245
- ISSN
- 2752-6542 (ISSN-L)
- PMC
- PMC11249969
- OpenAlex
- W4400678448
- Semantic Scholar
- 9e96c4a7dd4cbadd6d03f4a30325466641839831
- Cited by
- 111
- References
- 62
- Citations by year
- 2026: 51 · 2025: 54 · 2024: 6
- FWCI
- 96.27
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- PNAS Nexus (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Funders
- DARPA INCAS (HR001121C0165)
- AFOSR (A9550-23-1-0463)
- Topics
- Social Sciences › General Social Sciences › Computational and Text Analysis Methods
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Keywords
- large language models, psychological research methods, AI-generated data, text analysis, zero-shot learning, psychological diversity, sample diversity, reproducibility, AI ethics, ChatGPT, task automation, textual annotation, overreliance on AI
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
