

SPECTER: Document-level Representation Learning using Citation-informed Transformers
Open accessThe DOI matches its Crossref record; 62 of the 62 references it cites were found in a registry or an index; 1 of the 26 sources its claims cite were checked for support.
Abstract
Representation learning is a critical ingredient for natural language processing systems.Recent Transformer language models like BERT learn powerful textual representations, but these models are targeted towards token-and sentence-level training objectives and do not leverage information on inter-document relatedness, which limits their document-level representation power.For applications on scientific documents, such as classification and recommendation, the embeddings power strong performance on end tasks.We propose SPECTER, a new method to generate document-level embedding of scientific documents based on pretraining a Transformer language model on a powerful signal of document-level relatedness: the citation graph.Unlike existing pretrained language models, SPECTER can be easily applied to downstream applications without task-specific fine-tuning.Additionally, to encourage further research on document-level models, we introduce SCIDOCS, a new evaluation benchmark consisting of seven document-level tasks ranging from citation prediction, to document classification and recommendation.We show that SPECTER outperforms a variety of competitive baselines on the benchmark.1
Overview
CoChat Summary
TL;DR
SPECTER learns document-level embeddings of scientific papers by pretraining a SciBERT Transformer on citation-informed triplets, using only title and abstract at inference. It introduces the SCIDOCS seven-task benchmark and reports an average score of 80.0 across tasks/metrics, a 3.1-point absolute improvement over the next-best baseline.
Key findings
- SPECTER achieves an average of 80.0 across all SCIDOCS tasks/metrics, 3.1 points absolute over the next-best baseline. On MeSH classification it reaches F1 86.4 (+2.3 over best baseline) and on MAG F1 82.0 (+1.5); on co-view MAP 83.8 and co-read MAP 84.5, improving over Citeomatic by 2.7 and 4.0 points; on co-citation nDCG 94.8, +2.3 over SGC; on recommendation nDCG 53.9.
- In an online A/B test with 4,113 clicks, the SPECTER-based ranker improved clickthrough rate over the baseline by 46.5%.
- Ablations show removing the abstract drops average performance to 68.1, adding authors drops it to 67.3, using no hard negatives drops it to 78.4, and initializing from BERT-Large instead of SciBERT drops it to 77.5. Fixed SPECTER embeddings also outperform SciBERT fine-tuned on task-specific signals (SPECTER average 80.0 vs. multitask fine-tuning 78.0).
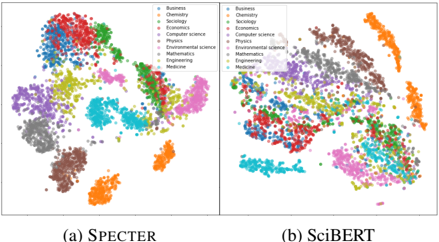
- t-SNE clustering quality for SPECTER is homogeneity 0.41 and completeness 0.72, compared with SciBERT’s 0.19 and 0.63.
Methods
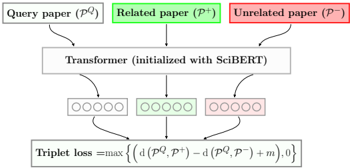
- SPECTER initializes from SciBERT, encodes the concatenated title and abstract, and uses the final [CLS] pooled output as the paper vector. It pretrains with a triplet margin loss on the citation graph: query paper, positive cited paper, and negative uncited paper, using L2 distance and margin m=1. Hard negatives are citations of citations; training uses 2 hard negatives and 3 easy negatives per query.
- Training data: a Semantic Scholar subset of about 146K query papers (~26.7M tokens) and 32K validation papers, yielding about 684K training triples and 145K validation triples. Training uses Adam with LR 2e-5, slanted triangular LR, 2 epochs, batch size 4 with gradient accumulation for effective batch size 32, on a single Titan V GPU.
- Evaluation: SCIDOCS covers seven tasks—MeSH classification (23K papers, 11 disease classes), MAG topic classification (25K papers, 19 level-1 classes), direct citation prediction (~30K total papers; 1K queries, up to 5 cited and 25 uncited candidates), co-citation (30K), co-views (~30K), co-reads (~30K), and recommendation (22K clickthrough events; 20K/1K/1K split; propensity-adjusted P@1 and nDCG). Baselines include SIF, SciBERT, Sent-BERT, Citeomatic, and SGC; classification uses a linear SVM, and recommendation uses a feedforward ranking network with ten features including cosine embedding distance.
Limitations
- Stated: SPECTER uses only title and abstract; adding full text could improve accuracy, but full text is often not freely available and Transformer memory limits would require new techniques. Venue metadata was not normalized, and author names were sparse/out-of-vocabulary; adding authors or venues did not help and authors hurt performance.
- Stated: On the recommendation task, differences between embedding methods are generally smaller because embeddings are used alongside several other informative features, limiting their impact on overall performance.
- Evident from the text: evaluation is limited to scientific documents and the released SCIDOCS tasks, with no evidence for other domains or languages; the online A/B test covers one production recommender and 4,113 clicks, so broader deployment evidence is not provided.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
1 Valid · 2 Not valid · 17 Not checked · 56 Own results and interpretations
Every source the paper cites for this claim was checked and supports it.
In the paper
“This is because SciBERT, like other pretrained language models, is trained via language modeling objectives, which only predict words or sentences given their in-document, nearby textual context.”
§ SPECTER: Document-level Representation Learning using Citation-informed Transformers > Document Representation
What the sources say
- Supportedcites Beltagy et al., 2019 matched to “SciBERT: A Pretrained Language Model for Scientific Text” (2019) source
The Methods (Sec. 2, Background) states that SciBERT follows BERT's architecture and pretraining tasks — 'predicting randomly masked tokens and predicting whether two sentences follow each other' — i.e. word-level and sentence-level objectives. The Corpus paragraph of Sec. 2 and Sec. 3.3 show these instances are built from the full text of papers with sentences split and packed up to 128/512 tokens, so the context the objectives use is nearby, in-document text. The Introduction likewise groups SciBERT with ELMo, GPT and BERT as unsupervised pretrained language models, covering the 'like other pretrained language models' clause. (LLM, conf=0.85)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“On the recommendations task, as opposed to previous experiments, the differences in method scores are generally smaller.”
§ SPECTER: Document-level Representation Learning using Citation-informed Transformers > 5 Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We found that these pretrained embeddings substantially outperform alternative off-theshelf embeddings.”
§ SPECTER: Document-level Representation Learning using Citation-informed Transformers > 3. Fasttext-Sum
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As we show in our experiments ( §6), including hard negatives results in more accurate embeddings compared to using random negatives alone.”
§ SPECTER: Document-level Representation Learning using Citation-informed Transformers > 2.4 Selecting Negative Distractors
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We achieve substantial improvements over the strongest of a wide variety of baselines, demonstrating the effectiveness of our model.”
§ SPECTER: Document-level Representation Learning using Citation-informed Transformers > 8 Conclusions and Future Work
boostedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
25 more claims
Create a free account to see all 76 claims and to verify the 18 references still open.
- It may state two separate claims as one. 22
- Probably not a substantial claim. 29
- The quote only partly states this claim. 1
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Covered model families span content-and embedding-based methods (e.g.,TF-IDF [63], BM25 [59] , SPECTER/SciBERT [17] ), graph-and HIN/GNN-based methods (GraphSAGE, Graph Attention Networks (GATs), meta-path reasoning), and hybrid/LLM pipelines (prompting, re-ranking, RAG).”
From A Critical Review on Citation Recommendation Systems Through a Graph-Centric Approach (2026) · cites this paper as [17]
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
Scikit-learn: Machine Learning in Python
Pedregosa, F., Varoquaux, G., Gramfort, A., Michel, V., Thirion, B., Grisel, O., Blondel, M., Müller, A., Nothman, J., Louppe, G., et al. (2012) · arXiv · doi:10.48550/arxiv.1201.0490 · Cited by 71,016
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Semi-supervised classification with graph convolutional networks
Kipf, T. N., & Welling, M. (2016) · arXiv · doi:10.48550/arxiv.1609.02907 · Cited by 24,853
(1996) · Cited by 20,179
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
Reimers, N., & Gurevych, I. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1410 · Cited by 12,778
Deep Contextualized Word Representations
Peters, M., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., & Zettlemoyer, L. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1202 · Cited by 11,983
Research works printed but not linked: 2
- William L. Hamilton, Zhitao Ying, and Jure Leskovec. 2017b. Inductive representation learning on large graphs. In NIPS.
- Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. 2018. Improving language under- standing by generative pre-training. arXiv.
Cited by
BioGPT: generative pre-trained transformer for biomedical text generation and mining
Luo, R., Sun, L., Xia, Y., Qin, T., Zhang, S., Poon, H., & Liu, T.-Y. (2022) · Briefings in Bioinformatics · doi:10.1093/bib/bbac409 · Cited by 1,150
MTEB: Massive Text Embedding Benchmark
Muennighoff, N., Tazi, N., Magne, L., & Reimers, N. (2023) · Proceedings of the 17th Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2023.eacl-main.148 · Cited by 548
Large Language Models on Graphs: A Comprehensive Survey
Jin, B., Liu, G., Han, C., Jiang, M., Ji, H., & Han, J. (2024) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2024.3469578 · Cited by 147
One Embedder, Any Task: Instruction-Finetuned Text Embeddings
Su, H., Shi, W., Kasai, J., Wang, Y., Hu, Y., Ostendorf, M., Yih, W.-T., Smith, N. A., Zettlemoyer, L., & Yu, T. (2023) · Findings of the Association for Computational Linguistics: ACL 2023 · doi:10.18653/v1/2023.findings-acl.71 · Cited by 131
ColBERTv2: Effective and Efficient Retrieval via Lightweight Late Interaction
Santhanam, K., Khattab, O., Saad-Falcon, J., Potts, C., & Zaharia, M. (2022) · Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/2022.naacl-main.272 · Cited by 353
LinkBERT: Pretraining Language Models with Document Links
Yasunaga, M., Leskovec, J., & Liang, P. (2022) · Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2022.acl-long.551 · Cited by 327
Benchmarking Retrieval-Augmented Generation for Medicine
Xiong, G., Jin, Q., Lu, Z., & Zhang, A. (2024) · Findings of the Association for Computational Linguistics ACL 2024 · doi:10.18653/v1/2024.findings-acl.372 · Cited by 310
Bridging Modalities: Improving Universal Multimodal Retrieval by Multimodal Large Language Models
Zhang, X., Zhang, Y., Xie, W., Li, M., Dai, Z., Long, D., Xie, P., Zhang, M., Li, W., & Zhang, M. (2025) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52734.2025.00866 · Cited by 296
ColBERTv2: Effective and Efficient Retrieval via Lightweight Late InteractionPreprint
Santhanam, K., Khattab, O., Saad-Falcon, J., Potts, C., & Zaharia, M. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2112.01488 · Cited by 295
Wang, K., Reimers, N., & Gurevych, I. (2021) · Findings of the Association for Computational Linguistics: EMNLP 2021 · doi:10.18653/v1/2021.findings-emnlp.59 · Cited by 125
Poisoning Retrieval Corpora by Injecting Adversarial Passages
Zhong, Z., Huang, Z., Wettig, A., & Chen, D. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.849 · Cited by 253
Dense Text Retrieval Based on Pretrained Language Models: A Survey
Zhao, W. X., Liu, J., Ren, R., & Wen, J.-R. (2024) · ACM Transactions on Information Systems · doi:10.1145/3637870 · Cited by 211
Zhang, Y., Chen, X., Jin, B., Wang, S., Ji, S., Wang, W., & Han, J. (2024) · Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2024.emnlp-main.498 · Cited by 44
Gomez, C. J., Herman, A. C., & Parigi, P. (2022) · Nature Human Behaviour · doi:10.1038/s41562-022-01351-5 · Cited by 191
Walker, M., Phung, T., Chakraborti, T., Williams, T., & Szafir, D. J. (2023) · ACM Transactions on Human-Robot Interaction · doi:10.1145/3597623 · Cited by 184
MSˆ2: Multi-Document Summarization of Medical Studies
DeYoung, J., Beltagy, I., van Zuylen, M., Kuehl, B., & Wang, L. (2021) · Proceedings of the 2021 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2021.emnlp-main.594 · Cited by 83
Self-citationJin, Q., Kim, W., Chen, Q., Comeau, D. C., Yeganova, L., Wilbur, W. J., & Lu, Z. (2023) · Bioinformatics · doi:10.1093/bioinformatics/btad651 · Cited by 175
Simplified Data Wrangling with ir_datasets
MacAvaney, S., Yates, A., Feldman, S., Downey, D., Cohan, A., & Goharian, N. (2021) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3404835.3463254 · Cited by 161
Self-citationWhiteningBERT: An Easy Unsupervised Sentence Embedding Approach
Huang, J., Tang, D., Zhong, W., Lu, S., Shou, L., Gong, M., Jiang, D., & Duan, N. (2021) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2021.findings-emnlp.23 · Cited by 159
Balancing Methods for Multi-label Text Classification with Long-Tailed Class Distribution
Huang, Y., Giledereli, B., Köksal, A., Özgür, A., & Özkırımlı, E. (2021) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2021.emnlp-main.643 · Cited by 151
Just, J. (2023) · Technovation · doi:10.1016/j.technovation.2023.102883 · Cited by 145
Eger, S., Cao, Y., D’Souza, J., Geiger, A., Greisinger, C., Gross, S., Hou, Y., Krenn, B., Lauscher, A., Li, Y., et al. (2026) · ACM Computing Surveys · doi:10.1145/3845596 · Cited by 139
Text Embeddings by Weakly-Supervised Contrastive Pre-training
Wang, L., Yang, N., Huang, X., Jiao, B., Yang, L., Jiang, D., Majumder, R., & Wei, F. (2022) · arXiv · doi:10.48550/arxiv.2212.03533 · Cited by 135
Text mining approaches for dealing with the rapidly expanding literature on COVID-19
Wang, L. L., & Lo, K. (2021) · Briefings in Bioinformatics · doi:10.1093/bib/bbaa296 · Cited by 116
Rethmeier, N., & Augenstein, I. (2022) · ACM Computing Surveys · doi:10.1145/3561970 · Cited by 132
Is Semantic Chunking Worth the Computational Cost?
Qu, R., Tu, R., & Bao, F. S. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.114 · Cited by 134
Artificial intelligence tools expand scientists' impact but contract science's focus
Hao, Q., Xu, F., Li, Y., & Evans, J. (2026) · Nature · doi:10.1038/s41586-025-09922-y · Cited by 117
Pu, K., Feng, K. J. K., Grossman, T., Hope, T., Mishra, B. D., Latzke, M., Bragg, J., Chang, J. C., & Siangliulue, P. (2025) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3706598.3714057 · Cited by 111
Making Text Embedders Few-Shot Learners
Li, C., Qin, M., Xiao, S., Chen, J., Luo, K., Shao, Y., Lian, D., & Liu, Z. (2024) · International Conference on Learning Representations · doi:10.48550/arxiv.2409.15700 · Cited by 110
Beyond word embeddings: A survey
Incitti, F., Urli, F., & Snidaro, L. (2022) · Information Fusion · doi:10.1016/j.inffus.2022.08.024 · Cited by 97
A Comprehensive Survey and Guide to Multimodal Large Language Models in Vision–Language Tasks
Liang, C. X., Tian, P., Yin, C. H., Yua, Y., An-Hou, W., Ming, L., Song, X., Wang, T., Bi, Z., Liu, M., et al. (2026) · Computation · doi:10.3390/computation14060125 · Cited by 96
Yu, Y., Xiong, C., Sun, S., Zhang, C., & Overwijk, A. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.95 · Cited by 92
The landscape of biomedical research
González-Márquez, R., Schmidt, L., Schmidt, B. M., Berens, P., & Kobak, D. (2024) · Patterns · doi:10.1016/j.patter.2024.100968 · Cited by 89
Patton: Language Model Pretraining on Text-Rich Networks
Jin, B., Zhang, W., Zhang, Y., Yu, M., Zhang, X., Zhu, Q., & Han, J. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.387 · Cited by 88
Information Retrieval: Advanced Topics and Techniques
(2024) · ACM eBooks · doi:10.1145/3674127 · Cited by 88
Two Tales of Persona in LLMs: A Survey of Role-Playing and Personalization
Tseng, Y.-M., Huang, Y.-C., Hsiao, T.-Y., Chen, W.-L., Huang, C.-W., Meng, Y., & Chen, Y.-N. (2024) · Findings of the Association for Computational Linguistics: EMNLP 2024 · doi:10.18653/v1/2024.findings-emnlp.969 · Cited by 87
COVID-19 research in Wikipedia
Colavizza, G. (2020) · Quantitative Science Studies · doi:10.1162/qss_a_00080 · Cited by 87
CSL: A Large-scale Chinese Scientific Literature DatasetPreprint
Li, Y., Zhang, Y., Zhao, Z., Shen, L., Liu, W., Mao, W., & Zhang, H. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2209.05034 · Cited by 86
Unsupervised Dense Retrieval with Relevance-Aware Contrastive Pre-Training
Lei, Y., Ding, L., Cao, Y. H., Zan, C., Yates, A., & Tao, D. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.695 · Cited by 83
Chang, J. C., Zhang, A. X., Bragg, J., Head, A., Lo, K., Downey, D., & Weld, D. S. (2023) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544548.3580847 · Cited by 78
Self-citationKhatua, A., Mailthody, V. S., Taleka, B., Ma, T., Song, X., & Hwu, W. (2023) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3580305.3599843 · Cited by 76
Multi-Vector Models with Textual Guidance for Fine-Grained Scientific Document Similarity
Mysore, S., Cohan, A., & Hope, T. (2022) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2022.naacl-main.331 · Cited by 74
Self-citationFeB4RAG: Evaluating Federated Search in the Context of Retrieval Augmented Generation
Wang, S., Khramtsova, E., Zhuang, S., & Zuccon, G. (2024) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3626772.3657853 · Cited by 74
Kang, H. B., Chang, J. C., Kim, Y., & Kittur, A. (2022) · ACM Symposium on User Interface Software and Technology (UIST) · doi:10.1145/3526113.3545660 · Cited by 72
BMRetriever: Tuning Large Language Models as Better Biomedical Text Retrievers
Xu, R., Shi, W., Yu, Y., Zhuang, Y., Zhu, Y., Wang, M. D., Ho, J. C., Zhang, C., & Yang, C. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-main.1241 · Cited by 68
SciRepEval: A Multi-Format Benchmark for Scientific Document Representations
Singh, A., D’Arcy, M., Cohan, A., Downey, D., & Feldman, S. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.338 · Cited by 67
Self-citationDeep learning for patent landscaping using transformer and graph embedding
Choi, S., Lee, H., Park, E., & Choi, S. (2021) · Technological Forecasting and Social Change · doi:10.1016/j.techfore.2021.121413 · Cited by 66
A systematic review of extended reality (XR) for understanding and augmenting vision loss
Kasowski, J., Johnson, B. A., Neydavood, R., Akkaraju, A., & Beyeler, M. (2023) · Journal of Vision · doi:10.1167/jov.23.5.5 · Cited by 65
Automated Peer Reviewing in Paper SEA: Standardization, Evaluation, and Analysis
Yu, J., Ding, Z., Tan, J., Luo, K., Weng, Z., Gong, C., Zeng, L., Cui, R., Han, C., Sun, Q., et al. (2024) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2024.findings-emnlp.595 · Cited by 65
CiteME: Can Language Models Accurately Cite Scientific Claims?
Press, O., Hochlehnert, A., Prabhu, A., Udandarao, V., Press, O., & Bethge, M. (2024) · neural information processing systems · doi:10.52202/079017-0252 · Cited by 65
The Semantic Scholar Open Data Platform
Kinney, R., Anastasiades, C., Authur, R., Beltagy, I., Bragg, J., Buraczynski, A., Cachola, I., Candra, S., Chandrasekhar, Y., Cohan, A., et al. (2023) · arXiv · doi:10.48550/arxiv.2301.10140 · Cited by 64
Self-citationA large-scale dataset of patient summaries for retrieval-based clinical decision support systems
Zhao, Z., Jin, Q., Chen, F., Peng, T., & Yu, S. (2023) · Scientific Data · doi:10.1038/s41597-023-02814-8 · Cited by 63
Beyond Citations: Measuring Novel Scientific Ideas and their Impact in Publication Text
Arts, S., Melluso, N., & Veugelers, R. (2025) · The Review of Economics and Statistics · doi:10.1162/rest_a_01561 · Cited by 63
Partisan disparities in the use of science in policy
Furnas, A. C., LaPira, T. M., & Wang, D. (2025) · Science · doi:10.1126/science.adt9895 · Cited by 64
The Semantic Scholar Academic Graph (S2AG)
Wade, A. D. (2022) · International World Wide Web Conference (WWW) · doi:10.1145/3487553.3527147 · Cited by 62
Retrieval as Attention: End-to-end Learning of Retrieval and Reading within a Single Transformer
Jiang, Z., Gao, L., Wang, Z., Araki, J., Ding, H., Callan, J., & Neubig, G. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.149 · Cited by 62
Lo, K., Chang, J. C., Head, A., Bragg, J., Zhang, A. X., Trier, C., Anastasiades, C., August, T., Authur, R., Bragg, D., et al. (2024) · Communications of the ACM · doi:10.1145/3659096 · Cited by 61
Self-citationRelatedly: Scaffolding Literature Reviews with Existing Related Work Sections
Palani, S., Naik, A., Downey, D., Zhang, A. X., Bragg, J., & Chang, J. C. (2023) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544548.3580841 · Cited by 59
Self-citationA Thorough Examination on Zero-shot Dense Retrieval
Ren, R., Qu, Y., Liu, J., Zhao, X., Wu, Q., Ding, Y., Wu, H. Y., Wang, H., & Wen, J.-R. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.1057 · Cited by 58
OAG-BERT: Towards a Unified Backbone Language Model for Academic Knowledge Services
Liu, X., Yin, D., Zheng, J., Zhang, X., Zhang, P., Yang, H., Dong, Y., & Tang, J. (2022) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3534678.3539210 · Cited by 58
Meta-survey on outlier and anomaly detection
Olteanu, M., Rossi, F., & Yger, F. (2023) · Neurocomputing · doi:10.1016/j.neucom.2023.126634 · Cited by 57
Neighborhood Contrastive Learning for Scientific Document Representations with Citation Embeddings
Ostendorff, M., Rethmeier, N., Augenstein, I., Gipp, B., & Rehm, G. (2022) · Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2022.emnlp-main.802 · Cited by 56
PaperQA: Retrieval-Augmented Generative Agent for Scientific Research
Lála, J., O'Donoghue, O., Shtedritski, A., Cox, S., Rodriques, S. G., & White, A. D. (2023) · arXiv · doi:10.48550/arxiv.2312.07559 · Cited by 55
Lee, Y., Kang, H. B., Latzke, M., Kim, J., Bragg, J., Chang, J. C., & Siangliulue, P. (2024) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3613904.3642196 · Cited by 55
LitLLMs, LLMs for Literature Review: Are we there yet?
Agarwal, S., Sahu, G., Puri, A., Laradji, I., Dvijotham, K., Stanley, J., Charlin, L., & Pal, C. (2025) · Transactions on machine learning research · doi:10.48550/arxiv.2412.15249 · Cited by 53
S2AND: A Benchmark and Evaluation System for Author Name Disambiguation
Subramanian, S., King, D., Downey, D., & Feldman, S. (2021) · ACM/IEEE Joint Conference on Digital Libraries · doi:10.1109/jcdl52503.2021.00029 · Cited by 53
Self-citationBursting Scientific Filter Bubbles: Boosting Innovation via Novel Author Discovery
Portenoy, J., Radensky, M., West, J. D., Horvitz, E., Weld, D. S., & Hope, T. (2022) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3491102.3501905 · Cited by 53
Self-citationChen, Q., Allot, A., Leaman, R., Islamaj, R., Du, J., Li, F., Wang, K., Xu, S., Zhang, Y., Bagherzadeh, P., et al. (2022) · Database · doi:10.1093/database/baac069 · Cited by 53
LaPraDoR: Unsupervised Pretrained Dense Retriever for Zero-Shot Text Retrieval
Xu, C., Guo, D., Duan, N., & McAuley, J. (2022) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2022.findings-acl.281 · Cited by 53
Contrastive Learning of Sentence Embeddings from Scratch
Zhang, J., Lan, Z., & He, J. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.238 · Cited by 52
A knowledge graph embeddings based approach for author name disambiguation using literals
Santini, C., Gesese, G. A., Peroni, S., Aldo Gangemi, A., Sack, H., & Alam, M. (2022) · Scientometrics · doi:10.1007/s11192-022-04426-2 · Cited by 51
Zero-Shot Dense Retrieval with Momentum Adversarial Domain Invariant Representations
Xin, J., Xiong, C., Srinivasan, A., Sharma, A., Jose, D., & Bennett, P. N. (2022) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2022.findings-acl.316 · Cited by 51
Moro, G., Ragazzi, L., Valgimigli, L., & Freddi, D. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.15 · Cited by 51
Li, M., Lin, S.-C., Oğuz, B., Ghoshal, A., Lin, J., Mehdad, Y., Yih, W.-T., & Chen, X. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.663 · Cited by 51
Detecting LLM-generated peer reviews
Rao, V. S., Kumar, A., Lakkaraju, H., & Shah, N. B. (2025) · PLOS One · doi:10.1371/journal.pone.0331871 · Cited by 50
“While natural language processing tools like large language models (LLMs) have improved certain aspects of peer review–such as identifying errors in manuscripts [LS23], verifying check-lists [GUK + 24a], and assigning reviewers to papers [CFB + 20]–they have also introduced new challenges.”
SEARCHFORMER: Semantic patent embeddings by siamese transformers for prior art search
Vowinckel, K., & Hähnke, V. D. (2023) · World Patent Information · doi:10.1016/j.wpi.2023.102192 · Cited by 50
Li, Y., Ding, K., & Lee, K. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.181 · Cited by 50
DisenCite: Graph-Based Disentangled Representation Learning for Context-Specific Citation Generation
Wang, Y., Song, Y., Li, S., Cheng, C., Ju, W., Zhang, M., & Wang, S. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i10.21397 · Cited by 49
Narechania, A. A., Karduni, A., Wesslen, R. S., & Wall, E. (2021) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2021.3114820 · Cited by 49
A Survey of AI for Materials Science: Foundation Models, LLM Agents, Datasets, and Tools
Van, M.-H., Verma, P., Zhao, C., & Wu, X. (2026) · ACM Computing Surveys · doi:10.1145/3822503 · Cited by 48
Aspect-based Document Similarity for Research Papers
Ostendorff, M., Ruas, T., Blume, T., Gipp, B., & Rehm, G. (2020) · International Conference on Computational Linguistics · doi:10.18653/v1/2020.coling-main.545 · Cited by 48
CiteRead: Integrating Localized Citation Contexts into Scientific Paper Reading
Rachatasumrit, N., Bragg, J., Zhang, A. X., & Weld, D. S. (2022) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3490099.3511162 · Cited by 48
Self-citationImproving BERT-based Query-by-Document Retrieval with Multi-task Optimization
Abolghasemi, A., Verberne, S., & Azzopardi, L. A. (2022) · Lecture notes in computer science · doi:10.1007/978-3-030-99739-7_1 · Cited by 48
Mix-of-Granularity: Optimize the Chunking Granularity for Retrieval-Augmented GenerationPreprint
Zhong, Z., Liu, H., Cui, X., Zhang, X., & Qin, Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2406.00456 · Cited by 48
Oil & Water? Diffusion of AI Within and Across Scientific FieldsPreprint
Duede, E., Dolan, W., Bauer, A., Foster, I. T., & Lakhani, K. R. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2405.15828 · Cited by 47
Task-aware Retrieval with Instructions
Asai, A., Schick, T., Lewis, P., Chen, X., Izacard, G., Riedel, S., Hajishirzi, H., & Yih, W.-T. (2023) · Findings of the Association for Computational Linguistics: ACL 2023 · doi:10.18653/v1/2023.findings-acl.225 · Cited by 46
An LLM-based Framework for Fingerprinting Internet-connected Devices
Sarabi, A., Yin, T., & Liu, M. (2023) · ACM Internet Measurement Conference (IMC) · doi:10.1145/3618257.3624845 · Cited by 46
ConceptEVA: Concept-Based Interactive Exploration and Customization of Document Summaries
Zhang, X., Li, J. K., Chi, P.-W., Chandrasegaran, S. K., & Ma, K. (2023) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544548.3581260 · Cited by 46
BEIR: A Heterogenous Benchmark for Zero-shot Evaluation of Information Retrieval Models
Thakur, N., Reimers, N., Rücklé, A., Srivastava, A., & Gurevych, I. (2021) · arXiv · doi:10.48550/arxiv.2104.08663 · Cited by 45
Benchmarking topic models on scientific articles using BERTeley
Chagnon, E., Pandolfi, R., Donatelli, J. J., & Ushizima, D. M. (2023) · Natural Language Processing Journal · doi:10.1016/j.nlp.2023.100044 · Cited by 45
ConGraT: Self-Supervised Contrastive Pretraining for Joint Graph and Text Embeddings
Brannon, W., Kang, W., Fulay, S. P., Jiang, H., Roy, B., Roy, D. K., & Kabbara, J. (2024) · Workshop on Graph Based Methods for Natural Language Processing · doi:10.18653/v1/2024.textgraphs-1.2 · Cited by 44
Barron, R., Eren, M. E., Serafimova, O. M., Matuszek, C., & Alexandrov, B. S. (2025) · International Conference on Artificial Intelligence and Law · doi:10.1145/3769126.3769215 · Cited by 45
Target-aware Abstractive Related Work Generation with Contrastive Learning
Chen, X., Alamro, H., Li, M., Gao, S., Yan, R., Gao, X., & Zhang, X. (2022) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3477495.3532065 · Cited by 44
PARM: A Paragraph Aggregation Retrieval Model for Dense Document-to-Document Retrieval
Althammer, S., Hofstätter, S., Sertkan, M., Verberne, S., & Hanbury, A. (2022) · Lecture notes in computer science · doi:10.1007/978-3-030-99736-6_2 · Cited by 43
Askari, A., Verberne, S., Abolghasemi, A., Kraaij, W., & Pasi, G. (2023) · ACM Transactions on Information Systems · doi:10.1145/3631938 · Cited by 43
The ACL OCL Corpus: Advancing Open Science in Computational Linguistics
Rohatgi, S., Qin, Y., Aw, B., Unnithan, N., & Kan, M. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.640 · Cited by 44
INTERS: Unlocking the Power of Large Language Models in Search with Instruction Tuning
Zhu, Y., Zhang, P., Zhang, C., Chen, Y., Xie, B., Liu, Z., Wen, J.-R., & Dou, Z. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.154 · Cited by 43
Metadata-Induced Contrastive Learning for Zero-Shot Multi-Label Text Classification
Zhang, Y., Shen, Z., Wu, C.-H., Xie, B.-Y., Hao, J., Wang, Y.-X., Wang, K., & Han, J. (2022) · The Web Conference · doi:10.1145/3485447.3512174 · Cited by 34
FigurA11y: AI Assistance for Writing Scientific Alt Text
Singh, N., Wang, L. L., & Bragg, J. (2024) · Proceedings of the 29th International Conference on Intelligent User Interfaces · doi:10.1145/3640543.3645212 · Cited by 42
ReGen: Zero-Shot Text Classification via Training Data Generation with Progressive Dense Retrieval
Yu, Y., Zhuang, Y., Zhang, R., Yu, M., Shen, J., & Zhang, C. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.748 · Cited by 42
Metadata
- Authors
- Cohan, A., Feldman, S., Beltagy, I., Downey, D., & Weld, D.
- Affiliations
- Allen Institute for Artificial Intelligence (US)
- University of Washington (US)
- Venue
- Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics
- Published
- 2020
- Pages
- 2270-2282
- ISSN
- 0736-587X (ISSN-L)
- OpenAlex
- W3016913119
- Cited by
- 1,108
- References
- 62
- Citations by year
- 2026: 364 · 2025: 244 · 2024: 178 · 2023: 157 · 2022: 113 · 2021: 44 · 2020: 8
- FWCI
- 21.99
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Proceedings of the conference - Association for Computational Linguistics. Meeting (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University) (cc-by)
- Zenodo (CERN European Organization for Nuclear Research) (cc-by)
- Funders
- National Science Foundation (1936940)
- University of Washington
- Office of Naval Research (N00014- 18-1-2193)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Information Systems › Recommender Systems and Techniques
- Keywords
- citation networks, citation prediction, scientific documents, transformer language models, pre-training, document classification, recommendations
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-18, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-18 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (qwen3.8-omni-flash).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
