

The DOI matches its Crossref record; 17 of the 18 references it cites were found in a registry or an index.
Effective Approaches to Attention-based Neural Machine Translation
Open accessAbstract
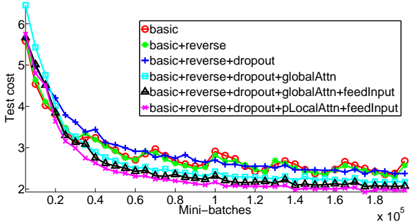
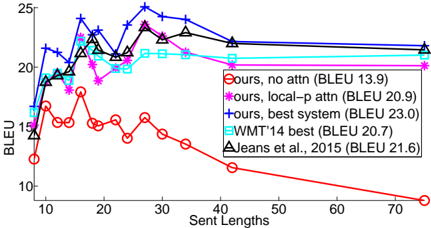
An attentional mechanism has lately been used to improve neural machine translation (NMT) by selectively focusing on parts of the source sentence during translation.However, there has been little work exploring useful architectures for attention-based NMT.This paper examines two simple and effective classes of attentional mechanism: a global approach which always attends to all source words and a local one that only looks at a subset of source words at a time.We demonstrate the effectiveness of both approaches on the WMT translation tasks between English and German in both directions.With local attention, we achieve a significant gain of 5.0 BLEU points over non-attentional systems that already incorporate known techniques such as dropout.Our ensemble model using different attention architectures yields a new state-of-the-art result in the WMT'15 English to German translation task with 25.9 BLEU points, an improvement of 1.0 BLEU points over the existing best system backed by NMT and an n-gram reranker.1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
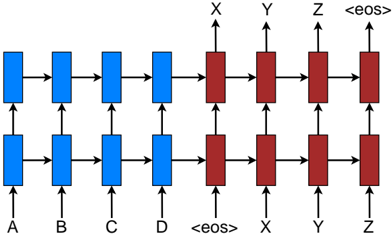
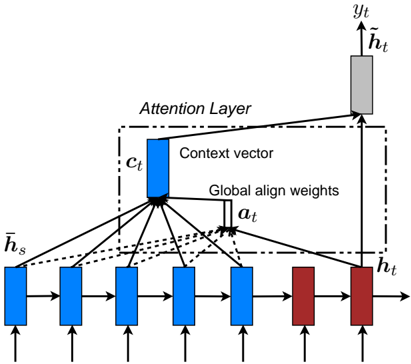
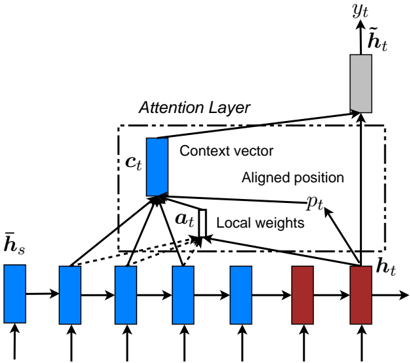
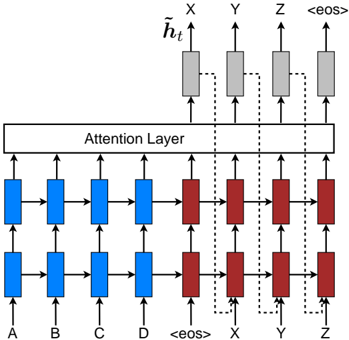
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Since then, various enhancements have been proposed, such as local attention (Luong et al. 2015), supervised attention (Mi et al. 2016; Liu et al. 2016), hierarchical attention (Zhao et al. 2018), and self-attention (Vaswani et al. 2017; Yang et al. 2018).”
From Large language models (LLMs): survey, technical frameworks, and future challenges (2024) · cites this paper as Luong et al. 2015
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Learning Phrase Representations using RNN Encoder–Decoder for Statistical Machine Translation
Cho, K., van Merrienboer, B., Gulcehre, C., Bahdanau, D., Bougares, F., Schwenk, H., & Bengio, Y. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1179 · Cited by 25,545
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
Sequence to Sequence Learning with Neural Networks
Sutskever, I., Vinyals, O., & Le, Q. V. (2014) · arXiv · doi:10.48550/arxiv.1409.3215 · Cited by 17,766
Neural Machine Translation by Jointly Learning to Align and Translate
Bahdanau, D., Cho, K., & Bengio, Y. (2014) · arXiv · doi:10.48550/arxiv.1409.0473 · Cited by 16,213
Show, Attend and Tell: Neural Image Caption Generation with Visual Attention
Xu, K., Ba, J., Kiros, R., Cho, K., Courville, A., Salakhutdinov, R., Zemel, R., & Bengio, Y. (2015) · arXiv · doi:10.48550/arxiv.1502.03044 · Cited by 8,248
Recurrent Models of Visual AttentionPreprint
Mnih, V., Heess, N., Graves, A., & Kavukcuoglu, K. (2014) · arXiv (Cornell University) · doi:10.48550/arxiv.1406.6247 · Cited by 3,393
Statistical phrase-based translation
Koehn, P., Och, F. J., & Marcu, D. (2003) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.3115/1073445.1073462 · Cited by 3,265
Recurrent Neural Network RegularizationPreprint
Zaremba, W., Sutskever, I., & Vinyals, O. (2014) · arXiv (Cornell University) · doi:10.48550/arxiv.1409.2329 · Cited by 3,174
Recurrent Continuous Translation Models
Kalchbrenner, N., & Blunsom, P. (2013) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d13-1176 · Cited by 1,277
Statistical Phrase-Based Translation
Koehn, P., Och, F. J., & Marcu, D. (2003) · doi:10.21236/ada461156 · Cited by 970
Research works printed but not linked: 1
- Percy Liang, Ben Taskar, and Dan Klein. 2006. Align- ment by agreement. In NAACL.
Cited by
Sorted by citations
A Comprehensive Survey on Graph Neural Networks
Wu, Z., Pan, S., Chen, F., Long, G., Zhang, C., & Yu, P. S. (2021) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2020.2978386 · Cited by 11,000
Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting
Zhou, H., Zhang, S., Peng, J., Zhang, S., Li, J., Xiong, H., & Zhang, W. (2021) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v35i12.17325 · Cited by 7,752
Energy and Policy Considerations for Deep Learning in NLP
Strubell, E., Ganesh, A., & McCallum, A. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1355 · Cited by 3,684
A review on the attention mechanism of deep learning
Niu, Z., Zhong, G., & Yu, H. (2021) · Neurocomputing · doi:10.1016/j.neucom.2021.03.091 · Cited by 3,379
Kudo, T., & Richardson, J. (2018) · Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-2012 · Cited by 4,454
A Comprehensive Survey on Graph Neural Networks
Wu, Z., Pan, S., Chen, F., Long, G., Zhang, C., & Yu, P. (2020) · UTS ePRESS (University of Technology Sydney) · Cited by 3,174
Convolutional Sequence to Sequence Learning
Gehring, J., Auli, M., Grangier, D., Yarats, D., & Dauphin, Y. N. (2017) · arXiv · doi:10.48550/arxiv.1705.03122 · Cited by 2,850
“The dominant approach to date encodes the input sequence with a series of bi-directional recurrent neural networks (RNN) and generates a variable length output with another set of decoder RNNs, both of which interface via a soft-attention mechanism (Bahdanau et al., 2014; Luong et al., 2015).”
BackgroundMethodInfluentialSelf-Attention with Relative Position Representations
Shaw, P., Uszkoreit, J., & Vaswani, A. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 2 (Short Papers) · doi:10.18653/v1/n18-2074 · Cited by 2,505
fairseq: A Fast, Extensible Toolkit for Sequence Modeling
Ott, M., Edunov, S., Baevski, A., Fan, A., Gross, S., Ng, N., Grangier, D., & Auli, M. (2019) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n19-4009 · Cited by 2,475
A Call for Clarity in Reporting BLEU Scores
Post, M. (2018) · Proceedings of the Third Conference on Machine Translation: Research Papers · doi:10.18653/v1/w18-6319 · Cited by 2,112
Attention gated networks: learning to leverage salient regions in medical images
Schlemper, J., Oktay, O., Schaap, M., Heinrich, M., Kainz, B., Glocker, B., & Rueckert, D. (2019) · Medical Image Analysis · doi:10.1016/j.media.2019.01.012 · Cited by 2,014
OpenNMT: Open-Source Toolkit for Neural Machine Translation
Klein, G., Kim, Y., Deng, Y., Sénellart, J., & Rush, A. M. (2017) · Annual Meeting of the Association for Computational Linguistics: System Demonstrations (ACL Demo) · doi:10.18653/v1/p17-4012 · Cited by 1,916
Google’s Multilingual Neural Machine Translation System: Enabling Zero-Shot Translation
Johnson, M., Schuster, M., Le, Q. V., Krikun, M., Wu, Y., Chen, Z., Thorat, N., Viégas, F. B., WATTENBERG, M. P., Corrado, G. S., et al. (2017) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00065 · Cited by 1,941
Deep Learning--based Text Classification
Minaee, S., Kalchbrenner, N., Cambria, E., Nikzad-Khasmakhi, N., Asgari-Chenaghlu, M., & Gao, J. (2021) · ACM Computing Surveys · doi:10.1145/3439726 · Cited by 2,122
Deep learning in bioinformatics
Min, S., Lee, B., & Yoon, S. (2016) · Briefings in Bioinformatics · doi:10.1093/bib/bbw068 · Cited by 1,571
Stacked Cross Attention for Image-Text Matching
Lee, K.-H., Chen, X., Hua, G., Hu, H., & He, X. (2018) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-01225-0_13 · Cited by 1,402
Recurrent Neural Networks for Time Series Forecasting: Current status and future directions
Hewamalage, H., Bergmeir, C., & Bandara, K. (2021) · International Journal of Forecasting · doi:10.1016/j.ijforecast.2020.06.008 · Cited by 1,371
The Curious Case of Neural Text Degeneration
Holtzman, A., Buys, J., Du, L., Forbes, M., & Choi, Y. (2019) · arXiv · doi:10.48550/arxiv.1904.09751 · Cited by 1,304
code2vec: Learning distributed representations of code
Alon, U., Zilberstein, M., Levy, O., & Yahav, E. (2019) · Proceedings of the ACM on Programming Languages · doi:10.1145/3290353 · Cited by 962
Anderson, P., Wu, Q., Teney, D., Bruce, J., Johnson, M., Sunderhauf, N., Reid, I., Gould, S., & van den Hengel, A. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00387 · Cited by 1,187
Bidirectional LSTM with attention mechanism and convolutional layer for text classification
Liu, G., & Guo, J. (2019) · Neurocomputing · doi:10.1016/j.neucom.2019.01.078 · Cited by 1,166
Mousavi, S. M., Ellsworth, W. L., Zhu, W., Chuang, L., & Beroza, G. C. (2020) · Nature Communications · doi:10.1038/s41467-020-17591-w · Cited by 1,207
Detecting sequence signals in targeting peptides using deep learning
Armenteros, J. J. A., Salvatore, M., Emanuelsson, O., Winther, O., von HEIJNE, G., Elofsson, A., & Nielsen, H. (2019) · Life Science Alliance · doi:10.26508/lsa.201900429 · Cited by 1,116
Recent advances and clinical applications of deep learning in medical image analysis
Chen, X., Wang, X., Zhang, K., Fung, K.-M. A., Thai, T., Moore, K. N., Mannel, R. S., Liu, H., Zheng, B., & Qiu, Y. (2022) · Medical Image Analysis · doi:10.1016/j.media.2022.102444 · Cited by 1,180
Aspect Level Sentiment Classification with Deep Memory Network
Tang, D., Qin, B., & Liu, T. (2016) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d16-1021 · Cited by 1,122
Molecular Transformer: A Model for Uncertainty-Calibrated Chemical Reaction Prediction
Schwaller, P., Laino, T., Gaudin, T., Bolgar, P., Hunter, C. A., Bekas, C., & Lee, A. A. (2019) · ACS Central Science · doi:10.1021/acscentsci.9b00576 · Cited by 1,163
Yu, T., Zhang, R., Yang, K., Yasunaga, M., Wang, D., Li, Z., Ma, J., Li, I., Yao, Q., Roman, S., et al. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1425 · Cited by 1,034
Concepts of Artificial Intelligence for Computer-Assisted Drug Discovery
Yang, X. Y., Wang, Y., Byrne, R., Schneider, G., & Yang, S. (2019) · Chemical Reviews · doi:10.1021/acs.chemrev.8b00728 · Cited by 1,079
Understanding Back-Translation at Scale
Edunov, S., Ott, M., Auli, M., & Grangier, D. (2018) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d18-1045 · Cited by 1,082
A Survey on the Explainability of Supervised Machine Learning
Burkart, N., & Huber, M. F. (2021) · Journal of Artificial Intelligence Research · doi:10.1613/jair.1.12228 · Cited by 1,008
Neural Machine Translation of Rare Words with Subword Units
Sennrich, R., Haddow, B., & Birch, A. (2016) · Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p16-1162 · Cited by 974
Temporal pattern attention for multivariate time series forecasting
Shih, S.-Y., Sun, F.-K., & Lee, H.-Y. (2019) · Machine Learning · doi:10.1007/s10994-019-05815-0 · Cited by 997
Region Attention Networks for Pose and Occlusion Robust Facial Expression Recognition
Wang, K., Peng, X., Yang, J., Meng, D., & Qiao, Y. (2020) · IEEE Transactions on Image Processing · doi:10.1109/tip.2019.2956143 · Cited by 970
ABCNN: Attention-Based Convolutional Neural Network for Modeling Sentence Pairs
Yin, W., Schütze, H., Xiang, B., & Zhou, B. (2016) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00097 · Cited by 955
Abstractive Sentence Summarization with Attentive Recurrent Neural Networks
Chopra, S., Auli, M., & Rush, A. M. (2016) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n16-1012 · Cited by 896
Adversarial Learning for Neural Dialogue Generation
Li, J., Monroe, W., Shi, T., Jean, S., Ritter, A., & Jurafsky, D. (2017) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d17-1230 · Cited by 955
Revisiting Spatial-Temporal Similarity: A Deep Learning Framework for Traffic Prediction
Yao, H., Tang, X., Wei, H., Zheng, G., & Li, Z. (2019) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v33i01.33015668 · Cited by 921
Sequence-Level Knowledge Distillation
Kim, Y., & Rush, A. M. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1139 · Cited by 836
Neural Sign Language Translation
Camgöz, N. C., Hadfield, S., Koller, O., Ney, H., & Bowden, R. (2018) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2018.00812 · Cited by 871
Training Spiking Neural Networks Using Lessons From Deep Learning
Eshraghian, J. K., Ward, M., Neftci, E., Wang, X., Lenz, G., Dwivedi, G., Bennamoun, M., Jeong, D. S., & Lu, W. D. (2023) · Proceedings of the IEEE · doi:10.1109/jproc.2023.3308088 · Cited by 1,106
Transfer Learning for Low-Resource Neural Machine Translation
Zoph, B., Yüret, D., May, J., & Knight, K. K. (2016) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d16-1163 · Cited by 903
An Attentive Survey of Attention Models
Chaudhari, S., Mithal, V., Polatkan, G., & Ramanath, R. (2021) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3465055 · Cited by 860
Aspect-based Sentiment Classification with Aspect-specific Graph Convolutional Networks
Zhang, C., Li, Q., & Song, D. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1464 · Cited by 780
Deep Biaffine Attention for Neural Dependency ParsingPreprint
Dozat, T., & Manning, C. D. (2016) · arXiv (Cornell University) · doi:10.4230/oasics.ldk.2021.24 · Cited by 1,019
A Comparative Study on Transformer vs RNN in Speech Applications
Karita, S., Chen, N., Hayashi, T., Hori, T., Inaguma, H., Jiang, Z., Someki, M., Yalta, N., Yamamoto, R., Wang, X., et al. (2019) · IEEE Workshop on Automatic Speech Recognition and Understanding (ASRU) · doi:10.1109/asru46091.2019.9003750 · Cited by 766
Ask, Attend and Answer: Exploring Question-Guided Spatial Attention for Visual Question Answering
Xu, H., & Saenko, K. (2016) · Lecture notes in computer science · doi:10.1007/978-3-319-46478-7_28 · Cited by 753
DiSAN: Directional Self-Attention Network for RNN/CNN-Free Language Understanding
Shen, T., Zhou, T., Long, G., Jiang, J., Pan, S., & Zhang, C. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.11941 · Cited by 779
Recurrent Neural Networks: A Comprehensive Review of Architectures, Variants, and Applications
Mienye, I. D., Swart, T. G., & Obaido, G. (2024) · Information · doi:10.3390/info15090517 · Cited by 962
Summarizing Source Code using a Neural Attention Model
Iyer, S. V., Konstas, I., Cheung, A., & Zettlemoyer, L. (2016) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p16-1195 · Cited by 739
Feng, J., Li, Y., Zhang, C., Sun, F., Meng, F., Guo, A., & Jin, D. (2018) · International World Wide Web Conference (WWW) · doi:10.1145/3178876.3186058 · Cited by 752
Modeling Coverage for Neural Machine Translation
Tu, Z., Lu, Z., Liu, Y., Liu, X., & Li, H. (2016) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p16-1008 · Cited by 747
Language to Logical Form with Neural Attention
Dong, L., & Lapata, M. (2016) · Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p16-1004 · Cited by 700
A General Survey on Attention Mechanisms in Deep Learning
Brauwers, G., & Frăsincar, F. (2021) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2021.3126456 · Cited by 722
QANet: Combining Local Convolution with Global Self-Attention for Reading ComprehensionPreprint
Yu, A. W., Dohan, D., Luong, M.-T., Zhao, R., Chen, K., Norouzi, M., & Le, Q. V. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1804.09541 · Cited by 882
Global Context-Aware Attention LSTM Networks for 3D Action Recognition
Liu, J., Wang, G., Hu, P., Duan, L., & Kot, A. C. (2017) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2017.391 · Cited by 682
Semantic Communications for Future Internet: Fundamentals, Applications, and Challenges
Yang, W., Du, H., Liew, Z. Q., Lim, W. Y. B., Xiong, Z., Niyato, D. T., Chi, X., Shen, X., & Miao, C. (2022) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2022.3223224 · Cited by 749
Serrano, S., & Smith, N. A. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1282 · Cited by 690
Learning to Ask: Neural Question Generation for Reading Comprehension
Du, X., Shao, J., & Cardie, C. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1123 · Cited by 696
“We model the conditional probability us-ing RNN encoder-decoder architecture (Bahdanau et al., 2015; Cho et al., 2014), and adopt the global attention mechanism (Luong et al., 2015a) to make the model focus on certain elements of the input when generating each word during decoding.”
MethodAgentFormer: Agent-Aware Transformers for Socio-Temporal Multi-Agent Forecasting
Yuan, Y., Weng, X., Ou, Y., & Kitani, K. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00967 · Cited by 715
A Discourse-Aware Attention Model for Abstractive Summarization of Long Documents
Cohan, A., Dernoncourt, F., Kim, D. S., Bui, T., Kim, S., Chang, W., & Goharian, N. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 2 (Short Papers) · doi:10.18653/v1/n18-2097 · Cited by 658
Evaluation and accurate diagnoses of pediatric diseases using artificial intelligence
Liang, H., Tsui, B., Ni, H., Valentim, C. C. S., Baxter, S. L., Liu, G., Cai, W., Kermany, D., Sun, X., Chen, J., et al. (2019) · Nature Medicine · doi:10.1038/s41591-018-0335-9 · Cited by 682
MirrorGAN: Learning Text-To-Image Generation by Redescription
Qiao, T., Zhang, J., Xu, D., & Tao, D. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00160 · Cited by 644
“Attention models have been extensively exploited in computer vision and natural language processing, for instance in object detection [21, 6, 18, 41], image/video captioning [34, 9, 31], visual question answering [2, 33, 36, 22], and neural machine translation [19, 8].”
BackgroundUnified Pre-training for Program Understanding and Generation
Ahmad, W., Chakraborty, S., Ray, B., & Chang, K.-W. (2021) · Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/2021.naacl-main.211 · Cited by 642
Attention in Natural Language Processing
Galassi, A., Lippi, M., & Torroni, P. (2020) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2020.3019893 · Cited by 726
Video Captioning With Attention-Based LSTM and Semantic Consistency
Gao, L., Guo, Z. Z., Zhang, H., Xu, X., & Shen, H. T. (2017) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2017.2729019 · Cited by 645
Reinforcement Learning for Solving the Vehicle Routing ProblemPreprint
Nazari, M., Oroojlooy, A., Snyder, L., & Takáč, M. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1802.04240 · Cited by 638
Learning Deep Transformer Models for Machine Translation
Wang, Q., Li, B., Xiao, T., Zhu, J., Li, C., Wong, D. F., & Chao, L. S. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1176 · Cited by 673
Phan, H., Andreotti, F., Cooray, N., Chén, O. Y., & Vos, M. D. (2019) · IEEE Transactions on Neural Systems and Rehabilitation Engineering · doi:10.1109/tnsre.2019.2896659 · Cited by 660
DeePMD-kit v2: A software package for deep potential models
Zeng, J., Zhang, D., Lu, D., Mo, P., Li, Z., Chen, Y., Rynik, M., Huang, L., Li, Z., Shi, S., et al. (2023) · The Journal of Chemical Physics · doi:10.1063/5.0155600 · Cited by 652
ProgPrompt: Generating Situated Robot Task Plans using Large Language Models
Singh, I., Blukis, V., Mousavian, A., Goyal, A., Xu, D., Tremblay, J., Fox, D., Thomason, J., & Garg, A. (2023) · 2023 IEEE International Conference on Robotics and Automation (ICRA) · doi:10.1109/icra48891.2023.10161317 · Cited by 613
Fast Abstractive Summarization with Reinforce-Selected Sentence Rewriting
Chen, Y.-C., & Bansal, M. (2018) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p18-1063 · Cited by 636
Deep neural networks for the evaluation and design of photonic devices
Jiang, J., Chen, M., & Fan, J. A. (2020) · Nature Reviews Materials · doi:10.1038/s41578-020-00260-1 · Cited by 627
FOTS: Fast Oriented Text Spotting with a Unified Network
Liu, X., Liang, D., Yan, S., Chen, D., Qiao, Y., & Yan, J. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00595 · Cited by 554
Learned in Translation: Contextualized Word Vectors
McCann, B., Bradbury, J., Xiong, C., & Socher, R. (2017) · arXiv · doi:10.48550/arxiv.1708.00107 · Cited by 572
“Luong et al. [2015] further study the effectiveness of various attention mechanisms with respect to machine translation.”
BackgroundMulti-Way, Multilingual Neural Machine Translation with a Shared Attention Mechanism
Fırat, O., Cho, K., & Bengio, Y. (2016) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n16-1101 · Cited by 616
DeepInf: Social Influence Prediction with Deep Learning
Qiu, J., Tang, J., Ma, H., Dong, Y., Wang, K., & Tang, J. (2018) · Proceedings of the 24th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining · doi:10.1145/3219819.3220077 · Cited by 587
Deep Learning for Entity Matching
Mudgal, S., Li, H., Rekatsinas, T., Doan, A., Park, Y., Krishnan, G., Deep, R., Arcaute, E., & Raghavendra, V. (2018) · ACM SIGMOD International Conference on Management of Data (SIGMOD) · doi:10.1145/3183713.3196926 · Cited by 616
Skeleton-Based Human Action Recognition With Global Context-Aware Attention LSTM Networks
Liu, J., Wang, G., Duan, L., Abdiyeva, K., & Kot, A. C. (2017) · IEEE Transactions on Image Processing · doi:10.1109/tip.2017.2785279 · Cited by 612
Deep Learning Methods for Improved Decoding of Linear Codes
Nachmani, E., Marciano, E., Lugosch, L., Gross, W. J., Burshtein, D., & Be'ery, Y. (2018) · IEEE Journal of Selected Topics in Signal Processing · doi:10.1109/jstsp.2017.2788405 · Cited by 563
Attention Branch Network: Learning of Attention Mechanism for Visual Explanation
Fukui, H., Hirakawa, T., Yamashita, T., & Fujiyoshi, H. (2019) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2019.01096 · Cited by 547
Deep Multimodal Representation Learning: A Survey
Guo, W., Wang, J., & Wang, S. (2019) · IEEE Access · doi:10.1109/access.2019.2916887 · Cited by 535
Xu, D., Ouyang, W., Wang, X., & Sebe, N. (2018) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2018.00077 · Cited by 551
Learning to decode linear codes using deep learning
Nachmani, E., Be'ery, Y., & Burshtein, D. (2016) · 2016 54th Annual Allerton Conference on Communication, Control, and Computing (Allerton) · doi:10.1109/allerton.2016.7852251 · Cited by 561
Transformation Networks for Target-Oriented Sentiment Classification
Li, X., Bing, L., Lam, W. P., & Shi, B. (2018) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p18-1087 · Cited by 549
Ma, F., Chitta, R., Zhou, J., You, Q., Sun, T., & Gao, J. (2017) · Proceedings of the 23rd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/3097983.3098088 · Cited by 576
Model compression via distillation and quantizationPreprint
Polino, A., Pascanu, R., & Alistarh, D. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1802.05668 · Cited by 768
Skeleton-Based Human Action Recognition with Global Context-Aware Attention LSTM Networks
Liu, J., Wang, G., Duan, L.-Y., Abdiyeva, K., & Kot, A. C. (2018) · Lancaster EPrints (Lancaster University) · Cited by 531
Physics-Informed Attention Temporal Convolutional Network for EEG-Based Motor Imagery Classification
Altaheri, H., Muhammad, G., & Alsulaiman, M. (2022) · IEEE Transactions on Industrial Informatics · doi:10.1109/tii.2022.3197419 · Cited by 531
Non-Autoregressive Neural Machine TranslationPreprint
Gu, J., Bradbury, J., Xiong, C., Li, V. O. K., & Socher, R. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1711.02281 · Cited by 689
MaX-DeepLab: End-to-End Panoptic Segmentation with Mask Transformers
Wang, H., Zhu, Y., Adam, H., Yuille, A., & Chen, L.-C. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00542 · Cited by 567
Wireless Image Transmission Using Deep Source Channel Coding With Attention Modules
Xu, J., Ai, B., Chen, W. R., Yang, A., Sun, P., & Rodrigues, M. R. D. (2021) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2021.3082521 · Cited by 545
Multimodal intelligence: Representation learning, information fusion, and applications
Zhang, C., Yang, Z., He, X., & Deng, L. (2020) · IEEE Journal of Selected Topics in Signal Processing · doi:10.1109/jstsp.2020.2987728 · Cited by 511
VaTeX: A Large-Scale, High-Quality Multilingual Dataset for Video-and-Language Research
Wang, X., Wu, J., Chen, J., Li, L., Wang, Y., & Wang, W. Y. (2019) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00468 · Cited by 536
A Thorough Examination of the CNN/Daily Mail Reading Comprehension Task
Chen, D., Bolton, J., & Manning, C. D. (2016) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p16-1223 · Cited by 494
Self-citationMassive Exploration of Neural Machine Translation Architectures
Britz, D., Goldie, A., Luong, M.-T., & Le, Q. V. (2017) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d17-1151 · Cited by 594
Sequence-to-Sequence Learning as Beam-Search Optimization
Wiseman, S., & Rush, A. M. (2016) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d16-1137 · Cited by 549
Seo, S., Huang, J., Yang, H., & Liu, Y. (2017) · ACM Conference on Recommender Systems (RecSys) · doi:10.1145/3109859.3109890 · Cited by 481
Multi-Modality Cross Attention Network for Image and Sentence Matching
Wei, X., Zhang, T., Li, Y., Zhang, Y., & Wu, F. (2020) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr42600.2020.01095 · Cited by 494
The multi-modal fusion in visual question answering: a review of attention mechanisms
Lu, S., Liu, M., Yin, L., Yin, Z., Liu, X., & Zheng, W. (2023) · PeerJ Computer Science · doi:10.7717/peerj-cs.1400 · Cited by 492
Modeling Point Clouds With Self-Attention and Gumbel Subset Sampling
Yang, J., Zhang, Q., Ni, B., Li, L., Liu, J., Zhou, M., & Tian, Q. (2019) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2019.00344 · Cited by 477
Metadata
- Authors
- Luong, T., Pham, H., & Manning, C. D.
- Affiliations
- Stanford University (US)
- Venue
- Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing
- Published
- 2015
- Pages
- 1412-1421
- OpenAlex
- W1902237438
- Cited by
- 8,382
- References
- 18
- Citations by year
- 2026: 177 · 2025: 454 · 2024: 586 · 2023: 839 · 2022: 985 · 2021: 1356 · 2020: 1354 · 2019: 1372 · 2018: 783 · 2017: 337 · 2016: 133 · 2015: 5
- FWCI
- 236.52
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- Funders
- Bloomberg L.P.
- Nvidia (Tesla K40)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Speech Recognition and Synthesis
- Keywords
- attention mechanism, neural machine translation, local attention, global attention, English-German translation, ensemble learning, dropout
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
