

The DOI matches its DataCite record; 395 of the 398 references it cites were found in a registry or an index, and 3 are not checked yet; none of the 478 sources its claims cite is checked for support yet.
The Landscape of Agentic Reinforcement Learning for LLMs: A Survey
Open accessAbstract
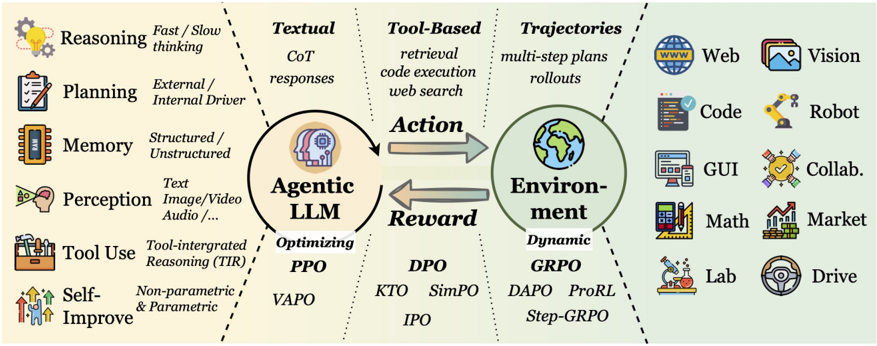
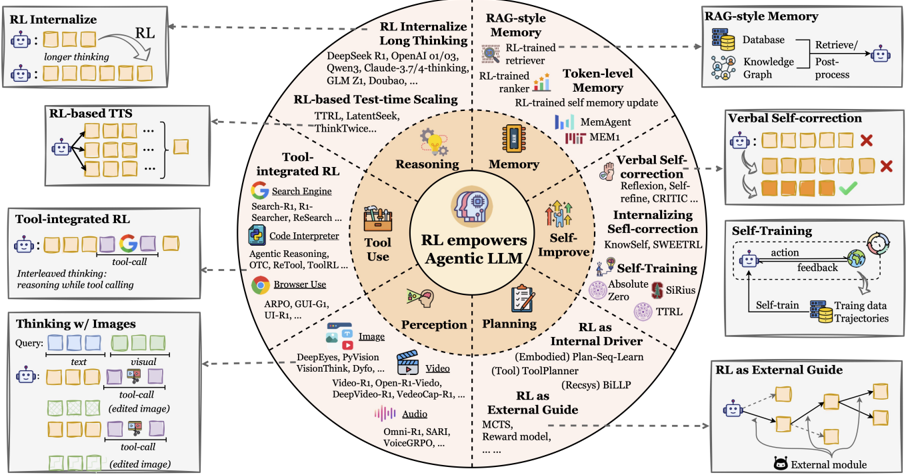
The emergence of agentic reinforcement learning (Agentic RL) marks a paradigm shift from conventional reinforcement learning applied to large language models (LLM RL), reframing LLMs from passive sequence generators into autonomous, decision-making agents embedded in complex, dynamic worlds. This survey formalizes this conceptual shift by contrasting the degenerate single-step Markov Decision Processes (MDPs) of LLM-RL with the temporally extended, partially observable Markov decision processes (POMDPs) that define Agentic RL. Building on this foundation, we propose a comprehensive twofold taxonomy: one organized around core agentic capabilities, including planning, tool use, memory, reasoning, self-improvement, and perception, and the other around their applications across diverse task domains. Central to our thesis is that reinforcement learning serves as the critical mechanism for transforming these capabilities from static, heuristic modules into adaptive, robust agentic behavior. To support and accelerate future research, we consolidate the landscape of open-source environments, benchmarks, and frameworks into a practical compendium. By synthesizing over five hundred recent works, this survey charts the contours of this rapidly evolving field and highlights the opportunities and challenges that will shape the development of scalable, general-purpose AI agents.
Checked 2026-11-14 · 3 references not checked yet
Overview
CoChat Summary
TL;DR
This survey formalizes agentic reinforcement learning (Agentic RL) as a shift from the degenerate single-step MDPs of conventional LLM RL to temporally extended POMDPs for autonomous LLM agents. It synthesizes over five hundred works into a twofold taxonomy of agentic capabilities and task domains, and consolidates environments, benchmarks, frameworks, and open challenges.
Key findings
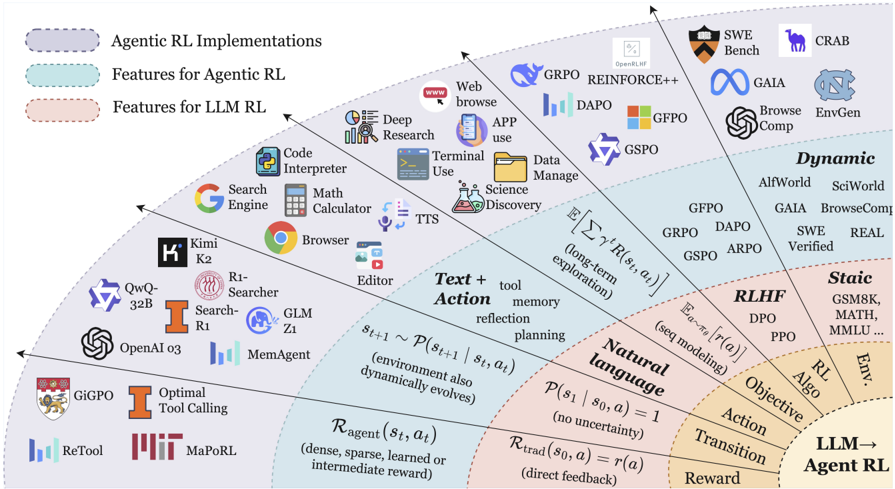
- The paper contrasts preference-based RFT (PBRFT), formalized as a degenerate MDP with horizon \(T=1\) and \(\gamma=1\), against Agentic RL, modeled as a POMDP with partial observations, multi-step transitions, action space \(A_{\text{agent}} = A_{\text{text}} \cup A_{\text{action}}\), and discounted reward \(0<\gamma<1\).
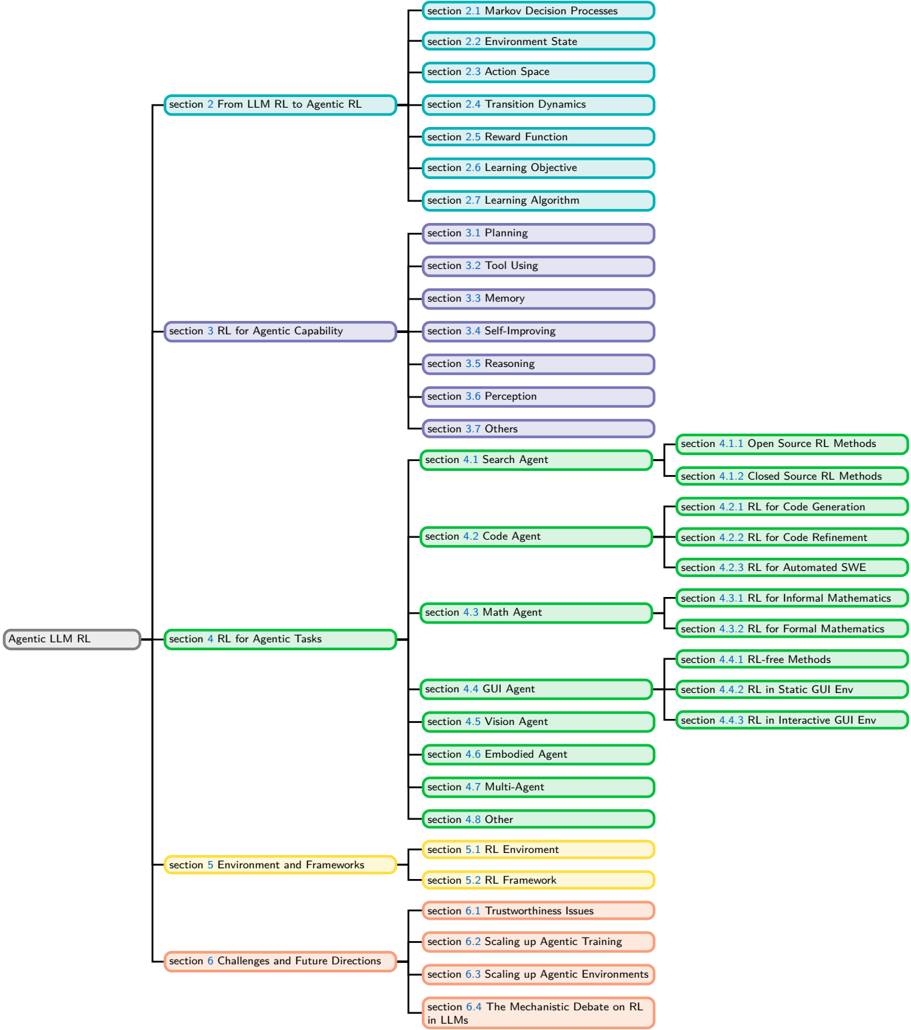
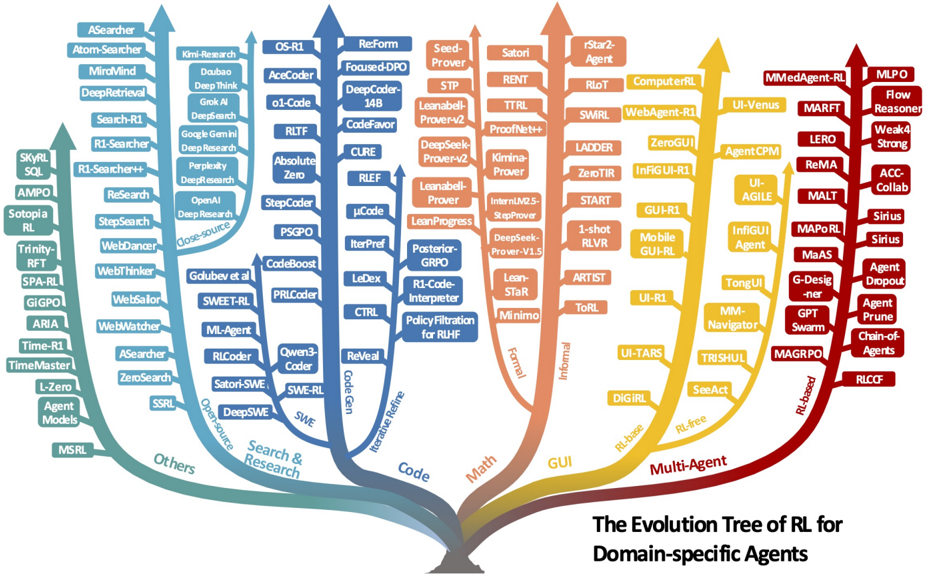
- It proposes a twofold taxonomy: one organized around core agentic capabilities—planning, tool use, memory, reasoning, self-improvement, perception, and others—and another around applications including search/research, code, mathematics, GUI, vision, embodied agents, and multi-agent systems.
- In a mechanistic case study on mathematical and code reasoning, the survey reports that approximately 2/3 of cited studies primarily emphasize pass@1 improvements, while about 1/3 explicitly report expanding pass@k frontiers; it argues “new-capability” behaviors appear most reliably with high-fidelity verifiable rewards, compositional multi-step structure, and base models in an intermediate regime.
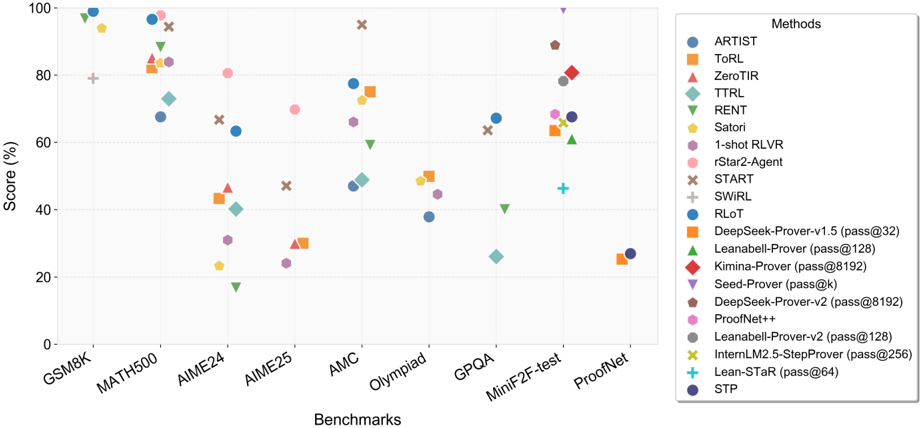
- Open challenges are grouped into trustworthiness (security, hallucination, sycophancy), scaling up agentic training (computation, model size, data, efficiency), scaling up agentic environments, architectural deployment patterns, and broader social impact; selected reported results include OpenAI Deep Research at 51.5% pass@1 on BrowseComp and rStar2-Agent at 80.6% on AIME24 and 69.8% on AIME25 in 510 RL steps.
Methods
- Survey/position paper that formalizes the conceptual shift from LLM RL to Agentic RL using MDP/POMDP notation and a seven-element tuple \(\langle S, O, A, P, R, T, \gamma\rangle\).
- Synthesizes over five hundred recent works and organizes them through a capability taxonomy and a task-domain taxonomy, with consolidated tables of methods, environments, benchmarks, and RL frameworks.
- No primary experiments or new empirical data are reported; the analysis is a narrative and taxonomic synthesis of cited literature.
Limitations
- Stated: the survey is not exhaustive in several sections—e.g., the capability section aims at high-level conceptual delineation rather than exhaustive enumeration, the vision section is explicitly non-exhaustive, and memory tables and listed methods are described as illustrative rather than complete.
- Stated: several prospective directions remain open and largely unsolved, including long-horizon tool-integrated reasoning and temporal credit assignment, RL for structured memory, meta-evolution of reflection, scalable embodied RL across the sim-to-real gap, and scalable credit decomposition in multi-agent RL.
- Evident: as a survey, it provides no empirical validation or systematic review protocol, and its coverage is bounded by the cited works and the field’s rapid evolution.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 11 Not valid · 374 Not checked · 165 Own results and interpretations
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“This is achieved through grounding (Nagaraja et al., 2016;Mao et al., 2016), which anchors each step of the generated chain-of-thought (CoT) to specific regions of the multimodal input-facilitating more valid and verifiable reasoning by explicitly linking text with corresponding visual regions.”
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > Grounding-Driven Active Perception.
What the sources say
- Not matchedcites Nagaraja et al., 2016
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Mao et al., 2016
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
None of the sources cited for this claim could be matched to a paper in Crossref, so there is nothing to check it against.
In the paper
“The paradigm is now evolving beyond simple information retrieval towards creating autonomous agents capable of deep research”
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > 4.1 Search & Research Agent
What the sources say
- Not matchedcites Kimi, 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Perplexity, 2025
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A second, complementary strategy is to (II) extend preference optimization from single turns to multi-step segments.”
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > 3.7 Others
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To date, little work has explored the use of RL to dynamically control the construction, refinement, or evolution of such structured memory”
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > Structured Memory
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A check of a cited source is scheduled, or we don’t hold its full text yet; the claim is checked once it runs.
In the paper
“recent research increasingly emphasizes RL as a mechanism for ongoing reflection, enabling agents to learn from their own mistakes across planning, reasoning, tool use, and memory”
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > 3.4 Self-Improvement
What the sources say
- Not checked yetcites ang Gao et al., 2025 source
A check is scheduled.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not checked yet
177 more claims
Create a free account to see all 550 claims and to verify the 93 references still open.
- Probably not a substantial claim. 202
- It may state two separate claims as one. 227
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > Outcome reward RL.
“DeepSeek-Prover-v2 (DeepSeek-AI et al., 2024) designs a dual-model pipeline”
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > References
“365. Z. Z. Ren, Zhihong Shao, Junxiao Song, Huajian Xin, Haocheng Wang, Wanjia Zhao, Liyue Zhang, Zhe Fu, Qihao Zhu, Dejian Yang, Z. F. Wu, Zhibin Gou, Shirong Ma, Hongxuan Tang, Yuxuan Liu, Wenjun Gao, Daya Guo, and Chong Ruan. Deepseek-prover-v2: Advancing formal mathematical reasoning via reinforcement learning for subgoal decomposition, 2025.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > 7 Conclusion
“| | RL-free GUI Agents | | | | | MM-Navigator (Yan et al., 2023) | Vanilla VLM - | GitHub | | | | SeeAct (Zheng et al., 2024) | Vanilla VLM - | GitHub | | | | TRISHUL (Kunal Singh, 2025) | Vanilla VLM - | - | | | | InfiGUIAgent (Liu et al., 2025n) | SFT | Static | GitHub | HuggingFace Website | | UI-AGILE (Lian et al., 2025) | SFT | Interactive | GitHub | HuggingFace |”
§ The Landscape of Agentic Reinforcement Learning for LLMs: A Survey > References
“242. Shuq uan Lian, Yuhang Wu, Jia Ma, Zihan Song, Bingqi Chen, Xiawu Zheng, and Hui Li. Ui-agile: Advancing gui agents with effective reinforcement learning and precise inference-time grounding.”
Citations
Cites
Items 201–398 of 398
The Landscape of Emerging AI Agent Architectures for Reasoning, Planning, and Tool Calling: A Survey
Masterman, T., Besen, S., Sawtell, M., & Chao, A. (2024) · arXiv · doi:10.48550/arxiv.2404.11584 · Cited by 35
Towards Uncertainty-Aware Language Agent
Han, J., Buntine, W., & Shareghi, E. (2024) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2024.findings-acl.398 · Cited by 35
DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments
Zheng, Y., Fu, D., Hu, X., Cai, X., Ye, L., Lu, P., & Liu, P. (2025) · Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2025.emnlp-main.22 · Cited by 35
Ji, X., Liu, Y., Wang, Q., Zhang, J., Yue, Y., Shi, R., Sun, C., Zhang, F., Zhou, G., & Gai, K. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2507.08649 · Cited by 35
StepCoder: Improving Code Generation with Reinforcement Learning from Compiler Feedback
Dou, S., Liu, Y., Jia, H., Zhou, E., Xiong, L., Shan, J., Huang, C., Wang, X., Fan, X., Xi, Z., et al. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.251 · Cited by 34
Self-citationVisualToolAgent (VisTA): A Reinforcement Learning Framework for Visual Tool SelectionPreprint
Huang, Z., Ji, Y., Rajan, A. S., Cai, Z., Xiao, W. J., Hu, J., & Lee, Y. J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.20289 · Cited by 34
Chen, L., Gao, H., Liu, T., Huang, Z., Sung, F., Zhou, X., Wu, Y., & Chang, B. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.13426 · Cited by 34
GHPO: Adaptive Guidance for Stable and Efficient LLM Reinforcement LearningPreprint
Liu, Z., Gong, C., Fu, X., Liu, Y., Ran, C., Hu, S., Zhang, S., Liu, R. Z. Z., Zhang, Q., & Tu, D. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2507.10628 · Cited by 33
Sotopia-RL: Reward Design for Social IntelligencePreprint
Yu, H., Qi, Z., Zhao, Y., Nottingham, K., Xuan, K., Majumder, B. P., Zhu, H., Liang, P. P., & You, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.03905 · Cited by 33
EchoInk-R1: Exploring Audio-Visual Reasoning in Multimodal LLMs via Reinforcement LearningPreprint
Xing, Z., Hu, X., Fu, C., Wang, W., Dai, J., & Heng, P. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.04623 · Cited by 32
Reinforcing Video Reasoning with Focused Thinking
Dang, J., Wu, J., Wang, T., Lin, X., Zhu, N., Chen, H., Zheng, W.-S., Wang, M., & Chua, T.-S. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37577-3_34 · Cited by 32
ReCode: Reinforcing Code Generation with Reasoning-Process Rewards
Fan, L., Zhang, Y., Chen, M., & Liu, Z. (2026) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2026.acl-long.2031 · Cited by 32
Code Simulation Challenges for Large Language ModelsPreprint
Malfa, E. L., Weinhuber, C., Torre, O., Lin, F., Marro, S., Cohn, A. G., Shadbolt, N., & Wooldridge, M. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2401.09074 · Cited by 30
He, B., Chen, N., He, X., Yan, L., Wei, Z., Luo, J., & Ling, Z.-H. (2024) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2024.findings-emnlp.607 · Cited by 30
debug-gym: A Text-Based Environment for Interactive DebuggingPreprint
Yuan, X., Moss, M. M., Feghali, C. E., Singh, C., Moldavskaya, D., MacPhee, D., Caccia, L., Pereira, M. M., Kim, M., Sordoni, A., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2503.21557 · Cited by 30
LiveTradeBench: Seeking Real-World Alpha with Large Language ModelsPreprint
Yu, H., Li, F., & You, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2511.03628 · Cited by 30
VAU-R1: Advancing Video Anomaly Understanding via Reinforcement Fine-TuningPreprint
Zhu, L., Chen, Q., Shen, X., & Cun, X. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.23504 · Cited by 30
ReVeal: Self-Evolving Code Agents via Reliable Self-VerificationPreprint
Jin, Y., Xu, K., Li, H., Han, X., Zhou, Y., Cheng, L., & Bai, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.11442 · Cited by 28
Self-citationProcess-Supervised Reinforcement Learning for Code Generation
Ye, Y., Zhang, T., Jiang, W., & Huang, H. (2025) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2025.emnlp-main.719 · Cited by 28
STAR-R1: Spatial TrAnsformation Reasoning by Reinforcing Multimodal LLMsPreprint
Li, Z., Ma, Z., Li, M., Li, S., Rong, Y., Xu, T., Zhang, Z., Zhao, D., & Huang, W. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.15804 · Cited by 27
Self-citationRePrompt: Reasoning-Augmented Reprompting for Text-to-Image Generation via Reinforcement LearningPreprint
Wu, M., Wang, L., Zhao, P., Yang, F., Zhang, J., Liu, J., Zhan, Y., Han, W., Sun, H., Ji, J., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.17540 · Cited by 27
MiniF2F: a cross-system benchmark for formal Olympiad-level mathematics
Zheng, K., Han, J. M., & Polu, S. (2021) · arXiv · doi:10.48550/arxiv.2109.00110 · Cited by 26
VIKI‑R: Coordinating Embodied Multi-Agent Cooperation via Reinforcement Learning
Li, K., Song, X., Zhou, H., Qin, Y., Yang, J., Liu, X., Torr, P. H. S., Bai, L., & Yin, Z. (2025) · neural information processing systems · doi:10.52202/085713-3935 · Cited by 26
Self-citationR1-Code-Interpreter: LLMs Reason with Code via Supervised and Multi-stage Reinforcement LearningPreprint
Chen, Y., Liu, Y., Zhou, J., Hao, Y., Wang, J., Zhang, Y., Li, N., & Fan, C. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.21668 · Cited by 26
Self-citationAWorld: Orchestrating the Training Recipe for Agentic AIPreprint
Yu, C., Lu, S., Zhuang, C., Wang, D., Wu, Q., Li, Z., Gan, R., Wang, C., Hou, S., Huang, G., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.20404 · Cited by 26
Self-citationDreamDPO: Aligning Text-to-3D Generation with Human Preferences via Direct Preference OptimizationPreprint
Zhou, Z., Xia, X., Ma, F., Fan, H., Yang, Y., & Chua, T. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2502.04370 · Cited by 25
v1: Learning to Point Visual Tokens for Multimodal Grounded ReasoningPreprint
Chung, J., Kim, J., Kim, S., Lee, J., Kim, M. S., & Yu, Y. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.18842 · Cited by 25
AR-GRPO: Training Autoregressive Image Generation Models via Reinforcement LearningPreprint
Yuan, S., Liu, Y., Yang, Y., Zhang, J., Zuo, W., Wang, Q., Zhang, F., & Zhou, G. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.06924 · Cited by 25
WeThink: Toward General-purpose Vision-Language Reasoning via Reinforcement LearningPreprint
Yang, J., Ma, F., Wang, Z., Yin, D., Rong, K., Rao, F., & Zhang, R. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.07905 · Cited by 24
Self-citationChen, Y.-C., Hsu, P.-C., Hsu, C.-J., & Shiu, D.-S. (2025) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2025.naacl-industry.9 · Cited by 23
Self-citationSDPO: Segment-Level Direct Preference Optimization for Social Agents
Kong, A., Ma, W., Zhao, S., Li, Y., Wu, Y., Wang, K., Liu, X., Li, Q., Qin, Y., & Huang, F. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.607 · Cited by 23
Self-citationMoRE: Unlocking Scalability in Reinforcement Learning for Quadruped Vision-Language-Action Models
Zhao, H., Song, W., Wang, D., Tong, X., Ding, P., Cheng, X., & Ge, Z. (2025) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra55743.2025.11128601 · Cited by 23
Reasoning Physical Video Generation with Diffusion Timestep Tokens via Reinforcement LearningPreprint
Wang, L., Jia, L., Hu, W., Pan, K., Yue, Z., Zhao, W., Chen, J., Wu, F., & Zhang, H. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2504.15932 · Cited by 23
Satori-SWE: Evolutionary Test-Time Scaling for Sample-Efficient Software EngineeringPreprint
Zeng, G., Shen, M., Chen, D., Qi, Z., Das, S., Gutfreund, D., Cox, D., Wornell, G. W., Lu, W., Hong, Z.-W., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.23604 · Cited by 23
Agent models: Internalizing Chain-of-Action Generation into Reasoning modelsPreprint
Zhang, Y., Yang, Y., Shu, J., Wen, X., & Sang, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2503.06580 · Cited by 23
RSafe: Incentivizing proactive reasoning to build robust and adaptive LLM safeguards
zheng, J., Ji, X., Lu, Y., Cui, C., Zhao, W., Deng, G., Liang, Z., Zhang, A., & Chua, T. (2025) · neural information processing systems · doi:10.52202/085713-0960 · Cited by 23
Trial and Error: Exploration-Based Trajectory Optimization of LLM Agents
Song, Y., Da, Y., Yue, X., Huang, J., Li, S., & Lin, B. Y. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.409 · Cited by 22
DA-Code: Agent Data Science Code Generation Benchmark for Large Language Models
Huang, Y., Luo, J., Yu, Y., Zhang, Y., Lei, F., Wei, Y., He, S., Huang, L., Liu, X., Zhao, J., et al. (2024) · Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2024.emnlp-main.748 · Cited by 22
Unveiling Environmental Impacts of Large Language Model Serving: A Functional Unit View
Wu, Y., Hua, I., & Ding, Y. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.519 · Cited by 22
RL of Thoughts: Navigating LLM Reasoning with Inference-time Reinforcement LearningPreprint
Hao, Q., Li, S., Yuan, J., & Li, Y. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.14140 · Cited by 22
Self-citationPan, X.-C., Chen, Y.-X., Chen, Y.-S., Sun, Y., Chen, D.-Y., Zhang, W.-H., Xie, Y.-X., Huang, Y., Zhang, Y., Gao, D.-W., et al. (2025) · arXiv.org · doi:10.48550/arxiv.2505.17826 · Cited by 22
Self-citationYu, L., Pan, Z., Lin, H., Sun, M., He, C., & Wu, L. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2507.17512 · Cited by 21
Breaking the SFT Plateau: Multimodal Structured Reinforcement Learning for Chart-to-Code GenerationPreprint
Chen, L., Zhao, X., Zeng, Z., Huang, J., Zheng, L., Zhong, Y., & Ma, L. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.13587 · Cited by 21
Adaptive Social Learning via Mode Policy Optimization for Language AgentsPreprint
Wang, M., Li, Y., Wang, H., Zhang, X., Xu, N., Wu, B., Huang, F., Yu, H., & Mao, W. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.02156 · Cited by 21
Self-citationLiveBench: A Challenging, Contamination-Limited LLM Benchmark
White, C., Dooley, S., Roberts, M., Pal, A., Feuer, B., Jain, S., Shwartz-Ziv, R., Jain, N., Saifullah, K., Dey, S., et al. (2024) · arXiv · doi:10.48550/arxiv.2406.19314 · Cited by 20
AgentGym: Evaluating and Training Large Language Model-based Agents across Diverse Environments
Xi, Z., Ding, Y., Chen, W.-X., Hong, B., Guo, H., Wang, J., Guo, X., Yang, D., Liao, C., He, W., et al. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.1355 · Cited by 20
Self-citationSelf-Evolving Multi-Agent Systems via Textual Backpropagation
Ma, X., Ma, Y., Lin, C., Yan, S., Bi, J., Cao, Z., Tian, Y., Volker Tresp, C., & Schuetze, H. (2026) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2026.findings-acl.483 · Cited by 20
Self-citationScene-R1: Video-Grounded Large Language Models for 3D Scene Reasoning with Lightweight AnnotationsPreprint
Wang, J., Yuan, Z., Jiang, S., Feng, C.-M., Zhang, Y., Cui, S. R., Li, Z., & Zhao, N. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.17545 · Cited by 20
Self-citationToo Long, Do Re-weighting for Efficient LLM Reasoning Compression
Li, Z.-Z., Liang, X., Tang, Z., Ji, L., Wang, P., Xu, H., Xing, W., Huang, H., Deng, W., Gong, Y., et al. (2026) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2026.acl-long.1856 · Cited by 20
Self-citationFeedback-Driven Tool-Use Improvements in Large Language Models via Automated Build Environments
Ye, J., Jiang, C., Du, Z., Xu, Y., Yao, X., Xi, Z., Fan, X., Zhang, Q., Gui, T., Huang, X., et al. (2026) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2026.findings-acl.109 · Cited by 19
Li, J., & Ng, H. T. (2025) · neural information processing systems · doi:10.52202/085713-5052 · Cited by 19
How to Train a Leader: Hierarchical Reasoning in Multi-Agent LLMsPreprint
Estornell, A., Ton, J.-F., Taufiq, M., & Li, H. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2507.08960 · Cited by 18
InternBootcamp: Boosting LLM Reasoning with Verifiable Task ScalingPreprint
Li, P., Ye, J., Chen, Y., Li, L., Ma, Y., Yu, Z., 蔡奇燁, Li, H., Chen, J., Lyu, C., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.08636 · Cited by 18
Self-citationXiao, J., Li, Z., Xie, X., Getzen, E., Fang, C., Long, Q., & Su, W. J. (2025) · Journal of the American Statistical Association · doi:10.1080/01621459.2025.2555067 · Cited by 17
Self-citationSVQA-R1: Reinforcing Spatial Reasoning in MLLMs via View-Consistent Reward OptimizationPreprint
Wang, P., & Ling, H. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.01371 · Cited by 17
Compile Scene Graphs with Reinforcement LearningPreprint
Chen, Z., Wu, J., Lei, Z., Pollefeys, M., & Chen, C. W. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2504.13617 · Cited by 17
In Prospect and Retrospect: Reflective Memory Management for Long-term Personalized Dialogue Agents
Tan, Z., Yan, J., Hsu, I.-H., Han, R., Wang, Z., Le, L., Song, Y., Chen, Y., Palangi, H., Lee, G., et al. (2025) · Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2025.acl-long.413 · Cited by 16
Self-citationBe Friendly, Not Friends: How LLM Sycophancy Shapes User Trust
Sun, Y., & Wang, T. (2026) · Proceedings of the 2026 CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791079 · Cited by 16
Liu, B., Li, X., Zhang, J., Wang, J., He, T., Hong, S., Liu, H., Zhang, S., Song, K., Zhu, K., et al. (2025) · arXiv · doi:10.48550/arxiv.2504.01990 · Cited by 16
Self-citationCooper: Co-Optimizing Policy and Reward Models in Reinforcement Learning for Large Language ModelsPreprint
Hong, H., Yan, Y., Wu, X., Hou, G., Zhang, W., Lu, W., Shen, Y., & Xiao, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.05613 · Cited by 16
Sample-Efficient Alignment for LLMsPreprint
Liu, Z., Chen, C., Du, C., Lee, W. S., & Lin, M. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2411.01493 · Cited by 15
GThinker: Towards General Multimodal Reasoning via Cue-Guided RethinkingPreprint
Zhan, Y., Wu, Z., Zhu, Y., Xue, R., Luo, R., Chen, Z., Zhang, C., Li, Y., He, Z., Yang, Z., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.01078 · Cited by 15
Self-citationYan, C., Che, F., Huang, X. T., Xu, X., Li, X., Li, Y., Qu, X., Shi, J., Lin, C., Yang, Y., et al. (2025) · Research Explorer (The University of Manchester) · doi:10.48550/arxiv.2507.16331 · Cited by 15
Self-citationObserve-R1: Unlocking Reasoning Abilities of MLLMs with Dynamic Progressive Reinforcement LearningPreprint
Guo, Z., Hong, M., & Jin, T. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.12432 · Cited by 15
From Seeing to Experiencing: Scaling Navigation Foundation Models with Reinforcement LearningPreprint
He, H., Ma, Y., Squicciarini, B., Wu, W., & Zhou, B. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2507.22028 · Cited by 15
AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents
Trivedi, H., Khot, T., Hartmann, M., Manku, R., Dong, V., Li, E., Gupta, S., Sabharwal, A., & Balasubramanian, N. (2024) · Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2024.acl-long.850 · Cited by 14
Qwen2.5-Math Technical Report: Toward Mathematical Expert Model via Self-Improvement
Yang, A., Zhang, B., Hui, B., Gao, B., Yu, B., Li, C., Liu, D., Tu, J., Zhou, J., Lin, J., et al. (2024) · arXiv · doi:10.48550/arxiv.2409.12122 · Cited by 14
Self-citationBadertdinov, I., Golubev, A., Nekrashevich, M., Shevtsov, A., Karasik, S., Andriushchenko, A., Trofimova, M., Litvintseva, D., & Yangel, B. (2025) · Advances in Neural Information Processing Systems 38 · doi:10.52202/085713-0788 · Cited by 14
Search-R1: Training LLMs to Reason and Leverage Search Engines with Reinforcement Learning
Jin, B., Zeng, H., Yue, Z., Yoon, J., Arik, S., Wang, D., Zamani, H., & Han, J. (2025) · arXiv · doi:10.48550/arxiv.2503.09516 · Cited by 13
Absolute Zero: Reinforced Self-play Reasoning with Zero Data
Zhao, A., Wu, Y., Yue, Y., Wu, T., Xu, Q., Yue, Y., Lin, M., Wang, S., Wu, Q., Zheng, Z., et al. (2025) · arXiv · Cited by 13
Zhu, L., Guan, Y., Liang, D., Ju, J., Luo, Z., Qin, B., Luan, J., Liu, Y., & Bai, X. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.05612 · Cited by 13
InfLVG: Reinforce Inference-Time Consistent Long Video Generation with GRPOPreprint
Fang, X., Ma, L., Chen, Z., Zhou, M., & Qi, G. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.17574 · Cited by 13
AppBench: Planning of Multiple APIs from Various APPs for Complex User Instruction
Wang, H., Wang, R., Xue, B., Xia, H., Cao, J., Liu, Z., Pan, J. Z., & Wong, K. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-main.856 · Cited by 13
Self-citationtrlX: A Framework for Large Scale Reinforcement Learning from Human Feedback
Havrilla, A., Zhuravinskyi, M., Phung, D., Tiwari, A., Tow, J., Biderman, S., Anthony, Q., & Castricato, L. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.530 · Cited by 12
Can 3D Vision-Language Models Truly Understand Natural Language?Preprint
Deng, W., Yang, J., Ding, R., Liu, J., Li, Y., Qi, X., & Ngai, E. C. ‐. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2403.14760 · Cited by 12
Self-citationKimi k1.5: Scaling Reinforcement Learning with LLMs
Kimi Team, Du, A., Gao, B., Xing, B., Jiang, C., Chen, C., Li, C., Xiao, C., Du, C., Liao, C., et al. (2025) · arXiv · doi:10.48550/arxiv.2501.12599 · Cited by 12
Self-citationReinforcement Learning for Machine Learning Engineering AgentsPreprint
Yang, S. X., He-Yueya, J., & Liang, P. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2509.01684 · Cited by 12
Think-RM: Enabling Long-Horizon Reasoning in Generative Reward Models
Hong, I., Yu, C., Qiu, L., Yan, W., Xu, Z., Jiang, H., Zhang, Q., Lu, Q., Liu, X., Zhang, C., et al. (2025) · neural information processing systems · doi:10.52202/085713-5795 · Cited by 12
Self-citationPlanning without Search: Refining Frontier LLMs with Offline Goal-Conditioned RL
Hong, J., Dragan, A., & Levine, S. (2025) · neural information processing systems · doi:10.52202/085713-0338 · Cited by 12
EPO: Explicit Policy Optimization for Strategic Reasoning in LLMs via Reinforcement Learning
Liu, X., Wang, K., Li, Y., Wu, Y., Ma, W., Kong, A., Huang, F., Jiao, J., & Zhang, J. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.747 · Cited by 11
Self-citationDuPO: Enabling Reliable LLM Self-Verification via Dual Preference OptimizationPreprint
She, S., Bao, Y., Yu, L., Xu, L., Li, T., Zhu, W., Huang, S., Cheng, S., Lu, L., & Wang, Y. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.14460 · Cited by 11
Self-citationBeyond Words: A Latent Memory Approach to Internal Reasoning in LLMsPreprint
Orlicki, J. I. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2502.21030 · Cited by 11
Aligning to What? Limits to RLHF Based Alignment
Barnhart, L., Bafghi, R. A., Becker, S., & Raissi, M. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.421 · Cited by 10
Liu, K., Pan, Y., Xiang, Y., He, D., Li, J., Du, Y., & Gao, T. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.1036 · Cited by 10
Park, C., Han, S., Guo, X., Ozdaglar, A. E., Zhang, K., & Kim, J.-K. (2025) · Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2025.acl-long.1459 · Cited by 10
Song, Z., Yue, S., & Zhang, J. (2025) · SuperIntelligence - Robotics - Safety & Alignment · doi:10.70777/si.v2i6.15961 · Cited by 10
Wisdom of the Crowd: Reinforcement Learning from Coevolutionary Collective FeedbackPreprint
Yuan, W., Tang, S., Lin, W., Ruan, J., Cui, G., Zhang, B., Chen, T., Liu, T., Fu, Y., Ye, P., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.12338 · Cited by 10
Self-citationJoyAgent-JDGenie: Technical Report on the GAIAPreprint
Liu, J., Xu, S., Liu, S., Li, Y., Liu, W., Liu, M., Zhou, X., Wang, H., Jia, S., Wang, Z., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.00510 · Cited by 10
Self-citationThinking Machines: Mathematical Reasoning in the Age of LLMs
Asperti, A., Naibo, A., & Coen, C. S. (2026) · Big Data and Cognitive Computing · doi:10.3390/bdcc10010038 · Cited by 10
The Hallucination Tax of Reinforcement Finetuning
Song, L., Shi, T., & Zhao, J. (2025) · Findings of the Association for Computational Linguistics: EMNLP 2025 · doi:10.18653/v1/2025.findings-emnlp.112 · Cited by 10
Unified Multimodal Understanding via Byte-Pair Visual Encoding
Zhang, W., Feng, Y., Luo, H., Li, Y., Yue, Z., Zheng, S., & Lu, Z. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.01206 · Cited by 10
Self-citationMem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
Chhikara, P., Khant, D., Aryan, S., Singh, T., & Yadav, D. (2025) · arXiv · doi:10.48550/arxiv.2504.19413 · Cited by 10
AgentFly: Scaling Agentic Reinforcement Learning with Unified Resource SystemPreprint
Wang, R., Bouardi, B. E., Genadi, R. A., Wang, Y., Wang, S., Koto, F., Liu, Z., Baldwin, T., & Li, H. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2507.14897 · Cited by 10
CodeBoost: Boosting Code LLMs by Squeezing Knowledge from Code Snippets with RLPreprint
Wang, S., Guo, Q., Zhao, K., Zhang, Y., Li, X., Li, X., Li, S., She, R., Yu, S., & Tay, W. P. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.05242 · Cited by 10
Zep: A Temporal Knowledge Graph Architecture for Agent Memory
Rasmussen, P., Paliychuk, P., Beauvais, T., Ryan, J., & Chalef, D. (2025) · arXiv · doi:10.48550/arxiv.2501.13956 · Cited by 9
FireAct: Toward Language Agent Fine-tuning
Chen, B., Shu, C., Shareghi, E., Collier, N., Narasimhan, K., & Yao, S. (2023) · arXiv · doi:10.48550/arxiv.2310.05915 · Cited by 9
A Survey on Self-Evolution of Large Language Models
Tao, Z., Lin, T.-E., Chen, X., Li, H., Wu, Y., Li, Y., Jin, Z., Huang, F., Tao, D., & Zhou, J. (2024) · arXiv · doi:10.48550/arxiv.2404.14387 · Cited by 9
Self-citationFrom Pixels to Tokens: Byte-Pair Encoding on Quantized Visual ModalitiesPreprint
Zhang, W., Xie, Z., Feng, Y., Li, Y., Xing, X., Zheng, S., & Lu, Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.02155 · Cited by 9
Self-citationNabla-R2D3: Effective and Efficient 3D Diffusion Alignment with 2D Rewards
Liu, Q., Liu, Z., Zhang, D., & Jia, K. (2025) · neural information processing systems · doi:10.52202/085713-1597 · Cited by 9
ARIA: Training Language Agents with Intention-driven Reward Aggregation
Yang, R., Zhang, Y., Chen, A., Wang, X., Chen, J., Yuan, S., Yang, D., & Xiao, Y. (2025) · neural information processing systems · doi:10.52202/085713-3665 · Cited by 9
Li, Z., Hu, Y., & Wang, W. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.19598 · Cited by 9
Self-citationTowards Better Correctness and Efficiency in Code Generation
Feng, Y., Xu, Y., Xu, X., Hui, B., & Lin, J. (2026) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v40i36.40327 · Cited by 9
DMOSpeech 2: Reinforcement Learning for Duration Prediction in Metric-Optimized Speech Synthesis
Li, Y. A., Jiang, X., Tao, F., Niu, C., Xu, K., Song, J., & Mesgarani, N. (2026) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v40i38.40450 · Cited by 9
Self-citationUnderstanding R1-Zero-Like Training: A Critical Perspective
Liu, Z., Chen, C., Li, W., Qi, P., Pang, T., Du, C., Lee, W. S., & Lin, M. (2025) · arXiv · doi:10.48550/arxiv.2503.20783 · Cited by 8
VideoOrion: Tokenizing Object Dynamics in Videos
Feng, Y., Li, Y., Zhang, W., Zheng, S., Luo, H., Yue, Z., & Lu, Z. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.01897 · Cited by 8
Self-citationGemini Robotics: Bringing AI into the Physical World
Gemini Robotics Team, Abeyruwan, S., Ainslie, J., Alayrac, J.-B., Arenas, M. G., Armstrong, T., Balakrishna, A., Baruch, R., Bauza, M., Blokzijl, M., et al. (2025) · arXiv · doi:10.48550/arxiv.2503.20020 · Cited by 8
Focused-DPO: Enhancing Code Generation Through Focused Preference Optimization on Error-Prone Points
Zhang, K., Li, G., Li, J., Dong, Y., Li, J., & Jin, Z. G. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.498 · Cited by 8
Planner-R1: Reward Shaping Enables Efficient Agentic RL with Smaller LLMsPreprint
Zhu, S., Jiang, Y., Sang, H., Tang, S., Song, Q., He, B., Jain, R., Wang, Z., & Geramifard, A. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2509.25779 · Cited by 8
Self-citationSoundMind: RL-Incentivized Logic Reasoning for Audio-Language Models
Diao, X., Zhang, C., Kong, K., Wu, W., Ma, C., Ouyang, Z., Qing, P., Vosoughi, S., & Gui, J. (2025) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2025.emnlp-main.27 · Cited by 8
Self-citationLuban: Building Open-Ended Creative Agents via Autonomous Embodied VerificationPreprint
Guo, Y., Peng, S., Guo, J., Huang, D., Zhang, X., Zhang, R., Hao, Y., Li, L., Tian, Z., Gao, M., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2405.15414 · Cited by 7
Self-citationUI-TARS: Pioneering Automated GUI Interaction with Native Agents
Qin, Y., Ye, Y., Fang, J., Wang, H., Liang, S., Tian, S., Zhang, J., Li, J., Li, Y., Huang, S., et al. (2025) · arXiv · doi:10.48550/arxiv.2501.12326 · Cited by 7
Self-citationSFT Memorizes, RL Generalizes: A Comparative Study of Foundation Model Post-training
Chu, T., Zhai, Y., Yang, J., Tong, S., Xie, S., Schuurmans, D., Le, Q. V., Levine, S., & Ma, Y. (2025) · arXiv · doi:10.48550/arxiv.2501.17161 · Cited by 7
TTRL: Test-Time Reinforcement Learning
Zuo, Y., Zhang, K., Sheng, L., Qu, S., Cui, G., Zhu, X., Li, H., Zhang, Y., Long, X., Hua, E., et al. (2025) · arXiv · Cited by 7
G-Memory: Tracing Hierarchical Memory for Multi-Agent Systems
Zhang, G., Fu, M., Wang, K., Wan, F., Yu, M., & Yan, S. (2025) · Advances in Neural Information Processing Systems 38 · doi:10.52202/085713-0439 · Cited by 7
Self-citationR1-Searcher: Incentivizing the Search Capability in LLMs via Reinforcement Learning
Song, H., Jiang, J., Min, Y., Chen, J., Chen, Z., Zhao, W. X., Fang, L., & Wen, J.-R. (2025) · arXiv · doi:10.48550/arxiv.2503.05592 · Cited by 7
Efficient Multi-Agent System Training with Data Influence-Oriented Tree Search
Shi, W., Yu, Z., Feng, F., He, X., & Xiong, C. (2026) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2026.acl-long.296 · Cited by 6
A Survey on Code Generation with LLM-based Agents
Dong, Y., Jiang, X., Qian, J., Wang, T., Zhang, K., Jin, Z., & Li, G. (2025) · arXiv · doi:10.48550/arxiv.2508.00083 · Cited by 6
TuneAgent: Agentic Operating System Kernel Tuning with Reinforcement LearningPreprint
Lin, H., Li, Y., Luo, H., Lin, Z., Zhang, L., Xing, M., & Wu, Y. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.12551 · Cited by 6
Self-citationALAS: Autonomous Learning Agent for Self-Updating Language ModelsPreprint
Atreja, D. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.15805 · Cited by 6
Kavathekar, I., Donakanti, R., Kumaraguru, P., & Vaidhyanathan, K. (2025) · Proceedings of the 29th International Conference on Evaluation and Assessment in Software Engineering · doi:10.1145/3756681.3757001 · Cited by 6
Singh, K. V., Singh, S., & Khanna, M. (2025) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw67362.2025.00022 · Cited by 5
Large Language Model Agent: A Survey on Methodology, Applications and Challenges
Luo, J., Zhang, W., Yuan, Y., Zhao, Y., Yang, J., Gu, Y., Wu, B., Chen, B., Qiao, Z., Long, Q., et al. (2025) · arXiv · doi:10.48550/arxiv.2503.21460 · Cited by 5
ADAPT: Actively Discovering and Adapting to Preferences for any TaskPreprint
Patel, M., Puig, X., Desai, R., Mottaghi, R., Chernova, S., Truong, J., & Rai, A. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2504.04040 · Cited by 5
MALT: Improving Reasoning with Multi-Agent LLM TrainingPreprint
Motwani, S., Smith, C., Das, R. J., Rafailov, R., Ivan Laptev, A., Torr, P. H. S., Pizzati, F., Clark, R., & de Witt, C. S. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2412.01928 · Cited by 4
Self-citationZero-Shot Llms in Human-in-The-Loop Rl: Replacing Human Feedback for Reward ShapingPreprint
Banerjee, C., & Nazir, M. S. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5218722 · Cited by 4
Towards Reward Fairness in RLHF: From a Resource Allocation Perspective
Ouyang, S., Hu, Y., Chen, G., Li, Q., Zhang, F., & Liu, Y. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.163 · Cited by 4
Chen, Y., Huang, W., Shi, B., Hu, Q., Ye, H., Zhu, L., Liu, Z., Molchanov, P. A., Kautz, J., Qi, X., et al. (2025) · neural information processing systems · doi:10.52202/085713-5753 · Cited by 4
Self-citationTeaching Your Models to Understand Code via Focal Preference Alignment
Wu, J., Li, H., Zhang, X., Liu, X., Huang, Y., Luo, J., Zhang, Y., Li, Z., Chu, R., Yang, Y., et al. (2025) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2025.emnlp-main.707 · Cited by 4
Self-citationL0: Reinforcement Learning to Become General AgentsPreprint
Zhang, J., Xi, J., Song, Z., Lu, J., Ke, Y., Sun, T., Yang, Y., Zhang, J., Zhang, S., & Xie, Z. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.23667 · Cited by 4
Ren, Z. Z., Shao, Z., Song, J., Xin, H., Wang, H., Zhao, W., Zhang, L., Fu, Z., Zhu, Q., Yang, D., et al. (2025) · arXiv · doi:10.48550/arxiv.2504.21801 · Cited by 4
Self-citationNaturalGAIA: A Verifiable Benchmark and Hierarchical Framework for Long-Horizon GUI Tasks
Zheng, Z., Cui, T., Wang, T., Wang, F., Pan, J., He, L., & Chen, Q. (2026) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2026.acl-long.2207 · Cited by 4
Windows Agent Arena: Evaluating Multi-Modal OS Agents at Scale
Bonatti, R., Zhao, D., Bonacci, F., Dupont, D., Abdali, S., Li, Y., Lu, Y., Wagle, J., Koishida, K., Bucker, A., et al. (2024) · arXiv · doi:10.48550/arxiv.2409.08264 · Cited by 3
Self-citationFrom Human Memory to AI Memory: A Survey on Memory Mechanisms in the Era of LLMs
Wu, Y., Liang, S., Zhang, C., Wang, Y., Zhang, Y., Guo, H., Tang, R., & Liu, Y. (2025) · arXiv · doi:10.48550/arxiv.2504.15965 · Cited by 3
Self-citationMind2Web 2: Evaluating Agentic Search with Agent-as-a-Judge
Gou, B., Huang, Z., Ning, Y., Gu, Y., Lin, M., Qi, W., Kopanev, A., Yu, B., Gutiérrez, B. J., Shu, Y., et al. (2025) · arXiv · doi:10.48550/arxiv.2506.21506 · Cited by 3
Self-citationTacticCraft: Natural Language-Driven Tactical Adaptation for StarCraft IIPreprint
Ma, W., Jiang, J., Fu, H., & Zhang, H. (2025) · arXiv (Cornell University) · Cited by 3
Pruning Long Chain-of-Thought of Large Reasoning Models via Small-Scale Preference OptimizationPreprint
Hong, B., Liu, J., Zhang, K., Sun, J., Zhang, M., & Huang, Z. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.10164 · Cited by 3
ToolRL: Reward is All Tool Learning Needs
Qian, C., Acikgoz, E. C., He, Q., Wang, H., Chen, X., Hakkani-Tür, D., Tur, G., & Ji, H. (2025) · arXiv · doi:10.48550/arxiv.2504.13958 · Cited by 3
Self-citationGao, H.-A., Geng, J., Hua, W., Hu, M., Juan, X., Liu, H., Liu, S., Qiu, J., Qi, X., Wu, Y., et al. (2025) · arXiv · doi:10.48550/arxiv.2507.21046 · Cited by 3
Self-citationProver-Verifier Games improve legibility of LLM outputs
Kirchner, J. H., Chen, Y., Edwards, H., Leike, J., McAleese, N., & Burda, Y. (2024) · arXiv · doi:10.48550/arxiv.2407.13692 · Cited by 2
Self-citationDiverse Preference Optimization
Lanchantin, J., Chen, A., Dhuliawala, S., Yu, P., Weston, J., Sukhbaatar, S., & Kulikov, I. (2025) · arXiv · doi:10.48550/arxiv.2501.18101 · Cited by 2
Aratchige, R. M., & Ilmini, W. M. K. S. (2025) · arXiv · doi:10.48550/arxiv.2504.01963 · Cited by 2
𝜙-Decoding: Adaptive Foresight Sampling for Balanced Inference-Time Exploration and Exploitation
Xu, F., Yan, H., Ma, C., Zhao, H., Liu, J., Lin, Q., & Wu, Z. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.647 · Cited by 2
Kimina-Prover Preview: Towards Large Formal Reasoning Models with Reinforcement Learning
Wang, H., Unsal, M., Lin, X., Baksys, M., Liu, J., Santos, M. D., Sung, F., Vinyes, M., Ying, Z., Zhu, Z., et al. (2025) · arXiv · doi:10.48550/arxiv.2504.11354 · Cited by 2
Self-citationBrowseComp: A Simple Yet Challenging Benchmark for Browsing Agents
Wei, J., Sun, Z., Papay, S., McKinney, S., Han, J., Fulford, I., Chung, H. W., Passos, A. T., Fedus, W., & Glaese, A. (2025) · arXiv · doi:10.48550/arxiv.2504.12516 · Cited by 2
Multi-agent Path Finding via Offline RL and LLM Collaboration
Atasever, M., Hong, M., Kulkarni, M. N., Li, Q., & Deshmukh, J. V. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-39395-1_2 · Cited by 2
TongUI: Internet-Scale Trajectories from Multimodal Web Tutorials for Generalized GUI Agents
Zhang, B., Shang, Z., Gao, Z., Zhang, W., Xie, R., Ma, X., Yuan, T., Wu, X., Zhu, S. C., & Li, Q. (2026) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v40i15.38229 · Cited by 2
Gardner, J., Dutta, A., Roy, S., Patrick Kreidl, O., & Bölöni, L. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-026-11520-x · Cited by 2
Acting Less is Reasoning More! Teaching Model to Act Efficiently
Wang, H., Qian, C., Zhong, W., Chen, X., Qiu, J., Huang, S., Jin, B., Wang, M., Wong, K.-F., & Ji, H. (2025) · arXiv · doi:10.48550/arxiv.2504.14870 · Cited by 1
Self-citationScaling Long-Horizon LLM Agent via Context-Folding
Sun, W., Lu, M., Ling, Z., Liu, K., Yao, X., Yang, Y., & Chen, J. (2025) · arXiv · doi:10.48550/arxiv.2510.11967 · Cited by 1
Evaluating Memory in LLM Agents via Incremental Multi-Turn Interactions
Hu, Y., Wang, Y., & McAuley, J. (2025) · arXiv · doi:10.48550/arxiv.2507.05257 · Cited by 1
TeViR: Text-to-Video Reward With Diffusion Models for Efficient Reinforcement Learning
Chen, Y., Li, H., Jiang, Z., Wen, H., & Zhao, D. (2025) · IEEE Transactions on Systems Man and Cybernetics Systems · doi:10.1109/tsmc.2025.3638818 · Cited by 1
Self-citationR-Zero: Self-Evolving Reasoning LLM from Zero Data
Huang, C., Yu, W., Wang, X., Zhang, H., Li, Z., Li, R., Huang, J., Mi, H., & Yu, D. (2025) · arXiv · doi:10.48550/arxiv.2508.05004 · Cited by 1
Self-citationMemAgent: Reshaping Long-Context LLM with Multi-Conv RL-based Memory Agent
Yu, H., Chen, T., Feng, J., Chen, J., Dai, W., Yu, Q., Zhang, Y.-Q., Ma, W.-Y., Liu, J., Wang, M., et al. (2025) · arXiv · doi:10.48550/arxiv.2507.02259 · Cited by 1
Self-citationAdaptive Command: Real-Time Policy Adjustment via Language Models in StarCraft IIPreprint
Ma, W., Xu, D., Lin, S., Zhang, H., & Wang, J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2508.16580 · Cited by 1
Self-citationAgent Lightning: Train ANY AI Agents with Reinforcement Learning
Luo, X., Zhang, Y., He, Z., Wang, Z., Zhao, S., Li, D., Qiu, L. K., & Yang, Y. (2025) · arXiv · doi:10.48550/arxiv.2508.03680
Self-citationThinking with Images for Multimodal Reasoning: Foundations, Methods, and Future Frontiers
Su, Z., Xia, P., Guo, H., Liu, Z., Ma, Y., Qu, X., Liu, J., Li, Y., Zeng, K., Yang, Z., et al. (2025) · arXiv · doi:10.48550/arxiv.2506.23918
Self-citationLearning to Give Checkable Answers with Prover-Verifier Games
Anil, C., Zhang, G., Wu, Y., & Grosse, R. (2021) · arXiv · doi:10.48550/arxiv.2108.12099
Self-citationCondor: Enhance LLM Alignment with Knowledge-Driven Data Synthesis and Refinement
Maosongcao, M., Zhang, T., Li, M., Zhang, C., Liu, Y., He, C., Duan, H., Zhang, S., & Chen, K. (2025) · Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2025.acl-long.1091
Self-citationBreakpoint: Scalable evaluation of system-level reasoning in LLM code agents
Hariharan, K., Girit, U., Wang, A., & Andreas, J. (2025) · arXiv · doi:10.48550/arxiv.2506.00172
Synthetic Data Generation & Multi-Step RL for Reasoning & Tool Use
Goldie, A., Mirhoseini, A., Zhou, H., Cai, I., & Manning, C. D. (2025) · arXiv · doi:10.48550/arxiv.2504.04736
Self-citationMaximizing Confidence Alone Improves Reasoning
Prabhudesai, M., Chen, L., Ippoliti, A., Fragkiadaki, K., Liu, H., & Pathak, D. (2025) · arXiv · doi:10.48550/arxiv.2505.22660
ZeroGUI: Automating Online GUI Learning at Zero Human Cost
Yang, C., Su, S., Liu, S., Dong, X., Yu, Y., Su, W., Wang, X., Liu, Z., Zhu, J., Li, H., et al. (2025) · arXiv · doi:10.48550/arxiv.2505.23762
CWM: An Open-Weights LLM for Research on Code Generation with World Models
FAIR CodeGen team, Copet, J., Carbonneaux, Q., Cohen, G., Gehring, J., Kahn, J., Kossen, J., Kreuk, F., McMilin, E., Meyer, M., et al. (2025) · arXiv · doi:10.48550/arxiv.2510.02387
DeepEyes: Incentivizing "Thinking with Images" via Reinforcement Learning
Zheng, Z., Yang, M., Hong, J., Zhao, C., Xu, G., Yang, L., Shen, C., & Yu, X. (2025) · arXiv · doi:10.48550/arxiv.2505.14362
Self-citationMARFT: Multi-Agent Reinforcement Fine-Tuning
Liao, J., Wen, M., Wang, J., & Zhang, W. (2025) · arXiv · doi:10.48550/arxiv.2504.16129
Self-citationMLE-Dojo: Interactive Environments for Empowering LLM Agents in Machine Learning Engineering
Qiang, R., Zhuang, Y., Li, Y., Sagar V K, D., Zhang, R., Li, C., Wong, I., Yang, S., Liang, P., Zhang, C., et al. (2025) · Advances in Neural Information Processing Systems 38 · doi:10.52202/085713-0139
Self-citationSeg-Zero: Reasoning-Chain Guided Segmentation via Cognitive Reinforcement
Liu, Y., Peng, B., Zhong, Z., Yue, Z., Lu, F., Yu, B., & Jia, J. (2025) · arXiv · doi:10.48550/arxiv.2503.06520
HERO: Hardware-Efficient RL-based Optimization Framework for NeRF Quantization
Zhang, Y., Ma, C., Ge, J., Jiang, L., Xu, J., & Zhang, W. (2026) · Asia and South Pacific Design Automation Conference (ASP-DAC) · doi:10.1109/asp-dac66049.2026.11420625
Acme: A Research Framework for Distributed Reinforcement Learning
Hoffman, M. W., Shahriari, B., Aslanides, J., Barth-Maron, G., Momchev, N., Sinopalnikov, D., Stańczyk, P., Ramos, S., Raichuk, A., Vincent, D., et al. (2020) · arXiv · doi:10.48550/arxiv.2006.00979
Self-citationProofNet: Autoformalizing and Formally Proving Undergraduate-Level Mathematics
Azerbayev, Z., Piotrowski, B., Schoelkopf, H., Ayers, E. W., Radev, D., & Avigad, J. (2023) · arXiv · doi:10.48550/arxiv.2302.12433
GPT-4V in Wonderland: Large Multimodal Models for Zero-Shot Smartphone GUI Navigation
Yan, A., Yang, Z., Zhu, W., Lin, K., Li, L., Wang, J., Yang, J., Zhong, Y., McAuley, J., Gao, J., et al. (2023) · arXiv · doi:10.48550/arxiv.2311.07562
Self-citationVideoLLaMA 2: Advancing Spatial-Temporal Modeling and Audio Understanding in Video-LLMs
Cheng, Z., Leng, S., Zhang, H., Xin, Y., Li, X., Chen, G., Zhu, Y., Zhang, W., Luo, Z., Zhao, D., et al. (2024) · arXiv · doi:10.48550/arxiv.2406.07476
VinePPO: Refining Credit Assignment in RL Training of LLMs
Kazemnejad, A., Aghajohari, M., Portelance, E., Sordoni, A., Reddy, S., Courville, A., & Roux, N. L. (2024) · arXiv · doi:10.48550/arxiv.2410.01679
The Vulnerability of Language Model Benchmarks: Do They Accurately Reflect True LLM Performance?
Banerjee, S., Agarwal, A., & Singh, E. (2024) · arXiv · doi:10.48550/arxiv.2412.03597
Code Simulation as a Proxy for High-order Tasks in Large Language Models
La Malfa, E., Weinhuber, C., Torre, O., Lin, F., Huang, X. A., Marro, S., Cohn, A., Shadbolt, N., & Wooldridge, M. (2025) · arXiv · doi:10.48550/arxiv.2502.03568
Agent RL Scaling Law: Agent RL with Spontaneous Code Execution for Mathematical Problem Solving
Mai, X., Xu, H., Li, Z.-Z., W, X., Wang, W., Hu, J., Zhang, Y., & Zhang, W. (2025) · arXiv · doi:10.48550/arxiv.2505.07773
Self-citationCode World Models for General Game Playing
Lehrach, W., Hennes, D., Lazaro-Gredilla, M., Lou, X., Wendelken, C., Li, Z., Dedieu, A., Grau-Moya, J., Lanctot, M., Iscen, A., et al. (2025) · arXiv · doi:10.48550/arxiv.2510.04542
Self-citationComputerRL: Scaling End-to-End Online Reinforcement Learning for Computer Use Agents
Lai, H., Liu, X., Zhao, Y., Xu, H., Zhang, H., Jing, B., Ren, Y., Yao, S., Dong, Y., & Tang, J. (2025) · arXiv · doi:10.48550/arxiv.2508.14040
EgoVLM: Policy Optimization for Egocentric Video Understanding
Vinod, A., Pandit, S., Vavre, A., & Liu, L. (2025) · arXiv · doi:10.48550/arxiv.2506.03097
Revisiting Reinforcement Learning for LLM Reasoning from A Cross-Domain Perspective
Cheng, Z., Hao, S., Liu, T., Zhou, F., Xie, Y., Yao, F., Bian, Y., Zhuang, Y., Dey, N., Zha, Y., et al. (2025) · arXiv · doi:10.48550/arxiv.2506.14965
Self-citationLian, S., Wu, Y., Ma, J., Ding, Y., Song, Z., Chen, B., Zheng, X., Li, H., & Ji, R. (2025) · arXiv · doi:10.48550/arxiv.2507.22025
Self-citationAgent Network Protocol Technical White Paper
Chang, G., Lin, E., Yuan, C., Cai, R., Chen, B., Xie, X., & Zhang, Y. (2025) · arXiv · doi:10.48550/arxiv.2508.00007
Are Reasoning Models More Prone to Hallucination?
Yao, Z., Liu, Y., Chen, Y., Chen, J., Fang, J., Hou, L., Li, J., & Chua, T.-S. (2025) · arXiv · doi:10.48550/arxiv.2505.23646
Self-citationJiang, P., Lin, J., Cao, L., Tian, R., Kang, S., Wang, Z., Sun, J., & Han, J. (2025) · arXiv · doi:10.48550/arxiv.2503.00223
Self-citationA Comprehensive Survey of Reward Models: Taxonomy, Applications, Challenges, and Future
Zhong, J., Shen, W., Li, Y., Gao, S., Lu, H., Chen, Y., Zhang, Y., Zhou, W., Gu, J., & Zou, L. (2025) · arXiv · doi:10.48550/arxiv.2504.12328
Self-citationA comprehensive taxonomy of hallucinations in Large Language Models
Cossio, M. (2025) · arXiv · doi:10.48550/arxiv.2508.01781
DreamCS: Geometry-Aware Text-to-3D Generation with Unpaired 3D Reward Supervision
Zou, X., Xia, R., Wang, H., & Zhou, P. (2025) · arXiv · doi:10.48550/arxiv.2506.09814
Self-citationDanceGRPO: Unleashing GRPO on Visual Generation
Xue, Z., Wu, J., Gao, Y., Kong, F., Zhu, L., Chen, M., Liu, Z., Liu, W., Guo, Q., Huang, W., et al. (2025) · arXiv · doi:10.48550/arxiv.2505.07818
LADDER: Self-Improving LLMs Through Recursive Problem Decomposition
Simonds, T., & Yoshiyama, A. (2025) · arXiv · doi:10.48550/arxiv.2503.00735
MetaSpatial: Reinforcing 3D Spatial Reasoning in VLMs for the Metaverse
Pan, Z., & Liu, H. (2025) · arXiv · doi:10.48550/arxiv.2503.18470
Magentic-UI: Towards Human-in-the-loop Agentic Systems
Mozannar, H., Bansal, G., Tan, C., Fourney, A., Dibia, V., Chen, J., Gerrits, J., Payne, T., Maldaner, M. K., Grunde-McLaughlin, M., et al. (2025) · arXiv · doi:10.48550/arxiv.2507.22358
Training Long-Context, Multi-Turn Software Engineering Agents with Reinforcement Learning
Golubev, A., Trofimova, M., Polezhaev, S., Badertdinov, I., Nekrashevich, M., Shevtsov, A., Karasik, S., Abramov, S., Andriushchenko, A., Fisin, F., et al. (2025) · arXiv · doi:10.48550/arxiv.2508.03501
Towards Alignment-Centric Paradigm: A Survey of Instruction Tuning in Large Language Models
Han, X., Yang, J., Wang, T., Bi, Z., Song, X., Hao, J., & Song, J. (2025) · arXiv · doi:10.48550/arxiv.2508.17184
Learning When to Plan: Efficiently Allocating Test-Time Compute for LLM Agents
Paglieri, D., Cupiał, B., Cook, J., Piterbarg, U., Tuyls, J., Grefenstette, E., Foerster, J. N., Parker-Holder, J., & Rocktäschel, T. (2025) · arXiv · doi:10.48550/arxiv.2509.03581
Coggins, S., Saeri, A. K., Daniell, K. A., Ruster, L. P., Liu, J., & Davis, J. L. (2025) · arXiv · doi:10.48550/arxiv.2509.24394
How Reinforcement Learning After Next-Token Prediction Facilitates Learning
Tsilivis, N., Malach, E., Ullrich, K., & Kempe, J. (2025) · arXiv · doi:10.48550/arxiv.2510.11495
Agentic Large Language Models, a survey
Plaat, A., van Duijn, M., van Stein, N., et al. (2025) · arXiv · doi:10.48550/arxiv.2503.23037
Research works printed but not linked: 206
- Marwa Abdulhai, Isadora White, Charlie Victor Snell, Charles Sun, Joey Hong, Yuexiang Zhai, Kelvin Xu, and Sergey Levine. LMRL gym: Benchmarks for multi-turn reinforcement learning with language models. In Forty-second International Conference on Machine Learning, 2025. URL https://openreview.net/ forum?id=hmGhP5DO2W.
- Pranjal Aggarwal and Sean Welleck. L1: Controlling how long a reasoning model thinks with reinforcement learning. In Second Conference on Language Modeling, 2025. URL https://openreview.net/forum? id=4jdIxXBNve.
- Thomas Anthony, Zheng Tian, and David Barber. Thinking fast and slow with deep learning and tree search. In I. Guyon, U. Von Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Garnett (eds.), Advances in Neural Information Processing Systems, volume 30.
- Curran Asso- ciates, Inc., 2017. URL https://proceedings.neurips.cc/paper_files/paper/2017/file/ d8e1344e27a5b08cdfd5d027d9b8d6de-Paper.pdf.
- Hao Bai, Yifei Zhou, Mert Cemri, Jiayi Pan, Alane Suhr, Sergey Levine, and Aviral Kumar. Digirl: Training in-the-wild device-control agents with autonomous reinforcement learning. In A. Globerson, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Advances in Neural Information Processing Systems, volume 37, pp. 12461-12495.
- Curran Asso- ciates, Inc., 2024. URL https://proceedings.neurips.cc/paper_files/paper/2024/file/ 1704ddd0bb89f159dfe609b32c889995-Paper-Conference.pdf.
- Logan Barnhart, Reza Akbarian Bafghi, Stephen Becker, and Maziar Raissi. Aligning to what? limits to RLHF based alignment. In Luis Chiruzzo, Alan Ritter, and Lu Wang (eds.), Findings of the Association for Computational Linguistics: NAACL 2025, pp. 7556-7591, Albuquerque, New Mexico, April 2025b. Association for Computational Linguistics. ISBN 979-8-89176-195-7. doi: 10.18653/v1/2025.findings-naacl. 421. URL https://aclanthology.org/2025.findings-naacl.421/. · DOI
- Victor Barres, Honghua Dong, Soham Ray, Xujie Si, and Karthik Narasimhan. τ 2 -bench: Evaluating conversational agents in a dual-control environment, 2025. URL https://arxiv.org/abs/2506. 07982.
- Jun Shern Chan, Neil Chowdhury, Oliver Jaffe, James Aung, Dane Sherburn, Evan Mays, Giulio Starace, Kevin Liu, Leon Maksin, Tejal Patwardhan, Aleksander Madry, and Lilian Weng. MLE-bench: Evaluating machine learning agents on machine learning engineering. In The Thirteenth International Conference on Learning Representations, 2025. URL https://openreview.net/forum?id=6s5uXNWGIh.
- Boyuan Chen, Zhuo Xu, Sean Kirmani, Brain Ichter, Dorsa Sadigh, Leonidas Guibas, and Fei Xia. Spatialvlm: Endowing vision-language models with spatial reasoning capabilities. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 14455-14465, 2024a.
- Sijin Chen, Xin Chen, Chi Zhang, Mingsheng Li, Gang Yu, Hao Fei, Hongyuan Zhu, Jiayuan Fan, and Tao Chen. Ll3da: Visual interactive instruction tuning for omni-3d understanding reasoning and planning. In Published in Transactions on Machine Learning Research (01/2026) Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pp. 26428-26438, 2024d.
- Weize Chen, Yusheng Su, Jingwei Zuo, Cheng Yang, Chenfei Yuan, Chi-Min Chan, Heyang Yu, Yaxi Lu, Yi-Hsin Hung, Chen Qian, Yujia Qin, Xin Cong, Ruobing Xie, Zhiyuan Liu, Maosong Sun, and Jie Zhou. Agentverse: Facilitating multi-agent collaboration and exploring emergent behaviors. In The Twelfth International Conference on Learning Representations, 2024e. URL https://openreview. net/forum?id=EHg5GDnyq1.
- Weize Chen, Jiarui Yuan, Chen Qian, Cheng Yang, Zhiyuan Liu, and Maosong Sun. Optima: Optimizing effectiveness and efficiency for llm-based multi-agent system, 2025e. URL https://arxiv.org/abs/ 2410.08115.
- Xingyu Chen, Jiahao Xu, Tian Liang, Zhiwei He, Jianhui Pang, Dian Yu, Linfeng Song, Qiuzhi Liu, Mengfei Zhou, Zhuosheng Zhang, Rui Wang, Zhaopeng Tu, Haitao Mi, and Dong Yu. Do NOT think that much for 2+3=? on the overthinking of long reasoning models. In Forty-second International Conference on Machine Learning, 2025g. URL https://openreview.net/forum?id=MSbU3L7V00.
- Xinyun Chen, Maxwell Lin, Nathanael Schärli, and Denny Zhou. Teaching large language models to self-debug. In The Twelfth International Conference on Learning Representations, 2024f. URL https: //openreview.net/forum?id=KuPixIqPiq.
- Zhe Chen, Jiannan Wu, Wenhai Wang, Weijie Su, Guo Chen, Sen Xing, Muyan Zhong, Qinglong Zhang, Xizhou Zhu, Lewei Lu, et al. Internvl: Scaling up vision foundation models and aligning for generic visual- linguistic tasks. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pp. 24185-24198, 2024j.
- Yinlam Chow, Guy Tennenholtz, Izzeddin Gur, Vincent Zhuang, Bo Dai, Aviral Kumar, Rishabh Agarwal, Sridhar Thiagarajan, Craig Boutilier, and Aleksandra Faust. Inference-aware fine-tuning for best-of-n sampling in large language models. In The Thirteenth International Conference on Learning Representations, 2025. URL https://openreview.net/forum?id=77gQUdQhE7.
- Paul F. Christiano, Jan Leike, Tom B. Brown, Miljan Martic, Shane Legg, and Dario Amodei. Deep reinforcement learning from human preferences. In Proceedings of the 31st International Conference on Neural Information Processing Systems, NIPS'17, pp. 4302-4310, Red Hook, NY, USA, 2017.
- Tianzhe Chu, Yuexiang Zhai, Jihan Yang, Shengbang Tong, Saining Xie, Sergey Levine, and Yi Ma. SFT memorizes, RL generalizes: A comparative study of foundation model post-training. In The Second Conference on Parsimony and Learning (Recent Spotlight Track), 2025a. URL https://openreview. net/forum?id=d3E3LWmTar.
- Marc-Alexandre Côté, Ákos Kádár, Xingdi Yuan, Ben Kybartas, Tavian Barnes, Emery Fine, James Moore, Matthew Hausknecht, Layla El Asri, Mahmoud Adada, Wendy Tay, and Adam Trischler. Textworld: A learning environment for text-based games. In Tristan Cazenave, Abdallah Saffidine, and Nathan Sturtevant (eds.), Computer Games, pp. 41-75, Cham, 2019. Springer International Publishing.
- Ning Dai, Zheng Wu, Renjie Zheng, Ziyun Wei, Wenlei Shi, Xing Jin, Guanlin Liu, Chen Dun, Liang Huang, and Lin Yan. Process supervision-guided policy optimization for code generation, 2025. URL https://openreview.net/forum?id=Cn5Z0MUPZT.
- Nicola Dainese, Matteo Merler, Minttu Alakuijala, and Pekka Marttinen. Generating code world models with large language models guided by monte carlo tree search. In Proceedings of the 38th International Conference on Neural Information Processing Systems, NIPS '24, Red Hook, NY, USA, 2024.
- DeepSeek-AI, Daya Guo, Dejian Yang, Haowei Zhang, Junxiao Song, Ruoyu Zhang, Runxin Xu, Qihao Zhu, Shirong Ma, Peiyi Wang, Xiao Bi, Xiaokang Zhang, Xingkai Yu, Yu Wu, Z. F. Wu, Zhibin Gou, Zhihong Shao, Zhuoshu Li, Ziyi Gao, Aixin Liu, Bing Xue, Bingxuan Wang, Bochao Wu, Bei Feng, Chengda Lu, Chenggang Zhao, Chengqi Deng, Chenyu Zhang, Chong Ruan, Damai Dai, Deli Chen, Dongjie Ji, Erhang Li, Fangyun Lin, Fucong Dai, Fuli Luo, Guangbo Hao, Guanting Chen, Guowei Li, H. Zhang, Han Bao, Hanwei Xu, Haocheng Wang, Honghui Ding, Huajian Xin, Huazuo Gao, Hui Qu, Hui Li, Jianzhong Guo, Jiashi Li, Jiawei Wang, Jingchang Chen, Jingyang Yuan, Junjie Qiu, Junlong Li, J. L. Cai, Jiaqi Ni, Jian Liang, Jin Chen, Kai Dong, Kai Hu, Kaige Gao, Kang Guan, Kexin Huang, Kuai Yu, Lean Wang, Lecong Zhang, Liang Zhao, Litong Wang, Liyue Zhang, Lei Xu, Leyi Xia, Mingchuan Zhang, Minghua Zhang, Minghui Tang, Meng Li, Miaojun Wang, Mingming Li, Ning Tian, Panpan Huang, Peng Zhang, Qiancheng Wang, Qinyu Chen, Qiushi Du, Ruiqi Ge, Ruisong Zhang, Ruizhe Pan, Runji Wang, R. J. Chen, R. L. Jin, Ruyi Chen, Shanghao Lu, Shangyan Zhou, Shanhuang Chen, Shengfeng Ye, Shiyu Wang, Shuiping Yu, Shunfeng Zhou, Shuting Pan, S. S. Li, Shuang Zhou, Shaoqing Wu, Shengfeng Ye, Tao Yun, Tian Pei, Tianyu Sun, T. Wang, Wangding Zeng, Wanjia Zhao, Wen Liu, Wenfeng Liang, Wenjun Gao, Wenqin Yu, Wentao Zhang, W. L. Xiao, Wei An, Xiaodong Liu, Xiaohan Wang, Xiaokang Chen, Xiaotao Nie, Xin Cheng, Xin Liu, Xin Xie, Xingchao Liu, Xinyu Yang, Xinyuan Li, Xuecheng Su, Xuheng Lin, X. Q. Li, Xiangyue Jin, Xiaojin Shen, Xiaosha Chen, Xiaowen Sun, Xiaoxiang Wang, Xinnan Song, Xinyi Zhou, Xianzu Wang, Xinxia Shan, Y. K. Li, Y. Q. Wang, Y. X. Wei, Yang Zhang, Yanhong Xu, Yao Li, Yao Zhao, Yaofeng Sun, Yaohui Wang, Yi Yu, Yichao Zhang, Yifan Shi, Yiliang Xiong, Ying He, Yishi Piao, Yisong Wang, Yixuan Tan, Yiyang Ma, Yiyuan Liu, Yongqiang Guo, Yuan Ou, Yuduan Wang, Yue Gong, Yuheng Zou, Yujia He, Yunfan Xiong, Yuxiang Luo, Yuxiang You, Yuxuan Liu, Yuyang Zhou, Y. X. Zhu, Yanhong Xu, Yanping Huang, Yaohui Li, Yi Zheng, Yuchen Zhu, Yunxian Ma, Ying Tang, Yukun Zha, Yuting Yan, Z. Z. Ren, Zehui Ren, Zhangli Sha, Zhe Fu, Zhean Xu, Zhenda Xie, Zhengyan Zhang, Zhewen Hao, Zhicheng Ma, Zhigang Yan, Zhiyu Wu, Zihui Gu, Zijia Zhu, Zijun Liu, Zilin Li, Ziwei Xie, Ziyang Song, Zizheng Pan, Zhen Huang, Zhipeng Xu, Zhongyu Zhang, and Zhen Zhang. Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning, 2025. URL https://arxiv.org/abs/2501.12948. · arXiv
- Le Deng, Zhonghao Jiang, Jialun Cao, Michael Pradel, and Zhongxin Liu. Nocode-bench: A benchmark for evaluating natural language-driven feature addition, 2025a. URL https://arxiv.org/abs/2507. 18130.
- Yue Deng, Yan Yu, Weiyu Ma, Zirui Wang, Wenhui Zhu, Jian Zhao, and Yin Zhang. Smac-hard: Enabling mixed opponent strategy script and self-play on smac, 2024b. URL https://arxiv.org/abs/2412. 17707.
- Connor Dilgren, Purva Chiniya, Luke Griffith, Yu Ding, and Yizheng Chen. Secrepobench: Benchmarking llms for secure code generation in real-world repositories, 2025. URL https://arxiv.org/abs/2504. 21205.
- Kefan Dong and Tengyu Ma. STP: Self-play LLM theorem provers with iterative conjecturing and proving. In Forty-second International Conference on Machine Learning, 2025. URL https://openreview.net/ forum?id=zWArMedNuW.
- Yuhao Dong, Zuyan Liu, Hai-Long Sun, Jingkang Yang, Winston Hu, Yongming Rao, and Ziwei Liu. Insight- v: Exploring long-chain visual reasoning with multimodal large language models. In Proceedings of the Computer Vision and Pattern Recognition Conference, pp. 9062-9072, 2025d.
- Yuqing Du, Olivia Watkins, Zihan Wang, Cédric Colas, Trevor Darrell, Pieter Abbeel, Abhishek Gupta, and Jacob Andreas. Guiding pretraining in reinforcement learning with large language models. In ICML, pp. 8657-8677, 2023. URL https://proceedings.mlr.press/v202/du23f.html.
- Andrew Estornell, Jean-Francois Ton, Yuanshun Yao, and Yang Liu. ACC-collab: An actor-critic approach to multi-agent LLM collaboration. In The Thirteenth International Conference on Learning Representations, 2025b. URL https://openreview.net/forum?id=nfKfAzkiez.
- Kawin Ethayarajh, Winnie Xu, Niklas Muennighoff, Dan Jurafsky, and Douwe Kiela. Model alignment as prospect theoretic optimization. In Forty-first International Conference on Machine Learning, 2024. URL https://openreview.net/forum?id=iUwHnoENnl.
- Lishui Fan, Yu Zhang, Mouxiang Chen, and Zhongxin Liu. Posterior-grpo: Rewarding reasoning processes in code generation, 2025a. URL https://arxiv.org/abs/2508.05170. · arXiv
- Yuchen Fan, Kaiyan Zhang, Heng Zhou, Yuxin Zuo, Yanxu Chen, Yu Fu, Xinwei Long, Xuekai Zhu, Che Jiang, Yuchen Zhang, Li Kang, Gang Chen, Cheng Huang, Zhizhou He, Bingning Wang, Lei Bai, Ning Ding, and Bowen Zhou. Ssrl: Self-search reinforcement learning, 2025b. URL https://arxiv.org/ abs/2508.10874. · arXiv
- Peiyuan Feng, Yichen He, Guanhua Huang, Yuan Lin, Hanchong Zhang, Yuchen Zhang, and Hang Li. Agile: A novel reinforcement learning framework of llm agents. In A. Globerson, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Advances in Neural Information Processing Systems, volume 37, pp. 5244-5284.
- Curran Associates, Inc., 2024a. URL https://proceedings.neurips.cc/paper_ files/paper/2024/file/097c514162ea7126d40671d23e12f51b-Paper-Conference.pdf.
- Wei Fu, Jiaxuan Gao, Shusheng Xu, Zhiyu Mei, Chen Zhu, Xujie Shen, Chuyi He, Guo Wei, Jun Mei, WANG JIASHU, Tongkai Yang, Binhang Yuan, and Yi Wu. AREAL: A large-scale asynchronous reinforcement learning system for language reasoning. In ES-FoMo III: 3rd Workshop on Efficient Systems for Foundation Models, 2025. URL https://openreview.net/forum?id=qJ0okaW9Z9.
- Yasuhiro Fujita, Prabhat Nagarajan, Toshiki Kataoka, and Takahiro Ishikawa. Chainerrl: A deep reinforcement learning library. Journal of Machine Learning Research, 22(77):1-14, 2021. URL http://jmlr.org/ papers/v22/20-376.html.
- Hongcheng Gao, Yue Liu, Yufei He, Longxu Dou, Chao Du, Zhijie Deng, Bryan Hooi, Min Lin, and Tianyu Pang. Flowreasoner: Reinforcing query-level meta-agents, 2025b. URL https://arxiv.org/abs/ 2504.15257.
- Jonas Gehring, Kunhao Zheng, Jade Copet, Vegard Mella, Taco Cohen, and Gabriel Synnaeve. RLEF: Grounding code LLMs in execution feedback with reinforcement learning. In Forty-second International Conference on Machine Learning, 2025. URL https://openreview.net/forum?id=PzSG5nKe1q.
- Mohammad Gheshlaghi Azar, Zhaohan Daniel Guo, Bilal Piot, Remi Munos, Mark Rowland, Michal Valko, and Daniele Calandriello. A general theoretical paradigm to understand learning from human preferences. In Sanjoy Dasgupta, Stephan Mandt, and Yingzhen Li (eds.), Proceedings of The 27th International Conference on Artificial Intelligence and Statistics, volume 238 of Proceedings of Machine Learning Research, pp. 4447-4455. PMLR, 02-04 May 2024. URL https://proceedings.mlr.press/v238/ gheshlaghi-azar24a.html.
- Zhibin Gou, Zhihong Shao, Yeyun Gong, yelong shen, Yujiu Yang, Nan Duan, and Weizhu Chen. CRITIC: Large language models can self-correct with tool-interactive critiquing. In The Twelfth International Confer- ence on Learning Representations, 2024. URL https://openreview.net/forum?id=Sx038qxjek. Significant Gravitas. AutoGPT: Autonomous gpt-4 agent framework. GitHub, MIT License, 3 2023. URL https://github.com/Significant-Gravitas/AutoGPT. Initial release date.
- Yilin Guan, Qingfeng Lan, Sun Fei, Dujian Ding, Devang Acharya, Chi Wang, William Yang Wang, and Wenyue Hua. Dynamic speculative agent planning, 2025b. URL https://arxiv.org/abs/2509. 01920.
- Daya Guo, Dejian Yang, Haowei Zhang, Junxiao Song, Peiyi Wang, Qihao Zhu, Runxin Xu, Ruoyu Zhang, Shirong Ma, Xiao Bi, et al. Deepseek-r1 incentivizes reasoning in llms through reinforcement learning. Nature, 645(8081):633-638, 2025a.
- Yiduo Guo, Zhen Guo, Chuanwei Huang, Zi-Ang Wang, Zekai Zhang, Haofei Yu, Huishuai Zhang, and Yikang Shen. Synthetic data rl: Task definition is all you need, 2025b. URL https://arxiv.org/abs/2505. 17063.
- Zichuan Guo and Hao Wang. A survey of reinforcement learning in large language models: From data generation to test-time inference. Available at SSRN 5128927, 2025. URL https://papers.ssrn.com/ sol3/papers.cfm?abstract_id=5128927.
- Tanmay Gupta and Aniruddha Kembhavi. Visual programming: Compositional visual reasoning without training. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pp. 14953-14962, 2023.
- Bernal Jiménez Gutiérrez, Yiheng Shu, Yu Gu, Michihiro Yasunaga, and Yu Su. Hipporag: Neurobiologically inspired long-term memory for large language models. In A. Globerson, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Advances in Neural Information Processing Systems, volume 37, pp. 59532-59569.
- Curran Associates, Inc., 2024. URL https://proceedings.neurips.cc/paper_ files/paper/2024/file/6ddc001d07ca4f319af96a3024f6dbd1-Paper-Conference.pdf.
- Danijar Hafner. Benchmarking the spectrum of agent capabilities. In International Conference on Learning Representations, 2022. URL https://openreview.net/forum?id=1W0z96MFEoH.
- Bingguang Hao, Maolin Wang, Zengzhuang Xu, Yicheng Chen, Cunyin Peng, Jinjie GU, and Chenyi Zhuang. Exploring superior function calls via reinforcement learning, 2025a. URL https://arxiv.org/abs/ 2508.05118.
- Shibo Hao, Sainbayar Sukhbaatar, DiJia Su, Xian Li, Zhiting Hu, Jason Weston, and Yuandong Tian. Training large language models to reason in a continuous latent space, 2024. URL https://arxiv.org/ abs/2412.06769. · arXiv
- Sirui Hong, Mingchen Zhuge, Jonathan Chen, Xiawu Zheng, Yuheng Cheng, Jinlin Wang, Ceyao Zhang, Zili Wang, Steven Ka Shing Yau, Zijuan Lin, Liyang Zhou, Chenyu Ran, Lingfeng Xiao, Chenglin Wu, and Jürgen Schmidhuber. MetaGPT: Meta programming for a multi-agent collaborative framework. In The Twelfth International Conference on Learning Representations, 2024b. URL https://openreview. net/forum?id=VtmBAGCN7o.
- Yining Hong, Haoyu Zhen, Peihao Chen, Shuhong Zheng, Yilun Du, Zhenfang Chen, and Chuang Gan. 3d-llm: Injecting the 3d world into large language models. Advances in Neural Information Processing Systems, 36:20482-20494, 2023.
- Jack Hopkins, Mart Bakler, and Akbir Khan. Factorio learning environment, 2025. URL https://arxiv. org/abs/2503.09617.
- Bairu Hou, Yang Zhang, Jiabao Ji, Yujian Liu, Kaizhi Qian, Jacob Andreas, and Shiyu Chang. Thinkprune: Pruning long chain-of-thought of llms via reinforcement learning, 2025. URL https://arxiv.org/ abs/2504.01296. · arXiv
- Shengran Hu, Cong Lu, and Jeff Clune. Automated design of agentic systems. In The Thirteenth Interna- tional Conference on Learning Representations, 2025d. URL https://openreview.net/forum?id= t9U3LW7JVX.
- Arnav Kumar Jain, Gonzalo Gonzalez-Pumariega, Wayne Chen, Alexander M Rush, Wenting Zhao, and Sanjiban Choudhury. Multi-turn code generation through single-step rewards. In Forty-second International Conference on Machine Learning, 2025a. URL https://openreview.net/forum?id=aJeLhLcsh0.
- Naman Jain, King Han, Alex Gu, Wen-Ding Li, Fanjia Yan, Tianjun Zhang, Sida Wang, Armando Solar- Lezama, Koushik Sen, and Ion Stoica. Livecodebench: Holistic and contamination free evaluation of large language models for code. In The Thirteenth International Conference on Learning Representations, 2025b. URL https://openreview.net/forum?id=chfJJYC3iL.
- Naman Jain, Jaskirat Singh, Manish Shetty, Tianjun Zhang, Liang Zheng, Koushik Sen, and Ion Stoica. R2e- gym: Procedural environment generation and hybrid verifiers for scaling open-weights SWE agents. In Second Conference on Language Modeling, 2025c. URL https://openreview.net/forum?id=7evvwwdo3z.
- Nan Jiang, Xiaopeng Li, Shiqi Wang, Qiang Zhou, Soneya Binta Hossain, Baishakhi Ray, Varun Kumar, Xiaofei Ma, and Anoop Deoras. Ledex: Training llms to better self-debug and explain code. In A. Globerson, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Advances in Neural Information Processing Systems, volume 37, pp. 35517-35543.
- Curran Asso- ciates, Inc., 2024. URL https://proceedings.neurips.cc/paper_files/paper/2024/file/ 3ea832724870c700f0a03c665572e2a9-Paper-Conference.pdf.
- Carlos E Jimenez, John Yang, Alexander Wettig, Shunyu Yao, Kexin Pei, Ofir Press, and Karthik R Narasimhan. SWE-bench: Can language models resolve real-world github issues? In The Twelfth International Conference on Learning Representations, 2024. URL https://openreview.net/forum? id=VTF8yNQM66.
- Zixuan Ke, Fangkai Jiao, Yifei Ming, Xuan-Phi Nguyen, Austin Xu, Do Xuan Long, Minzhi Li, Chengwei Qin, PeiFeng Wang, silvio savarese, Caiming Xiong, and Shafiq Joty. A survey of frontiers in LLM reasoning: Inference scaling, learning to reason, and agentic systems. Transactions on Machine Learning Research, 2025. ISSN 2835-8856. URL https://openreview.net/forum?id=SlsZZ25InC. Survey Certification.
- Jing Yu Koh, Robert Lo, Lawrence Jang, Vikram Duvvur, Ming Lim, Po-Yu Huang, Graham Neubig, Shuyan Zhou, Russ Salakhutdinov, and Daniel Fried. Visualwebarena: Evaluating multimodal agents on realistic visual web tasks. In Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pp. 881-905, 2024.
- Mukund Khanna Kunal Singh, Shreyas Singh. Trishul: A training-free agentic framework for zero-shot gui action grounding, 2025. URL https://arxiv.org/abs/2502.08226. · arXiv
- Hung Le, Yue Wang, Akhilesh Deepak Gotmare, Silvio Savarese, and Steven Chu Hong Hoi. Coderl: Mastering code generation through pretrained models and deep reinforcement learn- ing. In S. Koyejo, S. Mohamed, A. Agarwal, D. Belgrave, K. Cho, and A. Oh (eds.), Ad- vances in Neural Information Processing Systems, volume 35, pp. 21314-21328.
- Curran Asso- ciates, Inc., 2022. URL https://proceedings.neurips.cc/paper_files/paper/2022/file/ 8636419dea1aa9fbd25fc4248e702da4-Paper-Conference.pdf.
- Bowen Li, Wenhan Wu, Ziwei Tang, Lin Shi, John Yang, Jinyang Li, Shunyu Yao, Chen Qian, Binyuan Hui, Qicheng Zhang, Zhiyin Yu, He Du, Ping Yang, Dahua Lin, Chao Peng, and Kai Chen. Prompting large language models to tackle the full software development lifecycle: A case study. In Owen Rambow, Leo Wanner, Marianna Apidianaki, Hend Al-Khalifa, Barbara Di Eugenio, and Steven Schockaert (eds.), Proceedings of the 31st International Conference on Computational Linguistics, pp. 7511-7531, Abu Dhabi, UAE, January 2025a. Association for Computational Linguistics. URL https://aclanthology.org/ 2025.coling-main.502/.
- Geng Li, Jinglin Xu, Yunzhen Zhao, and Yuxin Peng. Dyfo: A training-free dynamic focus visual search for enhancing lmms in fine-grained visual understanding. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), pp. 9098-9108, June 2025e.
- Guohao Li, Hasan Hammoud, Hani Itani, Dmitrii Khizbullin, and Bernard Ghanem. Camel: Communicative agents for" mind" exploration of large language model society. Advances in Neural Information Processing Systems, 36:51991-52008, 2023a. URL https://openreview.net/forum?id=3IyL2XWDkG.
- Xiaoxi Li, Guanting Dong, Jiajie Jin, Yuyao Zhang, Yujia Zhou, Yutao Zhu, Peitian Zhang, and Zhicheng Dou. Search-o1: Agentic search-enhanced large reasoning models, 2025i. URL https://arxiv.org/ abs/2501.05366. · arXiv
- Xinzhe Li. A review of prominent paradigms for LLM-based agents: Tool use, planning (including RAG), and feedback learning. In Owen Rambow, Leo Wanner, Marianna Apidianaki, Hend Al-Khalifa, Barbara Di Eugenio, and Steven Schockaert (eds.), Proceedings of the 31st International Conference on Computational Linguistics, pp. 9760-9779, Abu Dhabi, UAE, January 2025. Association for Computational Linguistics. URL https://aclanthology.org/2025.coling-main.652/.
- Xuefeng Li, Haoyang Zou, and Pengfei Liu. Torl: Scaling tool-integrated rl, 2025l. URL https://arxiv. org/abs/2503.23383.
- Zhong-Zhi Li, Duzhen Zhang, Ming-Liang Zhang, Jiaxin Zhang, Zengyan Liu, Yuxuan Yao, Haotian Xu, Junhao Zheng, Pei-Jie Wang, Xiuyi Chen, Yingying Zhang, Fei Yin, Jiahua Dong, Zhiwei Li, Bao-Long Bi, Ling-Rui Mei, Junfeng Fang, Xiao Liang, Zhijiang Guo, Le Song, and Cheng-Lin Liu. From system 1 to system 2: A survey of reasoning large language models, 2025r. URL https://arxiv.org/abs/2502. 17419.
- Eric Liang, Richard Liaw, Robert Nishihara, Philipp Moritz, Roy Fox, Ken Goldberg, Joseph Gonzalez, Michael Jordan, and Ion Stoica. RLlib: Abstractions for distributed reinforcement learning. In Jennifer Dy and Andreas Krause (eds.), Proceedings of the 35th International Conference on Machine Learning, volume 80 of Proceedings of Machine Learning Research, pp. 3053-3062. PMLR, 10-15 Jul 2018. URL https://proceedings.mlr.press/v80/liang18b.html.
- Xiao Liang, Zhongzhi Li, Yeyun Gong, Yelong Shen, Ying Nian Wu, Zhijiang Guo, and Weizhu Chen. Beyond pass@1: Self-play with variational problem synthesis sustains rlvr, 2025b. URL https://arxiv.org/ abs/2508.14029. · arXiv
- Shalev Lifshitz, Sheila A. McIlraith, and Yilun Du. Multi-agent verification: Scaling test-time compute with goal verifiers. In ICLR 2025 Workshop on Modularity for Collaborative, Decentralized, and Continual Deep Learning, 2025. URL https://openreview.net/forum?id=mGAAoEWOq9.
- Hunter Lightman, Vineet Kosaraju, Yura Burda, Harri Edwards, Bowen Baker, Teddy Lee, Jan Leike, John Schulman, Ilya Sutskever, and Karl Cobbe. Let's verify step by step, 2023. URL https://arxiv.org/ abs/2305.20050. · arXiv
- Haohan Lin, Zhiqing Sun, Sean Welleck, and Yiming Yang. Lean-STar: Learning to interleave thinking and proving. In The Thirteenth International Conference on Learning Representations, 2025a. URL https://openreview.net/forum?id=SOWZ59UyNc.
- Heng Lin and Zhongwen Xu. Understanding tool-integrated reasoning, 2025. URL https://arxiv.org/ abs/2508.19201. · arXiv
- Bo Liu, Leon Guertler, Simon Yu, Zichen Liu, Penghui Qi, Daniel Balcells, Mickel Liu, Cheston Tan, Weiyan Shi, Min Lin, Wee Sun Lee, and Natasha Jaques. Spiral: Self-play on zero-sum games incentivizes reasoning via multi-agent multi-turn reinforcement learning, 2025b. URL https://arxiv.org/abs/ 2506.24119.
- Haotian Liu, Chunyuan Li, Qingyang Wu, and Yong Jae Lee. Visual instruction tuning. Advances in neural information processing systems, 36:34892-34916, 2023a.
- Jiate Liu, Yiqin Zhu, Kaiwen Xiao, QIANG FU, Xiao Han, Yang Wei, and Deheng Ye. RLTF: Reinforcement learning from unit test feedback. Transactions on Machine Learning Research, 2023b. ISSN 2835-8856. URL https://openreview.net/forum?id=hjYmsV6nXZ.
- Jiawei Liu, Thanh Nguyen, Mingyue Shang, Hantian Ding, Xiaopeng Li, Yu Yu, Varun Kumar, and Zijian Wang. Learning code preference via synthetic evolution, 2024a. URL https://arxiv.org/abs/2410. 03837.
- Xiao Liu, Hao Yu, Hanchen Zhang, Yifan Xu, Xuanyu Lei, Hanyu Lai, Yu Gu, Hangliang Ding, Kaiwen Men, Kejuan Yang, Shudan Zhang, Xiang Deng, Aohan Zeng, Zhengxiao Du, Chenhui Zhang, Sheng Shen, Tianjun Zhang, Yu Su, Huan Sun, Minlie Huang, Yuxiao Dong, and Jie Tang. Agentbench: Evaluating llms as agents. In ICLR, 2024b. URL https://openreview.net/forum?id=zAdUB0aCTQ.
- Yuhang Liu, Pengxiang Li, Zishu Wei, Congkai Xie, Xueyu Hu, Xinchen Xu, Shengyu Zhang, Xiaotian Han, Hongxia Yang, and Fei Wu. InfiGUIAgent: A multimodal generalist GUI agent with native reasoning and reflection. In ICML 2025 Workshop on Computer Use Agents, 2025n. URL https: //openreview.net/forum?id=p0h9XJ7fMH.
- Zexi Liu, Jingyi Chai, Xinyu Zhu, Shuo Tang, Rui Ye, Bo Zhang, Lei Bai, and Siheng Chen. Ml-agent: Reinforcing llm agents for autonomous machine learning engineering, 2025q. URL https://arxiv.org/ abs/2505.23723. · arXiv
- Jiarui Lu, Thomas Holleis, Yizhe Zhang, Bernhard Aumayer, Feng Nan, Felix Bai, Shuang Ma, Shen Ma, Mengyu Li, Guoli Yin, Zirui Wang, and Ruoming Pang. Toolsandbox: A stateful, conversational, interactive evaluation benchmark for llm tool use capabilities, 2025b. URL https://arxiv.org/abs/ 2408.04682.
- Keer Lu, Chong Chen, Bin Cui, Huang Leng, and Wentao Zhang. Pilotrl: Training language model agents via global planning-guided progressive reinforcement learning, 2025c. URL https://arxiv.org/abs/ 2508.00344.
- Taiming Lu, Lingfeng Shen, Xinyu Yang, Weiting Tan, Beidi Chen, and Huaxiu Yao. It takes two: On the seamlessness between reward and policy model in rlhf, 2024. URL https://arxiv.org/abs/2406. 07971.
- Aman Madaan, Niket Tandon, Prakhar Gupta, Skyler Hallinan, Luyu Gao, Sarah Wiegreffe, Uri Alon, Nouha Dziri, Shrimai Prabhumoye, Yiming Yang, Shashank Gupta, Bodhisattwa Prasad Majumder, Katherine Hermann, Sean Welleck, Amir Yazdanbakhsh, and Peter Clark. Self-refine: Iterative refine- ment with self-feedback. In A. Oh, T. Naumann, A. Globerson, K. Saenko, M. Hardt, and S. Levine (eds.), Advances in Neural Information Processing Systems, volume 36, pp. 46534-46594.
- Curran Asso- ciates, Inc., 2023. URL https://proceedings.neurips.cc/paper_files/paper/2023/file/ 91edff07232fb1b55a505a9e9f6c0ff3-Paper-Conference.pdf.
- Adyasha Maharana, Dong-Ho Lee, Sergey Tulyakov, Mohit Bansal, Francesco Barbieri, and Yuwei Fang. Evaluating very long-term conversational memory of llm agents, 2024. URL https://arxiv.org/abs/ 2402.17753.
- Junhua Mao, Jonathan Huang, Alexander Toshev, Oana Camburu, Alan L Yuille, and Kevin Murphy. Generation and comprehension of unambiguous object descriptions. In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 11-20, 2016.
- Michael Matthews, Michael Beukman, Benjamin Ellis, Mikayel Samvelyan, Matthew Thomas Jackson, Samuel Coward, and Jakob Nicolaus Foerster. Craftax: A lightning-fast benchmark for open-ended reinforcement learning. In Forty-first International Conference on Machine Learning, 2024. URL https: //openreview.net/forum?id=hg4wXlrQCV.
- Fanqing Meng, Lingxiao Du, Zongkai Liu, Zhixiang Zhou, Quanfeng Lu, Daocheng Fu, Botian Shi, Wenhai Wang, Junjun He, Kaipeng Zhang, et al. Mm-eureka: Exploring visual aha moment with rule-based large-scale reinforcement learning. CoRR, 2025.
- Yu Meng, Mengzhou Xia, and Danqi Chen. SimPO: Simple preference optimization with a reference-free reward. In The Thirty-eighth Annual Conference on Neural Information Processing Systems, 2024. URL https://openreview.net/forum?id=3Tzcot1LKb.
- Grégoire Mialon, Clémentine Fourrier, Thomas Wolf, Yann LeCun, and Thomas Scialom. GAIA: a benchmark for general AI assistants. In The Twelfth International Conference on Learning Representations, 2024. URL https://openreview.net/forum?id=fibxvahvs3.
- Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Alex Graves, Ioannis Antonoglou, Daan Wierstra, and Martin Riedmiller. Playing atari with deep reinforcement learning, 2013. URL https://arxiv.org/ abs/1312.5602. · arXiv
- Zhun Mou, Bin Xia, Zhengchao Huang, Wenming Yang, and Jiaya Jia. Gradeo: Towards human-like evaluation for text-to-video generation via multi-step reasoning, 2025. URL https://arxiv.org/abs/ 2503.02341.
- Varun K Nagaraja, Vlad I Morariu, and Larry S Davis. Modeling context between objects for referring expression understanding. In European Conference on Computer Vision, pp. 792-807. Springer, 2016.
- Allen Newell, John Calman Shaw, and Herbert A Simon. Elements of a theory of human problem solving. Psychological review, 65(3):151, 1958.
- OpenAI, :, Aaron Jaech, Adam Kalai, Adam Lerer, Adam Richardson, Ahmed El-Kishky, Aiden Low, Alec Helyar, Aleksander Madry, Alex Beutel, Alex Carney, Alex Iftimie, Alex Karpenko, Alex Tachard Passos, Alexander Neitz, Alexander Prokofiev, Alexander Wei, Allison Tam, Ally Bennett, Ananya Kumar, Andre Saraiva, Andrea Vallone, Andrew Duberstein, Andrew Kondrich, Andrey Mishchenko, Andy Applebaum, Angela Jiang, Ashvin Nair, Barret Zoph, Behrooz Ghorbani, Ben Rossen, Benjamin Sokolowsky, Boaz Barak, Bob McGrew, Borys Minaiev, Botao Hao, Bowen Baker, Brandon Houghton, Brandon McKinzie, Brydon Eastman, Camillo Lugaresi, Cary Bassin, Cary Hudson, Chak Ming Li, Charles de Bourcy, Chelsea Voss, Chen Shen, Chong Zhang, Chris Koch, Chris Orsinger, Christopher Hesse, Claudia Fischer, Clive Chan, Dan Roberts, Daniel Kappler, Daniel Levy, Daniel Selsam, David Dohan, David Farhi, David Mely, David Robinson, Dimitris Tsipras, Doug Li, Dragos Oprica, Eben Freeman, Eddie Zhang, Edmund Wong, Elizabeth Proehl, Enoch Cheung, Eric Mitchell, Eric Wallace, Erik Ritter, Evan Mays, Fan Wang, Felipe Petroski Such, Filippo Raso, Florencia Leoni, Foivos Tsimpourlas, Francis Song, Fred von Lohmann, Freddie Sulit, Geoff Salmon, Giambattista Parascandolo, Gildas Chabot, Grace Zhao, Greg Brockman, Guillaume Leclerc, Hadi Salman, Haiming Bao, Hao Sheng, Hart Andrin, Hessam Bagherinezhad, Hongyu Ren, Hunter Lightman, Hyung Won Chung, Ian Kivlichan, Ian O'Connell, Ian Osband, Ignasi Clavera Gilaberte, Ilge Akkaya, Ilya Kostrikov, Ilya Sutskever, Irina Kofman, Jakub Pachocki, James Lennon, Jason Wei, Jean Harb, Jerry Twore, Jiacheng Feng, Jiahui Yu, Jiayi Weng, Jie Tang, Jieqi Yu, Joaquin Quiñonero Candela, Joe Palermo, Joel Parish, Johannes Heidecke, John Hallman, John Rizzo, Jonathan Gordon, Jonathan Uesato, Jonathan Ward, Joost Huizinga, Julie Wang, Kai Chen, Kai Xiao, Karan Singhal, Karina Nguyen, Karl Cobbe, Katy Shi, Kayla Wood, Kendra Rimbach, Keren Gu-Lemberg, Kevin Liu, Kevin Lu, Kevin Stone, Kevin Yu, Lama Ahmad, Lauren Yang, Leo Liu, Leon Maksin, Leyton Ho, Liam Fedus, Lilian Weng, Linden Li, Lindsay McCallum, Lindsey Held, Lorenz Kuhn, Lukas Kondraciuk, Lukasz Kaiser, Luke Metz, Madelaine Boyd, Maja Trebacz, Manas Joglekar, Mark Chen, Marko Tintor, Mason Meyer, Matt Jones, Matt Kaufer, Max Schwarzer, Meghan Shah, Mehmet Yatbaz, Melody Y. Guan, Mengyuan Xu, Mengyuan Yan, Mia Glaese, Mianna Chen, Michael Lampe, Michael Malek, Michele Wang, Michelle Fradin, Mike McClay, Mikhail Pavlov, Miles Wang, Mingxuan Wang, Mira Murati, Mo Bavarian, Mostafa Rohaninejad, Nat McAleese, Neil Chowdhury, Neil Chowdhury, Nick Ryder, Nikolas Tezak, Noam Brown, Ofir Nachum, Oleg Boiko, Oleg Murk, Olivia Watkins, Patrick Chao, Paul Ashbourne, Pavel Izmailov, Peter Zhokhov, Rachel Dias, Rahul Arora, Randall Lin, Rapha Gontijo Lopes, Raz Gaon, Reah Miyara, Reimar Leike, Renny Hwang, Rhythm Garg, Robin Brown, Roshan James, Rui Shu, Ryan Cheu, Ryan Greene, Saachi Jain, Sam Altman, Sam Toizer, Sam Toyer, Samuel Miserendino, Sandhini Agarwal, Santiago Hernandez, Sasha Baker, Scott McKinney, Scottie Yan, Shengjia Zhao, Shengli Hu, Shibani Santurkar, Shraman Ray Chaudhuri, Shuyuan Zhang, Siyuan Fu, Spencer Papay, Steph Lin, Suchir Balaji, Suvansh Sanjeev, Szymon Sidor, Tal Broda, Aidan Clark, Tao Wang, Taylor Gordon, Ted Sanders, Tejal Patwardhan, Thibault Sottiaux, Thomas Degry, Thomas Dimson, Tianhao Zheng, Timur Garipov, Tom Stasi, Trapit Bansal, Trevor Creech, Troy Peterson, Tyna Eloundou, Valerie Qi, Vineet Kosaraju, Vinnie Monaco, Vitchyr Pong, Vlad Fomenko, Weiyi Zheng, Wenda Zhou, Wes McCabe, Wojciech Zaremba, Yann Dubois, Yinghai Lu, Yining Chen, Young Cha, Yu Bai, Yuchen He, Yuchen Zhang, Yunyun Wang, Zheng Shao, and Zhuohan Li. Openai o1 system card, 2024. URL https://arxiv.org/abs/2412.16720. · arXiv
- Long Ouyang, Jeffrey Wu, Xu Jiang, Diogo Almeida, Carroll Wainwright, Pamela Mishkin, Chong Zhang, Sandhini Agarwal, Katarina Slama, Alex Ray, John Schulman, Jacob Hilton, Fraser Kelton, Luke Miller, Maddie Simens, Amanda Askell, Peter Welinder, Paul F Christiano, Jan Leike, and Ryan Lowe. Training language models to follow instructions with human feedback. In S. Koyejo, S. Mohamed, A. Agarwal, D. Belgrave, K. Cho, and A. Oh (eds.), Advances in Neural Information Processing Systems, volume 35, pp. 27730-27744.
- Curran Associates, Inc., 2022. URL https://proceedings.neurips.cc/paper_ files/paper/2022/file/b1efde53be364a73914f58805a001731-Paper-Conference.pdf.
- Richard Yuanzhe Pang, Weizhe Yuan, Kyunghyun Cho, He He, Sainbayar Sukhbaatar, and Jason Weston. Iterative reasoning preference optimization. In A. Globerson, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Advances in Neural Information Processing Systems, volume 37, pp. 116617-116637.
- Curran Associates, Inc., 2024. URL https://proceedings.neurips.cc/paper_ files/paper/2024/file/d37c9ad425fe5b65304d500c6edcba00-Paper-Conference.pdf.
- Eduardo Pignatelli, Johan Ferret, Matthieu Geist, Thomas Mesnard, Hado van Hasselt, and Laura Toni. A survey of temporal credit assignment in deep reinforcement learning. Transactions on Machine Learning Research, 2024. ISSN 2835-8856. URL https://openreview.net/forum?id=bNtr6SLgZf. Survey Certification.
- Gabriel Poesia, David Broman, Nick Haber, and Noah Goodman. Learning formal mathematics from intrinsic motivation. In The Thirty-eighth Annual Conference on Neural Information Processing Systems, 2024. URL https://openreview.net/forum?id=uNKlTQ8mBD.
- Shuofei Qiao, Zhisong Qiu, Baochang Ren, Xiaobin Wang, Xiangyuan Ru, Ningyu Zhang, Xiang Chen, Yong Jiang, Pengjun Xie, Fei Huang, and Huajun Chen. Agentic knowledgeable self-awareness. In Workshop on Reasoning and Planning for Large Language Models, 2025. URL https://openreview.net/forum? id=PGdSLjYwMT.
- In A. Oh, T. Naumann, A. Globerson, K. Saenko, M. Hardt, and S. Levine (eds.), Ad- vances in Neural Information Processing Systems, volume 36, pp. 53728-53741.
- Curran Asso- ciates, Inc., 2023. URL https://proceedings.neurips.cc/paper_files/paper/2023/file/ a85b405ed65c6477a4fe8302b5e06ce7-Paper-Conference.pdf.
- Antonin Raffin, Ashley Hill, Adam Gleave, Anssi Kanervisto, Maximilian Ernestus, and Noah Dormann. Stable-baselines3: Reliable reinforcement learning implementations. Journal of Machine Learning Research, 22(268):1-8, 2021. URL http://jmlr.org/papers/v22/20-1364.html.
- Christopher Rawles, Sarah Clinckemaillie, Yifan Chang, Jonathan Waltz, Gabrielle Lau, Marybeth Fair, Alice Li, William E Bishop, Wei Li, Folawiyo Campbell-Ajala, Daniel Kenji Toyama, Robert James Berry, Divya Tyamagundlu, Timothy P Lillicrap, and Oriana Riva. Androidworld: A dynamic benchmarking environment for autonomous agents. In The Thirteenth International Conference on Learning Representations, 2025. URL https://openreview.net/forum?id=il5yUQsrjC.
- Yangjun Ruan, Honghua Dong, Andrew Wang, Silviu Pitis, Yongchao Zhou, Jimmy Ba, Yann Dubois, Chris J. Maddison, and Tatsunori Hashimoto. Identifying the risks of LM agents with an LM-emulated sandbox. In The Twelfth International Conference on Learning Representations, 2024. URL https: //openreview.net/forum?id=GEcwtMk1uA.
- Mikayel Samvelyan, Tabish Rashid, Christian Schroeder de Witt, Gregory Farquhar, Nantas Nardelli, Tim G. J. Rudner, Chia-Man Hung, Philip H. S. Torr, Jakob Foerster, and Shimon Whiteson. The starcraft multi- agent challenge. In Proceedings of the 18th International Conference on Autonomous Agents and MultiAgent Systems, AAMAS '19, pp. 2186-2188, Richland, SC, 2019. International Foundation for Autonomous Agents and Multiagent Systems. ISBN 9781450363099.
- Shibani Santurkar, Esin Durmus, Faisal Ladhak, Cinoo Lee, Percy Liang, and Tatsunori Hashimoto. Whose opinions do language models reflect? In Proceedings of the 40th International Conference on Machine Learning, ICML'23. JMLR.org, 2023.
- Timo Schick, Jane Dwivedi-Yu, Roberto Dessi, Roberta Raileanu, Maria Lomeli, Eric Hambro, Luke Zettlemoyer, Nicola Cancedda, and Thomas Scialom. Toolformer: Language models can teach them- selves to use tools. In A. Oh, T. Naumann, A. Globerson, K. Saenko, M. Hardt, and S. Levine (eds.), Advances in Neural Information Processing Systems, volume 36, pp. 68539-68551.
- Curran Asso- ciates, Inc., 2023. URL https://proceedings.neurips.cc/paper_files/paper/2023/file/ d842425e4bf79ba039352da0f658a906-Paper-Conference.pdf.
- Yu Shang, Yu Li, Keyu Zhao, Likai Ma, Jiahe Liu, Fengli Xu, and Yong Li. Agentsquare: Automatic LLM agent search in modular design space. In The Thirteenth International Conference on Learning Representations, 2025b. URL https://openreview.net/forum?id=mPdmDYIQ7f.
- Hao Shao, Shengju Qian, Han Xiao, Guanglu Song, Zhuofan Zong, Letian Wang, Yu Liu, and Hongsheng Li. Visual cot: Advancing multi-modal language models with a comprehensive dataset and benchmark for chain-of-thought reasoning. Advances in Neural Information Processing Systems, 37:8612-8642, 2024a.
- Maohao Shen, Guangtao Zeng, Zhenting Qi, Zhang-Wei Hong, Zhenfang Chen, Wei Lu, Gregory W. Wornell, Subhro Das, David Daniel Cox, and Chuang Gan. Satori: Reinforcement learning with chain-of-action- thought enhances LLM reasoning via autoregressive search. In Forty-second International Conference on Machine Learning, 2025b. URL https://openreview.net/forum?id=j4FXxMiDjL.
- Noah Shinn, Federico Cassano, Ashwin Gopinath, Karthik Narasimhan, and Shunyu Yao. Reflexion: language agents with verbal reinforcement learning. In A. Oh, T. Naumann, A. Globerson, K. Saenko, M. Hardt, and S. Levine (eds.), Advances in Neural Information Processing Systems, volume 36, pp. 8634-8652.
- Curran Associates, Inc., 2023. URL https://proceedings.neurips.cc/paper_files/paper/ 2023/file/1b44b878bb782e6954cd888628510e90-Paper-Conference.pdf.
- Mohit Shridhar, Xingdi Yuan, Marc-Alexandre Cote, Yonatan Bisk, Adam Trischler, and Matthew Hausknecht. Alfworld: Aligning text and embodied environments for interactive learning. In International Conference on Learning Representations, 2021. URL https://openreview.net/forum?id=0IOX0YcCdTn.
- Yawar Siddiqui, Antonio Alliegro, Alexey Artemov, Tatiana Tommasi, Daniele Sirigatti, Vladislav Rosov, Angela Dai, and Matthias Nießner. Meshgpt: Generating triangle meshes with decoder-only transformers. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pp. 19615-19625, 2024.
- Yifan Song, Weimin Xiong, Xiutian Zhao, Dawei Zhu, Wenhao Wu, Ke Wang, Cheng Li, Wei Peng, and Sujian Li. Agentbank: Towards generalized llm agents via fine-tuning on 50000+ interaction trajectories. In EMNLP (Findings), pp. 2124-2141, 2024a. URL https://aclanthology.org/2024.findings-emnlp.116.
- Giulio Starace, Oliver Jaffe, Dane Sherburn, James Aung, Jun Shern Chan, Leon Maksin, Rachel Dias, Evan Mays, Benjamin Kinsella, Wyatt Thompson, Johannes Heidecke, Amelia Glaese, and Tejal Patwardhan. Paperbench: Evaluating AI's ability to replicate AI research. In Forty-second International Conference on Machine Learning, 2025. URL https://openreview.net/forum?id=xF5PuTLPbn.
- Alex Su, Haozhe Wang, Weiming Ren, Fangzhen Lin, and Wenhu Chen. Pixel reasoner: Incentivizing pixel-space reasoning with curiosity-driven reinforcement learning, 2025a. URL https://arxiv.org/ abs/2505.15966. · arXiv
- Shuang Sun, Huatong Song, Yuhao Wang, Ruiyang Ren, Jinhao Jiang, Junjie Zhang, Fei Bai, Jia Deng, Wayne Xin Zhao, Zheng Liu, Lei Fang, Zhongyuan Wang, and Ji-Rong Wen. Simpledeepsearcher: Deep information seeking via web-powered reasoning trajectory synthesis, 2025b. URL https://arxiv.org/ abs/2505.16834. · arXiv
- Gokul Swamy, Christoph Dann, Rahul Kidambi, Zhiwei Steven Wu, and Alekh Agarwal. A minimaximalist approach to reinforcement learning from human feedback, 2024. URL https://arxiv.org/abs/2401. 04056.
- Marton Szep, Daniel Rueckert, Rüdiger von Eisenhart-Rothe, and Florian Hinterwimmer. Fine-tuning large language models with limited data: A survey and practical guide, 2025. URL https://arxiv.org/ abs/2411.09539. · arXiv
- Huajie Tan, Yuheng Ji, Xiaoshuai Hao, Minglan Lin, Pengwei Wang, Zhongyuan Wang, and Shanghang Zhang. Reason-rft: Reinforcement fine-tuning for visual reasoning. arXiv preprint arXiv:2503.20752, 2025a. · arXiv
- Hao Tang, Darren Key, and Kevin Ellis. Worldcoder, a model-based llm agent: building world models by writing code and interacting with the environment. In Proceedings of the 38th International Conference on Neural Information Processing Systems, NIPS '24, Red Hook, NY, USA, 2024.
- Ye Tian, Baolin Peng, Linfeng Song, Lifeng Jin, Dian Yu, Lei Han, Haitao Mi, and Dong Yu. Toward self-improvement of llms via imagination, searching, and criticizing. In A. Glober- son, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Ad- vances in Neural Information Processing Systems, volume 37, pp. 52723-52748.
- Curran Asso- ciates, Inc., 2024. URL https://proceedings.neurips.cc/paper_files/paper/2024/file/ 5e5853f35164e434015716a8c2a66543-Paper-Conference.pdf.
- Dheeraj Vattikonda, Santhoshi Ravichandran, Emiliano Penaloza, Hadi Nekoei, Megh Thakkar, Thibault Le Sellier de Chezelles, Nicolas Gontier, Miguel Muñoz-Mármol, Sahar Omidi Shayegan, Stefania Raimondo, Xue Liu, Alexandre Drouin, Laurent Charlin, Alexandre Piché, Alexandre Lacoste, and Massimo Caccia. How to train your llm web agent: A statistical diagnosis, 2025. URL https://arxiv.org/abs/2507. 04103.
- Fanqi Wan, Deng Cai, Shijue Huang, Xiaojun Quan, and Mingxuan Wang. Let large language models find the data to train themselves, 2025a. URL https://openreview.net/forum?id=5YCZZSEosw.
- Chaoqi Wang, Yibo Jiang, Chenghao Yang, Han Liu, and Yuxin Chen. Beyond reverse kl: Generalizing direct preference optimization with diverse divergence constraints, 2023a. URL https://arxiv.org/ abs/2309.16240. · arXiv
- Dequan Wang, Evan Shelhamer, Shaoteng Liu, Bruno Olshausen, and Trevor Darrell. Tent: Fully test-time adaptation by entropy minimization. In International Conference on Learning Representations, 2021. URL https://openreview.net/forum?id=uXl3bZLkr3c.
- Guanzhi Wang, Yuqi Xie, Yunfan Jiang, Ajay Mandlekar, Chaowei Xiao, Yuke Zhu, Linxi Fan, and Anima Anandkumar. Voyager: An open-ended embodied agent with large language models. Transactions on Machine Learning Research, 2024a. ISSN 2835-8856. URL https://openreview.net/forum?id= ehfRiF0R3a.
- Haoming Wang, Haoyang Zou, Huatong Song, Jiazhan Feng, Junjie Fang, Junting Lu, Longxiang Liu, Qinyu Luo, Shihao Liang, Shijue Huang, Wanjun Zhong, Yining Ye, Yujia Qin, Yuwen Xiong, Yuxin Song, Zhiyong Wu, Aoyan Li, Bo Li, Chen Dun, Chong Liu, Daoguang Zan, Fuxing Leng, Hanbin Wang, Hao Yu, Haobin Chen, Hongyi Guo, Jing Su, Jingjia Huang, Kai Shen, Kaiyu Shi, Lin Yan, Peiyao Zhao, Pengfei Liu, Qinghao Ye, Renjie Zheng, Shulin Xin, Wayne Xin Zhao, Wen Heng, Wenhao Huang, Wenqian Wang, Xiaobo Qin, Yi Lin, Youbin Wu, Zehui Chen, Zihao Wang, Baoquan Zhong, Xinchun Zhang, Xujing Li, Yuanfan Li, Zhongkai Zhao, Chengquan Jiang, Faming Wu, Haotian Zhou, Jinlin Pang, Li Han, Qi Liu, Qianli Ma, Siyao Liu, Songhua Cai, Wenqi Fu, Xin Liu, Yaohui Wang, Zhi Zhang, Bo Zhou, Guoliang Li, Jiajun Shi, Jiale Yang, Jie Tang, Li Li, Qihua Han, Taoran Lu, Woyu Lin, Xiaokang Tong, Xinyao Li, Yichi Zhang, Yu Miao, Zhengxuan Jiang, Zili Li, Ziyuan Zhao, Chenxin Li, Dehua Ma, Feng Lin, Ge Zhang, Haihua Yang, Hangyu Guo, Hongda Zhu, Jiaheng Liu, Junda Du, Kai Cai, Kuanye Li, Lichen Yuan, Meilan Han, Minchao Wang, Shuyue Guo, Tianhao Cheng, Xiaobo Ma, Xiaojun Xiao, Xiaolong Huang, Xinjie Chen, Yidi Du, Yilin Chen, Yiwen Wang, Zhaojian Li, Zhenzhu Yang, Zhiyuan Zeng, Chaolin Jin, Chen Li, Hao Chen, Haoli Chen, Jian Chen, Qinghao Zhao, and Guang Shi. Ui-tars-2 technical report: Advancing gui agent with multi-turn reinforcement learning, 2025c. URL https://arxiv.org/abs/2509.02544. · arXiv
- Hongru Wang, Cheng Qian, Manling Li, Jiahao Qiu, Boyang Xue, Mengdi Wang, Heng Ji, and Kam-Fai Wong. Toward a theory of agents as tool-use decision-makers, 2025d. URL https://arxiv.org/abs/ 2506.00886.
- Junlin Wang, Jue WANG, Ben Athiwaratkun, Ce Zhang, and James Zou. Mixture-of-agents enhances large language model capabilities. In The Thirteenth International Conference on Learning Representations, 2025g. URL https://openreview.net/forum?id=h0ZfDIrj7T.
- Yu Wang, Yifan Gao, Xiusi Chen, Haoming Jiang, Shiyang Li, Jingfeng Yang, Qingyu Yin, Zheng Li, Xian Li, Bing Yin, Jingbo Shang, and Julian McAuley. MEMORYLLM: Towards self-updatable large language models. In Forty-first International Conference on Machine Learning, 2024h. URL https: //openreview.net/forum?id=p0lKWzdikQ.
- Yu Wang, Dmitry Krotov, Yuanzhe Hu, Yifan Gao, Wangchunshu Zhou, Julian McAuley, Dan Gutfreund, Rogerio Feris, and Zexue He. M+: Extending memoryLLM with scalable long-term memory. In Forty-second International Conference on Machine Learning, 2025s. URL https://openreview.net/forum?id= OcqbkROe8J.
- Yu Wang, Ryuichi Takanobu, Zhiqi Liang, Yuzhen Mao, Yuanzhe Hu, Julian McAuley, and Xiaojian Wu. Mem-α: Learning memory construction via reinforcement learning, 2025t. URL https://arxiv.org/ abs/2509.25911. · arXiv
- Zhiruo Wang, Zhoujun Cheng, Hao Zhu, Daniel Fried, and Graham Neubig. What are tools anyway? a survey from the language model perspective. In First Conference on Language Modeling, 2024k. URL https://openreview.net/forum?id=Xh1B90iBSR.
- Ziliang Wang, Xuhui Zheng, Kang An, Cijun Ouyang, Jialu Cai, Yuhang Wang, and Yichao Wu. Stepsearch: Igniting llms search ability via step-wise proximal policy optimization, 2025w. URL https://arxiv. org/abs/2505.15107.
- Yuan Wei, Xiaohan Shan, and Jianmin Li. Lero: Llm-driven evolutionary framework with hybrid rewards and enhanced observation for multi-agent reinforcement learning, 2025d. URL https://arxiv.org/ abs/2503.21807. · arXiv
- Zhepei Wei, Wenlin Yao, Yao Liu, Weizhi Zhang, Qin Lu, Liang Qiu, Changlong Yu, Puyang Xu, Chao Zhang, Bing Yin, Hyokun Yun, and Lihong Li. Webagent-r1: Training web agents via end-to-end multi-turn reinforcement learning. In ICML 2025 Workshop on Computer Use Agents, 2025f. URL https://openreview.net/forum?id=KqrYTALRjH.
- Jiaxin Wen, Ruiqi Zhong, Akbir Khan, Ethan Perez, Jacob Steinhardt, Minlie Huang, Samuel R. Bowman, He He, and Shi Feng. Language models learn to mislead humans via rlhf, 2024. URL https://arxiv. org/abs/2409.12822.
- Jiayi Weng, Huayu Chen, Dong Yan, Kaichao You, Alexis Duburcq, Minghao Zhang, Yi Su, Hang Su, and Jun Zhu. Tianshou: A highly modularized deep reinforcement learning library. Journal of Machine Learning Research, 23(267):1-6, 2022. URL http://jmlr.org/papers/v23/21-1127.html.
- Jialong Wu, Wenbiao Yin, Yong Jiang, Zhenglin Wang, Zekun Xi, Runnan Fang, Linhai Zhang, Yulan He, Deyu Zhou, Pengjun Xie, and Fei Huang. Webwalker: Benchmarking LLMs in web traversal. In Workshop on Reasoning and Planning for Large Language Models, 2025b. URL https://openreview. net/forum?id=cVI9lAfkuK.
- Jie Wu, Haoling Li, Xin Zhang, Jianwen Luo, Yangyu Huang, Ruihang Chu, Yujiu Yang, and Scarlett Li. Iterpref: Focal preference learning for code generation via iterative debugging, 2025c. URL https: //arxiv.org/abs/2503.02783.
- Junkang Wu, Yuexiang Xie, Zhengyi Yang, Jiancan Wu, Jinyang Gao, Bolin Ding, Xiang Wang, and Xiangnan He. $\beta$-DPO: Direct preference optimization with dynamic $\beta$. In The Thirty-eighth Annual Conference on Neural Information Processing Systems, 2024. URL https://openreview.net/forum? id=ZfBuhzE556.
- Minchao Wu, Michael Norrish, Christian Walder, and Amir Dezfouli. Tacticzero: Learning to prove theorems from scratch with deep reinforcement learning. In A. Beygelzimer, Y. Dauphin, P. Liang, and J. Wortman Vaughan (eds.), Advances in Neural Information Processing Systems, 2021. URL https://openreview.net/forum?id=edmYVRkYZv.
- Weijia Wu, Chen Gao, Joya Chen, Kevin Qinghong Lin, Qingwei Meng, Yiming Zhang, Yuke Qiu, Hong Zhou, and Mike Zheng Shou. Reinforcement learning in vision: A survey, 2025h. URL https://arxiv. org/abs/2508.08189.
- Zijian Wu, Suozhi Huang, Zhejian Zhou, Huaiyuan Ying, Zheng Yuan, Wenwei Zhang, Dahua Lin, and Kai Chen. InternLM2.5-stepprover: Advancing automated theorem proving via critic-guided search. In 2nd AI for Math Workshop @ ICML 2025, 2025m. URL https://openreview.net/forum?id=qwCqeIg5iI. x.ai. Grok 3 beta -the age of reasoning agents, 2025. URL https://x.ai/news/grok-3.
- Tianbao Xie, Danyang Zhang, Jixuan Chen, Xiaochuan Li, Siheng Zhao, Ruisheng Cao, Toh Jing Hua, Zhoujun Cheng, Dongchan Shin, Fangyu Lei, Yitao Liu, Yiheng Xu, Shuyan Zhou, Silvio Savarese, Caiming Xiong, Victor Zhong, and Tao Yu. Osworld: Benchmarking multimodal agents for open-ended tasks in real com- puter environments. In A. Globerson, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Advances in Neural Information Processing Systems, volume 37, pp. 52040-52094.
- Curran Asso- ciates, Inc., 2024. URL https://proceedings.neurips.cc/paper_files/paper/2024/file/ 5d413e48f84dc61244b6be550f1cd8f5-Paper-Datasets_and_Benchmarks_Track.pdf. Published in Transactions on Machine Learning Research (01/2026)
- Zhihui Xie, Jie chen, Liyu Chen, Weichao Mao, Jingjing Xu, and Lingpeng Kong. Teaching language models to critique via reinforcement learning. In Forty-second International Conference on Machine Learning, 2025. URL https://openreview.net/forum?id=UVoxPlv5E1.
- Huajian Xin, Z.Z. Ren, Junxiao Song, Zhihong Shao, Wanjia Zhao, Haocheng Wang, Bo Liu, Liyue Zhang, Xuan Lu, Qiushi Du, Wenjun Gao, Haowei Zhang, Qihao Zhu, Dejian Yang, Zhibin Gou, Z.F. Wu, Fuli Luo, and Chong Ruan. Deepseek-prover-v1.5: Harnessing proof assistant feedback for reinforcement learning and monte-carlo tree search. In The Thirteenth International Conference on Learning Representations, 2025. URL https://openreview.net/forum?id=I4YAIwrsXa.
- Wei Xiong, Wenting Zhao, Weizhe Yuan, Olga Golovneva, Tong Zhang, Jason Weston, and Sainbayar Sukhbaatar. Stepwiser: Stepwise generative judges for wiser reasoning, 2025. URL https://arxiv. org/abs/2508.19229.
- Frank F. Xu, Yufan Song, Boxuan Li, Yuxuan Tang, Kritanjali Jain, Mengxue Bao, Zora Z. Wang, Xuhui Zhou, Zhitong Guo, Murong Cao, Mingyang Yang, Hao Yang Lu, Amaad Martin, Zhe Su, Leander Maben, Raj Mehta, Wayne Chi, Lawrence Jang, Yiqing Xie, Shuyan Zhou, and Graham Neubig. Theagentcompany: Benchmarking llm agents on consequential real world tasks, 2024a. URL https://arxiv.org/abs/ 2412.14161.
- Ran Xu, Yuchen Zhuang, Yishan Zhong, Yue Yu, Xiangru Tang, Hang Wu, May D. Wang, Peifeng Ruan, Donghan Yang, Tao Wang, Guanghua Xiao, Carl Yang, Yang Xie, and Wenqi Shi. Medagentgym: Training llm agents for code-based medical reasoning at scale, 2025c. URL https://arxiv.org/abs/2506. 04405.
- Runsen Xu, Xiaolong Wang, Tai Wang, Yilun Chen, Jiangmiao Pang, and Dahua Lin. Pointllm: Empowering large language models to understand point clouds. In European Conference on Computer Vision, pp. 131-147. Springer, 2024b.
- Kaiyu Yang, Gabriel Poesia, Jingxuan He, Wenda Li, Kristin Lauter, Swarat Chaudhuri, and Dawn Song. Formal mathematical reasoning: A new frontier in ai, 2024b. URL https://arxiv.org/abs/2412. 16075.
- Shunyu Yao, Howard Chen, John Yang, and Karthik Narasimhan. Webshop: Towards scalable real-world web interaction with grounded language agents. In S. Koyejo, S. Mohamed, A. Agarwal, D. Belgrave, K. Cho, and A. Oh (eds.), Advances in Neural Information Processing Systems, volume 35, pp. 20744-20757.
- Curran Associates, Inc., 2022. URL https://proceedings.neurips.cc/paper_files/paper/ 2022/file/82ad13ec01f9fe44c01cb91814fd7b8c-Paper-Conference.pdf.
- Shunyu Yao, Dian Yu, Jeffrey Zhao, Izhak Shafran, Thomas L. Griffiths, Yuan Cao, and Karthik R Narasimhan. Tree of thoughts: Deliberate problem solving with large language models. In Thirty-seventh Conference on Neural Information Processing Systems, 2023a. URL https://openreview.net/forum? id=5Xc1ecxO1h.
- Shunyu Yao, Jeffrey Zhao, Dian Yu, Nan Du, Izhak Shafran, Karthik R Narasimhan, and Yuan Cao. React: Synergizing reasoning and acting in language models. In The Eleventh International Conference on Learning Representations, 2023b. URL https://openreview.net/forum?id=WE_vluYUL-X.
- Junliang Ye, Fangfu Liu, Qixiu Li, Zhengyi Wang, Yikai Wang, Xinzhou Wang, Yueqi Duan, and Jun Zhu. Dreamreward: Text-to-3d generation with human preference. In European Conference on Computer Vision, pp. 259-276. Springer, 2024. URL https://icml.cc/virtual/2025/poster/45024.
- Fukun Yin, Xin Chen, Chi Zhang, Biao Jiang, Zibo Zhao, Wen Liu, Gang Yu, and Tao Chen. Shapegpt: 3d shape generation with a unified multi-modal language model. IEEE Transactions on Multimedia, 2025.
- Hangjie Yuan, Shiwei Zhang, Xiang Wang, Yujie Wei, Tao Feng, Yining Pan, Yingya Zhang, Ziwei Liu, Samuel Albanie, and Dong Ni. Instructvideo: Instructing video diffusion models with human feedback. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pp. 6463-6474, 2024.
- Abhay Zala, Jaemin Cho, Han Lin, Jaehong Yoon, and Mohit Bansal. Envgen: Generating and adapting environments via LLMs for training embodied agents. In First Conference on Language Modeling, 2024. URL https://openreview.net/forum?id=F9tqgOPXH5.
- Eric Zelikman, Yuhuai Wu, Jesse Mu, and Noah D. Goodman. Star: self-taught reasoner bootstrapping reasoning with reasoning. In Proceedings of the 36th International Conference on Neural Information Processing Systems, NIPS '22, Red Hook, NY, USA, 2022.
- Curran Associates Inc. ISBN 9781713871088. URL https://dl.acm.org/doi/10.5555/3600270.3601396. · doi:10.5555/3600270.3601396
- Liang Zeng and Liangjun Zhong. Skywork-math: Data scaling laws for mathematical reasoning in LLMs - the story goes on. In The 4th Workshop on Mathematical Reasoning and AI at NeurIPS'24, 2024. URL https://openreview.net/forum?id=uHtzqZKbeK.
- Weihao Zeng, Yuzhen Huang, Qian Liu, Wei Liu, Keqing He, Zejun MA, and Junxian He. SimpleRL-zoo: Investigating and taming zero reinforcement learning for open base models in the wild. In Second Conference on Language Modeling, 2025c. URL https://openreview.net/forum?id=vSMCBUgrQj.
- Bofei Zhang, Zirui Shang, Zhi Gao, Wang Zhang, Rui Xie, Xiaojian Ma, Tao Yuan, Xinxiao Wu, Song-Chun Zhu, and Qing Li. Tongui: Building generalized gui agents by learning from multimodal web tutorials. arXiv preprint arXiv:2504.12679, 2025a. URL https://arxiv.org/abs/2504.12679. · arXiv
- Chaoyun Zhang, Shilin He, Jiaxu Qian, Bowen Li, Liqun Li, Si Qin, Yu Kang, Minghua Ma, Guyue Liu, Qingwei Lin, Saravan Rajmohan, Dongmei Zhang, and Qi Zhang. Large language model-brained GUI agents: A survey. Transactions on Machine Learning Research, 2025b. ISSN 2835-8856. URL https://openreview.net/forum?id=xChvYjvXTp.
- Chuheng Zhang, Wei Shen, Li Zhao, Xuyun Zhang, Xiaolong Xu, Wanchun Dou, and Jiang Bian. Policy filtration for RLHF to mitigate noise in reward models. In Forty-second International Conference on Machine Learning, 2025c. URL https://openreview.net/forum?id=L8hYdTQVcs.
- Dan Zhang, Sining Zhoubian, Ziniu Hu, Yisong Yue, Yuxiao Dong, and Jie Tang. Rest-mcts*: Llm self-training via process reward guided tree search. In A. Globerson, L. Mackey, D. Belgrave, A. Fan, U. Paquet, J. Tomczak, and C. Zhang (eds.), Advances in Neural Information Processing Systems, volume 37, pp. 64735-64772.
- Curran Associates, Inc., 2024a. URL https://proceedings.neurips.cc/paper_ files/paper/2024/file/76ec4dc30e9faaf0e4b6093eaa377218-Paper-Conference.pdf.
- Guibin Zhang, Luyang Niu, Junfeng Fang, Kun Wang, LEI BAI, and Xiang Wang. Multi-agent architecture search via agentic supernet. In Forty-second International Conference on Machine Learning, 2025f. URL https://openreview.net/forum?id=imcyVlzpXh.
- Guibin Zhang, Yanwei Yue, Xiangguo Sun, Guancheng Wan, Miao Yu, Junfeng Fang, Kun Wang, Tianlong Chen, and Dawei Cheng. G-designer: Architecting multi-agent communication topologies via graph neural networks. In Forty-second International Conference on Machine Learning, 2025g. URL https: //openreview.net/forum?id=LpE54NUnmO.
- Jiayi Zhang, Jinyu Xiang, Zhaoyang Yu, Fengwei Teng, Xiong-Hui Chen, Jiaqi Chen, Mingchen Zhuge, Xin Cheng, Sirui Hong, Jinlin Wang, Bingnan Zheng, Bang Liu, Yuyu Luo, and Chenglin Wu. AFlow: Automat- ing agentic workflow generation. In The Thirteenth International Conference on Learning Representations, 2025i. URL https://openreview.net/forum?id=z5uVAKwmjf.
- Jingyuan Zhang, Qi Wang, Xingguang Ji, Yahui Liu, Yang Yue, Fuzheng Zhang, Di Zhang, Guorui Zhou, and Kun Gai. Leanabell-prover: Posttraining scaling in formal reasoning, 2025k. URL https://arxiv. org/abs/2504.06122.
- Junru Zhang, Lang Feng, Xu Guo, Yuhan Wu, Yabo Dong, and Duanqing Xu. Timemaster: Training time-series multimodal llms to reason via reinforcement learning, 2025m. URL https://arxiv.org/ abs/2506.13705. · arXiv
- Wentao Zhang, Ce Cui, Yilei Zhao, Rui Hu, Yang Liu, Yahui Zhou, and Bo An. Agentorchestra: A hierarchical multi-agent framework for general-purpose task solving, 2025r. URL https://arxiv.org/abs/2506. 12508.
- Yadong Zhang, Shaoguang Mao, Tao Ge, Xun Wang, Yan Xia, Wenshan Wu, Ting Song, Man Lan, and Furu Wei. LLM as a mastermind: A survey of strategic reasoning with large language models. In First Conference on Language Modeling, 2024c. URL https://openreview.net/forum?id=iMqJsQ4evS.
- Yichi Zhang, Zihao Zeng, Dongbai Li, Yao Huang, Zhijie Deng, and Yinpeng Dong. Realsafe-r1: Safety-aligned deepseek-r1 without compromising reasoning capability, 2025z. URL https://arxiv.org/abs/2504. 10081.
- Yuxiang Zhang, Jiangming Shu, Ye Ma, Xueyuan Lin, Shangxi Wu, and Jitao Sang. Memory as action: Autonomous context curation for long-horizon agentic tasks, 2025v. URL https://arxiv.org/abs/ 2510.12635.
- Zijing Zhang, Ziyang Chen, Mingxiao Li, Zhaopeng Tu, and Xiaolong Li. Rlvmr: Reinforcement learning with verifiable meta-reasoning rewards for robust long-horizon agents, 2025z. URL https://arxiv.org/ abs/2507.22844. · arXiv
- Wanjia Zhao, Mert Yuksekgonul, Shirley Wu, and James Zou. Sirius: Self-improving multi-agent systems via bootstrapped reasoning. In Workshop on Reasoning and Planning for Large Language Models, 2025e. URL https://openreview.net/forum?id=sLBSJr3hH5.
- Boyuan Zheng, Boyu Gou, Jihyung Kil, Huan Sun, and Yu Su. GPT-4V(ision) is a generalist web agent, if grounded. In Ruslan Salakhutdinov, Zico Kolter, Katherine Heller, Adrian Weller, Nuria Oliver, Jonathan Scarlett, and Felix Berkenkamp (eds.), Proceedings of the 41st International Conference on Machine Learning, volume 235 of Proceedings of Machine Learning Research, pp. 61349-61385. PMLR, 21-27 Jul 2024. URL https://proceedings.mlr.press/v235/zheng24e.html.
- Zihan Zheng, Tianle Cui, Chuwen Xie, Jiahui Zhang, Jiahui Pan, Lewei He, and Qianglong Chen. Naturegaia: Pushing the frontiers of gui agents with a challenging benchmark and high-quality trajectory dataset, 2025f. URL https://arxiv.org/abs/2508.01330. · arXiv
- Andy Zhou, Kai Yan, Michal Shlapentokh-Rothman, Haohan Wang, and Yu-Xiong Wang. Language agent tree search unifies reasoning, acting, and planning in language models. In Proceedings of the 41st International Conference on Machine Learning, ICML'24. JMLR.org, 2024a.
- Heng Zhou, Hejia Geng, Xiangyuan Xue, Li Kang, Yiran Qin, Zhiyong Wang, Zhenfei Yin, and Lei Bai. Reso: A reward-driven self-organizing llm-based multi-agent system for reasoning tasks. Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025b. URL https: //openreview.net/forum?id=te0jBwgBRm.
200 of 206 shown
Cited by
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
Self-citationMemory in the Age of AI Agents
Hu, Y., Liu, S., Yue, Y., Zhang, G., Liu, B., Zhu, F., Lin, J., Guo, H., Dou, S., Xi, Z., et al. (2025) · arXiv · doi:10.48550/arxiv.2512.13564 · Cited by 389
Self-citationA Survey of Reinforcement Learning for Large Reasoning ModelsPreprint
Zhang, K., Zuo, Y., He, B., Sun, Y., Liu, R., Jiang, C., Fan, Y., Tian, K., Jia, G., Li, P., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2509.08827 · Cited by 232
Self-citationRoboRefer: Towards Spatial Referring with Reasoning in Vision-Language Models for Robotics
Zhou, E., An, J., Chi, C., Han, Y., Rong, S., Zhang, C., Wang, P., Wang, Z., Huang, T., Sheng, L., et al. (2025) · neural information processing systems · doi:10.52202/085713-0957 · Cited by 135
Self-citationAgentFold: Long-Horizon Web Agents with Proactive Context ManagementPreprint
Ye, R., Zhang, Z., Li, K., Yin, H., Tao, Z., Zhao, Y., Su, L., Zhang, L., Qiao, Z., Wang, X., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.24699 · Cited by 127
Self-citation
Metadata
- Authors
- Zhang, G., Geng, H., Yu, X., Yin, Z., Zhang, Z., Tan, Z., Zhou, H., Li, Z., Xue, X., Li, Y., Zhou, Y., Chen, Y., Zhang, C., Fan, Y., Wang, Z., Huang, S., Piedrahita-Velez, F., Liao, Y., Wang, H., Yang, M., Ji, H., Wang, J., Yan, S., Torr, P., & Bai, L.
- Affiliations
- National University of Singapore (SG)
- University of Oxford (GB)
- Imperial College London (GB)
- Dalian University of Technology (CN)
- University of Science and Technology of China (CN)
- Chinese Academy of Sciences (CN)
- Chinese University of Hong Kong (HK)
- University of California San Diego (US)
- University of Georgia (US)
- Shanghai Artificial Intelligence Laboratory (CN)
- University of California, Santa Barbara (US)
- University of Bristol (GB)
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2025
- ISSN
- 2331-8422 (ISSN-L)
- arXiv
- 2509.02547
- OpenAlex
- W4416711932
- Cited by
- 229
- References
- 394
- Citations by year
- 2026: 180 · 2025: 48
- Type
- posted content
- Language
- en
- Open access
- green
- arxiv.org
- Licence
- Locations
- arXiv (Cornell University) (submittedVersion, cc-by)
- arXiv (Cornell University) (cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Reinforcement Learning in Robotics
- Physical Sciences › Computer Science › Artificial Intelligence › AI-based Problem Solving and Planning
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- agentic reinforcement learning, large language models, LLM agents, partially observable Markov decision processes, planning, tool use, memory, reasoning, human development, perception, benchmark
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-14, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-14 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
