

The DOI matches its Crossref record; 55 of the 60 references it cites were found in a registry or an index; 9 of the 26 sources its claims cite were checked for support.
In-Context Retrieval-Augmented Language Models
Open accessAbstract
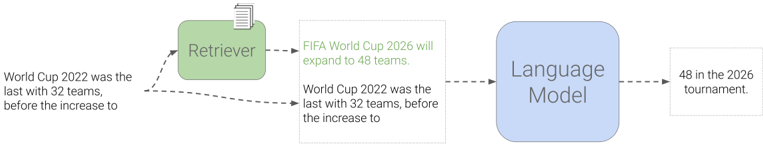
Abstract Retrieval-Augmented Language Modeling (RALM) methods, which condition a language model (LM) on relevant documents from a grounding corpus during generation, were shown to significantly improve language modeling performance. In addition, they can mitigate the problem of factually inaccurate text generation and provide natural source attribution mechanism. Existing RALM approaches focus on modifying the LM architecture in order to facilitate the incorporation of external information, significantly complicating deployment. This paper considers a simple alternative, which we dub In-Context RALM: leaving the LM architecture unchanged and prepending grounding documents to the input, without any further training of the LM. We show that In-Context RALM that builds on off-the-shelf general purpose retrievers provides surprisingly large LM gains across model sizes and diverse corpora. We also demonstrate that the document retrieval and ranking mechanism can be specialized to the RALM setting to further boost performance. We conclude that In-Context RALM has considerable potential to increase the prevalence of LM grounding, particularly in settings where a pretrained LM must be used without modification or even via API access.1
Overview
CoChat Summary
TL;DR
In-Context RALM prepends retrieved documents to a frozen LM’s input without architecture changes or training, and off-the-shelf retrievers yield large perplexity gains across model sizes and corpora. Tailoring document ranking via zero-shot or trained rerankers further improves performance, including on open-domain QA.
Key findings
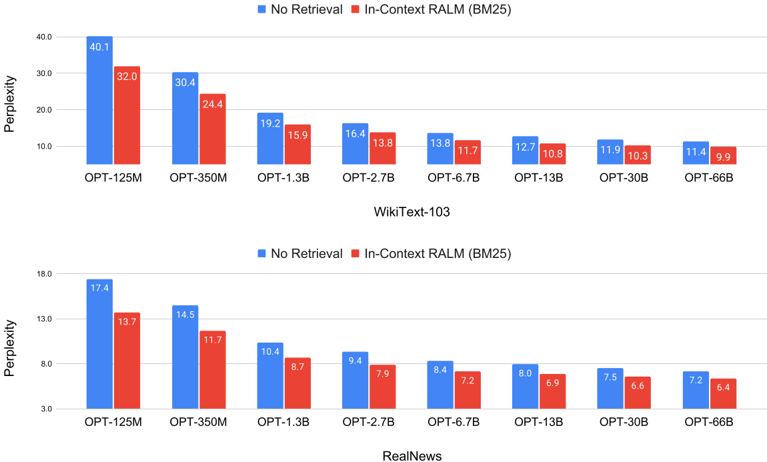
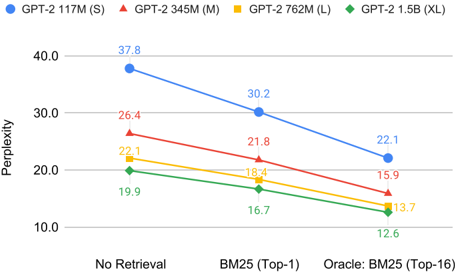
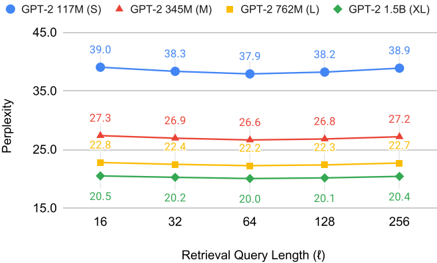
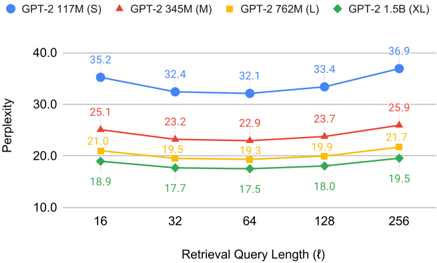
- With BM25 retrieval (`s = 4`, `ℓ = 32`), In-Context RALM improved LM perplexity enough to match a 2–3× larger model; e.g., 6.7B OPT matched 66B OPT, and 345M GPT-2 + BM25 outperformed 762M GPT-2.
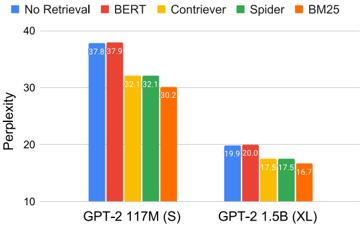
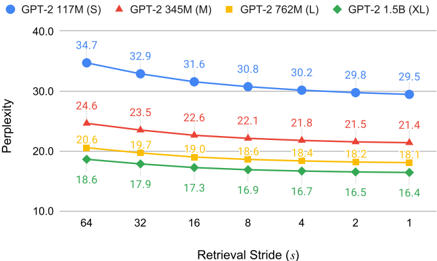
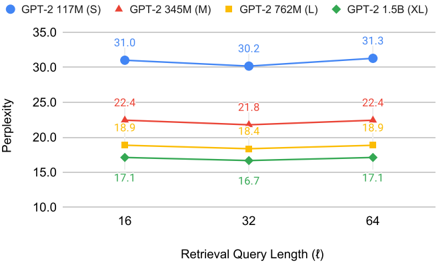
- BM25 outperformed dense retrievers (Contriever, Spider, BERT mean pooling); optimal query length was `ℓ = 32` for BM25 vs. `ℓ = 64` for dense retrievers, and more frequent retrieval (smaller stride) improved performance.
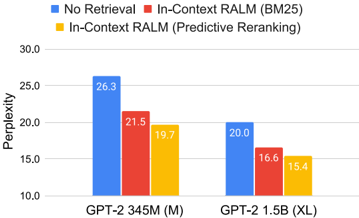
- Predictive reranking improved WikiText-103 word perplexity for GPT-2 110M from 29.6 to 26.8 and GPT-2 1.5B from 16.6 to 15.4; zero-shot reranking also improved over taking the top BM25 document.
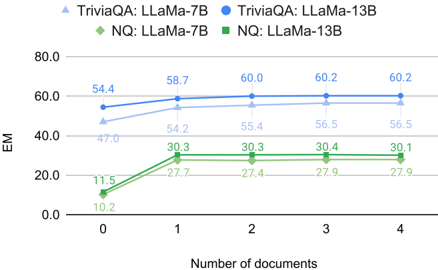
- On ODQA with two DPR documents, LLaMA-13B improved NQ exact match from 12.0% to 31.0% and TriviaQA from 54.8% to 60.1%; LLaMA-33B improved NQ from 13.7% to 32.3% and TriviaQA from 58.3% to 62.7%.
Methods
- Evaluated on five LM datasets (WikiText-103, RealNews, ArXiv, Stack Exchange, FreeLaw) and two ODQA datasets (Natural Questions, TriviaQA), using GPT-2 (110M–1.5B), GPT-Neo/GPT-J (1.3B–6B), OPT (125M–66B), and LLaMA (7B–33B) models with max sequence length 1,024.
- Retrieval corpora: Wikipedia (Dec. 20, 2018) for WikiText-103/ODQA with 120 WikiText dev/test articles removed; training data for other datasets; non-overlapping 100-word passages truncated at 256 tokens. Retrievers: BM25, BERT mean pooling, Contriever, Spider; DPR for ODQA.
- Main analyses measured perplexity on LM datasets and exact match on ODQA; reranking used top-16 BM25 documents, with zero-shot LM reranking and a RoBERTa-base predictive reranker trained for 10,000 steps (peak LR 1e-5, batch 32, 300,000 WikiText-103 examples).
Limitations
- Stated: the paper considers only prepending a single external document; adding more documents could drive further gains. It retrieves every fixed interval of `s` tokens, and future work could retrieve more sparsely (e.g., when a specialized model predicts retrieval is needed) for latency/cost gains.
- Stated: predictive reranking still leaves room compared with top-16 BM25 oracle results; oracle could improve with `k > 16` or stronger RALM-dedicated retrievers.
- Evident: main LM experiments use one document and max sequence length 1,024 despite some models supporting 2,048; the predictive reranker assumes availability of training data from the target corpus and was trained on WikiText-103.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
5 Valid · 4 Not valid · 9 Not checked · 43 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Their results are based on training a dedicated retriever for language modeling.”
§ In-Context Retrieval-Augmented Language Models > 1 Introduction
What the sources say
- Partly supportedcites Shi et al., 2023 sourceExperimental — accuracy not yet measured
Section 4 describes training a retriever with language-model supervision for REPLUG LSR, and Section 5.2 gives its training procedure. But the ‘Our model’ results also include REPLUG without that retriever training, so training a dedicated retriever underlies only part of the reported results. The indexed passages provide no page numbers. (LLM, conf=0.88)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“More importantly, they tend to produce factual inaccuracies and errors (Lin et al., 2022;Maynez et al., 2020;Huang et al., 2020).”
§ In-Context Retrieval-Augmented Language Models > 1 Introduction
What the sources say
- Supportedcites Lin et al., 2022 source
The Introduction (p. 1) explicitly says that recent language models have a tendency to generate false statements, ranging from subtle inaccuracies to hallucinations. The Discussion (p. 8) also reports poor performance by the baseline models on truthfulness questions. (LLM, conf=0.94)
- Partly supportedcites Maynez et al., 2020 sourceExperimental — accuracy not yet measured
Section 5.3 reports that over 90% of hallucinations from the BERTS2S summarization model are erroneous, and the Abstract reports substantial hallucinated content across the evaluated summarization systems. This supports factual errors in those systems, but the claim extends the finding to language models generally, which the paper did not evaluate. (LLM, conf=0.83)
- Partly supportedcites Huang et al., 2020 sourceExperimental — accuracy not yet measured
Section 2.3 (p. 10) says generation-based dialog methods often produce undesirable responses that are ungrammatical or irrelevant, supporting the general point about errors. Section 3.2 (p. 12) stresses grounding responses in real-world facts, but the passages do not establish that language models tend to produce factual inaccuracies specifically; the paper discusses open-domain dialog systems rather than LMs generally. (LLM, conf=0.78)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Existing RALM approaches focus on modifying the LM architecture in order to facilitate the incorporation of external information, significantly complicating deployment.”
- Also stated in: § 1 Introduction · plain
“Leading RALM systems introduced recently tend to be focused on altering the language model architecture (Khandelwal et al., 2020;Borgeaud et al., 2022;Zhong et al., 2022;Levine et al., 2022c;Li et al., 2022).”
§ In-Context Retrieval-Augmented Language Models > Abstract
What the sources say
- Not matchedcites Khandelwal et al., 2020
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites Borgeaud et al., 2022
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Partly supportedcites Zhong et al., 2022 sourceExperimental — accuracy not yet measured
The Introduction and §2.2 Memory Augmentation say that several earlier approaches modify Transformer architectures to incorporate memory from previous segments. They do not establish that existing retrieval-augmented language modeling approaches generally focus on architecture changes, or that those changes significantly complicate deployment. (LLM, conf=0.84)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 1 Introduction · plain
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“All prior work involves training the LM.”
§ In-Context Retrieval-Augmented Language Models > Nearest Neighbor Language Models
What the sources say
- Not matchedcites Lewis et al., 2020
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Could not verifycites Izacard and Grave, 2021 sourceExperimental — accuracy not yet measured
The Related work section (p. 2) describes earlier retrieval-augmented QA systems but does not say whether all of them train the language model. The Experiments section (p. 4) says this paper fine-tunes its own pretrained T5 model; that does not establish the claim about all prior work. I searched for discussion of training or freezing the language model in earlier retrieve-and-read systems. (LLM, conf=0.72)
- Not matchedcites Borgeaud et al., 2022
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“While they showed significant gains from kNN-LM, the approach requires storing the representations for each token in the corpus, an expensive requirement even for a small corpus like Wikipedia.”
§ In-Context Retrieval-Augmented Language Models > Nearest Neighbor Language Models
What the sources say
- Partly supportedcites Zhong et al., 2022 sourceExperimental — accuracy not yet measured
Section 2.2 defines external memory as context–token pairs from a corpus and says that accessing a memory of roughly 10^8 entries is computationally expensive. The Introduction identifies kNN-LM as using external memory, and Table 2 notes large SSD storage for one retrieval setup. The paper tests on WIKITEXT-103, but these passages do not characterize Wikipedia itself as a small corpus or establish the claimed storage cost for it. (LLM, conf=0.82)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
42 more claims
Create a free account to see all 61 claims and to verify the 2 references still open.
- Probably not a substantial claim. 9
- The quote only partly states this claim. 3
- It may state two separate claims as one. 4
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“or when language models are augmented with external information (relevant documents from a search engine, database query results, etc.; Petroni et al., 2020;Ram et al., 2023;Shi et al., 2023;Mallen et al., 2023;Schick et al., 2023, inter alia).”
From Lost in the Middle: How Language Models Use Long Contexts (2024) · cites this paper as Ram et al., 2023
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“In contrast to fine-tuning, RAG does not seek to adjust the internal parameters (or internal memory) of an LLM.”
From ChatGPT, extended: large language models and the extended mind (2025) · cites this paper as Ram et al., 2023
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“the task of retrieving relevant and precise information from extensive corpora can be computationally demanding and resourceintensive, necessitating continuous updating and modification of knowledge databases to keep pace with the latest information (Chen et al. 2023; Siriwardhana et al. 2023; Ram et al. 2023; Cheng et al. 2024).”
From Large Legal Fictions: Profiling Legal Hallucinations in Large Language Models (2024) · cites this paper as Ram et al. 2023
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Memory-augmented methods extend this concept by retrieving user-specific information from past interactions. This addresses the challenge of a limited context window and enables the integration of past information into the input prompt [25, 29, 45].”
From CAIM: Development and Evaluation of a Cognitive AI Memory Framework for Long-Term Interaction with Intelligent Agents (2026) · cites this paper as [45]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Despite their capabilities, LLMs still have shortcomings, such as a limited context window, which restricts the amount of information that can be processed and thus the ability to understand the ever-changing environment [58, 60] and maintain effective long-term interactions [45, 50].”
From CAIM: Development and Evaluation of a Cognitive AI Memory Framework for Long-Term Interaction with Intelligent Agents (2026) · cites this paper as [45]
Experimental — accuracy not yet measured
9 more claims about this paper
Create a free account to see every claim other papers make about this one.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ In-Context Retrieval-Augmented Language Models > 8 Discussion
“this paper considers only the case of prepending a single external document to the context”
§ In-Context Retrieval-Augmented Language Models > 7 In-Context RALM for Open-Domain Question Answering
“In the open-book setting, we include the top two documents returned by DPR.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ In-Context Retrieval-Augmented Language Models > Nearest Neighbor Language Models
“All prior work involves training the LM.”
§ In-Context Retrieval-Augmented Language Models > Nearest Neighbor Language Models
“Levine et al. (2022a) showed competitive open domain question-answering performance by prompt-tuning a frozen LM as a reader.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ In-Context Retrieval-Augmented Language Models > Model
“Table 3 shows that a small LM (GPT-2 117M) can be used to rerank the documents for all larger GPT-2 models”
§ In-Context Retrieval-Augmented Language Models > Model
“GPT-2 345M (M) GPT-2 110M (S) 20.8 12.1”
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Advances in neural information processing systems 7
(1996) · Computers & Mathematics with Applications · doi:10.1016/s0898-1221(96)90463-0 · Cited by 14,281
Advances in Neural Information Processing Systems 29
Teymur, O., Zygalakis, K., & Calderhead, B. (2016) · Cited by 13,887
Transformers: State-of-the-Art Natural Language Processing
Wolf, T., Debut, L., Sanh, V., Chaumond, J., Delangue, C., Moi, A., Cistac, P., Rault, T., Louf, R., Funtowicz, M., et al. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations · doi:10.18653/v1/2020.emnlp-demos.6 · Cited by 8,741
LLaMA: Open and Efficient Foundation Language Models
Touvron, H., Lavril, T., Izacard, G., Martinet, X., Lachaux, M.-A., Lacroix, T., Rozière, B., Goyal, N., Hambro, E., Azhar, F., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.13971 · Cited by 4,602
Billion-scale similarity search with GPUs
Johnson, J., Douze, M., & Jegou, H. (2021) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2019.2921572 · Cited by 4,228 · cited 1×
“For dense retrieval, we applied exact search using FAISS (Johnson et al., 2021).”
MethodBillion-scale similarity search with GPUs
Johnson, J., Douze, M., & Jégou, H. (2017) · arXiv · doi:10.48550/arxiv.1702.08734 · Cited by 4,140
Research works printed but not linked: 1
- Levine, 2022, Huge frozen language models as readers for open-domain question answering
Cited by
Huang, L., Yu, W., Ma, W., Zhong, W., Feng, Z., Wang, H., Chen, Q., Peng, W., Feng, X., Qin, B., et al. (2025) · ACM Transactions on Information Systems · doi:10.1145/3703155 · Cited by 4,688
Lost in the Middle: How Language Models Use Long Contexts
Liu, N. F., Lin, K., Hewitt, J., Paranjape, A., Bevilacqua, M., Petroni, F., & Liang, P. (2023) · arXiv · doi:10.48550/arxiv.2307.03172 · Cited by 1,599
Lost in the Middle: How Language Models Use Long Contexts
Liu, N. F., Lin, K., Hewitt, J., Paranjape, A., Bevilacqua, M., Petroni, F., & Liang, P. (2024) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00638 · Cited by 1,612
A Comprehensive Overview of Large Language Models
Naveed, H., Khan, A. U., Qiu, S., Saqib, M., Anwar, S., Usman, M., Akhtar, N., Barnes, N., & Mian, A. (2023) · arXiv · doi:10.48550/arxiv.2307.06435 · Cited by 1,259
A Comprehensive Overview of Large Language Models
Naveed, H., Khan, A. U., Qiu, S., Saqib, M., Anwar, S., Usman, M., Akhtar, N., Barnes, N., & Mian, A. (2025) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3744746 · Cited by 1,257
“This paper will serve as a valuable resource for researchers, offering insights into the recent advancements in LLMs and providing fundamental concepts and details to develop improved LLMs.”
A Survey on RAG Meeting LLMs: Towards Retrieval-Augmented Large Language Models
Fan, W., Ding, Y., Ning, L., Wang, S., Li, H., Yin, D., Chua, T.-S., & Li, Q. (2024) · Proceedings of the 30th ACM SIGKDD Conference on Knowledge Discovery and Data Mining · doi:10.1145/3637528.3671470 · Cited by 827
Retrieval-Augmented Generation for Large Language Models: A Survey
Gao, Y., Xiong, Y., Gao, X., Jia, K., Pan, J., Bi, Y., Dai, Y., Sun, J., Wang, M., & Wang, H. (2023) · arXiv · doi:10.48550/arxiv.2312.10997 · Cited by 876
“…progressed from simple token [ Khandelwal et al. , 2019 ] and entity retrieval [ Nishikawa et al. , 2022 ] to more complex structures like chunks [ Ram et al. , 2023 ] and knowledge graph [ Kang et al. , 2023 ] , with studies focusing on the granularity of retrieval and the level of data…”
BackgroundLarge Legal Fictions: Profiling Legal Hallucinations in Large Language Models
Dahl, M., Magesh, V., Suzgun, M., & Ho, D. E. (2024) · Journal of Legal Analysis · doi:10.1093/jla/laae003 · Cited by 559
Siren's Song in the AI Ocean: A Survey on Hallucination in Large Language Models
Zhang, Y., Li, Y., Cui, L., Cai, D., Liu, L., Fu, T., Huang, X., Zhao, E., Zhang, Y., Chen, Y., et al. (2025) · Computational Linguistics · doi:10.1162/coli.a.16 · Cited by 534
“The most straightforward approach to utilize retrieved knowledge or tool feedback is to directly concatenate them with user queries before prompting LLMs (Shi et al., 2023c; Mallen et al., 2023; Ram et al., 2023).”
Active Retrieval Augmented Generation
Jiang, Z., Xu, F., Gao, L., Sun, Z., Liu, Q., Dwivedi-Yu, J., Yang, Y., Callan, J., & Neubig, G. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.495 · Cited by 497
Almanac — Retrieval-Augmented Language Models for Clinical Medicine
Zakka, C., Shad, R., Chaurasia, A., Dalal, A. R., Kim, J. L., Moor, M., Fong, R., Phillips, C., Alexander, K., Ashley, E., et al. (2024) · NEJM AI · doi:10.1056/aioa2300068 · Cited by 424
Katz, D. M., Bommarito, M. J., Gao, S., & Arredondo, P. (2024) · Philosophical Transactions of the Royal Society A: Mathematical, Physical and Engineering Sciences · doi:10.1098/rsta.2023.0254 · Cited by 420
Unleashing the potential of prompt engineering for large language models
Chen, B., Zhang, Z., Langrené, N., & Zhu, S. (2025) · Patterns · doi:10.1016/j.patter.2025.101260 · Cited by 490
RAFT: Adapting Language Model to Domain Specific RAG
Zhang, T., Patil, S. G., Jain, N., Shen, S., Zaharia, M., Stoica, I., & Gonzalez, J. E. (2024) · arXiv · doi:10.48550/arxiv.2403.10131 · Cited by 286
Retrieval-Augmented Generation for AI-Generated Content: A Survey
Zhao, P., Zhang, H., Yu, Q., Wang, Z., Geng, Y., Fu, F., Yang, L., Zhang, W., Jiang, J., & Cui, B. (2024) · arXiv · doi:10.48550/arxiv.2402.19473 · Cited by 240
“In-Context In-Context RALM [128] uses BM25 for document retrieval and trains a predictive reranker to reorder and integrate the top-ranked documents.”
Yang, L., Chen, H., Li, Z., Ding, X., & Wu, X. (2024) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2024.3360454 · Cited by 238
“Retrievalaugmentationhasemergedasa widelyadoptedapproach,allowingLLMstoretrieveexternal datafromdatabases[149]ortoolsandpassittoLLMsin the form of prompts or embeddings to improve LLMs’ generations.”
BackgroundThe power of noise: Redefining retrieval for rag systems
Cuconasu, F., Trappolini, G., Siciliano, F., Filice, S., Campagnano, C., Maarek, Y., Tonellotto, N., & Silvestri, F. (2024) · Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval · doi:10.1145/3626772.3657834 · Cited by 236
Large Language Models for Information Retrieval: A Survey
Zhu, Y., Yuan, H., Wang, S., Liu, J., Liu, W., Deng, C., Chen, H., Liu, Z., Dou, Z., & Wen, J.-R. (2026) · ACM Transactions on Information Systems · doi:10.1145/3748304 · Cited by 225
Huang, L., Yu, W., Ma, W., Zhong, W., Feng, Z., Wang, H., Chen, Q., Peng, W., Feng, X., Qin, B., et al. (2023) · arXiv · doi:10.48550/arxiv.2311.05232 · Cited by 2,516
Dense Text Retrieval Based on Pretrained Language Models: A Survey
Zhao, W. X., Liu, J., Ren, R., & Wen, J.-R. (2024) · ACM Transactions on Information Systems · doi:10.1145/3637870 · Cited by 211
LightRAG: Simple and Fast Retrieval-Augmented Generation
Guo, Z., Xia, L., Yu, Y., Ao, T., & Huang, C. (2025) · Findings of the Association for Computational Linguistics: EMNLP 2025 · doi:10.18653/v1/2025.findings-emnlp.568 · Cited by 208
Zhao, S., Yang, Y., Wang, Z., He, Z., Qiu, L. K., & Qiu, L. (2024) · arXiv · doi:10.48550/arxiv.2409.14924 · Cited by 180
From Matching to Generation: A Survey on Generative Information Retrieval
Li, X., Jin, J., Zhou, Y., Zhang, Y., Zhang, P., Zhu, Y., & Dou, Z. (2025) · ACM Transactions on Information Systems · doi:10.1145/3722552 · Cited by 172
“User-centric Reliable Response Search Query”
RepoCoder: Repository-Level Code Completion Through Iterative Retrieval and Generation
Zhang, F., Chen, B., Zhang, Y., Keung, J., Liu, J., Zan, D., Mao, Y., Lou, J.-G., & Chen, W. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.151 · Cited by 173
Retrieval-augmented generation for educational application: A systematic survey
Li, Z., Wang, Z., Wang, W., Hung, K., Xie, H., & Wang, F. L. (2025) · Computers and Education: Artificial Intelligence · doi:10.1016/j.caeai.2025.100417 · Cited by 151
The Good and The Bad: Exploring Privacy Issues in Retrieval-Augmented Generation (RAG)
Zeng, S., Zhang, J., He, P., Liu, Y., Xing, Y., Xu, H., Ren, J., Chang, Y., Wang, S., Yin, D., et al. (2024) · Findings of the Association for Computational Linguistics ACL 2024 · doi:10.18653/v1/2024.findings-acl.267 · Cited by 149
Hallucination Mitigation for Retrieval-Augmented Large Language Models: A Review
Zhang, W., & Zhang, J. (2025) · Mathematics · doi:10.3390/math13050856 · Cited by 145
A survey on knowledge-oriented retrieval-augmented generation
Cheng, M., Luo, Y., Ouyang, J., Liu, Q., Liu, H., Li, L., Yu, S., Zhang, B., Cao, J., Ma, J., et al. (2025) · arXiv · doi:10.48550/arxiv.2503.10677 · Cited by 140
Bias and Unfairness in Information Retrieval Systems: New Challenges in the LLM Era
Dai, S., Chen, X., Xu, S., Pang, L., Dong, Z., & Xu, J. (2024) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3637528.3671458 · Cited by 329
CacheGen: KV Cache Compression and Streaming for Fast Large Language Model Serving
Liu, Y., Li, H., Cheng, Y., Ray, S., Huang, Y., Zhang, Q., Du, K., Yao, J., Lu, S., Ananthanarayanan, G., et al. (2024) · Proceedings of the ACM SIGCOMM 2024 Conference · doi:10.1145/3651890.3672274 · Cited by 118
Zhao, X., Liu, S., Yang, S.-Y., & Miao, C. (2025) · Proceedings of the ACM on Web Conference 2025 · doi:10.1145/3696410.3714782 · Cited by 116
Wang, F., Zhang, Z., Zhang, X., Wu, Z., Mo, T., Lu, Q., Wang, W., Li, R., Xu, J., Tang, X., et al. (2025) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3768165 · Cited by 106
Asai, A., Wu, Z., Wang, Y., Sil, A., & Hajishirzi, H. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.11511 · Cited by 101
“Retrieval-Augmented Generation (RAG) methods (Figure 1 left; Lewis et al. 2020; Guu et al. 2020) augment the input of LLMs with relevant retrieved passages, reducing factual errors in knowledge-intensive tasks (Ram et al., 2023; Asai et al., 2023a).”
MethodLLM for SoC Security: A Paradigm Shift
Saha, D., Tarek, S., Yahyaei, K., Saha, S. K., Zhou, J., Tehranipoor, M. M., & Farahmandi, F. (2024) · IEEE Access · doi:10.1109/access.2024.3427369 · Cited by 152
“Retrieval-augmented in-context learning (RA-ICL) enhances GPT models by integrating external knowledge sources to provide up-to-date information, addressing the limitations of the last training update of the models [84], [85].”
BackgroundHuman-AI Collaborative Essay Scoring: A Dual-Process Framework with LLMs
Xiao, C., Ma, W., Song, Q., Xu, S. X., Zhang, K., Wang, Y., & Fu, Q. T. (2025) · International Conference on Learning Analytics and Knowledge (LAK) · doi:10.1145/3706468.3706507 · Cited by 214
MemoRAG: Boosting Long Context Processing with Global Memory-Enhanced Retrieval Augmentation
Qian, H., Liu, Z., Zhang, P., Mao, K., Lian, D., Dou, Z., & Huang, T. (2025) · Proceedings of the ACM on Web Conference 2025 · doi:10.1145/3696410.3714805 · Cited by 86
Information Retrieval meets Large Language Models: A strategic report from Chinese IR community
Ai, Q., Bai, T., Cao, Z., Chang, Y., Chen, J., Chen, Z., Cheng, Z., Dong, S., Dou, Z., Feng, F., et al. (2023) · AI Open · doi:10.1016/j.aiopen.2023.08.001 · Cited by 141
CacheBlend: Fast Large Language Model Serving for RAG with Cached Knowledge Fusion
Yao, J., Li, H., Liu, Y., Ray, S., Cheng, Y., Zhang, Q., Du, K., Lu, S., & Jiang, J. (2025) · Proceedings of the Twentieth European Conference on Computer Systems · doi:10.1145/3689031.3696098 · Cited by 75
“Retrieval augmented generation (RAG): RAG [22, 23, 37, 46, 48] can enhance the accuracy and reliability of LLMs with text chunks fetched from external sources.”
Domain Specialization as the Key to Make Large Language Models Disruptive: A Comprehensive Survey
Ling, C., Zhao, X., Lu, J., Deng, C., Zheng, C., Wang, J., Chowdhury, T., Li, Y., Cui, H., Zhang, X., et al. (2025) · ACM Computing Surveys · doi:10.1145/3764579 · Cited by 464
“With the prevalence of LLMs, researchers have been using LLMs to replace the neural network based retriever [27, 57, 126], and Izacard et al.”
Han, B., Susnjak, T., & Mathrani, A. (2024) · Applied Sciences · doi:10.3390/app14199103 · Cited by 68
Wang, Y., Pan, Y., Su, Z., Deng, Y., Zhao, Q., Du, L., Luan, T. H., Kang, J., & Niyato, D. T. (2025) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2025.3576176 · Cited by 147
“For traditional AI models, an adversarial attack involves an adversary subtly manipulating the input by injecting imperceptible perturbations, causing the AI model to generate outputs that deviate from the expected results.”
Beyond Traditional Assessment: Exploring the Impact of Large Language Models on Grading Practices
Fagbohun, O., Iduwe, N. P., Abdullahi, M., Ifaturoti, A., & Nwanna, M. (2024) · Journal of Artificial Intelligence Machine Learning and Data Science · doi:10.51219/jaimld/oluwole-fagbohun/19 · Cited by 107
On the use of large language models in model-driven engineering
Rocco, J. D., Ruscio, D. D., Sipio, C. D., Nguyen, P. T., & Rubei, R. (2025) · Software & Systems Modeling · doi:10.1007/s10270-025-01263-8 · Cited by 84
“More importantly, RAG also helps to reduce factually inaccurate answers in text generation tasks [70].”
RAGCache: Efficient Knowledge Caching for Retrieval-Augmented Generation
Jin, C., Zhang, Z., Jiang, X., Liu, F., Liu, S., Liu, X., & Jin, X. (2026) · ACM Transactions on Computer Systems · doi:10.1145/3768628 · Cited by 61
RAGCache: Efficient Knowledge Caching for Retrieval-Augmented Generation
Jin, C., Zhang, Z., Jiang, X., Liu, F., Liu, X., Liu, X., & Jin, X. (2024) · arXiv · doi:10.48550/arxiv.2404.12457 · Cited by 61
MemGPT: Towards LLMs as Operating Systems
Packer, C., Wooders, S., Lin, K., Fang, V., Patil, S. G., Stoica, I., & Gonzalez, J. E. (2023) · arXiv · doi:10.48550/arxiv.2310.08560 · Cited by 64
“…generated response against the ‘gold response’ using ROUGE-L scores (Lin, 2004) and an ‘LLM judge’, which is instructed to evaluate whether or not the generated response is consistent with the gold response (GPT-4 has been shown to have high agreement with human evaluators (Zheng et al., 2023)).”
MethodIdentifying and Mitigating the Security Risks of Generative AI
Barrett, C., Boyd, B., Bursztein, E., Carlini, N., Chen, B., Choi, J., Chowdhury, A. R., Christodorescu, M., Datta, A., Feizi, S., et al. (2023) · Foundations and Trends® in Privacy and Security · doi:10.1561/3300000041 · Cited by 57
“We note that storing user-LLM conversations might lead to serious privacy concerns.”
BackgroundBiomedRAG: A retrieval augmented large language model for biomedicine
Li, M., Halil Kilicoglu, B., Xu, H., & Zhang, R. (2025) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2024.104769 · Cited by 103
Improving accuracy of GPT-3/4 results on biomedical data using a retrieval-augmented language model
Soong, D., Sridhar, S., Si, H., Wagner, J.-S., Sá, A. C. C., Yu, C. Y., Karagoz, K., Guan, M., Kumar, S., Hamadeh, H. K., et al. (2024) · PLOS Digital Health · doi:10.1371/journal.pdig.0000568 · Cited by 69
“approaches have proven promising [24] [30].”
Evaluating Generative Ad Hoc Information Retrieval
Gienapp, L., Scells, H., Deckers, N., Bevendorff, J., Wang, S., Kiesel, J., Syed, S., Fröbe, M., Zuccon, G., Stein, B., et al. (2024) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3626772.3657849 · Cited by 71
Ren, T., Zhang, Z., Jia, B., & Zhang, S. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.127306 · Cited by 60
Large language models as tax attorneys: a case study in legal capabilities emergence
Nay, J. J., Karamardian, D., Lawsky, S. B., Tao, W., Bhat, M., Jain, R., Lee, A. T., Choi, J. H., & Kasai, J. (2024) · Philosophical Transactions of the Royal Society A Mathematical Physical and Engineering Sciences · doi:10.1098/rsta.2023.0159 · Cited by 100
“[57] present a simpler alternative to Retrieval-Augmented Language Modeling (RALM): in-context RALM, where grounding documents are incorporated into the LLM’s input without modifying its architecture.”
MethodRetrieval-Generation Synergy Augmented Large Language Models
Feng, Z., Feng, X., Zhao, D., Yang, M., & Qin, B. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10448015 · Cited by 117
“Recent research shows that retrieving relevant documents from an external datastore [9, 10, 11] or directly generating contextual documents from LLMs [12, 13] both can improve LLMs’ performance on knowledge-intensive tasks.”
BackgroundLong, C., Subburam, D., Lowe, K., dos Santos, A., Zhang, J. J., Hwang, S. W., Saduka, N., Horev, Y., Su, T., Côté, D. W. J., et al. (2024) · Otolaryngology · doi:10.1002/ohn.864 · Cited by 50
“30 It uses a prebuilt LLM (in this case, ChatGPT) as is but with an additional preparatory stage.”
Answering Questions by Meta-Reasoning over Multiple Chains of Thought
Yoran, O., Wolfson, T., Bogin, B., Katz, U., Deutch, D., & Berant, J. (2023) · arXiv · doi:10.48550/arxiv.2304.13007 · Cited by 38
“Recent works also target retrieval-augmented LLMs, prompted to solve open-domain questions (Lazaridou et al., 2023; Khattab et al., 2022; Trivedi et al., 2022a; Ram et al., 2023; Yoran et al., 2023).”
BackgroundLearning to break: Knowledge-enhanced reasoning in multi-agent debate system
Wang, H., Du, X., Yu, W., Chen, Q., Zhu, K., Chu, Z., Yan, L., & Guan, Y. (2025) · Neurocomputing · doi:10.1016/j.neucom.2024.129063 · Cited by 36
“Additionally, introducing exter-nal knowledge relevant to the query via prompts can improve the model’s reasoning capabilities(Shi et al., 2023; Ram et al., 2023).”
(2023) · doi:10.18653/v1/2023.emnlp-main.364 · Cited by 38
Baek, J., Jauhar, S. K., Cucerzan, S., & Hwang, S. J. (2025) · Proceedings of the 2025 Conference of the Nations of the Americas Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) · doi:10.18653/v1/2025.naacl-long.342 · Cited by 46
Synthesizing scientific literature with retrieval-augmented language models
Asai, A., He, J., Shao, R., Shi, W., Singh, A., Chang, J. C., Lo, K., Soldaini, L., Feldman, S., D’Arcy, M., et al. (2026) · Nature · doi:10.1038/s41586-025-10072-4 · Cited by 38
“5,35), a generator LM takes in the original input x and top N retrieved passages P and generates the output y 0 .”
Enhancing Conversational Search: Large Language Model-Aided Informative Query Rewriting
Ye, F., Fang, M., Li, S., & Yılmaz, E. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.398 · Cited by 147
Rasool, Z., Kurniawan, S., Balugo, S., Barnett, S., Vasa, R., Chesser, C., Hampstead, B. M., Belleville, S., Mouzakis, K., & Bahar-Fuchs, A. (2024) · Natural Language Processing Journal · doi:10.1016/j.nlp.2024.100083 · Cited by 34
Knowledge-Enhanced Dual-Stream Zero-Shot Composed Image Retrieval
Suo, Y., Ma, F., Zhu, L., & Yang, Y. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02545 · Cited by 85
“With the rise of Large Language Models, knowledge-enhanced methods are used for comprehending long context and improving generation quality [25, 31, 47, 60, 62].”
MethodXu, K., Zhang, K., Li, J., Huang, W. D., & Wang, Y. (2024) · Electronics · doi:10.3390/electronics14010047 · Cited by 51
Xu, K., Zhang, K., Li, J., Huang, W., & Wang, Y. (2024) · doi:10.20944/preprints202411.1648.v1 · Cited by 28
Wang, Z., Liu, Z., Lu, J. W. Z., & Lu, J. H. (2025) · Journal of Building Engineering · doi:10.1016/j.jobe.2025.112189 · Cited by 48
RA-DIT: Retrieval-Augmented Dual Instruction Tuning
Lin, X. V., Chen, X., Chen, M., Shi, W., Lomeli, M., James, R., Rodriguez, P., Kahn, J., Szilvasy, G., Lewis, M., et al. (2023) · arXiv · doi:10.48550/arxiv.2310.01352 · Cited by 26
How Do Large Language Models Capture the Ever-changing World Knowledge? A Review of Recent Advances
Zhang, Z., Fang, M., Chen, L., Namazi‐Rad, M., & Wang, Y.-X. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.516 · Cited by 113
Enhancing Question Answering for Enterprise Knowledge Bases using Large Language Models
Jiang, F., Qin, C., Yao, K., Fang, C., Zhuang, F., Zhu, H., & Xiong, H. (2024) · Lecture notes in computer science · doi:10.1007/978-981-97-5562-2_18 · Cited by 38
Fayyazi, R., Taghdimi, R., & Yang, S. J. (2024) · Annual Computer Security Applications Conference Workshops (ACSAC Workshops) · doi:10.1109/acsacw65225.2024.00036 · Cited by 45
“We present preliminary results showing that the use of generic prompts seemingly provide more informative responses vs. the use of specific prompts.”
Fayyazi, R., Taghdimi, R., & Yang, S. J. (2024) · arXiv · doi:10.48550/arxiv.2401.00280 · Cited by 25
“There have been works that used RAG in NLP tasks (Borgeaud et al. 2022; Mallen et al. 2023; Ram et al. 2023; Al Ghadban et al. 2023).”
MethodRetrieval-Augmented Egocentric Video Captioning
Xu, J., Huang, Y., Hou, J., Chen, G., Zhang, Y., Feng, R., & Xie, W. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01284 · Cited by 92
“Retrieval-augmented language models in the NLP community aim at retrieving ex-ternal knowledge to enhance performance in various NLP tasks [4, 12, 22, 36, 53].”
BackgroundUniIR: Training and Benchmarking Universal Multimodal Information Retrievers
Wei, C., Chen, Y., Chen, H., Hu, H., Zhang, G., Fu, J., Ritter, A., & Chen, W. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73021-4_23 · Cited by 250
TCRA-LLM: Token Compression Retrieval Augmented Large Language Model for Inference Cost Reduction
Liu, J., Li, L., Xiang, T., Wang, B., & Qian, Y. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.655 · Cited by 70
Li, X., Zhou, Y., & Dou, Z. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i8.28714 · Cited by 63
Retrieval-Augmented Egocentric Video Captioning
Xu, J., Huang, Y., Hou, J., Chen, G., Zhang, Y., Feng, R., & Xie, W. (2024) · arXiv · doi:10.48550/arxiv.2401.00789 · Cited by 24
Joffe, I., Felobes, G., Elgouhari, Y., Talebi-Kalaleh, M., Mei, Q., & Chui, Y. H. (2025) · Journal of Computing in Civil Engineering · doi:10.1061/jccee5.cpeng-6037 · Cited by 33
Memolet: Reifying the Reuse of User-AI Conversational Memories
Yen, R., & Zhao, J. (2024) · Proceedings of the 37th Annual ACM Symposium on User Interface Software and Technology · doi:10.1145/3654777.3676388 · Cited by 22
“As users engage in more conversations and share additional details, they may discover valuable contextual information scattered at multiple previous conversations that can enrich their current conversation with the AI [30, 50, 67, 74].”
Liu, R., Zou, Z., Chen, S., Liu, Y., & Wan, J. (2025) · Materials Today Energy · doi:10.1016/j.mtener.2025.101818 · Cited by 25
Budakoglu, G., & Emekçi, H. (2025) · IEEE Access · doi:10.1109/access.2025.3542334 · Cited by 24
Leng, Y., Zhong, Y., Gu, Z., Li, P., Cui, H., Li, X., Liu, Y., & Wan, J. (2025) · ACS Materials Letters · doi:10.1021/acsmaterialslett.4c02674 · Cited by 31
DoLa: Decoding by Contrasting Layers Improves Factuality in Large Language Models
Chuang, Y.-S., Xie, Y., Luo, H., Kim, Y., Glass, J., & He, P. (2023) · arXiv · doi:10.48550/arxiv.2309.03883 · Cited by 29
“3) Not Grounding on External Knowledge: Our method relies solely on the model’s internal knowledge and does not use external retrieval modules like some retrieval augmented LMs do (Izacard et al., 2022; Borgeaud et al., 2022; Ram et al., 2023).”
MethodShusterman, R., Waters, A. C., O’Neill, S. K., Bangs, M., Luu, P., & Tucker, D. M. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01516-2 · Cited by 32
“Early work focused on single-hop queries 26,27 , involving retrieving a relevant document and integrating this into Question-and-Answer models.”
Karakurt, E., & Akbulut, A. (2025) · Applied Sciences · doi:10.3390/app16010368 · Cited by 58
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
Gutiérrez, B. J., Shu, Y., Gu, Y., Yasunaga, M., & Su, Y. (2024) · arXiv · doi:10.48550/arxiv.2405.14831 · Cited by 152
“Due in part to its ease of use and the limitations of other techniques such as model editing [35], retrieval-augmented generation (RAG) has become the de facto solution for long-term memory in LLMs, allowing users to present new knowledge to a static model [28, 33, 50].”
Large Language Models for Clinical Text Cleansing Enhance Medical Concept Normalization
Abdulnazar, A., Roller, R., Schulz, S., & Kreuzthaler, M. (2024) · IEEE Access · doi:10.1109/access.2024.3472500 · Cited by 35
“Re-ranking aims to present the most pertinent information to the LLM, thereby improving the quality and relevance of the generated responses [62].”
BackgroundSun, L., Qin, T., Hu, A., Zhang, J., Lin, S., Chen, J., Ali, M., & Prpa, M. (2025) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3706598.3713445 · Cited by 60
Deng, C., Duan, Y., Jin, X., Chang, H., Tian, Y., Liu, H., Wang, Y., Gao, K., Zou, H. P., Jin, Y., et al. (2025) · AI and Ethics · doi:10.1007/s43681-025-00797-3 · Cited by 83
“Most existing mitigation strategies can be categorized into data-centric approaches [3, 96, 147, 216, 248, 359] and model-cen-tric approaches [158, 169, 231, 293].”
Search Augmented Instruction Learning
Luo, H., Zhang, T., Chuang, Y.-S., Gong, Y., Kim, Y., Wu, X., Meng, H. M. L., & Glass, J. R. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.242 · Cited by 56
Broadening the View: Demonstration-augmented Prompt Learning for Conversational Recommendation
Dao, H. Q., Deng, Y., Le, D. D., & Liao, L. (2024) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3626772.3657755 · Cited by 45
“Wang et al. [47] and Ram et al. [38] prepended retrieved segments of texts to the current input of an LM model.”
MethodAdjust to reality: LLM-driven test-time semantic adjustment for zero-shot fault diagnosis
Zhao, J., Yue, J., Zhao, C., & Chen, C. (2025) · Control Engineering Practice · doi:10.1016/j.conengprac.2025.106406 · Cited by 21
Huang, J., Wang, M., Cui, Y., Liu, J., Chen, L., Wang, T., Li, H., & Wu, J. (2024) · Applied Sciences · doi:10.3390/app142311014 · Cited by 17
Improving LLM Reliability with RAG in Religious Question-Answering: MufassirQASPreprint
Alan, A. Y., Karaarslan, E., & Aydın, Ö. (2024) · SSRN Electronic Journal · doi:10.2139/ssrn.4707470 · Cited by 37
RAGO: Systematic Performance Optimization for Retrieval-Augmented Generation Serving
Jiang, W., Subramanian, S., Graves, C., Alonso, G., Yazdanbakhsh, A., & Dadu, V. (2025) · Proceedings - International Symposium on Computer Architecture/Proceedings · doi:10.1145/3695053.3731093 · Cited by 54
Cai, T., Tan, Z., Song, X., Sun, T., Jiang, J., Xu, Y., Zhang, Y., & Gu, J. (2024) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3637528.3672065 · Cited by 43
“Different from these work, we treat the retrieval step as a black box and focus on improving the generation quality given the query and retrieved passages.”
Adaptive Control of Retrieval-Augmented Generation for Large Language Models Through Reflective Tags
Yao, C., & Fujita, S. (2024) · Electronics · doi:10.3390/electronics13234643 · Cited by 24
“For example, Ram et al. [12] considered a simple alternative called an in-context retrieval-augmented language model (RALM), which incorporates documents containing additional information or background knowledge before input without modifying the LM architecture or requiring further training.”
Sun, S., Zhang, K., Li, J., Yu, M., Hou, K., Wang, Y., & Cheng, X. (2025) · Information Processing & Management · doi:10.1016/j.ipm.2025.104147 · Cited by 19
VDocRAG: Retrieval-Augmented Generation over Visually-Rich Documents
Tanaka, R., Iki, T., Hasegawa, T., Nishida, K., Saito, K., & Suzuki, J. (2025) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52734.2025.02312 · Cited by 119
FT2Ra: A Fine-Tuning-Inspired Approach to Retrieval-Augmented Code Completion
Guo, Q., Li, X., Xie, X., Liu, S., Tang, Z. J., Feng, R., Wang, J., Ge, J., & Bu, L. (2024) · ACM SIGSOFT International Symposium on Software Testing and Analysis (ISSTA) · doi:10.1145/3650212.3652130 · Cited by 28
PathOCL: Path-Based Prompt Augmentation for OCL Generation with GPT-4
Abukhalaf, S., Hamdaqa, M., & Khomh, F. (2024) · IEEE/ACM International Conference on AI Foundation Models and Software Engineering (FORGE) · doi:10.1145/3650105.3652290 · Cited by 22
Retrieval Augmented Recipe Generation
Liu, G., Yin, H., Zhu, B., Chen, J., Ngo, C., & Jiang, Y. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00244 · Cited by 33
“On the one hand, we propose Stochastic Diversi-fied Retrieval Augmentation (SDRA) to provide a rich and diverse set of retrieved recipes as references, which could provide relevant knowledge for the generation to reduce hallucination [24, 29, 52].”
Metadata
- Authors
- Ram, O., Levine, Y., Dalmedigos, I., Muhlgay, D., Shashua, A., Leyton-Brown, K., & Shoham, Y.
- Affiliations
- AI21 Labs, Israel. orir@ai21.com
- AI21 Labs, Israel. yoavl@ai21.com
- AI21 Labs, Israel. itayd@ai21.com
- AI21 Labs, Israel. dorm@ai21.com
- AI21 Labs, Israel. amnons@ai21.com
- AI21 Labs, Israel. kevinlb@ai21.com
- AI21 Labs, Israel. yoavs@ai21.com
- Corresponding author
- Ram, Ori
- Levine, Yoav
- Dalmedigos, Itay
- Muhlgay, Dor
- Shashua, Amnon
- Shoham, Yoav
- Venue
- Transactions of the Association for Computational Linguistics
- Publisher
- MIT Press
- Published
- 2023
- Volume
- 11
- Pages
- 1316-1331
- ISSN
- 2307-387X (ISSN-L)
- OpenAlex
- W4388778348
- Cited by
- 449
- References
- 55
- Citations by year
- 2026: 160 · 2025: 189 · 2024: 80 · 2023: 20
- FWCI
- 42.21
- Type
- journal article
- Language
- en
- Open access
- diamond
- doi.org
- Locations
- Transactions of the Association for Computational Linguistics (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion, public-domain)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University) (public-domain)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Information Systems › Information Retrieval and Search Behavior
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- retrieval-augmented language models, document retrieval, document ranking, factual accuracy, source attribution, pre-trained language models, large language models
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
