

The DOI matches its Crossref record; 15 of the 15 references it cites were found in a registry or an index.
Three assays for in-solution enrichment of ancient human DNA at more than a million SNPs
Published version of a preprint
Abstract
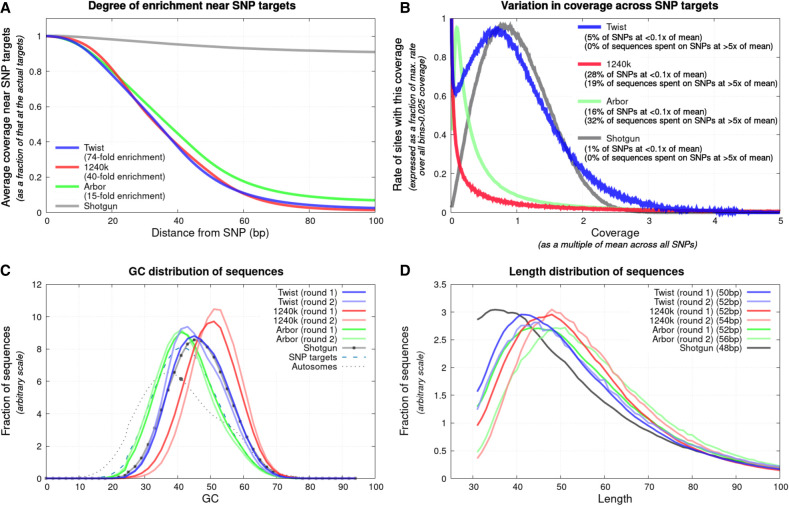
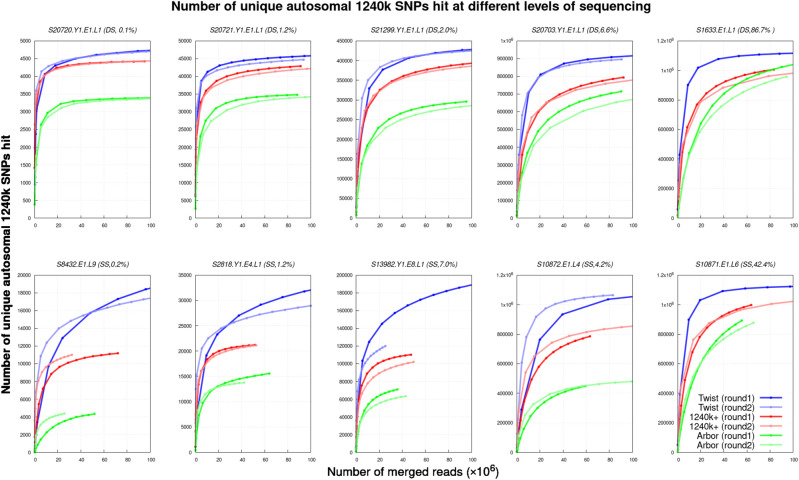
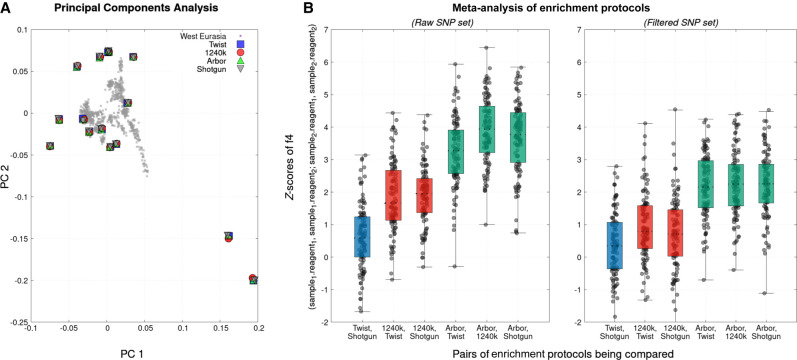
The strategy of in-solution enrichment for hundreds of thousands of single-nucleotide polymorphisms (SNPs) has been used to analyze >70% of individuals with genome-scale ancient DNA published to date. This approach makes it economical to study ancient samples with low proportions of human DNA and increases the rate of conversion of sampled remains into interpretable data. So far, nearly all such data have been generated using a set of bait sequences targeting about 1.24 million SNPs (the “1240k reagent”), but synthesis of the reagent has been cost-effective for only a few laboratories. In 2021, two companies, Daicel Arbor Biosciences and Twist Bioscience, made available assays that target the same core set of SNPs along with supplementary content. We test all three assays on a common set of 27 ancient DNA libraries and show that all three are effective at enriching many hundreds of thousands of SNPs. For all assays, one round of enrichment produces data that are as useful as two. In our testing, the “Twist Ancient DNA” assay produces the highest coverages, greatest uniformity on targeted positions, and almost no bias toward enriching one allele more than another relative to shotgun sequencing. We also identify hundreds of thousands of targeted SNPs for which there is minimal allelic bias when comparing 1240k data to either shotgun or Twist data. This facilitates coanalysis of the large data sets that have been generated using 1240k and Twist capture, as well as shotgun sequencing approaches.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The combined aDNA data from the libraries gave a read depth of ~3.9×, enabling us to call a sufficient number of 1,240 K SNPs (35) for CKZ002 (Table 1).”
From Genomes of the Golden Horde elites and their implications for the rulers of the Mongol Empire (2026) · cites this paper as [35]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
A global reference for human genetic variation
The 1000 Genomes Project Consortium, authors, C., Auton, A., Abecasis, G. R., Steering committee, Altshuler, D. M., Durbin, R. M., Abecasis, G. R., Bentley, D. R., Chakravarti, A., et al. (2015) · Nature · doi:10.1038/nature15393 · Cited by 18,247
Ancient Admixture in Human History
Patterson, N., Moorjani, P., Luo, Y., Mallick, S., Rohland, N., Zhan, Y., Genschoreck, T., Webster, T., & Reich, D. (2012) · Genetics · doi:10.1534/genetics.112.145037 · Cited by 2,848
Self-citationMassive migration from the steppe was a source for Indo-European languages in Europe
Haak, W., Lazaridis, I., Patterson, N., Rohland, N., Mallick, S., Llamas, B., Brandt, G., Nordenfelt, S., Harney, E., Stewardson, K., et al. (2015) · Nature · doi:10.1038/nature14317 · Cited by 1,940
Self-citationGenome-wide patterns of selection in 230 ancient Eurasians
Mathieson, I., Lazaridis, I., Rohland, N., Mallick, S., Patterson, N., Roodenberg, S. A., Harney, E., Stewardson, K., Fernandes, D., Novak, M., et al. (2015) · Nature · doi:10.1038/nature16152 · Cited by 1,515
Self-citationDabney, J., Knapp, M., Glocke, I., Gansauge, M.-T., Weihmann, A., Nickel, B., Valdiosera, C., García, N., Pääbo, S., Arsuaga, J.-L., et al. (2013) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1314445110 · Cited by 1,443
Gnirke, A., Melnikov, A., Maguire, J., Rogov, P., LeProust, E. M., Brockman, W., Fennell, T., Giannoukos, G., Fisher, S., Russ, C., et al. (2009) · Nature Biotechnology · doi:10.1038/nbt.1523 · Cited by 1,433
Insights into human genetic variation and population history from 929 diverse genomes
Bergström, A., McCarthy, S. A., Hui, R., Almarri, M. A., Ayub, Q., Danecek, P., Chen, Y., Felkel, S., Hallast, P., Kamm, J., et al. (2020) · Science · doi:10.1126/science.aay5012 · Cited by 1,020
Self-citationGenomic insights into the origin of farming in the ancient Near East
Lazaridis, I., Nadel, D., Rollefson, G., Merrett, D. C., Rohland, N., Mallick, S., Fernandes, D., Novak, M., Gamarra, B., Sirak, K., et al. (2016) · Nature · doi:10.1038/nature19310 · Cited by 955 · cited 2×
“L1 DS 94.90% 789,102 675,731 1,074,256 (Lazaridis et al. 2016)a S2520.”
InfluentialSelf-citationAn early modern human from Romania with a recent Neanderthal ancestor
Fu, Q., Hajdinjak, M., Moldovan, O. T., Constantin, S., Mallick, S., Skoglund, P., Patterson, N., Rohland, N., Lazaridis, I., Nickel, B., et al. (2015) · Nature · doi:10.1038/nature14558 · Cited by 802
Self-citationDNA analysis of an early modern human from Tianyuan Cave, China
Fu, Q., Meyer, M., Gao, X., Stenzel, U., Burbano, H. A., Kelso, J., & Pääbo, S. (2013) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1221359110 · Cited by 608 · cited 6×
“The baits were then cleaved, amplified, and biotinylated in preparation for enrichment (Fu et al. 2013).”
BackgroundMethodInfluentialPartial uracil–DNA–glycosylase treatment for screening of ancient DNA
Rohland, N., Harney, E., Mallick, S., Nordenfelt, S., & Reich, D. (2015) · Philosophical Transactions of the Royal Society B: Biological Sciences · doi:10.1098/rstb.2013.0624 · Cited by 572
Self-citationThe genomic history of the Iberian Peninsula over the past 8000 years
Olalde, I., Mallick, S., Patterson, N., Rohland, N., Villalba-Mouco, V., Silva, M., Dulias, K., Edwards, C. J., Gandini, F., Pala, M., et al. (2019) · Science · doi:10.1126/science.aav4040 · Cited by 552
Self-citationPatterns of coding variation in the complete exomes of three Neandertals
Castellano, S., Parra, G., Sánchez-Quinto, F. A., Racimo, F., Kuhlwilm, M., Kircher, M., Sawyer, S., Fu, Q., Heinze, A., Nickel, B., et al. (2014) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1405138111 · Cited by 247
Günther, T., & Nettelblad, C. (2019) · PLOS Genetics · doi:10.1371/journal.pgen.1008302 · Cited by 228
Martiniano, R., Garrison, E., Jones, E. R., Manica, A., & Durbin, R. (2020) · Genome Biology · doi:10.1186/s13059-020-02160-7 · Cited by 128 · cited 1×
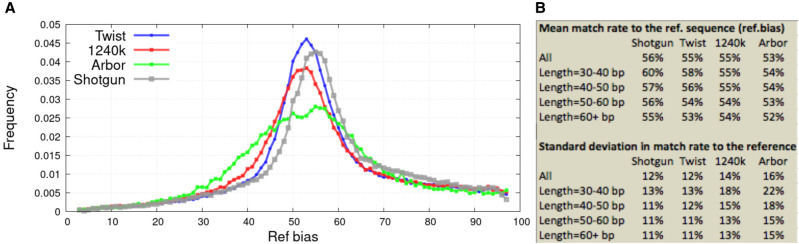
“This reflects the fact that when sequences perfectly match the reference genome sequence, they will have a higher probability of aligning with high mapping quality and thus of passing the mapping filters used to allow sequences into analysis (Günther and Nettelblad 2019; Martiniano et al. 2020).”
Method
Research works printed but not linked: 21
- 10.1126/science.1188046 · DOI
- 10.1016/j.ajhg.2013.10.002 · DOI
- 10.1038/s41586-019-1251-y · DOI
- 10.1038/s41586-021-04241-4 · DOI · Paper page
- 10.1038/s41596-020-0338-0 · DOI · Paper page
- 10.1038/s41467-020-15020-6 · DOI · Paper page
- 10.2144/000114320 · DOI · Paper page
- 10.1093/nar/gkz972 · DOI · Paper page
- 10.1093/bioinformatics/btp698 · DOI · Paper page
- 10.1093/bioinformatics/btp352 · DOI · Paper page
- 10.1038/s41586-020-1929-1 · DOI
- 10.1038/s41586-022-04430-9 · DOI
- 10.1371/journal.pone.0014004 · DOI
- 10.1038/nature25778 · DOI
- 10.1038/s41586-021-04287-4 · DOI
- 10.1038/s41596-018-0050-5 · DOI
- 10.1038/s41588-020-00756-0 · DOI
- 10.1038/s41588-019-0484-x · DOI · Paper page
- 10.1093/hmg/ddq333 · DOI
- 10.1038/s41588-019-0481-0 · DOI · Paper page
- 10.1038/s41588-020-00735-5 · DOI · Paper page
Cited by
Accurate detection of identity-by-descent segments in human ancient DNA
Ringbauer, H., Huang, Y., Akbari, A., Mallick, S., Olalde, I., Patterson, N., & Reich, D. (2024) · Nature Genetics · doi:10.1038/s41588-023-01582-w · Cited by 155
Self-citationGenomes of the Golden Horde elites and their implications for the rulers of the Mongol Empire
Askapuli, A., Kanzawa-Kiriyama, H., Kakuda, T., Kassenali, A., Yessen, S., Schamiloglu, U., Schrodi, S. J., Hawks, J., & Saitou, N. (2026) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2531003123 · Cited by 5
Metadata
- Authors
- Rohland, N., Mallick, S., Mah, M., Maier, R., Patterson, N., & Reich, D.
- Venue
- Genome Research
- Publisher
- Cold Spring Harbor Laboratory
- Published
- 2022-11
- Volume
- 32
- Issue
- 11-12
- Pages
- 2068-2078
- ISSN
- 1088-9051
- 1549-5469
- PMC
- PMC9808625
- Cited by
- 163
- References
- 15
- Language
- en
- Funders
- National Institutes of Health (HG012287)
- Allen Discovery Center program
- Paul G. Allen Frontiers Group
- Paul G. Allen Family Foundation
- John Templeton Foundation (61220)
- Howard Hughes Medical Institute
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
