

Image Super-Resolution Via Iterative Refinement
Open accessThe DOI matches its Crossref record; 81 of the 85 references it cites were found in a registry or an index.
Abstract
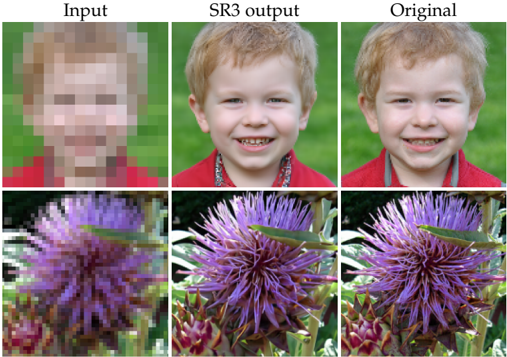
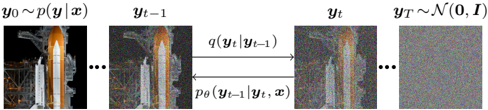
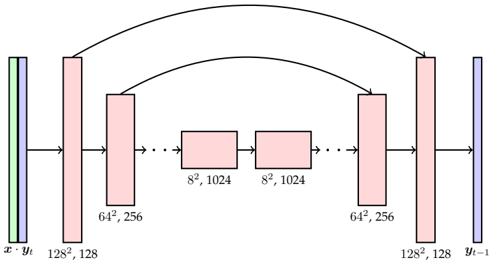
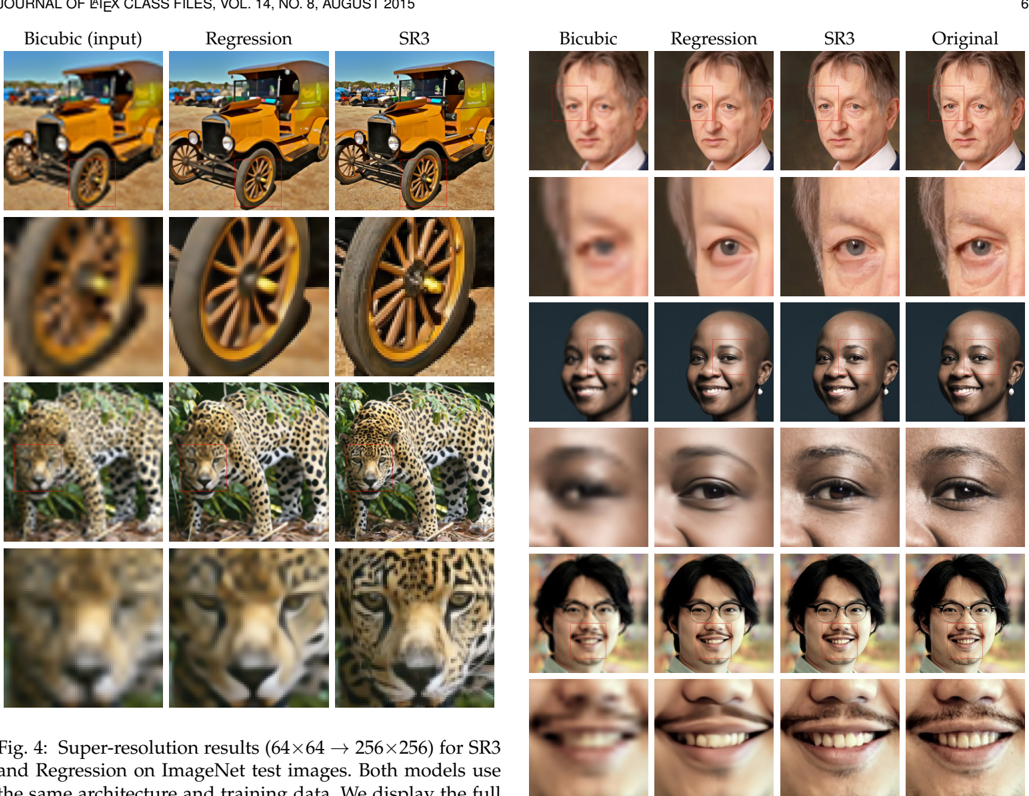
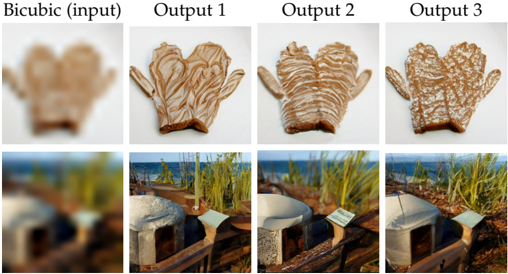
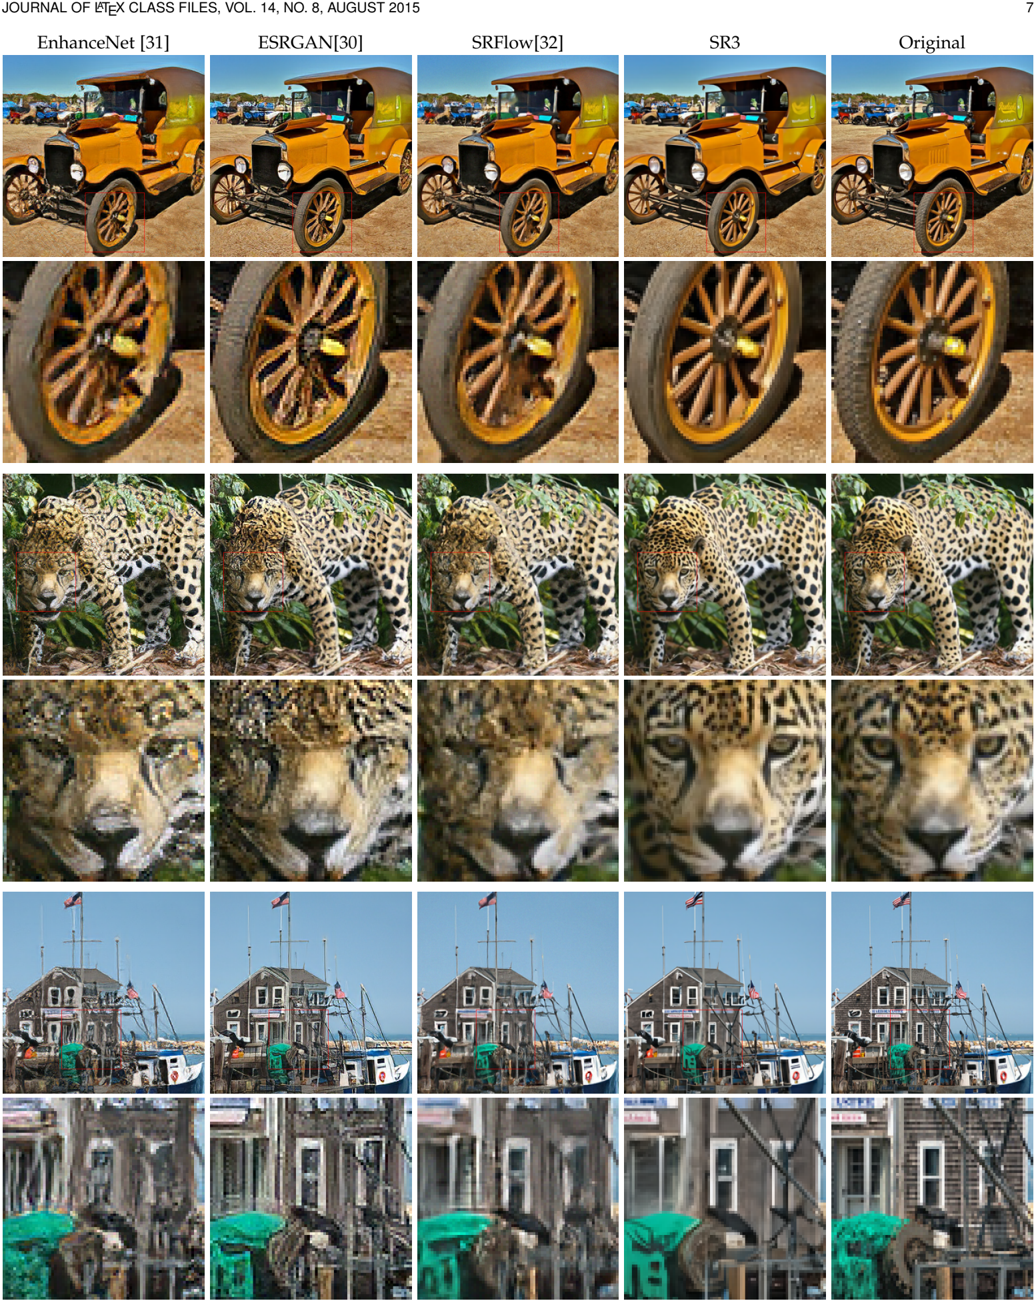
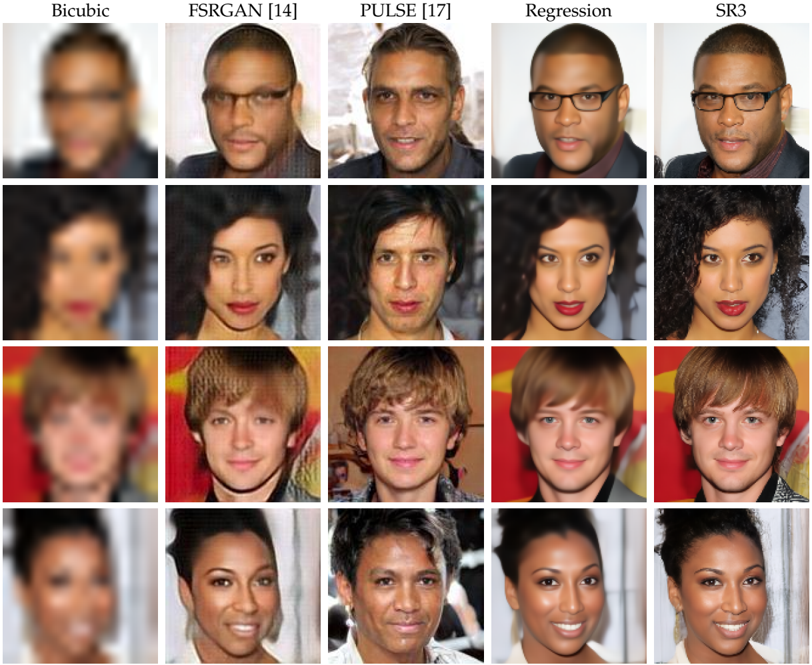
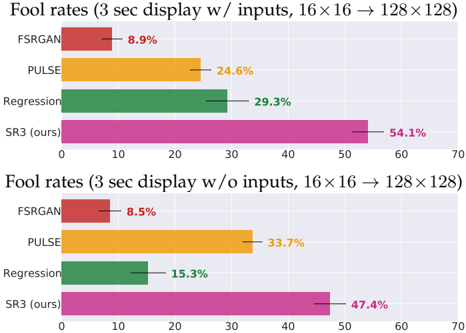
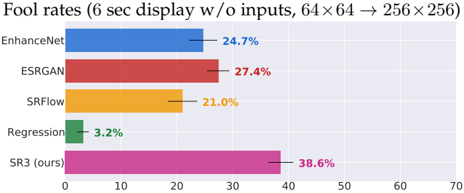
We present SR3, an approach to image Super-Resolution via Repeated Refinement. SR3 adapts denoising diffusion probabilistic models (Ho et al. 2020), (Sohl-Dickstein et al. 2015) to image-to-image translation, and performs super-resolution through a stochastic iterative denoising process. Output images are initialized with pure Gaussian noise and iteratively refined using a U-Net architecture that is trained on denoising at various noise levels, conditioned on a low-resolution input image. SR3 exhibits strong performance on super-resolution tasks at different magnification factors, on faces and natural images. We conduct human evaluation on a standard 8× face super-resolution task on CelebA-HQ for which SR3 achieves a fool rate close to 50%, suggesting photo-realistic outputs, while GAN baselines do not exceed a fool rate of 34%. We evaluate SR3 on a 4× super-resolution task on ImageNet, where SR3 outperforms baselines in human evaluation and classification accuracy of a ResNet-50 classifier trained on high-resolution images. We further show the effectiveness of SR3 in cascaded image generation, where a generative model is chained with super-resolution models to synthesize high-resolution images with competitive FID scores on the class-conditional 256×256 ImageNet generation challenge.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures





Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Both the SR3 and CDM directly apply the diffusion process to input images, which leads to larger evaluation steps.”
From Diffusion Models: A Comprehensive Survey of Methods and Applications (2024) · cites this paper as [200]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Low-light face videos suffer from severe noise and detail loss, limiting their use in surveillance and photography applications.”
From Temporally consistent low-light face video enhancement via video-to-video conditional diffusion (2026) · cites this paper as [5]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“This greatly improves FID on ImageNet 256×256, but does not reach the same performance as state-of-the-art models like BigGAN-deep [43, 53], as seen in Table 5.”
From Diffusion Models Beat GANs on Image Synthesis (2021) · cites this paper as [53]
Experimental — accuracy not yet measuredIn the citing paper
“Super-Resolution via Repeated Refinement (SR3) [200] uses DDPM to enable conditional image generation.”
From Diffusion Models: A Comprehensive Survey of Methods and Applications (2024) · cites this paper as [200]
In the citing paper
“SR3 conducts super-resolution through a stochastic, iterative denoising process.”
From Diffusion Models: A Comprehensive Survey of Methods and Applications (2024) · cites this paper as [200]
2 more claims about this paper
Create a free account to see every claim other papers make about this one.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474 · cited 1×
“Then, we report classification accuracy of a pre-trained ResNet50 [65] model.”
MethodVaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
Exploiting Generative AI to Scale up Intelligent Tutoring Systems
Jakubův, J., Chvalovský, K., Goertzel, Z., Kaliszyk, C., Olšák, M., Piotrowski, B., Schulz, S., Suda, M., & Urban, J. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,658
Image quality assessment: from error visibility to structural similarity
Wang, Z., Bovik, A. C., Sheikh, H. R., & Simoncelli, E. P. (2004) · IEEE Transactions on Image Processing · doi:10.1109/tip.2003.819861 · Cited by 57,892 · cited 10×
“Table 2 shows the PSNR, SSIM [63] and Consistency scores for 16 16 !”
BackgroundInfluentialImageNet Large Scale Visual Recognition Challenge
Russakovsky, O., Deng, J., Su, H., Krause, J., Satheesh, S., Ma, S., Huang, Z., Karpathy, A., Khosla, A., Bernstein, M., et al. (2015) · International Journal of Computer Vision · doi:10.1007/s11263-015-0816-y · Cited by 39,380 · cited 2×
“on ImageNet 1K [62] and use the dev split for evaluation.”
BackgroundMethodAuto-Encoding Variational Bayes
Kingma, D. P., & Welling, M. (2013) · arXiv · doi:10.48550/arxiv.1312.6114 · Cited by 20,067 · cited 2×
“VAEs [7], [46] offer fast sampling, but tend to underperform GANs”
BackgroundGenerative adversarial networks
Goodfellow, I., Pouget-Abadie, J., Mirza, M., Xu, B., Warde-Farley, D., Ozair, S., Courville, A., & Bengio, Y. (2020) · Communications of the ACM · doi:10.1145/3422622 · Cited by 18,384
Sequence to Sequence Learning with Neural Networks
Sutskever, I., Vinyals, O., & Le, Q. V. (2014) · arXiv · doi:10.48550/arxiv.1409.3215 · Cited by 17,766
Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network
Ledig, C., Theis, L., Huszar, F., Caballero, J., Cunningham, A., Acosta, A., Aitken, A., Tejani, A., Totz, J., Wang, Z., et al. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.19 · Cited by 12,696
Research works printed but not linked: 2
- 11. I. J. Goodfellow, J. Pouget-Abadie, M. Mirza, B. Xu, D. Warde- Farley, S. Ozair, A. Courville, and Y. Bengio, "Generative Adver- sarial Networks," NIPS, 2014.
- 46. D. J. Rezende, S. Mohamed, and D. Wierstra, "Stochastic back- propagation and approximate inference in deep generative mod- els," in ICML, 2014, pp. 1278-1286.
Cited by
Items 601–700 of 1,005
ZS-SRT: An efficient zero-shot super-resolution training method for Neural Radiance Fields
Feng, X. Z., He, Y., Wang, Y., Wang, C., Kuang, Z., Ding, J., Qin, F., Yu, J., & Fan, J. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.127714 · Cited by 22
“Besides, the recent generative model is also exploited for image super-resolution by learning a mapping function from low resolution (LR) image to high resolution (HR) image [38–41].”
BackgroundHein, D., Holmin, S., Szczykutowicz, T. P., Maltz, J. S., Danielsson, M. E., Wang, G., & Persson, M. (2024) · IEEE Transactions on Radiation and Plasma Medical Sciences · doi:10.1109/trpms.2024.3410092 · Cited by 23
“This has been used with great success empirically [51], [52], and [48] showed mathematically that this “trick” has a solid Algorithm 1: Proposed PPFM Training.”
MethodZhu, Z., Wang, J., Qin, Y., Sun, D., Jampani, V., & Wang, X. (2024) · International Conference on 3D Vision (3DV) · doi:10.1109/3dv62453.2024.00028 · Cited by 22
“Inspired by these results, the conditional diffusion model has been widely applied in text-to-image generation [17, 53, 60, 66, 68, 72], image super resolution [39, 60, 65] and image-to-image translation tasks [6, 15, 64, 88].”
MethodDiffPlate: A Diffusion Model for Super-Resolution of License Plate Images
AlHalawani, S., Benjdira, B., Ammar, A., Koubâa, A., & Ali, A. M. (2024) · Electronics · doi:10.3390/electronics13132670 · Cited by 19
“Drawing from Saharia et al. [14], we adopted a fixed learning rate of 0.0002, incorporating a linear warm-up schedule via the Adam Optimizer.”
BackgroundMethodInfluentialReplication in Visual Diffusion Models: A Survey and Outlook
Wang, W., Sun, Y., Yang, Z., Hu, Z., Tan, Z., & Yang, Y. (2026) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2026.3713990 · Cited by 20
“In this section, we provide an overview of visual diffusion models and formally define the replication phenomenon.”
Towards Robust Pansharpening: A Large-Scale High-Resolution Multi-Scene Dataset and Novel Approach
Wang, S., Zou, X., Li, K., Xing, J., Cao, T., & Tao, P. (2024) · Remote Sensing · doi:10.3390/rs16162899 · Cited by 17
WeaFU: Weather-Informed Image Blind Restoration via Multi-Weather Distribution Diffusion
Cheng, B., Li, J., Shi, J., Fang, Y., Zhang, G., Chen, Y., Zeng, T., & Li, Z. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3450971 · Cited by 18
“For instance, [26] introduced SR3, an image super-resolution method based on DDPMs, employing stochastic iterative denoising and U-Net architecture.”
Diffusion-FOF: Single-View Clothed Human Reconstruction via Diffusion-Based Fourier Occupancy Field
Li, Y., Luo, F., & Xiao, C. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00910 · Cited by 20
“[26, 33, 44].”
MethodLaDiffGAN: Training GANs with Diffusion Supervision in Latent Spaces
Liu, X., Zeng, B., Gao, S., Li, S., Feng, Y., Li, H., Liu, B., Liu, J., & Zhang, B. (2024) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw63382.2024.00118 · Cited by 23
Liu, Y., Liu, A., & Gao, S. L. (2024) · Chemometrics and Intelligent Laboratory Systems · doi:10.1016/j.chemolab.2024.105269 · Cited by 18
MaskDiffusion: Boosting Text-to-Image Consistency with Conditional Mask
Zhou, Y., Zhou, D., Wang, Y., Feng, J., & Hou, Q. (2024) · International Journal of Computer Vision · doi:10.1007/s11263-024-02294-2 · Cited by 22
“…based on cross attention [34] were proposed, conditional generation under diverse types of guidance becomes practical, benefiting to numerous related tasks, including super resolution [37], inpainting [23, 43], layout-to-image generation [48, 8] and text-to-image (T2I) generation [36, 32, 1].”
Hypergraph neural network for remote sensing hyperspectral image super-resolution
Chen, C., Wang, Y., Zhang, Y., Zhang, N., Feng, H., & Xu, D. (2025) · Knowledge-Based Systems · doi:10.1016/j.knosys.2025.113755 · Cited by 23
Distribution-Aware Data Expansion with Diffusion Models
Zhu, H., Yang, L., Yong, J., Yin, H., Jiang, J., Xiao, M., Zhang, W., & Wang, B. (2024) · neural information processing systems · doi:10.52202/079017-3264 · Cited by 29
Wei, H., Liu, S., Yuan, C., & Zhang, L. (2025) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51701.2025.01732 · Cited by 29
Deep Model-Based Super-Resolution with Non-uniform Blur
Laroche, C., Almansa, A., & Tassano, M. (2023) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv56688.2023.00184 · Cited by 24
“producing extremely high-quality results for very large (×16) scale factors, as long as blur is uniform and small [48].”
BackgroundDeblending Galaxies with Generative Adversarial Networks
Hemmati, S., Huff, E., Nayyeri, H., Ferté, A., Melchior, P., Mobasher, B., Rhodes, J. D., Shahidi, A., & Teplitz, H. I. (2022) · The Astrophysical Journal · doi:10.3847/1538-4357/aca1b8 · Cited by 19
Liu, F., & Huang, W. (2023) · Biomedical Optics Express · doi:10.1364/boe.506205 · Cited by 18
“…ϵ θ takes the low-quality image y , the intermediate variable x t , and the time step t as input to predict the noise map n t and the refined vessel mask v t as follows: ( − ) We employ a UNet architecture similar to the denoiser ϵ θ of [10]. ϵ by marginalizing the Gaussian diffusion process.”
BackgroundMethodQuasi-Taylor Samplers for Diffusion Generative Models based on Ideal DerivativesPreprint
Tachibana, H., Go, M., Inahara, M., Katayama, Y., & Watanabe, Y. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2112.13339 · Cited by 18
“, 2021), image superresoution (Saharia et al., 2021; Ho et al., 2021), image translation (Sasaki et al.”
BackgroundInfluentialDM-FNet: Unified Multimodal Medical Image Fusion via Diffusion Process-Trained Encoder-Decoder
He, D., Li, W., Wang, G., Huang, Y., & Liu, S. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3613156 · Cited by 21
“Thisdesignenablesthenetworktoadaptto differentdatasetswithoutspecificfusionrules.”
Deep-Learning-Empowered Super Resolution: A Comprehensive Survey and Future Prospects
Zhang, L., Li, A., Hou, Q., Zhu, C., & Eldar, Y. C. (2025) · Proceedings of the IEEE · doi:10.1109/jproc.2025.3613233 · Cited by 23
“SR3 [37] established the baseline approach by combining DDPMs with U-Net architectures, demonstrating superior performance over GANs through iterative multilevel refinement.”
Neural Knitworks: Patched neural implicit representation networks
Czerkawski, M., Cardona, J., Atkinson, R. C., Michie, C., Andonović, I., Clemente, C., & Tachtatzis, C. (2024) · Pattern Recognition · doi:10.1016/j.patcog.2024.110378 · Cited by 18
Chen, L., Zhou, L., Li, L., & Luo, M. (2023) · Smart Materials and Structures · doi:10.1088/1361-665x/acc624 · Cited by 16
Berger, G., Dhingra, M., Mercier, A., Savani, Y., Panchal, S., & Porikli, F. (2023) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw59228.2023.00212 · Cited by 20
“In recent years, deep learning (DL) based approaches have become increasingly popular in the field [6, 10, 11, 20, 24, 27, 28, 34, 35], producing impressive results compared to interpolation-based techniques and hand-engineered heuristics (see Fig.”
BackgroundLi, G., Xing, W., Zhao, L., Lan, Z., Sun, J., Zhang, Z., Zhang, Q., Lin, H., & Lin, Z. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3611866 · Cited by 21
“Specifically, we explore the substitution of the stable diffusion model with SR3[43], IDM[9], and StableSR[49] for generating the reference image.”
MethodSuper-resolution reconstruction of LF NMR image based on DDPM for fruit non-destructive testing
Yang, Y., Yang, K., Zeng, S., Wang, L., Li, B., & Yang, Z. (2024) · Journal of Food Composition and Analysis · doi:10.1016/j.jfca.2024.106219 · Cited by 17
Suin, M., Nair, N. G., Lau, C. P., Patel, V. M., & Chellappa, R. (2024) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv57701.2024.00622 · Cited by 27
“Following [28]; the denoising UNet takes the degraded input as a conditional input during training.”
BackgroundMethodInfluentialSuper-resolution reconstruction of ultrasound image using a modified diffusion model
Liu, T., Han, S., Xie, L., Xing, W., Liu, C., Li, B., & Ta, D. (2024) · Physics in Medicine and Biology · doi:10.1088/1361-6560/ad4086 · Cited by 20
Enhancing Image Quality by Reducing Compression Artifacts Using Dynamic Window Swin Transformer
Ma, Z., Wang, Y., Tohidypour, H. R., Nasiopoulos, P., & Leung, V. C. M. (2024) · IEEE Journal on Emerging and Selected Topics in Circuits and Systems · doi:10.1109/jetcas.2024.3392868 · Cited by 17
“Image restoration is an important area of image processing that has many practical applications in fields such as medical imaging [1], [2], image super-resolution [3], [4] and compression artifacts reduction [5].”
BackgroundBiDiCOS: Camouflaged object segmentation via bilateral diffusion model
Jiang, X., Cai, W., Ding, Y., Wang, X., Hong, D., Di, X., & Gao, W. (2024) · Expert Systems with Applications · doi:10.1016/j.eswa.2024.124747 · Cited by 18
Synthesizing Multimodal Electronic Health Records via Predictive Diffusion Models
Zhong, Y., Wang, X., Wang, J., Zhang, X., Wang, Y., Huai, M., Xiao, C., & Ma, F. (2024) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3637528.3671836 · Cited by 23
“Forward Noise Addition Process works [16, 25, 26].”
Boosting Flow-based Generative Super-Resolution Models via Learned Prior
Tsao, L.-Y., Lo, Y.-C., Chang, C.-C., Chen, H., Tseng, R., Feng, C., & Lee, C. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02457 · Cited by 23
“To overcome this and synthe-size realistic HR images, various generative SR techniques have been proposed, including GAN-based [40, 58, 59, 71, 72, 79], AR-based [23], flow-based [34, 45, 50, 51, 67], and diffusion-based [43, 60] methods.”
MethodTowards More Accurate Diffusion Model Acceleration with a Timestep Tuner
Xia, M., Shen, Y., Lei, C., Zhou, Y., Zhao, D., Yi, R., Wang, W., & Liu, Y. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00548 · Cited by 30
“With rapid advances in recent studies, DPMs show great potential in various down-stream applications, including speech synthesis [2, 17], video synthesis [10], super-resolution [20, 32], conditional generation [3], and image-to-image translation [33, 36].”
BackgroundMethodImage Neural Field Diffusion Models
Chen, Y., Wang, O., Zhang, R., Shechtman, E., Wang, X., & Gharbi, M. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00765 · Cited by 31
“They were recently connected to score-based generative models [51–53] and have been greatly improved [16, 34] for architectures and other training details, achieving state-of-the-art results on both unconditional and conditional image synthesis [11, 17, 33, 42, 44].”
Automatic Controllable Colorization via Imagination
Cong, X., Wu, Y., Chen, Q., & Lei, C. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00252 · Cited by 27
“Image Diffusion Models address the image generation task by learning to perform progressive denoising [14, 24, 60, 62].”
BackgroundTELA: Text to Layer-Wise 3D Clothed Human Generation
Dong, J., Fang, Q., Huang, Z., Xu, X., Wang, J., Peng, S., & Dai, B. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72698-9_2 · Cited by 28
You Only Need One Step: Fast Super-Resolution with Stable Diffusion via Scale Distillation
Noroozi, M., Hadji, I., Martínez, B., Bulat, A., & Tzimiropoulos, G. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73397-0_9 · Cited by 30
Stochastic Super-resolution of Cosmological Simulations with Denoising Diffusion Models
Schanz, A., List, F., & Hahn, O. (2024) · The Open Journal of Astrophysics · doi:10.33232/001c.125902 · Cited by 20
Sui, J., Ma, X., Zhang, X., Pun, M.-O., & Wu, H. (2024) · IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing · doi:10.1109/jstars.2024.3504569 · Cited by 18
A Conditional Diffusion Model for Electrical Impedance Tomography Image Reconstruction
Shi, S., Kang, R., & Liatsis, P. (2025) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2025.3550245 · Cited by 24
“Moreover, DDPM with the use of additional inputs can be employed for conditional generation tasks, including image superresolution [23], image fusion [24], text-to-image generation [25], and image editing [26], encompassing inpainting, uncropping, etc. DDPM learns to generate a clean output from…”
DiffMC‐Gen: A Dual Denoising Diffusion Model for Multi‐Conditional Molecular Generation
Yang, Y., Gu, S., Liu, B., Gong, X., Lu, R., Qiu, J., Yao, X., & Liu, H. (2025) · Advanced Science · doi:10.1002/advs.202417726 · Cited by 21
Implicit Image-to-Image Schrödinger Bridge for image restoration
Wang, Y., Yoon, S., Jin, P., Tivnan, M., Song, S., Chen, Z., Hu, R., Zhang, L., Li, Q., Chen, Z., et al. (2025) · Pattern Recognition · doi:10.1016/j.patcog.2025.111627 · Cited by 26
“Notable examples of task-specific models include SR3 [2] and ADM [1].”
InfluentialXu, X., Kapse, S., & Prasanna, P. (2025) · Medical Image Analysis · doi:10.1016/j.media.2025.103808 · Cited by 22
Emergence and Evolution of Interpretable Concepts in Diffusion Models
Tınaz, B., Fabian, Z., & Soltanolkotabi, M. (2025) · neural information processing systems · doi:10.52202/085713-5566 · Cited by 23
DSPO: Direct Semantic Preference Optimization for Real-World Image Super-Resolution
Cai, M., Li, S., Li, W., Huang, X., Chen, H., Hu, J., & Wang, Y. (2026) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3767308.3835421 · Cited by 17
NightRain: Nighttime Video Deraining via Adaptive-Rain-Removal and Adaptive-Correction
Lin, B., Jin, Y., Yan, W., Ye, W., Yuan, Y., Zhang, S., & Tan, R. T. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i4.28124 · Cited by 36
Adaptive Double-Branch Fusion Conditional Diffusion Model for Underwater Image Restoration
Wang, Y., He, K., Qu, Q., Du, X., Liu, T., Lei, T., & Nandi, A. K. (2025) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2025.3570372 · Cited by 17
Latent space diffusion model for image dehazing
Liang, H., Yang, Y. C., & Jing, J. (2025) · Applied Soft Computing · doi:10.1016/j.asoc.2025.113322 · Cited by 18
A diffusion model for universal medical image enhancement
Fei, B., Li, Y., Yang, W., Gao, H., Xu, J., Ma, L., Yang, Y. S., & Zhou, P. (2025) · Communications Medicine · doi:10.1038/s43856-025-00998-1 · Cited by 19
EDEN: Enhanced Diffusion for High-quality Large-motion Video Frame Interpolation
Zhang, Z., Chen, H., Zhao, H., Lu, G., Fu, Y., Xu, S., & Wu, Z. (2025) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52734.2025.00202 · Cited by 38
“For image super-resolution, [47, 48] demonstrates that diffusion models can produce high-fidelity results with better detail preservation than GANs.”
MSFusion: A Degradation-Correctable Framework for Robust Infrared and Visible Image Fusion
Hu, Q., Peng, Y., KinTak, U., & Chen, J. (2025) · IEEE Sensors Journal · doi:10.1109/jsen.2025.3640678 · Cited by 32
“Diffusion models, recognized for their strong generative capacity, have achieved notable progress in image generation, inpainting, and super-resolution [23], [24] and are increasingly adopted in image fusion.”
Wang, H. H., Xu, G., & Zhou, Q. (2024) · Journal of Inverse and Ill-Posed Problems · doi:10.1515/jiip-2023-0037 · Cited by 18
“When using conditional generative models, such as the one in Saharia et al. (2022), to solve inverse problems, they can generate high-quality samples but require a large number of training iterations and time-consuming inference.”
MethodFace De-Morphing Based on Diffusion Autoencoders
Long, M., Yao, Q., Zhang, L., & Peng, F. (2024) · IEEE Transactions on Information Forensics and Security · doi:10.1109/tifs.2024.3359029 · Cited by 21
“Recently, diffusion-based generative models [18] have demonstrated a strong generation ability in image manipulation, translation, super-resolution [19], [20], [21], [22], and various other multimodal tasks [23].”
BackgroundHe, K., Cai, Y., Peng, S., & Tan, M. (2024) · IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing · doi:10.1109/jstars.2024.3386702 · Cited by 15
Model-Based Super-Resolution for Sentinel-5P Data
Carbone, A., Restaino, R., Vivone, G., & Chanussot, J. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3387877 · Cited by 17
“Likewise, other important works on this subject employ either diffusion mechanisms [58], transformers [53], [59], residual information [45], [60], [61], or knowledge distillation [62], [63], [64], [65].”
BackgroundDetail-aware image denoising via structure preserved network and residual diffusion model
Wu, J., Wu, H., & Yuan, G. (2024) · The Visual Computer · doi:10.1007/s00371-024-03353-y · Cited by 18
Diffusion Model for Image Generation - A Survey
Hu, X., Jin, Y., Liang, J., Liu, J., Luo, R., Li, M., & Peng, T. (2023) · International Conference on Artificial Intelligence, Human-Computer Interaction and Robotics (AIHCIR) · doi:10.1109/aihcir61661.2023.00073 · Cited by 22
“Diffusion models are applied to super-resolution in [55].”
Parallel diffusion models promote high detail-fidelity photoacoustic microscopy in sparse sampling
Wu, J., Zhang, K., Huang, C., Ma, Y., Ma, R., Chen, X., Guo, T., Yang, S., Yuan, Z., & Zhang, Z. (2024) · Optics Express · doi:10.1364/oe.528474 · Cited by 15
DiffMAR: A Generalized Diffusion Model for Metal Artifact Reduction in CT Images
Cai, T., Li, X., Zhong, C., Tang, W. D., & Guo, J. (2024) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2024.3439729 · Cited by 17
Sun, R., Yang, D., Zhang, S., & Hao, Q. (2024) · Advanced Photonics Nexus · doi:10.1117/1.apn.3.5.056003 · Cited by 17
“We opted for a U-Net network with an attention mechanism 28 as the core of our DL modules.”
Plug-and-Play Diffusion Distillation
Hsiao, Y.-T., Khodadadeh, S., Duarte, K., Lin, W.-A., Qu, H., Kwon, M., & Kalarot, R. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01304 · Cited by 31
“However, the sampling speed of diffusion models stands out as a significant obstacle to their adoption in practical scenarios [20].”
BackgroundTorch-Advent-Civilization-Evolution: Accelerating Diffusion Model for Image Restoration
Song, J., Huang, D., Huang, X., Ruan, M., & Zeng, H. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3470888 · Cited by 17
“I MAGE restoration [1], [2] (IR) has been a critical topic in low-level vision tasks due to its significant potential in real-world scenarios.”
Unpaired Photo-realistic Image Deraining with Energy-informed Diffusion Model
Wen, Y., Gao, T., & Chen, T. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3680560 · Cited by 28
“[27, 28] develop a conditional SBDM to achieve paired super-resolution and colorization.”
Efficient Single Image Super-Resolution with Entropy Attention and Receptive Field Augmentation
Zhao, X., Li, L., Xie, C., Zhang, X., Jiang, T., Lin, W., Liu, S., & Li, T. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3680744 · Cited by 21
Conditional Denoising Diffusion Probabilistic Model for Ground-Roll Attenuation
Li, Y., Zhang, H., Huang, J., & Li, Z. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3489716 · Cited by 22
“We adopt the modified U-Net architecture, an adaptation of the network used by [39], as the backbone for the c-DDPM.”
MethodJoint Conditional Diffusion Model for image restoration with mixed degradations
Yue, Y., Yu, M., Yang, L., & Liu, T. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.129512 · Cited by 20
Federated Learning for Diffusion Models
Peng, Z., Wang, X., Chen, S., Rao, H., & Shen, C. (2025) · IEEE Transactions on Cognitive Communications and Networking · doi:10.1109/tccn.2025.3550359 · Cited by 23
Wu, H., Mo, J., Sun, X., & Ma, J. (2025) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2025.3571290 · Cited by 22
“We compare LDCSR with SR3 [20], as well as real-world SR methods including DASR [74], RealESRGAN [75], and BlindSRSNF [51].”
InfluentialZoomLDM: Latent Diffusion Model for multi-scale image generation
Yellapragada, S., Graikos, A., Triaridis, K., Prasanna, P., Gupta, R., Saltz, J., & Samaras, D. (2025) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52734.2025.02184 · Cited by 33
“This has led to synthesizing images of up to 1024 × 1024 resolution at the cost of increased parameter count and slower inference speed.”
Annotator Consensus Prediction for Medical Image Segmentation with Diffusion Models
Amit, T., Shichrur, S., Shaharabany, T., & Wolf, L. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-43901-8_52 · Cited by 26
Super-resolution reconstruction of single image for latent features
Wang, X., Yan, J.-K., Cai, J., Deng, J.-H., Qin, Q., & Cheng, Y. (2024) · Computational Visual Media · doi:10.1007/s41095-023-0387-8 · Cited by 16
“[23] designed based on a repeat detailed image SuperResolution model (SR3).”
Diffusion-Based Radiotherapy Dose Prediction Guided by Inter-Slice Aware Structure Encoding
Feng, Z., Wen, L., Xiao, J., Xu, Y., Wu, X., Zhou, J., Peng, X., & Wang, Y. (2024) · IEEE Transactions on Emerging Topics in Computational Intelligence · doi:10.1109/tetci.2024.3436568 · Cited by 17
“These results confirm the strong capability of our methodincapturingtheadditionalinter-sliceinformationamong 2Dsliceswhichcanserveasacompetitivesubstitutetothe3D onesinsidethevolumes.”
ArtFusion: Controllable Arbitrary Style Transfer using Dual Conditional Latent Diffusion ModelsPreprint
Chen, D.-Y. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2306.09330 · Cited by 27
“[58] for super-resolution.”
BackgroundPosterior-Mean Rectified Flow: Towards Minimum MSE Photo-Realistic Image Restoration
Ohayon, G., Michaeli, T., & Elad, M. (2024) · International Conference on Learning Representations · doi:10.48550/arxiv.2410.00418 · Cited by 26
Chen, J., Jia, L., Zhang, J., Feng, Y., Zhao, X., & Tao, R. (2024) · Remote Sensing · doi:10.3390/rs16081356 · Cited by 14
Zhang, W., Zhang, X., Dong, J., Song, X., & Pang, R. (2025) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2025.02.001 · Cited by 14
Liu, Y., Jiang, T., Li, R., Yuan, L., Grzegorzek, M., Li, C., & Li, X. (2025) · Frontiers in Medicine · doi:10.3389/fmed.2025.1551894 · Cited by 16
EgoHMR: Egocentric Human Mesh Recovery via Hierarchical Latent Diffusion Model
Liu, Y., Yang, J., Gu, X., Guo, Y., & Yang, G. (2023) · Proceedings - IEEE International Conference on Robotics and Automation/Proceedings · doi:10.1109/icra48891.2023.10161247 · Cited by 16
“Since the processes of noise adding and removing enable the generated images highly robust to domain shifts, diffusion models have shown excellent performance in the field of image generation [28]– [30] and super-resolution [31].”
BackgroundMa, Z., Sun, S., Yan, B., Kwak, H. T., & Gao, J. (2023) · SPE Annual Technical Conference and Exhibition · doi:10.2118/214883-ms · Cited by 20
Zhao, Z., Wang, C., Li, C., Zhang, Y., & Tang, J. (2024) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2024.3354878 · Cited by 19
“Saharia et al. [32] enhanced the architecture of DM by integrating additional residual blocks.”
BackgroundSemantic Image Synthesis for Abdominal CT
Zhuang, Y., Hou, B., Mathai, T. S., Mukherjee, P., Kim, B., & Summers, R. M. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-53767-7_21 · Cited by 18
Single-pixel imaging based on self-supervised conditional mask classifier-free guidance
Li, Q., Yan, Q., Dong, J., Feng, J., Wu, J., Cao, J., Liu, G., & Wang, H. (2024) · Optics Express · doi:10.1364/oe.518455 · Cited by 14
MedDiffusion: Boosting Health Risk Prediction via Diffusion-based Data Augmentation
Zhong, Y., Cui, S., Wang, J., Wang, X., Yin, Z., Wang, Y., Xiao, H., Huai, M., Wang, T., & Ma, F. (2024) · Society for Industrial and Applied Mathematics eBooks · doi:10.1137/1.9781611978032.58 · Cited by 19
Head and neck tumor segmentation from [ 18 F]F-FDG PET/CT images based on 3D diffusion model
Dong, Y., & Gong, K. (2024) · Physics in Medicine and Biology · doi:10.1088/1361-6560/ad5ef2 · Cited by 17
“Beyond image synthesis, they also demonstrated significant potentials across various domains, e.g. image super-resolution (Saharia et al 2023), denoising (Gong et al 2024), inpainting (Rombach et al 2022) and segmentation (Wu et al 2022, Khosravi et al 2023, Li et al 2024, Zhao et al 2024).”
Seven decades of image super-resolution: achievements, challenges, and opportunities
Maiseli, B. J., & Abdalla, A. T. (2024) · EURASIP Journal on Advances in Signal Processing · doi:10.1186/s13634-024-01170-y · Cited by 17
“Google researchers applied two approaches to achieve outstanding super-resolution results: iterative refinement [118] and cascaded diffusion models [119].”
UltrAvatar: A Realistic Animatable 3D Avatar Diffusion Model with Authenticity Guided Textures
Zhou, M., Hyder, R., Xuan, Z., & Qi, G.-J. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00124 · Cited by 20
“Although multi-view 3D reconstruction methods, such as Multi-View Stereo (MVS) [62] and Structure from Motion (SfM) [61], have facilitated avatar generation from multiple images captured at various angles, generating realistic 3D avatars from few images, like a single view taken by a user or particularly generated fro…”
MethodAdaptive Compressed Sensing with Diffusion-Based Posterior Sampling
Elata, N., Michaeli, T., & Elad, M. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73229-4_17 · Cited by 26
Infusion: Preventing Customized Text-to-Image Diffusion from Overfitting
Zeng, W., Yan, Y., Zhu, Q., Chen, Z., Chu, P., Zhao, W., & Yang, X. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3680894 · Cited by 18
JoReS-Diff: Joint Retinex and Semantic Priors in Diffusion Model for Low-light Image Enhancement
Wu, Y., Wang, G., Wang, Z., Yang, Y., Li, T., Zhang, M., Li, C., & Shen, H. T. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3680876 · Cited by 20
“Diffusion models [13, 28] show promising capability in image generation tasks [2, 27].”
BackgroundMethodInfluentialComparative Analysis of GANs and Diffusion Models in Image Generation
Wang, H. (2024) · Highlights in Science Engineering and Technology · doi:10.54097/9gba9v27 · Cited by 18
Super-Resolved 3-D Satellite Lidar Imaging of Earth via Generative Diffusion Models
Ramírez-Jaime, A., Porras-Diaz, N., Arce, G. R., & Stephen, M. A. (2025) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2025.3543670 · Cited by 16
“This is particularly true in super-resolution problems since multiple high-resolution images may be consistent with a single low-resolution image [23].”
CWFAS-Net: Low-light image enhancement using curvelet wavelet Attention and Fourier Transform
Zhou, H., Cao, C., Tong, J., & Zheng, K. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.127263 · Cited by 14
PFCM: Poisson Flow Consistency Models for Low-Dose CT Image Denoising
Hein, D., Stevens, G. M., Wang, A., & Wang, G. (2025) · IEEE Transactions on Medical Imaging · doi:10.1109/tmi.2025.3558019 · Cited by 20
“Feeding the condition image, y , as additional input to the network to directly learn a given inverse problem has been demonstrated to work well empirically for diffusion models [45], [48], [49].”
Bracket Diffusion: HDR Image Generation by Consistent LDR Denoising
Bemana, M., Leimkühler, T., Myszkowski, K., Seidel, H., & Ritschel, T. (2025) · Computer Graphics Forum · doi:10.1111/cgf.70086 · Cited by 22
Zan, Y., Ji, S., Chao, S., & Luo, M. (2025) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2025.04.023 · Cited by 17
Image-to-Image Steganography based on multimodal generative model
Jiang, J., Wang, Z., & Zhang, X. (2025) · Signal Processing · doi:10.1016/j.sigpro.2025.110106 · Cited by 20
Toward Advancing License Plate Super-Resolution in Real-World Scenarios: A Dataset and Benchmark
Nascimento, V., Lima, G. E., Ribeiro, R. O., Schwartz, W. R., Laroca, R., & Menotti, D. (2025) · Journal of the Brazilian Computer Society · doi:10.5753/jbcs.2025.5159 · Cited by 17
Multi-scale adaptive residual cold diffusion model for Low-Dose CT denoising
Zhang, J., Liu, G., Chen, J., & Cheng, Y. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.128817 · Cited by 15
Principles and Perspectives of Radiographic Imaging with Muons
Cimmino, L. (2021) · Journal of Imaging · doi:10.3390/jimaging7120253 · Cited by 14
“One of the most impressive recent applicatiosn is the manipulation of low quality images in order to improve their quality and increase their resolution [49].”
BackgroundImage Interpolation Based on Spiking Neural Network Model
İncetaş, M. O. (2023) · Applied Sciences · doi:10.3390/app13042438 · Cited by 14
CUF: Continuous Upsampling Filters
Vasconcelos, C. N., Öztireli, C., Matthews, M. A., Hashemi, M., Swersky, K., & Tagliasacchi, A. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00964 · Cited by 20
Metadata
- Authors
- Saharia, C., Ho, J., Chan, W., Salimans, T., Fleet, D. J., & Norouzi, M.
- Affiliations
- Google (United States) (US)
- Venue
- IEEE Transactions on Pattern Analysis and Machine Intelligence
- Published
- 2022
- Volume
- 45
- Issue
- 4
- Pages
- 1-14
- ISSN
- 0162-8828 (ISSN-L)
- 2160-9292
- 1939-3539
- OpenAlex
- W3155072588
- Cited by
- 1,829
- References
- 85
- Citations by year
- 2026: 234 · 2025: 580 · 2024: 662 · 2023: 301 · 2022: 40
- FWCI
- 129.48
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- IEEE Transactions on Pattern Analysis and Machine Intelligence (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Image Processing Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Generative Adversarial Networks and Image Synthesis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Image and Signal Denoising Methods
- Keywords
- image super-resolution, iterative refinement, denoising diffusion probabilistic models, image-to-image translation, U-Net, face super-resolution, high-resolution image generation, human evaluation, image classification accuracy
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
