

The DOI matches its DataCite record; 242 of the 243 references it cites were found in a registry or an index, and 1 are not checked yet; none of the 334 sources its claims cite is checked for support yet.
A Survey on Knowledge-Oriented Retrieval-Augmented Generation
Open accessAbstract
Retrieval-Augmented Generation (RAG) has gained significant attention in recent years for its potential to enhance natural language understanding and generation by combining large-scale retrieval systems with generative models. RAG leverages external knowledge sources, such as documents, databases, or structured data, to improve model performance and generate more accurate and contextually relevant outputs. This survey aims to provide a comprehensive overview of RAG by examining its fundamental components, including retrieval mechanisms, generation processes, and the integration between the two. We discuss the key characteristics of RAG, such as its ability to augment generative models with dynamic external knowledge, and the challenges associated with aligning retrieved information with generative objectives. We also present a taxonomy that categorizes RAG methods, ranging from basic retrieval-augmented approaches to more advanced models incorporating multimodal data and reasoning capabilities. Additionally, we review the evaluation benchmarks and datasets commonly used to assess RAG systems, along with a detailed exploration of its applications in fields such as question answering, summarization, and information retrieval. Finally, we highlight emerging research directions and opportunities for improving RAG systems, such as enhanced retrieval efficiency, model interpretability, and domain-specific adaptations. This paper concludes by outlining the prospects for RAG in addressing real-world challenges and its potential to drive further advancements in natural language processing.
Checked 2026-11-14 · 1 reference not checked yet
Overview
CoChat Summary
TL;DR
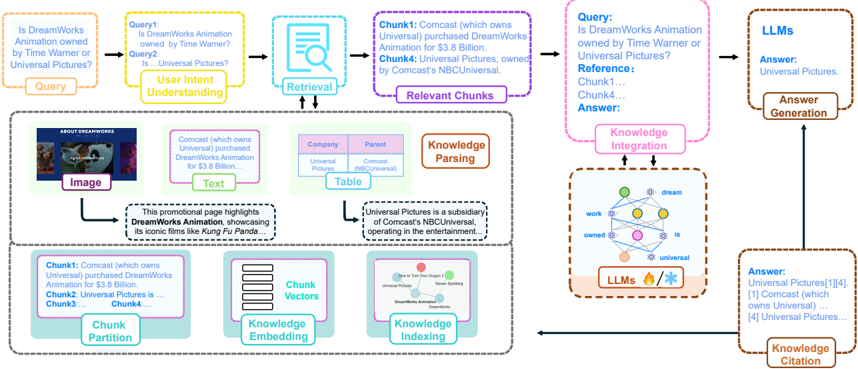
This survey reviews retrieval-augmented generation (RAG) through a knowledge-centric lens, organizing the field around the lifecycle of external knowledge: sourcing, retrieval, integration, reasoning, and generation. It proposes a taxonomy spanning basic approaches, advanced approaches (training, multimodal, memory, agentic, parametric RAG), and evaluation strategies.
Key findings
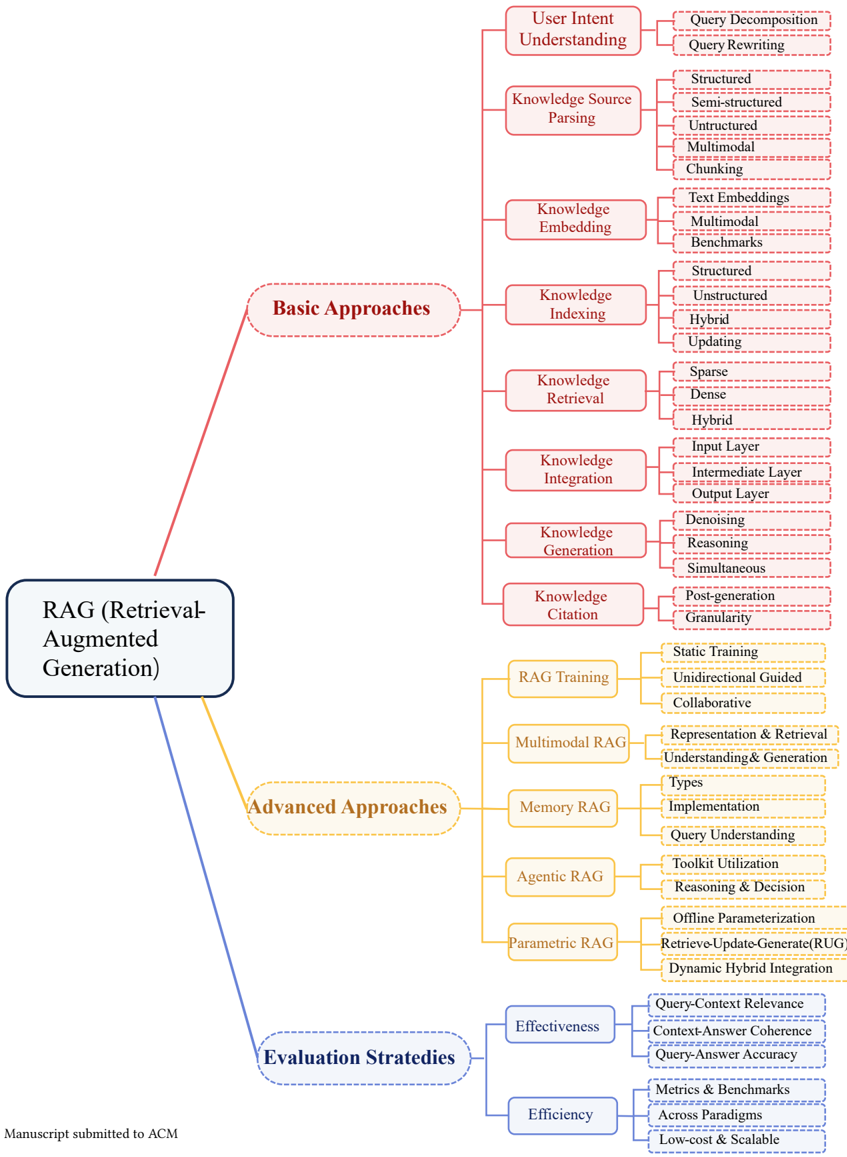
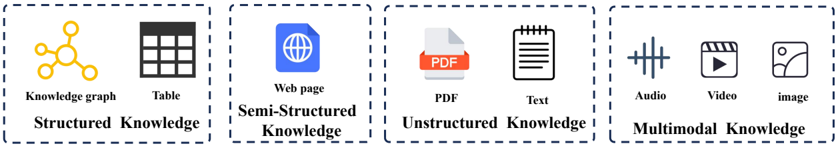
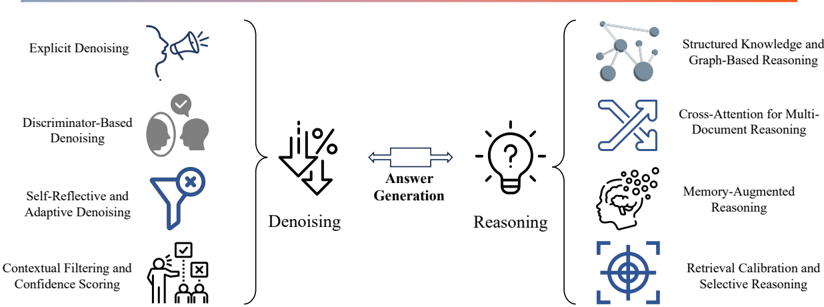
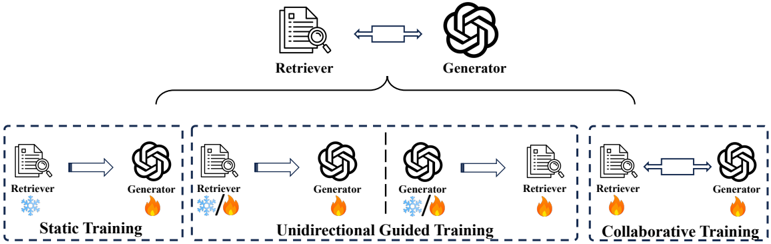
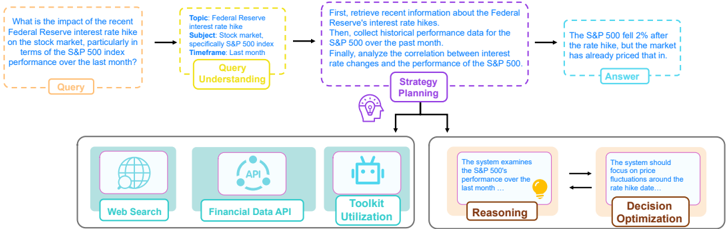
- The authors structure RAG as a multi-stage knowledge lifecycle and propose a taxonomy with three branches: basic approaches (user intent understanding, knowledge source/parsing, embedding, indexing, retrieval, integration, answer generation, citation), advanced approaches (RAG training, multimodal RAG, memory RAG, agentic RAG, parametric RAG), and evaluation strategies (effectiveness and efficiency).
- Knowledge integration is categorized by architectural stage: input-layer (text-level concatenation or feature-level), intermediate-layer (e.g., RETRO's cross-attention, TOME/LongMem memory, weighted addition), and output-layer (kNN-LM interpolation, calibration-based methods, and Contrastive Decoding as post-hoc logit-level alignment).
- Parametric RAG parameterizes documents as low-rank LoRA matrices merged into feed-forward layers; the survey reports that on HotpotQA, 2WikiMultihopQA, and ComplexWebQuestions it "reduces inference time by up to 36% while maintaining or exceeding in-context RAG baselines."
- Evaluation is split into effectiveness (query-context relevance, context-answer coherence, query-answer accuracy) and efficiency (latency, throughput, resource utilization), with benchmarks such as ARES, RAGAS, TruLens, KILT, CRUD, RECALL, CRAG, and RGB.
Methods
- Design: a systematic literature survey, not an empirical study; the stated unique contribution is organizing RAG research around the lifecycle of knowledge rather than by model architecture or task.
- Scope: covers RAG origins (2020 onward), core pipeline components, a taxonomy of basic and advanced methods, evaluation benchmarks and metrics, downstream tasks (QA, information extraction, text understanding/generation), and domain applications (science, finance, education, healthcare, legal, industry).
- Analysis: narrative synthesis with comparison tables (e.g., Table 1 comparing prior RAG surveys; Table 2 embedding models and dimensions; Table 3 retrieval models; Table 4 comparing implicit/explicit/working memory; Table 5 datasets by task).
Limitations
- The paper does not state explicit limitations of the survey itself; it instead lists open issues for RAG subfields (e.g., lack of systematic multi-source heterogeneous graph integration, dynamic graph updating, multimodal alignment and real-time retrieval, absence of a universally accepted trustworthiness framework, and ineffective defenses against knowledge poisoning).
- Evident from the text: as a survey, it reports no original experiments or quantitative comparisons of its own, and its performance figures (e.g., the 36% inference-time reduction) are drawn from cited primary work rather than independently verified.
- Evident from the text: the survey notes that existing benchmarks often focus on single-modality or offline use cases and that there is no unified standard for quantifying interpretability, trustworthiness, or uncertainty handling.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 21 Not valid · 233 Not checked · 237 Own results and interpretations
In the paper
“The RETRO model [21], for instance, exemplifies this by introducing a dedicated cross-attention module that merges retrieved information with the model's intermediate representations at each layer.”
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > Intermediate Layer Integration.
What the sources say
- Not matchedcites [21]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
In the paper
“InstructRAG [263] instructs the model to generate intermediate rationales, which act as a filter by clarifying the relevance of each document.”
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > 6.7 Answer Generation
What the sources say
- Not matchedcites [263]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
In the paper
“In a similar vein, the REFEED framework [295] is well-suited for fact-checking applications, as it uses an iterative loop where the LLM refines answers by reassessing factual accuracy.”
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > 6.7 Answer Generation
What the sources say
- Not matchedcites [295]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
boostedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
In the paper
“The canonical example, kNN-LM [116], interpolates the probabilities of the Manuscript submitted to ACM k-nearest neighbors from an external datastore with the language model's own predictions.”
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > Output Layer Integration.
What the sources say
- Not matchedcites [116]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
In the paper
“Building upon this foundation, [313] introduce a multi-input extension that integrates both relevant and irrelevant retrievals, encouraging the model to discriminate between supportive and misleading evidence.”
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > Output Layer Integration.
What the sources say
- Not matchedcites [313]
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
119 more claims
Create a free account to see all 491 claims and every source verdict.
- Probably not a substantial claim. 281
- It may state two separate claims as one. 180
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Agentic RAG systems treat retrieval as dynamic operations where agents function as intelligent investigators analyzing content and cross-referencing information [654, 166, 973].”
From A Survey of Context Engineering for Large Language Models (2025) · cites this paper as [166]
In the citing paper
“Tool utilization enables systems to employ diverse resources including search engines, calculators, and APIs, with frameworks like ReAct and Reflexion exemplifying how interleaving reasoning with actions enhances adaptability [166, 1169, 964].”
From A Survey of Context Engineering for Large Language Models (2025) · cites this paper as [166]
In the citing paper
“Memory mechanisms provide external long-term storage, while adaptive retrieval strategies enable autonomous analysis of complexity and context [166, 1137].”
From A Survey of Context Engineering for Large Language Models (2025) · cites this paper as [166]
In the citing paper
“PlanRAG improves decision-making through plan-then-retrieve approaches, enabling agents to evaluate multiple information sources and optimize retrieval strategies, while SLA management frameworks address reconfigurable multi-agent architectures [166, 467].”
From A Survey of Context Engineering for Large Language Models (2025) · cites this paper as [166]
In the citing paper
“Unlike static approaches, Agentic RAG treats retrieval as dynamic operation where agents function as intelligent investigators analyzing content and cross-referencing information [654, 166].”
From A Survey of Context Engineering for Large Language Models (2025) · cites this paper as [166]
2 more claims about this paper
Create a free account to see every claim other papers make about this one.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > 7.5 Parametric RAG
“Unlike conventional RAG methods that append documents into the input prompt, Parametric RAG parameterizes each document into a set of low-rank matrices that can be merged into the feed-forward layers of the model, enabling the LLM to utilize external knowledge in the same manner as its internal parametric knowledge [241].”
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > References
“241. Haitian Sun, Tania Bedrax-Weiss, and William W Cohen. 2019. Pullnet: Open domain question answering with iterative retrieval on knowledge bases and text.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > 11 Conclusion
“| Usage Frequency | high | medium | low |”
§ A Survey on Knowledge-Oriented Retrieval-Augmented Generation > 11 Conclusion
“This type of memory is characterized by high-frequency access, rapid updates with each new task, and temporary storage.”
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Glove: Global Vectors for Word Representation
Pennington, J., Socher, R., & Manning, C. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1162 · Cited by 34,071
Efficient Estimation of Word Representations in Vector Space
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013) · arXiv · doi:10.48550/arxiv.1301.3781 · Cited by 26,568
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Learning Transferable Visual Models From Natural Language Supervision
Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., et al. (2021) · arXiv · doi:10.48550/arxiv.2103.00020 · Cited by 15,293
Enriching Word Vectors with Subword Information
Bojanowski, P., Grave, E., Joulin, A., & Mikolov, T. (2017) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00051 · Cited by 9,645
Multidimensional binary search trees used for associative searching
Bentley, J. L. (1975) · Communications of the ACM · doi:10.1145/361002.361007 · Cited by 7,498
Recursive Deep Models for Semantic Compositionality Over a Sentiment Treebank
Socher, R., Perelygin, A., Wu, J., Chuang, J., Manning, C. D., Ng, A., & Potts, C. (2013) · Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d13-1170 · Cited by 6,878
The magical number 4 in short-term memory: A reconsideration of mental storage capacity
Cowan, N. (2001) · Behavioral and Brain Sciences · doi:10.1017/s0140525x01003922 · Cited by 6,779
Guttman, A. (1984) · ACM SIGMOD International Conference on Management of Data (SIGMOD) · doi:10.1145/602259.602266 · Cited by 6,679
SQuAD: 100,000+ Questions for Machine Comprehension of Text
Rajpurkar, P., Zhang, J., Lopyrev, K., & Liang, P. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1264 · Cited by 6,208
DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter
Sanh, V., Debut, L., Chaumond, J., & Wolf, T. (2019) · arXiv · doi:10.48550/arxiv.1910.01108 · Cited by 4,653
Billion-scale similarity search with GPUs
Johnson, J., Douze, M., & Jegou, H. (2021) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2019.2921572 · Cited by 4,228
Dense passage retrieval for open-domain question answering
Karpukhin, V., Oguz, B., Min, S., Lewis, P., Wu, L., Edunov, S., Chen, D., & Yih, W.-T. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.550 · Cited by 3,575
Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
Lewis, P., Perez, E., Piktus, A., Petroni, F., Karpukhin, V., Goyal, N., Küttler, H., Lewis, M., Yih, W.-T., Rocktäschel, T., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.11401 · Cited by 3,101
Locality-sensitive hashing scheme based on p-stable distributions
Datar, M., Immorlica, N., Indyk, P., & Mirrokni, V. (2004) · Annual Symposium on Computational Geometry (SoCG) · doi:10.1145/997817.997857 · Cited by 2,971
Product Quantization for Nearest Neighbor Search
Jégou, H., Douze, M., & Schmid, C. (2011) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2010.57 · Cited by 2,956
ViViT: A Video Vision Transformer
Arnab, A., Dehghani, M., Heigold, G., Sun, C., Lucic, M., & Schmid, C. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00676 · Cited by 2,767
An optimal algorithm for approximate nearest neighbor searching fixed dimensions
Arya, S., Mount, D. M., Netanyahu, N. S., Silverman, R., & Wu, A. Y. (1998) · Journal of the ACM · doi:10.1145/293347.293348 · Cited by 2,347
Natural Questions: A benchmark for question answering research
Kwiatkowski, T., Palomaki, J., Redfield, O., Collins, M., Parikh, A., Alberti, C., Epstein, D., Polosukhin, I., Devlin, J., Lee, K., et al. (2019) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00276 · Cited by 2,069
Malkov, Y. A., & Yashunin, D. A. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2889473 · Cited by 1,904
HotpotQA: A Dataset for Diverse, Explainable Multi-hop Question Answering
Yang, Z., Qi, P., Zhang, S., Bengio, Y., Cohen, W., Salakhutdinov, R., & Manning, C. D. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1259 · Cited by 1,804
TriviaQA: A Large Scale Distantly Supervised Challenge Dataset for Reading Comprehension
Joshi, M., Choi, E., Weld, D., & Zettlemoyer, L. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1147 · Cited by 1,690
TriviaQA: A Large Scale Distantly Supervised Challenge Dataset for Reading Comprehension
Joshi, M., Choi, E., Weld, D. S., & Zettlemoyer, L. (2017) · arXiv · doi:10.48550/arxiv.1705.03551 · Cited by 1,650
Lost in the Middle: How Language Models Use Long Contexts
Liu, N. F., Lin, K., Hewitt, J., Paranjape, A., Bevilacqua, M., Petroni, F., & Liang, P. (2024) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00638 · Cited by 1,612
Semantic Parsing on Freebase from Question-Answer Pairs
Berant, J., Chou, A., Frostig, R., & Liang, P. (2013) · Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d13-1160 · Cited by 1,517
Near-optimal hashing algorithms for approximate nearest neighbor in high dimensions
Andoni, A., & Indyk, P. (2008) · Communications of the ACM · doi:10.1145/1327452.1327494 · Cited by 1,437
ColBERT: Efficient and Effective Passage Search via Contextualized Late Interaction over BERT
Khattab, O., & Zaharia, M. (2020) · Proceedings of the 43rd International ACM SIGIR Conference on Research and Development in Information Retrieval · doi:10.1145/3397271.3401075 · Cited by 1,301
Narayan, S., Cohen, S. B., & Lapata, M. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1206 · Cited by 1,207
A study of smoothing methods for language models applied to information retrieval
Zhai, C., & Lafferty, J. (2004) · ACM Transactions on Information Systems · doi:10.1145/984321.984322 · Cited by 1,201
Leveraging Passage Retrieval with Generative Models for Open Domain Question Answering
Izacard, G., & Grave, E. (2021) · Proceedings of the 16th Conference of the European Chapter of the Association for Computational Linguistics: Main Volume · doi:10.18653/v1/2021.eacl-main.74 · Cited by 1,109
Yacouby, R., & Axman, D. (2020) · Workshop on Evaluation and Comparison of NLP Systems (Eval4NLP) · doi:10.18653/v1/2020.eval4nlp-1.9 · Cited by 909
Retrieval-Augmented Generation for Large Language Models: A Survey
Gao, Y., Xiong, Y., Gao, X., Jia, K., Pan, J., Bi, Y., Dai, Y., Sun, J., Wang, M., & Wang, H. (2023) · arXiv · doi:10.48550/arxiv.2312.10997 · Cited by 876
A Survey on RAG Meeting LLMs: Towards Retrieval-Augmented Large Language Models
Fan, W., Ding, Y., Ning, L., Wang, S., Li, H., Yin, D., Chua, T.-S., & Li, Q. (2024) · Proceedings of the 30th ACM SIGKDD Conference on Knowledge Discovery and Data Mining · doi:10.1145/3637528.3671470 · Cited by 827
LaMDA: Language Models for Dialog Applications
Thoppilan, R., De Freitas, D., Hall, J., Shazeer, N., Kulshreshtha, A., Cheng, H.-T., Jin, A., Bos, T., Baker, L., Du, Y., et al. (2022) · arXiv · doi:10.48550/arxiv.2201.08239 · Cited by 778
What's new with the amnesic patient H.M.?
Corkin, S. (2002) · Nature Reviews Neuroscience · doi:10.1038/nrn726 · Cited by 726
Cowan, N. (2012) · Psychology Press eBooks · doi:10.4324/9780203342398 · Cited by 700
Text and Code Embeddings by Contrastive Pre-TrainingPreprint
Neelakantan, A., Xu, T., Puri, R., Radford, A., Han, J. M., Tworek, J., Yuan, Q., Tezak, N., Kim, J. W., Hallacy, C., et al. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2201.10005 · Cited by 687
Learning semantic representations using convolutional neural networks for web search
Shen, Y., He, X., Gao, J., Deng, L., & Mesnil, G. (2014) · International World Wide Web Conference (WWW) · doi:10.1145/2567948.2577348 · Cited by 677
Show-o: One Single Transformer to Unify Multimodal Understanding and GenerationPreprint
Xie, J., Mao, W., Bai, Z., Zhang, D. J., Wang, W., Lin, K. Q., Gu, Y., Chen, Z., Yang, Z., & Shou, M. Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2408.12528 · Cited by 674
Query Rewriting in Retrieval-Augmented Large Language Models
Ma, X., Gong, Y., He, P., Zhao, H., & Duan, N. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.322 · Cited by 606
The NarrativeQA Reading Comprehension Challenge
Kočiský, T., Schwarz, J., Blunsom, P., Dyer, C., Hermann, K. M., Melis, G., & Grefenstette, E. (2018) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00023 · Cited by 596 · cited 1×
“…QA HotpotQA [261] 2WikiMultiHopQA [89] StrategyQA [75] MuSiQue [231] MultiHop-RAG [227] Long-form QA ELI5 [62] WebCPM [192] NarrativeQA (NQA) [118] Information Extraction Entity Linking ZESHEL [150] CoNLL [90] Relation Extraction T-REx [59] ZsRE [125] Text Understanding Text Classification…”
Wizard of Wikipedia: Knowledge-Powered Conversational agents
Dinan, E., Roller, S., Shuster, K., Fan, A., Auli, M., & Weston, J. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1811.01241 · Cited by 572
MTEB: Massive Text Embedding Benchmark
Muennighoff, N., Tazi, N., Magne, L., & Reimers, N. (2023) · Proceedings of the 17th Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2023.eacl-main.148 · Cited by 548
Document language models, query models, and risk minimization for information retrieval
Lafferty, J., & Zhai, C. (2001) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/383952.383970 · Cited by 531
C-Pack: Packed Resources For General Chinese Embeddings
Xiao, S., Liu, Z., Zhang, P., Muennighoff, N., Lian, D., & Nie, J.-Y. (2024) · Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval · doi:10.1145/3626772.3657878 · Cited by 523 · cited 1×
“These methods often struggle with documents that have varied formats or contain cross-paragraph semantic flows, resulting in suboptimal retrieval due to fragmented contextual information[122, 128, 149, 155, 249, 277].”
C-Pack: Packed Resources For General Chinese Embeddings
Xiao, S., Liu, Z., Zhang, P., Muennighoff, N., Lian, D., & Nie, J.-Y. (2023) · arXiv · doi:10.48550/arxiv.2309.07597 · Cited by 514
Fang, S., Xie, H., Wang, Y., Mao, Z., & Zhang, Y. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00702 · Cited by 495
Transfusion: Predict the Next Token and Diffuse Images with One Multi-Modal ModelPreprint
Zhou, C., Yu, L., Babu, A., Tirumala, K., Yasunaga, M., Shamis, L., Kahn, J., Ma, X., Zettlemoyer, L., & Levy, O. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2408.11039 · Cited by 491
Zero-Shot Relation Extraction via Reading Comprehension
Levy, O., Seo, M., Choi, E., & Zettlemoyer, L. (2017) · arXiv · doi:10.48550/arxiv.1706.04115 · Cited by 482
Zero-Shot Relation Extraction via Reading Comprehension
Levy, O., Seo, M., Choi, E., & Zettlemoyer, L. (2017) · Proceedings of the 21st Conference on Computational Natural Language Learning (CoNLL 2017) · doi:10.18653/v1/k17-1034 · Cited by 482 · cited 1×
“…[231] MultiHop-RAG [227] Long-form QA ELI5 [62] WebCPM [192] NarrativeQA (NQA) [118] Information Extraction Entity Linking ZESHEL [150] CoNLL [90] Relation Extraction T-REx [59] ZsRE [125] Text Understanding Text Classification TREC [136] SST-2 [220] Text Summarization WikiASP [85] XSum [172]”
Open Domain Question Answering Using Early Fusion of Knowledge Bases and Text
Sun, H., Dhingra, B., Zaheer, M., Mazaitis, K., Salakhutdinov, R., & Cohen, W. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1455 · Cited by 466
Wu, Y., Chen, K., Zhang, T., Hui, Y., Berg-Kirkpatrick, T., & Dubnov, S. (2023) · ICASSP 2023 - 2023 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp49357.2023.10095969 · Cited by 459 · cited 4×
“…4096 text-embedding[178] 768 Specific Domain Encoders ru-en-RoSBERTa[219] 1024 USTORY[263] 768 E5-Base-4k[289] 768 Image Vision Transformer (ViT)[55] 768 (Base) CLIP[196] 512 Audio Wav2Vec 2.0[16] 768 (Base) CLAP[247] 512 Video ViViT[9] 768 (Base) space for unified processing and retrieval.”
InfluentialBenchmarking Large Language Models in Retrieval-Augmented Generation
Chen, J., Lin, H., Han, X., & Sun, L. (2023) · arXiv · doi:10.48550/arxiv.2309.01431 · Cited by 455
Benchmarking Large Language Models in Retrieval-Augmented Generation
Chen, J., Lin, H., Han, X., & Sun, L. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i16.29728 · Cited by 454
PullNet: Open Domain Question Answering with Iterative Retrieval on Knowledge Bases and Text
Sun, H., Bedrax-Weiss, T., & Cohen, W. W. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1242 · Cited by 449
In-Context Retrieval-Augmented Language Models
Ram, O., Levine, Y., Dalmedigos, I., Muhlgay, D., Shashua, A., Leyton-Brown, K., & Shoham, Y. (2023) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00605 · Cited by 449
Neural Text Generation from Structured Data with Application to the Biography Domain
Lebret, R., Grangier, D., & Auli, M. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1128 · Cited by 444
LongLLMLingua: Accelerating and Enhancing LLMs in Long Context Scenarios via Prompt Compression
Jiang, H., Wu, Q., Luo, X., Li, D., Lin, C.-Y., Yang, Y., & Qiu, L. (2024) · Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2024.acl-long.91 · Cited by 400
SPLADE: Sparse Lexical and Expansion Model for First Stage Ranking
Formal, T., Piwowarski, B., & Clinchant, S. (2021) · Proceedings of the 44th International ACM SIGIR Conference on Research and Development in Information Retrieval · doi:10.1145/3404835.3463098 · Cited by 394
G-Retriever: Retrieval-Augmented Generation for Textual Graph Understanding and Question Answering
He, X., Tian, Y., Sun, Y., Chawla, N. V., Laurent, T., LeCun, Y., Bresson, X., & Hooi, B. (2024) · neural information processing systems · doi:10.52202/079017-4224 · Cited by 384
Least-to-Most Prompting Enables Complex Reasoning in Large Language Models
Zhou, D., Schärli, N., Hou, L., Wei, J., Scales, N., Wang, X., Schuurmans, D., Cui, C., Bousquet, O., Le, Q., et al. (2022) · arXiv · doi:10.48550/arxiv.2205.10625 · Cited by 380
Evaluation of Retrieval-Augmented Generation: A Survey
Yu, H., Gan, A., Zhang, K., Tong, S., Liu, Q., & Liu, Z. (2025) · Communications in computer and information science · doi:10.1007/978-981-96-1024-2_8 · Cited by 377
Self-citationPrecise Zero-Shot Dense Retrieval without Relevance Labels
Gao, L., Ma, X., Lin, J., & Callan, J. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.99 · Cited by 362
KILT: a Benchmark for Knowledge Intensive Language Tasks
Petroni, F., Piktus, A., Fan, A., Lewis, P., Yazdani, M., De Cao, N., Thorne, J., Jernite, Y., Karpukhin, V., Maillard, J., et al. (2021) · Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/2021.naacl-main.200 · Cited by 357
Interleaving Retrieval with Chain-of-Thought Reasoning for Knowledge-Intensive Multi-Step Questions
Trivedi, H., Balasubramanian, N., Khot, T., & Sabharwal, A. (2022) · arXiv · doi:10.48550/arxiv.2212.10509 · Cited by 349
Interleaving Retrieval with Chain-of-Thought Reasoning for Knowledge-Intensive Multi-Step Questions
Trivedi, H., Balasubramanian, N., Khot, T., & Sabharwal, A. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.557 · Cited by 349
Mallen, A., Asai, A., Zhong, V., Das, R., Khashabi, D., & Hajishirzi, H. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.546 · Cited by 340
A Survey on Retrieval-Augmented Text GenerationPreprint
Li, H., Su, Y., Cai, D., Wang, Y., & Liu, L. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2202.01110 · Cited by 331
Grigoriou, K., & Rothaermel, F. T. (2015) · Strategic Management Journal · doi:10.1002/smj.2489 · Cited by 328
ELI5: long form question answering
Fan, A., Jernite, Y., Perez, E., Grangier, D., Weston, J., & Auli, M. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1346 · Cited by 319
TypeSQL: Knowledge-Based Type-Aware Neural Text-to-SQL Generation
Tao, Y., Li, Z., Zhang, Z., Zhang, R., & Radev, D. (2018) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n18-2093 · Cited by 316
SGPT: GPT Sentence Embeddings for Semantic SearchPreprint
Muennighoff, N. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2202.08904 · Cited by 316
The impaired learning of semantic knowledge following bilateral medial temporal-lobe resection
Gabrieli, J. D. E., Cohen, N. J., & Corkin, S. (1988) · Brain and Cognition · doi:10.1016/0278-2626(88)90027-9 · Cited by 311
A Survey on Retrieval-Augmented Text Generation for Large Language Models
Huang, Y., & Huang, J. X. (2026) · ACM Computing Surveys · doi:10.1145/3805774 · Cited by 311
Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context
Gemini Team, Georgiev, P., Lei, V. I., Burnell, R., Bai, L., Gulati, A., Tanzer, G., Vincent, D., Pan, Z., Wang, S., et al. (2024) · arXiv · doi:10.48550/arxiv.2403.05530 · Cited by 306
Measuring and Narrowing the Compositionality Gap in Language Models
Press, O., Zhang, M., Min, S., Schmidt, L., Smith, N., & Lewis, M. (2023) · Findings of the Association for Computational Linguistics: EMNLP 2023 · doi:10.18653/v1/2023.findings-emnlp.378 · Cited by 303
Jeong, S., Baek, J., Cho, S., Hwang, S. J., & Park, J. (2024) · Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) · doi:10.18653/v1/2024.naacl-long.389 · Cited by 299
Constructing A Multi-hop QA Dataset for Comprehensive Evaluation of Reasoning Steps
Ho, X., Duong Nguyen, A.-K., Sugawara, S., & Aizawa, A. (2020) · Proceedings of the 28th International Conference on Computational Linguistics · doi:10.18653/v1/2020.coling-main.580 · Cited by 287
Generalization through Memorization: Nearest Neighbor Language Models
Khandelwal, U., Levy, O., Jurafsky, D., Zettlemoyer, L., & Lewis, M. (2019) · arXiv · doi:10.48550/arxiv.1911.00172 · Cited by 285
SQLizer: query synthesis from natural language
Yaghmazadeh, N., Wang, Y., Dillig, I., & Dillig, T. (2017) · Proceedings of the ACM on Programming Languages · doi:10.1145/3133887 · Cited by 284
GRAG: Graph Retrieval-Augmented Generation
Hu, Y., Lei, Z., Zhang, Z., Pan, B., Ling, C., & Zhao, L. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.232 · Cited by 284
♫ MuSiQue: Multihop Questions via Single-hop Question Composition
Trivedi, H., Balasubramanian, N., Khot, T., & Sabharwal, A. (2022) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00475 · Cited by 283
Zero-Shot Entity Linking by Reading Entity Descriptions
Logeswaran, L., Chang, M.-W., Lee, K., Toutanova, K., Devlin, J., & Lee, H. (2019) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p19-1335 · Cited by 275
WebGPT: Browser-assisted question-answering with human feedback
Nakano, R., Hilton, J., Balaji, S., Wu, J., Ouyang, L., Kim, C., Hesse, C., Jain, S., Kosaraju, V., Saunders, W., et al. (2021) · arXiv · doi:10.48550/arxiv.2112.09332 · Cited by 272
MuRAG: Multimodal Retrieval-Augmented Generator for Open Question Answering over Images and Text
Chen, W., Hu, H., Chen, X., Verga, P., & Cohen, W. W. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.375 · Cited by 268
RECOMP: Improving Retrieval-Augmented LMs with Compression and Selective AugmentationPreprint
Xu, F.-Y., Shi, W., & Choi, E. S. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.04408 · Cited by 268
Retrieval-augmented generation for natural language processing: a survey
Wu, S., Xiong, Y., Cui, Y., Wu, H., Chen, C., Yuan, Y., Huang, L., Liu, X., Kuo, T., Guan, N., et al. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-026-11605-7 · Cited by 256
(2023) · doi:10.18653/v1/2023.emnlp-main.574 · Cited by 249
Did Aristotle Use a Laptop? A Question Answering Benchmark with Implicit Reasoning Strategies
Geva, M., Khashabi, D., Segal, E., Khot, T., Roth, D., & Berant, J. (2021) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00370 · Cited by 242
Retrieval-Augmented Generation for AI-Generated Content: A Survey
Zhao, P., Zhang, H., Yu, Q., Wang, Z., Geng, Y., Fu, F., Yang, L., Zhang, W., Jiang, J., & Cui, B. (2024) · arXiv · doi:10.48550/arxiv.2402.19473 · Cited by 240
Retrieval-Augmented Generation with Knowledge Graphs for Customer Service Question Answering
Xu, Z., Cruz, M. M. C. D., Guevara, M., Wang, T., Deshpande, M., Wang, X., & Li, Z. (2024) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3626772.3661370 · Cited by 234
VisRAG: Vision-based Retrieval-augmented Generation on Multi-modality DocumentsPreprint
Shi, Y., Tang, C., Xu, B., Cui, J., Ran, J., Yan, Y., Liu, Z., Wang, S., Han, X., Liu, Z., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.10594 · Cited by 234
Take a Step Back: Evoking Reasoning via Abstraction in Large Language ModelsPreprint
Zheng, H., Mishra, S. R., Chen, X., Cheng, H.-T., Ed, H., Le, Q. V., & Zhou, D. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.06117 · Cited by 231
Lin, J., & Ma, X. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.14807 · Cited by 228
WebDancer: Towards Autonomous Information Seeking Agency
Wu, J., Li, B., Fang, R., Yin, W., Zhang, L., Wang, Z., Tao, Z., Zhang, D.-C., Xi, Z., Tang, R., et al. (2025) · neural information processing systems · doi:10.52202/085713-4035 · Cited by 227
Enabling Large Language Models to Generate Text with Citations
Gao, T., Yen, H., Yu, J., & Chen, D. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.398 · Cited by 216
LegalBench-RAG: A Benchmark for Retrieval-Augmented Generation in the Legal DomainPreprint
Pipitone, N., & Alami, G. H. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2408.10343 · Cited by 212
LightRAG: Simple and Fast Retrieval-Augmented Generation
Guo, Z., Xia, L., Yu, Y., Ao, T., & Huang, C. (2025) · Findings of the Association for Computational Linguistics: EMNLP 2025 · doi:10.18653/v1/2025.findings-emnlp.568 · Cited by 208
Graph Retrieval-Augmented Generation: A Survey
Peng, B., Zhu, Y., Liu, Y., Bo, X., Shi, H., Hong, C., Zhang, Y., & Tang, S. (2026) · ACM Transactions on Information Systems · doi:10.1145/3777378 · Cited by 206
Approximate Nearest Neighbor Negative Contrastive Learning for Dense Text Retrieval
Xiong, L., Xiong, C., Li, Y., Tang, K.-F., Liu, J., Bennett, P., Ahmed, J., & Overwijk, A. (2020) · arXiv · doi:10.48550/arxiv.2007.00808 · Cited by 204
Enhancing Retrieval-Augmented Large Language Models with Iterative Retrieval-Generation Synergy
Shao, Z., Gong, Y., Shen, Y., Huang, M., Duan, N., & Chen, W. (2023) · Findings of the Association for Computational Linguistics: EMNLP 2023 · doi:10.18653/v1/2023.findings-emnlp.620 · Cited by 200
Chain-of-Note: Enhancing Robustness in Retrieval-Augmented Language Models
Yu, W., Zhang, H., Pan, X., Cao, P., Ma, K., Li, J., Wang, H., & Yu, D. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-main.813 · Cited by 196
A Multi-Task Embedder For Retrieval Augmented LLMs
Zhang, P., Liu, Z., Xiao, S., Dou, Z., & Nie, J. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.194 · Cited by 179
Jiang, Z., Araki, J., Ding, H., & Neubig, G. (2021) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00407 · Cited by 177
Trustworthiness in Retrieval-Augmented Generation Systems: A SurveyPreprint
Zhou, Y., Zhang, W., Shao, J., Liu, Y., Li, X., Jin, J., Qian, H., Liu, Z., Li, C., Zhang, C., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2409.10102 · Cited by 169
Li, J., Yuan, Y., & Zhang, Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2403.10446 · Cited by 168
Retrieve and Refine: Improved Sequence Generation Models For Dialogue
Weston, J., Dinan, E., & Miller, A. (2018) · Proceedings of the 2018 EMNLP Workshop SCAI: The 2nd International Workshop on Search-Oriented Conversational AI · doi:10.18653/v1/w18-5713 · Cited by 165
Chain-of-Table: Evolving Tables in the Reasoning Chain for Table UnderstandingPreprint
Wang, Z., Zhang, H., Li, C., Eisenschlos, J. M., Perot, V., Wang, Z., Miculicich, L., Fujii, Y., Shang, J., Lee, C.-Y., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2401.04398 · Cited by 165
CRAG - Comprehensive RAG Benchmark
Yang, X., Sun, K., Xin, H., Sun, Y., Bhalla, N., Chen, X., Choudhary, S., Gui, R., Jiang, Z., Jiang, Z., et al. (2024) · neural information processing systems · doi:10.52202/079017-0335 · Cited by 162
From local to global: a graph rag approach to query-focused summarization
Edge, D., Trinh, H., Cheng, N., Bradley, J., Chao, A., Mody, A., Truitt, S., Metropolitansky, D., Ness, R. O., & Larson, J. (2024) · arXiv · doi:10.48550/arxiv.2404.16130 · Cited by 159
Entities as Experts: Sparse Memory Access with Entity Supervision
Févry, T., Soares, L. B., FitzGerald, N., Choi, E., & Kwiatkowski, T. (2020) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.400 · Cited by 158
Sui, Y., Zhou, M., Zhou, M., Han, S., & Zhang, D. (2024) · Proceedings of the 17th ACM International Conference on Web Search and Data Mining · doi:10.1145/3616855.3635752 · Cited by 155
ARES: An Automated Evaluation Framework for Retrieval-Augmented Generation Systems
Saad-Falcon, J., Khattab, O., Potts, C., & Zaharia, M. (2024) · Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) · doi:10.18653/v1/2024.naacl-long.20 · Cited by 148
Sawarkar, K., Mangal, A., & Solanki, S. R. (2024) · 2024 IEEE 7th International Conference on Multimedia Information Processing and Retrieval (MIPR) · doi:10.1109/mipr62202.2024.00031 · Cited by 145
Retrieval-Augmented Multimodal Language ModelingPreprint
Yasunaga, M., Aghajanyan, A., Shi, W., James, R., Leskovec, J., Liang, P., Lewis, M., Zettlemoyer, L., & Yih, W.-T. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2211.12561 · Cited by 144
On the differential nature of implicit and explicit memory
Parkin, A. J., Reid, T. K., & Russo, R. (1990) · Memory & Cognition · doi:10.3758/bf03198483 · Cited by 142
RARR: Researching and revising what language models say, using language models
Gao, L., Dai, Z., Pasupat, P., Chen, A., Chaganty, A. T., Fan, Y., Zhao, V., Lao, N., Lee, H., Juan, D.-C., et al. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.910 · Cited by 141
KG-RAG: Bridging the Gap Between Knowledge and CreativityPreprint
Sanmartin, D. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2405.12035 · Cited by 139
Biomedical knowledge graph-optimized prompt generation for large language models
Soman, K., Rose, P. W., Morris, J. H., Akbas, R. E., Smith, B., Peetoom, B., Villouta-Reyes, C., Cerono, G., Shi, Y., Rizk-Jackson, A., et al. (2024) · Bioinformatics · doi:10.1093/bioinformatics/btae560 · Cited by 135
Large Language Models Can Be Easily Distracted by Irrelevant Context
Shi, F., Chen, X., Misra, K., Scales, N., Dohan, D., Chi, E., Schärli, N., & Zhou, D. (2023) · arXiv · doi:10.48550/arxiv.2302.00093 · Cited by 134
RAP-Gen: Retrieval-Augmented Patch Generation with CodeT5 for Automatic Program Repair
Wang, W., Wang, Y., Joty, S., & Hoi, S. C. H. (2023) · ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering (ESEC/FSE) · doi:10.1145/3611643.3616256 · Cited by 134
Large Language Model based Long-tail Query Rewriting in Taobao Search
Peng, W., Li, G., Jiang, Y., Wang, Z., Ou, D., Zeng, X., Xu, D., Xu, T., & Chen, E. (2024) · International World Wide Web Conference (WWW) · doi:10.1145/3589335.3648298 · Cited by 116
Self-citationLate Chunking: Contextual Chunk Embeddings Using Long-Context Embedding ModelsPreprint
Günther, M., Mohr, I., Williams, D. L., Wang, B., & Xiao, H. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2409.04701 · Cited by 108
Failure to acquire new semantic knowledge in patients with large medial temporal lobe lesions
Bayley, P. J., & Squire, L. R. (2004) · Hippocampus · doi:10.1002/hipo.20057 · Cited by 105
RAT: Retrieval Augmented Thoughts Elicit Context-Aware Reasoning in Long-Horizon GenerationPreprint
Wang, Z., Liu, A., Lin, H., Li, J., Ma, X., & Liang, Y. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2403.05313 · Cited by 104
Distilling Knowledge from Reader to Retriever for Question Answering
Izacard, G., & Grave, E. (2020) · arXiv · doi:10.48550/arxiv.2012.04584 · Cited by 102
Asai, A., Wu, Z., Wang, Y., Sil, A., & Hajishirzi, H. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.11511 · Cited by 101
LeanContext: Cost-efficient domain-specific question answering using LLMs
Arefeen, M. A., Debnath, B. K., & Chakradhar, S. (2024) · Natural Language Processing Journal · doi:10.1016/j.nlp.2024.100065 · Cited by 100
Lyu, Y., Li, Z., Niu, S., Xiong, F., Tang, B., Wang, W., Wu, H., Liu, H., Xu, T., & Chen, E. (2025) · ACM Transactions on Information Systems · doi:10.1145/3701228 · Cited by 99
Self-citationThüs, D., Malone, S., & Brünken, R. (2024) · Frontiers in Psychology · doi:10.3389/fpsyg.2024.1474892 · Cited by 98
HotpotQA: A Dataset for Diverse, Explainable Multi-hop Question Answering
Yang, Z., Qi, P., Zhang, S., Bengio, Y., Cohen, W. W., Salakhutdinov, R., & Manning, C. D. (2018) · arXiv · doi:10.48550/arxiv.1809.09600 · Cited by 97
LongCite: Enabling LLMs to Generate Fine-grained Citations in Long-Context QA
Zhang, J., Bai, Y., Lv, X., Gu, W., Liu, D., Zou, M., Cao, S., Hou, L., Dong, Y., Feng, L., et al. (2025) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2025.findings-acl.264 · Cited by 97
ReACC: A Retrieval-Augmented Code Completion Framework
Lu, S., Duan, N., Han, H., Guo, D., Hwang, S.-W., & Svyatkovskiy, A. (2022) · arXiv · doi:10.48550/arxiv.2203.07722 · Cited by 96
Improving Retrieval for RAG based Question Answering Models on Financial DocumentsPreprint
Setty, S., Thakkar, H., Lee, A., Chung, E., & Vidra, N. (2024) · RePEc: Research Papers in Economics · doi:10.48550/arxiv.2404.07221 · Cited by 94
TILDE: Term Independent Likelihood moDEl for Passage Re-ranking
Zhuang, S., & Zuccon, G. (2021) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3404835.3462922 · Cited by 92
Jointly Optimizing Query Encoder and Product Quantization to Improve Retrieval Performance
Zhan, J., Mao, J., Liu, Y., Guo, J., Zhang, M., & Ma, S. (2021) · Proceedings of the 30th ACM International Conference on Information & Knowledge Management · doi:10.1145/3459637.3482358 · Cited by 91
Making Text Embedders Few-Shot LearnersPreprint
Li, C., Qin, M., Xiao, S., Chen, J., Luo, K., Shao, Y., Lian, D., & Liu, Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2409.15700 · Cited by 91
Don't Do RAG: When Cache-Augmented Generation is All You Need for Knowledge Tasks
Chan, B. J., Chen, C.-T., Cheng, J.-H., & Huang, H. (2025) · International World Wide Web Conference (WWW) · doi:10.1145/3701716.3715490 · Cited by 88
Retrieving Multimodal Information for Augmented Generation: A SurveyPreprint
Zhao, R. C., Chen, H., Wang, W., Jiao, F., Do, X. L., Qin, C., Ding, B., Guo, X., Li, M., Li, X., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2303.10868 · Cited by 87
MemoRAG: Boosting Long Context Processing with Global Memory-Enhanced Retrieval Augmentation
Qian, H., Liu, Z., Zhang, P., Mao, K., Lian, D., Dou, Z., & Huang, T. (2025) · Proceedings of the ACM on Web Conference 2025 · doi:10.1145/3696410.3714805 · Cited by 86
Ball*-tree: Efficient spatial indexing for constrained nearest-neighbor search in metric spacesPreprint
Dolatshah, M., Hadian, A., & Bidgoli, B. M. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1511.00628 · Cited by 85
KAG: Boosting LLMs in Professional Domains via Knowledge Augmented GenerationPreprint
Liang, L., Sun, M., Gui, Z., Zhu, Z., Jiang, Z., Zhong, L., Qu, Y., Zhao, P., Bo, Z., Yang, J. Y., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2409.13731 · Cited by 85
Trusting Your Evidence: Hallucinate Less with Context-aware Decoding
Shi, W., Han, X., Lewis, M., Tsvetkov, Y., Zettlemoyer, L., & Yih, W.-T. (2024) · Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 2: Short Papers) · doi:10.18653/v1/2024.naacl-short.69 · Cited by 83
Maximizing RAG efficiency: A comparative analysis of RAG methods
Şakar, T., & Emekci, H. (2024) · Natural language processing. · doi:10.1017/nlp.2024.53 · Cited by 83
InstructRAG: Instructing Retrieval-Augmented Generation via Self-Synthesized RationalesPreprint
Wei, Z., Chen, W., & Meng, Y. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2406.13629 · Cited by 80
Re2G: Retrieve, Rerank, Generate
Glass, M., Rossiello, G., Chowdhury, M. F. M., Naik, A., Cai, P., & Gliozzo, A. (2022) · Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/2022.naacl-main.194 · Cited by 79
RAGAs: Automated Evaluation of Retrieval Augmented Generation
Es, S., James, J., Espinosa-Anke, L., & Schockaert, S. (2023) · arXiv · doi:10.48550/arxiv.2309.15217 · Cited by 79
Parametric Retrieval Augmented Generation
Su, W., Tang, Y., Ai, Q., Yan, J., Wang, C., Wang, H., Ye, Z., Zhou, Y., & Liu, Y. (2025) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3726302.3729957 · Cited by 75
Dense X Retrieval: What Retrieval Granularity Should We Use?
Chen, T., Wang, H., Chen, S., Yu, W., Ma, K., Zhao, X., Zhang, H., & Yu, D. (2024) · Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2024.emnlp-main.845 · Cited by 74
OMNIPARSER: A Unified Framework for Text Spotting, Key Information Extraction and Table Recognition
Wan, J., Song, S., Yu, W., Liu, Y., Cheng, W., Huang, F., Bai, X., Yao, C., & Yang, Z. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01481 · Cited by 74
Think-on-Graph: Deep and Responsible Reasoning of Large Language Model on Knowledge Graph
Sun, J., Xu, C., Tang, L., Wang, S., Lin, C., Gong, Y., Ni, L. M., Shum, H.-Y., & Guo, J. (2023) · arXiv · doi:10.48550/arxiv.2307.07697 · Cited by 74
Zhan, J., Mao, J., Liu, Y., Guo, J., Zhang, M., & Ma, S. (2022) · Proceedings of the Fifteenth ACM International Conference on Web Search and Data Mining · doi:10.1145/3488560.3498443 · Cited by 72
Memory$^3$: Language Modeling with Explicit Memory
Yang, H., Lin, Z., Wang, W., Wu, H., Li, Z., Tang, B., Wei, W., Wang, J., Tang, Z., Song, S., et al. (2024) · Journal of Machine Learning · doi:10.4208/jml.240708 · Cited by 71
Understanding user intent in community question answering
Chen, L., Zhang, D., & Mark Levene, A. (2012) · International World Wide Web Conference (WWW) · doi:10.1145/2187980.2188206 · Cited by 70
LongEmbed: Extending Embedding Models for Long Context Retrieval
Zhu, D., Wang, L., Yang, N., et al. (2024) · Conference on Empirical Methods in Natural Language Processing · doi:10.48550/arxiv.2404.12096 · Cited by 70
Large-language models: The game-changers for materials science research
Yu, S., Ran, N., & Liu, J. (2024) · Artificial Intelligence Chemistry · doi:10.1016/j.aichem.2024.100076 · Cited by 67
Self-citationAugmentation-Adapted Retriever Improves Generalization of Language Models as Generic Plug-In
Yu, Z., Xiong, C., Shi, Y., & Liu, Z. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.136 · Cited by 65
Visual Semantics Allow for Textual Reasoning Better in Scene Text Recognition
He, Y., Chen, C., Zhang, J., Liu, J., He, F., Wang, C., & Du, B. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i1.19971 · Cited by 64
Retrieving Multimodal Information for Augmented Generation: A Survey
Zhao, R., Chen, H., Wang, W., Jiao, F., Long, D., Qin, C., Ding, B., Guo, X., Li, M., Li, X., et al. (2023) · Findings of the Association for Computational Linguistics: EMNLP 2023 · doi:10.18653/v1/2023.findings-emnlp.314 · Cited by 63
RECALL: A Benchmark for LLMs Robustness against External Counterfactual KnowledgePreprint
Liu, Y., Huang, L., Li, S., Chen, S., Zhou, H., Meng, F., Zhou, J., & Sun, X. H. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.08147 · Cited by 61
RAGCache: Efficient Knowledge Caching for Retrieval-Augmented Generation
Jin, C., Zhang, Z., Jiang, X., Liu, F., Liu, S., Liu, X., & Jin, X. (2026) · ACM Transactions on Computer Systems · doi:10.1145/3768628 · Cited by 61
LumberChunker: Long-Form Narrative Document Segmentation
Duarte, A. V., Marques, J. D., Graça, M., Freire, M., Li, L., & Oliveira, A. L. (2024) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2024.findings-emnlp.377 · Cited by 60
Self-citationLiu, F., Kang, Z., & Han, X. (2024) · International Conference on Artificial Intelligence and Intelligent Information Processing (AIIIP) · doi:10.1145/3707292.3707358 · Cited by 60
Metacognitive Retrieval-Augmented Large Language Models
Zhou, Y., Liu, Z., Jin, J., Nie, J., & Dou, Z. (2024) · International World Wide Web Conference (WWW) · doi:10.1145/3589334.3645481 · Cited by 55
Business insights using RAG–LLMs: a review and case study
Arslan, M., Munawar, S., & Cruz, C. (2024) · Journal of Decision System · doi:10.1080/12460125.2024.2410040 · Cited by 54
Teaching language models to support answers with verified quotes
Menick, J., Trebacz, M., Mikulik, V., Aslanides, J., Song, F., Chadwick, M., Glaese, M., Young, S., Campbell-Gillingham, L., Irving, G., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.11147 · Cited by 53
TCRA-LLM: Token Compression Retrieval Augmented Large Language Model for Inference Cost Reduction
Liu, J., Li, L., Xiang, T., Wang, B., & Qian, Y. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.655 · Cited by 53
Self-citationWebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep ResearchPreprint
Li, Z., Guan, X., Zhang, B., Huang, S., Zhou, H., Lai, S., Yan, M., Jiang, Y. J., Xie, P., Huang, F., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2509.13312 · Cited by 53
Self-citationTables as Texts or Images: Evaluating the Table Reasoning Ability of LLMs and MLLMs
Deng, N., Sun, Z., He, R., Sikka, A., Chen, Y., Ma, L., Zhang, Y., & Mihalcea, R. F. (2024) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2024.findings-acl.23 · Cited by 52
K-means tree: an optimal clustering tree for unsupervised learning
Tavallali, P., Tavallali, P., & Singhal, M. (2020) · The Journal of Supercomputing · doi:10.1007/s11227-020-03436-2 · Cited by 51
Enhancing Contextual Understanding in Large Language Models through Contrastive Decoding
Zhao, Z., Monti, E., Lehmann, J., & Assem, H. (2024) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2024.naacl-long.237 · Cited by 51
LongEmbed: Extending Embedding Models for Long Context Retrieval
Zhu, D., Wang, L., Yang, N., Song, Y., Wu, W., Wei, F., & Li, S. (2024) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2024.emnlp-main.47 · Cited by 50
SafeRAG: Benchmarking Security in Retrieval-Augmented Generation of Large Language Model
Liang, X., Niu, S., Li, Z., Zhang, S., Wang, H., Xiong, F., Fan, Z., Tang, B., Zhao, J., Yang, J., et al. (2025) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2025.acl-long.230 · Cited by 50
HtmlRAG: HTML is Better Than Plain Text for Modeling Retrieved Knowledge in RAG Systems
Tan, J., Dou, Z., Wang, W., Wang, M., Chen, W., & Wen, J.-R. (2025) · International World Wide Web Conference (WWW) · doi:10.1145/3696410.3714546 · Cited by 48
TabPedia: Towards Comprehensive Visual Table Understanding with Concept Synergy
Zhao, W., Feng, H., Liu, Q., Tang, J., Wei, S., Wu, B., Liao, L., Ye, Y., Líu, H., Zhou, W., et al. (2024) · neural information processing systems · doi:10.52202/079017-0230 · Cited by 48
Self-citationA RAG Chatbot for Precision Medicine of Multiple MyelomaPreprint
Quidwai, M., & Laganà, A. (2024) · medRxiv · doi:10.1101/2024.03.14.24304293 · Cited by 47
Lee, M., An, S., & Kim, M. (2024) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2024.naacl-long.364 · Cited by 47
WikiAsp: A Dataset for Multi-domain Aspect-based Summarization
Hayashi, H., Budania, P., Wang, P., Ackerson, C., Neervannan, R., & Neubig, G. (2021) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00362 · Cited by 46
Learning Transferable User Representations with Sequential Behaviors via Contrastive Pre-training
Cheng, M., Yuan, F., Liu, Q., Xin, X., & Chen, E. (2021) · Proceedings · doi:10.1109/icdm51629.2021.00015 · Cited by 46
Self-citationKalra, R., Wu, Z., Gulley, A., Hilliard, A., Guan, X., Koshiyama, A., & Treleaven, P. C. (2024) · Workshop on Customizable NLP: Progress and Challenges in Customizing NLP for a Domain, Application, Group, or Individual (CustomNLP4U) · doi:10.18653/v1/2024.customnlp4u-1.18 · Cited by 46
Da, C., Wang, P., & Yao, C. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19815-1_19 · Cited by 45
Chain-of-Verification Reduces Hallucination in Large Language Models
Dhuliawala, S., Komeili, M., Xu, J., Raileanu, R., Li, X., Celikyilmaz, A., & Weston, J. (2023) · arXiv · doi:10.48550/arxiv.2309.11495 · Cited by 42
Curriculum Contrastive Context Denoising for Few-shot Conversational Dense Retrieval
Mao, K., Dou, Z., & Qian, H. (2022) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3477495.3531961 · Cited by 41
TableRAG: Million-Token Table Understanding with Language Models
Chen, S., Miculicich, L., Eisenschlos, J. M., Wang, Z., Wang, Z., Chen, Y., Fujii, Y., Lin, H.-T., Lee, C.-Y., & Pfister, T. (2024) · neural information processing systems · doi:10.52202/079017-2382 · Cited by 41
Mention Memory: incorporating textual knowledge into Transformers through entity mention attentionPreprint
de Jong, M., Zemlyanskiy, Y., FitzGerald, N., Sha, F., & Cohen, W. W. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2110.06176 · Cited by 40
LLM Intelligent Agent Tutoring in Higher Education Courses Using a RAG Approach
Modran, H. A., Bogdan, C., Ursuțiu, D., Samoilă, C., & Modran, P. L. (2025) · Lecture notes in networks and systems · doi:10.1007/978-3-031-83520-9_54 · Cited by 40
Reasoning-Enhanced Healthcare Predictions with Knowledge Graph Community RetrievalPreprint
Jiang, P., Xiao, C., Jiang, M., Bhatia, P., Kass‐Hout, T., Sun, J., & Han, J. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2410.04585 · Cited by 38
Barron, R., Grantcharov, V., Wanna, S., Eren, M. E., Bhattarai, M., Solovyev, N., Tompkins, G., Nicholas, C., Rasmussen, K. Ø., Matuszek, C., et al. (2024) · International Conference on Machine Learning and Applications · doi:10.1109/icmla61862.2024.00258 · Cited by 38
Qian, H., Zhu, Y., Dou, Z., Gu, H., Zhang, X., Liu, Z., Lai, R., Cao, Z., Nie, J., & Wen, J.-R. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2304.04358 · Cited by 36
RAPTOR: Recursive Abstractive Processing for Tree-Organized Retrieval
Sarthi, P., Abdullah, S., Tuli, A., Khanna, S., Goldie, A., & Manning, C. D. (2024) · arXiv · doi:10.48550/arxiv.2401.18059 · Cited by 36
A Comprehensive Survey on Vector Database: Storage and Retrieval Technique, Challenge
Ma, L., Zhang, R., Han, Y., Yu, S., Wang, Z., Ning, Z., Zhang, J., Xu, P., Li, P., Qiao, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2310.11703 · Cited by 34
Self-citationUPRISE: Universal Prompt Retrieval for Improving Zero-Shot Evaluation
Cheng, D., Huang, S., Bi, J., Zhan, Y., Liu, J., Wang, Y., Sun, H., Wei, F., Deng, W., & Zhang, Q. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.758 · Cited by 32
IDAS: Intelligent Driving Assistance System Using RAG
Hernandez-Salinas, L.-B., Terven, J. R., Chávez‐Urbiola, E. A., Esparza, D. M. C., Romero-González, J.-A., Argüelles-Cruz, A.-J., & Cervantes, I. (2024) · IEEE Open Journal of Vehicular Technology · doi:10.1109/ojvt.2024.3447449 · Cited by 32
The Russian-focused embedders’ exploration: ruMTEB benchmark and Russian embedding model design
Snegirev, A., Tikhonova, M., Anna, M., Fenogenova, A., & Abramov, A. (2025) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2025.naacl-long.12 · Cited by 31
Xia, S., Wang, X., Liang, J., Zhang, Y., Zhou, W., Deng, J., Yu, F., & Xiao, Y. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.55 · Cited by 29
Language Models are Universal Embedders
Zhang, X., Li, Z., Zhang, Y., Long, D., Xie, P., Zhang, M., & Zhang, M. (2025) · Joint Workshop on Large Language Models and Structure Modeling (XLLM) · doi:10.18653/v1/2025.xllm-1.21 · Cited by 29
Incorporating Structural Information into Legal Case Retrieval
Ma, Y., Wu, Y., Ai, Q., Liu, Y., Shao, Y., Zhang, M., & Ma, S. (2023) · ACM Transactions on Information Systems · doi:10.1145/3609796 · Cited by 28
Sequence Model with Self-Adaptive Sliding Window for Efficient Spoken Document Segmentation
Zhang, Q., Chen, Q., Li, Y., Liu, J., & Wang, W. (2021) · IEEE Workshop on Automatic Speech Recognition and Understanding (ASRU) · doi:10.1109/asru51503.2021.9688078 · Cited by 27
Research works printed but not linked: 66
- Rubayyi Alghamdi and Khalid Alfalqi. 2015. A survey of topic modeling in text mining. Int. J. Adv. Comput. Sci. Appl.(IJACSA) 6, 1 (2015).
- Avinash Anand, Arnav Goel, Medha Hira, Snehal Buldeo, Jatin Kumar, Astha Verma, Rushali Gupta, and Rajiv Ratn Shah. 2023. Sciphyrag-retrieval augmentation to improve llms on physics q &a. In International Conference on Big Data Analytics. Springer, 50-63.
- Apache Software Foundation. 2024. HugeGraph Documentation. https://hugegraph.apache.org/docs/ Accessed: 2024-11-05. Manuscript submitted to ACM
- Alexei Baevski, Yuhao Zhou, Abdelrahman Mohamed, and Michael Auli. 2020. wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations. In Advances in Neural Information Processing Systems, H. Larochelle, M. Ranzato, R. Hadsell, M.F. Balcan, and H. Lin (Eds.), Vol. 33. Curran Associates, Inc., 12449-12460. https://proceedings.neurips.cc/paper_files/paper/2020/file/92d1e1eb1cd6f9fba3227870bb6d7f07-Paper.pdf
- Sebastian Borgeaud, Arthur Mensch, Jordan Hoffmann, Trevor Cai, Eliza Rutherford, Katie Millican, George Bm Van Den Driessche, Jean-Baptiste Lespiau, Bogdan Damoc, Aidan Clark, et al. 2022. Improving language models by retrieving from trillions of tokens. In International conference on machine learning. PMLR, 2206-2240.
- Andy Brock, Soham De, Samuel L Smith, and Karen Simonyan. 2021. High-Performance Large-Scale Image Recognition Without Normalization. In Proceedings of the 38th International Conference on Machine Learning (Proceedings of Machine Learning Research, Vol. 139), Marina Meila and Tong Zhang (Eds.). PMLR, 1059-1071. https://proceedings.mlr.press/v139/brock21a.html
- Si-An Chen, Lesly Miculicich, Julian Martin Eisenschlos, Zifeng Wang, Zilong Wang, Yanfei Chen, Yasuhisa Fujii, Hsuan-Tien Lin, Chen-Yu Lee, and Tomas Pfister. 2024. TableRAG: Million-Token Table Understanding with Language Models. arXiv preprint arXiv:2410.04739 (2024). · arXiv
- Paolo Ciaccia, Marco Patella, Pavel Zezula, et al. 1997. M-tree: An efficient access method for similarity search in metric spaces. In Vldb, Vol. 97. Citeseer, 426-435.
- Kevin Clark, Minh-Thang Luong, Quoc V. Le, and Christopher D. Manning. 2020. ELECTRA: Pre-training Text Encoders as Discriminators Rather Than Generators. In International Conference on Learning Representations. https://openreview.net/forum?id=r1xMH1BtvB
- Suzanne Corkin. 2002. What's new with the amnesic patient HM? Nature reviews neuroscience 3, 2 (2002), 153-160.
- Michiel De Jong, Yury Zemlyanskiy, Nicholas FitzGerald, Joshua Ainslie, Sumit Sanghai, Fei Sha, and William W Cohen. 2023. Pre-computed memory or on-the-fly encoding? A hybrid approach to retrieval augmentation makes the most of your compute. In International Conference on Machine Learning. PMLR, 7329-7342.
- Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, and Neil Houlsby. 2021. An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. In International Conference on Learning Representations. https://openreview.net/forum?id=YicbFdNTTy
- Adel Elmessiry and Magdi Elmessiry. 2024. NAVIGATING THE EVOLUTION OF ARTIFICIAL INTELLIGENCE: TOWARDS EDUCATION-SPECIFIC RETRIEVAL AUGMENTED GENERATIVE AI (ES-RAG-AI). In INTED2024 Proceedings. IATED, 7692-7697.
- Hady Elsahar, Pavlos Vougiouklis, Arslen Remaci, Christophe Gravier, Jonathon Hare, Frederique Laforest, and Elena Simperl. 2018. T-rex: A large scale alignment of natural language with knowledge base triples. In Proceedings of the Eleventh International Conference on Language Resources and Evaluation (LREC 2018).
- Zhengcong Fei. 2021. Memory-augmented image captioning. In Proceedings of the AAAI Conference on Artificial Intelligence, Vol. 35. 1317-1324.
- Clinton Gormley and Zachary Tong. 2015. Elasticsearch: the definitive guide: a distributed real-time search and analytics engine. " O'Reilly Media, Inc. ".
- Antonin Guttman. 1984. R-trees: A dynamic index structure for spatial searching. In Proceedings of the 1984 ACM SIGMOD international conference on Management of data. 47-57.
- Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat, and Mingwei Chang. 2020. Retrieval augmented language model pre-training. In International conference on machine learning. PMLR, 3929-3938.
- Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat, and Mingwei Chang. 2020. Retrieval Augmented Language Model Pre-Training. In Proceedings of the 37th International Conference on Machine Learning (Proceedings of Machine Learning Research, Vol. 119), Hal Daumé III and Aarti Singh (Eds.). PMLR, 3929-3938. https://proceedings.mlr.press/v119/guu20a.html
- Zheng Liu Kelong Mao Zhicheng Dou Hongjin Qian, Peitian Zhang. 2024. MemoRAG: Moving towards Next-Gen RAG Via Memory-Inspired Knowledge Discovery. arXiv:2409.05591 (2024). · arXiv
- Edward J Hu, yelong shen, Phillip Wallis, Zeyuan Allen-Zhu, Yuanzhi Li, Shean Wang, Lu Wang, and Weizhu Chen. 2022. LoRA: Low-Rank Adaptation of Large Language Models. In International Conference on Learning Representations. https://openreview.net/forum?id=nZeVKeeFYf9
- Po-Sen Huang, Xiaodong He, Jianfeng Gao, Li Deng, Alex Acero, and Larry Heck. 2013. Learning deep structured semantic models for web search using clickthrough data. In Proceedings of the 22nd ACM international conference on Information & Knowledge Management. 2333-2338.
- Gautier Izacard and Edouard Grave. 2020. Leveraging passage retrieval with generative models for open domain question answering. arXiv preprint arXiv:2007.01282 (2020). · arXiv
- Jinhao Jiang, Kun Zhou, Zican Dong, Keming Ye, Wayne Xin Zhao, and Ji-Rong Wen. 2023. StructGPT: A General Framework for Large Language Model to Reason over Structured Data. arXiv:2305.09645 [cs.CL] https://arxiv.org/abs/2305.09645 · arXiv
- Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih. 2020. Dense passage retrieval for open-domain question answering. arXiv preprint arXiv:2004.04906 (2020). · arXiv
- Urvashi Khandelwal, Omer Levy, Dan Jurafsky, Luke Zettlemoyer, and Mike Lewis. 2020. Generalization through Memorization: Nearest Neighbor Language Models. arXiv:1911.00172 [cs.CL] https://arxiv.org/abs/1911.00172 · arXiv
- Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, and Radu Soricut. 2020. ALBERT: A Lite BERT for Self-supervised Learning of Language Representations. In International Conference on Learning Representations. https://openreview.net/forum?id=H1eA7AEtvS
- Patrick Lewis, Ethan Perez, Aleksandra Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, et al. 2020. Retrieval-augmented generation for knowledge-intensive nlp tasks. Advances in Neural Information Processing Systems 33 (2020), 9459-9474.
- Patrick Lewis, Ethan Perez, Aleksandra Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, and Douwe Kiela. 2020. Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. In Advances in Neural Information Processing Systems, H. Larochelle, M. Ranzato, R. Hadsell, M.F. Balcan, and H. Lin (Eds.), Vol. 33. Curran Associates, Inc., 9459-9474. https://proceedings.neurips.cc/paper_files/paper/2020/file/6b493230205f780e1bc26945df7481e5-Paper.pdf
- Chaofan Li, Zheng Liu, Shitao Xiao, Yingxia Shao, and Defu Lian. 2024. Llama2vec: Unsupervised adaptation of large language models for dense retrieval. In Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). 3490-3500.
- Jia Allen Li, Yongmin Li, Ge Li, Xing Hu, Xin Xia, and Zhi Jin. 2021. Editsum: A retrieve-and-edit framework for source code summarization. In 2021 36th IEEE/ACM International Conference on Automated Software Engineering (ASE). IEEE, 155-166. Manuscript submitted to ACM
- Xin Li and Dan Roth. 2002. Learning question classifiers. In COLING 2002: The 19th International Conference on Computational Linguistics.
- Chang Liu, Loc Hoang, Andrew Stolman, and Bo Wu. 2024. HiTA: A RAG-Based Educational Platform that Centers Educators in the Instructional Loop. In International Conference on Artificial Intelligence in Education. Springer, 405-412.
- Haomiao Liu, Ruiping Wang, Shiguang Shan, and Xilin Chen. 2016. Deep supervised hashing for fast image retrieval. In Proceedings of the IEEE conference on computer vision and pattern recognition. 2064-2072.
- Ting Liu, Andrew W Moore, Alexander Gray, and Claire Cardie. 2006. New algorithms for efficient high-dimensional nonparametric classification. Journal of machine learning research 7, 6 (2006).
- Yufeng Liu. 2024. The application of RAG technology in traditional chinese medicine. In 2024 international conference on artificial intelligence and communication (ICAIC 2024). Atlantis press, 402-408.
- Siwen Luo, Yihao Ding, Siqu Long, Josiah Poon, and Soyeon Caren Han. 2022. Doc-gcn: Heterogeneous graph convolutional networks for document layout analysis. In Proceedings of the 29th International Conference on Computational Linguistics. 2906-2916.
- Yucong Luo, Mingyue Cheng, Hao Zhang, Junyu Lu, and Enhong Chen. 2024. Unlocking the potential of large language models for explainable recommendations. In International Conference on Database Systems for Advanced Applications. Springer, 286-303.
- Shengjie Ma, Chengjin Xu, Xuhui Jiang, Muzhi Li, Huaren Qu, Cehao Yang, Jiaxin Mao, and Jian Guo. 2024. Think-on-Graph 2.0: Deep and Faithful Large Language Model Reasoning with Knowledge-guided Retrieval Augmented Generation. arXiv:2407.10805 [cs.CL] https://arxiv.org/abs/2407. 10805 · arXiv
- Xueguang Ma, Liang Wang, Nan Yang, Furu Wei, and Jimmy Lin. 2024. Fine-tuning llama for multi-stage text retrieval. In Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval. 2421-2425.
- Tomas Mikolov, Ilya Sutskever, Kai Chen, Greg S Corrado, and Jeff Dean. 2013. Distributed Representations of Words and Phrases and their Compositionality. In Advances in Neural Information Processing Systems, C.J. Burges, L. Bottou, M. Welling, Z. Ghahramani, and K.Q. Weinberger (Eds.), Vol. 26. Curran Associates, Inc. https://proceedings.neurips.cc/paper_files/paper/2013/file/9aa42b31882ec039965f3c4923ce901b-Paper.pdf
- Neo4j, Inc. 2024. Neo4j Documentation. https://neo4j.com/docs/ Accessed: 2024-11-05. Manuscript submitted to ACM
- Chaima Njeh, Haïfa Nakouri, and Fehmi Jaafar. 2024. Enhancing RAG-Retrieval to Improve LLMs Robustness and Resilience to Hallucinations. In International Conference on Hybrid Artificial Intelligence Systems. Springer, 201-213.
- Zhenyu Pan, Haozheng Luo, Manling Li, and Han Liu. 2025. Chain-of-Action: Faithful and Multimodal Question Answering through Large Language Models. In The Thirteenth International Conference on Learning Representations. https://openreview.net/forum?id=1BdPHbuimc
- Kishore Papineni, Salim Roukos, Todd Ward, and Wei-Jing Zhu. 2002. Bleu: a method for automatic evaluation of machine translation. In Proceedings of the 40th annual meeting of the Association for Computational Linguistics. 311-318.
- Boci Peng, Yun Zhu, Yongchao Liu, Xiaohe Bo, Haizhou Shi, Chuntao Hong, Yan Zhang, and Siliang Tang. 2024. Graph retrieval-augmented generation: A survey. arXiv preprint arXiv:2408.08921 (2024). · arXiv
- Jay M Ponte and W Bruce Croft. 2017. A language modeling approach to information retrieval. In ACM SIGIR Forum, Vol. 51. ACM New York, NY, USA, 202-208.
- Yujia Qin, Zihan Cai, Dian Jin, Lan Yan, Shihao Liang, Kunlun Zhu, Yankai Lin, Xu Han, Ning Ding, Huadong Wang, et al. 2023. WebCPM: Interactive Web Search for Chinese Long-form Question Answering. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). 8968-8988.
- Junyan Qiu and Yiping Yang. 2024. Learning to Deliberate: Multi-pass Decoding for Document-Grounded Conversations. In 2024 International Joint Conference on Neural Networks (IJCNN). IEEE, 1-8.
- Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, and Ilya Sutskever. 2021. Learning Transferable Visual Models From Natural Language Supervision. In Proceedings of the 38th International Conference on Machine Learning (Proceedings of Machine Learning Research, Vol. 139), Marina Meila and Tong Zhang (Eds.). PMLR, 8748-8763. https://proceedings.mlr.press/v139/radford21a.html
- Mahimai Raja, E Yuvaraajan, et al. 2024. A RAG-based Medical Assistant Especially for Infectious Diseases. In 2024 International Conference on Inventive Computation Technologies (ICICT). IEEE, 1128-1133.
- Parikshit Ram and Alexander G Gray. 2012. Maximum inner-product search using cone trees. In Proceedings of the 18th ACM SIGKDD international conference on Knowledge discovery and data mining. 931-939.
- Rita Ramos, Bruno Martins, Desmond Elliott, and Yova Kementchedjhieva. 2023. Smallcap: lightweight image captioning prompted with retrieval augmentation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition. 2840-2849.
- Stephen Robertson, Hugo Zaragoza, et al. 2009. The probabilistic relevance framework: BM25 and beyond. Foundations and Trends® in Information Retrieval 3, 4 (2009), 333-389.
- Stephen E Robertson and Steve Walker. 1997. On relevance weights with little relevance information. In Proceedings of the 20th annual international ACM SIGIR conference on Research and development in information retrieval. 16-24.
- Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Ł ukasz Kaiser, and Illia Polosukhin. 2017. Attention is All you Need. In Advances in Neural Information Processing Systems, I.
- Yair Weiss, Antonio Torralba, and Rob Fergus. 2008. Spectral hashing. Advances in neural information processing systems 21 (2008). Manuscript submitted to ACM
- Geemi Wellawatte, Huixuan Guo, Magdalena Lederbauer, Anna Borisova, Matthew Hart, Marta Brucka, and Philippe Schwaller. [n. d.]. ChemLit-QA: A human evaluated dataset for chemistry RAG tasks. In AI for Accelerated Materials Design-NeurIPS 2024.
- Nirmalie Wiratunga, Ramitha Abeyratne, Lasal Jayawardena, Kyle Martin, Stewart Massie, Ikechukwu Nkisi-Orji, Ruvan Weerasinghe, Anne Liret, and Bruno Fleisch. 2024. CBR-RAG: case-based reasoning for retrieval augmented generation in LLMs for legal question answering. In International Conference on Case-Based Reasoning. Springer, 445-460.
- Chenyan Xiong, Zhuyun Dai, Jamie Callan, Zhiyuan Liu, and Russell Power. 2017. End-to-end neural ad-hoc ranking with kernel pooling. In Proceedings of the 40th International ACM SIGIR conference on research and development in information retrieval. 55-64.
- Shicheng Xu, Liang Pang, Huawei Shen, Xueqi Cheng, and Tat-Seng Chua. 2024. Search-in-the-Chain: Interactively Enhancing Large Language Models with Search for Knowledge-intensive Tasks. In Proceedings of the ACM on Web Conference 2024. 1362-1373.
- Xiao Yang, Kai Sun, Hao Xin, Yushi Sun, Nikita Bhalla, Xiangsen Chen, Sajal Choudhary, Rongze Daniel Gui, Ziran Will Jiang, Ziyu Jiang, Lingkun Kong, Brian Moran, Jiaqi Wang, Yifan Ethan Xu, An Yan, Chenyu Yang, Eting Yuan, Hanwen Zha, Nan Tang, Lei Chen, Nicolas Scheffer, Yue Liu, Nirav Shah, Rakesh Wanga, Anuj Kumar, Wen tau Yih, and Xin Luna Dong. 2024. CRAG -Comprehensive RAG Benchmark. arXiv:2406.04744 [cs.CL] https://arxiv.org/abs/2406.04744 · arXiv
- Chi Yu, Guang Yang, Xiang Chen, Ke Liu, and Yanlin Zhou. 2022. Bashexplainer: Retrieval-augmented bash code comment generation based on fine-tuned codebert. In 2022 IEEE International Conference on Software Maintenance and Evolution (ICSME). IEEE, 82-93.
- John M. Zelle and Raymond J. Mooney. 1996. Learning to parse database queries using inductive logic programming. In Proceedings of the Thirteenth National Conference on Artificial Intelligence -Volume 2 (Portland, Oregon) (AAAI'96). AAAI Press, 1050-1055.
- Boyu Zhang, Hongyang Yang, Tianyu Zhou, Muhammad Ali Babar, and Xiao-Yang Liu. 2023. Enhancing financial sentiment analysis via retrieval augmented large language models. In Proceedings of the fourth ACM international conference on AI in finance. 349-356.
- Long Zhao, Nitesh Bharadwaj Gundavarapu, Liangzhe Yuan, Hao Zhou, Shen Yan, Jennifer J. Sun, Luke Friedman, Rui Qian, Tobias Weyand, Yue Zhao, Rachel Hornung, Florian Schroff, Ming-Hsuan Yang, David A Ross, Huisheng Wang, Hartwig Adam, Mikhail Sirotenko, Ting Liu, and Boqing Gong. 2024. VideoPrism: A Foundational Visual Encoder for Video Understanding. In Forty-first International Conference on Machine Learning. https://openreview.net/forum?id=oBP8vXFJNQ
Cited by
A Survey of Context Engineering for Large Language Models
Mei, L., Yao, J., Ge, Y., Wang, Y., Bi, B., Cai, Y., Liu, J., Li, M., Li, Z.-Z., Zhang, D., et al. (2025) · arXiv · doi:10.48550/arxiv.2507.13334 · Cited by 281
A survey on retrieval-augmentation generation (RAG) models for healthcare applications
El-Enen, M. A. A., Saad, S., & Nazmy, T. M. (2025) · Neural Computing and Applications · doi:10.1007/s00521-025-11666-9 · Cited by 89
Gan, A., Yu, H., Zhang, K., Liu, Q., Yan, W., Huang, Z., Tong, S., & Hu, G. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2504.14891 · Cited by 78
Self-citationFrom Web Search towards Agentic Deep Research: Incentivizing Search with Reasoning AgentsPreprint
Zhang, W., Li, Y., Bei, Y., Luo, J., Wan, G., Yang, L., Xie, C., Yang, Y., Huang, W., Miao, C., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.18959 · Cited by 65
Miao, Y., Zhao, Y., Luo, Y., Wang, H., & Wu, Y. (2025) · Journal of Medical Internet Research · doi:10.2196/80557 · Cited by 38
Self-citation
Metadata
- Authors
- Cheng, M., Luo, Y., Ouyang, J., Liu, Q., Liu, H., Li, L., Yu, S., Zhang, B., Cao, J., Ma, J., Wang, D., & Chen, E.
- Affiliations
- University of Science and Technology of China (CN)
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2025
- Volume
- 44
- Issue
- 8
- Pages
- 1-57
- ISSN
- 1046-8188 (ISSN-L)
- arXiv
- 2503.10677
- OpenAlex
- W6910741274
- Cited by
- 140
- References
- 232
- Citations by year
- 2026: 89 · 2025: 51
- FWCI
- 124.99
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- ACM Transactions on Information Systems (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- National Natural Science Foundation of China (62525606, 62502486)
- University of Science and Technology of China
- National Key Research and Development Program of China (2024YFC3308200)
- Fundamental Research Funds for the Central Universities
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Information Systems › Information Retrieval and Search Behavior
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Keywords
- retrieval-augmented generation, external knowledge integration, large language models, document retrieval, question answering, text summarization, information retrieval, retrieval efficiency, model interpretability, domain adaptation, multimodal retrieval, reasoning
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-14, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-14 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
