

The DOI matches its Crossref record; 71 of the 80 references it cites were found in a registry or an index, and 9 are not checked yet; none of the 187 sources its claims cite is checked for support yet.
Generative AI and intellectual property: a systematic literature review of possible issues and mitigations
Open accessAbstract
The voracious appetite of Generative Artificial Intelligence (GenAI) for data has raised a number of issues regarding copyright. We conducted a systematic literature review (SLR), focusing on the types of copyright-protected data involved, the main challenges for compliance, and the ongoing mitigation efforts. This study—encompassing the literature published between 2019 and the first half of 2025—seeks to examine the entire Generative AI pipeline under the lights of the European Union (EU) copyright legislation. At the input stage, recurring issues include opacity surrounding the use of training data, misalignment between content licences and their usage, and the lack of mechanisms to regulate web scrapers collecting training material. Concerns also arise from fine-tuning aimed at stylistic emulation, as well as inadvertent memorisation and verbatim reproduction of training material. Various mitigation strategies have emerged: watermarking, adversarial perturbation, training data attribution with eventual royalties distribution, synthetic datasets, and machine-readable Text and Data Mining (TDM) opt-out mechanisms. Output-related vulnerabilities are similarly relevant, as adversarial attacks may extract sensitive data or generate style-imitating content. Retrieval-Augmented Generation (RAG) offers improved transparency, but remains prone to misattribution. The review underscores ongoing research dedicated to enhancing transparency in GenAI’s output, including provenance-tracking protocols, blockchain-based integrity systems, watermarking techniques, and inference-time defences. Given the heterogeneity of the field, this review prioritised breadth over depth, leaving room for future studies while serving as a foundational guide for individuals with prior exposure or a developing understanding of the field. The findings underscore the necessity for enhanced copyright safeguards—potentially structured as multi-layered protective systems—and cross-sectoral collaboration to align rapid generative AI development with robust intellectual property protection.
Checked 2026-11-12 · 9 references not checked yet
Overview
CoChat Summary
Written by AI from the paper’s full text.
TL;DR
This systematic literature review maps copyright issues and mitigations across the generative AI input and output pipeline under EU law, based on 24 high-quality studies published between 2019 and early 2025. It finds recurring concerns around opaque training data, web scraping and licence misalignment, memorisation and style mimicry, and reviews technical and legal mitigations including watermarking, TDM opt-outs, attribution, synthetic data, and provenance tracking.
Key findings
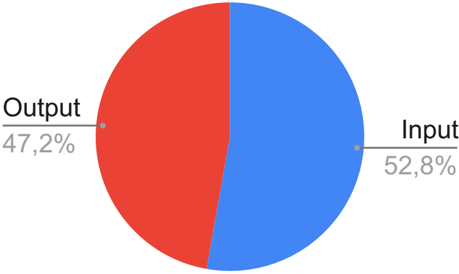
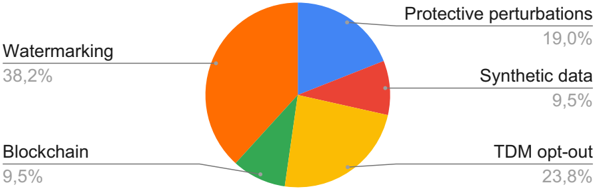
- The final SLR pool contained 24 sources, with input and output stages covered in a balanced way (52.8% input, 47.2% output). Input-stage mitigations explicitly mentioned included watermarking (38.2%), TDM opt-out (23.8%), protective perturbations (19.0%), synthetic data (9.5%), and blockchain (9.5%).
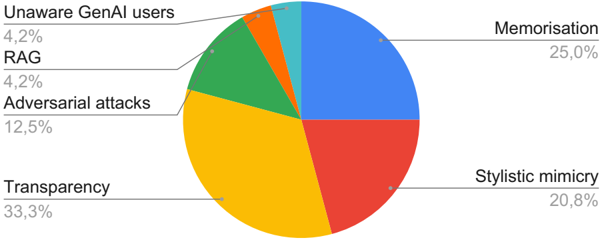
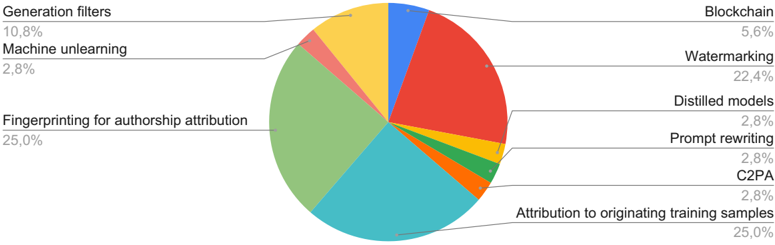
- Output-stage issues explicitly identified included transparency (33.3%), memorisation (25.0%), stylistic mimicry (20.8%), adversarial attacks (12.5%), RAG (4.2%), and unaware GenAI users (4.2%). Output mitigations included fingerprinting for authorship attribution (25.0%), attribution to originating training samples (25.0%), watermarking (22.4%), generation filters (10.8%), blockchain (5.6%), distilled models (2.8%), prompt rewriting (2.8%), C2PA (2.8%), and machine unlearning (2.8%).
- Specific reported results include: TPE truncation efficacy reached 99% in mathematics but dropped to 22% in coding; 93% of surveyed artists considered Glaze effective against generative style mimicry; approximately 80 million images were excluded from Stable Diffusion 3 training data; PREGen reduced direct-anchoring generation of copyrighted characters from 56.0–82.6% baseline to 0.6–6.6%, and indirect-anchoring from 26.6–27.4% to 0–2.0%.
- Other reported figures: fuzzy-fingerprint authorship attribution achieved 67.4% accuracy on 50 authors; Sakurai et al. achieved 88.4% accuracy on eight Japanese authors, with distillation reducing inference time from 20.33 to 3.38 s but decreasing accuracy by about 10%; DistilBERT has 40% fewer parameters and retains 97% of original performance; Lee et al. estimated nearly 1% of language model outputs are verbatim copies of training data.
Methods
- The authors conducted a systematic literature review following steps inspired by Garousi, Felderer & Mäntylä (2019) and quality-assessment guidelines from Kitchenham & Charters (2007), focusing on EU copyright law and the GenAI pipeline.
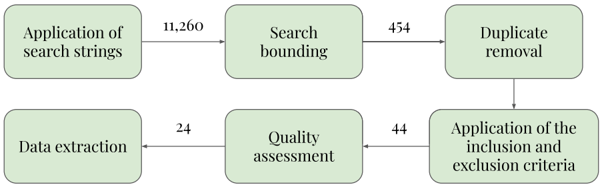
- Search strings covering GenAI and copyright were applied to ACM, IEEE, Springer, ScienceDirect, and Google Scholar, with a publication-year filter for 2019 to early 2025. Search bounding yielded 454 initial sources; after duplicate removal and inclusion/exclusion criteria, 44 sources remained.
- Two authors independently assessed source quality using tailored questionnaires; scores were normalised to 0–5, the average threshold was 3.48/5, and sources above this threshold were retained, resulting in 24 high-quality studies. Relevant information was extracted in structured form and organised around research questions for input and output stages.
Limitations
- The paper states that the topic’s fragmented nature made it harder to design an efficient and comprehensive search string; some recent rights-information-management initiatives such as JPEG Trust and Liccium’s Trust Engine fell outside its scope. It also states that audio and video remain underexplored, that the EU-only focus may lack global generalisability, and that the final corpus of 24 sources was smaller than that of a comparable secondary study.
- The authors state that legally charged keywords such as “copyright” likely biased ranking algorithms toward law-centric sources, limiting visibility of computer science literature, and that bounding strategies in Google Search and Springer Nature further restricted access to technical contributions. They also state that the review prioritised breadth over depth.
- Evident from the text: the review does not report new primary experiments; effectiveness figures are drawn from cited studies, and several mitigation results are described as limited by real-world transformations, model-specific vulnerabilities, or scalability constraints.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
103 Check pending · 65 Own interpretation · 32 Own result · 31 Sources not found · 24 No basis given · 22 No full text of the sources · 16 Not checked yet · 14 Own method
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It emerged that there is a marked lack of transparency regarding the specific training data employed in machine learning processes.”
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > GenAI input
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, their published manuscript lacks transparency regarding the methodology utilised for primary study selection.”
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > Related secondary studies
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Notably, press contents and open-source code appear to be particularly affected by data harvesting practices, mainly accomplished through web scraping activities.”
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > GenAI input
hedgedstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A check of a cited source is scheduled, or we don’t hold its full text yet; the claim is checked once it runs.
In the paper
“There are instances of models labelled as open-source due to the public availability of their internal parameters; however, this does not necessarily imply that the training datasets have also been disclosed (Widder, Whittaker & West, 2024;Liesenfeld & Dingemanse, 2024).”
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > GenAI input
What the sources say
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“This is especially true for commercial models, with AI companies often refraining from disclosing very fragmented composition of large training corpus.”
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > GenAI input
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 176
- It may state two separate claims as one. 57
Create a free account to see these claims.
Create a free account to see these assumptions.
97 more claims
Create a free account to see all 307 claims and to verify the 122 references still open.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > APPENDICES A. ONLINE MATERIAL
“| Year | 2024 |”
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > APPENDICES A. ONLINE MATERIAL
“| Reference | Intersection of generative artificial intelligence and copyright: an Indian perspective (Vig, 2026) |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > Misalignement of Licences:
“Some examples of these fine-tuning methods are Textual Inversion (Gal et al., 2022), DreamBooth (Ruiz et al., 2023), and Custom Diffusion (Kumari et al., 2023).”
§ Generative AI and intellectual property: a systematic literature review of possible issues and mitigations > Adversarial Attacks
“Another example is Textual Inversion: an image modification technique for Stable Diffusion that operates without the need for training or fine-tuning.”
Citations
Cites
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Learning Transferable Visual Models From Natural Language Supervision
Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., et al. (2021) · arXiv · doi:10.48550/arxiv.2103.00020 · Cited by 15,293
The Unreasonable Effectiveness of Deep Features as a Perceptual Metric
Zhang, R., Isola, P., Efros, A. A., Shechtman, E., & Wang, O. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00068 · Cited by 14,623
On the Opportunities and Risks of Foundation Models
Bommasani, R., Hudson, D. A., Adeli, E., Altman, R., Arora, S., von Arx, S., Bernstein, M. S., Bohg, J., Bosselut, A., Brunskill, E., et al. (2021) · arXiv · doi:10.48550/arxiv.2108.07258 · Cited by 2,676
DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation
Ruiz, N., Li, Y., Jampani, V., Pritch, Y., Rubinstein, M., & Aberman, K. (2022) · arXiv · doi:10.48550/arxiv.2208.12242 · Cited by 2,442
DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation
Ruiz, N., Li, Y., Jampani, V., Pritch, Y., Rubinstein, M., & Aberman, K. (2023) · 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52729.2023.02155 · Cited by 2,295
AutoPrompt: Eliciting Knowledge from Language Models with Automatically Generated Prompts
Shin, T., Razeghi, Y., Logan IV, R. L., Wallace, E., & Singh, S. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.346 · Cited by 1,279
LAION-5B: An open large-scale dataset for training next generation image-text models
Schuhmann, C., Beaumont, R., Vencu, R., Gordon, C., Wightman, R., Cherti, M., Coombes, T., Katta, A., Mullis, C., Wortsman, M., et al. (2022) · arXiv · doi:10.48550/arxiv.2210.08402 · Cited by 1,022
SinGAN: Learning a Generative Model From a Single Natural Image
Shaham, T. R., Dekel, T., & Michaeli, T. (2019) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00467 · Cited by 965
Garousi, V., Felderer, M., & Mäntylä, M. V. (2019) · Information and Software Technology · doi:10.1016/j.infsof.2018.09.006 · Cited by 831
Bourtoule, L., Chandrasekaran, V., Choquette-Choo, C. A., Jia, H., Travers, A., Zhang, B., Lie, D., & Papernot, N. (2021) · 2021 IEEE Symposium on Security and Privacy (SP) · doi:10.1109/sp40001.2021.00019 · Cited by 810
Multi-Concept Customization of Text-to-Image Diffusion
Kumari, N., Zhang, B., Zhang, R., Shechtman, E., & Zhu, J.-Y. (2023) · 2023 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52729.2023.00192 · Cited by 674
An Image is Worth One Word: Personalizing Text-to-Image Generation using Textual Inversion
Gal, R., Alaluf, Y., Atzmon, Y., Patashnik, O., Bermano, A. H., Chechik, G., & Cohen-Or, D. (2022) · arXiv · doi:10.48550/arxiv.2208.01618 · Cited by 611
The Secret Revealer: Generative Model-Inversion Attacks Against Deep Neural Networks
Zhang, Y., Jia, R., Pei, H., Wang, W., Li, B., & Song, D. X. (2020) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr42600.2020.00033 · Cited by 519
The Secret Revealer: Generative Model-Inversion Attacks Against Deep Neural Networks
Zhang, Y., Jia, R., Pei, H., Wang, W., Li, B., & Song, D. (2019) · arXiv · doi:10.48550/arxiv.1911.07135 · Cited by 465
Diffusion Art or Digital Forgery? Investigating Data Replication in Diffusion Models
Somepalli, G., Singla, V., Goldblum, M., Geiping, J., & Goldstein, T. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00586 · Cited by 318
StarCoder: may the source be with you!
Li, R., Allal, L. B., Zi, Y., Muennighoff, N., Kocetkov, D., Mou, C., Marone, M., Akiki, C., Li, J., Chim, J., et al. (2023) · arXiv · doi:10.48550/arxiv.2305.06161 · Cited by 261
A large-scale audit of dataset licensing and attribution in AI
Longpre, S., Mahari, R., Chen, A., Obeng-Marnu, N., Sileo, D., Brannon, W., Muennighoff, N., Khazam, N., Kabbara, J., Perisetla, K., et al. (2024) · Nature Machine Intelligence · doi:10.1038/s42256-024-00878-8 · Cited by 249
Explainable Generative AI (GenXAI): a survey, conceptualization, and research agenda
Schneider, J. (2024) · Artificial Intelligence Review · doi:10.1007/s10462-024-10916-x · Cited by 219
Quantifying Memorization Across Neural Language Models
Carlini, N., Ippolito, D., Jagielski, M., Lee, K., Tramer, F., & Zhang, C. (2022) · arXiv · doi:10.48550/arxiv.2202.07646 · Cited by 204
ChatGPT: A Case Study on Copyright Challenges for Generative Artificial Intelligence Systems
Lucchi, N. (2024) · European Journal of Risk Regulation · doi:10.1017/err.2023.59 · Cited by 173
Who Wrote this Code? Watermarking for Code Generation
Lee, T. P., Hong, S., Ahn, J., Hong, I., Lee, H., Yun, S., Shin, J., & Kim, G. (2024) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2024.acl-long.268 · Cited by 148
Right to be forgotten in the Era of large language models: implications, challenges, and solutions
Zhang, D., Finckenberg-Broman, P., Hoang, T., Pan, S., Xing, Z., Staples, M., & Xu, X. (2024) · AI and Ethics · doi:10.1007/s43681-024-00573-9 · Cited by 138
Rethinking open source generative AI: open washing and the EU AI Act
Liesenfeld, A., & Dingemanse, M. (2024) · The 2024 ACM Conference on Fairness, Accountability, and Transparency · doi:10.1145/3630106.3659005 · Cited by 123
Anti-DreamBooth: Protecting users from personalized text-to-image synthesis
Le, T. V., Phung, H., Nguyen, T. H., Dao, Q. T., Tran, N., & Tran, A. N. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00202 · Cited by 112
7. A value for n-person games. Contributions to the Theory of Games II (1953) 307–317
Shapley, L. (1997) · Classics in Game Theory · doi:10.1515/9781400829156-012 · Cited by 107
Nightshade: prompt-specific poisoning attacks on text-to-image generative models
Shan, S., Ding, W., Passananti, J., Wu, S., Zheng, H., & Zhao, B. Y. (2024) · 2024 IEEE Symposium on Security and Privacy (SP) · doi:10.1109/sp54263.2024.00207 · Cited by 93
Why ‘open’ AI systems are actually closed, and why this matters
Widder, D. G., Whittaker, M., & West, S. M. (2024) · Nature · doi:10.1038/s41586-024-08141-1 · Cited by 86
CoProtector: Protect Open-Source Code against Unauthorized Training Usage with Data Poisoning
Sun, Z., Du, X., Song, F., Ni, M., & Li, L. (2022) · International World Wide Web Conference (WWW) · doi:10.1145/3485447.3512225 · Cited by 77
Copyright and AI training data—transparency to the rescue?
Buick, A. (2025) · Journal of Intellectual Property Law and Practice · doi:10.1093/jiplp/jpae102 · Cited by 51
Embarrassingly Simple Text WatermarksPreprint
Sato, R., Takezawa, Y., Bao, H., Niwa, K., & Yamada, M. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2310.08920 · Cited by 45
Avoiding Copyright Infringement via Large Language Model Unlearning
Dou, G., Liu, Z., Lyu, Q., Ding, K., & Wong, E. (2025) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2025.findings-naacl.288 · Cited by 44
Gamification in Requirements Engineering: A Systematic Review
Cursino, R., Ferreira, D., Lencastre, M., Fagundes, R., & Pimentel, J. H. C. (2018) · International Conference on the Quality of Information and Communications Technology (QUATIC) · doi:10.1109/quatic.2018.00025 · Cited by 38
CodeMark: Imperceptible Watermarking for Code Datasets against Neural Code Completion Models
Sun, Z., Du, X., Song, F., & Li, L. (2023) · ACM Joint European Software Engineering Conference and Symposium on the Foundations of Software Engineering (ESEC/FSE) · doi:10.1145/3611643.3616297 · Cited by 37
FT-Shield: A Watermark Against Unauthorized Fine-tuning in Text-to-Image Diffusion Models
Cui, Y., Ren, J., Lin, Y., Xu, H., He, P., Xing, Y. Q., Lyu, L., Fan, W., Liu, H., & Tang, J. (2025) · ACM SIGKDD Explorations Newsletter · doi:10.1145/3715073.3715080 · Cited by 32
When deep learning meets watermarking: A survey of application, attacks and defenses
Chen, H., Liu, C., Zhu, T., & Zhou, W. (2024) · Computer Standards & Interfaces · doi:10.1016/j.csi.2023.103830 · Cited by 28
Fantastic Copyrighted Beasts and How (Not) to Generate ThemPreprint
He, L., Huang, Y., Shi, W., Xie, T., Liu, H., Wang, Y., Zettlemoyer, L., Zhang, C., Chen, D., & Henderson, P. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2406.14526 · Cited by 28
DUAW: Data-free Universal Adversarial Watermark against Stable Diffusion CustomizationPreprint
Ye, X., Huang, H., An, J., & Wang, Y. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2308.09889 · Cited by 26
The “Code” of Ethics: A Holistic Audit of AI Code Generators
Ma, W., Song, Y., Xue, M., Wen, S., & Xiang, Y. (2024) · IEEE Transactions on Dependable and Secure Computing · doi:10.1109/tdsc.2024.3367737 · Cited by 25
Can protective perturbation safeguard personal data from being exploited by stable diffusion?
Zhao, Z., Duan, J., Xu, K., Wang, C., Zhang, R., Du, Z., Guo, Q., & Hu, X. (2024) · 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52733.2024.02303 · Cited by 25
Legal challenges to generative AI, part I
Samuelson, P. (2023) · Communications of the ACM · doi:10.1145/3597151 · Cited by 22
Stealing Watermarks of Large Language Models via Mixed Integer Programming
Zhang, Z., Zhang, X., Zhang, Y., Zhang, L. Y., Chen, C., Hu, S., Gill, A. Q., & Pan, S. (2024) · Annual Computer Security Applications Conference · doi:10.1109/acsac63791.2024.00021 · Cited by 20
Should ChatGPT and Bard Share Revenue with Their Data Providers? A New Business Model for the AI Era
Zhang, D. (2023) · Advances in Artificial Intelligence and Machine Learning · doi:10.54364/aaiml.2023.1163 · Cited by 19
Who's Harry Potter? Approximate Unlearning in LLMs
Eldan, R., & Russinovich, M. (2023) · arXiv · doi:10.48550/arxiv.2310.02238 · Cited by 19
Risks, Causes, and Mitigations of Widespread Deployments of Large Language Models (LLMs): A Survey
Sakib, M. N., Islam, M. A., Pathak, R., & Arifin, M. M. (2024) · International Conference on Artificial Intelligence, Blockchain, and Internet of Things (AIBThings) · doi:10.1109/aibthings63359.2024.10863356 · Cited by 18
How to protect copyright data in optimization of large language models?
Chu, T., Song, Z., & Yang, C. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i16.29741 · Cited by 16
SrcMarker: Dual-Channel Source Code Watermarking via Scalable Code Transformations
Yang, B., Li, W., Xiang, L., & Li, B. (2024) · IEEE Symposium on Security and Privacy (S&P) · doi:10.1109/sp54263.2024.00097 · Cited by 15
Kassem, A., Mahmoud, O., & Saad, S. (2023) · Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2023.emnlp-main.265 · Cited by 12
Silent guardian: protecting text from malicious exploitation by large language models
Zhao, J., Chen, K., Yuan, X., Qi, Y., Zhang, W., & Yu, N. (2024) · IEEE Transactions on Information Forensics and Security · doi:10.1109/tifs.2024.3455775 · Cited by 12
Deduplicating Training Data Makes Language Models Better
Lee, K., Ippolito, D., Nystrom, A., Zhang, C., Eck, D., Callison-Burch, C., & Carlini, N. (2021) · arXiv · doi:10.48550/arxiv.2107.06499 · Cited by 11
Invisible Watermarking for Audio Generation Diffusion Models
Cao, X., Li, X., Jadav, D., Wu, Y., Chen, Z., Zeng, C., & Wei, W. (2023) · IEEE International Conference on Trust, Privacy and Security in Intelligent Systems and Applications (TPS-ISA) · doi:10.1109/tps-isa58951.2023.00033 · Cited by 11
Manteghi, M. (2024) · Law, Innovation and Technology · doi:10.1080/17579961.2024.2392928 · Cited by 9
WhyGen: Explaining ML-powered Code Generation by Referring to Training Examples
Yan, W., & Li, Y. (2022) · ACM/IEEE International Conference on Software Engineering: Companion Proceedings (ICSE-Companion) · doi:10.1109/icse-companion55297.2022.9793816 · Cited by 8
Intersection of generative artificial intelligence and copyright: an Indian perspective
Vig, S. (2026) · Journal of Science and Technology Policy Management · doi:10.1108/jstpm-08-2023-0145 · Cited by 8
CodeWMBench: An Automated Benchmark for Code Watermarking Evaluation
Wu, B., Chen, K., He, Y., Chen, G., Zhang, W., & Yu, N. (2024) · ACM Turing Celebration Conference - China (ACM TURC) · doi:10.1145/3674399.3674447 · Cited by 6
Kowala, M. (2024) · IIC - International Review of Intellectual Property and Competition Law · doi:10.1007/s40319-024-01515-y · Cited by 6
Tackling copyright issues in AI image generation through originality estimation and genericization
Chiba-Okabe, H., & Su, W. J. (2025) · Scientific Reports · doi:10.1038/s41598-025-90827-1 · Cited by 6
Unlearnable examples: protecting open-source software from unauthorized neural code learning
Ji, Z., Ma, P., & Wang, S. (2022) · International Conferences on Software Engineering and Knowledge Engineering · doi:10.18293/seke2022-066 · Cited by 5
RO-SVD: a reconfigurable hardware copyright protection framework for AIGC applications
Ran, Z., Abdelgawad, M. A. A., Zhang, Z., Cheung, R. C. C., & Yan, H. (2024) · 2024 IEEE 35th International Conference on Application-specific Systems, Architectures and Processors (ASAP) · doi:10.1109/asap61560.2024.00037 · Cited by 5
Leveraging fuzzy fingerprints from large language models for authorship attribution
Ribeiro, R., Carvalho, J. P., & Coheur, L. (2024) · 2024 IEEE International Conference on Fuzzy Systems (FUZZ-IEEE) · doi:10.1109/fuzz-ieee60900.2024.10612177 · Cited by 5
Generative artificial intelligence under German copyright law (part 1)
Lukas, A. J. F. (2023) · doi:10.2139/ssrn.4635645 · Cited by 4
Towards collecting royalties for copyrighted data for generative models
Ludwig, H., Zhou, Y., Zawad, S., Ong, Y., Li, P., Butler, E., & Zahid, E. (2024) · 2024 IEEE International Conference on Web Services (ICWS) · doi:10.1109/icws62655.2024.00020 · Cited by 4
Advancing membership inference attacks: the present and the future
Li, Z., & Zhang, Y. (2025) · Security and Safety · doi:10.1051/sands/2024017 · Cited by 4
Who wrote this code? Watermarking for code generation
Lee, T., Hong, S., Ahn, J., Hong, I., Lee, H., Yun, S., Shin, J., & Kim, G. (2023) · arXiv · doi:10.48550/arxiv.2305.15060 · Cited by 4
Chain-of-thought enhanced content detection in large language models
Zou, C., Feng, Z., Guan, H., & Xing, C. (2024) · 2024 3rd International Conference on Cloud Computing, Big Data Application and Software Engineering (CBASE) · doi:10.1109/cbase64041.2024.10824407 · Cited by 2
Efficient authorship attribution method using ensemble models built by knowledge distillation
Sakurai, W., Asano, M., Imoto, D., Honma, M., & Kurosawa, K. (2023) · 2023 9th International Conference on Computer and Communications (ICCC) · doi:10.1109/iccc59590.2023.10507584 · Cited by 1
Gradient-based adversarial attacks against text transformers
Guo, C., Sablayrolles, A., Jégou, H., & Kiela, D. (2021) · arXiv · doi:10.48550/arxiv.2104.13733
Preventing verbatim memorization in language models gives a false sense of privacy
Ippolito, D., Tramèr, F., Nasr, M., Zhang, C., Jagielski, M., Lee, K., Choquette-Choo, C. A., & Carlini, N. (2022) · arXiv · doi:10.48550/arxiv.2210.17546
Extracting Training Data from Diffusion Models
Carlini, N., Hayes, J., Nasr, M., Jagielski, M., Sehwag, V., Tramèr, F., Balle, B., Ippolito, D., & Wallace, E. (2023) · arXiv · doi:10.48550/arxiv.2301.13188
Glaze: protecting artists from style mimicry by text-to-image models
Shan, S., Cryan, J., Wenger, E., Zheng, H., Hanocka, R., & Zhao, B. Y. (2023) · arXiv · doi:10.48550/arxiv.2302.04222
Jailbreaking ChatGPT via prompt engineering: an empirical study
Liu, Y., Deng, G., Xu, Z., Li, Y., Zheng, Y., Zhang, Y., Zhao, L., Zhang, T., Wang, K., & Liu, Y. (2023) · arXiv · doi:10.48550/arxiv.2305.13860
Unlearnable examples for diffusion models: protect data from unauthorized exploitation
Zhao, Z., Duan, J., Hu, X., Xu, K., Wang, C., Zhang, R., Du, Z., Guo, Q., & Chen, Y. (2023) · arXiv · doi:10.48550/arxiv.2306.01902
Copyright protection in generative AI: a technical perspective
Ren, J., Xu, H., He, P., Cui, Y., Zeng, S., Zhang, J., Wen, H., Ding, J., Huang, P., Lyu, L., et al. (2024) · arXiv · doi:10.48550/arxiv.2402.02333
An economic solution to copyright challenges of generative AI
Wang, J. T., Deng, Z., Chiba-Okabe, H., Barak, B., & Su, W. J. (2024) · arXiv · doi:10.48550/arxiv.2404.13964
Bourtoule, L., Chandrasekaran, V., Choquette-Choo, C. A., Jia, H., Travers, A., Zhang, B., Lie, D., & Papernot, N. (2019) · arXiv · doi:10.48550/arxiv.1912.03817
The Data Provenance Initiative: A Large Scale Audit of Dataset Licensing & Attribution in AI
Longpre, S., Mahari, R., Chen, A., Obeng-Marnu, N., Sileo, D., Brannon, W., Muennighoff, N., Khazam, N., Kabbara, J., Perisetla, K., et al. (2023) · arXiv · doi:10.48550/arxiv.2310.16787
AutoPrompt: eliciting knowledge from language models with automatically generated prompts
Shin, T., Razeghi, Y., Logan, R. L., Wallace, E., & Singh, S. (2020) · arXiv · doi:10.48550/arxiv.2010.15980
Diffusion art or digital forgery? Investigating data replication in diffusion models
Somepalli, G., Singla, V., Goldblum, M., Geiping, J., & Goldstein, T. (2022) · arXiv · doi:10.48550/arxiv.2212.03860
Right to be Forgotten in the Era of Large Language Models: Implications, Challenges, and Solutions
Zhang, D., Finckenberg-Broman, P., Hoang, T., Pan, S., Xing, Z., Staples, M., & Xu, X. (2023) · arXiv · doi:10.48550/arxiv.2307.03941
The unreasonable effectiveness of deep features as a perceptual metric
Zhang, R., Isola, P., Efros, A. A., Shechtman, E., & Wang, O. (2018) · arXiv · doi:10.48550/arxiv.1801.03924
Research works printed but not linked: 1
- Cooper, 2025, The files are in the computer: on copyright, memorization, and generative AI, Chicago-Kent Law Review, 100, 141
Cited by
(n.d.) · GSI Repository (German Federal Government) · doi:10.5204/lthj · Cited by 3
Introduction: Ordering of Human-Artificial Intelligent Constructs
Arvidsson, M., & Tranter, K. M. (2026) · Law Technology and Humans · doi:10.5204/lthj.4923
Legal Challenges of Generative Artificial Intelligence in Intellectual Property Protection
Junaidi (2026) · Jurnal Hukum dan Keadilan · doi:10.61942/jhk.v3i5.670
Metadata
- Authors
- Arnaudo, A., Coppola, R., Morisio, M., Vetrò, A., Borghi, M., Raso, R., & Khan, B.
- Affiliations
- Politecnico di Torino (IT)
- University of Turin (IT)
- Venue
- PeerJ Computer Science
- Publisher
- PeerJ
- Published
- 2026-06-29
- Volume
- 12
- Pages
- e3928
- ISSN
- 2376-5992 (ISSN-L)
- OpenAlex
- W7166565796
- Cited by
- 2
- References
- 71
- Citations by year
- 2026: 2
- FWCI
- 0.99
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- PeerJ Computer Science (publishedVersion, cc-by)
- PORTO@Iris (submittedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Law, AI, and Intellectual Property
- Social Sciences › Law › Digitalization, Law, and Regulation
- Social Sciences › Law › Intellectual Property Rights and Media
- Keywords
- generative AI, copyright, intellectual property, training data, EU copyright law, web scraping, fine-tuning, watermarking, adversarial perturbations, retrieval-augmented generation, provenance tracking
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-12, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-12 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
