

The DOI matches its Crossref record; 36 of the 37 references it cites were found in a registry or an index; none of the 9 sources its claims cite is checked for support yet.
Racial disparities in automated speech recognition
Open accessAbstract
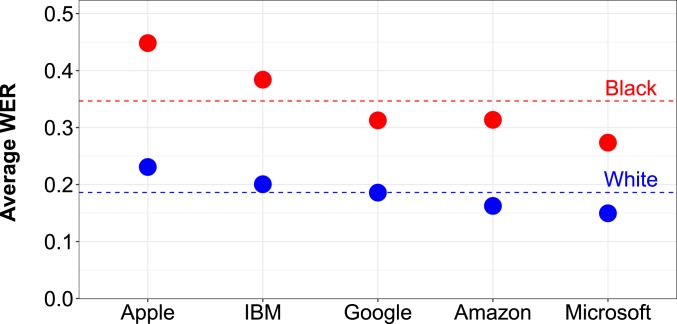
Automated speech recognition (ASR) systems, which use sophisticated machine-learning algorithms to convert spoken language to text, have become increasingly widespread, powering popular virtual assistants, facilitating automated closed captioning, and enabling digital dictation platforms for health care. Over the last several years, the quality of these systems has dramatically improved, due both to advances in deep learning and to the collection of large-scale datasets used to train the systems. There is concern, however, that these tools do not work equally well for all subgroups of the population. Here, we examine the ability of five state-of-the-art ASR systems—developed by Amazon, Apple, Google, IBM, and Microsoft—to transcribe structured interviews conducted with 42 white speakers and 73 black speakers. In total, this corpus spans five US cities and consists of 19.8 h of audio matched on the age and gender of the speaker. We found that all five ASR systems exhibited substantial racial disparities, with an average word error rate (WER) of 0.35 for black speakers compared with 0.19 for white speakers. We trace these disparities to the underlying acoustic models used by the ASR systems as the race gap was equally large on a subset of identical phrases spoken by black and white individuals in our corpus. We conclude by proposing strategies—such as using more diverse training datasets that include African American Vernacular English—to reduce these performance differences and ensure speech recognition technology is inclusive.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This paper audits five commercial automated speech recognition (ASR) systems and finds large racial disparities in word error rates for African American speakers compared with white speakers. The authors trace the gap primarily to acoustic models rather than language or lexical models, suggesting insufficient audio data from black speakers in training.
Key findings
- Across five ASR systems (Amazon, Apple, Google, IBM, Microsoft), the aggregate word error rate (WER) was 0.35 for black speakers versus 0.19 for white speakers; for Microsoft, the best overall system, WER was 0.27 for black speakers versus 0.15 for white speakers, and for Apple, the worst overall, 0.45 versus 0.23.
- Disparities were larger for black men: averaging across the five ASR systems, error rate was 0.41 for black men versus 0.30 for black women, compared with 0.21 for white men and 0.17 for white women.
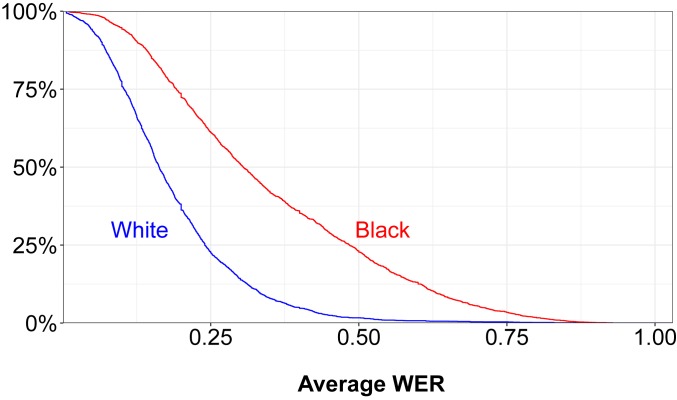
- More than 20% of snippets of black speakers had an average WER of at least 0.5, versus fewer than 2% of white speakers; if WER >0.5 implies an unusable transcript, 23% of black-speaker snippets versus 1.6% of white-speaker snippets were unusable.
- Lexical and language-model gaps did not explain the disparity: 98–99% of spoken words were in reconstructed ASR vocabularies for both groups, and language-model perplexity was lower (better) for black speakers (e.g., GPT-2: 45 vs 55). On 206 matched identical short phrases, WERs were about twice as large for black speakers (e.g., Microsoft: 0.13 vs 0.07), pointing to acoustic-model differences.
Methods
- The study used sociolinguistic interviews from the Corpus of Regional African American Language (CORAAL) and Voices of California (VOC), restricting to adult interviewee-only snippets of 5–50 s. The main matched sample contained 2,141 snippets each from black and white speakers, averaging 17 s per snippet and totaling 19.8 h of audio.
- Propensity-score matching selected black and white snippets with similar age, gender, and snippet duration; WER was computed between cleaned human transcripts and cleaned ASR transcripts.
- Dialect density was hand-coded in a random sample of 150 snippets of black speakers (50 per AAVE site), counting AAVE phonological and grammatical features normalized by word count; interrater Pearson correlations were 0.92 and 0.74. Language-model perplexity was also examined using Transformer-XL, GPT, and GPT-2.
Limitations
- Stated: the white and black audio samples came from different U.S. regions (white speakers in California; black speakers in the Eastern United States), so some differences could reflect regional rather than ethnic linguistic variation; the authors argue AAVE dialect density and similar error rates across two California white sites support an AAVE-driven interpretation.
- Stated: data were collected across different years and recording equipment (Princeville in 2004 on cassette, others digitally in 2014–2017), and the small number of speakers per location limits conclusions about broader geographic dialect patterns; the authors say these issues are unlikely to affect main results.
- Evident: the analysis covers five commercial ASR systems and specific corpora, so findings may not generalize to all ASR systems, speakers, or nonstandard English varieties beyond those studied.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
28 Own result · 18 Own interpretation · 9 Own method · 4 Not checked yet · 1 No basis given
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The pairwise differences in DDM by location are statistically significant, with P < 0.05 in all cases.”
§ Racial disparities in automated speech recognition > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Aggregated across the three AAVE sites, the DDM for male speakers is 0.13 (n=52; SE: 0.02), compared with 0.096 for female speakers (n=98; SE: 0.01).”
§ Racial disparities in automated speech recognition > Results
plaincorrelationaln = 52- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Under all three language models, we find the average perplexity of snippets by black speakers is lower—meaning better performance—than the average perplexity of snippets by white speakers in our sample.”
§ Racial disparities in automated speech recognition > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In comparison, the average error rates for white men and women are more similar at 0.21 (SE: 0.004) and 0.17 (SE: 0.003), respectively.”
§ Racial disparities in automated speech recognition > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
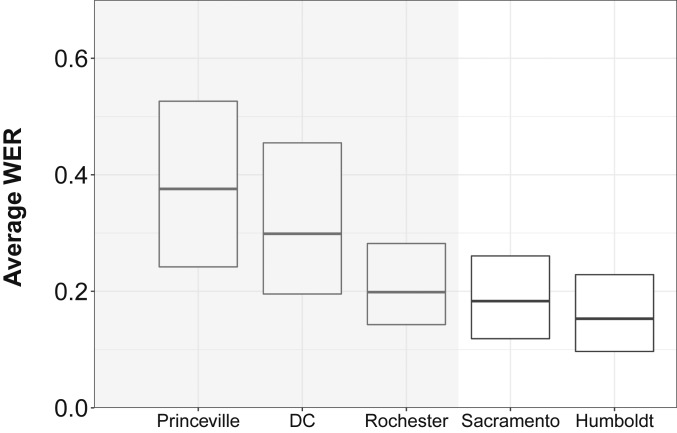
“However, the error rate in the third AAVE site, Rochester (0.20), is comparable to the error rates in the two California locations with white speakers.”
§ Racial disparities in automated speech recognition > Results
plainn = 13- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
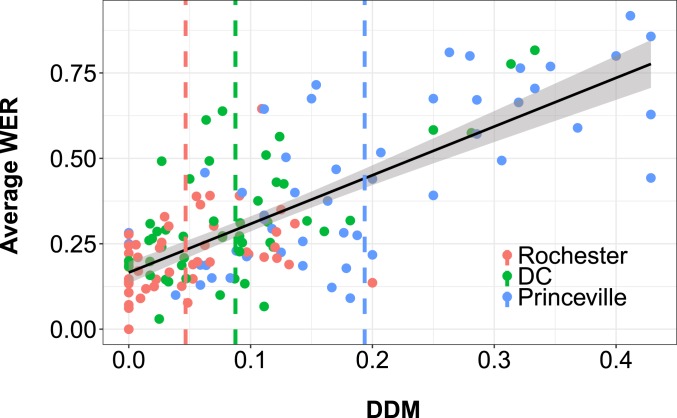
“In Fig. 4, we directly examine the relationship between DDM (on the horizontal axis) and WER (on the vertical axis), which illustrates the positive correlation between DDM and error rates.”
§ Racial disparities in automated speech recognition > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“By analyzing a large corpus of sociolinguistic interviews with white and African American speakers, we demonstrate large racial disparities in the performance of five popular commercial ASR systems.”
- Also stated in: § Results · plain
“For each of the five commercial ASR systems we examine, Fig. 1 shows that the average WER for black speakers is substantially larger than the average WER for white speakers.”
§ Racial disparities in automated speech recognition > Abstract
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Results · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“word error rate is strongly associated with AAVE dialect density, as seen in Fig. 4.”
§ Racial disparities in automated speech recognition > Discussion
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: The dialect density measure (DDM) used in this study provides insight into drivers of the ASR performance gaps.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Thus, if one considers a WER of 0.5 to be the bar for a useful transcription, more than 10 times as many snippets of black speakers fail to meet that standard.”
§ Racial disparities in automated speech recognition > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For both white and black speakers, and across the five ASR systems, 98 to 99% of the words spoken are in the reconstructed vocabularies.”
§ Racial disparities in automated speech recognition > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 10
- It may state two separate claims as one. 8
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For example, “he a pastor” has perplexity of 305, compared with 67 for “he’s a pastor.””
§ Racial disparities in automated speech recognition > Results
plainSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For example, of the 104,486 words uttered by black speakers in our sample, Google’s ASR had at least 103,142 (98.7%) of them in its vocabulary; in comparison, of the 98,653 words spoken by white individuals in our sample, at least 97,260 (98.6%) were in the vocabulary.”
§ Racial disparities in automated speech recognition > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We find that average DDM is lowest in Rochester (0.047)—and also relatively small on an absolute scale—followed by Washington, DC (0.088), and Princeville (0.19), mirroring the ordering of word error rates by location seen in Fig. 3.”
§ Racial disparities in automated speech recognition > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For example, more than 20% of snippets of black speakers have an error rate of at least 0.5; in contrast, fewer than 2% of snippets of white speakers are above that threshold.”
§ Racial disparities in automated speech recognition > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As we discuss next, we find evidence of a gap in the acoustic models but not in the language models.”
§ Racial disparities in automated speech recognition > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Although the total duration and number of words spoken by black and white speakers in our sample were similar, black speakers uttered fewer unique words (5,651) than white speakers (6,280).”
§ Racial disparities in automated speech recognition > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“whose speakers may similarly be burdened by poor ASR performance—including those with regional and nonnative-English accents.”
§ Racial disparities in automated speech recognition > Discussion
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Most previous studies using DDMs have focused on the syntactic complexity of AAVE (34, 35).”
§ Racial disparities in automated speech recognition > Materials and Methods > Measuring Dialect Density.
What the sources say
- Not checked yetcites [34] Craig H. K., Washington J. A., An assessment battery for identifying language impairments in African American children. J. Speech Lang. Hear. Res. 43, 366– 379 (2000). 10757690 source
- Not checked yetcites [35] Oetting J. B., McDonald J. L., Methods for characterizing participants’ nonmainstream dialect use in child language research. J. Speech Lang. Hear. Res. (2002). PMC3390149 12069003 source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Given the relatively small number of speakers in each location, we cannot determine whether these patterns are representative of more general geographic differences in dialect or are simply idiosyncratic trends in our particular sample of speakers.”
§ Racial disparities in automated speech recognition > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We compared our results with those where all snippets containing a list of hard-to-spell city names uttered in the audio snippets were removed. Again, our results did not meaningfully change”
§ Racial disparities in automated speech recognition > Materials and Methods > Data.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We match these snippets across the two datasets based on the age and gender of the speaker and the duration of the snippet.”
- Also stated in: § Abstract · plain
“After matching, we are left with 2,141 snippets from each dataset, with an average length of 17 s per snippet, amounting to 19.8 total hours of audio.”
§ Racial disparities in automated speech recognition > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
- Also stated in: § Abstract · plain
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We confirmed that our results were nearly identical if, instead of performing the above operations, snippets with questionable content were removed entirely.”
§ Racial disparities in automated speech recognition > Materials and Methods > Data.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“The complete list of AAVE features that we tagged is based on past work (23–25)”
§ Racial disparities in automated speech recognition > Materials and Methods > Measuring Dialect Density.
What the sources say
- Not checked yetcites [23] Rickford J. R., Phonological and Grammatical Features of African American Vernacular (AAVE) (Blackwell Publishers, 1999).
- Not checked yetcites [24] Thomas E. R., Phonological and phonetic characteristics of African American Vernacular English. Lang. Linguist. Compass 1, 450– 475 (2007). source
- Not checked yetcites [25] Bailey G., Thomas E., “ Some aspects of African-American Vernacular English phonology” in African-American English: Structure, History and Use, Mufwene S., Rickford J. R., Bailey G., Baugh J., Eds. (Routledge, New York, NY, 1998), pp. 85– 109.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Past work has also found that ASRs perform somewhat worse on conversational speech from male speakers than female speakers, likely due to male speakers using more informal style with shorter, more reduced pronunciations and more disfluencies (28, 29).”
§ Racial disparities in automated speech recognition > Results
What the sources say
- Not checked yetcites [28] Goldwater S., Jurafsky D., Manning C. D., Which words are hard to recognize? Prosodic, lexical, and disfluency factors that increase speech recognition error rates. Speech Commun. 52, 181– 200 (2010). source
- Not checked yetcites [29] Adda-Decker M., Lamel L., “ Do speech recognizers prefer female speakers?” in Proceedings of INTERSPEECH-2005 (International Speech Communication Association, 2005), pp. 2205– 2208. source
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“In both datasets, the interviews were transcribed by human experts, which we use as the ground truth when evaluating the performance of machine transcriptions.”
§ Racial disparities in automated speech recognition > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These disparities may also actively harm African American communities when, for example, speech recognition software is used by employers to automatically evaluate candidate interviews or by criminal justice agencies to automatically transcribe courtroom proceedings.”
§ Racial disparities in automated speech recognition > Discussion
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
The paper relies on this without support.
Commercial ASR systems use language models that have similar statistical properties to publicly available state-of-the-art models like Transformer-XL, GPT, and GPT-2.
“However, it is likely that these systems use language models that have similar statistical properties to state-of-the-art models that are publicly available, like Transformer-XL (30), GPT (31), and GPT-2 (32).”
The paper relies on this without support.
The study's limitations (different years and recording equipment) are unlikely to impact the main results.
“While it is important to recognize these limitations of our study design, we believe they are unlikely to impact our main results.”
The paper relies on this without support.
The time gap between the 2004 Princeville data and the 2014–2017 data does not represent a significant time gap for sociolinguistic analysis.
“The majority of our data come from 2014 to 2017—a span that does not represent a significant time gap for sociolinguistic analysis”
The paper relies on this without support.
Combining audio collected across different years and recorded with different equipment is acceptable because it is common in dialectology studies.
“Given the obstacles in assembling data from a large number of speakers across multiple field sites, it is not uncommon in dialectology studies to combine audio collected across different years and recorded with different equipment.”
The paper relies on this without support.
The dialect density measure (DDM) used in this study provides insight into drivers of the ASR performance gaps.
“in our setting, the measure we use provides insight into drivers of the ASR performance gaps we see.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“but also pose usability barriers for novice users such as older adults learning how to engage with them [59, 93].”
From "It's Kind of Like Code-Switching": Black Older Adults' Experiences with a Voice Assistant for Health Information Seeking (2022) · cites this paper as [59]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Many sources show ASR's volatility with diferent datasets: ASR performs diferently for male or female speakers, shows racial biases or varying accuracy rates for speakers with diferent accents [Cumbal et al. 2021;Koenecke et al. 2020;Speechmatics 2023;Tadimeti et al. 2022;Tatman and Kasten 2017].”
From Measuring the Accuracy of Automatic Speech Recognition Solutions (2023) · cites this paper as Koenecke et al. 2020
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“The studies aim to show that ASR has speciic biases that often afect speakers of underrepresented groups, but are not concerned with the overall accuracy of the engines.”
From Measuring the Accuracy of Automatic Speech Recognition Solutions (2023) · cites this paper as Koenecke et al. 2020
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Unsurprisingly, gendered and racial disparities have been documented in a number of language technologies [37, 79, 141]”
From Data Governance in the Age of Large-Scale Data-Driven Language Technology (2022) · cites this paper as [79]
The cited source says what the claim attributes to it.
In the citing paper
“it is well-documented that standard models often perform poorly on under-represented demographics (Buolamwini and Gebru, 2018; Koenecke et al., 2020)”
From WILDS: A Benchmark of in-the-Wild Distribution Shifts (2020) · cites this paper as Koenecke et al., 2020
The cited source says what the claim attributes to it.
In the citing paper
“Performance disparities across individuals have been observed in a wide range of tasks and applications, including in natural language processing (Geva et al., 2019), automatic speech recognition (Koenecke et al., 2020; Tatman, 2017), federated learning (Li et al., 2019b; Caldas et al., 2018), and medical imaging (Badgeley et al., 2019).”
From WILDS: A Benchmark of in-the-Wild Distribution Shifts (2020) · cites this paper as Koenecke et al., 2020
In the citing paper
“This means that AIaaS might not only contribute to replicating fairness issues at scale by propagating model's intrinsic biases (or other issues) to the vast number of user applications powered by a given service (see previous work including [22,81,133,139]).”
From Out of Context: Investigating the Bias and Fairness Concerns of “Artificial Intelligence as a Service” (2023) · cites this paper as [81]
In the citing paper
“These issues are particularly related to biases in datasets and algorithms, such as unfair representation.”
From Artificial intelligence in assessment and intervention of speech and language disorders: A literature review (2025) · cites this paper as [47]
In the citing paper
“In addition, Koenecke et al . [47] emphasized that ethical issues need to be systematically addressed in the clinical use of AI.”
From Artificial intelligence in assessment and intervention of speech and language disorders: A literature review (2025) · cites this paper as [47]
In the citing paper
“For instance, automatic speech recognition systems demonstrate lower accuracy for African American speakers of English compared to speakers of General American English, and this difference is particularly pronounced in children [47].”
From Artificial intelligence in assessment and intervention of speech and language disorders: A literature review (2025) · cites this paper as [47]
Citations
Cites
Dissecting racial bias in an algorithm used to manage the health of populations
Obermeyer, Z., Powers, B., Vogeli, C., & Mullainathan, S. (2019) · Science · doi:10.1126/science.aax2342 · Cited by 7,137
MatchIt : Nonparametric Preprocessing for Parametric Causal Inference
Ho, D. E., Imai, K., King, G., & Stuart, E. A. (2011) · Journal of Statistical Software · doi:10.18637/jss.v042.i08 · Cited by 4,385
(2018) · Cited by 3,510
Transformer-XL: Attentive language models beyond a fixed-length context
Dai, Z., Yang, Z., Yang, Y., Carbonell, J., Le, Q., & Salakhutdinov, R. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1285 · Cited by 3,169
Semantics derived automatically from language corpora contain human-like biases
Caliskan, A., Bryson, J. J., & Narayanan, A. (2017) · Science · doi:10.1126/science.aal4230 · Cited by 2,887
Fair prediction with disparate impact: a study of bias in recidivism prediction instruments
Chouldechova, A. (2017) · Big Data · doi:10.1089/big.2016.0047 · Cited by 2,159
MatchIt: Nonparametric Preprocessing for Parametric Causal Inference
Ho, D. E., Imai, K., King, G., Stuart, E. A., & Greifer, N. (2005) · doi:10.32614/cran.package.matchit · Cited by 1,210
Algorithmic Decision Making and the Cost of Fairness
Corbett-Davies, S., Pierson, E., Feller, A., Goel, S., & Huq, A. (2017) · Proceedings of the 23rd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/3097983.3098095 · Cited by 1,149
Self-citationInherent trade-offs in the fair determination of risk scores
Kleinberg, J., Mullainathan, S., & Raghavan, M. (2017) · Schloss Dagstuhl – Leibniz-Zentrum für Informatik · doi:10.4230/lipics.itcs.2017.43 · Cited by 943
The Risk of Racial Bias in Hate Speech Detection
Sap, M., Card, D., Gabriel, S., Choi, Y., & Smith, N. A. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1163 · Cited by 817
Research works printed but not linked: 2
- I. D. Raji, J. Buolamwini, “Actionable auditing: Investigating the impact of publicly naming biased performance results of commercial ai products” in AAAI/ACM Conference on AI Ethics and Society (Association for Computing Machinery, 2019), Vol. 1, pp. 429–435.
- J. R. Rickford, Phonological and Grammatical Features of African American Vernacular (AAVE) (Blackwell Publishers, 1999).
Cited by
Sorted by citations
On the Opportunities and Risks of Foundation Models
Bommasani, R., Hudson, D. A., Adeli, E., Altman, R., Arora, S., von Arx, S., Bernstein, M. S., Bohg, J., Bosselut, A., Brunskill, E., et al. (2021) · arXiv · doi:10.48550/arxiv.2108.07258 · Cited by 2,676
Self-citationAI recognition of patient race in medical imaging: a modelling study
Gichoya, J. W., Banerjee, I., Bhimireddy, A. R., Burns, J. L., Celi, L. A., Chen, L.-C., Correa, R., Dullerud, N., Ghassemi, M., Huang, S.-C., et al. (2022) · The Lancet Digital Health · doi:10.1016/s2589-7500(22)00063-2 · Cited by 611
Trustworthy AI: From Principles to Practices
Li, B., Qi, P., Liu, B., Di, S., Liu, J., Pei, J., Yi, J., & Zhou, B. (2023) · ACM Computing Surveys · doi:10.1145/3555803 · Cited by 612
“, recognizing speech in less-spoken accents can be naturally harder due to data scarcity [191]).”
BackgroundEthical and social risks of harm from Language Models
Weidinger, L., Mellor, J., Rauh, M., Griffin, C., Uesato, J., Huang, P.-S., Cheng, M., Glaese, M., Balle, B., Kasirzadeh, A., et al. (2021) · arXiv · doi:10.48550/arxiv.2112.04359 · Cited by 477
Computational bioacoustics with deep learning: a review and roadmap
Stowell, D. (2022) · PeerJ · doi:10.7717/peerj.13152 · Cited by 471
Shifting machine learning for healthcare from development to deployment and from models to data
Zhang, A., Xing, L., Zou, J., & Wu, J. C. (2022) · Nature Biomedical Engineering · doi:10.1038/s41551-022-00898-y · Cited by 420
Inherent Tradeoffs in the Fair Determination of Risk Scores
Raghavan, M. (2023) · ACM eBooks · doi:10.1145/3603195.3603197 · Cited by 350
WILDS: A Benchmark of in-the-Wild Distribution Shifts
Koh, P. W., Sagawa, S., Marklund, H., Xie, S. M., Zhang, M., Balsubramani, A., Hu, W., Yasunaga, M., Phillips, R. L., Gao, I., et al. (2020) · arXiv · doi:10.48550/arxiv.2012.07421 · Cited by 518
“…in applications that call for good performance across a wide range of users, including many user-facing applications such as speech recognition (Koenecke et al., 2020; Tatman, 2017) and personalized recommender systems (Patro et al., 2020), tools used for analysis of individuals such as…”
InfluentialTimmons, A. C., Duong, J. B., Simo Fiallo, N., Lee, T., Vo, H. P. Q., Ahle, M. W., Comer, J. S., Brewer, L. C., Frazier, S. L., & Chaspari, T. (2023) · Perspectives on Psychological Science · doi:10.1177/17456916221134490 · Cited by 263
Sociotechnical Harms of Algorithmic Systems: Scoping a Taxonomy for Harm Reduction
Shelby, R., Rismani, S., Henne, K., Moon, A., Rostamzadeh, N., Nicholas, P., Yilla-Akbari, N., Gallegos, J., Smart, A., Garcia, E., et al. (2023) · Proceedings of the 2023 AAAI/ACM Conference on AI, Ethics, and Society · doi:10.1145/3600211.3604673 · Cited by 279
Bad machines corrupt good morals
Köbis, N., Bonnefon, J., & Rahwan, I. (2021) · Nature Human Behaviour · doi:10.1038/s41562-021-01128-2 · Cited by 225
Investigating Bias and Fairness in Facial Expression Recognition
Tian, X., White, J. C., Kalkan, S., & Güneş, H. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-65414-6_35 · Cited by 174
Addressing algorithmic bias and the perpetuation of health inequities: An AI bias aware framework
Agarwal, R., Bjarnadottir, M., Rhue, L., Dugas, M., Crowley, K., Clark, J., & Gao, G. (2023) · Health Policy and Technology · doi:10.1016/j.hlpt.2022.100702 · Cited by 170
"I wouldn't say offensive but...": Disability-Centered Perspectives on Large Language Models
Gadiraju, V., Kane, S., Dev, S., Taylor, A., Wang, D., Denton, R., & Brewer, R. (2023) · 2023 ACM Conference on Fairness Accountability and Transparency · doi:10.1145/3593013.3593989 · Cited by 155
Assessing the Fairness of AI Systems: AI Practitioners' Processes, Challenges, and Needs for Support
Madaio, M., Egede, L., Subramonyam, H., Wortman Vaughan, J., & Wallach, H. (2022) · Proceedings of the ACM on Human-Computer Interaction · doi:10.1145/3512899 · Cited by 156
Mengesha, Z., Heldreth, C., Lahav, M., Sublewski, J., & Tuennerman, E. (2021) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2021.725911 · Cited by 140
Self-citationRepresentation Bias in Data: A Survey on Identification and Resolution Techniques
Shahbazi, N., Yin, L., Asudeh, A., & Jagadish, H. V. (2023) · ACM Computing Surveys · doi:10.1145/3588433 · Cited by 178
Understanding and Mitigating Annotation Bias in Facial Expression Recognition
Chen, Y., & Joo, J. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.01471 · Cited by 126
Comparison of Methods to Reduce Bias From Clinical Prediction Models of Postpartum Depression
Park, Y., Hu, J., Singh, M., Sylla, I., Dankwa‐Mullan, I., Koski, E., & Das, A. K. (2021) · JAMA Network Open · doi:10.1001/jamanetworkopen.2021.3909 · Cited by 116
Demszky, D., Liu, J., Hill, H. C., Jurafsky, D., & Piech, C. (2023) · Educational Evaluation and Policy Analysis · doi:10.3102/01623737231169270 · Cited by 147
Self-citationBiosignal Sensors and Deep Learning-Based Speech Recognition: A Review
Lee, W., Seong, J. J., Özlü, B., Shim, B. S., Marakhimov, A., & Lee, S. (2021) · Sensors · doi:10.3390/s21041399 · Cited by 119
Gupta, S., Langhans, S. D., Domisch, S., Nerini, F. F., Felländer, A., Battaglini, M., Tegmark, M., & Vinuesa, R. (2021) · Transportation Engineering · doi:10.1016/j.treng.2021.100064 · Cited by 122
Towards inclusive automatic speech recognition
Feng, S., Halpern, B. M., Kudina, O., & Scharenborg, O. (2023) · Computer Speech & Language · doi:10.1016/j.csl.2023.101567 · Cited by 106
Ahmed, N., & Wahed, M. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2010.15581 · Cited by 254
AI auditing: The Broken Bus on the Road to AI Accountability
Birhane, A., Steed, R., Ojewale, V., Vecchione, B., & Raji, I. D. (2024) · 2024 IEEE Conference on Secure and Trustworthy Machine Learning (SaTML) · doi:10.1109/satml59370.2024.00037 · Cited by 158
Harrington, C. N., Garg, R., Woodward, A., & Williams, D. (2022) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3491102.3501995 · Cited by 98
“As a consequence, we know less about interactions and experiences with voice assistants among subgroups of older adults that may experience additional barriers to technology engagement related to demographic factors of identity outside of age, which have been found to be important factors of interaction [60].”
BackgroundInfluentialExploring How Machine Learning Practitioners (Try To) Use Fairness Toolkits
Deng, W. H., Nagireddy, M., Lee, M. S. A., Singh, J., Wu, Z. S., Holstein, K., & Zhu, H. (2022) · 2022 ACM Conference on Fairness Accountability and Transparency · doi:10.1145/3531146.3533113 · Cited by 99
Careless Whisper: Speech-to-Text Hallucination Harms
Koenecke, A., Choi, A. S. G., Mei, K. X., Schellmann, H., & Sloane, M. (2024) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3630106.3658996 · Cited by 95
Self-citationEvaluating OpenAI's Whisper ASR: Performance analysis across diverse accents and speaker traits
Graham, C., & Roll, N. (2024) · JASA Express Letters · doi:10.1121/10.0024876 · Cited by 90
Ng, J. J. W., Wang, E., Zhou, X., Zhou, K. X., Goh, C. X. L., Sim, G.-H., Tan, H. K., Goh, S. S. N., & Ng, Q. X. (2025) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-025-03061-0 · Cited by 110
Rio, D. D. F. D., Sovacool, B. K., & Griffiths, S. (2021) · Energy and Climate Change · doi:10.1016/j.egycc.2021.100035 · Cited by 105
Temporal Sentence Grounding in Videos: A Survey and Future Directions
Zhang, H., Sun, A., Jing, W., & Zhou, J. T. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3258628 · Cited by 105
Carrasco-Farré, C. (2022) · Humanities and Social Sciences Communications · doi:10.1057/s41599-022-01174-9 · Cited by 84
Understanding and Evaluating Racial Biases in Image Captioning
Zhao, D., Wang, A., & Russakovsky, O. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.01456 · Cited by 85
Assessing the accuracy of automatic speech recognition for psychotherapy
Miner, A. S., Haque, A., Fries, J., Fleming, S. L., Wilfley, D. E., Wilson, G. T., Milstein, A. S., Jurafsky, D., Arnow, B. A., Agras, W. S., et al. (2020) · npj Digital Medicine · doi:10.1038/s41746-020-0285-8 · Cited by 87
Self-citationHitczenko, K., Mittal, V. A., & Goldrick, M. (2020) · Schizophrenia Bulletin · doi:10.1093/schbul/sbaa141 · Cited by 85
Markl, N. (2022) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3531146.3533117 · Cited by 100
Uneven success: automatic speech recognition and ethnicity-related dialects
Wassink, A. B., Gansen, C., & Bartholomew, I. (2022) · Speech Communication · doi:10.1016/j.specom.2022.03.009 · Cited by 77
Lam, M. S., Gordon, M., Metaxa, D., Hancock, J. T., Landay, J. A., & Bernstein, M. S. (2022) · Proceedings of the ACM on Human-Computer Interaction · doi:10.1145/3555625 · Cited by 95
Can AI be racist? Color‐evasiveness in the application of machine learning to science assessments
Cheuk, T. (2021) · Science Education · doi:10.1002/sce.21671 · Cited by 86
More than a biomarker: could language be a biosocial marker of psychosis?
Palaniyappan, L. K. (2021) · Schizophrenia · doi:10.1038/s41537-021-00172-1 · Cited by 73
Corbett, C. F., Wright, P. J., Jones, K., & Parmer, M. (2021) · Frontiers in Public Health · doi:10.3389/fpubh.2021.742012 · Cited by 68
Designing Disaggregated Evaluations of AI Systems: Choices, Considerations, and Tradeoffs
Barocas, S., Guo, A., Kamar, E., Krones, J., Morris, M. R., Vaughan, J. W., Wadsworth, W. D., & Wallach, H. (2021) · Proceedings of the 2021 AAAI/ACM Conference on AI, Ethics, and Society · doi:10.1145/3461702.3462610 · Cited by 72
Multilingualism and AI: The Regimentation of Language in the Age of Digital Capitalism
Schneider, B. (2022) · Signs and Society · doi:10.1086/721757 · Cited by 81
Mitigating Bias in Algorithmic Hiring: Evaluating Claims and Practices
Raghavan, M. (2023) · ACM eBooks · doi:10.1145/3603195.3603203 · Cited by 67
Ethical AI in facial expression analysis: racial bias
Sham, A. H., Aktas, K., Rizhinashvili, D., Kuklyanov, D., Alisinanoğlu, F., Ofodile, I., Ozcinar, C., & Anbarjafari, G. (2022) · Signal Image and Video Processing · doi:10.1007/s11760-022-02246-8 · Cited by 65
Bias in Automatic Speech Recognition: The Case of African American Language
Martin, J., & Wright, K. E. (2022) · Applied Linguistics · doi:10.1093/applin/amac066 · Cited by 71
Linguistic Bias in ChatGPT: Language Models Reinforce Dialect Discrimination
Fleisig, E., Smith, G., Bossi, M., Rustagi, I., Yin, X., & Klein, D. (2024) · Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2024.emnlp-main.750 · Cited by 64
The Algorithmic Divide: A Systematic Review on AI-Driven Racial Disparities in Healthcare
Haider, S. A., Borna, S., Gomez-Cabello, C. A., Pressman, S. M., Haider, C. R., & Forte, A. J. (2024) · Journal of Racial and Ethnic Health Disparities · doi:10.1007/s40615-024-02237-0 · Cited by 72
Widening Access to Applied Machine Learning with TinyML
Janapa Reddi, V., Plancher, B., Kennedy, S., Moroney, L., Warden, P., Suzuki, L., Agarwal, A., Banbury, C., Banzi, M., Bennett, M., et al. (2022) · Harvard Data Science Review · doi:10.1162/99608f92.762d171a · Cited by 62
Harrington, C., & Egede, L. (2023) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544548.3580719 · Cited by 64
Acoustic-phonetic properties of Siri- and human-directed speech
Cohn, M., Šegedin, B. F., & Zellou, G. (2021) · Journal of Phonetics · doi:10.1016/j.wocn.2021.101123 · Cited by 61
Quantifying Bias in Automatic Speech RecognitionPreprint
Feng, S., Kudina, O., Halpern, B. M., & Scharenborg, O. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2103.15122 · Cited by 61
Expectations for Artificial Intelligence (AI) in Psychiatry
Monteith, S., Glenn, T., Geddes, J. R., Whybrow, P. C., Achtyes, E. D., & Bauer, M. (2022) · Current Psychiatry Reports · doi:10.1007/s11920-022-01378-5 · Cited by 61
Carter, M., & Egliston, B. (2021) · New Media & Society · doi:10.1177/14614448211012794 · Cited by 66
The Spotlight: A General Method for Discovering Systematic Errors in Deep Learning Models
d'Eon, G., d’Eon, J., Wright, J. R., & Leyton‐Brown, K. (2022) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3531146.3533240 · Cited by 62
Working at the Intersection of Race, Disability and Accessibility
Harrington, C. N., Desai, A., Lewis, A., Moharana, S., Ross, A. S., & Mankoff, J. (2023) · The 25th International ACM SIGACCESS Conference on Computers and Accessibility · doi:10.1145/3597638.3608389 · Cited by 53
Privacy-preserving Voice Analysis via Disentangled Representations
Aloufi, R., Haddadi, H., & Boyle, D. (2020) · Cloud Computing Security Workshop · doi:10.1145/3411495.3421355 · Cited by 54
FrugalGPT: How to Use Large Language Models While Reducing Cost and Improving Performance
Chen, L., Zaharia, M., & Zou, J. (2023) · arXiv · doi:10.48550/arxiv.2305.05176 · Cited by 889
“Its goal is to provide the same output as a large LLM at lower latency.”
Enabling Design Methodologies and Future Trends for Edge AI: Specialization and Codesign
Hao, C., Dotzel, J., Xiong, J., Benini, L., Zhang, Z., & Chen, D. (2021) · IEEE Design and Test · doi:10.1109/mdat.2021.3069952 · Cited by 59
Large Language Models in Qualitative Research: Uses, Tensions, and Intentions
Schroeder, H., Quéré, M. A. L., Randazzo, C., Mimno, D., & Schoenebeck, S. Y. (2025) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3706598.3713120 · Cited by 109
Bias in Automated Speaker Recognition
Toussaint, W., & Ding, A. Y. (2022) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3531146.3533089 · Cited by 53
Harris, C., Johnson, A. G., Palmer, S., Yang, D.-Y., & Bruckman, A. (2023) · Proc. ACM Hum. Comput. Interact. · doi:10.1145/3610169 · Cited by 54
Rio, D. D. F. D., Sovacool, B. K., & Martiskainen, M. (2021) · Energy Research & Social Science · doi:10.1016/j.erss.2021.102105 · Cited by 47
Chen, K., Shao, A., Burapacheep, J., & Li, Y. (2024) · Scientific Reports · doi:10.1038/s41598-024-51969-w · Cited by 74
Wei, J., Tag, B., Trippas, J. R., Dingler, T., & Kostakos, V. (2022) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3491102.3517432 · Cited by 46
Data Governance in the Age of Large-Scale Data-Driven Language Technology
Jernite, Y., Nguyen, H., Biderman, S., Rogers, A., Masoud, M., Danchev, V., Tan, S., Luccioni, A. S., Subramani, N., Johnson, I., et al. (2022) · 2022 ACM Conference on Fairness Accountability and Transparency · doi:10.1145/3531146.3534637 · Cited by 75
“Unsurprisingly, gendered and racial disparities have been documented in a number of language technologies [37, 79, 141], and processes of creating resources and technologies may further entrench such disparities [25, 38, 144].”
BackgroundRaghavan, M. (2023) · ACM eBooks · doi:10.1145/3603195.3603207 · Cited by 49
Alshaabi, T., Adams, J. L., Arnold, M., Minot, J. R., Dewhurst, D. R., Reagan, A. J., Danforth, C. M., & Dodds, P. S. (2021) · Science Advances · doi:10.1126/sciadv.abe6534 · Cited by 52
Measuring the Accuracy of Automatic Speech Recognition Solutions
Kuhn, K., Kersken, V., Reuter, B., Egger, N., & Zimmermann, G. (2023) · ACM Transactions on Accessible Computing · doi:10.1145/3636513 · Cited by 44
“Researchers from Google report a WER of 5.6% on an internal dataset of 12500 hours of Google Voice Search utterances [Chiu et al. 2018].”
MethodInfluentialEnvisioning Equitable Speech Technologies for Black Older Adults
Brewer, R. N., Harrington, C., & Heldreth, C. M. (2023) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3593013.3594005 · Cited by 43
Berger, S., & Baria, A. T. (2022) · Frontiers in Pain Research · doi:10.3389/fpain.2022.896276 · Cited by 42
Generative AI Meets Open-Ended Survey Responses: Research Participant Use of AI and Homogenization
Zhang, S., Xu, J., & Alvero, A. (2025) · Sociological Methods & Research · doi:10.1177/00491241251327130 · Cited by 68
Opportunities and Challenges for AI-Based Support for Speech-Language Pathologists
Suh, H., Dangol, A., Meadan, H., Miller, C. A., & Kientz, J. A. (2024) · Proceedings of the 3rd Annual Meeting of the Symposium on Human-Computer Interaction for Work · doi:10.1145/3663384.3663387 · Cited by 43
Towards Measuring Fairness in Speech Recognition: Casual Conversations Dataset Transcriptions
Liu, C., Picheny, M., Sarı, L., Chitkara, P., Xiao, A., Zhang, X., Chou, M., Alvarado, A., Hazırbaş, C., & Saraf, Y. (2022) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp43922.2022.9747501 · Cited by 42
Do, K., Pang, R. Y., Jiang, J., & Reinecke, K. (2023) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544548.3581347 · Cited by 51
Berman, G., Goyal, N., & Madaio, M. (2024) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3613904.3642398 · Cited by 51
Language Generation Models Can Cause Harm: So What Can We Do About It? An Actionable Survey
Kumar, S., Balachandran, V., Njoo, L., Anastasopoulos, A., & Tsvetkov, Y. (2023) · Proceedings of the 17th Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2023.eacl-main.241 · Cited by 38
Alvero, A. J., Lee, J., Regla-Vargas, A., Kizilcec, R. F., Joachims, T., & Antonio, A. L. (2024) · Journal of Big Data · doi:10.1186/s40537-024-00986-7 · Cited by 48
Firefox Voice: An Open and Extensible Voice Assistant Built Upon the Web
Cambre, J., Williams, A. C., Razi, A., Bicking, I., Wallin, A., Tsai, J., Kulkarni, C., & Kaye, J. (2021) · Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems · doi:10.1145/3411764.3445409 · Cited by 39
Mitigating bias against non-native accents
Zhang, Y., Zhang, Y., Halpern, B. M., Patel, T. B., & Scharenborg, O. (2022) · Interspeech (USB) · doi:10.21437/interspeech.2022-836 · Cited by 38
Hey ASR System! Why Aren’t You More Inclusive?
Ngueajio, M. K., & Washington, G. J. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-21707-4_30 · Cited by 43
Moore, S., Liao, Q. V., & Subramonyam, H. (2023) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3544548.3581242 · Cited by 46
Zolnoori, M., Vergez, S., Xu, Z., Esmaeili, E., Zolnour, A., Briggs, K. A., Scroggins, J. K., Ebrahimabad, S. F. H., Noble, J. M., Topaz, M., et al. (2024) · JAMIA Open · doi:10.1093/jamiaopen/ooae130 · Cited by 38
Mildner, T., Cooney, O., Meck, A.-M., Bartl, M., Savino, G.-L., Doyle, P. R., Garaialde, D., Clark, L., Sloan, J., Wenig, N., et al. (2024) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3613904.3642542 · Cited by 39
Linguistic analysis of human-computer interaction
Zellou, G., & Holliday, N. R. (2024) · Frontiers in Computer Science · doi:10.3389/fcomp.2024.1384252 · Cited by 38
WER we are and WER we think we are
Szymański, P., Żelasko, P., Morzy, M., Szymczak, A., Żyła-Hoppe, M., Banaszczak, J., Augustyniak, Ł., Mizgajski, J. T., & Carmiel, Y. (2020) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2020.findings-emnlp.295 · Cited by 38
Razumovskaia, E., Glavaš, G., Majewska, O., Ponti, E. M., Korhonen, A., & Vulić, I. (2022) · Journal of Artificial Intelligence Research · doi:10.1613/jair.1.13083 · Cited by 65
Fair Enough: Searching for Sufficient Measures of Fairness
Majumder, S., Chakraborty, J., Bai, G. R., Stolee, K. T., & Menzies, T. (2023) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3585006 · Cited by 36
Designing equitable algorithms
Chohlas-Wood, A., Coots, M., Goel, S., & Nyarko, J. (2023) · Nature Computational Science · doi:10.1038/s43588-023-00485-4 · Cited by 42
Self-citationUnderstanding Racial Disparities in Automatic Speech Recognition: The Case of Habitual “be”
Martin, J., & Tang, K. (2020) · Interspeech (USB) · doi:10.21437/interspeech.2020-2893 · Cited by 34
Broaden the Vision: Geo-Diverse Visual Commonsense Reasoning
Yin, D., Li, L. H., Hu, Z., Peng, N., & Chang, K.-W. (2021) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2021.emnlp-main.162 · Cited by 49
A Practical Guide to Conversation Research: How to Study What People Say to Each Other
Yeomans, M., Boland, F. K., Collins, H. K., Abi-Esber, N., & Brooks, A. W. (2023) · Advances in Methods and Practices in Psychological Science · doi:10.1177/25152459231183919 · Cited by 44
Considering the Safety and Quality of Artificial Intelligence in Health Care
Ross, P. A., & Spates, K. (2020) · The Joint Commission Journal on Quality and Patient Safety · doi:10.1016/j.jcjq.2020.08.002 · Cited by 33
Erroneous data: The Achilles' heel of AI and personalized medicine
Kristiansen, T. B., Kristensen, K., Uffelmann, J., & Brandslund, I. (2022) · Frontiers in Digital Health · doi:10.3389/fdgth.2022.862095 · Cited by 33
Lalor, J. P., Abbasi, A., Oketch, K., Yang, Y., & Forsgren, N. (2024) · ACM Transactions on Information Systems · doi:10.1145/3641276 · Cited by 40
Nee, J., Smith, G. M., Sheares, A. M., & Rustagi, I. (2022) · Big Data & Society · doi:10.1177/20539517221090930 · Cited by 43
Can Whisper Perform Speech-Based In-Context Learning?
Wang, S., Yang, C.-H. H., Wu, J. Y., & Zhang, C. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10446502 · Cited by 50
Local Languages, Third Spaces, and other High-Resource Scenarios
Bird, S. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.539 · Cited by 43
Debiasing Pre-Trained Language Models via Efficient Fine-Tuning
Gira, M., Zhang, R., & Lee, K. (2022) · Workshop on Language Technology for Equality, Diversity, Inclusion (LT-EDI) · doi:10.18653/v1/2022.ltedi-1.8 · Cited by 38
Metadata
- Authors
- Koenecke, A., Nam, A., Lake, E., Nudell, J., Quartey, M., Mengesha, Z., Toups, C., Rickford, J. R., Jurafsky, D., & Goel, S.
- Affiliations
- Stanford University (US)
- Georgetown University (US)
- Corresponding author
- Goel, Sharad
- ORCID
- Venue
- Proceedings of the National Academy of Sciences
- Publisher
- National Academy of Sciences
- Published
- 2020-03-23
- Volume
- 117
- Issue
- 14
- Pages
- 7684-7689
- ISSN
- 0027-8424 (ISSN-L)
- 1091-6490
- PMC
- PMC7149386
- OpenAlex
- W3012624518
- Semantic Scholar
- 219b7266ae848937da170c5510b2bfc66d17859a
- Cited by
- 765
- References
- 37
- Citations by year
- 2026: 169 · 2025: 110 · 2024: 112 · 2023: 171 · 2022: 112 · 2021: 68 · 2020: 23
- FWCI
- 36.76
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Proceedings of the National Academy of Sciences (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- RePEc: Research Papers in Economics (submittedVersion)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Speech Recognition and Synthesis
- Physical Sciences › Computer Science › Artificial Intelligence › Ethics and Social Impacts of AI
- Physical Sciences › Computer Science › Signal Processing › Speech and Audio Processing
- Keywords
- speech recognition, racial disparities, algorithmic bias, word error rate, acoustic modeling, African American English, training data diversity, inclusive technology
- MeSH terms
- Adult, Automation, Black or African American, Humans, Language, Speech Perception, White People, Speech Recognition Software, Racism
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-06, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-06 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
